
312 ·GitHub
What is this?
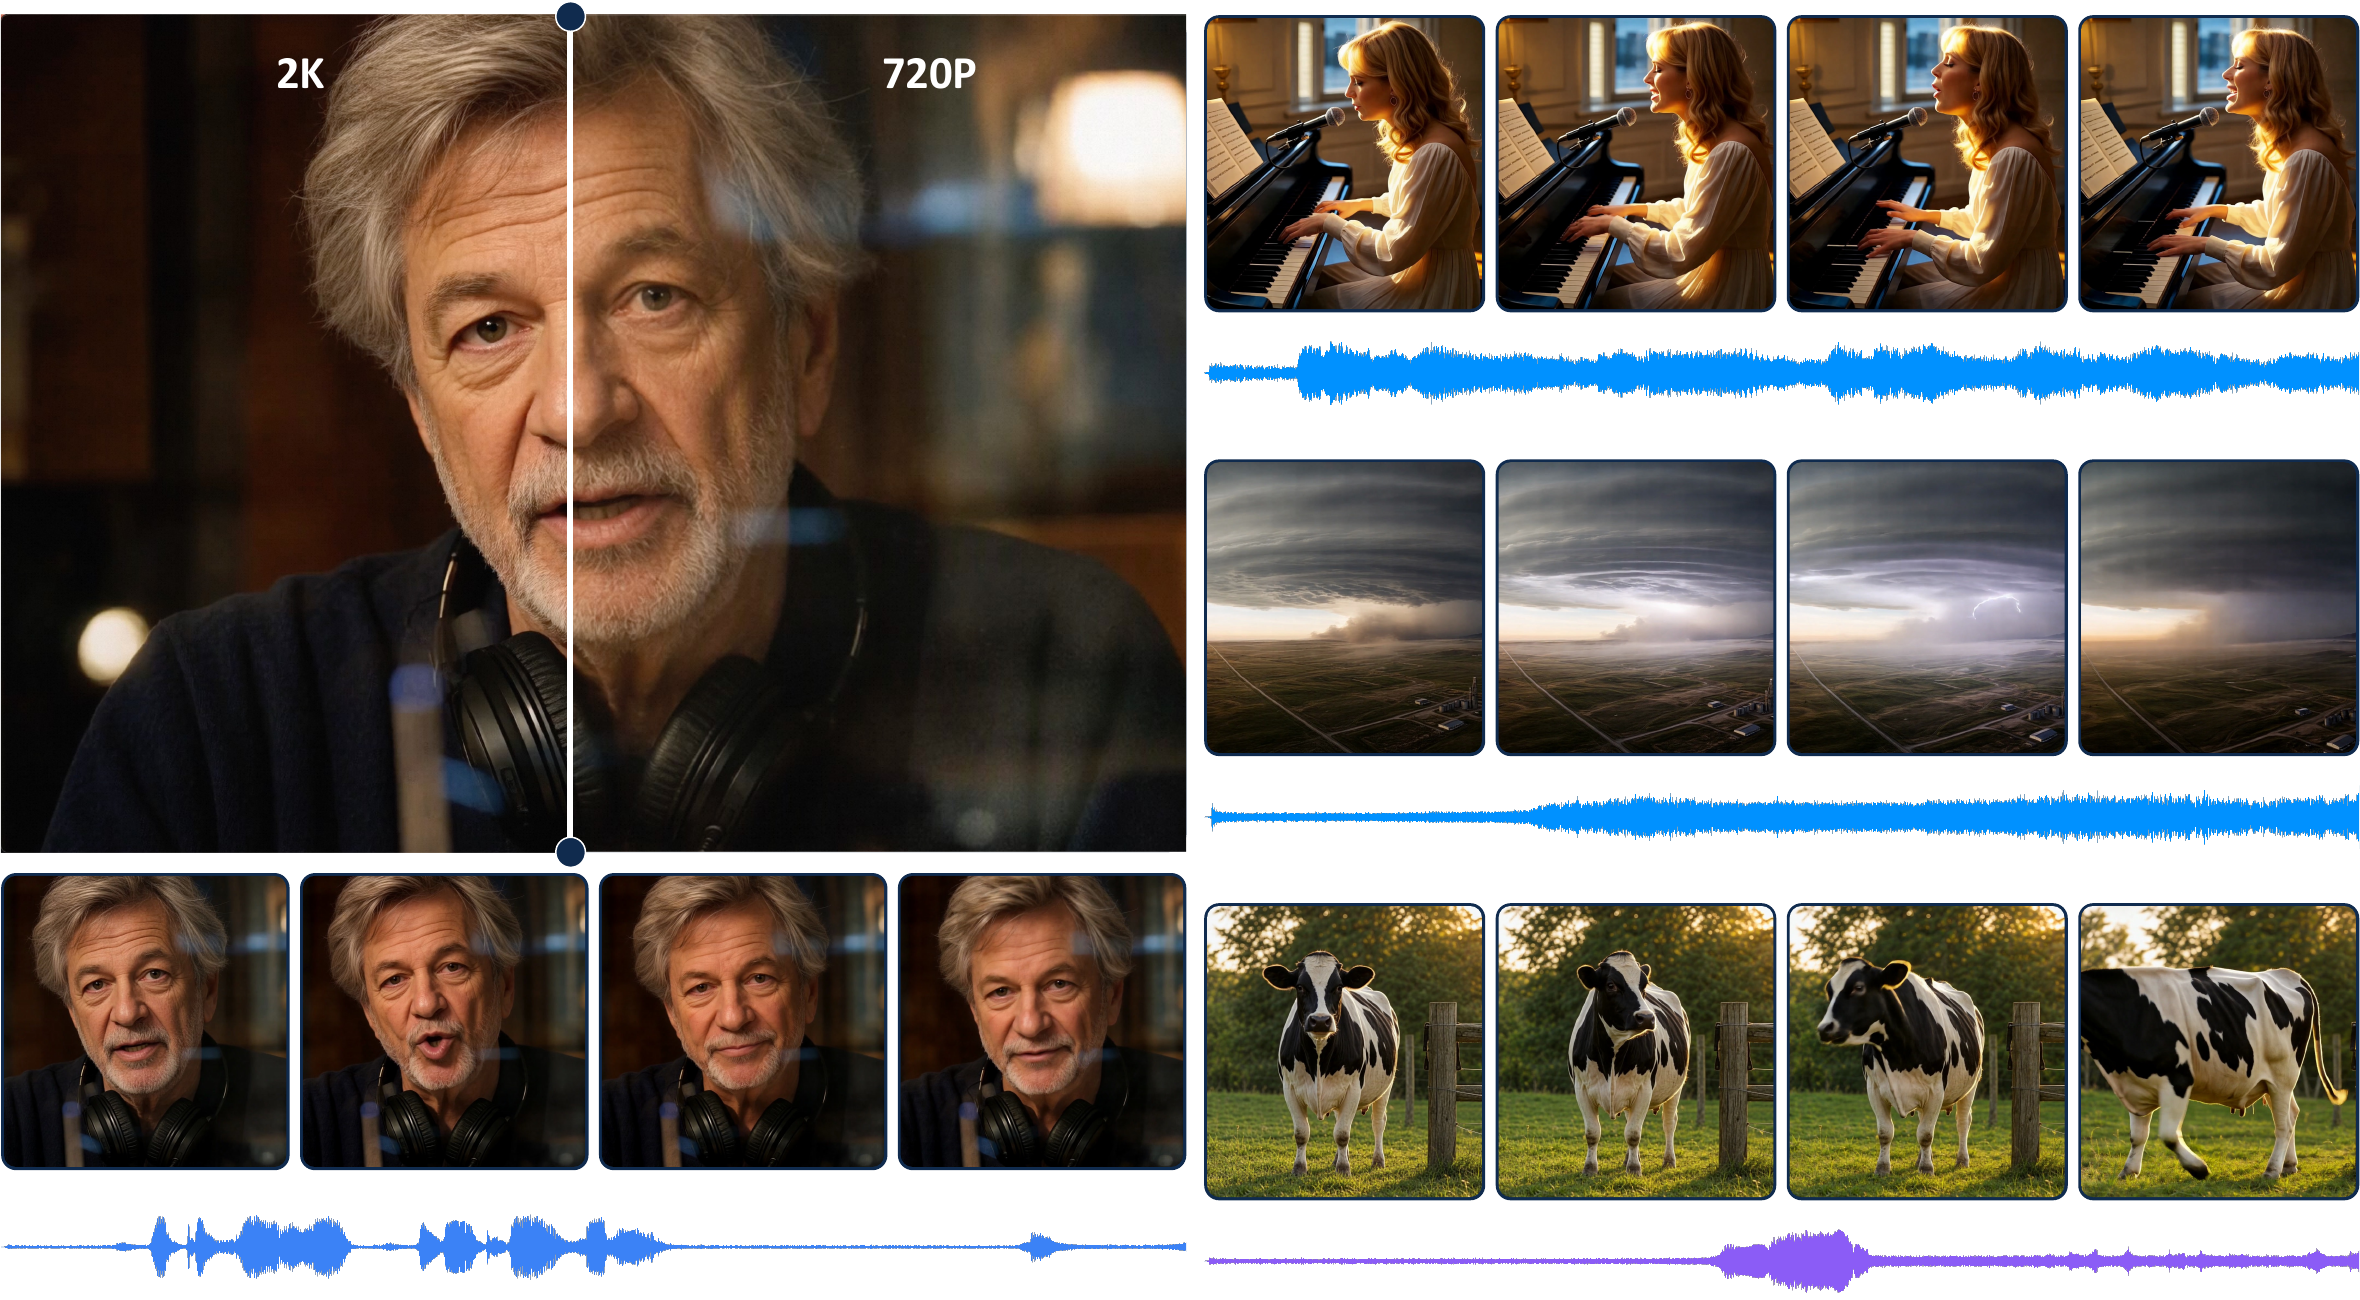
 DreamX-Creator is an open-source research framework for native joint audio-video generation: it produces video and a synchronized audio track together, refined up to 2K resolution.
What do you feed it, and what do you get back?You give it a first frame plus a text prompt; the 7B generator returns video with a matching audio track, and the SR-DiT 5B refiner then upgrades the result to high-quality 2K.
You give it a first frame plus a text prompt; the 7B generator returns video with a matching audio track, and the SR-DiT 5B refiner then upgrades the result to high-quality 2K.How do I get it running?Each component (audiovideogeneration/, videorefiner/) is a self-contained folder with its own requirements.txt and README: install that environment, download the weights into checkpoints/, then run its inference scripts.
Each component (audiovideogeneration/, videorefiner/) is a self-contained folder with its own requirements.txt and README: install that environment, download the weights into checkpoints/, then run its inference scripts.Which model weights do I need, and from where?From HuggingFace or ModelScope: the DreamX 7B audio-video generator, the SR-DiT 5B refiner, and Wan-AI/Wan2.2-TI2V-5B — all placed under checkpoints/ as its README describes.
From HuggingFace or ModelScope: the DreamX 7B audio-video generator, the SR-DiT 5B refiner, and Wan-AI/Wan2.2-TI2V-5B — all placed under checkpoints/ as its README describes.Is everything described in the technical report actually available?Only the inference side: released weights and code cover the 7B generator and the 1-step 2K refiner, while distilled, faster models with fewer sampling steps are still an unchecked roadmap item.
Only the inference side: released weights and code cover the 7B generator and the 1-step 2K refiner, while distilled, faster models with fewer sampling steps are still an unchecked roadmap item.Can I use it freely, including commercially?Yes — Apache 2.0 lets you use, modify and redistribute it, including in commercial work, as long as you keep the license.
Yes — Apache 2.0 lets you use, modify and redistribute it, including in commercial work, as long as you keep the license.Will it run on an ordinary machine, or do I need a serious GPU?The 7B generator is built to run on a single GPU, with CPU-offload and memory options for tighter setups and optional multi-GPU sequence-parallel inference for faster runs.
The 7B generator is built to run on a single GPU, with CPU-offload and memory options for tighter setups and optional multi-GPU sequence-parallel inference for faster runs.How does it keep audio and video in sync?The generator uses Gated Cross-Modal Attention with Progressive Joint Training for bidirectional audio-video interaction, and the broader pipeline adds audio-video reinforcement learning with modality-aware multimodal feedback to improve synchronization, consistency and quality.
The generator uses Gated Cross-Modal Attention with Progressive Joint Training for bidirectional audio-video interaction, and the broader pipeline adds audio-video reinforcement learning with modality-aware multimodal feedback to improve synchronization, consistency and quality.Why does it need a first frame instead of just a prompt?The released base generator is image-conditioned: your first frame anchors the scene while the prompt drives the motion and sound. The README does not mention a prompt-only mode.
The released base generator is image-conditioned: your first frame anchors the scene while the prompt drives the motion and sound. The README does not mention a prompt-only mode.Is this built on other open-source work?Yes — the team credits the Wan, OpenMOSS and VideoX-Fun teams and reuses Wan2.2-TI2V-5B weights; there is also a technical report you can cite if the framework helps your research.
Yes — the team credits the Wan, OpenMOSS and VideoX-Fun teams and reuses Wan2.2-TI2V-5B weights; there is also a technical report you can cite if the framework helps your research.What are similar projects?LTX-Video, hyperflow, DiffSynth-Studio, LTX-2, diffusers, Open-Sora, MiniMax-H3, CogVideo
LTX-Video, hyperflow, DiffSynth-Studio, LTX-2, diffusers, Open-Sora, MiniMax-H3, CogVideoWhich topics is it in?wan, super-resolution, diffusion, image-to-video, audio-generation, attention-mechanism, text-to-video, reinforcement-learning, multimodal, video-generation, audio, video
wan, super-resolution, diffusion, image-to-video, audio-generation, attention-mechanism, text-to-video, reinforcement-learning, multimodal, video-generation, audio, video