
External-Attention-pytorch README

The project's README from github.com/xmu-xiaoma666/External-Attention-pytorch. As one markdown file: README.md.

简体中文 | English

FightingCV 代码库, 包含 Attention,Backbone, MLP, Re-parameter, Convolution

🌟 Star History

Star History Chart

使用

安装

直接通过 pip 安装

pip install fightingcv-attention

或克隆该仓库

git clone https://github.com/xmu-xiaoma666/External-Attention-pytorch.git

cd External-Attention-pytorch

演示

使用 pip 方式

import torch
from torch import nn
from torch.nn import functional as F

# 使用 pip 方式

from fightingcv_attention.attention.MobileViTv2Attention import *

if __name__ == '__main__':
    input=torch.randn(50,49,512)
    sa = MobileViTv2Attention(d_model=512)
    output=sa(input)
    print(output.shape)

使用 git 方式

import torch
from torch import nn
from torch.nn import functional as F

# 与 pip方式 区别在于 将 `fightingcv_attention` 替换 `model`

from model.attention.MobileViTv2Attention import *

if __name__ == '__main__':
    input=torch.randn(50,49,512)
    sa = MobileViTv2Attention(d_model=512)
    output=sa(input)
    print(output.shape)

目录


Attention Series


1. External Attention Usage

1.1. Paper

"Beyond Self-attention: External Attention using Two Linear Layers for Visual Tasks"

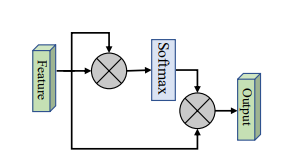
1.2. Overview

1.3. Usage Code

from model.attention.ExternalAttention import ExternalAttention
import torch

input=torch.randn(50,49,512)
ea = ExternalAttention(d_model=512,S=8)
output=ea(input)
print(output.shape)

2. Self Attention Usage

2.1. Paper

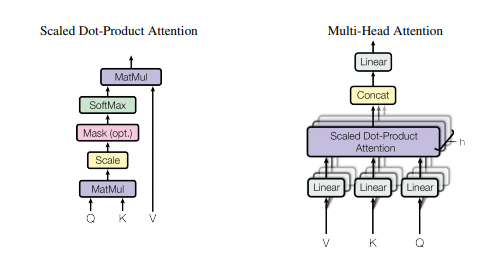
"Attention Is All You Need"

1.2. Overview

1.3. Usage Code

from model.attention.SelfAttention import ScaledDotProductAttention
import torch

input=torch.randn(50,49,512)
sa = ScaledDotProductAttention(d_model=512, d_k=512, d_v=512, h=8)
output=sa(input,input,input)
print(output.shape)

3. Simplified Self Attention Usage

3.1. Paper

None

3.2. Overview

3.3. Usage Code

from model.attention.SimplifiedSelfAttention import SimplifiedScaledDotProductAttention
import torch

input=torch.randn(50,49,512)
ssa = SimplifiedScaledDotProductAttention(d_model=512, h=8)
output=ssa(input,input,input)
print(output.shape)

4. Squeeze-and-Excitation Attention Usage

4.1. Paper

"Squeeze-and-Excitation Networks"

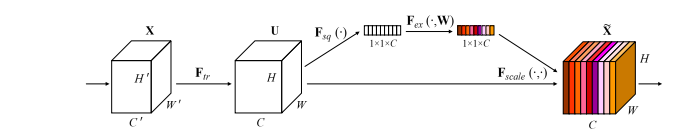
4.2. Overview

4.3. Usage Code

from model.attention.SEAttention import SEAttention
import torch

input=torch.randn(50,512,7,7)
se = SEAttention(channel=512,reduction=8)
output=se(input)
print(output.shape)

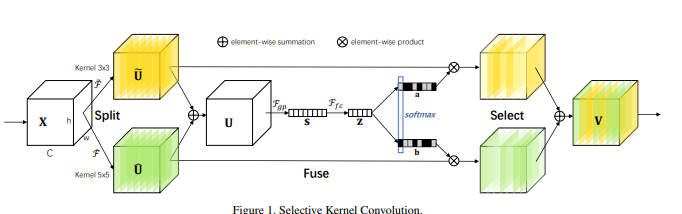
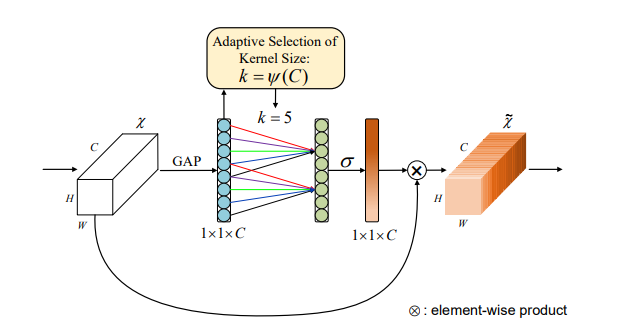
5. SK Attention Usage

5.1. Paper

"Selective Kernel Networks"

5.2. Overview

5.3. Usage Code

from model.attention.SKAttention import SKAttention
import torch

input=torch.randn(50,512,7,7)
se = SKAttention(channel=512,reduction=8)
output=se(input)
print(output.shape)

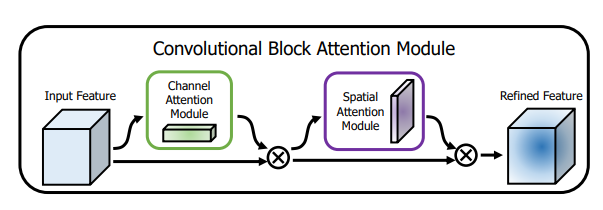
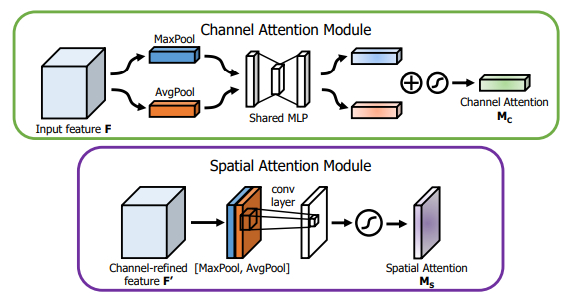
6. CBAM Attention Usage

6.1. Paper

"CBAM: Convolutional Block Attention Module"

6.2. Overview

6.3. Usage Code

from model.attention.CBAM import CBAMBlock
import torch

input=torch.randn(50,512,7,7)
kernel_size=input.shape[2]
cbam = CBAMBlock(channel=512,reduction=16,kernel_size=kernel_size)
output=cbam(input)
print(output.shape)

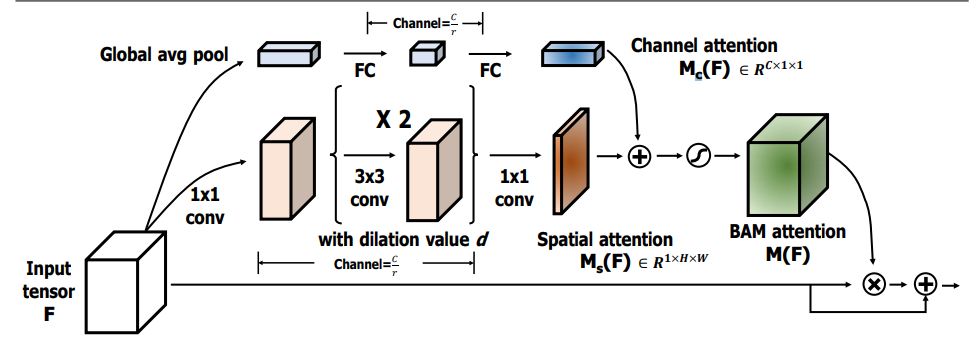
7. BAM Attention Usage

7.1. Paper

"BAM: Bottleneck Attention Module"

7.2. Overview

7.3. Usage Code

from model.attention.BAM import BAMBlock
import torch

input=torch.randn(50,512,7,7)
bam = BAMBlock(channel=512,reduction=16,dia_val=2)
output=bam(input)
print(output.shape)

8. ECA Attention Usage

8.1. Paper

"ECA-Net: Efficient Channel Attention for Deep Convolutional Neural Networks"

8.2. Overview

8.3. Usage Code

from model.attention.ECAAttention import ECAAttention
import torch

input=torch.randn(50,512,7,7)
eca = ECAAttention(kernel_size=3)
output=eca(input)
print(output.shape)

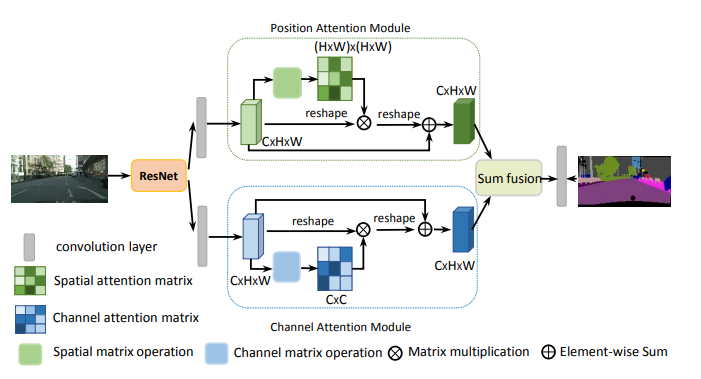
9. DANet Attention Usage

9.1. Paper

"Dual Attention Network for Scene Segmentation"

9.2. Overview

9.3. Usage Code

from model.attention.DANet import DAModule
import torch

input=torch.randn(50,512,7,7)
danet=DAModule(d_model=512,kernel_size=3,H=7,W=7)
print(danet(input).shape)

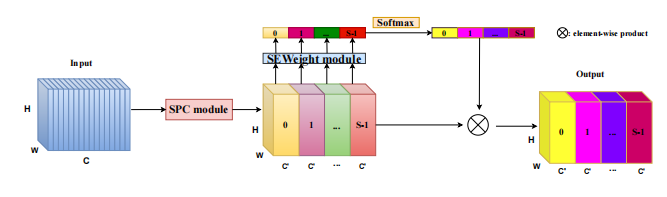
10. Pyramid Split Attention Usage

10.1. Paper

"EPSANet: An Efficient Pyramid Split Attention Block on Convolutional Neural Network"

10.2. Overview

10.3. Usage Code

from model.attention.PSA import PSA
import torch

input=torch.randn(50,512,7,7)
psa = PSA(channel=512,reduction=8)
output=psa(input)
print(output.shape)

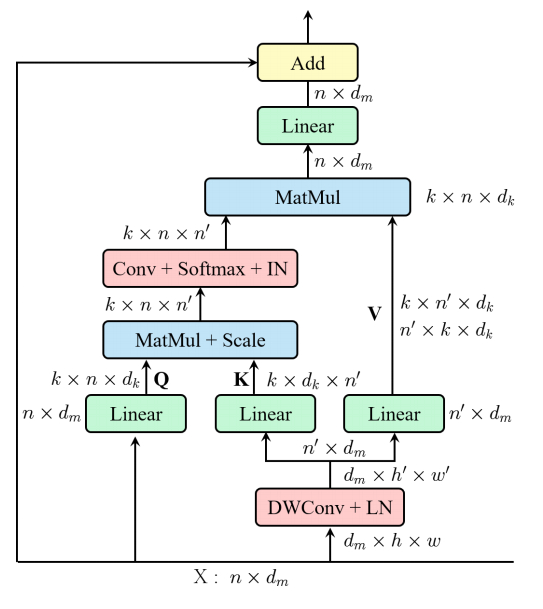
11. Efficient Multi-Head Self-Attention Usage

11.1. Paper

"ResT: An Efficient Transformer for Visual Recognition"

11.2. Overview

11.3. Usage Code


from model.attention.EMSA import EMSA
import torch
from torch import nn
from torch.nn import functional as F

input=torch.randn(50,64,512)
emsa = EMSA(d_model=512, d_k=512, d_v=512, h=8,H=8,W=8,ratio=2,apply_transform=True)
output=emsa(input,input,input)
print(output.shape)
    

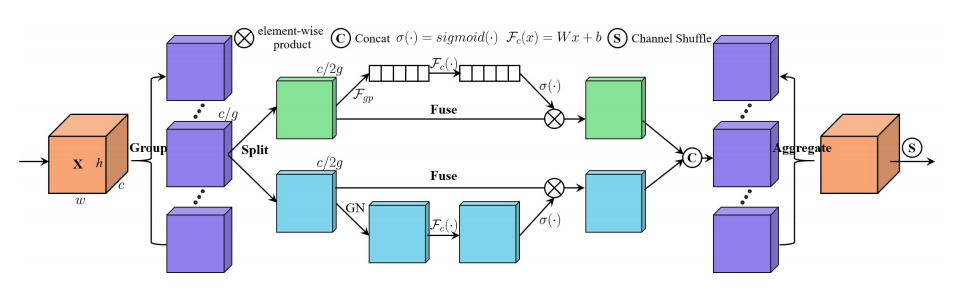
12. Shuffle Attention Usage

12.1. Paper

"SA-NET: SHUFFLE ATTENTION FOR DEEP CONVOLUTIONAL NEURAL NETWORKS"

12.2. Overview

12.3. Usage Code


from model.attention.ShuffleAttention import ShuffleAttention
import torch
from torch import nn
from torch.nn import functional as F


input=torch.randn(50,512,7,7)
se = ShuffleAttention(channel=512,G=8)
output=se(input)
print(output.shape)


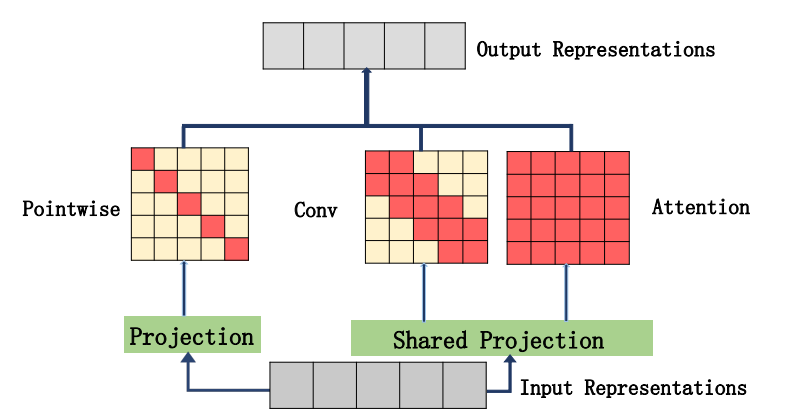
13. MUSE Attention Usage

13.1. Paper

"MUSE: Parallel Multi-Scale Attention for Sequence to Sequence Learning"

13.2. Overview

13.3. Usage Code

from model.attention.MUSEAttention import MUSEAttention
import torch
from torch import nn
from torch.nn import functional as F


input=torch.randn(50,49,512)
sa = MUSEAttention(d_model=512, d_k=512, d_v=512, h=8)
output=sa(input,input,input)
print(output.shape)

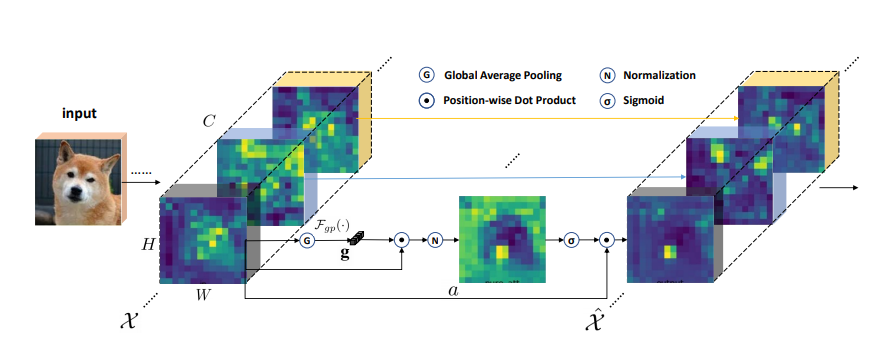
14. SGE Attention Usage

14.1. Paper

Spatial Group-wise Enhance: Improving Semantic Feature Learning in Convolutional Networks

14.2. Overview

14.3. Usage Code

from model.attention.SGE import SpatialGroupEnhance
import torch
from torch import nn
from torch.nn import functional as F

input=torch.randn(50,512,7,7)
sge = SpatialGroupEnhance(groups=8)
output=sge(input)
print(output.shape)

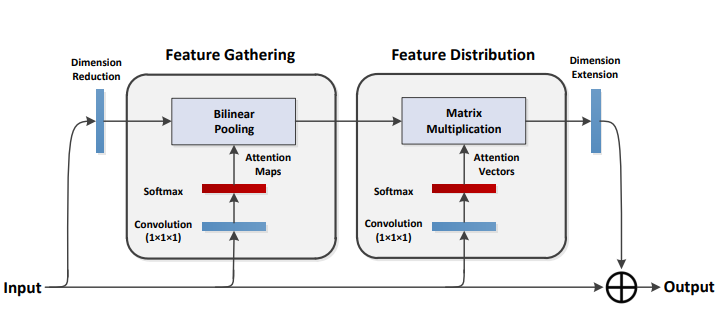
15. A2 Attention Usage

15.1. Paper

A2-Nets: Double Attention Networks

15.2. Overview

15.3. Usage Code

from model.attention.A2Atttention import DoubleAttention
import torch
from torch import nn
from torch.nn import functional as F

input=torch.randn(50,512,7,7)
a2 = DoubleAttention(512,128,128,True)
output=a2(input)
print(output.shape)

16. AFT Attention Usage

16.1. Paper

An Attention Free Transformer

16.2. Overview

![](./model/img/

External-Attention-pytorch (xmu-xiaoma666/External-Attention-pytorch)

Searching Database…

What is this?A PyTorch collection of Attention, Backbone, MLP, Re-parameter, and Convolution implementations from research papers, meant to help you understand papers by seeing their mechanisms coded up.
Is this a library I import, or just reference code?Both: it is pip-installable as a package (fightingcv-attention) and also works as a repo of standalone modules you copy into your own model code.
How do I start using a module from it?Install via pip or clone the repo, then import the specific attention/backbone/MLP class you need (e.g. External Attention, CBAM, SE) and call it like any nn.Module.
Do I need PyTorch to use this?Yes, every module is implemented as a PyTorch nn.Module, so you need PyTorch installed in your environment.
Is every module equally production-ready?Not stated explicitly, but the repo is organized purely as paper reimplementations for learning/reference, not a trained model zoo or benchmark suite — there are no pretrained weights or training scripts mentioned.
How many mechanisms are included?Dozens across four series: 37 Attention modules (e.g. External, Self, CBAM, SE, ECA, Shuffle), 25 Backbones (ResNet, PVT, DeiT, VOLO...), 6 MLP variants, 3 Re-parameter methods, and 5 Convolution variants.
What is CBAM in this repo?CBAM (Convolutional Block Attention Module) is one of the included attention implementations, reproducing the ECCV2018 paper that combines channel and spatial attention.
Can I use a module directly in my own model?Yes, each module is a self-contained PyTorch class with usage code shown in the README, so you can drop it straight into your own network architecture.
Is there a Chinese version of the docs?Yes, the README is available in both Simplified Chinese and English.
Size
5.6 MB
Stars
12.2K
Updated
CommitMar 16
Age
5y
Commits · 90 Days