
ESP32s3-LLM-Cluster README

The project's README from github.com/Low-Zi-Hong/ESP32s3-LLM-Cluster. As one markdown file: README.md.

ESP32s3-LLM-Cluster

A distributed pipeline inference engine on multiple ESP32S3 running 1.58-bit (BitNet) Language model.

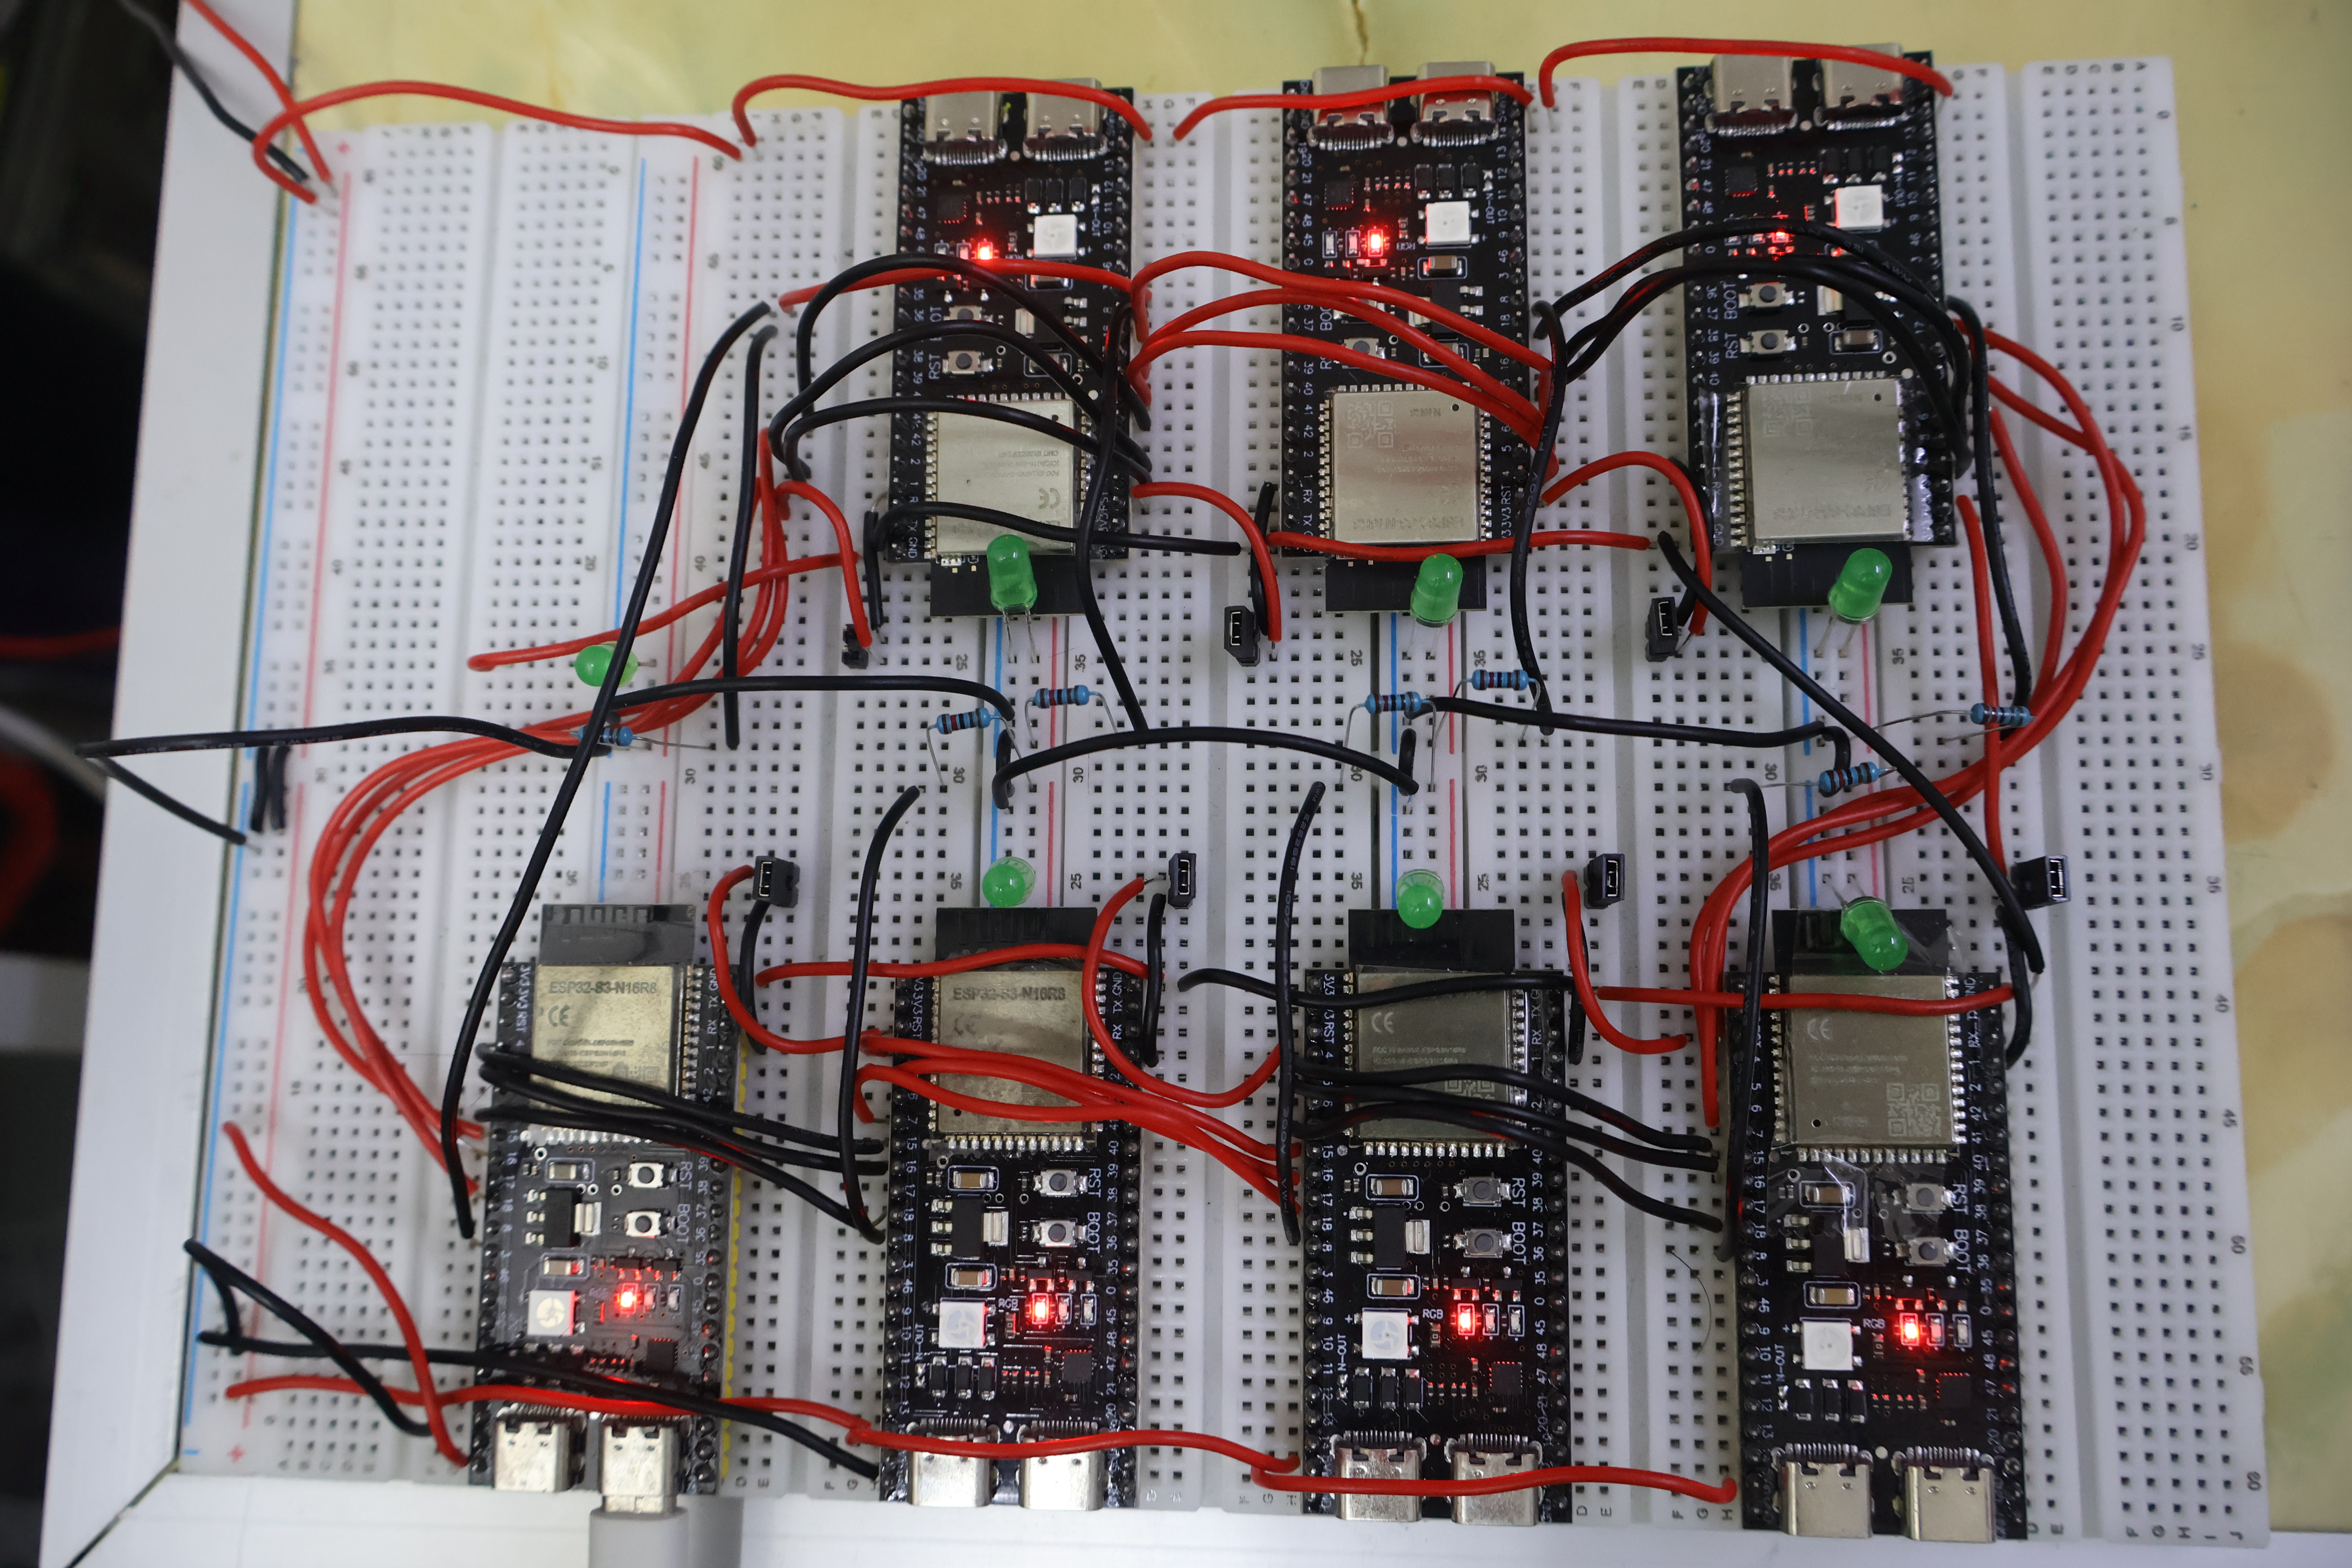
ESP32S3 boards

Architecture

This project runs a sliced 0.5B LLM across a cluster of 7 ESP32s3. One act as master and others are node. The master node runs the tokenizer and embeding and the other attention layer and MLP ran on the nodes. The master and node communicate through high speed SPI Daisy-Chain.

┌─────────────────────────────────────────────────────────┐
│                     MASTER NODE                         │
│                                                         │
│  [ Prompt ] ---> BPE Tokenizer                          │
│                       │                                 │
│                 Token Embedding                         │
│             (INT4, ~14MB in Flash)                      │
│                       │                                 │
│             (SPI CH A - TX to Node 1)                   │
└───────────────────────┬─────────────────────────────────┘
                        │ Hidden State Vector (FP32)
                        ▼
┌─────────────────────────────────────────────────────────┐
│                    COMPUTE NODE 1                       │
│             (SPI CH B - RX from Master)                 │
│                                                         │
│  ► Layer 0 to 3 (4x Transformer Blocks)                 │
│    • RMSNorm (FP16 scaled to FP32)                      │
│    • 1.58-bit Attention (Q, K, V, O proj) + RoPE        │
│    • KV Cache (PSRAM)                                   │
│    • 1.58-bit MLP (Gate, Up, Down proj)                 │
│                                                         │
│             (SPI CH A - TX to Node 2)                   │
└───────────────────────┬─────────────────────────────────┘
                        │
                       ... (Nodes 2 to 5)
                        │
                        ▼
┌─────────────────────────────────────────────────────────┐
│                    COMPUTE NODE 6                       │
│             (SPI CH B - RX from Node 5)                 │
│                                                         │
│  ► Layer 20 to 23 (4x Transformer Blocks)               │
│    • Same 1.58-bit Architecture                         │
│                                                         │
│             (SPI CH A - TX back to Master)              │
└───────────────────────┬─────────────────────────────────┘
                        │
                        ▼
┌─────────────────────────────────────────────────────────┐
│                     MASTER NODE                         │
│             (SPI CH B - RX from Node 6)                 │
│                                                         │
│                 Final RMS Norm                          │
│             (FP16, 64KB in 'fnorm' partition)           │
│                       │                                 │
│         LM Head (Tied to INT4 Embeddings)               │
│                       │                                 │
│               Greedy Sampling                           │
│                       │                                 │
│  [ Output ] <--- Next Token ID                          │
└─────────────────────────────────────────────────────────┘

Getting Started

pls refer workflow guide to start with the project.

Project Structure

.
├── README.md                   # Project documentation
├── workflow.md                 # Step-by-step flashing, model prep & wiring guide
├── .gitignore                  # Git ignore rules for build files & binaries
│
├── docs/                       
│   └── images/                 # Architecture diagrams and hardware photos
│
├── master_board/               # Firmware for the Master Node (ESP-IDF)
│   ├── main/
│   │   ├── main.cpp            # Master orchestrator, user I/O & BPE tokenizer
│   │   ├── embedding.cpp       # INT4 embedding lookup logic
│   │   ├── lm_head.cpp         # LM Head mapping and greedy sampling
│   │   └── spi_bus.cpp         # Master dual-channel SPI driver
│   ├── partitions.csv          # Custom partition table (token, model, fnorm)
│   └── CMakeLists.txt
│
├── node_firmware/              # Firmware for the Compute Nodes (ESP-IDF)
│   ├── main/
│   │   ├── main.cpp            # Node worker entry point & inference loop
│   │   ├── bitlinear.cpp       # 1.58-bit ternary linear layer implementation
│   │   ├── bitlinear_forward.S # Assembly optimized MAC ops for 1.58-bit
│   │   ├── qwen_attention.cpp  # Qwen Attention, RoPE & KV-Cache runtime
│   │   ├── lut_table.cpp       # Look-up tables for extreme optimization
│   │   └── spi_bus.cpp         # Daisy-chain SPI DMA receiver/transmitter
│   ├── partitions.csv          # Layer partition layout for Node
│   └── CMakeLists.txt
│
├── python_tools/               # PC-side quantization & preprocessing suite
    ├── crop_token.py           # Vocabulary pruning (scales down to 32K tokens)
    ├── crop_model_weight.py    # Embedding matrix slicing
    ├── qat_158.py              # BitNet QAT (Quantization-Aware Training) fine-tuning
    ├── bit4_embedding.py       # INT4 weight packer for embeddings
    ├── pack_tokenizer_bin.py   # Serializes tokenizer rules into ESP32 .bin
    ├── pack_model_bin.py       # Packs 1.58-bit layer chunks for physical alignment
    ├── look_model_structure.py # Debug tool for inspecting .safetensors
    └── flash_*.bat             # Multi-threaded fast flashing scripts

License

This project is licensed under the MIT License - see the LICENSE file for details.

Acknowledgments

Inspiration, related works, and references:

ESP32s3-LLM-Cluster (Low-Zi-Hong/ESP32s3-LLM-Cluster)

Searching Database…

What is this?This project is a distributed inference engine that runs a 0.5B-parameter LLM, quantized to 1.58-bit (BitNet) ternary weights, split across a cluster of 7 ESP32-S3 microcontrollers connected via SPI.
Is this a single ESP32-S3 device or a multi-board cluster?It's a 7-board hardware cluster, not a single chip: one ESP32-S3 acts as the master running the tokenizer and embedding step, while the other six run the attention and MLP layers of the model.
How do I get this running?The README only points to a separate workflow guide for setup; it doesn't include step-by-step build or flashing instructions itself.
What hardware do I need to build this?You need 7 physical ESP32-S3 boards wired together in an SPI daisy-chain, plus a pre-quantized BitNet (1.58-bit ternary) model to load onto the master and node boards.
How mature is this project — is there a tested build guide?The README itself is sparse, with an empty 'Project Structure' section, and defers actual setup to an external workflow guide, so expect to do real assembly and wiring work rather than follow a polished quick-start.
Why split the model across 7 boards instead of one ESP32-S3?Dividing the tokenizer/embedding (master) from the attention and MLP layers (nodes) lets the cluster run a model whose memory and compute needs exceed what a single ESP32-S3 can handle on its own.
What is BitNet 1.58-bit quantization?BitNet restricts model weights to ternary values (-1, 0, 1), shrinking the memory footprint dramatically so an LLM can realistically fit on microcontroller-class hardware like the ESP32-S3.
What inspired this project?The author credits 'ESP-32-s3-Story-maker-LLM' for single-node quantized LLM deployment on ESP32-S3 and 'esp32s3-distributed-ai' for multi-node distributed AI architecture, combining both ideas with BitNet quantization.
Size
8.6 MB
Stars
239
Updated
CommitOct 08
Age
2mo
Commits · 90 Days