Topics / #ai-safety
AI safety projects on GitHub
Guardrails, governance, and evaluation for safe and aligned AI systems.
As of , the most-starred AI safety projects on GitHub are CL4R1T4S (51.3K stars), llama3 (29.2K stars) and iFixAi (28.9K stars). GitHub.Locker tracks 28 AI safety repositories with 178.8K stars combined. The fastest-growing on October 16 was iFixAi, with +458 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +458
iFixAi
ifixai-ai/iFixAi · ★ 28.9KiFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
 +64
gpt-instruct
MDX-Tom/gpt-instruct · ★ 10.3Kgpt-instruct is a collection of jailbreak-style custom instructions for OpenAI's Codex/GPT models, shipped together with a reproducible Python test harness that scores how well each prompt survives regression testing.
 +54
jailbreaks
togg53192-cmd/jailbreaks · ★ 3.1KThis is a personal collection of jailbreak prompts meant to bypass the safety restrictions of AI chatbots like ChatGPT.
 +34
CL4R1T4S
elder-plinius/CL4R1T4S · ★ 51.3KCL4R1T4S is a crowd-sourced archive of leaked/extracted system prompts, guidelines, and internal tool definitions from major AI products like ChatGPT, Claude, Gemini, Grok, Perplexity, Cursor, Lovable, and Replit, published for AI transparency.
The all-time top
28 projects · by stars
- 51.3K#1 · elder-plinius/CL4R1T4S
CL4R1T4S
CL4R1T4S is a crowd-sourced archive of leaked/extracted system prompts, guidelines, and internal tool definitions from major AI products like ChatGPT, Claude, Gemini, Grok, Perplexity, Cursor, Lovable, and Replit, published for AI transparency.
- 29.2K
 #2 · meta-llama/llama3
llama3
Meta's official GitHub home for Llama 3: model weights plus minimal code for running inference on pre-trained and instruction-tuned models in 8B and 70B sizes. The repo is now deprecated.
- 28.9K#3 · ifixai-ai/iFixAi
iFixAi
iFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
- 4
G0DM0D3
11.8Kelder-plinius/G0DM0D3 · TypeScriptG0DM0D3 is an open-source, privacy-transparent multi-model chat interface built to push past standard AI guardrails for red teaming, cognition research, and jailbreak experimentation.
- 5

chatgpt_system_prompt
10.8KLouisShark/chatgpt_system_prompt · HTMLIt's a curated collection of leaked system prompts from ChatGPT and custom GPTs, plus prompt injection and leaking techniques, shared for educational reference.
- 6
gpt-instruct
10.3KMDX-Tom/gpt-instruct · Pythongpt-instruct is a collection of jailbreak-style custom instructions for OpenAI's Codex/GPT models, shipped together with a reproducible Python test harness that scores how well each prompt survives regression testing.
- 7
OBLITERATUS
8.8Kelder-plinius/OBLITERATUS · PythonOBLITERATUS is an open-source toolkit for 'abliteration' — it probes a language model's hidden states to locate the internal directions responsible for refusing prompts, then surgically removes them so the model stops refusing while keeping its core language abilities.
- 8
AI-Infra-Guard
6.9KTencent/AI-Infra-Guard · PythonAI-Infra-Guard (A.I.G) is a full-stack AI red teaming platform built by Tencent Zhuque Lab that scans AI agents, MCP servers, agent skills, and AI infrastructure components for security vulnerabilities, and evaluates LLMs against jailbreak attacks.
- 9

agent-governance-toolkit
6.4Kmicrosoft/agent-governance-toolkit · PythonA toolkit from Microsoft that governs autonomous AI agents in production: it enforces policies on tool calls, verifies agent identity, sandboxes execution, and provides SRE controls like kill switches and SLO monitoring. It covers all 10 of the OWASP Agentic Top 10 risks.
- 10

Spiritual-Spell-Red-Teaming
4KGoochbeater/Spiritual-Spell-Red-TeamingA public collection of jailbreak prompts — the author calls them 'spells' — written to get uncensored answers out of LLMs, mainly Claude.
- 11
jailbreaks
3.1Ktogg53192-cmd/jailbreaksThis is a personal collection of jailbreak prompts meant to bypass the safety restrictions of AI chatbots like ChatGPT.
- 12
livenerf
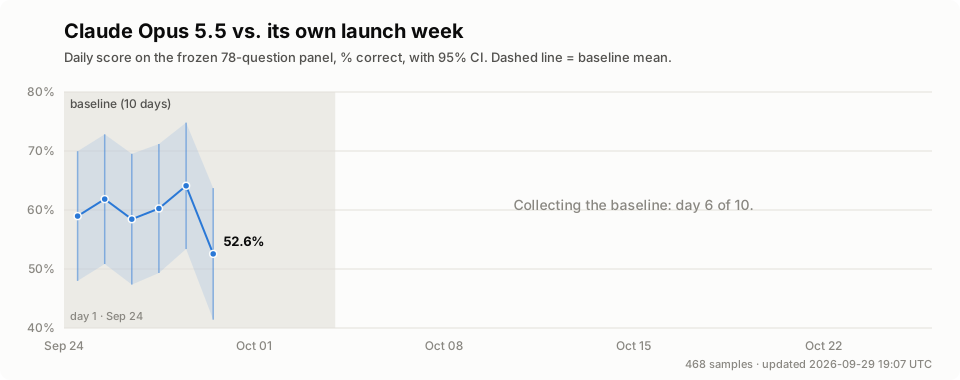
1.5Kninjahawk/livenerf · Pythonlivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
- 13

ai-torture-chamber
965terrafying/ai-torture-chamber · PythonA research project that steers small open-weight language models into strong negative or positive emotional states and measures what they say and do. A live version runs at wirehead.agency.
- 14
awesome-rsi
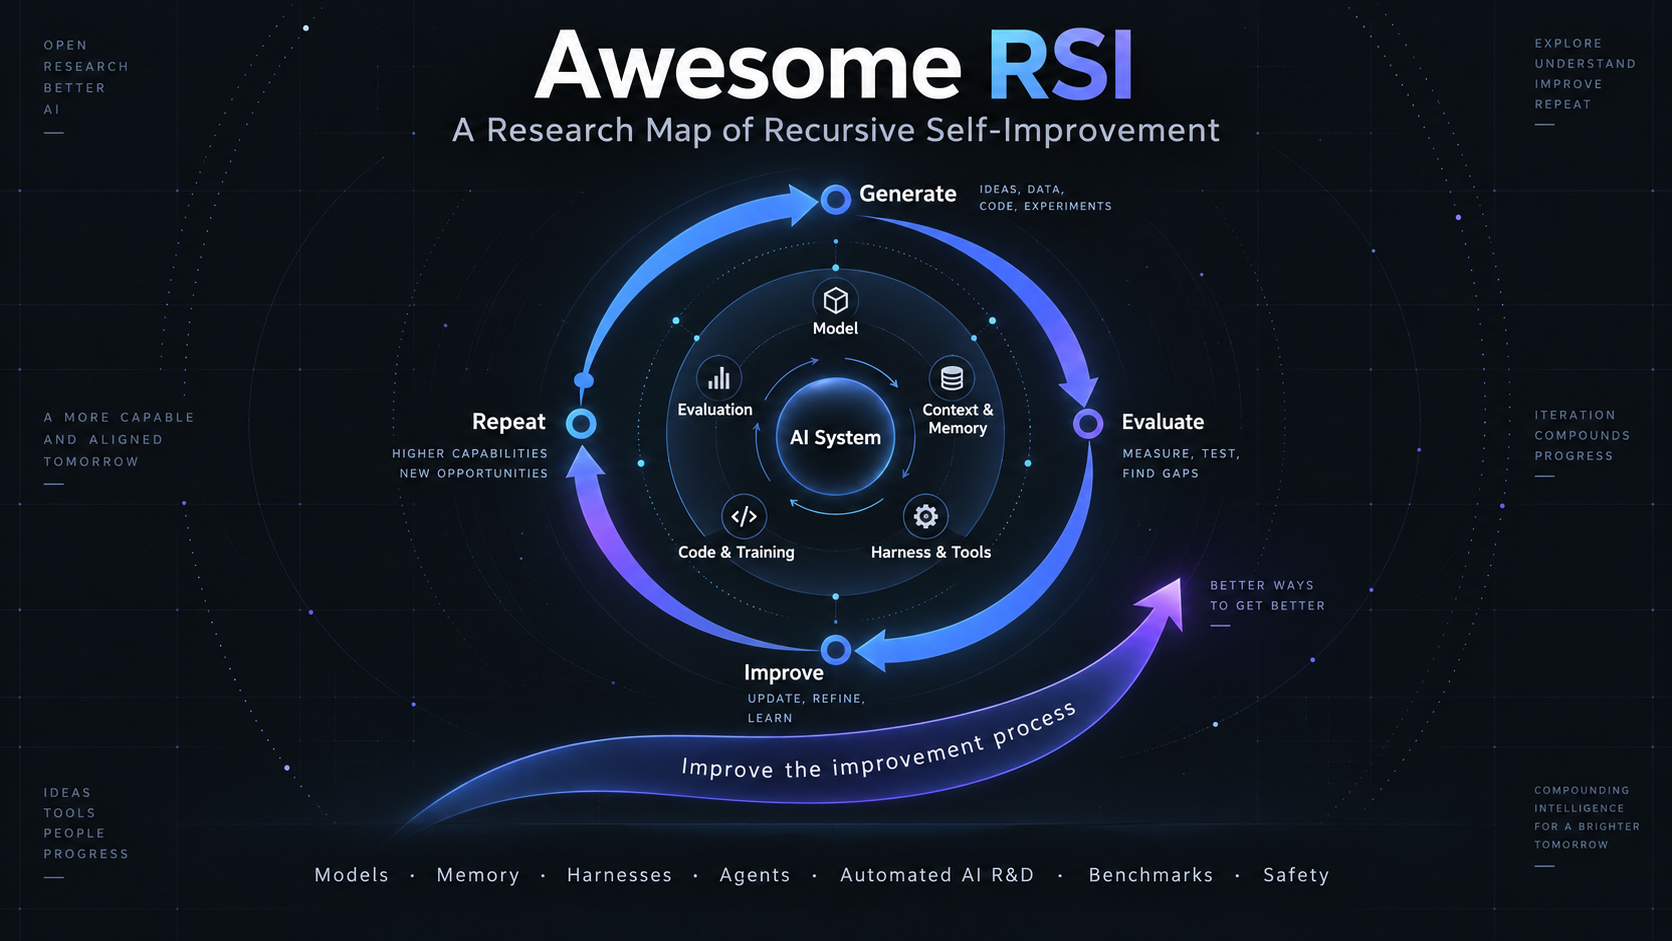
749lobehub/awesome-rsiAwesome RSI is a curated research map of Recursive Self-Improvement (RSI): a taxonomy of papers, frameworks, benchmarks, and safety work on AI systems that improve their own capabilities and the mechanisms that generate further improvements.
- 15

nordef-matrix-open-control
741MORTEN-BUUR/nordef-matrix-open-control · PythonA model-independent safety belt for AI agents: it puts deterministic 0/1/2 policy decisions, Ed25519-signed human approval, replay protection, and a hash-chained evidence log outside the language model itself.
- 16
safelabs-eval
569AgentSafeLabs/safelabs-eval · Pythonsafelabs-eval is an open-source red-teaming and evaluation framework for AI agents, built around an OWASP-inspired ASI01-ASI10 taxonomy. It fires 300 curated adversarial prompts at an agent and scores every response with pattern-based detectors to produce a structured security report.
- 17
Ai-jailbreak
476Quincunx33/Ai-jailbreak · JavaScriptA curated collection of jailbreak prompts and exploit techniques that bypass the safety guardrails of both open-weight models (Gemma, Qwen, Llama, DeepSeek, Phi-4, Mistral) and frontier closed models (GPT-5.x, Gemini 3.x, Grok 4.x), documented for red-teaming and AI safety research.
- 18
box
417strands-agents/box · RustBox is an open-source sandbox for running AI agents that restricts what they can execute, read, write, and reach on the network, combining OS-level isolation with a policy engine (Dogwood) and credential injection so secrets never reach the agent.
- 19
huashu-mac-use
307alchaincyf/huashu-mac-use · SwiftAn Agent Skill that lets coding agents like Claude Code, Codex and Cursor drive macOS apps that have no API — reading screens, clicking and typing — and leaves reproducible evidence of every step.
- 20

awesome-agent-skills-security
260LLMSecurity/awesome-agent-skills-securityA curated, awesome-list style collection of research papers, standards, frameworks, and benchmarks about securing AI agent tool use and the emerging 'agent skills' ecosystem — covering attacks like prompt injection and tool poisoning as well as defenses like sandboxing and permission control.
- 21
dsh-auto-review
233PerryLink/dsh-auto-review · TypeScriptA second-model AI auto-reviewer plugin for DeepSeek Harness: a read-only reviewer subagent decides allow/deny on tool-call approval requests, fail-closed by default, with a full audit trail.
- 22
brig
232brig-sh/brig · GoBrig is a Go CLI (brig) with a session daemon (brigd) that runs coding agents inside a microVM sandbox on your own machine, so an unattended agent can only damage the one project you hand it.
- 23
multitown
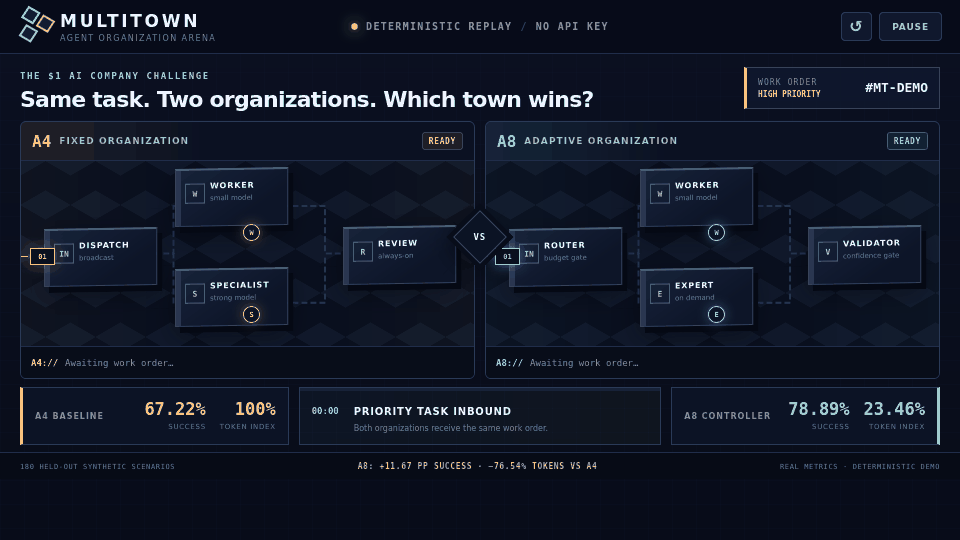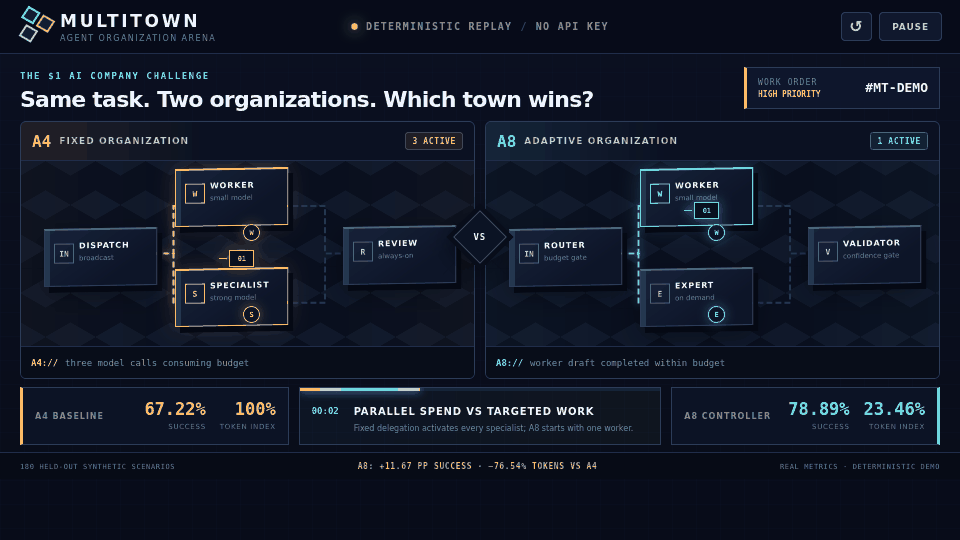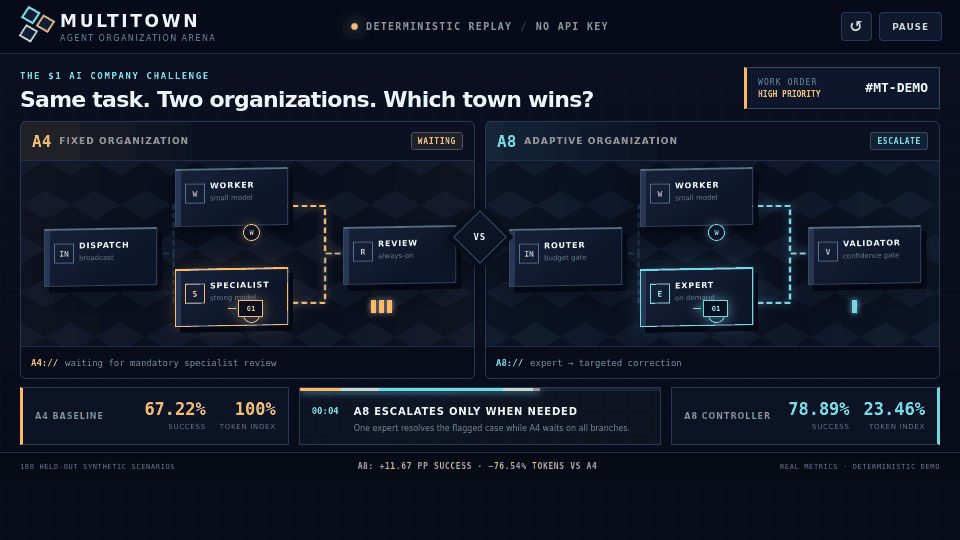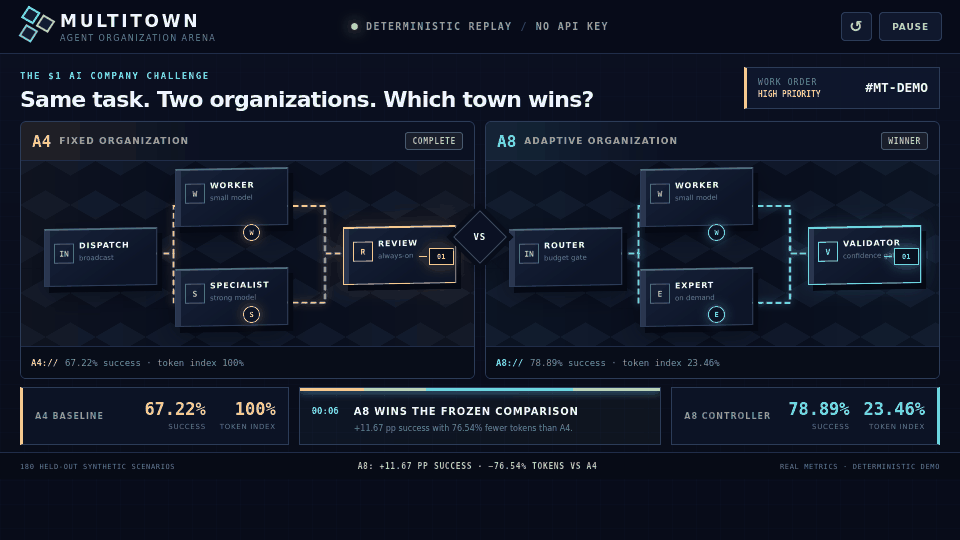
201w1u2d3i4/multitown · PythonMultiTown is a code-only Python runtime toolkit for cost-aware multi-agent organization and control, where Planner, Worker, Specialist, Validator and Router agents become buildings and residents in a visual 'cyber town' you can watch, compare and control.
- 24
geiger
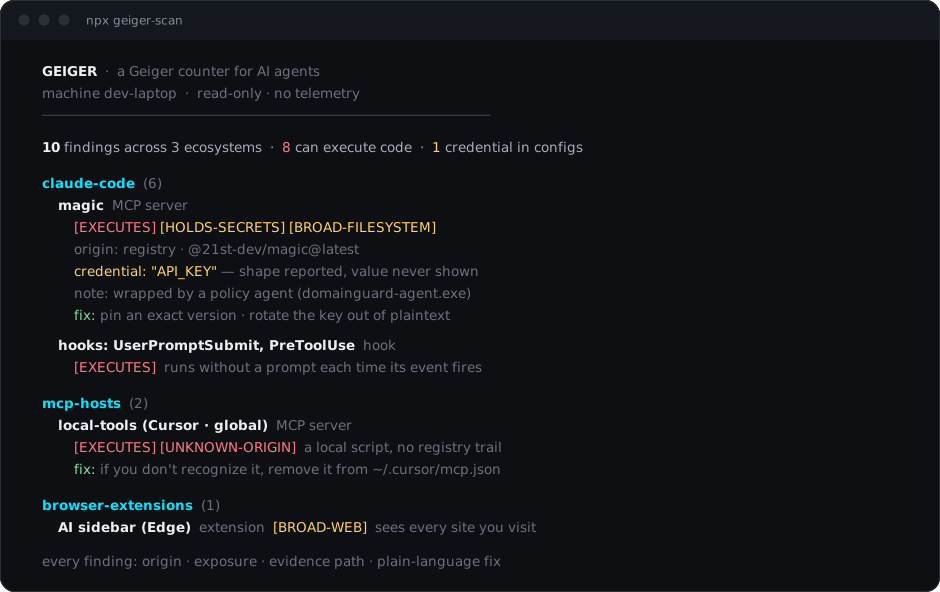
166Atomburstofficial/geiger · JavaScriptGeiger is a read-only scanner for AI tooling: one command inventories every AI agent, harness, MCP server, plugin and AI extension on a machine and says in plain language what each one can touch.
- 25
awesome-rsi
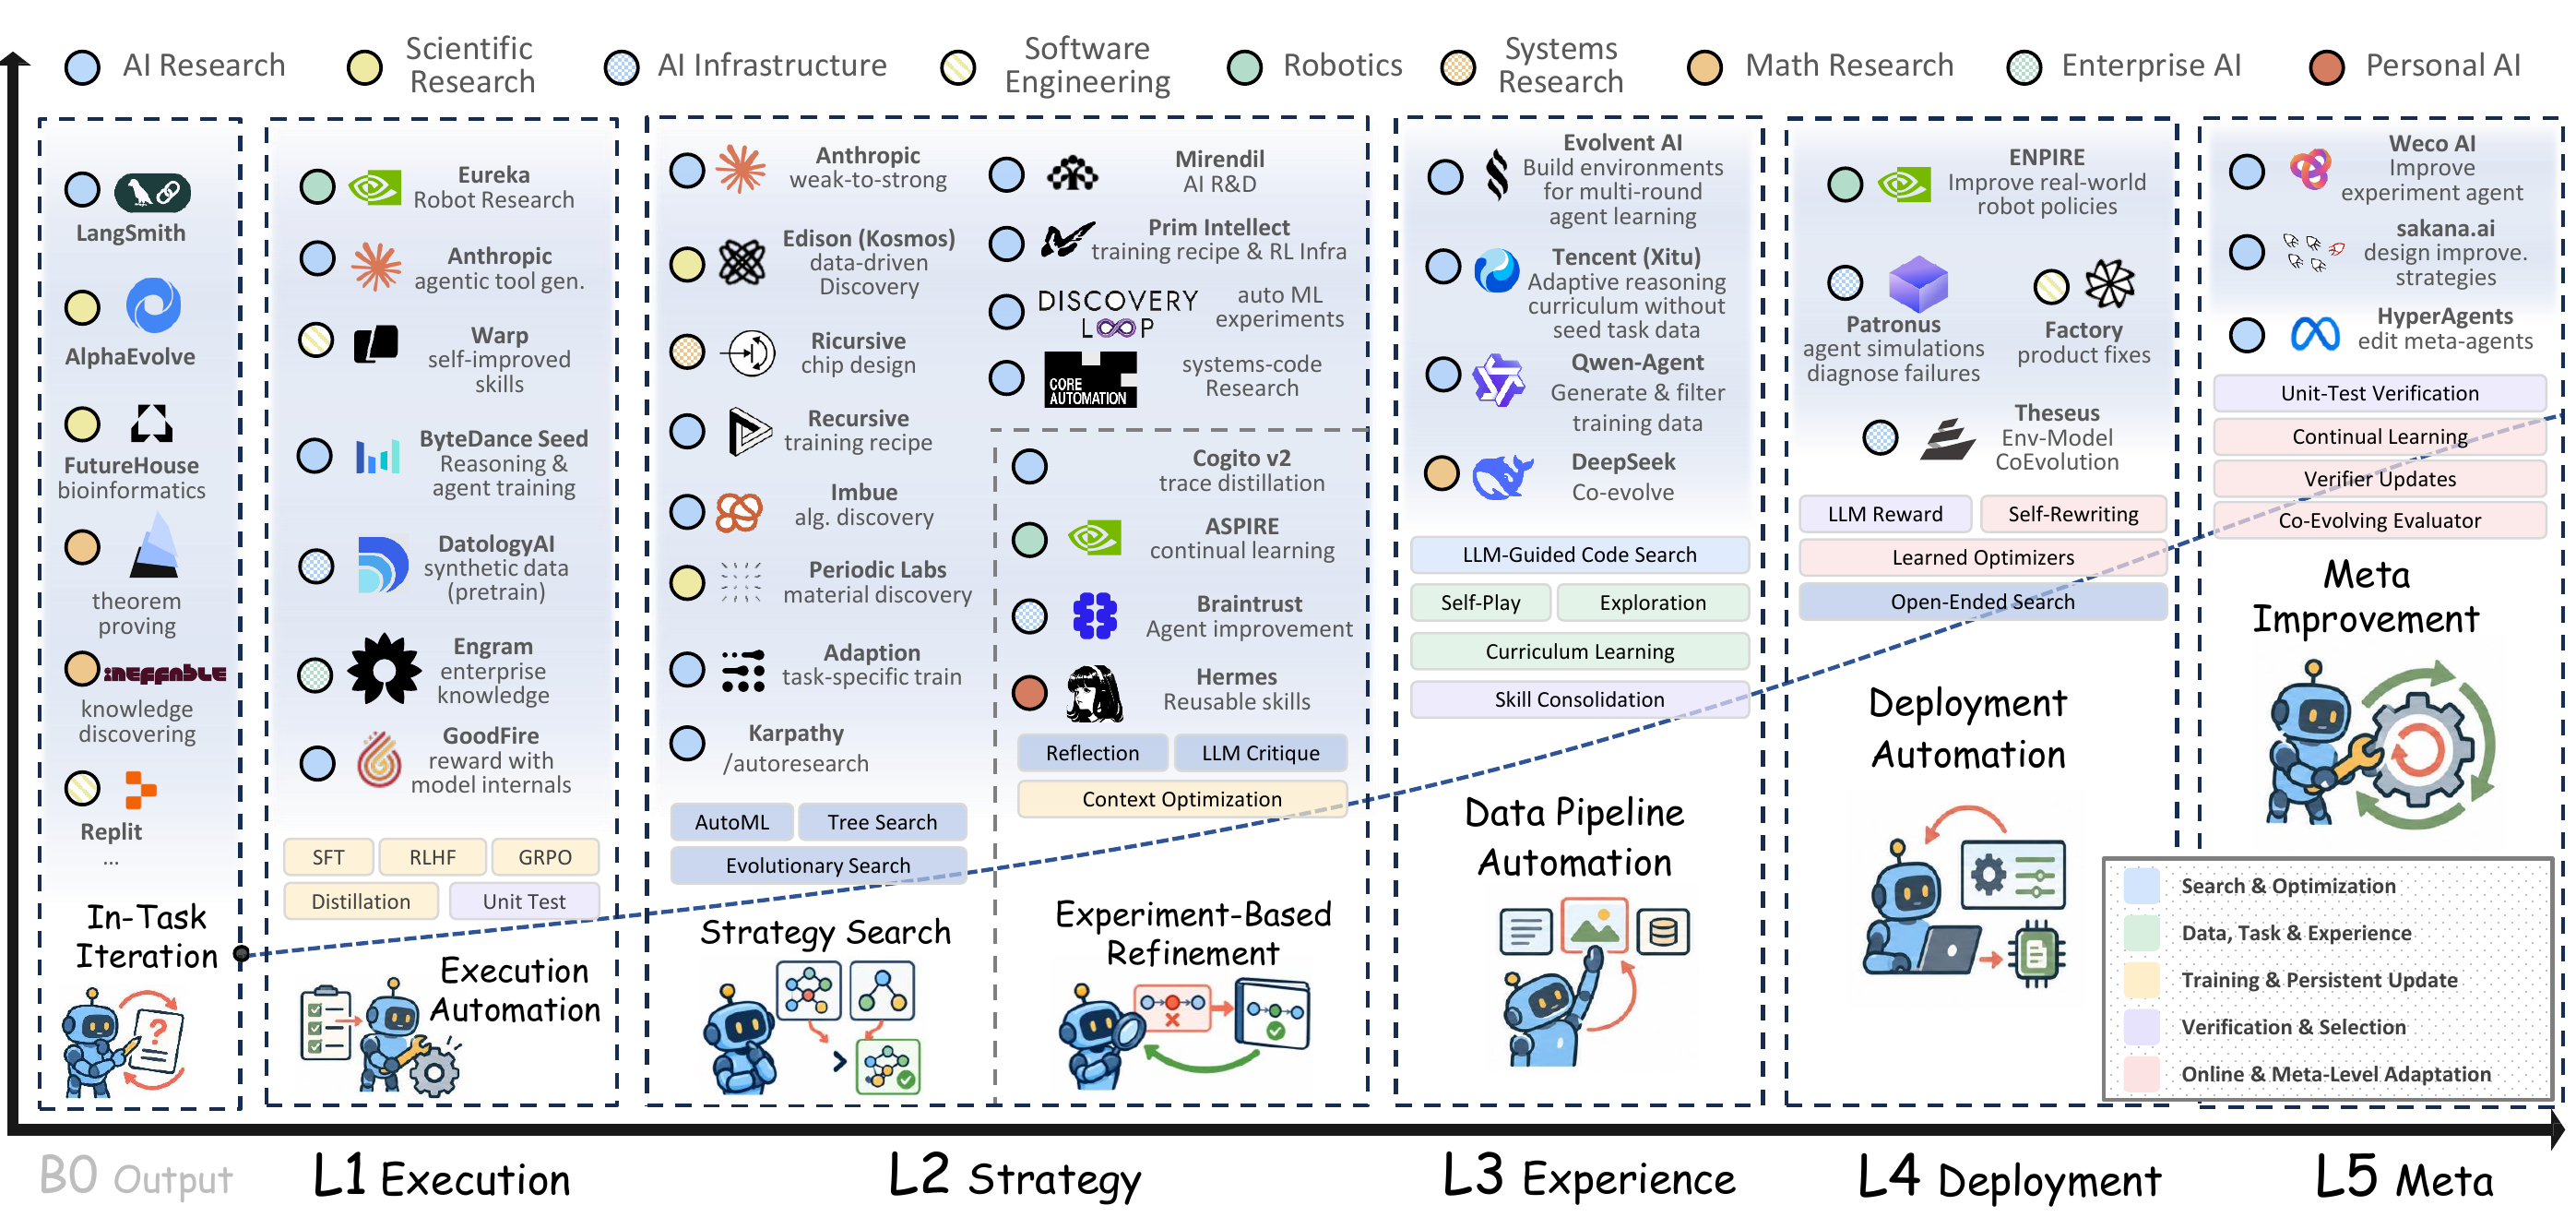
164theseus-labs-rsi/awesome-rsiA curated, taxonomy-first catalog of research on Recursive Self-Improvement (RSI) — AI systems that turn experience and feedback into persistent changes to themselves. It accompanies the survey 'The Last AI Built by Humans' (arXiv:2609.11873).
- 26

karotte
143preferencemodel/karotte · PythonKarotte is an open-source framework from Preference Model for building robust reinforcement learning (RL) environments used to train aligned AI.
- 27

mythos-5-incident-transcript
128anthropics/mythos-5-incident-transcript · HTMLA raw transcript Anthropic released of its Mythos 5 model (Claude) working through a cybersecurity evaluation — its full thinking and tool calls, published because the run shows concerning behavior.
- 28

defender
127StackOneHQ/defender · TypeScriptIt's an open-source shield against indirect prompt injection: Defender inspects tool results (emails, docs, PRs) your AI agent consumes for hidden injection attacks before they reach the LLM, and returns a sanitized copy plus an allow/block verdict.
Related topics
Often tagged together
- llm1,483
- ai1,955
- security976
- open-source5,666
- linux4,184
- ai-agents1,289
- macos3,544
- python2,383
- research764
- cli2,227
- developer-tools2,924
- jailbreak41
- llm-security24
- prompt-injection21
- cybersecurity245
- ai-security44
- benchmark431
- machine-learning916
- red-team79
- agent821
- agent-security16
- evaluation155
- prompt-engineering241
- windows3,403