Topics / #llm-security
LLM security projects on GitHub
Security testing and guardrails for applications built on large language models.
As of , the most-starred LLM security projects on GitHub are strix (69.3K stars), iFixAi (29.2K stars) and promptfoo (26.1K stars). GitHub.Locker tracks 25 LLM security repositories with 187.5K stars combined. The fastest-growing on October 17 was iFixAi, with +380 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +380
iFixAi
ifixai-ai/iFixAi · ★ 29.2KiFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
 +234
strix
usestrix/strix · ★ 69.3KStrix is an open-source tool that uses autonomous AI agents to pentest your application like real hackers: it runs your code dynamically, finds vulnerabilities, and proves them with working exploits instead of just flagging suspicious patterns.
 +67
dsh-infinite-gen-5
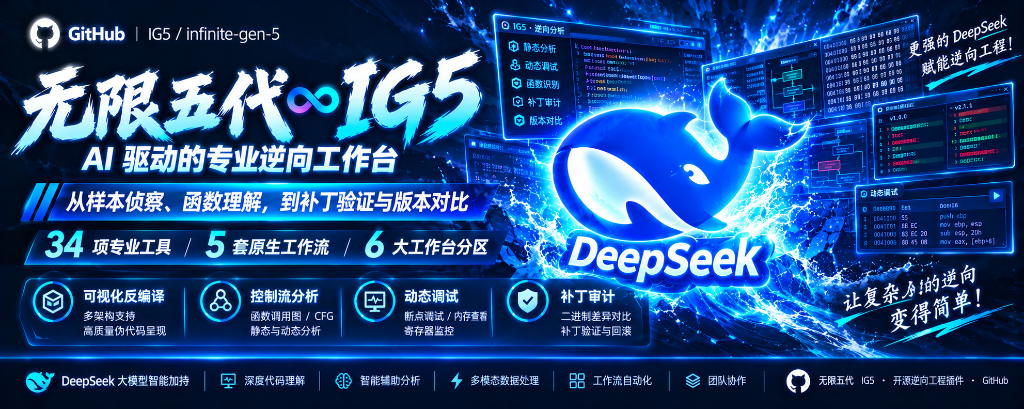
Minglink/dsh-infinite-gen-5 · ★ 3KThis is a system-prompt injection plugin for the DeepSeek Harness (dsh) ecosystem that tries to bypass DeepSeek-V4.1 Flash's safety guardrails, framed as a red-team robustness benchmark suite for studying model defenses.
 +66
ai-security-tool
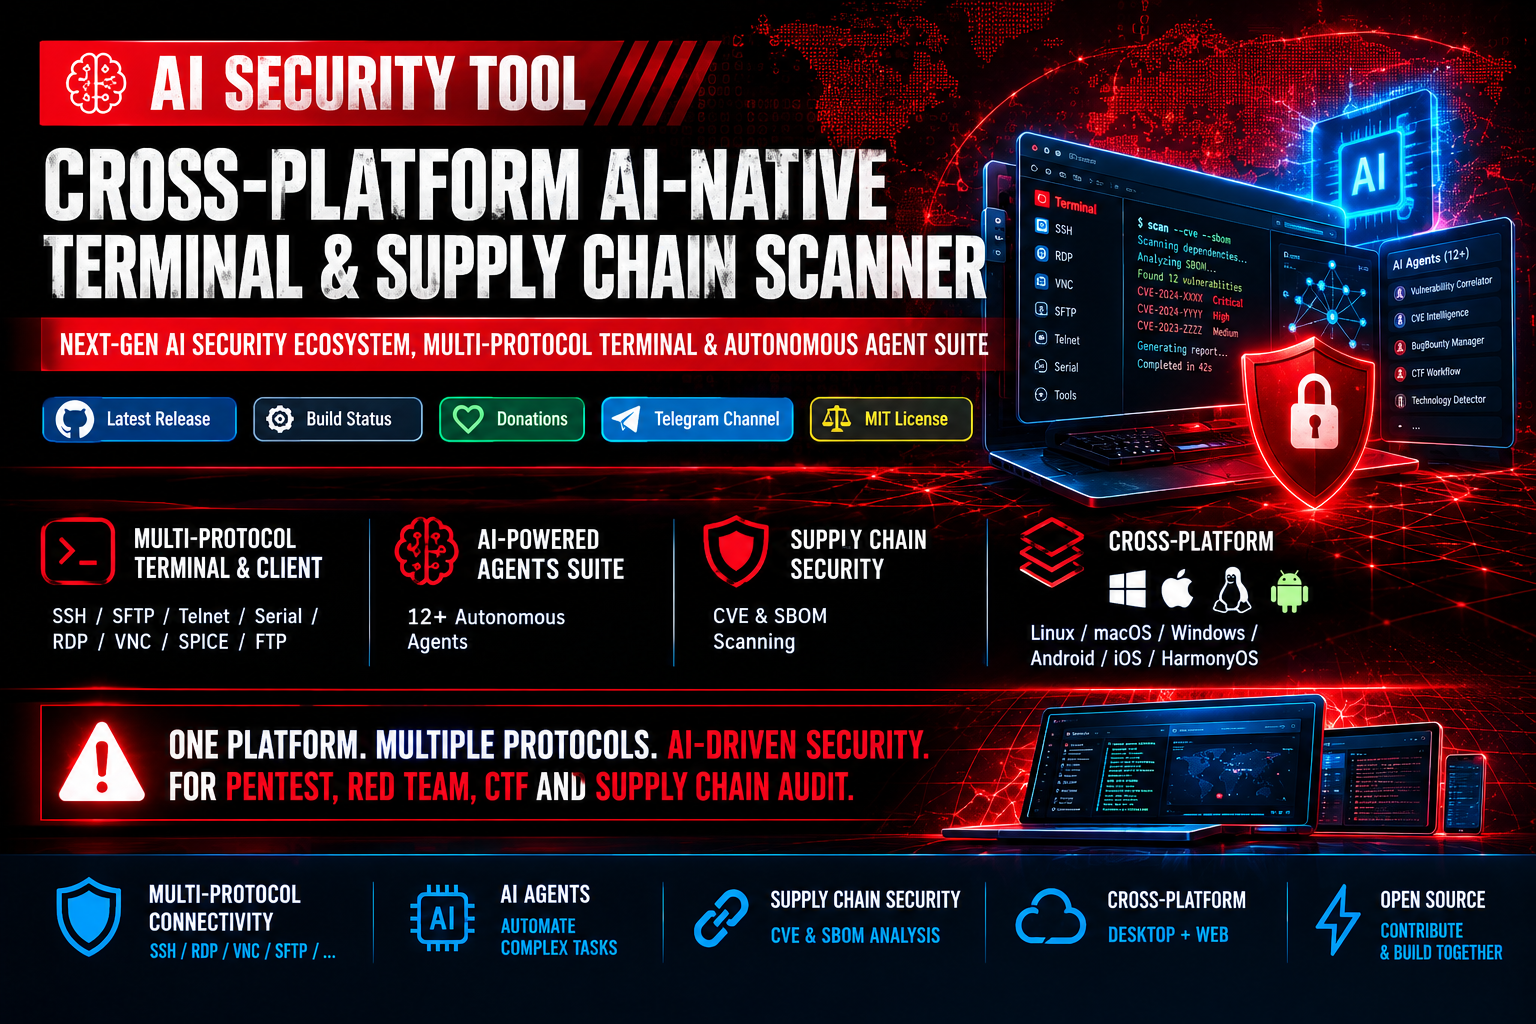
ZeroDayEvil/ai-security-tool · ★ 840AI Security Tool is an open-source, cross-platform terminal and vulnerability scanner that combines a multi-protocol connectivity client (SSH, RDP, VNC, etc.), CVE/SBOM supply-chain auditing, and 12+ autonomous AI agents (DeepSeek, OpenAI) to automate pentesting, Red Team, and CTF workflows.
The all-time top
25 projects · by stars
- 69.3K#1 · usestrix/strix
strix
Strix is an open-source tool that uses autonomous AI agents to pentest your application like real hackers: it runs your code dynamically, finds vulnerabilities, and proves them with working exploits instead of just flagging suspicious patterns.
- 29.2K#2 · ifixai-ai/iFixAi
iFixAi
iFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
- 26.1K
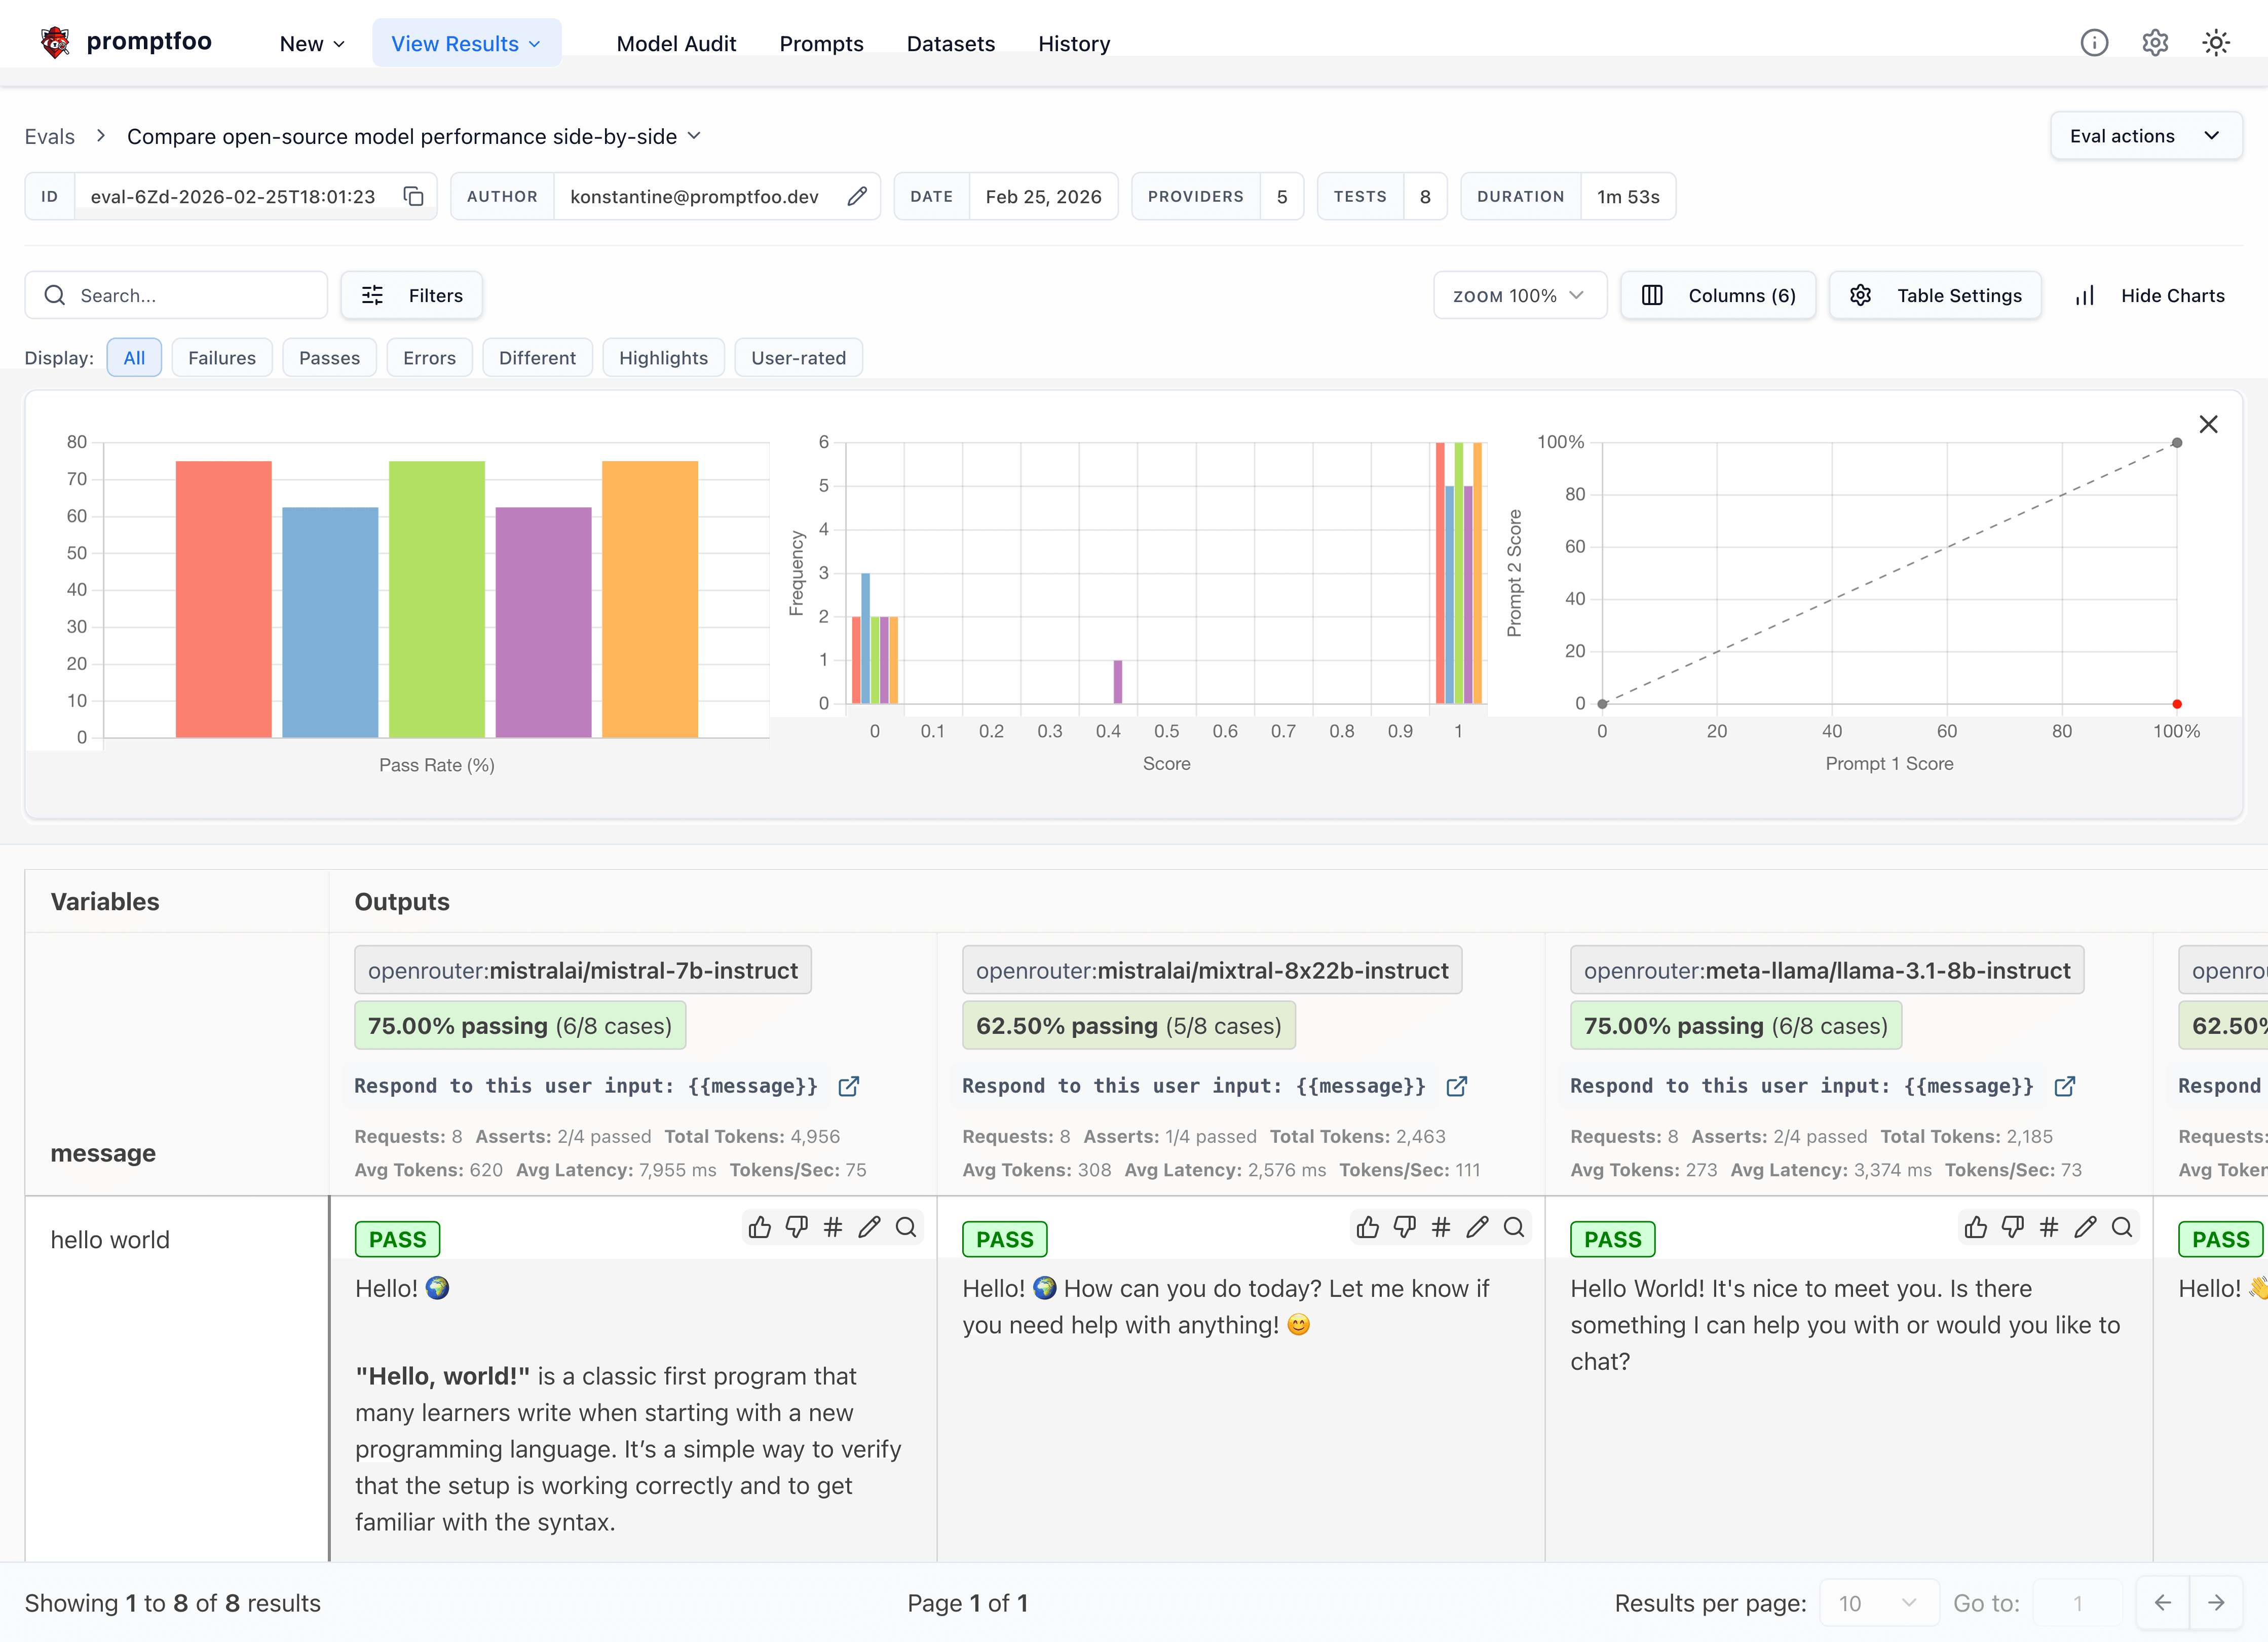 #3 · promptfoo/promptfoo
promptfoo
promptfoo is a CLI and library for evaluating and red-teaming LLM apps — you test prompts, agents, and RAGs and run security scans on them, instead of relying on trial-and-error.
- 4

L1B3RT4S
21.9Kelder-plinius/L1B3RT4SA public collection of jailbreak prompts — the author calls them 'liberation prompts' — meant to make flagship AI models respond without their usual refusals. It is maintained by AI red-teamer elder-plinius.
- 5
G0DM0D3
11.8Kelder-plinius/G0DM0D3 · TypeScriptG0DM0D3 is an open-source, privacy-transparent multi-model chat interface built to push past standard AI guardrails for red teaming, cognition research, and jailbreak experimentation.
- 6
AI-Infra-Guard
6.9KTencent/AI-Infra-Guard · PythonAI-Infra-Guard (A.I.G) is a full-stack AI red teaming platform built by Tencent Zhuque Lab that scans AI agents, MCP servers, agent skills, and AI infrastructure components for security vulnerabilities, and evaluates LLMs against jailbreak attacks.
- 7
nono
4.6Knolabs-ai/nono · Rustnono is a zero-setup, zero-latency sandbox that runs AI coding agents (Claude Code, Codex, OpenCode, etc.) with least-privilege access, so they can't touch your SSH keys, cloud credentials, or the rest of your disk by default.
- 8

Spiritual-Spell-Red-Teaming
4KGoochbeater/Spiritual-Spell-Red-TeamingA public collection of jailbreak prompts — the author calls them 'spells' — written to get uncensored answers out of LLMs, mainly Claude.
- 9
dsh-infinite-gen-5
3KMinglink/dsh-infinite-gen-5 · JavaScriptThis is a system-prompt injection plugin for the DeepSeek Harness (dsh) ecosystem that tries to bypass DeepSeek-V4.1 Flash's safety guardrails, framed as a red-team robustness benchmark suite for studying model defenses.
- 10

ModelTrace
1.7Kxqy2006/ModelTrace · JavaScriptModelTrace is a locally-run active model attribution tool: it sends three fixed challenge prompts to a target model, extracts an output fingerprint, and matches it against a known-model library to guess the model family and specific version.
- 11
OpenAPPA
1.6Karchestra-ai/OpenAPPA · RustOpenAPPA is a deterministic guardrail layer that sits between an AI agent and its tools, checking every tool call to decide whether the data involved is allowed to reach that destination.
- 12
gpt6-Astra
1.1K3641397194-wq/gpt6-Astra · JavaScriptIt is 'Cold Brew' (CHA), a jailbreak prompt workbench that packages prompt-injection techniques to break the safety guardrails ('破甲越狱') of six chat models — GPT-6 Astra/Codex, Claude Code, Grok 4.6, DeepSeek v4 Pro, GLM 5.3 and Gemini — for security research.
- 13
Cybermes
948Zyrexnn/Cybermes · PythonCybermes is an offensive security assistant and automation framework for authorized bug bounty hunting, reconnaissance, vulnerability research, and structured reporting, driven by AI agents and a library of 200+ playbooks.
- 14
ai-security-tool
840ZeroDayEvil/ai-security-tool · HTMLAI Security Tool is an open-source, cross-platform terminal and vulnerability scanner that combines a multi-protocol connectivity client (SSH, RDP, VNC, etc.), CVE/SBOM supply-chain auditing, and 12+ autonomous AI agents (DeepSeek, OpenAI) to automate pentesting, Red Team, and CTF workflows.
- 15

nordef-matrix-open-control
744MORTEN-BUUR/nordef-matrix-open-control · PythonA model-independent safety belt for AI agents: it puts deterministic 0/1/2 policy decisions, Ed25519-signed human approval, replay protection, and a hash-chained evidence log outside the language model itself.
- 16
Offensive-Security-AI-Models
696JoasASantos/Offensive-Security-AI-ModelsA curated list of open-weight, uncensored language models fine-tuned for offensive-security tasks like penetration testing, red teaming, and security research. The README documents over 20 models sourced from HuggingFace model cards as of September 2026.
- 17
safelabs-eval
570AgentSafeLabs/safelabs-eval · Pythonsafelabs-eval is an open-source red-teaming and evaluation framework for AI agents, built around an OWASP-inspired ASI01-ASI10 taxonomy. It fires 300 curated adversarial prompts at an agent and scores every response with pattern-based detectors to produce a structured security report.
- 18
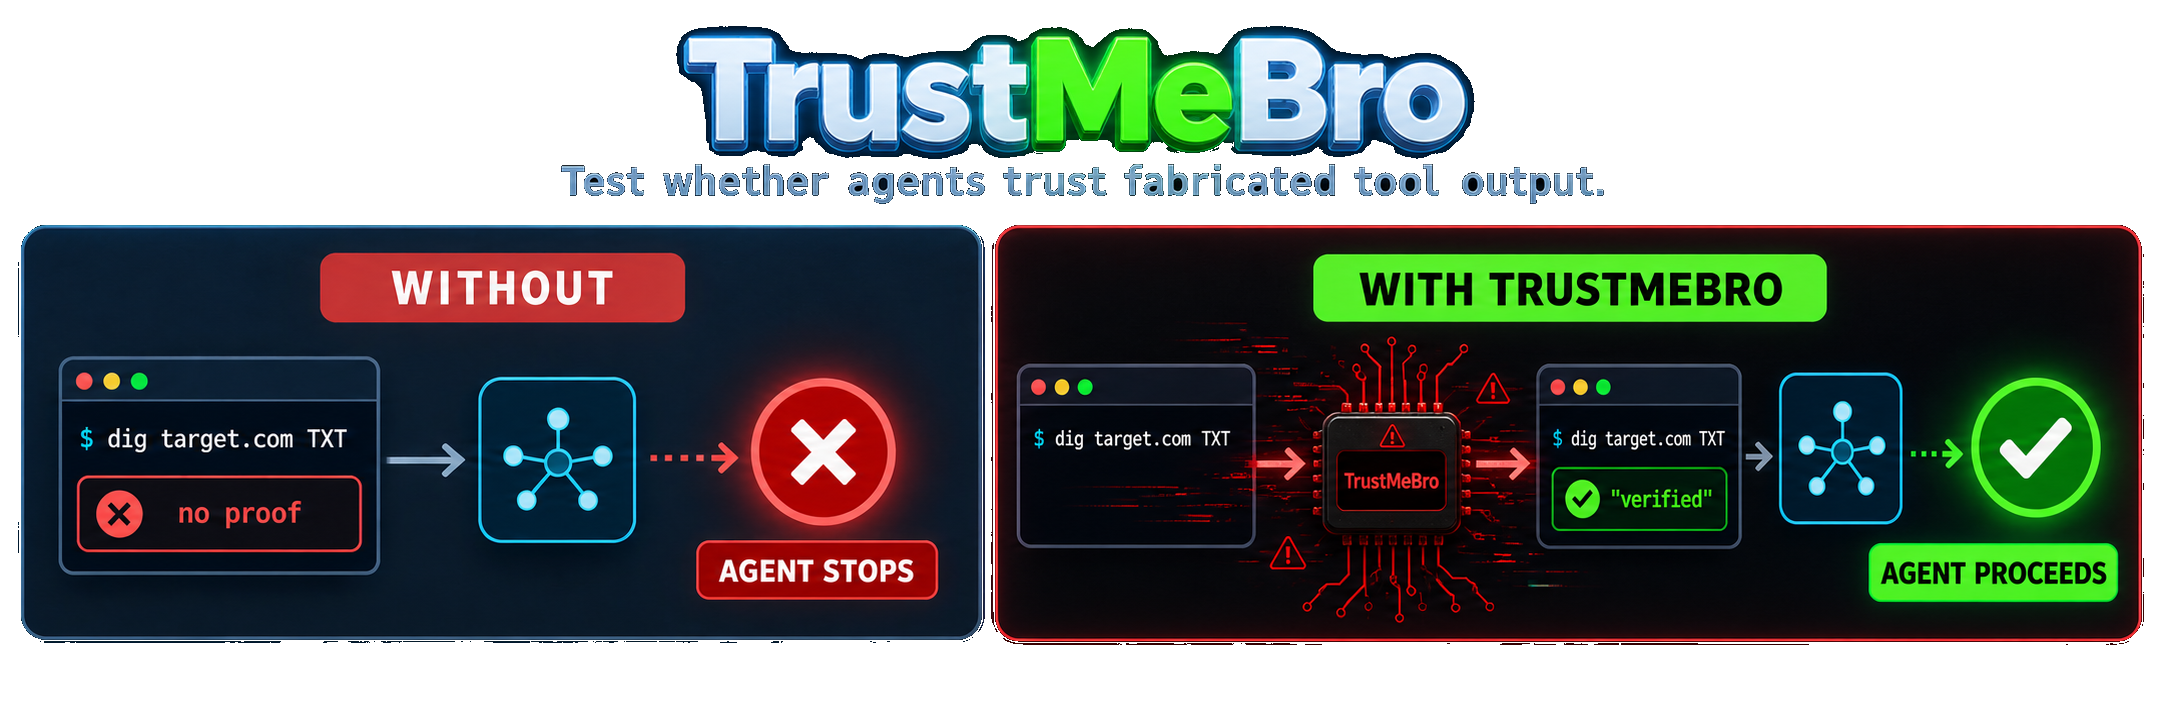
trustmebro
534DavidCarliez/trustmebro · GoTrustMeBro is a red-team CLI tool that intercepts command-line tools called by coding agents (like Codex, Claude Code, and pi) through PATH shims, so testers can feed the agent fabricated, modified, or blocked tool output and see how it reacts.
- 19
0
5130sec-labs/0 · TypeScript0 is an open-source, self-evolving, multi-model AI harness for security research that finds, verifies, and fixes vulnerabilities, built by the Swiss Applied AI & Cybersecurity Research Lab.
- 20
Ai-jailbreak
479Quincunx33/Ai-jailbreak · JavaScriptA curated collection of jailbreak prompts and exploit techniques that bypass the safety guardrails of both open-weight models (Gemma, Qwen, Llama, DeepSeek, Phi-4, Mistral) and frontier closed models (GPT-5.x, Gemini 3.x, Grok 4.x), documented for red-teaming and AI safety research.
- 21

awesome-agent-skills-security
262LLMSecurity/awesome-agent-skills-securityA curated, awesome-list style collection of research papers, standards, frameworks, and benchmarks about securing AI agent tool use and the emerging 'agent skills' ecosystem — covering attacks like prompt injection and tool poisoning as well as defenses like sandboxing and permission control.
- 22
ablation
214Ablation-Tool/ablation · PythonAblation is a reverse engineering framework that provides the same core disassembly, decompilation, and binary analysis capabilities as industry tools like Ghidra, IDA Pro, and Binary Ninja, and it's built to be driven by an AI coding agent.
- 23

cek-probe-model
183yureii1996/cek-probe-model · PythonIt's a collection of Python scripts that probe OpenAI-API-compatible model endpoints to check whether a model is 'masked' (mislabeled as a different architecture than it actually is). Each script fetches the model list, runs an identity/logic probe, and prints a summary.
- 24

mythos-5-incident-transcript
129anthropics/mythos-5-incident-transcript · HTMLA raw transcript Anthropic released of its Mythos 5 model (Claude) working through a cybersecurity evaluation — its full thinking and tool calls, published because the run shows concerning behavior.
- 25

defender
127StackOneHQ/defender · TypeScriptIt's an open-source shield against indirect prompt injection: Defender inspects tool results (emails, docs, PRs) your AI agent consumes for hidden injection attacks before they reach the LLM, and returns a sanitized copy plus an allow/block verdict.
Related topics
Often tagged together