


What is this?
 VibeVoice is Microsoft's family of open-source voice AI models covering text-to-speech and speech recognition: long-form multi-speaker TTS, real-time streaming TTS, and ASR built for hour-long recordings.
So is it an app I install, or a set of models?It is a research framework plus Hugging Face model weights rather than a finished app: VibeVoice-ASR-7B, ASR-Streaming, ASR-BitNet (CPU), TTS-1.5B and Realtime-0.5B, each with docs and a quick-try route.
It is a research framework plus Hugging Face model weights rather than a finished app: VibeVoice-ASR-7B, ASR-Streaming, ASR-BitNet (CPU), TTS-1.5B and Realtime-0.5B, each with docs and a quick-try route.Where can I actually try these models?ASR-7B has a browser Playground and Realtime-0.5B has a Colab demo; in your own code, the ASR model loads directly through the Hugging Face Transformers library.
ASR-7B has a browser Playground and Realtime-0.5B has a Colab demo; in your own code, the ASR model loads directly through the Hugging Face Transformers library.How reliable is the audio it produces?The README cautions that outputs may still be unexpected, biased, or inaccurate, and that the models inherit the errors of their base model, Qwen2.5 1.5b in this release.
The README cautions that outputs may still be unexpected, biased, or inaccurate, and that the models inherit the errors of their base model, Qwen2.5 1.5b in this release.Can I serve the models from my own server?Yes, vLLM inference is supported for speed, including a recipe for serving streaming recognition, though the repo ships no Dockerfile, so deployment is on you.
Yes, vLLM inference is supported for speed, including a recipe for serving streaming recognition, though the repo ships no Dockerfile, so deployment is on you.Am I allowed to use this in a product?That is the catch: the repository is MIT-licensed on GitHub, but the README says the models are intended for research and development purposes only and does not recommend commercial use without further testing.
That is the catch: the repository is MIT-licensed on GitHub, but the README says the models are intended for research and development purposes only and does not recommend commercial use without further testing.Will it run on my CPU-only machine?Hardware needs are not spelled out, but there is a dedicated CPU-oriented checkpoint, VibeVoice-ASR-BitNet, whose quick-try route is the VibeASR.cpp project, so speech recognition does not strictly require a GPU.
Hardware needs are not spelled out, but there is a dedicated CPU-oriented checkpoint, VibeVoice-ASR-BitNet, whose quick-try route is the VibeASR.cpp project, so speech recognition does not strictly require a GPU.Why is the text-to-speech part disabled?Microsoft removed the VibeVoice-TTS code from the repository in September 2025 after discovering misuse inconsistent with its responsible-AI principles. The TTS-1.5B weights are still listed, but its quick-try option is marked Disabled.
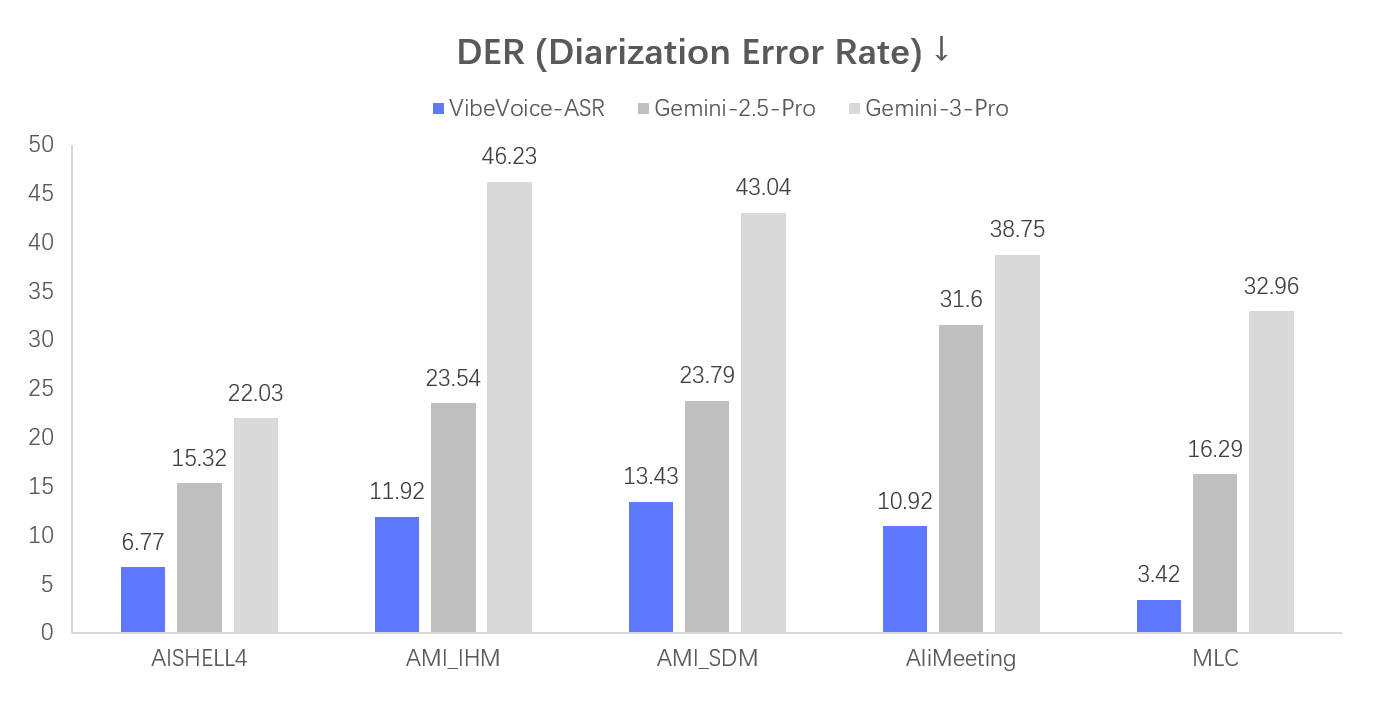
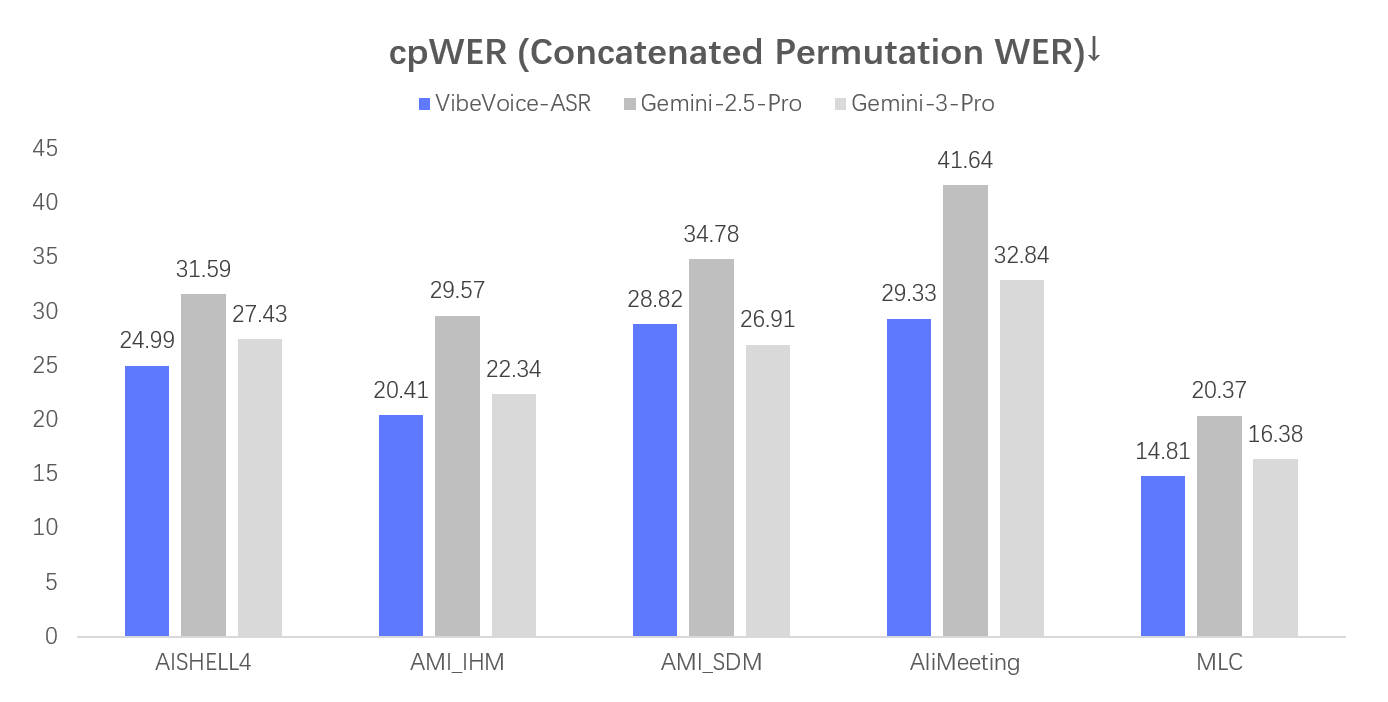
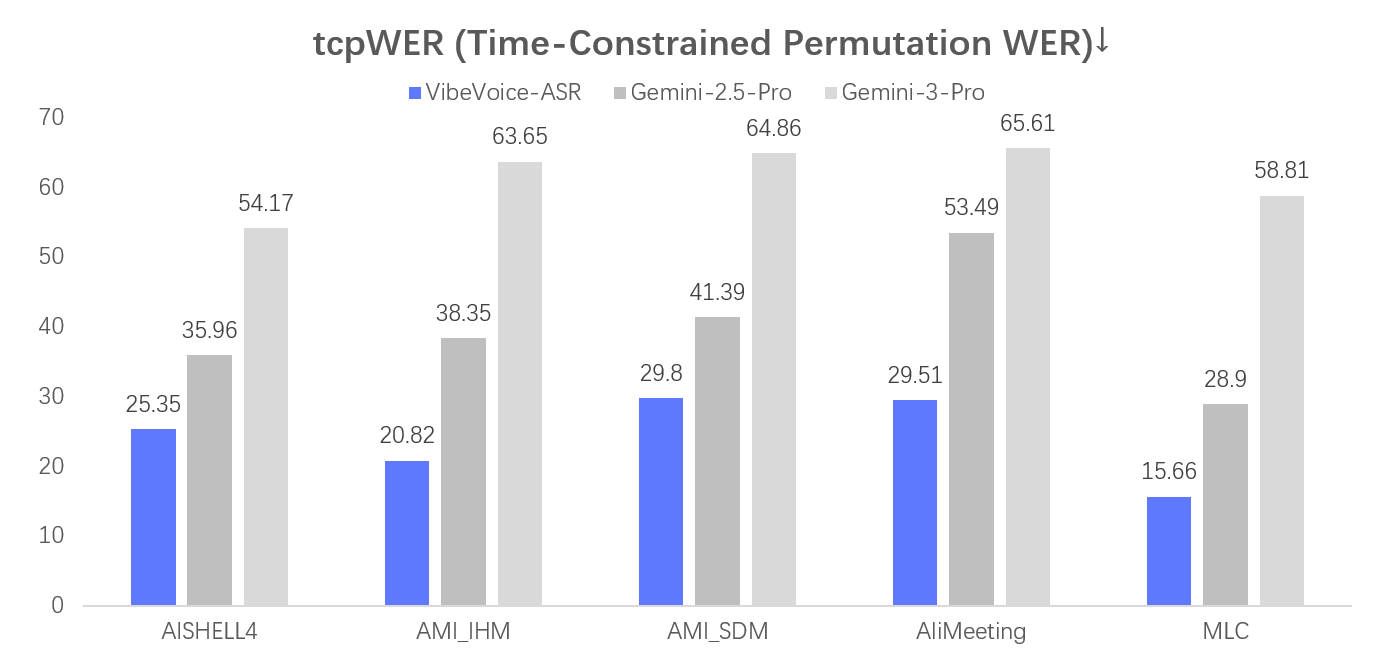
Microsoft removed the VibeVoice-TTS code from the repository in September 2025 after discovering misuse inconsistent with its responsible-AI principles. The TTS-1.5B weights are still listed, but its quick-try option is marked Disabled.What can the ASR model do with a long recording?It handles up to 60 minutes of continuous audio in a single pass and jointly performs recognition, diarization, and timestamping, returning who said what and when. Custom hotwords can sharpen accuracy on names and domain-specific terms.
It handles up to 60 minutes of continuous audio in a single pass and jointly performs recognition, diarization, and timestamping, returning who said what and when. Custom hotwords can sharpen accuracy on names and domain-specific terms.Which languages does it handle?VibeVoice-ASR is natively multilingual with over 50 languages. The Realtime-0.5B experimental speakers add nine languages (DE, FR, IT, JP, KR, NL, PL, PT, ES) plus 11 distinct English style voices.
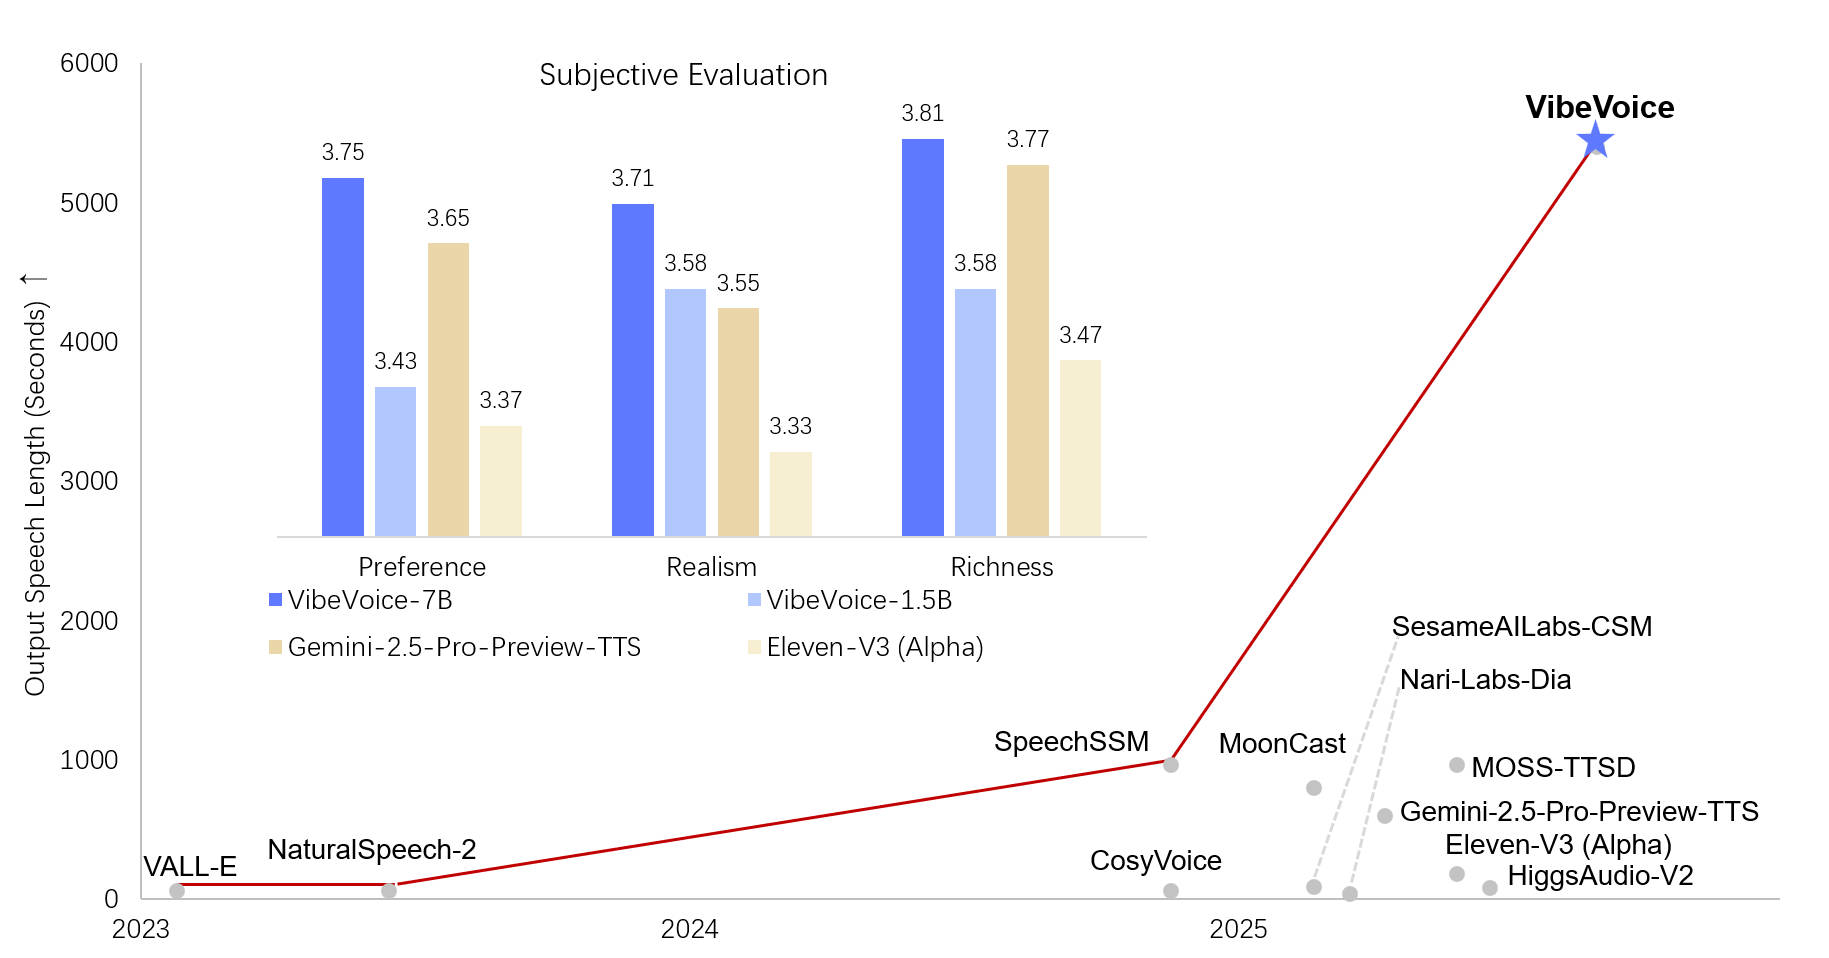
VibeVoice-ASR is natively multilingual with over 50 languages. The Realtime-0.5B experimental speakers add nine languages (DE, FR, IT, JP, KR, NL, PL, PT, ES) plus 11 distinct English style voices.What is VibeVoice-Realtime-0.5B?A lightweight 0.5B-parameter real-time TTS model with roughly 300 milliseconds to first audible audio, streaming text input, and long-form generation of about 10 minutes. It has a one-click Colab demo.
A lightweight 0.5B-parameter real-time TTS model with roughly 300 milliseconds to first audible audio, streaming text input, and long-form generation of about 10 minutes. It has a one-click Colab demo.What are similar projects?Speech, MOSS-TTS, FunASR, WhisperLiveKit, speechbrain, ChatTTS, faster-whisper, seamless_communication
Speech, MOSS-TTS, FunASR, WhisperLiveKit, speechbrain, ChatTTS, faster-whisper, seamless_communicationWhich topics is it in?diarization, voice-ai, asr, mit-license, diffusion, transcription, speech-to-text, transformers, speech-recognition, tts, vllm, text-to-speech
diarization, voice-ai, asr, mit-license, diffusion, transcription, speech-to-text, transformers, speech-recognition, tts, vllm, text-to-speech