Topics / #text-to-speech
Text-to-speech projects on GitHub
Spelled-out variant of the TTS topic: synthesizing speech from text.
As of , the most-starred Text-to-speech projects on GitHub are MoneyPrinterTurbo (132.9K stars), unsloth (78.2K stars) and VoiceStudio (75.3K stars). GitHub.Locker tracks 133 Text-to-speech repositories with 1.9M stars combined. The fastest-growing on October 18 was VoiceStudio, with +2.4K stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +2.4K
VoiceStudio
debpalash/VoiceStudio · ★ 75.3KVoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
 +991
B
AhmadHassan-BTed/B · ★ 1.2KB is an autonomous AI desktop companion that lives on your screen as an animated floating face, watching your active windows and screen content, listening to you, and proactively speaking up when it has something useful to say.
 +440
MoneyPrinterTurbo
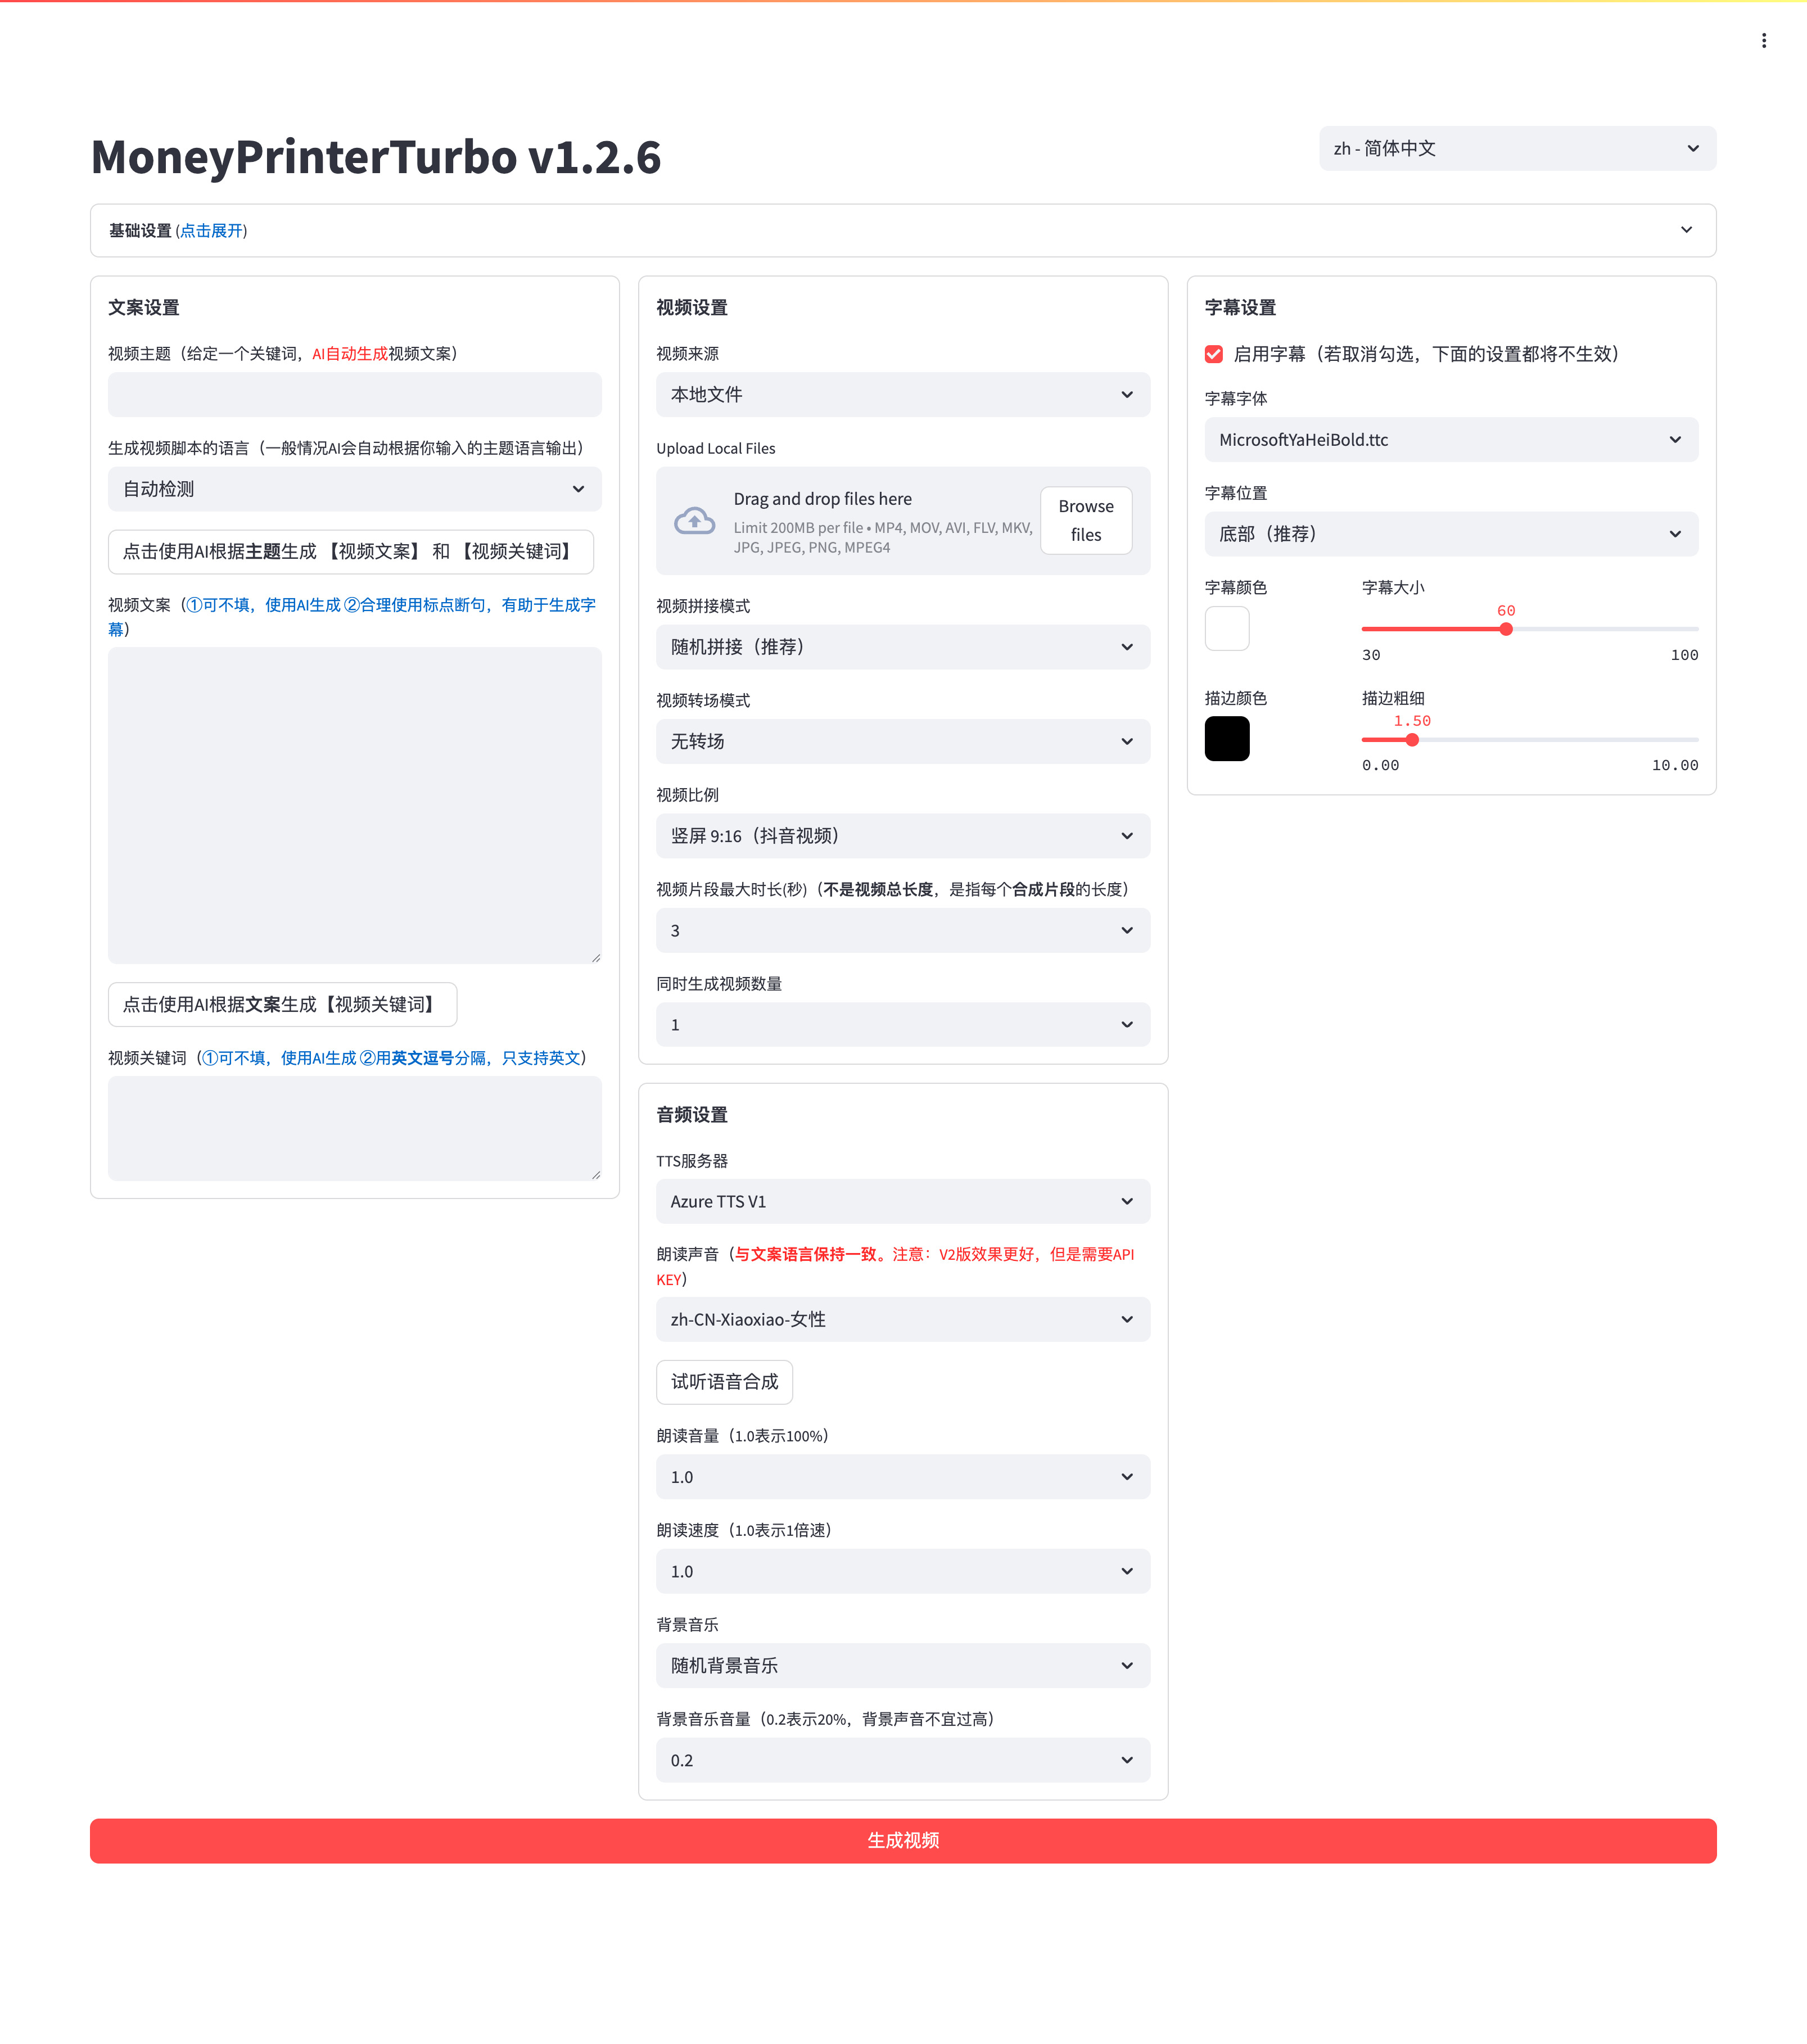
harry0703/MoneyPrinterTurbo · ★ 132.9KMoneyPrinterTurbo is an all-in-one AI tool that turns a topic or keyword into a finished short video: it writes the script, finds matching footage, generates subtitles and background music, and renders the final HD clip automatically.
 +382
OpenMontage
calesthio/OpenMontage · ★ 69.5KOpenMontage turns your AI coding assistant (Claude Code, Cursor, Copilot, Windsurf, Codex) into a full video production studio: you describe a video in plain language and it handles research, scripting, asset generation, editing, and final composition through 12 production pipelines and 100+ tools.
The all-time top
Top 100 of 133 · by stars
- 132.9K#1 · harry0703/MoneyPrinterTurbo
MoneyPrinterTurbo
MoneyPrinterTurbo is an all-in-one AI tool that turns a topic or keyword into a finished short video: it writes the script, finds matching footage, generates subtitles and background music, and renders the final HD clip automatically.
- 78.2K
 #2 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 75.3K#3 · debpalash/VoiceStudio
VoiceStudio
VoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
- 4
OpenMontage
69.5Kcalesthio/OpenMontage · PythonOpenMontage turns your AI coding assistant (Claude Code, Cursor, Copilot, Windsurf, Codex) into a full video production studio: you describe a video in plain language and it handles research, scripting, asset generation, editing, and final composition through 12 production pipelines and 100+ tools.
- 5

GPT-SoVITS
63.2KRVC-Boss/GPT-SoVITS · PythonGPT-SoVITS is a few-shot voice cloning and text-to-speech WebUI: feed it a short voice sample and it can clone that voice to read out any text, including in languages the speaker never recorded.
- 6
Real-Time-Voice-Cloning
60.2KCorentinJ/Real-Time-Voice-Cloning · PythonIt's an implementation of SV2TTS, a deep learning framework that lets you clone a voice from just a few seconds of audio and then generate arbitrary speech in that voice in real time.
- 7
voicebox
58Kjamiepine/voicebox · PythonVoicebox is an open-source, local-first AI voice studio: it clones voices, generates speech in 23 languages, lets you dictate into any app with a global hotkey, and gives MCP-aware AI agents a voice - all running on your own machine as a free alternative to ElevenLabs and WisprFlow combined.
- 8
VibeVoice
54.9Kmicrosoft/VibeVoice · PythonVibeVoice is Microsoft's family of open-source voice AI models covering text-to-speech and speech recognition: long-form multi-speaker TTS, real-time streaming TTS, and ASR built for hour-long recordings.
- 9

TTS
46.1Kcoqui-ai/TTS · PythonCoqui TTS is a deep learning toolkit for Text-to-Speech, shipping 1100+ pretrained models plus tools for training, fine-tuning, and curating datasets for new voices.
- 10
LibreChat
45.9KLibreChat-AI/LibreChat · TypeScriptLibreChat is a self-hosted AI chat platform that unifies all major AI providers (OpenAI, Anthropic, Google, AWS Bedrock, Azure, Mistral, OpenRouter and more) in a single ChatGPT-like interface, with Agents, MCP support, Code Interpreter and Artifacts built in.
- 11
ChatTTS
39.9K2noise/ChatTTS · PythonChatTTS is an open-source text-to-speech model built for conversational speech — the natural-sounding voice layer for things like LLM assistants — speaking English and Chinese.
- 12
VoxCPM
39.6KOpenBMB/VoxCPM · PythonVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
- 13
bark
39.3Ksuno-ai/bark · Jupyter NotebookBark is a transformer-based text-to-audio model from Suno that generates realistic, multilingual speech plus music, background noise, and sound effects from text prompts.
- 14
OpenVoice
38Kmyshell-ai/OpenVoice · PythonOpenVoice is an audio foundation model for instant voice cloning, built by MIT and MyShell; it clones a reference speaker's tone color and generates speech in multiple languages and accents.
- 15
MockingBird
36.9Kbabysor/MockingBird · PythonMockingBird is a PyTorch voice-cloning toolbox: it learns a voice from a short audio clip and generates arbitrary Mandarin speech in real time. The repo is no longer actively updated — the author is building an optimized cloud-hosted version instead.
- 16
SillyTavern
34.6KSillyTavern/SillyTavern · JavaScriptSillyTavern is a locally installed user interface for interacting with text generation LLMs, image generation engines, and TTS voice models. It unifies many LLM APIs (KoboldAI, Horde, NovelAI, Ooba, Tabby, OpenAI, OpenRouter, Claude, Mistral and more) behind a single frontend built for roleplay and prompt tinkering.
- 17
fish-speech
33.3Kfishaudio/fish-speech · PythonFish Speech (Fish Audio S2) is a state-of-the-art open-source text-to-speech system that generates natural, emotionally rich speech in 80+ languages, led by the flagship S2-Pro model that combines a Dual-AR architecture with reinforcement-learning alignment.
- 18
onyx
32.6Konyx-dot-app/onyx · PythonOnyx is an open source AI platform that gives you a full-featured chat interface on top of any LLM, with built-in RAG, web search, agents, and more.
- 19
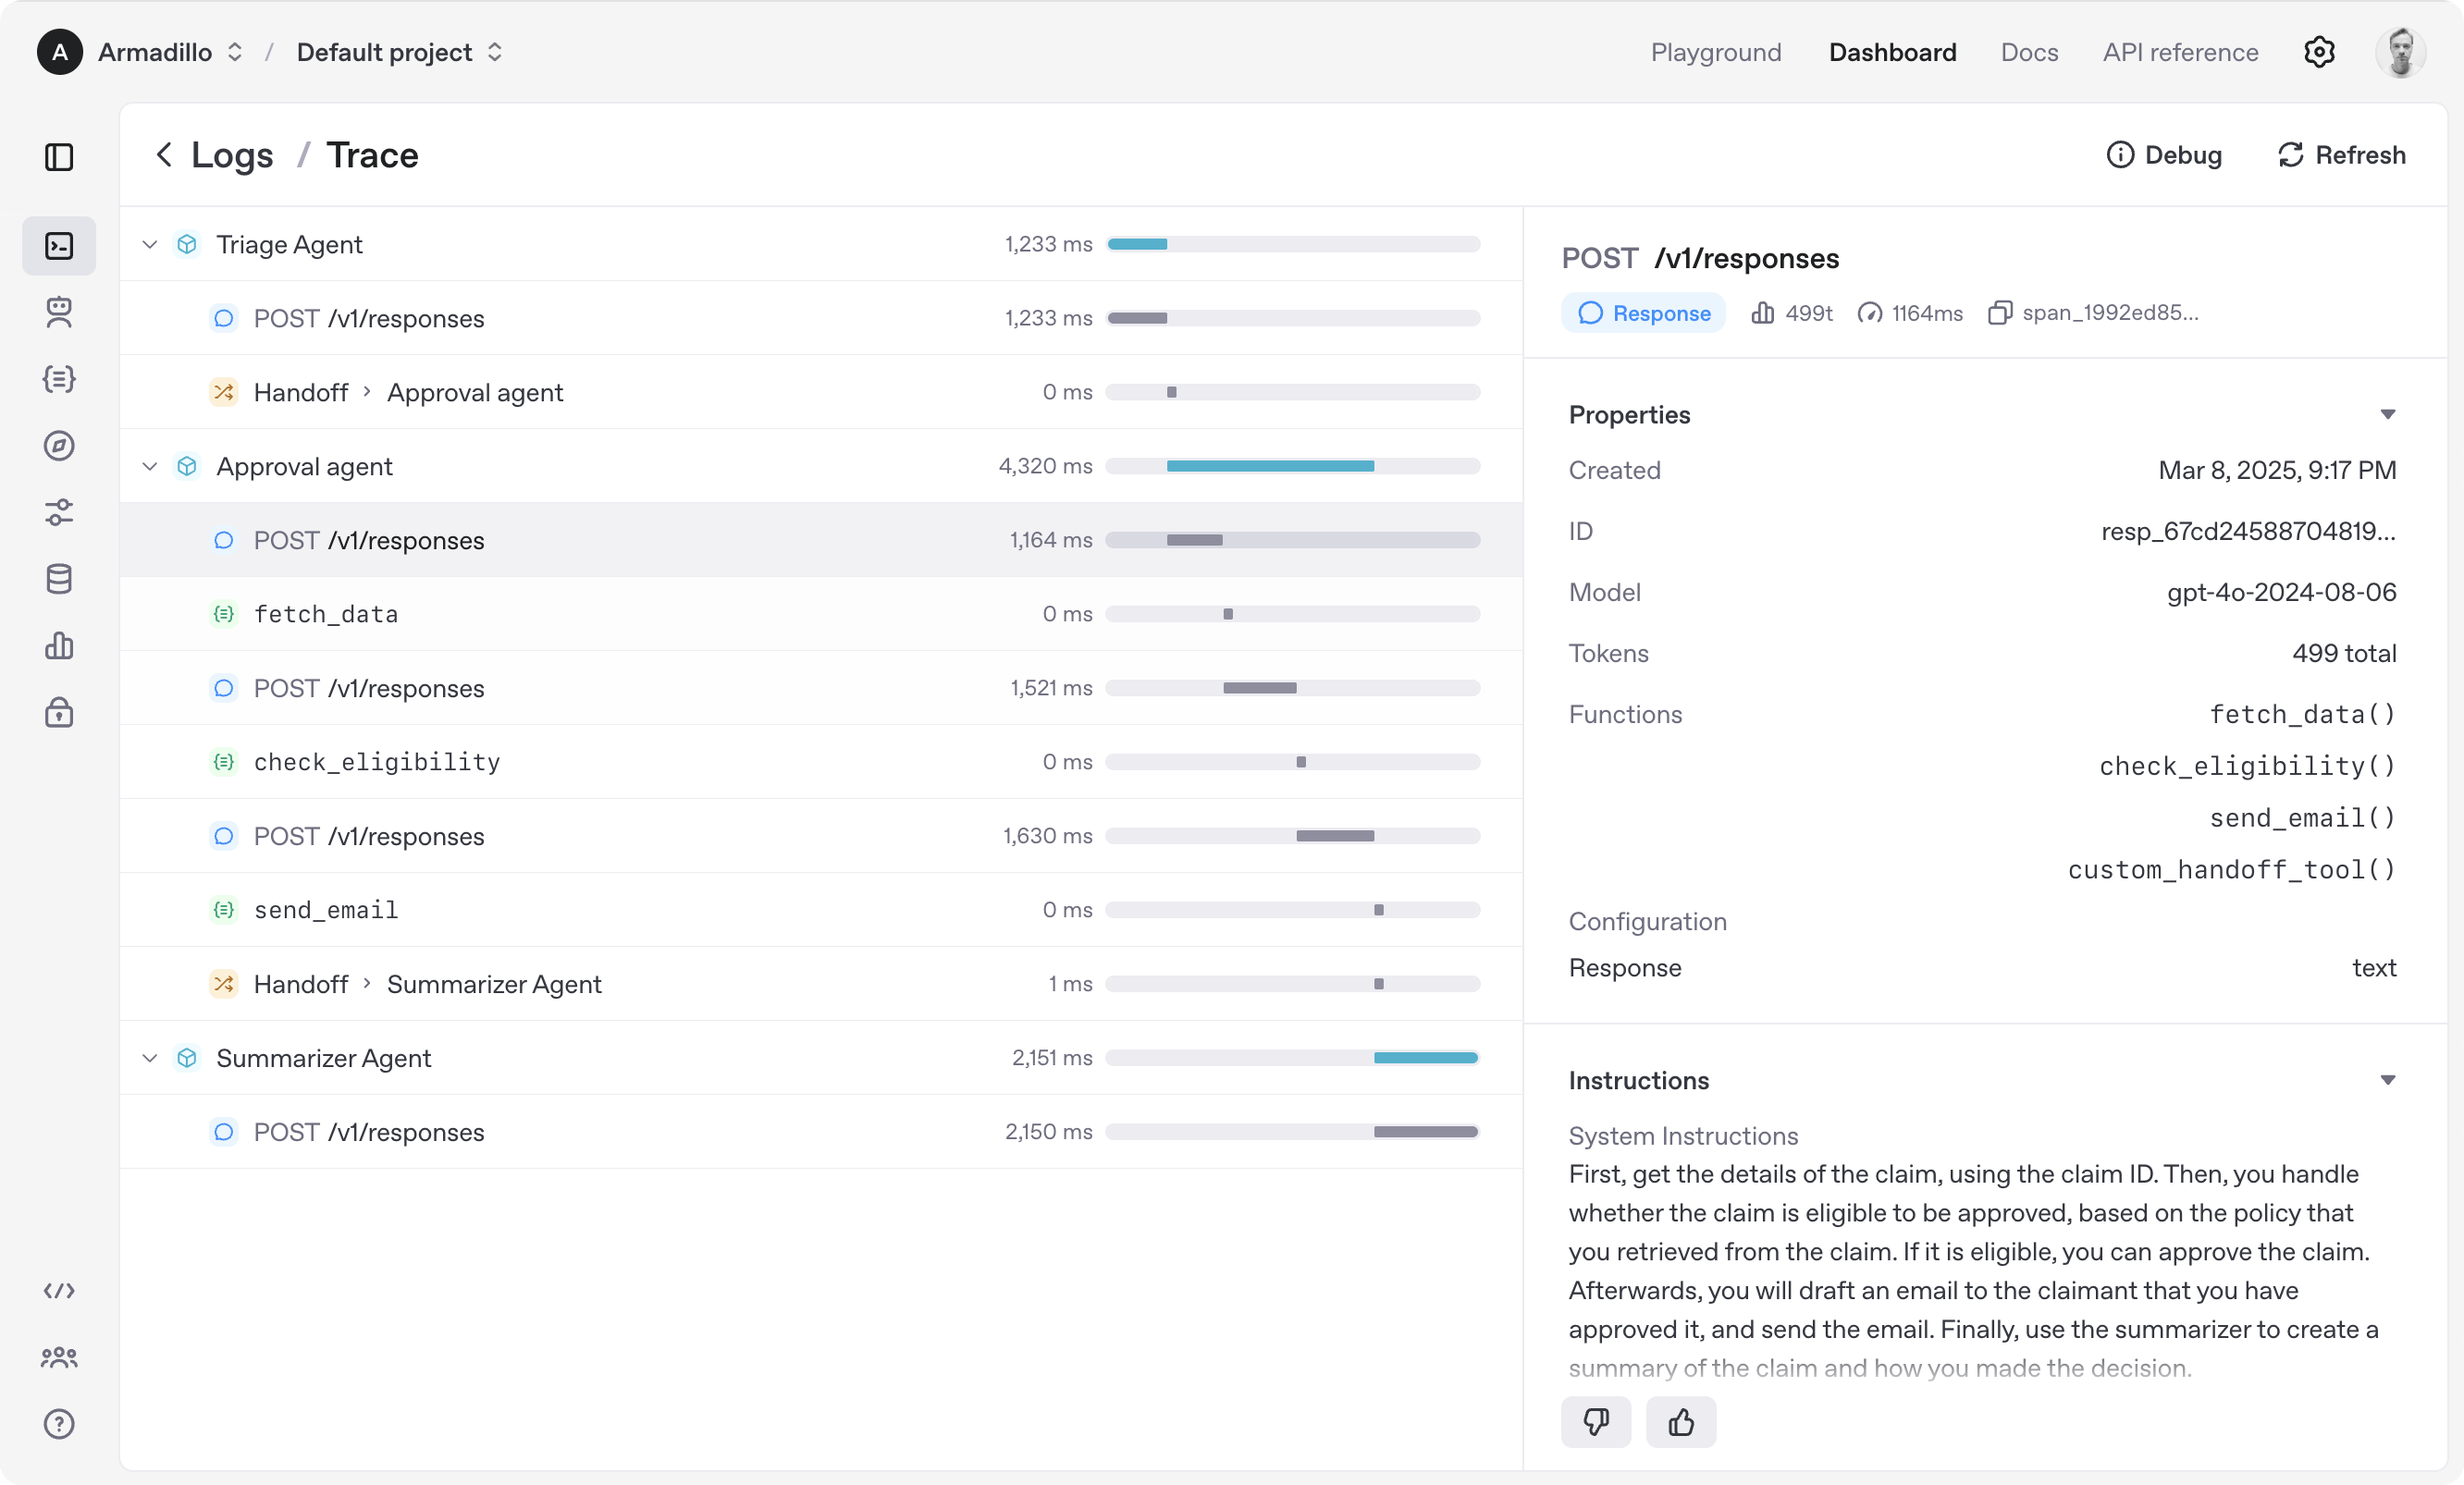
openai-agents-python
30.1Kopenai/openai-agents-python · PythonIt is the OpenAI Agents SDK: a lightweight yet powerful Python framework for building multi-agent workflows, where an agent is an LLM configured with instructions, tools, guardrails and handoffs.
- 20
chatterbox
27.1Kresemble-ai/chatterbox · PythonChatterbox is a family of state-of-the-art, open-source text-to-speech (TTS) models from Resemble AI, including multilingual and low-latency voice-agent variants.
- 21

MiniCPM-V
26.9KOpenBMB/MiniCPM-V · PythonA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 22
index-tts
24.6Kindex-tts/index-tts · PythonIndexTTS is a zero-shot text-to-speech system that clones a voice from a single reference audio clip. The latest version, IndexTTS-2.5, supports Chinese, English, Japanese, Spanish and Arabic with fine-grained emotion, speed and pronunciation control.
- 23
CosyVoice
24KQwenAudio/CosyVoice · PythonCosyVoice is Alibaba's open-source, LLM-based text-to-speech system. It generates natural speech in 9 languages plus 18+ Chinese dialects, supports zero-shot voice cloning, and ships inference, training and deployment code.
- 24

unilm
22.2Kmicrosoft/unilm · PythonMicrosoft's research hub for large-scale self-supervised pre-training: a family of foundation models spanning NLP, vision, speech, and multimodal tasks across 100+ languages - including BEiT, LayoutLM, Kosmos, MiniLM, TrOCR, and WavLM.
- 25
ebook2audiobook
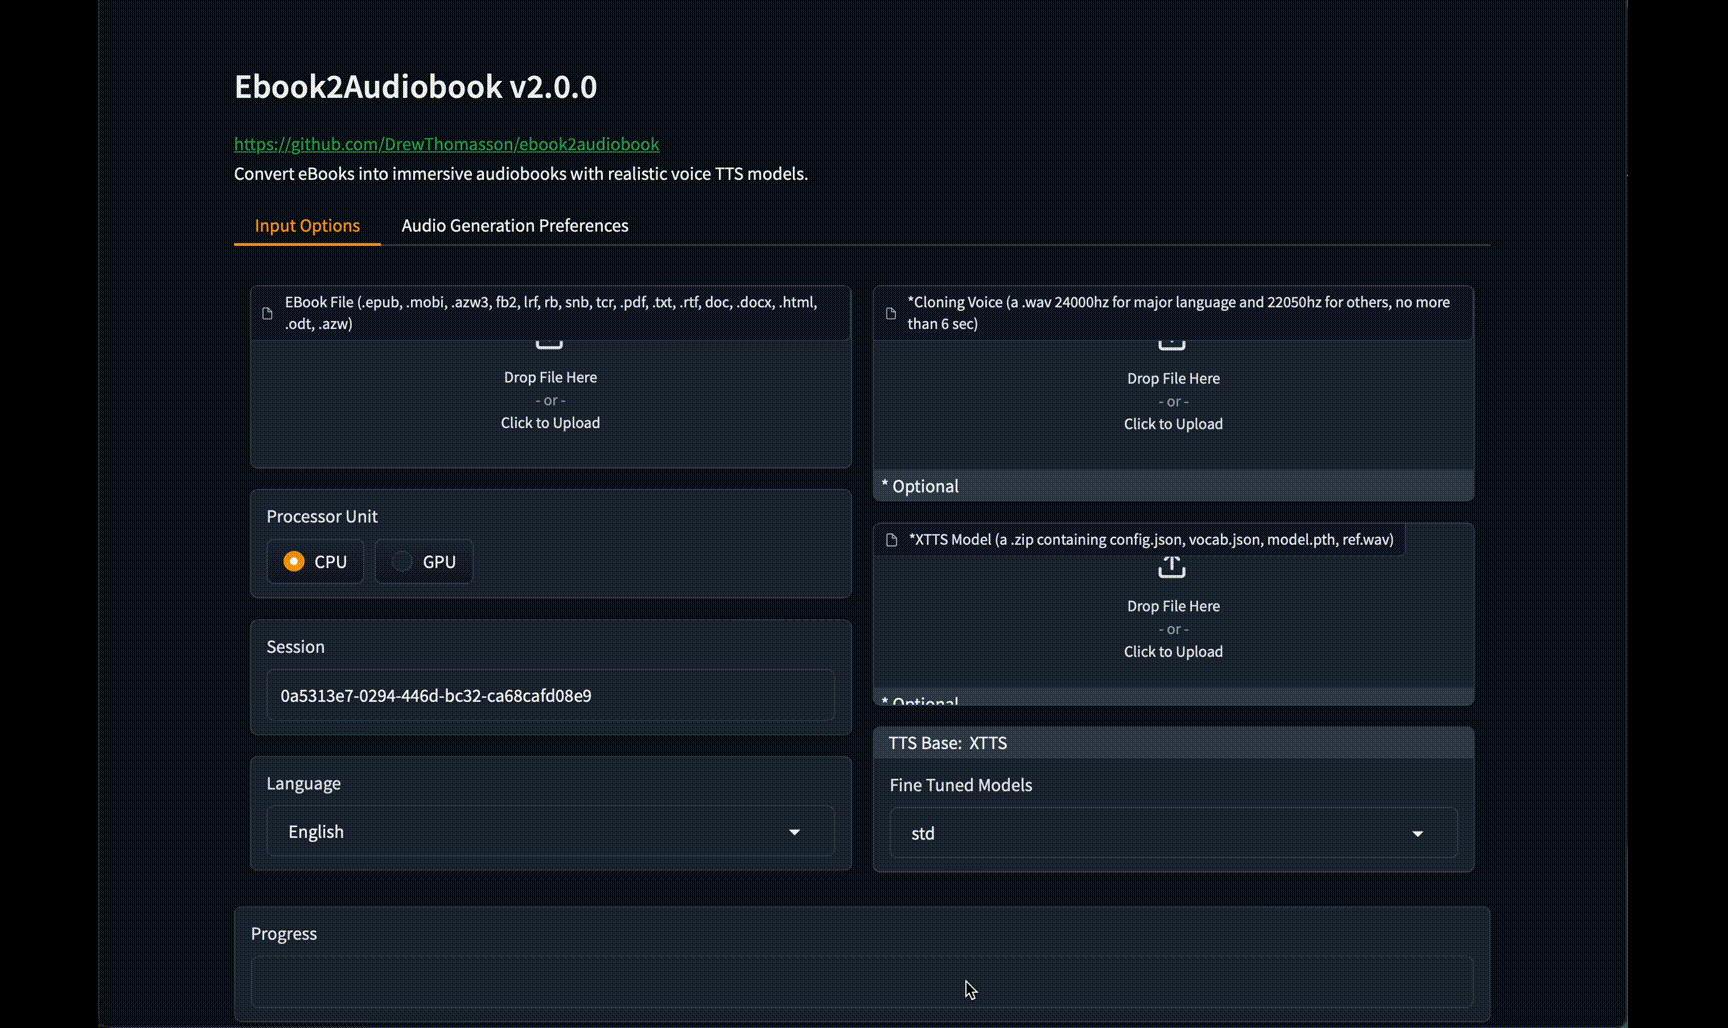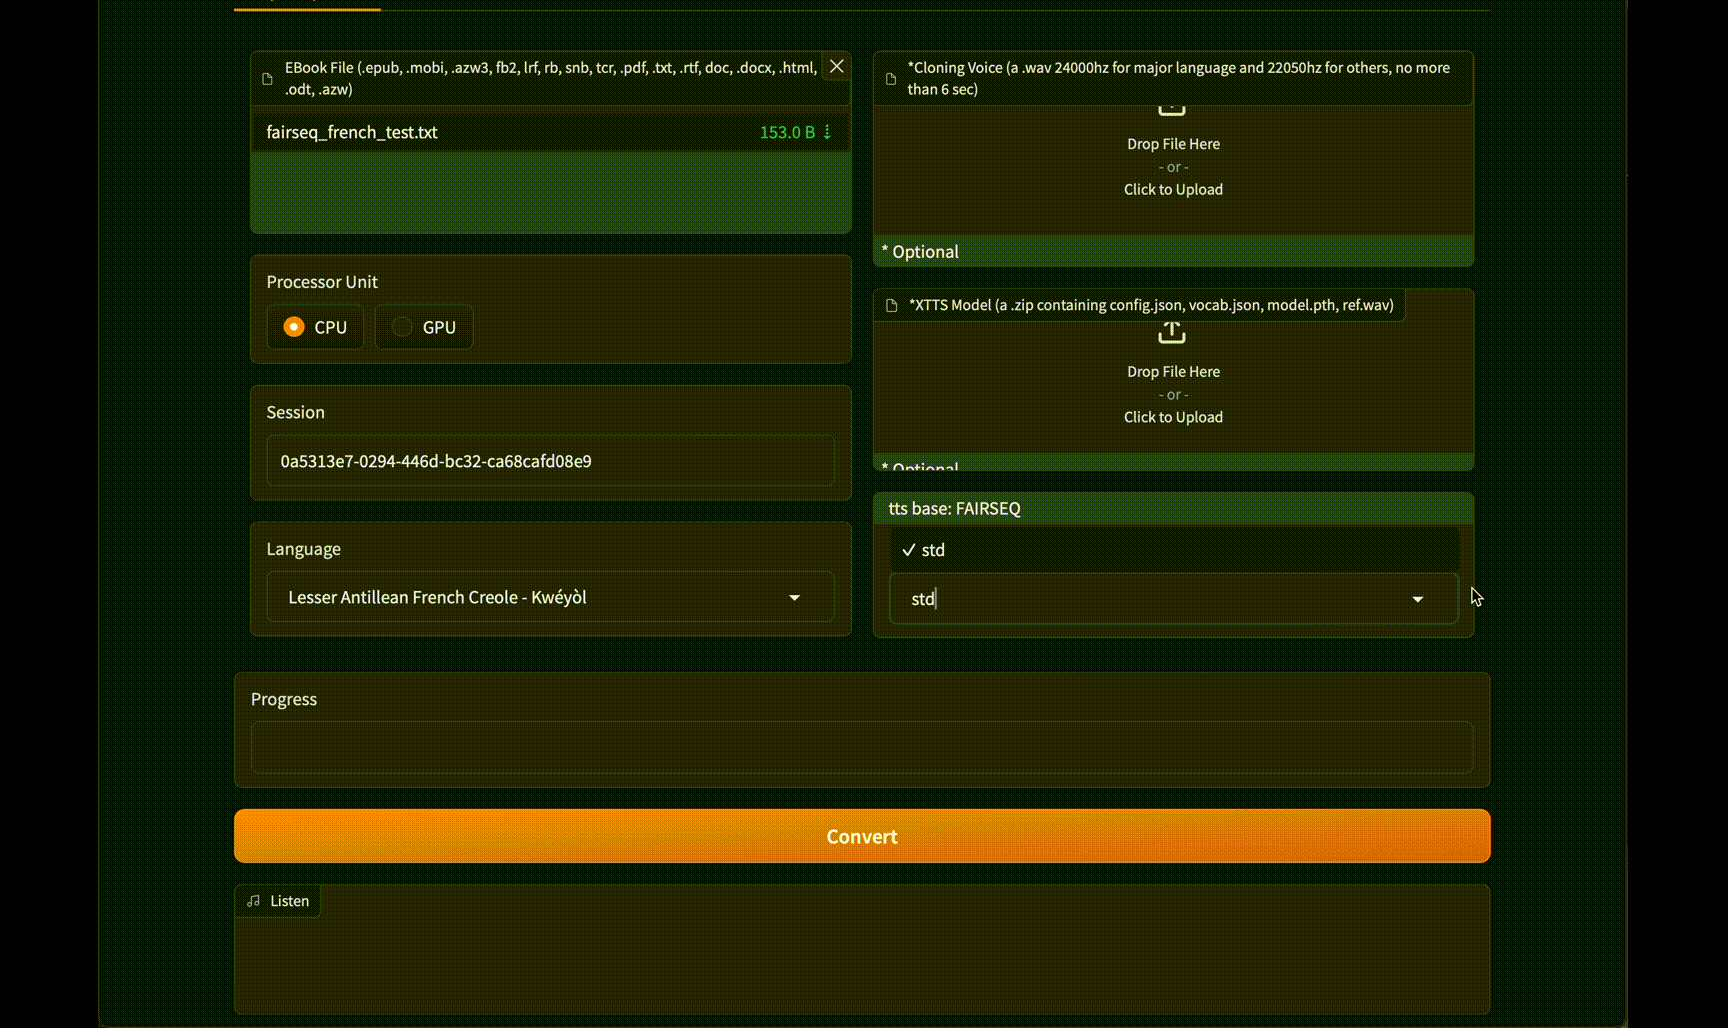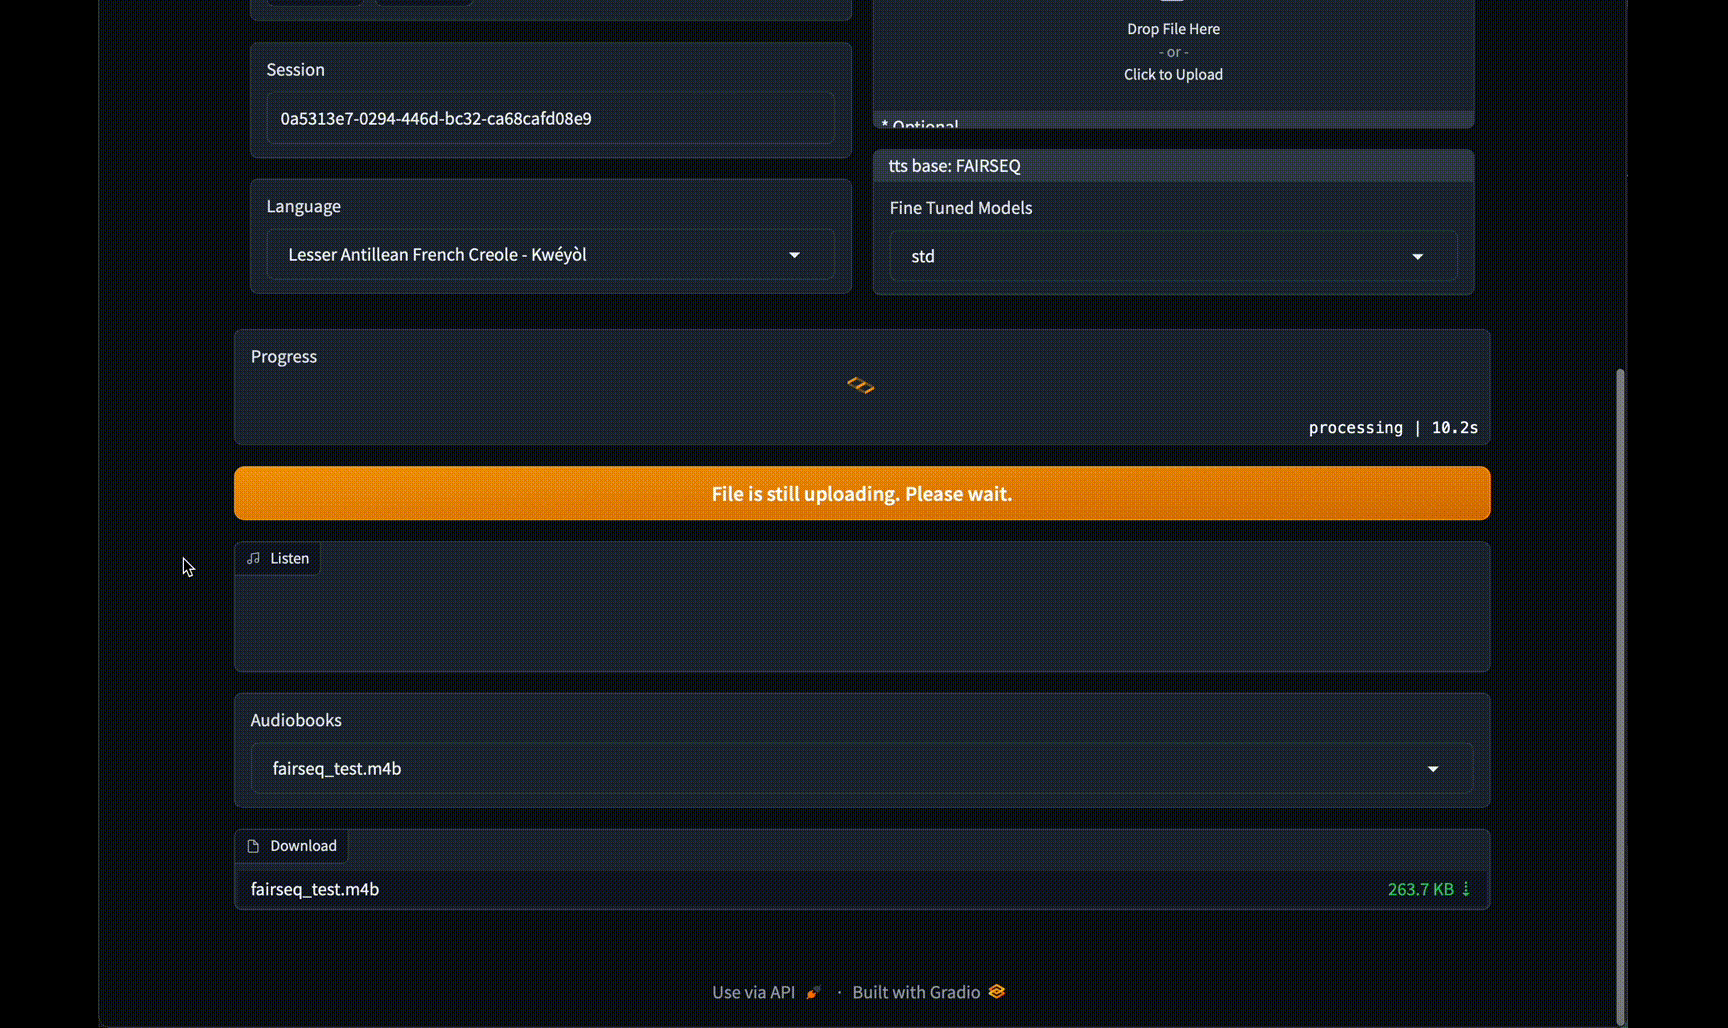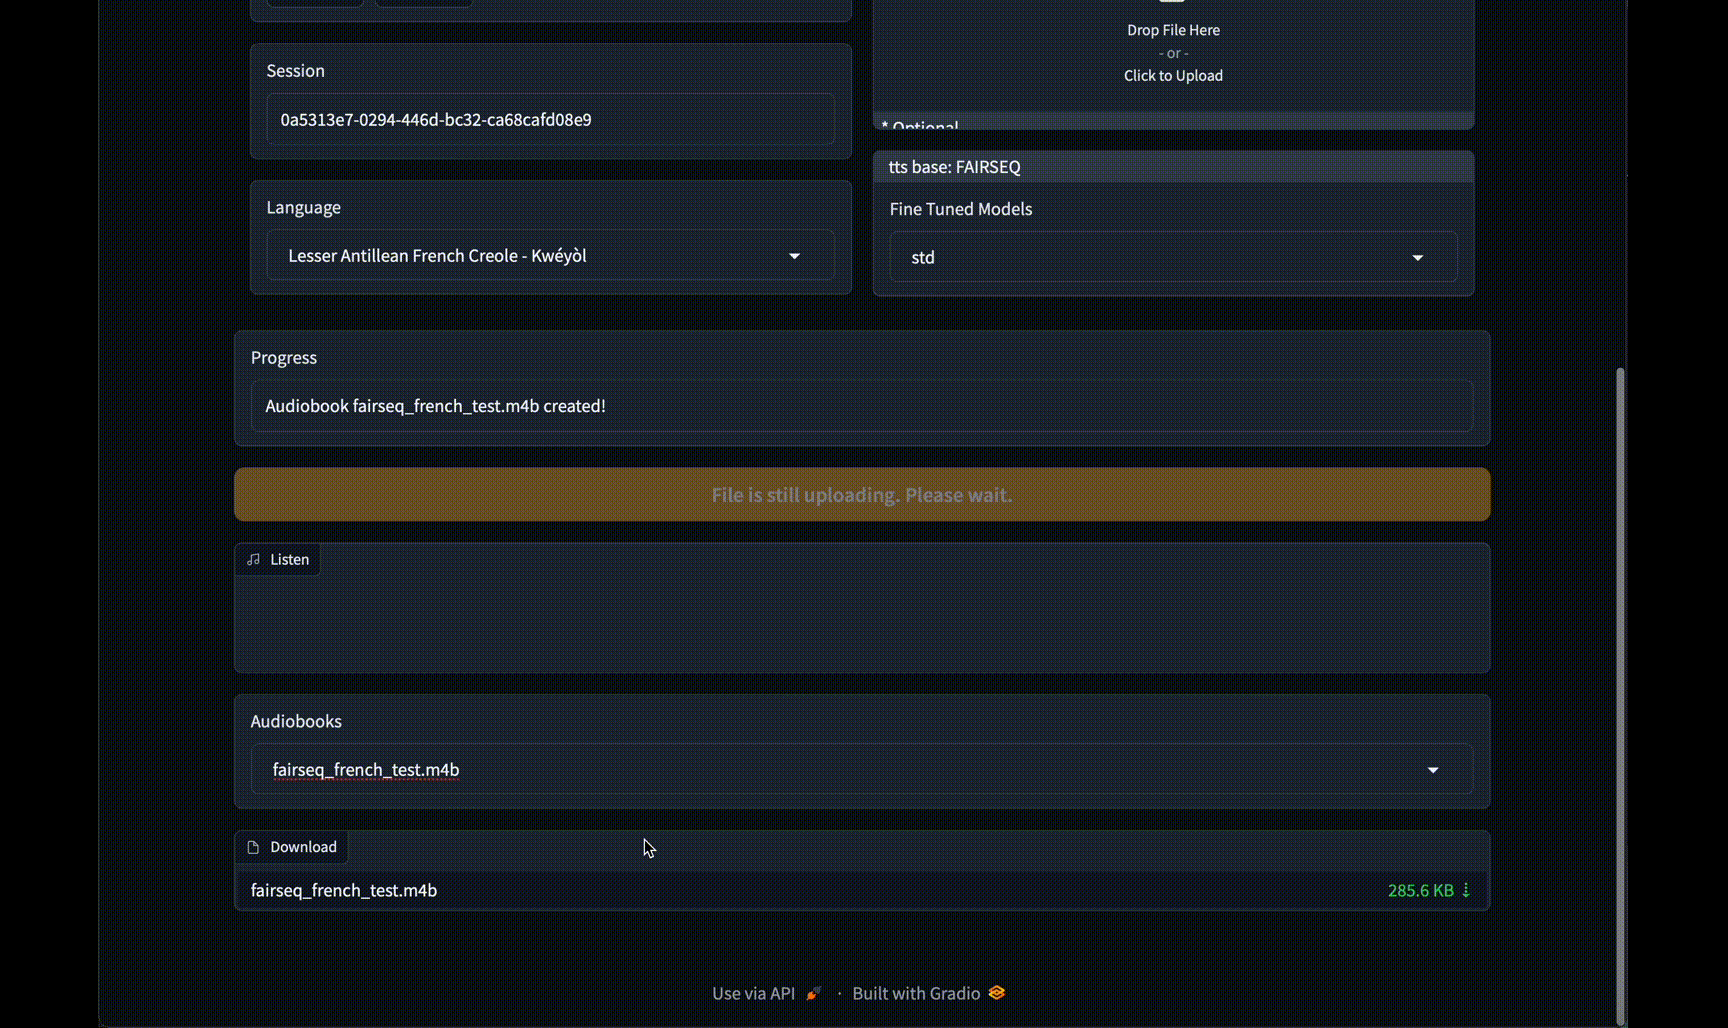
20.4KDrewThomasson/ebook2audiobook · PythonA converter that turns DRM-free e-books into audiobooks with chapters and metadata, using TTS engines with optional voice cloning, in 1158+ languages. It runs locally on modest hardware or in Docker.
- 26
pyvideotrans
19.4Kjianchang512/pyvideotrans · PythonAn open-source video translation and dubbing tool: it converts a video from one language to another through a one-click pipeline of speech recognition, subtitle translation, TTS dubbing, and video synthesis.
- 27

dia
19.4Knari-labs/dia · PythonDia is a 1.6B-parameter open-weights text-to-speech model from Nari Labs that generates ultra-realistic multi-speaker dialogue from a transcript in a single pass.
- 28
pot-desktop
19.4Kpot-app/pot-desktop · JavaScriptPot is a cross-platform desktop app for instant translation: select text anywhere on screen, press a hotkey, get a translation. It also does screenshot OCR, text-to-speech, and exports words to vocabulary apps like Anki.
- 29
kirara-ai
19.1Klss233/kirara-ai · PythonKirara AI is a DIY, open-source multimodal AI chatbot you self-host: a Python server that plugs mainstream LLMs into chat platforms like QQ, Telegram, Discord and WeChat.
- 30
VideoLingo
18.8KHuanshere/VideoLingo · PythonVideoLingo is an all-in-one AI tool for video translation, localization, and dubbing. It generates Netflix-quality single-line subtitles and can add high-quality dubbing, fully automated in one click.
- 31

Speech
18.6KNVIDIA-NeMo/Speech · PythonAn open-source NVIDIA framework for building speech AI models — automatic speech recognition (ASR), text-to-speech (TTS), and speech LLMs — with pre-trained checkpoints you can customize and deploy.
- 32

aimoneyhunter
18.3Kbleedline/aimoneyhunterThis is a curated Chinese-language collection of ideas, tutorials, and tools for making money with AI side hustles - covering AI video, images, text, audio, and live streaming projects.
- 33
leon
17.6Kleon-ai/leon · TypeScriptLeon is an open-source personal AI assistant that runs locally and is built around tools, context, memory, and agentic execution — it understands a goal, uses real tools, and completes tasks end to end.
- 34
awesome-ai-apps
16.4KArindam200/awesome-ai-apps · PythonA curated collection of 132 projects, tutorials, and recipes for building LLM-powered applications - covering text agents, voice assistants, RAG apps, and MCP-backed tools.
- 35

transformers.js
16.4Khuggingface/transformers.js · JavaScriptTransformers.js lets you run Hugging Face's state-of-the-art machine learning models directly in a web browser, with no server required, using an API designed to mirror the Python transformers library.
- 36
KittenTTS
16.2KKittenML/KittenTTS · PythonKitten TTS is an open-source, lightweight text-to-speech library built on ONNX that converts text into natural-sounding speech using tiny 15M-80M parameter models, running entirely on CPU.
- 37

lectures
15.9Koxford-cs-deepnlp-2017/lecturesThe lecture slides and course description for the Deep Natural Language Processing course offered in Hilary Term 2017 at the University of Oxford: an advanced, applied NLP course organised by Phil Blunsom and delivered in partnership with the DeepMind Natural Language Research Group.
- 38

F5-TTS
15.4KSWivid/F5-TTS · PythonF5-TTS is a text-to-speech system that generates fluent, faithful speech using flow matching with a Diffusion Transformer (ConvNeXt V2 backbone), and it supports cloning a speaker's voice from a short reference clip.
- 39

sherpa-onnx
15.4Kk2-fsa/sherpa-onnx · C++sherpa-onnx is an offline toolkit for speech-to-text, text-to-speech, speaker diarization, speaker identification/verification, spoken language identification, audio tagging, VAD, speech enhancement, keyword spotting and source separation, built on next-gen Kaldi and ONNX Runtime, with no internet connection required.
- 40

tortoise-tts
14.9Kneonbjb/tortoise-tts · Jupyter NotebookTortoise is a text-to-speech system built with an emphasis on quality: strong multi-voice capabilities and highly realistic prosody and intonation. This repo contains everything needed to run it in inference mode.
- 41
OmniVoice
14.8Kk2-fsa/OmniVoice · PythonOmniVoice is a zero-shot text-to-speech model that supports over 600 languages, built on a diffusion language model-style architecture, with voice cloning and voice design capabilities.
- 42

csm
14.7KSesameAILabs/csm · PythonCSM (Conversational Speech Model) is a speech generation model from Sesame that turns text and audio input into spoken audio by producing RVQ audio codes, using a Llama backbone plus a smaller audio decoder.
- 43

subtitleedit
14.6KSubtitleEdit/subtitleedit · C#Subtitle Edit is an open-source subtitle editor: it creates, edits, converts and syncs subtitle files, with video playback built in so you can time lines against the actual media.
- 44
Open-LLM-VTuber
14.2KOpen-LLM-VTuber/Open-LLM-VTuber · PythonOpen-LLM-VTuber is a voice-interactive AI companion with a Live2D avatar that you talk to with your voice, running entirely offline on your own computer. It supports real-time voice conversations, visual perception (camera/screen), and can act as a virtual girlfriend, boyfriend, pet, or custom character.
- 45
ai-edu
14.1Kmicrosoft/ai-edu · HTMLAI-Edu is an open-source AI education community created by Microsoft Research Asia's AI education team, offering systematised tutorials, practice cases and practice projects for Chinese learners.
- 46
Qwen3-TTS
13.9KQwenLM/Qwen3-TTS · PythonQwen3-TTS is an open-source text-to-speech model series from Alibaba's Qwen team that generates stable, expressive speech, supports voice design from text descriptions, and can clone voices from a short audio sample.
- 47
LunaTranslator
13.8KHIllya51/LunaTranslator · C++LunaTranslator is a Windows desktop tool that extracts text from visual novels and galgames in real time (mainly via text hooking) and translates it, so you can play untranslated Japanese games.
- 48
supertonic
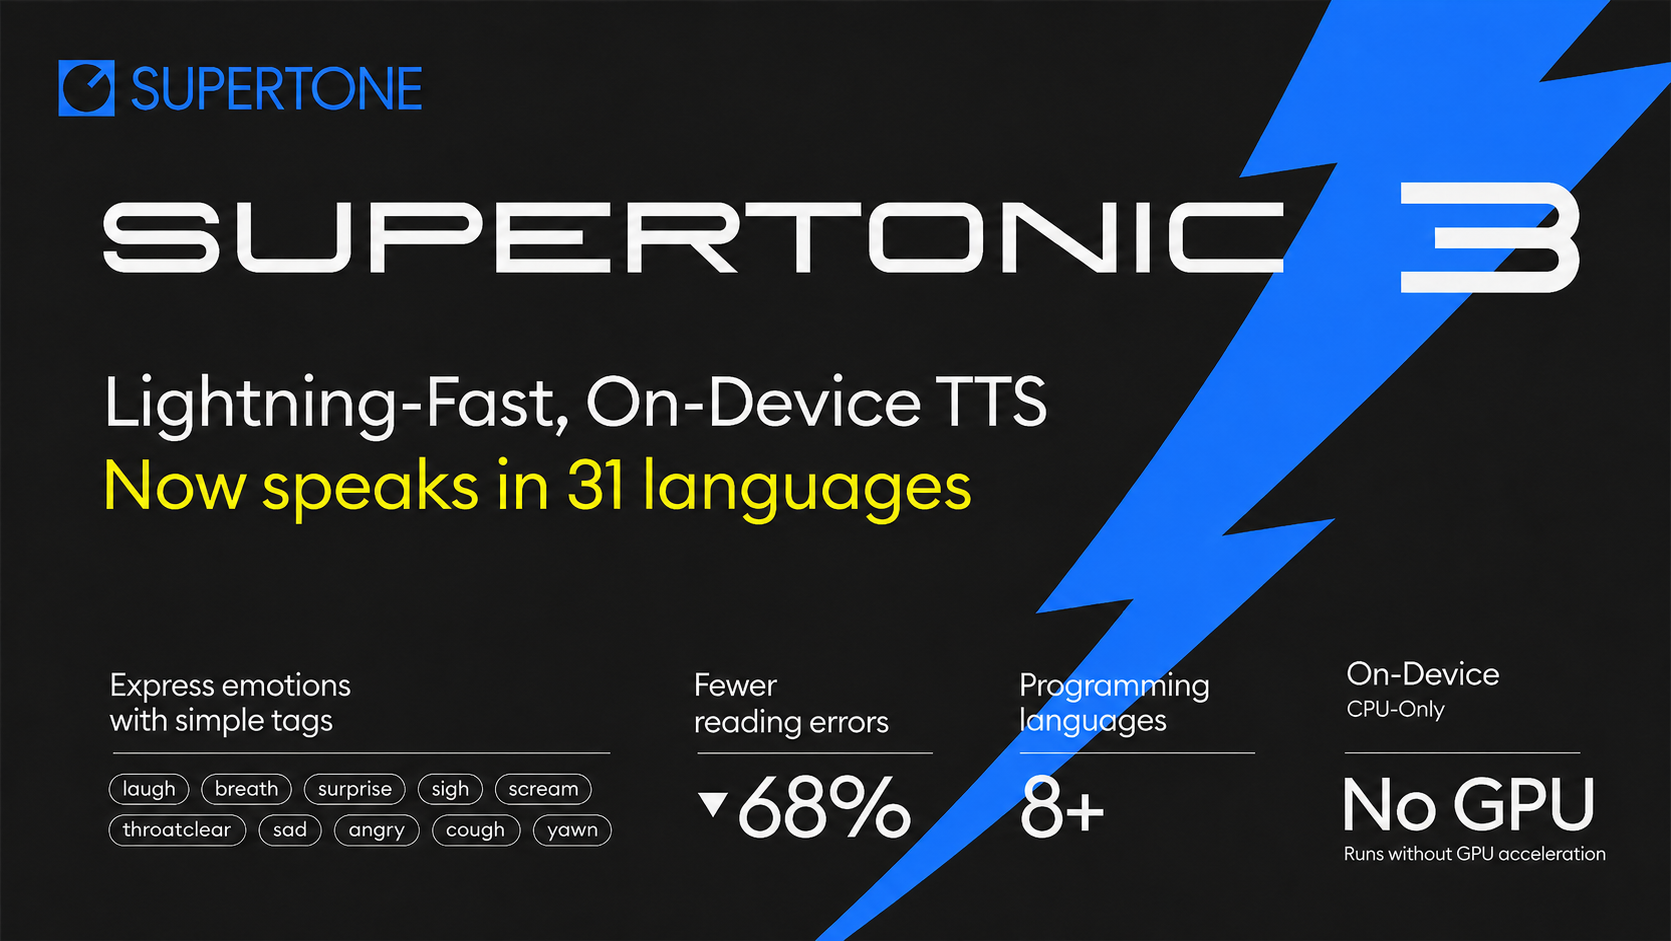
13.8Ksupertone-oss-archive/supertonic · SwiftSupertonic is a lightning-fast, on-device text-to-speech system: it converts text into 44.1kHz 16-bit WAV speech locally via ONNX Runtime — no cloud, no API calls, no GPU. The open-weight model, Supertonic 3, covers 31 languages.
- 49
skills
13.7KMiniMax-AI/skills · C#MiniMax Skills is a collection of plug-in 'skill' packages that give AI coding agents (Claude Code, Cursor, Codex, OpenCode) structured, production-quality guidance for frontend, fullstack, Android, iOS, Flutter, React Native, shader work, and MiniMax-API-powered media generation (images, video, music, TTS, documents).
- 50
voice-pro
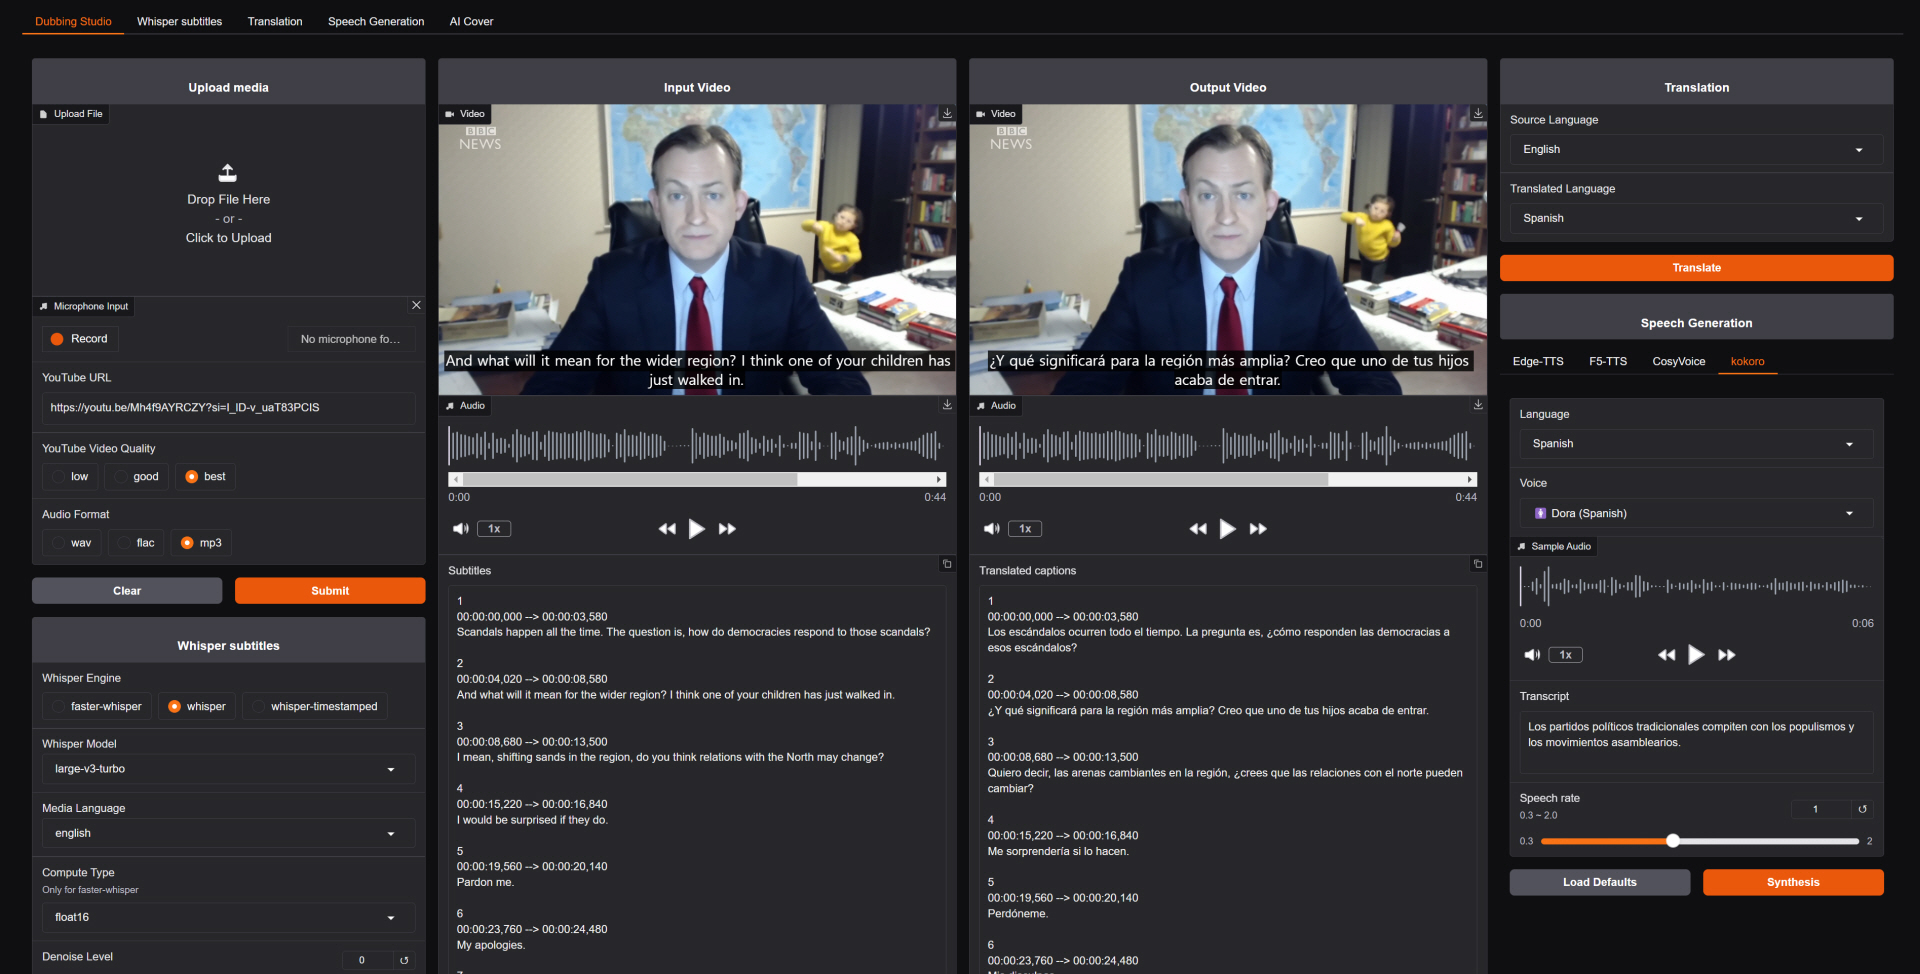
13.2Kabus-aikorea/voice-pro · PythonVoice-Pro is a free, open-source AI web app (built with Gradio) that combines speech recognition, zero-shot voice cloning, text-to-speech, YouTube downloading, vocal isolation, and multilingual translation into one tool for creators and researchers.
- 51
PaddleSpeech
12.7KPaddlePaddle/PaddleSpeech · PythonPaddleSpeech is an open-source speech and audio toolkit built on the PaddlePaddle platform, covering tasks like Automatic Speech Recognition (ASR), Text-to-Speech (TTS), Speaker Verification, Speech Translation, Keyword Spotting and Punctuation Restoration. It won the NAACL2022 Best Demo Award.
- 52

RedditVideoMakerBot
12.5Kelebumm/RedditVideoMakerBot · PythonA Python bot that turns Reddit posts into short-form videos with text-to-speech narration and background footage, ready to upload to TikTok, YouTube, or Instagram.
- 53

Yuedu
12.5KXIU2/YueduThis is a personal collection of 'book sources' (JSON parsing rule files) for the Chinese novel-reading app '阅读' (Legado). The sources tell the app how to search, list chapters, and extract text from various free novel websites.
- 54

edge-tts
12.3Krany2/edge-tts · Pythonedge-tts is a Python module and CLI that lets you use Microsoft Edge's online text-to-speech service from your code or terminal, without needing Microsoft Edge, Windows, or an API key.
- 55
Anki-Android
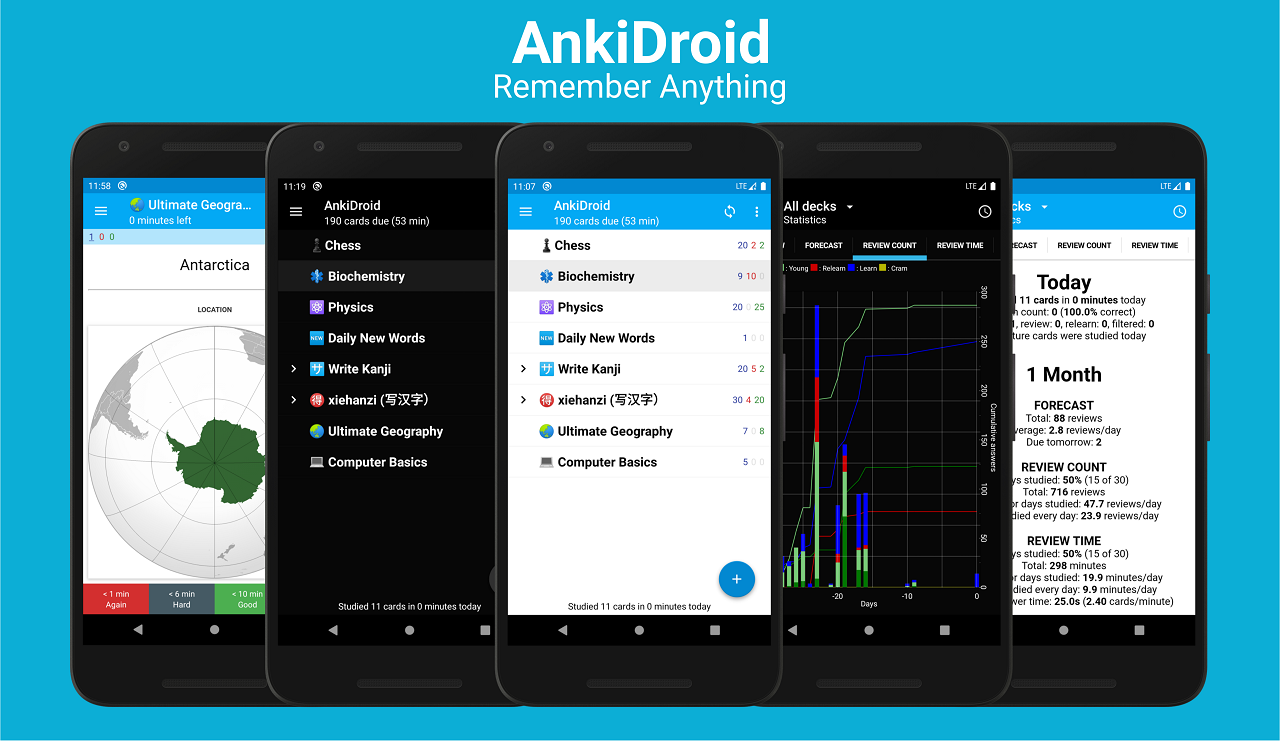
12Kankidroid/Anki-Android · KotlinAnkiDroid is the Android port of Anki, an open-source spaced repetition flashcard system that helps you memorize anything more efficiently.
- 56

seamless_communication
11.9Kfacebookresearch/seamless_communication · Jupyter NotebookSeamless Communication is Meta's family of foundational AI models for speech and text translation across roughly 100 languages, covering speech-to-speech, speech-to-text, text-to-speech and text-to-text translation plus automatic speech recognition.
- 57
TranslationPlugin
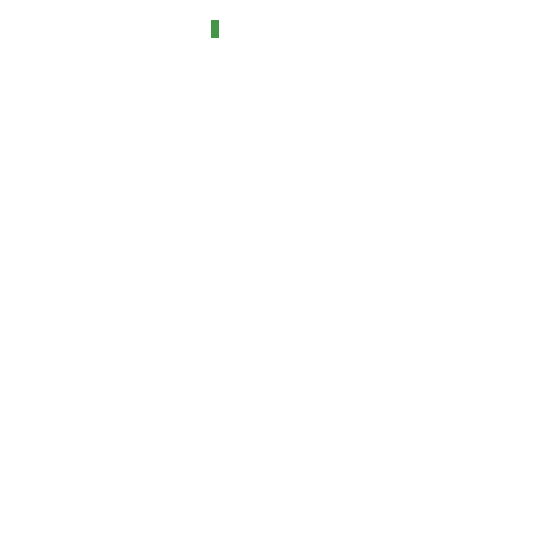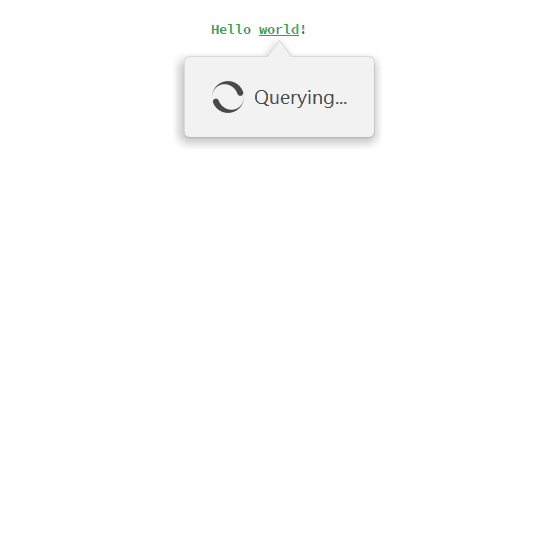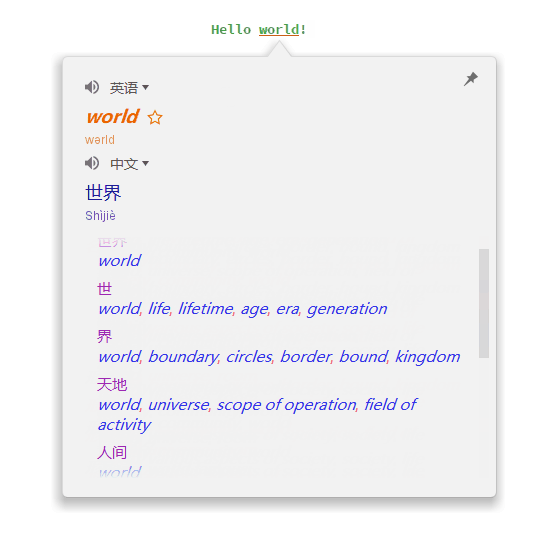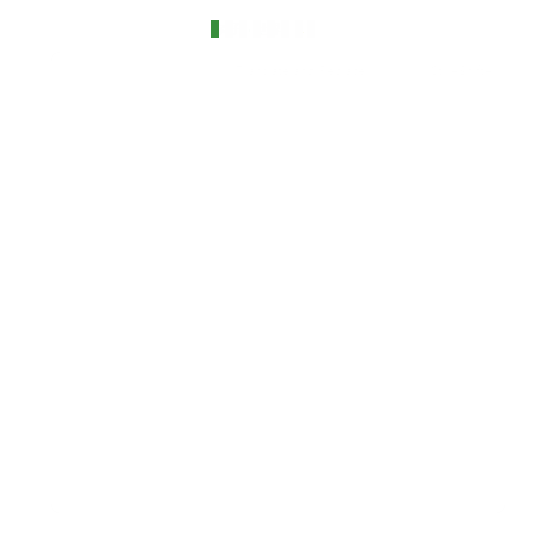
11.9KYiiGuxing/TranslationPlugin · KotlinTranslationPlugin is a translation plugin for IntelliJ-based IDEs and Android Studio that lets you translate text, documentation and code symbols right inside the editor using multiple translation engines.
- 58
OpenJarvis
11.6Kopen-jarvis/OpenJarvis · PythonOpenJarvis is an open-source framework for personal AI that runs on your own devices: agents use local models by default and call the cloud only when truly necessary.
- 59
NarratoAI
11.5Klinyqh/NarratoAI · PythonNarratoAI is an all-in-one AI tool for film/show narration and automated video editing: it uses an LLM to write the narration script, then automatically edits the footage, generates voice-over, and adds subtitles.
- 60

piper
11.3Krhasspy/piper · C++Piper is a fast, local neural text-to-speech (TTS) engine written in C++ that converts text into speech entirely on-device, without needing a cloud service.
- 61
moonshine
11.3Kmoonshine-ai/moonshine · C++Moonshine Voice is an open source AI toolkit for building real-time voice agents and interfaces, covering speech-to-text, intent recognition, and text-to-speech.
- 62

ten-framework
11.2KTEN-framework/ten-framework · PythonTEN is an open-source framework for building real-time, multimodal conversational voice AI agents, with example agents for assistants, drawing, speaker diarization, lip-sync avatars, SIP calls, and transcription.
- 63
Spark-TTS
11KSparkAudio/Spark-TTS · PythonSpark-TTS is a text-to-speech system that uses a large language model (built on Qwen2.5) to generate highly natural, accurate speech, including zero-shot voice cloning.
- 64
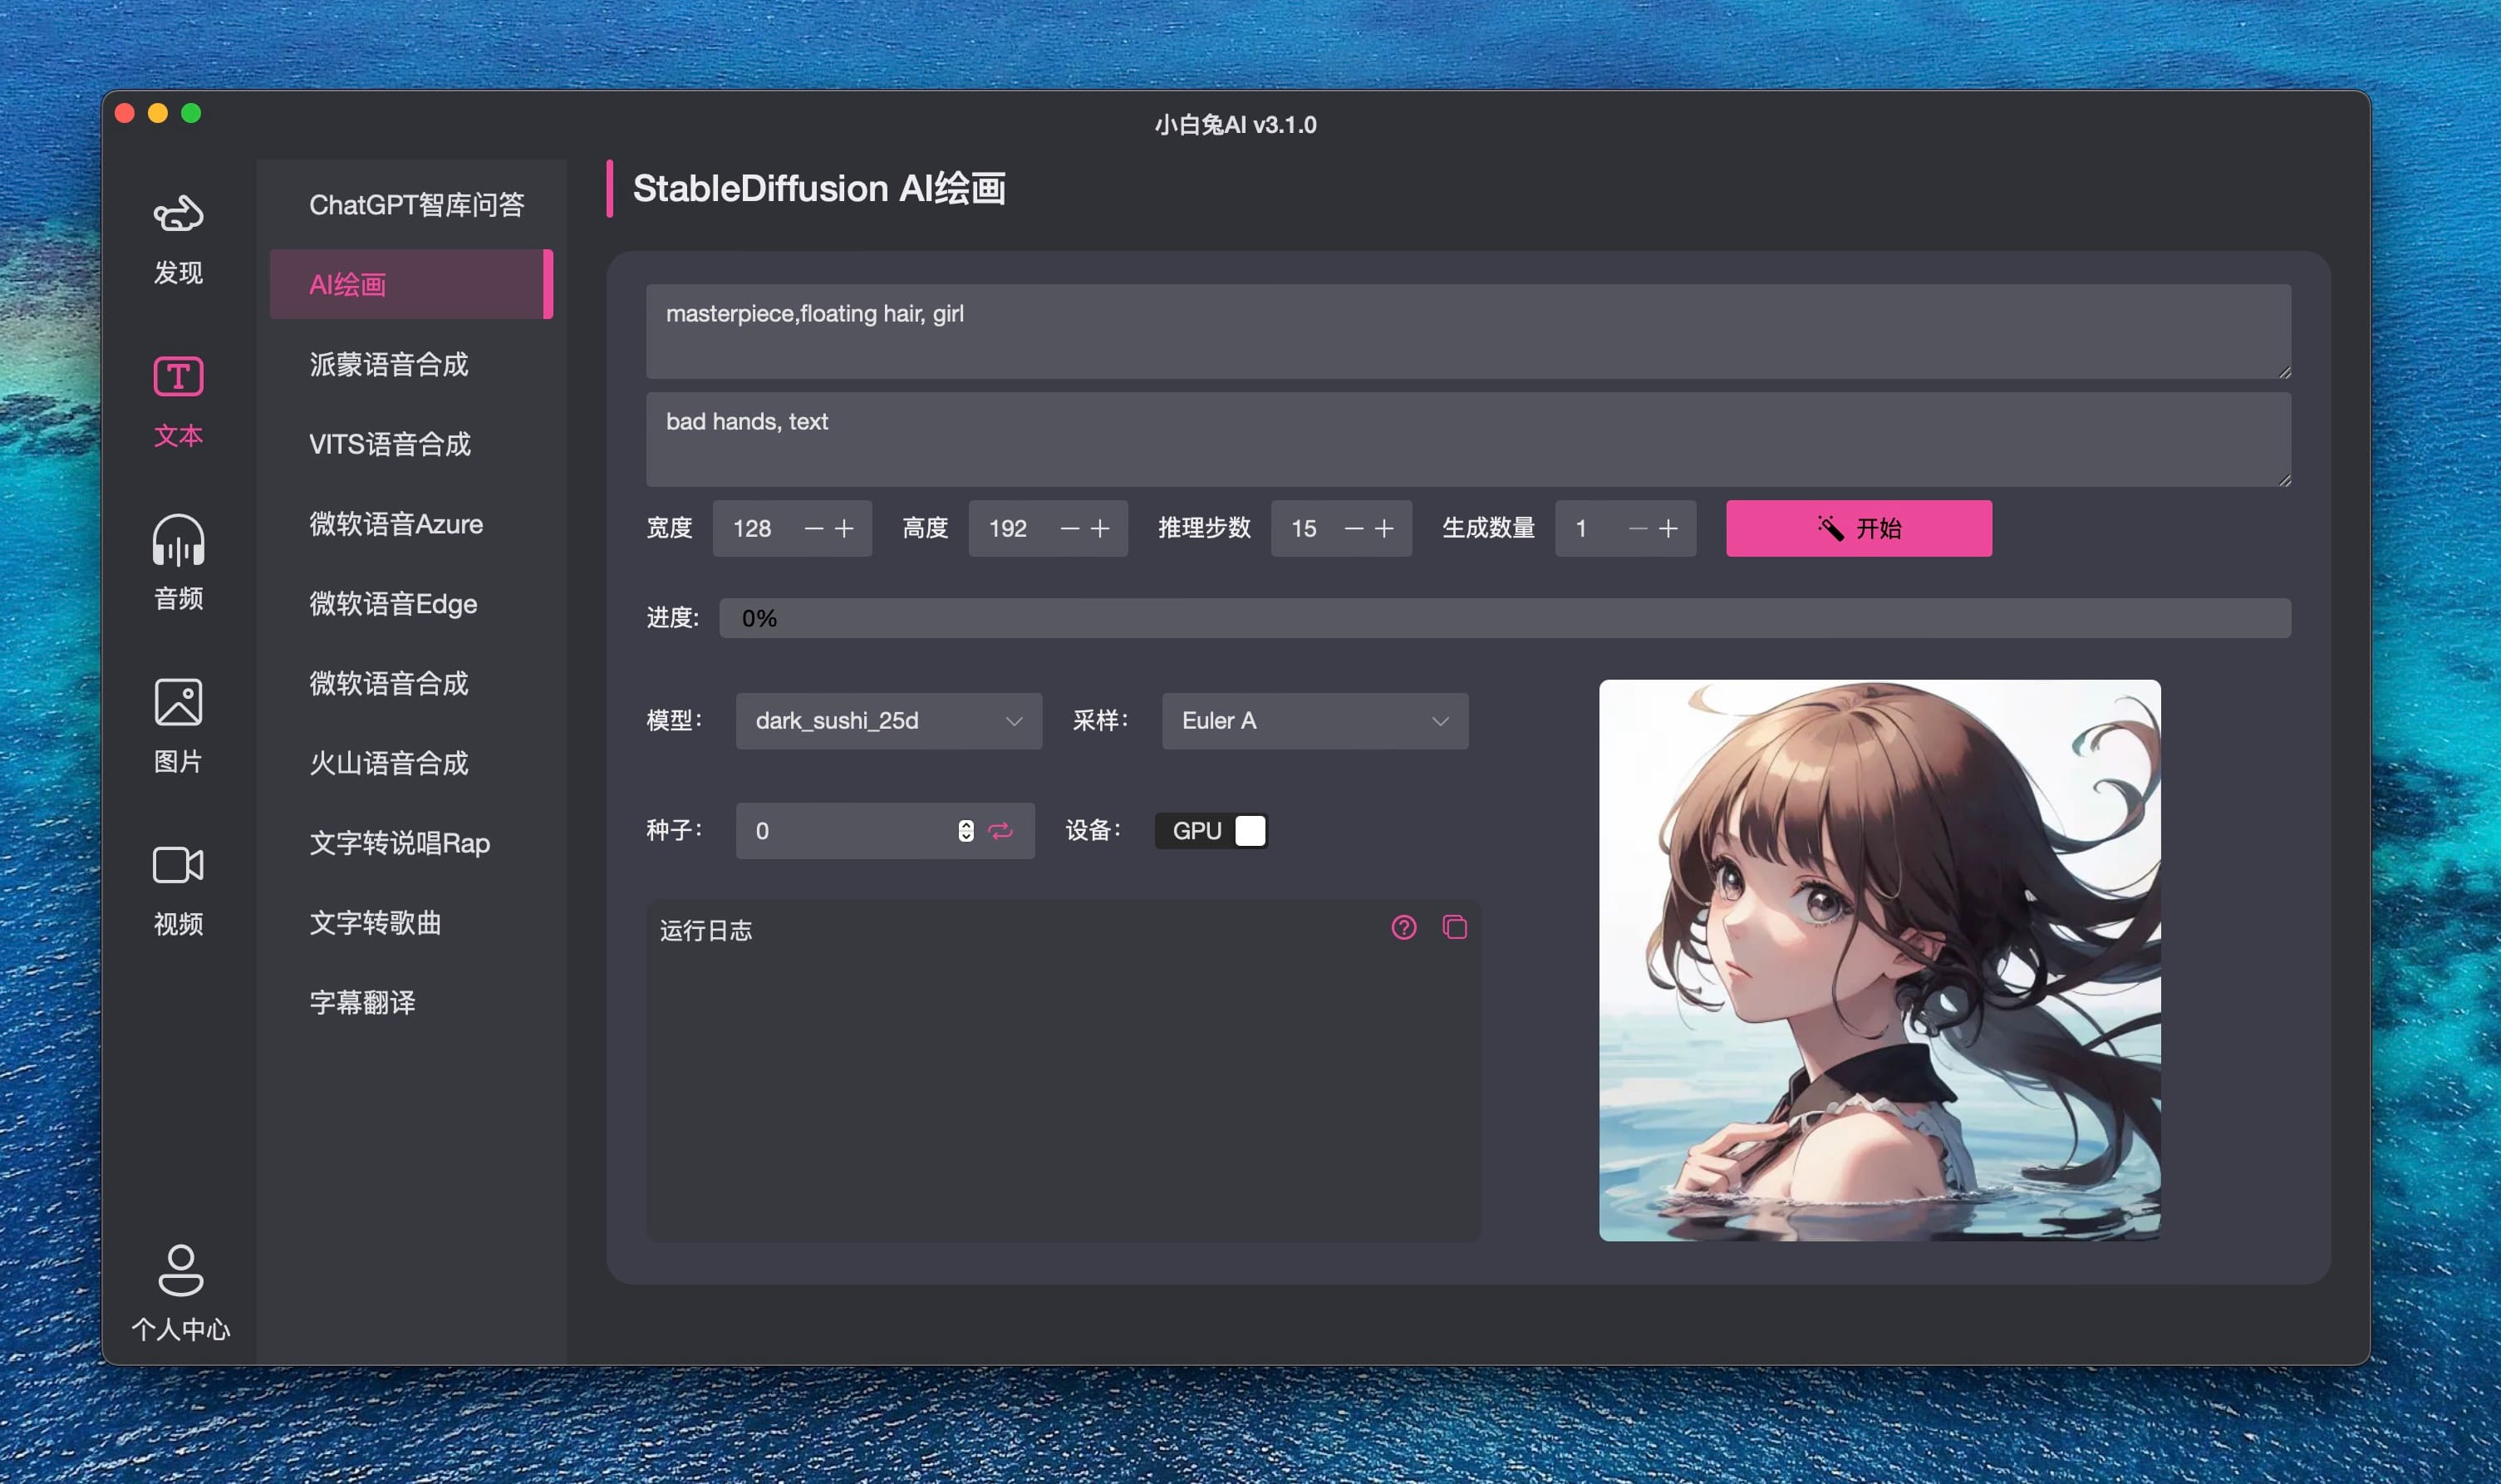
paper2gui
10.7KBaiyuetribe/paper2gui · Jupyter NotebookA desktop toolbox that wraps research AI models into ready-to-run apps for non-coders: 50+ models for AI painting, speech synthesis, video frame interpolation, video super-resolution and OCR.
- 65
RTranslator
10.5Kniedev/RTranslator · JavaRTranslator is an open-source Android app that translates conversations in real time. Speech recognition and translation run entirely on your phone — no cloud service behind it.
- 66
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 67
Amphion
10.3Kopen-mmlab/Amphion · PythonAn open-source toolkit for audio, music, and speech generation. It is built to support reproducible research and help junior researchers and engineers get started in the field.
- 68

TTS
10.2Kmozilla/TTS · Jupyter NotebookAn open-source deep learning library for text-to-speech: pretrained models, vocoders, a speaker encoder and dataset tools, already used in 20+ languages for products and research.
- 69

AudioGPT
10.2KAIGC-Audio/AudioGPT · PythonAudioGPT is an open-source research system for understanding and generating speech, music, sound, and talking heads — pretrained foundation models wrapped behind prompt-driven audio tasks.
- 70
pocket-tts
9.9Kkyutai-labs/pocket-tts · PythonPocket TTS is a lightweight text-to-speech engine from Kyutai that runs efficiently on CPU only, using a tiny 100M-parameter model with streaming audio output and voice cloning.
- 71
ODS
7.6KOsmantic/ODS · PythonODS (Osmantic Deployment System) turns your PC, Mac, or Linux box into a private AI server by installing and wiring together local LLM inference, a chat UI, agents, voice, RAG, image generation, and privacy tools in one go.
- 72

neutts
6.3Kneuphonic/neutts · PythonNeuTTS is a collection of open-source, on-device text-to-speech language models that can clone a voice from just a few seconds of reference audio.
- 73

LuxTTS
5.5Kysharma3501/LuxTTS · PythonLuxTTS is a lightweight text-to-speech model built on the ZipVoice architecture, designed for high-quality voice cloning and fast speech generation.
- 74
OpenMausBot
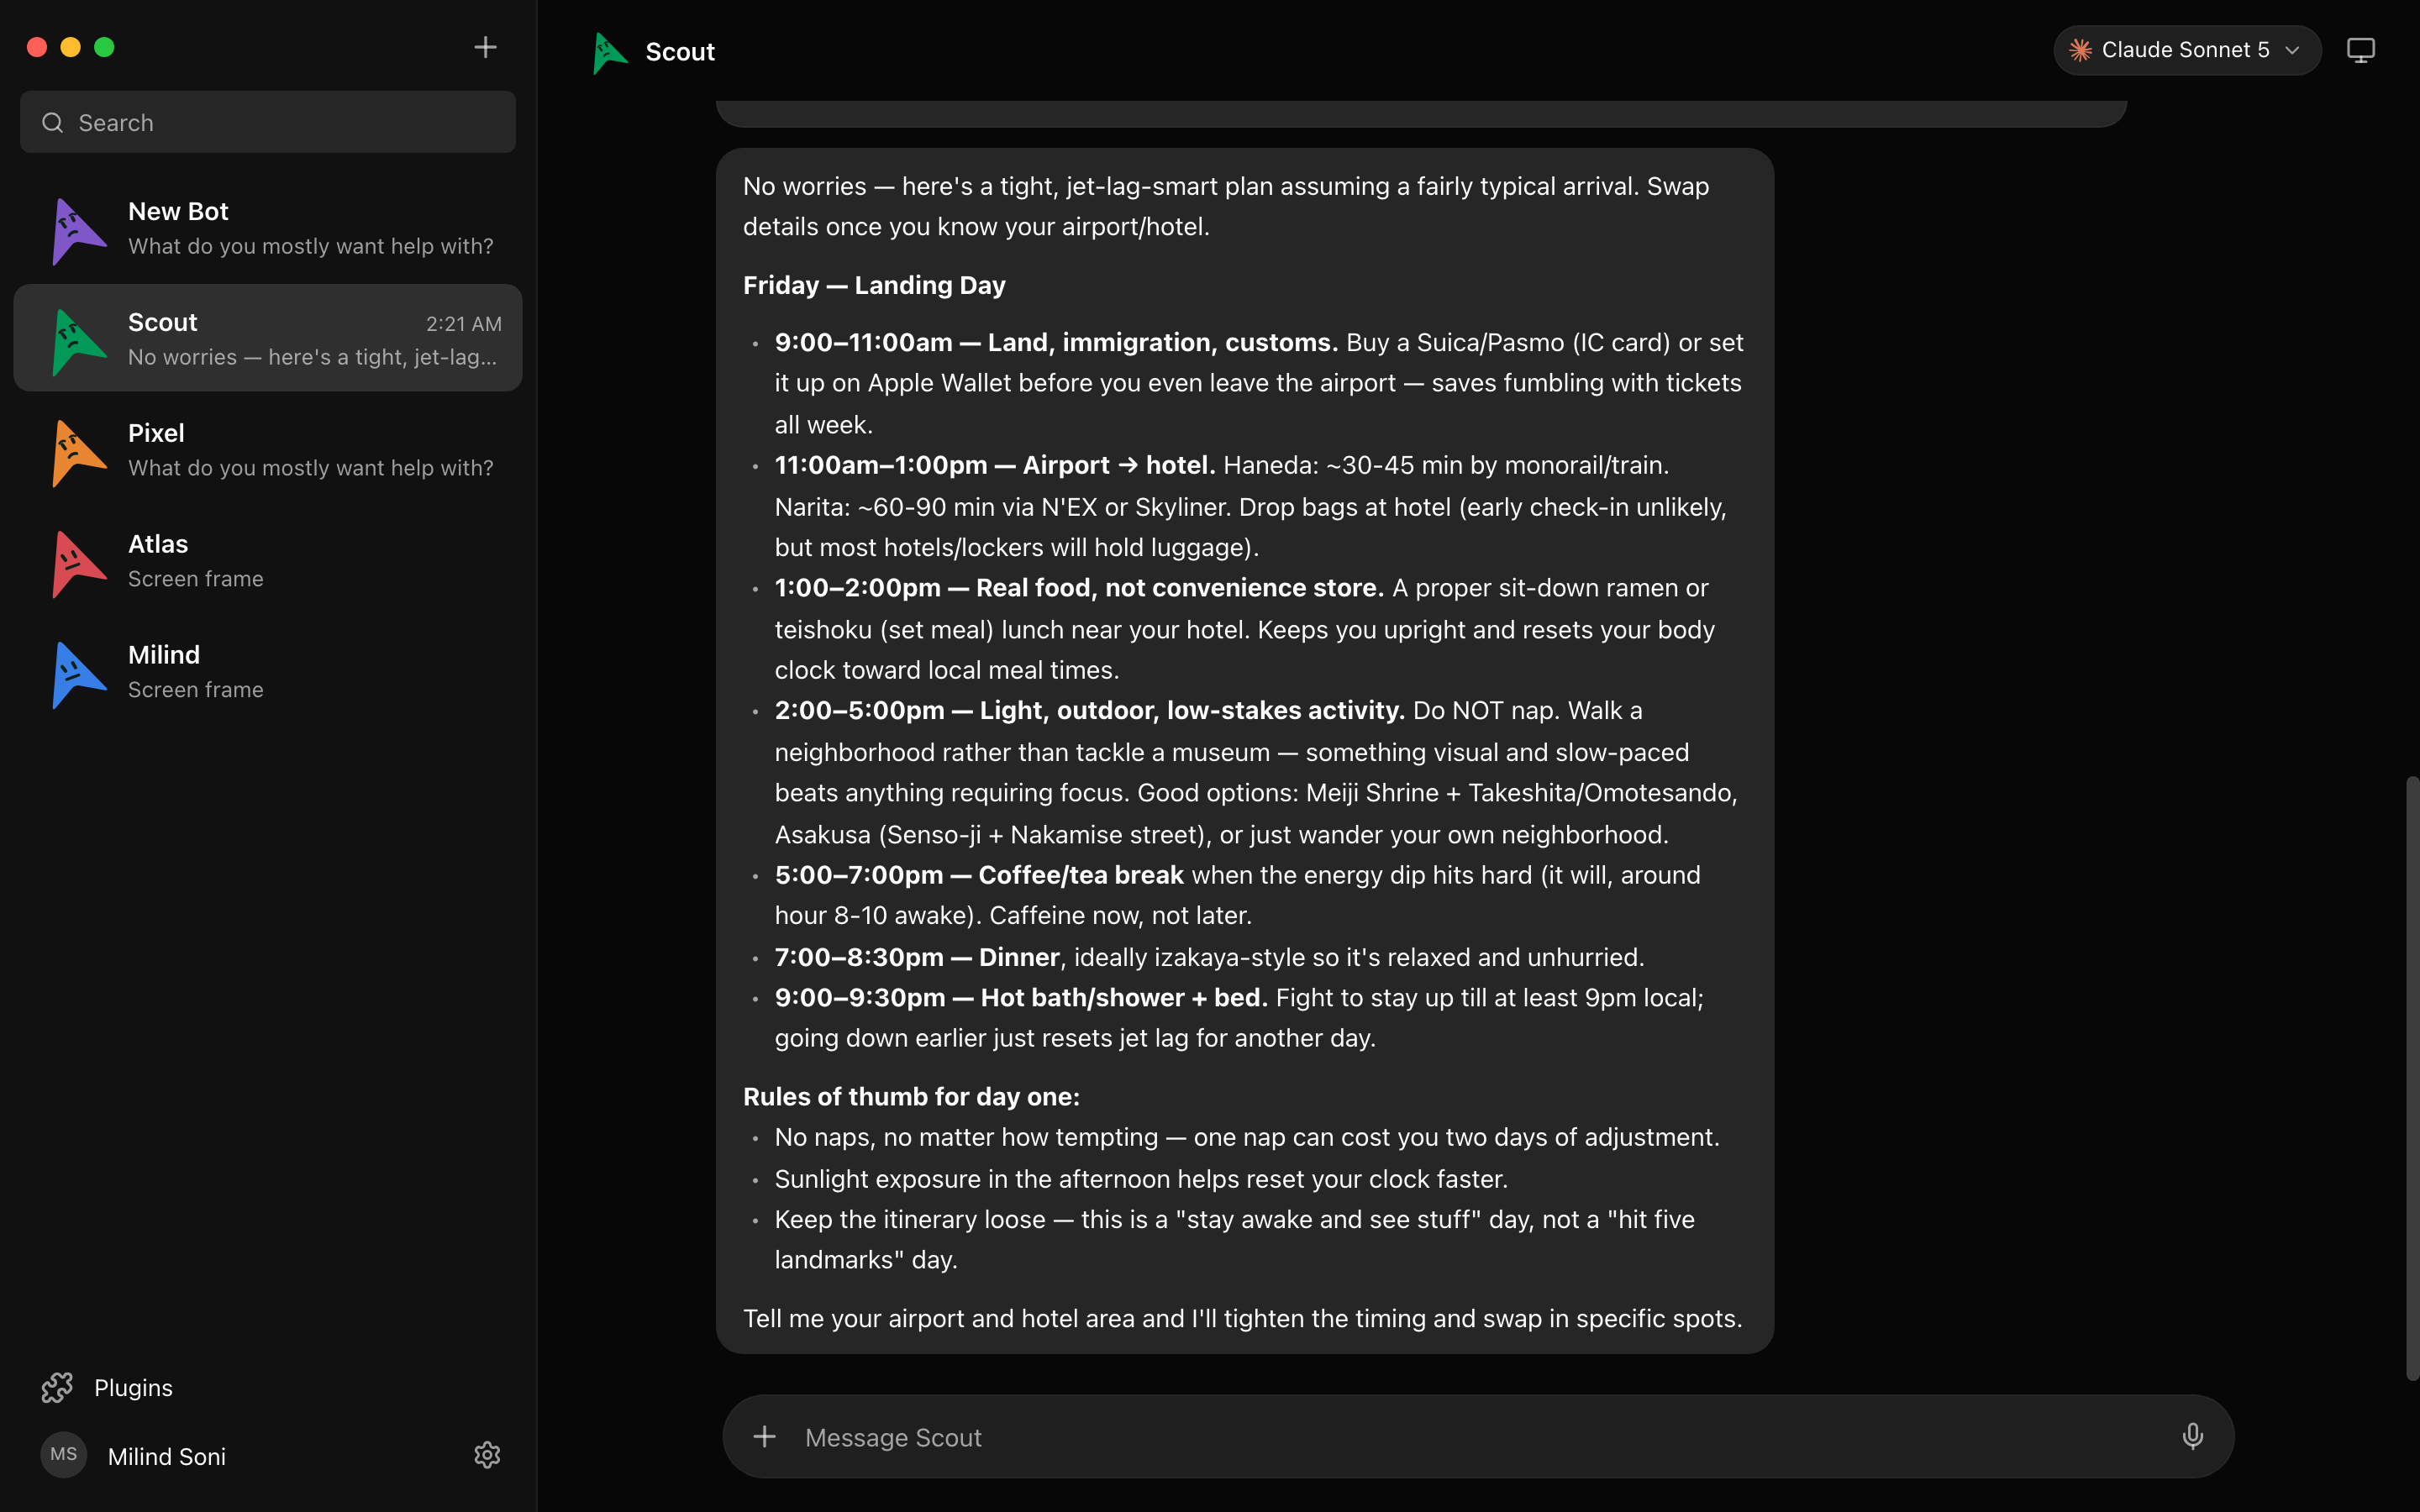
5.1Kmilind-soni/OpenMausBot · TypeScriptOpenMausBot is an open-source, local-first alternative to Grok Bot: a chat app where every bot in the sidebar is a real AI agent (Claude, Codex, or Grok) running on your own machine, each with its own personality, model, memory, and a 'computer' it can use to do work.
- 75
MOSS-TTS-Nano
4.5KOpenMOSS/MOSS-TTS-Nano · PythonMOSS-TTS-Nano is an open-source, 100M-parameter multilingual text-to-speech model from MOSI.AI and OpenMOSS that supports voice cloning, 48kHz stereo output, and real-time generation directly on CPU.
- 76

youtube-automation-agent
4.4KdarkzOGx/youtube-automation-agent · JavaScriptAgentTube (youtube-automation-agent) is an open-source AI agent that runs a YouTube channel end to end: it researches topics, writes scripts, generates narration and visuals, assembles videos, optimizes metadata, runs review gates, schedules, publishes, and learns from analytics.
- 77
jianying-editor-skill
4.2Kluoluoluo22/jianying-editor-skill · PythonIt is an AI agent skill that fully automates video editing inside JianYing (the Chinese version of CapCut). You describe the video you want in natural language, and it writes the script, generates voiceover, adds subtitles, picks music and effects, and exports the final cut.
- 78
MOSS-TTS
4.2KOpenMOSS/MOSS-TTS · PythonMOSS-TTS Family is an open-source speech and sound generation model family from OpenMOSS, covering long-form narration, multi-speaker dialogue, voice design, sound effects, and real-time streaming text-to-speech.
- 79

Qwen3-Omni
4.1KQwenLM/Qwen3-Omni · Jupyter NotebookQwen3-Omni is a family of open, natively end-to-end omni-modal LLMs from Alibaba's Qwen team: they take text, images, audio and video as input and stream back answers as text or natural speech in real time.
- 80
Rapid-MLX
4Kraullenchai/Rapid-MLX · PythonRapid-MLX is a local LLM inference server for Apple Silicon Macs, built on MLX, that exposes OpenAI- and Anthropic-compatible APIs and focuses on reliable tool calling for coding agents like Claude Code and Codex CLI.
- 81
Easel
3.9KZJU-REAL/Easel · PythonEasel is an open-source content workbench built around an AI agent that discovers trends, plans topics, creates text/image/audio/video content, publishes it to Chinese social platforms, and learns from performance data to improve future content.
- 82

answer-me-with-html
3.7KQingYunA/answer-me-with-html · JavaScriptAnswer me with HTML is an agent skill that turns a coding agent's long text answers into a single-page HTML with diagrams, tables, or timelines instead of a wall of text. The model only writes a short Markdown draft and a bundled CLI renders the layout, CSS and SVG.
- 83
SoulX-Podcast
3.6KSoul-AILab/SoulX-Podcast · PythonSoulX-Podcast is an inference codebase that generates realistic, long-form, multi-speaker podcast-style dialogue from text, including paralinguistic effects and several Chinese dialects.
- 84
lemo-opuscar
3.3Klemomo-ai/lemo-opuscar · JavaScriptLemo-Opuscar is a Claude Code skill that lets Claude Opus 5.5 direct, draw, score and mix short films entirely in code, with 43 ready-made film styles you can apply to your own story.
- 85
narrator-ai-cli-skill
3.1KNarratorAI-Studio/narrator-ai-cli-skillThis is a machine-readable skill file (SKILL.md) that teaches AI agents like Claude Code, Codex, or OpenClaw how to use the narrator-ai-cli tool to automatically produce movie narration videos.
- 86
lanshu-create-ai-presenter-video
2.7Kcclank/lanshu-create-ai-presenter-video · HTMLThis is a Codex Skill that turns a topic or script plus an authorized photo of a person into a full AI presenter video: it writes the script, generates voiceover, creates the character, syncs lips, adds subtitles and keyword animations, edits, renders and runs quality checks.
- 87
VoiceMem
2.6Kxzf-thu/VoiceMem · PythonVoiceMem is an open-source memory infrastructure for real-time voice agents, giving them long-term memory through a dual-brain architecture: a 'left brain' that stores factual information and a 'right brain' that tracks emotions and personality, built on a fully streaming pipeline to keep latency low.
- 88

threejs-game-skills
2.5Kmajidmanzarpour/threejs-game-skills · PythonA set of nine self-contained skill packages (SKILL.md files) that teach Codex and Claude Code how to build playable, polished Three.js browser games end-to-end, including gameplay, AAA-style graphics, UI, QA, and optional AI-generated 3D, image, and audio assets.
- 89
locally-uncensored
2.4KPurpleDoubleD/locally-uncensored · TypeScriptThis is an all-in-one local AI studio for your desktop that bundles chat, image and video generation, and a coding agent into a single free, open-source app for Windows and Linux.
- 90
Vela
2KPimpinPumpkin/Vela · KotlinVela is a degoogled maps and turn-by-turn navigation app for Android that runs with zero Google Play Services. It draws the basemap from open data (OpenStreetMap, Overture Maps, AllThePlaces) and only asks Google's public web endpoints, anonymously and per-device, for things open data lacks like live traffic, reviews and photos.
- 91
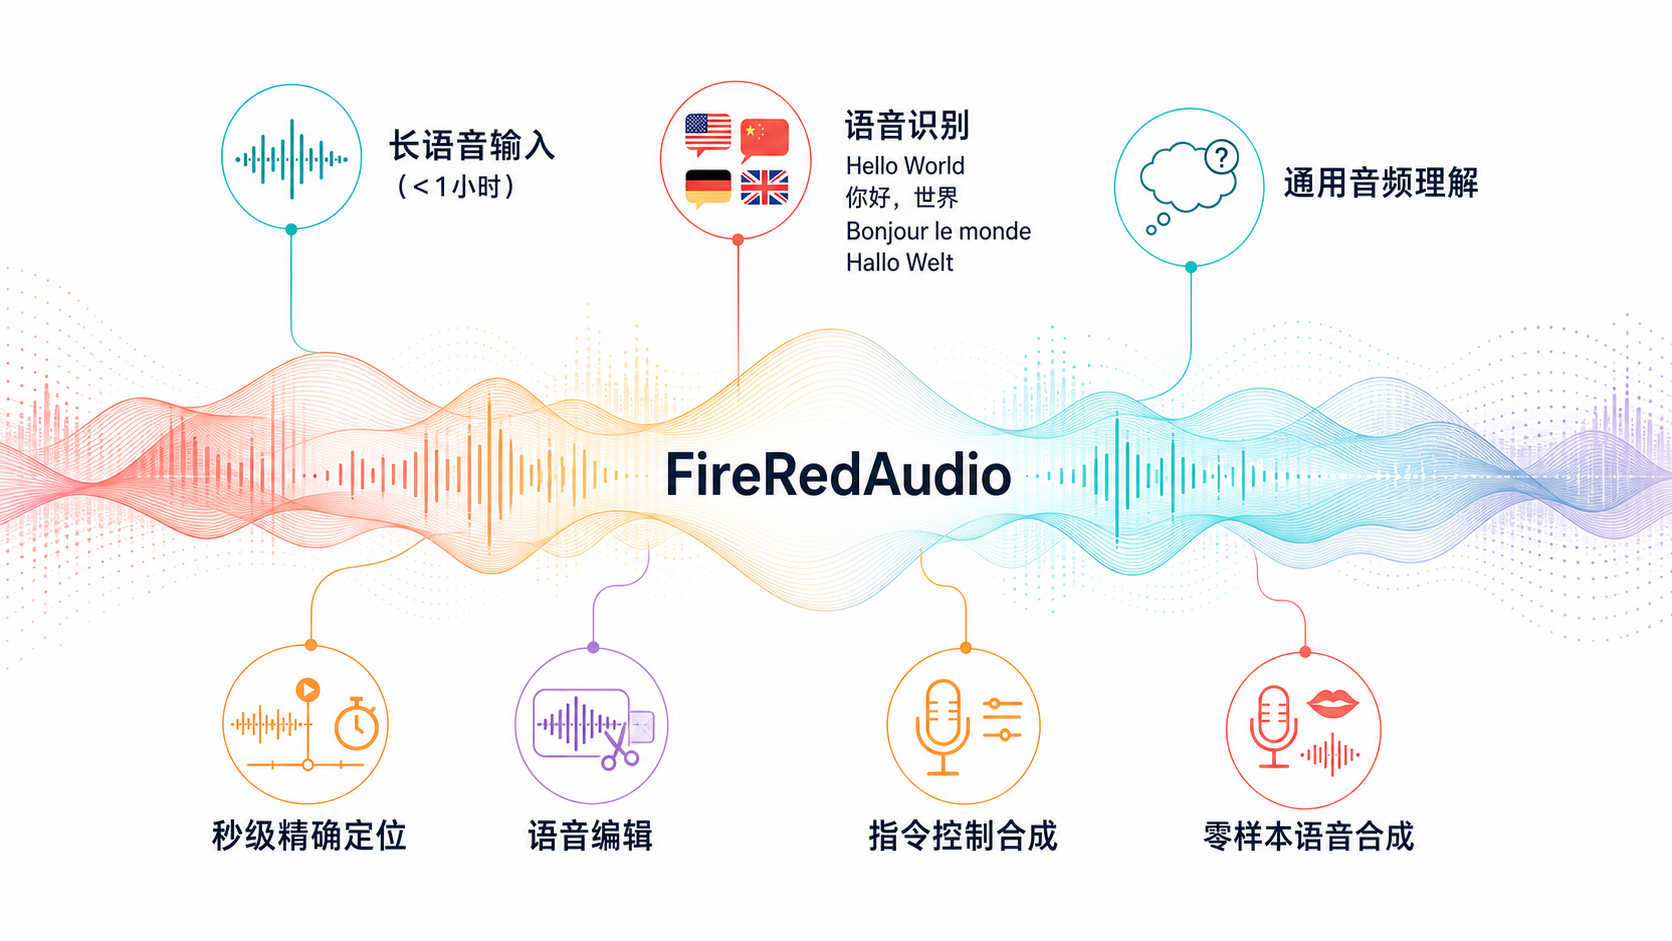
FireRedAudio
2KFireRedTeam/FireRedAudio · PythonFireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM that can transcribe speech (ASR), understand audio, do zero-shot and instruct text-to-speech, and edit speech, all from one model.
- 92
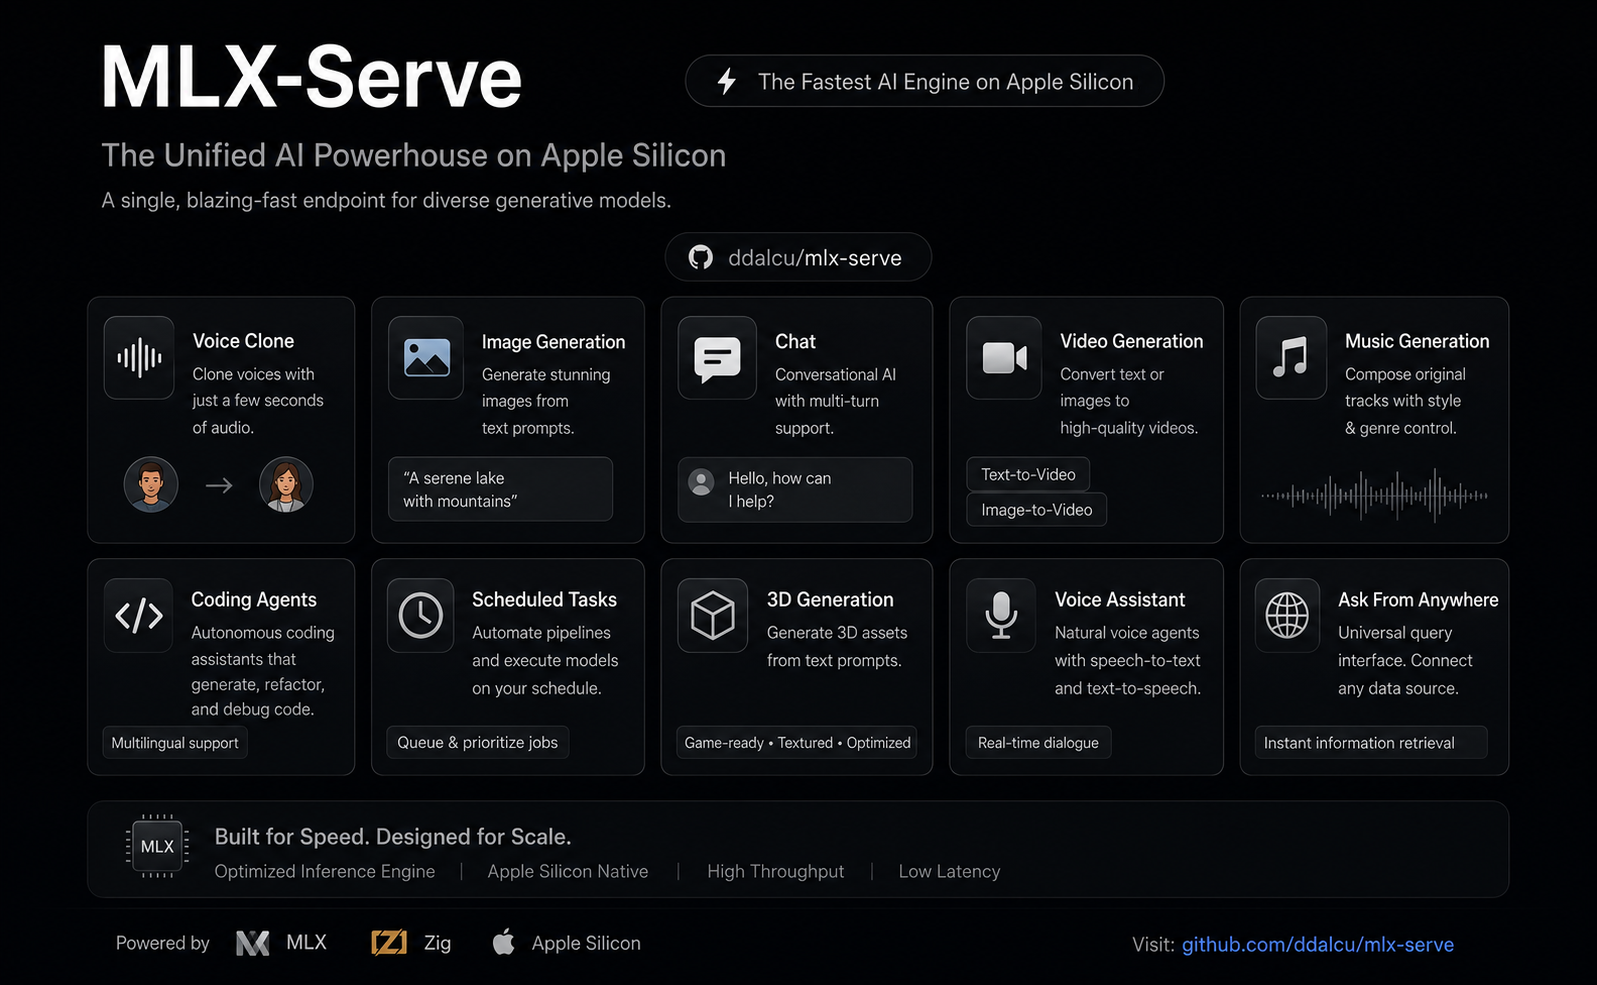
mlx-serve
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 93
VideoAgent
2KHKUDS/VideoAgent · PythonVideoAgent is an all-in-one agentic framework that understands, edits, and remakes videos from natural-language requests, handling everything from summarization to meme remixes and cross-lingual comedy adaptations.
- 94
FireRedTTS3
1.8KFireRedTeam/FireRedTTS3 · PythonFireRedTTS3 is a unified speech generation and editing model: it clones voices across 24 languages and 21 Chinese dialects, can design brand-new voices from a text description, and can edit existing speech (semantic and acoustic) using natural-language instructions.
- 95
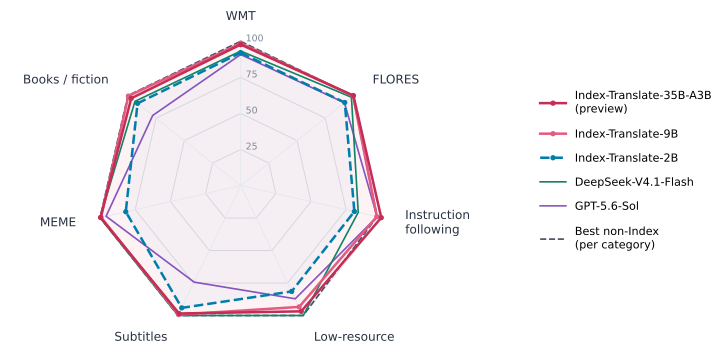
Index-Translate
1.7Kbilibili/Index-Translate · PythonIndex-Translate is a family of multilingual translation models built on Qwen3.5, covering text translation across 150 languages plus speech, syllable-controlled, and full-document translation variants.
- 96
yovoice
1.7Kleemysw/yovoice · TypeScriptyovoice is an open-source desktop app for macOS and Windows that turns text into natural, expressive speech locally, with voice cloning and emotion control, and no cloud API calls or per-character fees.
- 97
nobodywho
1.6Knobodywho-ooo/nobodywho · RustNobodyWho is an open-source inference engine that runs LLMs locally and offline on phones, desktops and even Apple Watch — no API keys, no cloud calls. Under the hood it is powered by llama.cpp and accelerates through the GPU via Vulkan or Metal.
- 98

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.
- 99
speech-swift
1.2Ksoniqo/speech-swift · SwiftSpeech Swift is a collection of on-device AI speech models for Apple Silicon — speech recognition (ASR), text-to-speech, speech-to-speech, voice activity detection, and speaker diarization — built as Swift packages powered by MLX and CoreML.
- 100
B
1.2KAhmadHassan-BTed/B · PythonB is an autonomous AI desktop companion that lives on your screen as an animated floating face, watching your active windows and screen content, listening to you, and proactively speaking up when it has something useful to say.
Showing the 100 most-starred of 133. See every one in the catalog.
Related topics
Often tagged together
- python2,425
- ai1,993
- linux4,248
- open-source5,749
- macos3,608
- windows3,480
- tts119
- llm1,516
- voice-cloning58
- gpu809
- speech-synthesis56
- huggingface367
- deep-learning746
- machine-learning930
- self-hosted1,978
- mit3,387
- multilingual219
- audio253
- apache-2.01,452
- chinese1,182
- cross-platform2,673
- docker1,684
- speech-recognition103
- cli2,275