FireRedAudio
Overview
One model to listen, understand, reason, speak, and edit.
FireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM with decoupled continuous representations: an Audio Encoder handles understanding, while a RedAE pathway handles generation. A single model supports ASR, audio understanding, zero-shot TTS, instruct TTS, semantic/acoustic speech editing, and accurate temporal grounding over recordings up to one hour long.
Highlights ✨
- 🧩 Purpose-built representations, one shared backbone — The Audio Encoder pathway serves understanding, while the RedAE-Patch pathway serves speech generation. Their representations remain decoupled but share the same language and reasoning backbone. To the best of our knowledge, this is the first publicly disclosed design of its kind in a unified audio-language model.
- 📊 One model, a full audio stack — FireRedAudio spans ASR, broad and fine-grained audio understanding, zero-shot TTS, Instruct TTS, and free-form speech editing, achieving competitive or leading results across MMAU, MMSU, Seed-TTS-Eval, InstructTTSEval, and Ming-Freeform-Audio-Edit.
- 🎙️ Create and edit speech with natural language — Clone a voice from a reference clip, design a voice from a description, or edit what was said and how it sounds through one continuous-latent generation pathway.
- ⏱️ Go from minutes to hour-long recordings — Understand recordings up to one hour with precise time-to-content alignment. Organize audio into timestamped structures, produce grounded summaries, retrieve content by time (or time by content), and reason over evidence distributed across the recording.
Long-Audio Understanding: Time–Content Alignment Demo
News
- [2026.09.08] We release a Gradio web demo for zero-shot TTS, instruct TTS, speech editing, ASR, and audio understanding.
- [2026.08.21] We release the FireRedAudio code and model.
Contents
Quick Start 🚀
Installation
Requires Python 3.10 and uv. System prerequisites: a
CUDA toolkit (GPU inference + compiling the causal-conv1d / flash-attn kernels) and
ffmpeg (audio decoding via torchaudio/torchcodec).
Wheels target CUDA 12.8 (cu128) by default. For a different CUDA version, change the
pytorch-cu128 index URL in pyproject.toml (e.g. cu126 / cu129) and
re-run uv sync.
uv sync --extra accel --extra accel-build --group tools # + compile causal-conv1d, flash-attn
Model Download
Download the pretrained model from Hugging Face with the hf CLI:
uv run hf download FireRedTeam/FireRedAudio --local-dir pretrained_models/
Alternatively, download the pretrained model using modelscope CLI:
uv pip install modelscope
uv run modelscope download --model FireRedTeam/FireRedAudio --local_dir pretrained_models/
Python API
import torch
import torchaudio
from inference import FireRedAudioInference

# Init the model. Understanding tasks need only --model; generation tasks
# additionally need the RedAE decoder weights.
engine = FireRedAudioInference(
    model_path="pretrained_models/FireRedAudio",
    vae_decoder_path="pretrained_models/RedAE_decoder/model.pt",   # only for tts / edit / voice_design
    device="cuda:0",
)

# ---- 1) Speech recognition (ASR) -----------------------------------------
res = engine.understand("assets/examples/asr_zh_fleurs.wav", "Transcribe speech to text.", task="asr")
print(res.answer)

# ---- 2) Audio understanding (with optional chain-of-thought) --------------
res = engine.understand(
    "assets/examples/assets_mmau_test.wav",
    "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease",
    task="understand", enable_thinking=True, max_new_tokens=10240,
)
print("CoT:")
print(res.reasoning)   # CoT reasoning, or None
print("Answer")
print(res.answer)

# ---- 3) Zero-shot TTS (ICL voice cloning) ---------------------------------
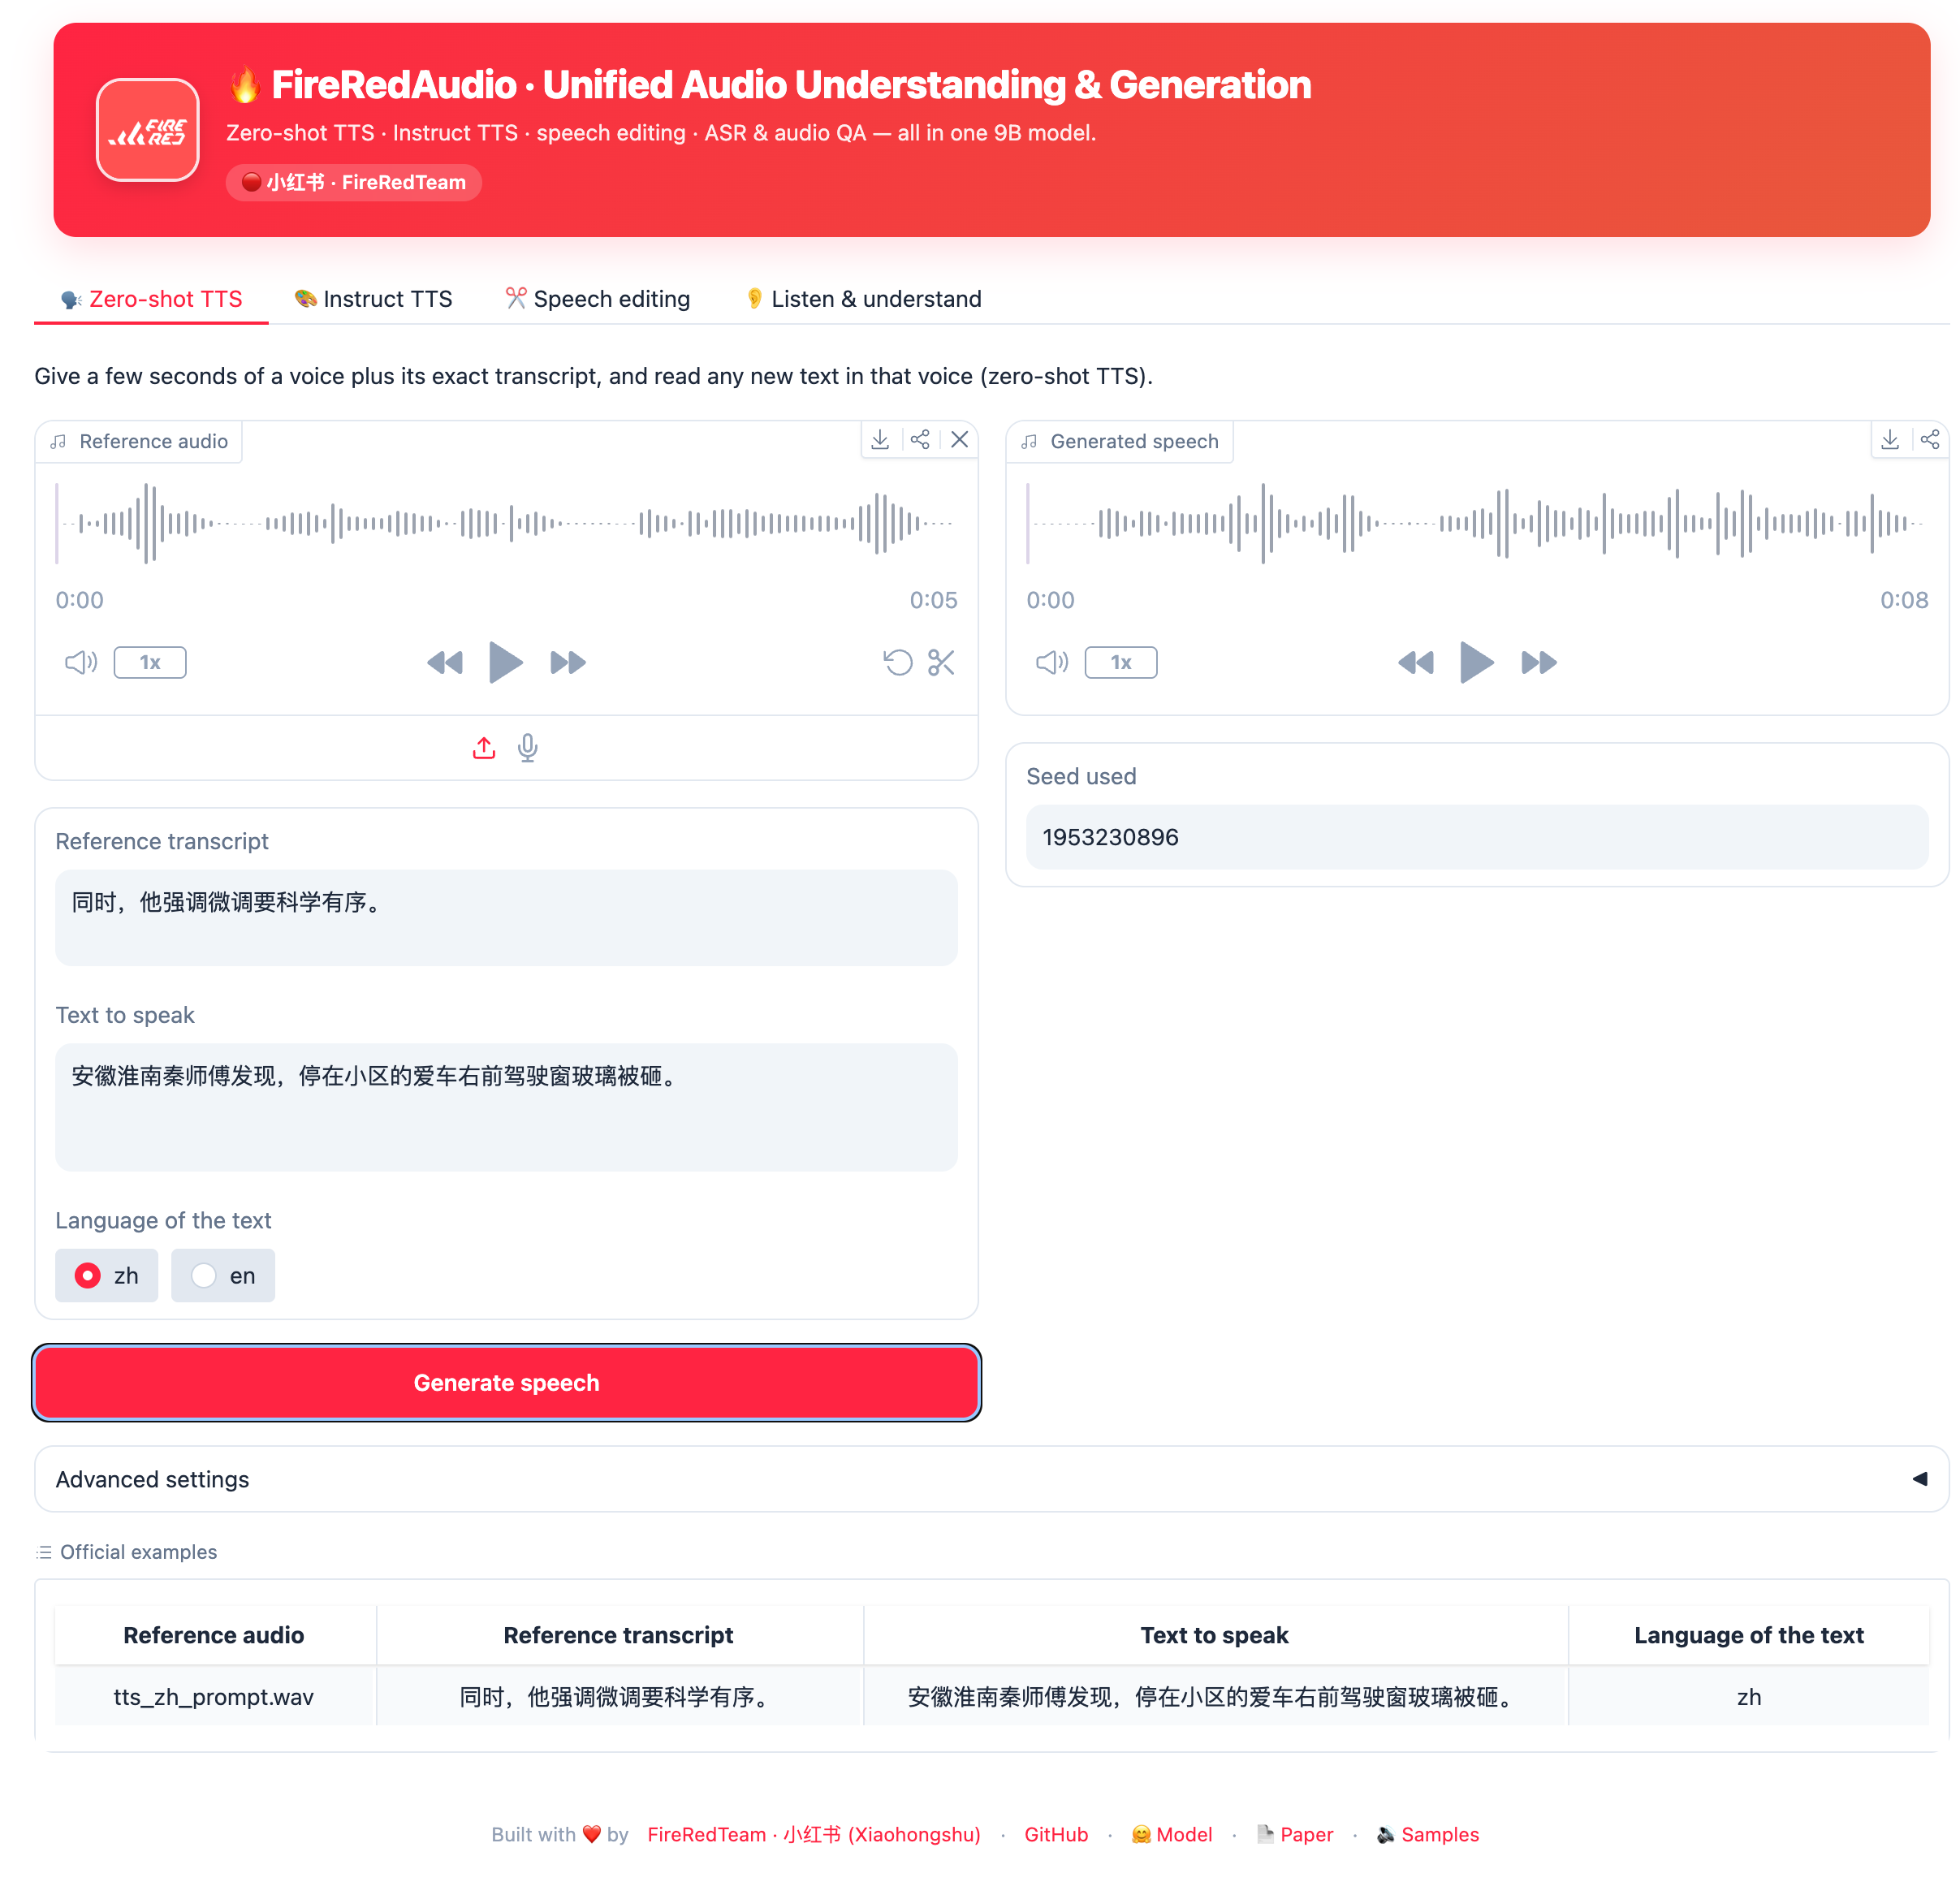
res = engine.tts(
    prompt_text="同时,他强调微调要科学有序。",
    prompt_audio="assets/examples/tts_zh_prompt.wav",
    target_text="安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。",
    language="zh",
)
torchaudio.save("tts.wav", res.audio.cpu(), sample_rate=24000)

# ---- 4) Speech editing -----------------------------------------------------
# semantic: rewrite / substitute / insert / delete content. The model first writes
#          <|sot|>{rewritten text}<|eot|> then renders the audio.
res = engine.edit("assets/examples/edit_semantic_zh_ref.wav", "delete '比普通的茶叶要'", edit_type="semantic")
print(res.text)
torchaudio.save("edit_semantic.wav", res.audio.cpu(), sample_rate=24000)

# acoustic: change pitch / speed / volume. The instruction must follow the exact
#           templates below (the model is trained on these, not free-form phrasing):
#   pitch   ->  "shift the pitch by N step(s)"       N in {-6, ..., -1, 1, ..., +6}
#   speed   ->  "adjust the speed to X"              X in [0.5, 2.0], step 0.1
#   volume  ->  "adjust the volume to X"             X in [0.3, 2.0], step 0.1
res = engine.edit("assets/examples/edit_acoustic_zh_ref.wav", "shift the pitch by 3 steps", edit_type="acoustic")
torchaudio.save("edit_acoustic.wav", res.audio.cpu(), sample_rate=24000)

# ---- 5) Voice design (synthesis from a timbre description) -----------------
res = engine.voice_design(
    instruction="以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。",
    text="是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?",
)
torchaudio.save("voice_design.wav", res.audio.cpu(), sample_rate=24000)
Command Line Inference
# speech recognition
uv run inference.py --task asr --model pretrained_models/FireRedAudio --audio assets/examples/asr_zh_fleurs.wav

# audio understanding and QA; pass multiple files after one --audio
# (e.g. --audio a.wav b.wav for speaker verification).
# --enable-thinking to let the model reason first
uv run inference.py --task understand --model pretrained_models/FireRedAudio --audio assets/examples/assets_mmau_test.wav \
    --prompt "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease" --enable-thinking --max-new-tokens 4096


# ICL voice cloning from a reference audio and its transcript
uv run inference.py --task tts --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --prompt-audio assets/examples/tts_zh_prompt.wav --prompt-text "同时,他强调微调要科学有序。" \
    --target-text "安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。" --language zh --output tts.wav

# speech editing; semantic rewrites content, acoustic changes pitch / speed / volume.
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_semantic_zh_ref.wav --instruction "delete '比普通的茶叶要'" --edit-type semantic \
    --output edit_semantic.wav

# acoustic: instructions must use the exact trained templates, e.g.
#   "shift the pitch by N step(s)"  in  -6..6 steps        (pitch)
#   "adjust the speed to X"         in  [0.5, 2.0], step .1 (speed)
#   "adjust the volume to X"        in  [0.3, 2.0], step .1 (volume)
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_acoustic_zh_ref.wav --instruction "shift the pitch by 3 steps" --edit-type acoustic \
    --output edit_acoustic.wav

# voice design
uv run inference.py --task voice_design --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --instruction "以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。" \
    --text "是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?" --output voice_design.wav
Web Demo (Gradio)
A single-file Gradio app at app.py wraps all four tasks
(zero-shot TTS · instruct TTS · speech editing · listen & understand) with the
same weights and prompt templates as the CLI. Gradio is the only extra dep on
top of the base install:
uv pip install gradio

uv run app.py \
    --model_path       pretrained_models/FireRedAudio \
    --vae_decoder_path pretrained_models/RedAE_decoder/model.pt \
    --host 0.0.0.0 --port 7860
Defaults to http://0.0.0.0:7860. The understanding tab exposes the full Qwen3
sampling controls (temperature, top_p, top_k, min_p, repetition_penalty,
do_sample) with a think-preset toggle that swaps in Qwen3's recommended
(temperature, top_p) for reasoning / non-reasoning modes. If you're serving
behind a reverse proxy, add --root-path <prefix>.
Audio Understanding
Model |
MMAU test-mini |
MMAU test |
MMSU |
| Step-Audio-R1.1 | 77.7 | – | 75.9 |
| Step-Audio 2 | 78.0 | – | – |
| MiMo-Audio-7B-Instruct | 74.9 | – | 61.7 |
| Kimi-Audio | 65.2 | – | – |
| LongCat-Next | 76.4 | – | – |
| Qwen3-Omni-30B-A3B-Instruct | 77.5 | – | 69.0 |
| Gemini 3.1 Pro | 80.7* | 78.8* | 82.7* |
| Qwen3.5-Omni-Plus | 81.4* | 79.9* | 80.7* |
| FireRedAudio | 82.0 | 80.9 | 83.3 |
- Results marked with * are obtained from our own evaluation.
ASR
Model |
AISHELL‑1 |
AISHELL‑2
test‑ios |
WenetSpeech
Net | Meeting |
LibriSpeech
clean | other |
FLEURS
en | zh |
FLEURS‑102
avg |
KeSpeech |
Opencpop |
| Step‑Audio 2 | 0.63 | 2.10 | 4.67 | 4.75 | 1.17 | 2.42 | 3.03 | 2.68 | – | 3.63 | – |
| MiMo‑Audio‑7B‑Instruct | 1.65 | – | – | 3.50 | – | – | – | – | – |
| Ming‑UniAudio‑16B‑A3B | – | 2.84 | – | 1.62 | – | – | – | – | – |
| Kimi‑Audio | 0.60 | 2.56 | 5.37 | 6.28 | 1.28 | 2.42 | 4.44 | 2.69 | – | – | – |



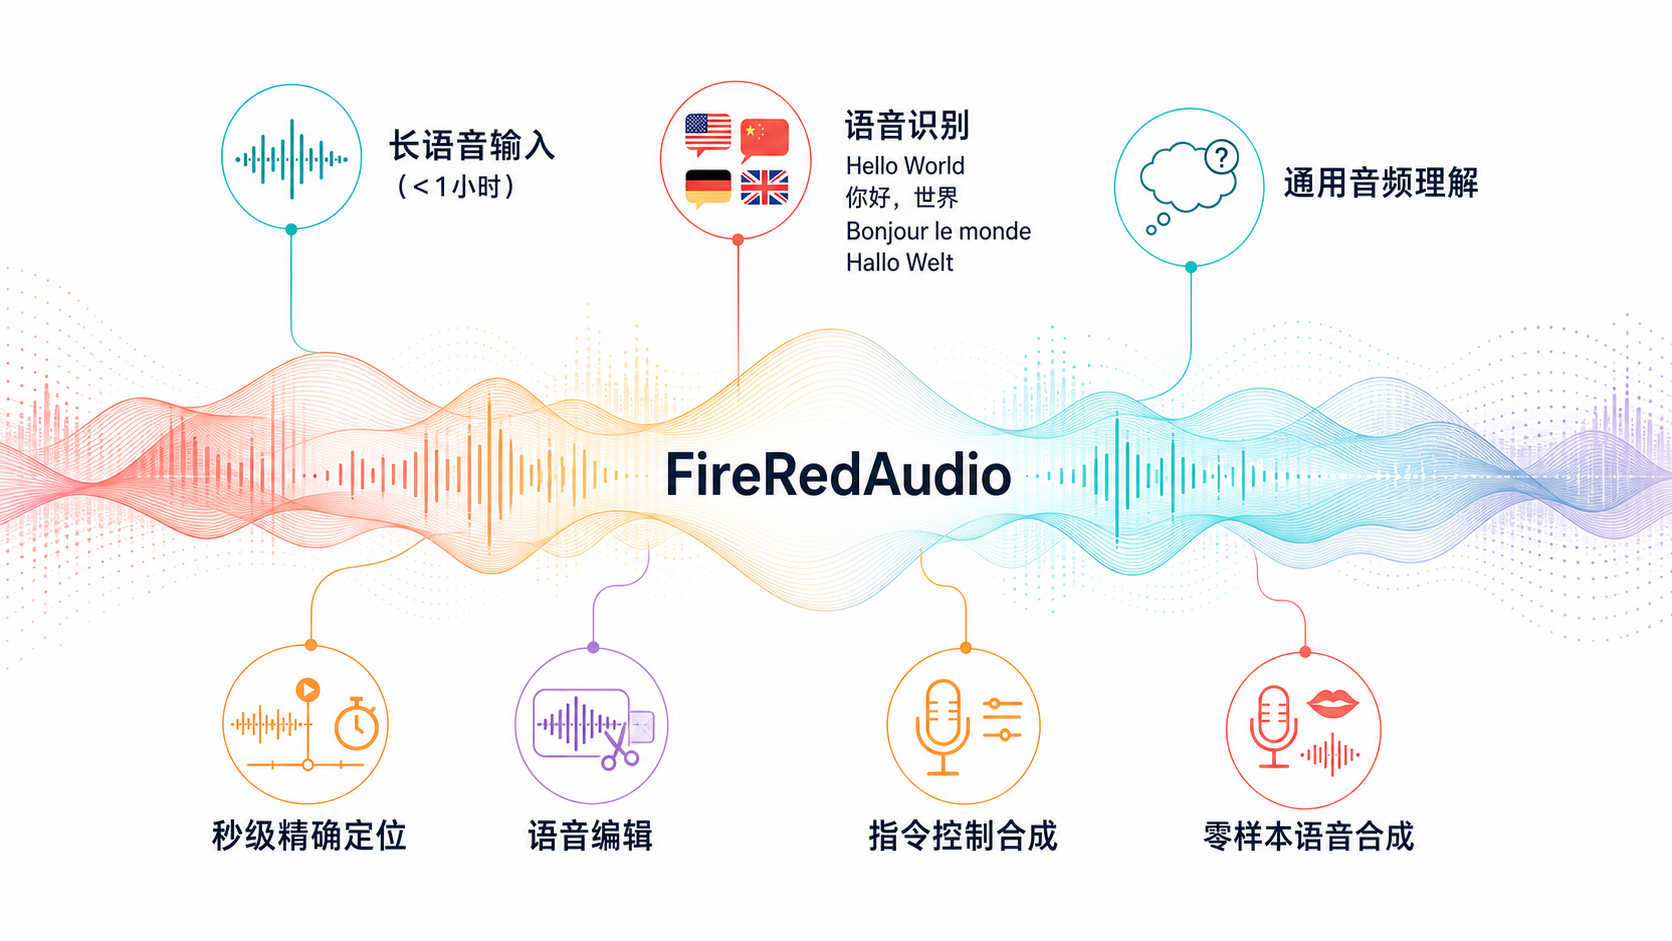

 FireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM that can transcribe speech (ASR), understand audio, do zero-shot and instruct text-to-speech, and edit speech, all from one model.