Topics / #spark
Spark projects on GitHub
Distributed data processing engine for big data workloads
As of , the most-starred Spark projects on GitHub are data-engineering-zoomcamp (46.2K stars), spark (44.2K stars) and data-science-ipython-notebooks (29.4K stars). GitHub.Locker tracks 23 Spark repositories with 434.2K stars combined. The fastest-growing on October 16 was data-engineering-zoomcamp, with +17 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +17
data-engineering-zoomcamp
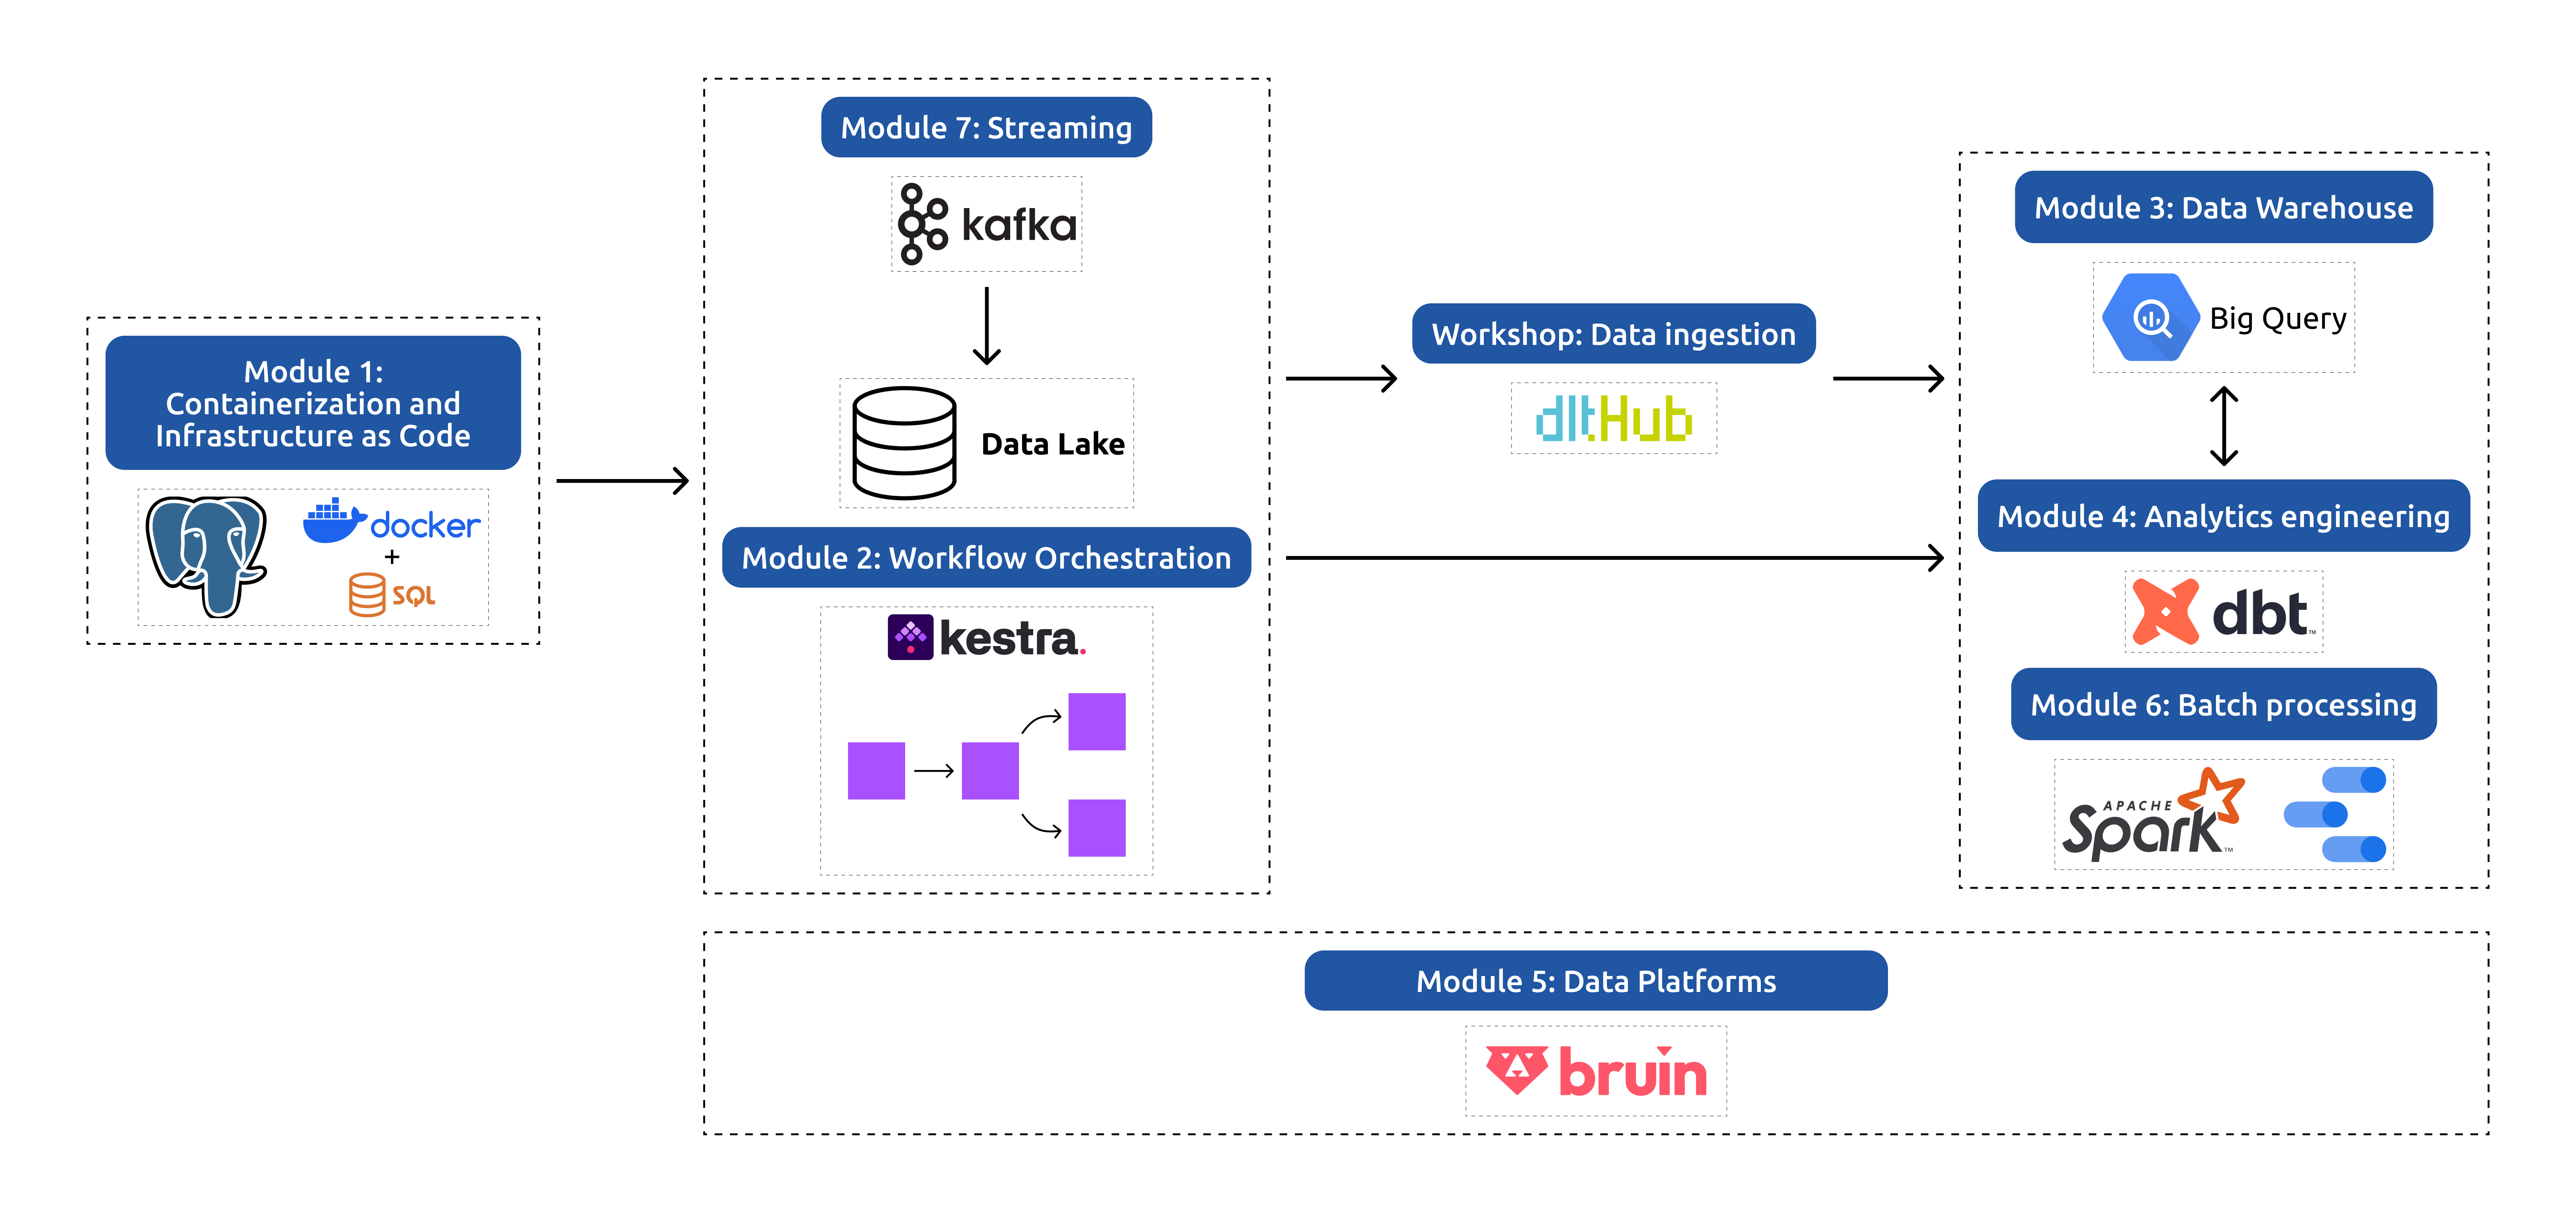
DataTalksClub/data-engineering-zoomcamp · ★ 46.2KThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
 +17
presidio
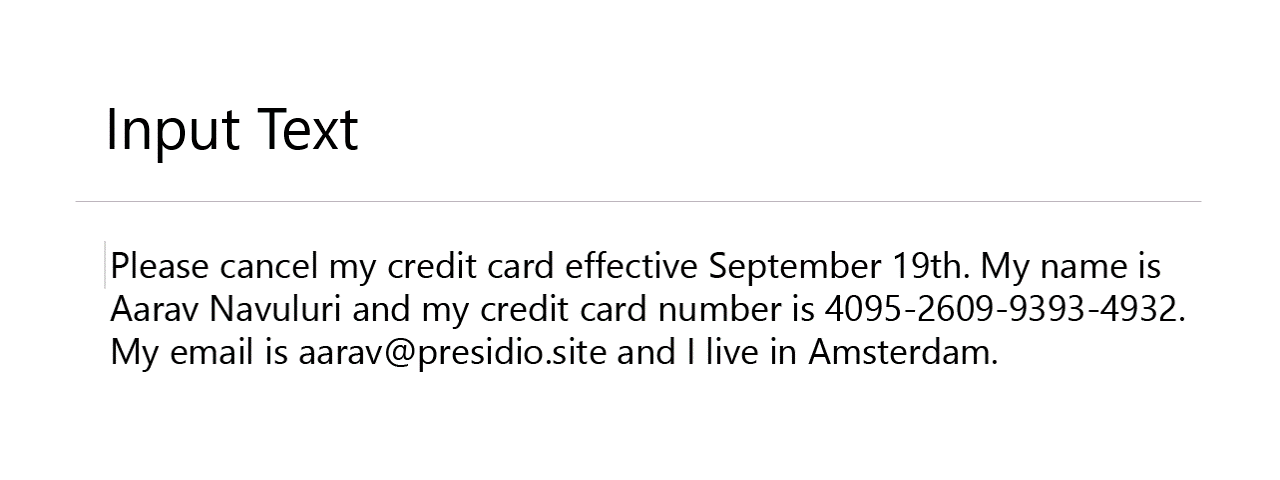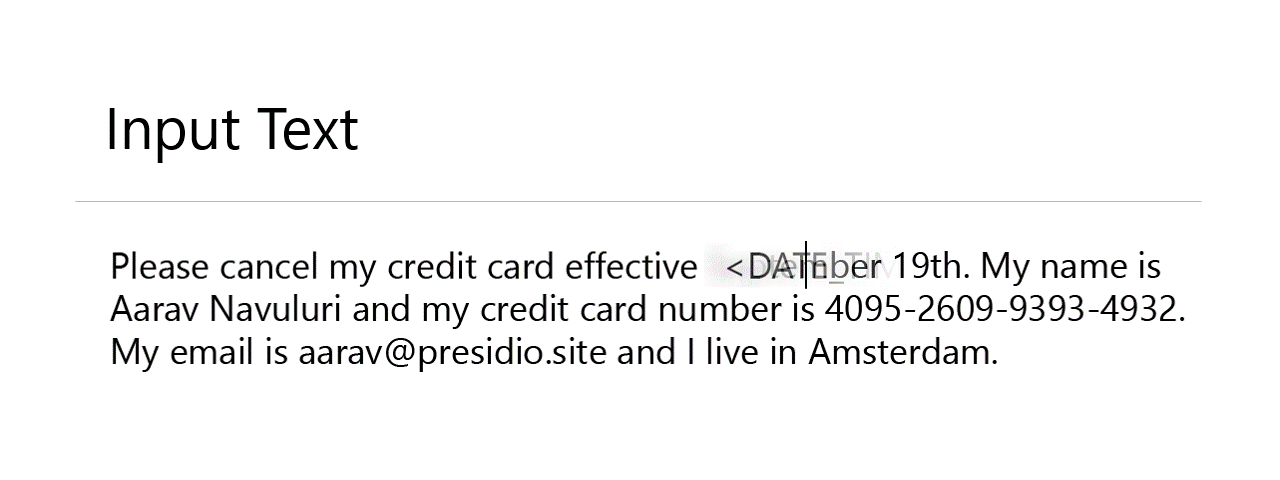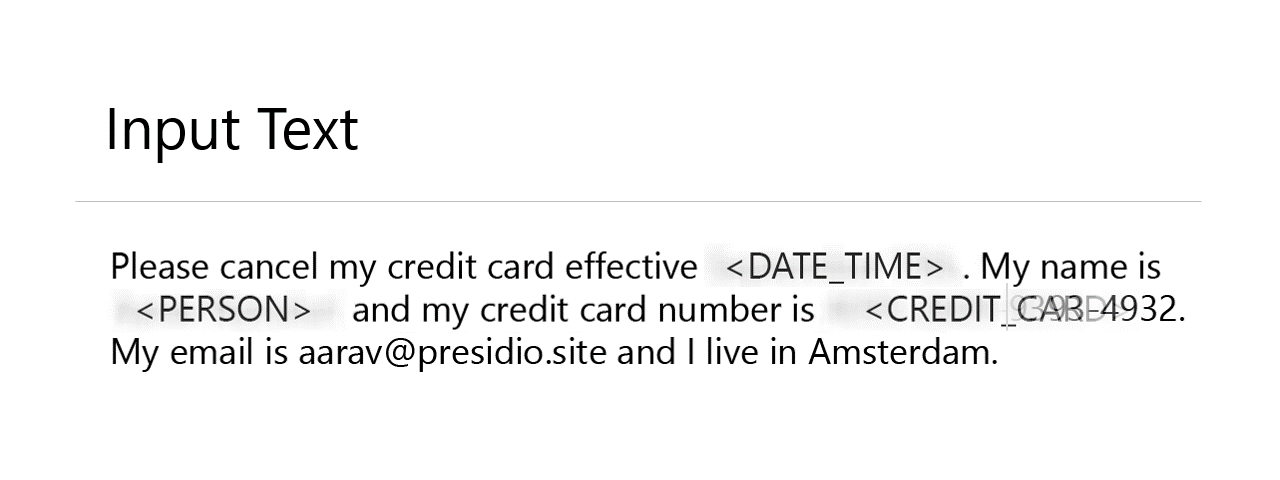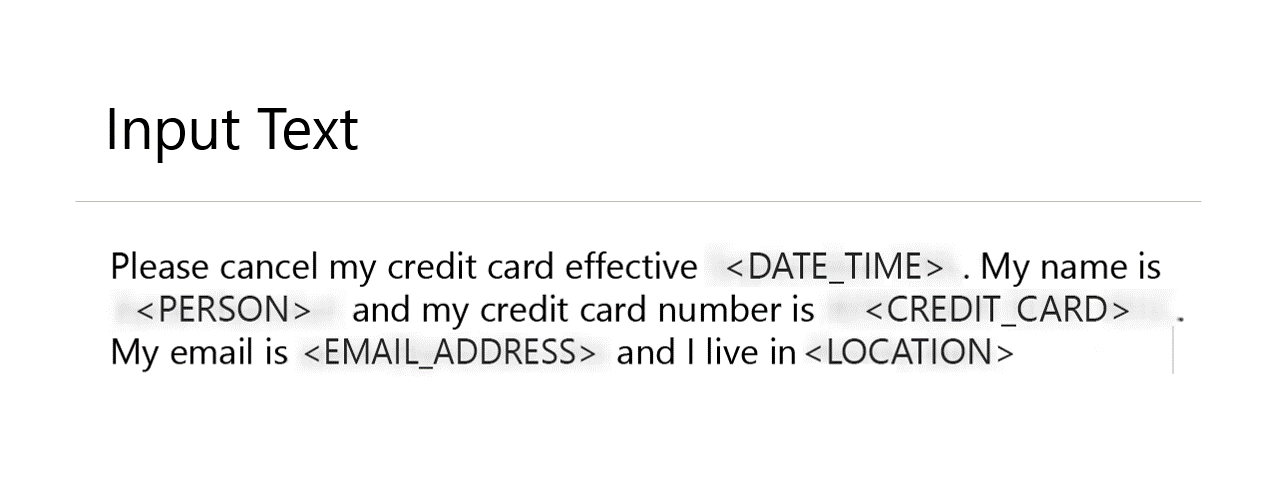
data-privacy-stack/presidio · ★ 11.4KAn open-source framework (SDK) that detects, redacts, masks and anonymizes sensitive data (PII) — names, credit card numbers, SSNs, phone numbers — in text, images and structured data.
 +10
spark
apache/spark · ★ 44.2KApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
 +9
Spark-X2.5
XHToken/Spark-X2.5 · ★ 812Spark-X2.5 is a series of two open-source language models (4B and 1.7B parameters) built for everyday conversation, writing, translation, coding, reasoning and agentic tool-use tasks, aiming for strong performance in a compact size.
The all-time top
23 projects · by stars
- 46.2K#1 · DataTalksClub/data-engineering-zoomcamp
data-engineering-zoomcamp
This is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
- 44.2K#2 · apache/spark
spark
Apache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 29.4K
 #3 · donnemartin/data-science-ipython-notebooks
data-science-ipython-notebooks
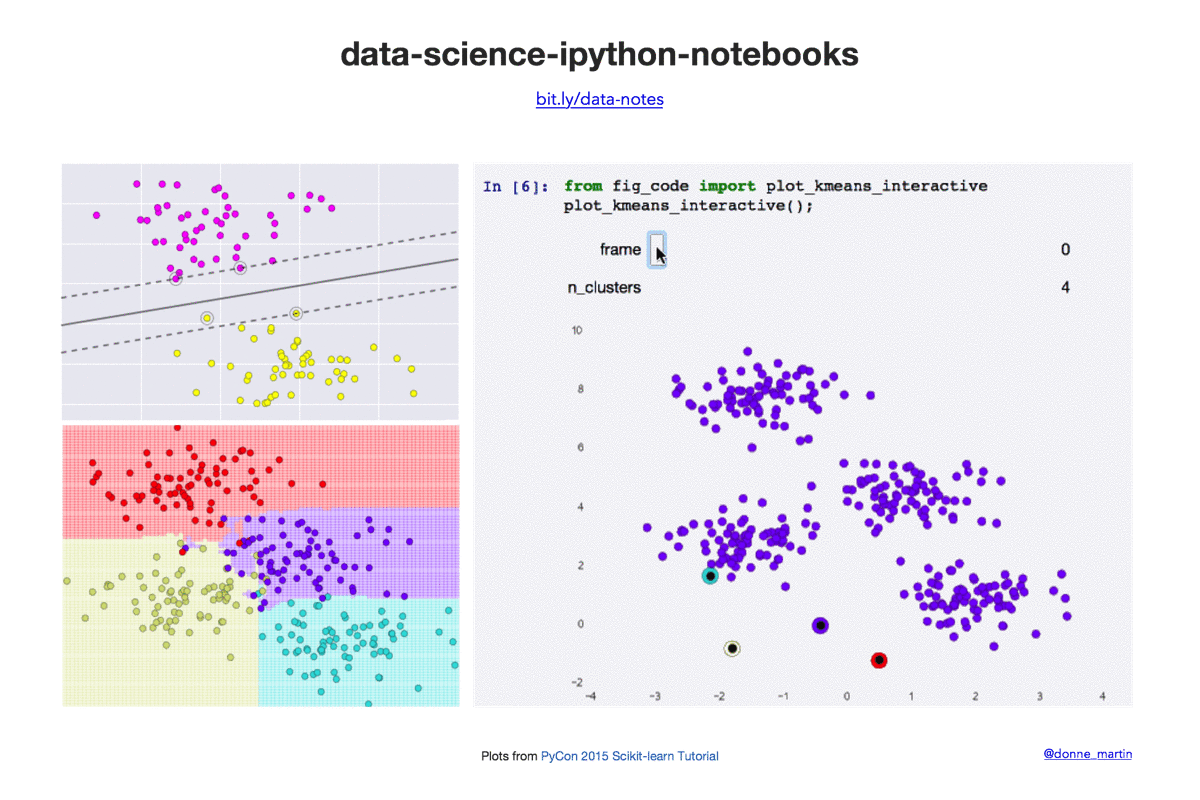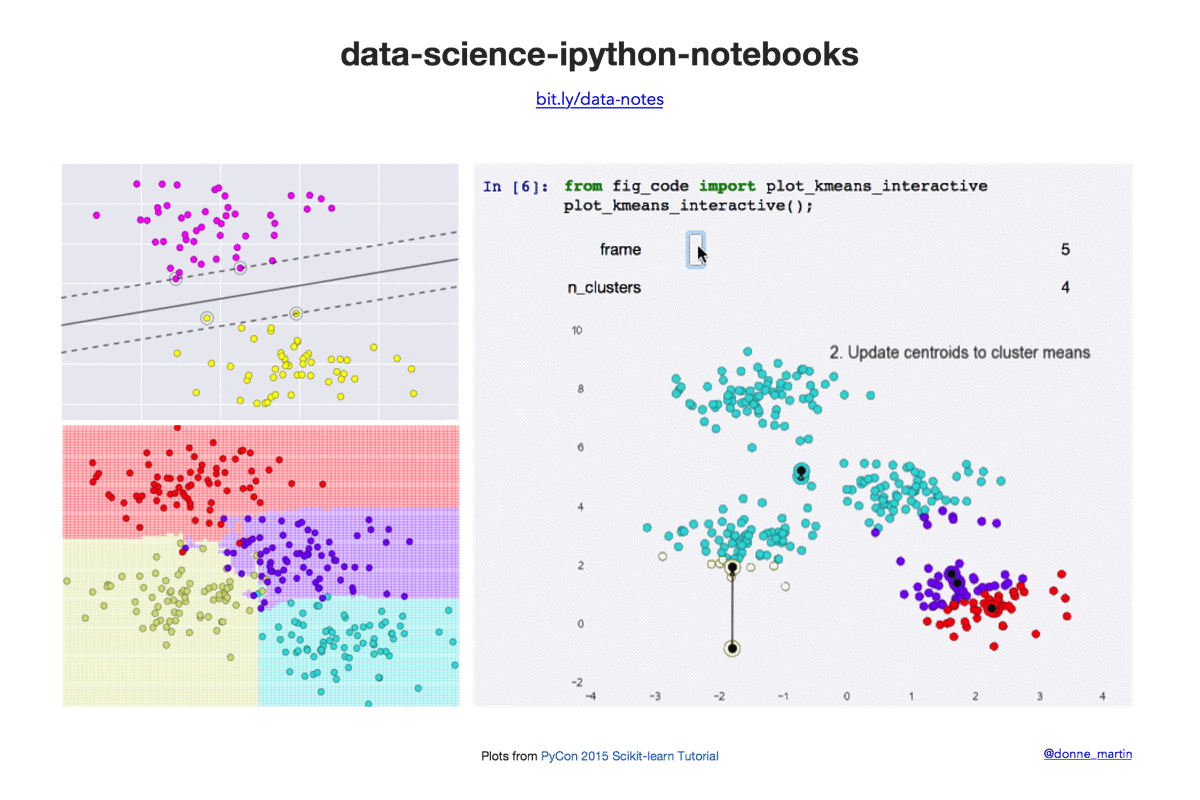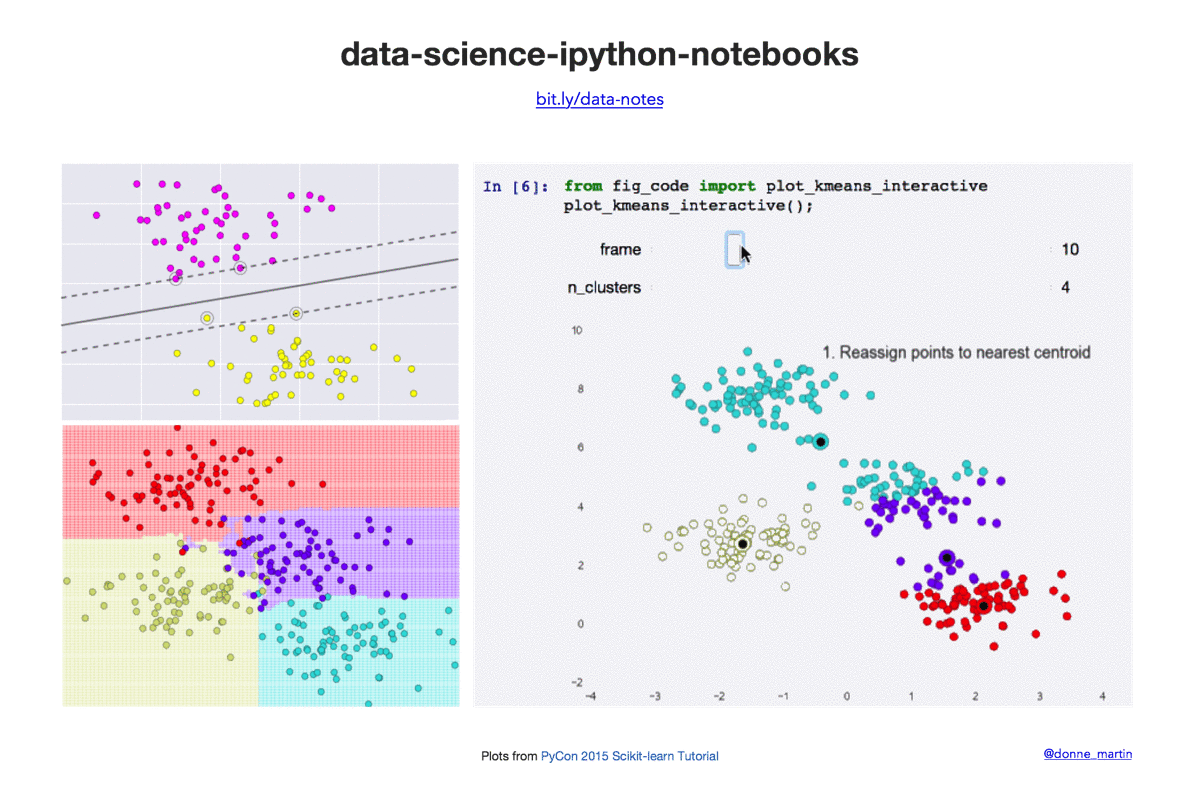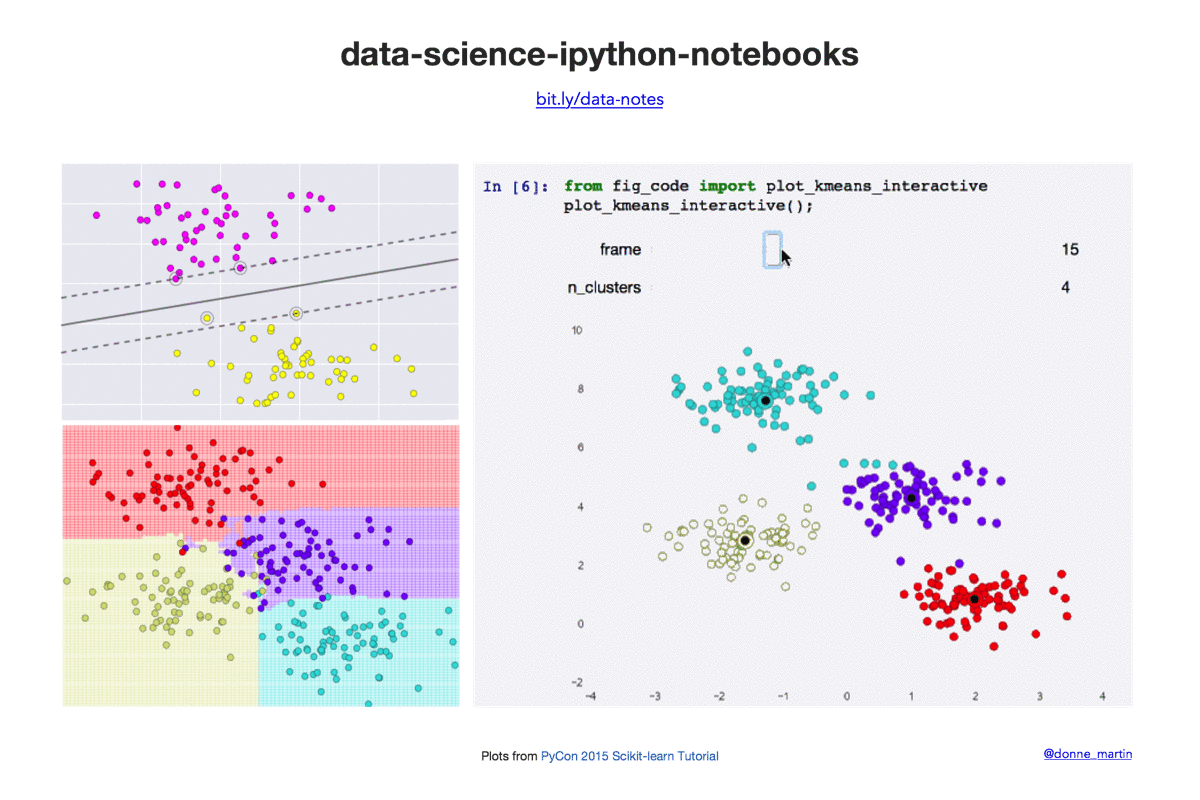
A large curated collection of IPython/Jupyter notebooks covering the Python data science stack: deep learning (TensorFlow, Theano, Caffe, Keras), scikit-learn, statistics with SciPy, pandas, matplotlib, NumPy, Kaggle competition analyses, big data (Spark, Hadoop MapReduce, HDFS), AWS, and command-line essentials.
- 4
xgboost
28.9Kdmlc/xgboost · C++XGBoost is an optimized distributed gradient boosting library designed to be highly efficient, flexible and portable — it implements machine learning algorithms under the Gradient Boosting framework.
- 5
redash
28.8Kgetredash/redash · PythonRedash is an open-source business intelligence platform: you connect data sources, explore and query them, visualize the results and share dashboards with your team. Thousands of organizations use it for data-driven decisions.
- 6

docker_practice
26.3Kyeasy/docker_practice · GoAn open-source Chinese book that takes you from zero to real DevOps practice with Docker: core concepts, internals and hands-on skills for developers, ops engineers and architects.
- 7

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 8

recommenders
22Krecommenders-team/recommenders · PythonAn open-source Python library and notebook collection with best practices for building, evaluating and deploying recommendation systems — a Linux Foundation of AI & Data project that started at Microsoft.
- 9

BigData-Notes
17Kheibaiying/BigData-Notes · JavaThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
- 10
ds-cheatsheets
16.4KFavioVazquez/ds-cheatsheetsA curated list of data science cheatsheets covering Python, R, math, big data, machine learning, deep learning, SQL, and data visualization, meant to be a quick-reference collection rather than a tutorial.
- 11

doris
16.1Kapache/doris · JavaApache Doris is an open-source, real-time analytics and search database built on MPP architecture. It serves fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
- 12

cheatsheets-ai
15.4Kkailashahirwar/cheatsheets-aiA curated collection of one-page cheat sheets covering popular machine learning and deep learning tools such as TensorFlow, Keras, NumPy, Pandas, Scikit-learn, Matplotlib, PySpark, Dask, and R's dplyr/tidyr, aimed at ML and DL researchers.
- 13
ChuanhuChatGPT
15.3KGaiZhenbiao/ChuanhuChatGPT · PythonChuanhuChatGPT is a web-based GUI for ChatGPT and many other LLMs, adding extras like agents, file-based Q&A, local model deployment, web search, and GPT fine-tuning on top of a Gradio interface.
- 14

flink-learning
15.1Kzhisheng17/flink-learning · JavaA companion repo to a Chinese-language Apache Flink learning blog, packed with runnable example code, source-code analysis articles, and real-world project case studies (PV/UV stats, log storage, large-scale dedup, monitoring/alerting).
- 15
technology-talk
14.7Kaalansehaiyang/technology-talkA curated Chinese knowledge base of Java interview prep articles, system architecture notes, middleware deep-dives, and career advice, written by a self-described Alibaba P7 architect who goes by 'Tom哥'.
- 16

horovod
14.7Khorovod/horovod · PythonHorovod is a distributed deep learning training framework that adds distributed training support to TensorFlow, Keras, PyTorch, and Apache MXNet, aiming to make scaling training across many GPUs and machines fast and easy.
- 17
deeplearning4j
14.3Kdeeplearning4j/deeplearning4j · JavaEclipse Deeplearning4J is a suite of JVM libraries for building, training and deploying deep learning applications, usable from Java, Scala, Kotlin and Clojure.
- 18
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 19
presidio
11.4Kdata-privacy-stack/presidio · PythonAn open-source framework (SDK) that detects, redacts, masks and anonymizes sensitive data (PII) — names, credit card numbers, SSNs, phone numbers — in text, images and structured data.
- 20

dolly
10.8Kdatabrickslabs/dolly · PythonDolly is Databricks' instruction-following large language model, trained on the Databricks Machine Learning Platform and licensed for commercial use; the flagship dolly-v2-12b derives from EleutherAI's Pythia-12b.
- 21
God-Of-BigData
10.6Kwangzhiwubigdata/God-Of-BigDataA curated Chinese-language knowledge base for learning big data engineering and passing big data interviews, covering Java fundamentals, distributed systems theory, and deep dives into Hadoop, Hive, Spark, Flink, HBase, Kafka, and Zookeeper.
- 22
Spark-X2.5
812XHToken/Spark-X2.5Spark-X2.5 is a series of two open-source language models (4B and 1.7B parameters) built for everyday conversation, writing, translation, coding, reasoning and agentic tool-use tasks, aiming for strong performance in a compact size.
- 23

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.
Related topics
Often tagged together