PaperBanana README

The project's README from github.com/dwzhu-pku/PaperBanana. As one markdown file: README.md.

PaperBanana 🍌

Dawei Zhu, Rui Meng, Yale Song, Xiyu Wei, Sujian Li, Tomas Pfister and Jinsung yoon

Paper page on HF Dataset on HF Demo on HF Spaces

Hi everyone! The original version of PaperBanana is already open-sourced under Google-Research as PaperVizAgent. This repository forked the content of that repo and aims to keep evolving toward better support for academic paper illustration—though we have made solid progress, there is still a long way to go for more reliable generation and for more diverse, complex scenarios. PaperBanana is intended to be a fully open-source project dedicated to facilitating academic illustration for all researchers. Our goal is simply to benefit the community, so we currently have no plans to use it for commercial purposes.

Latest News

TODO List

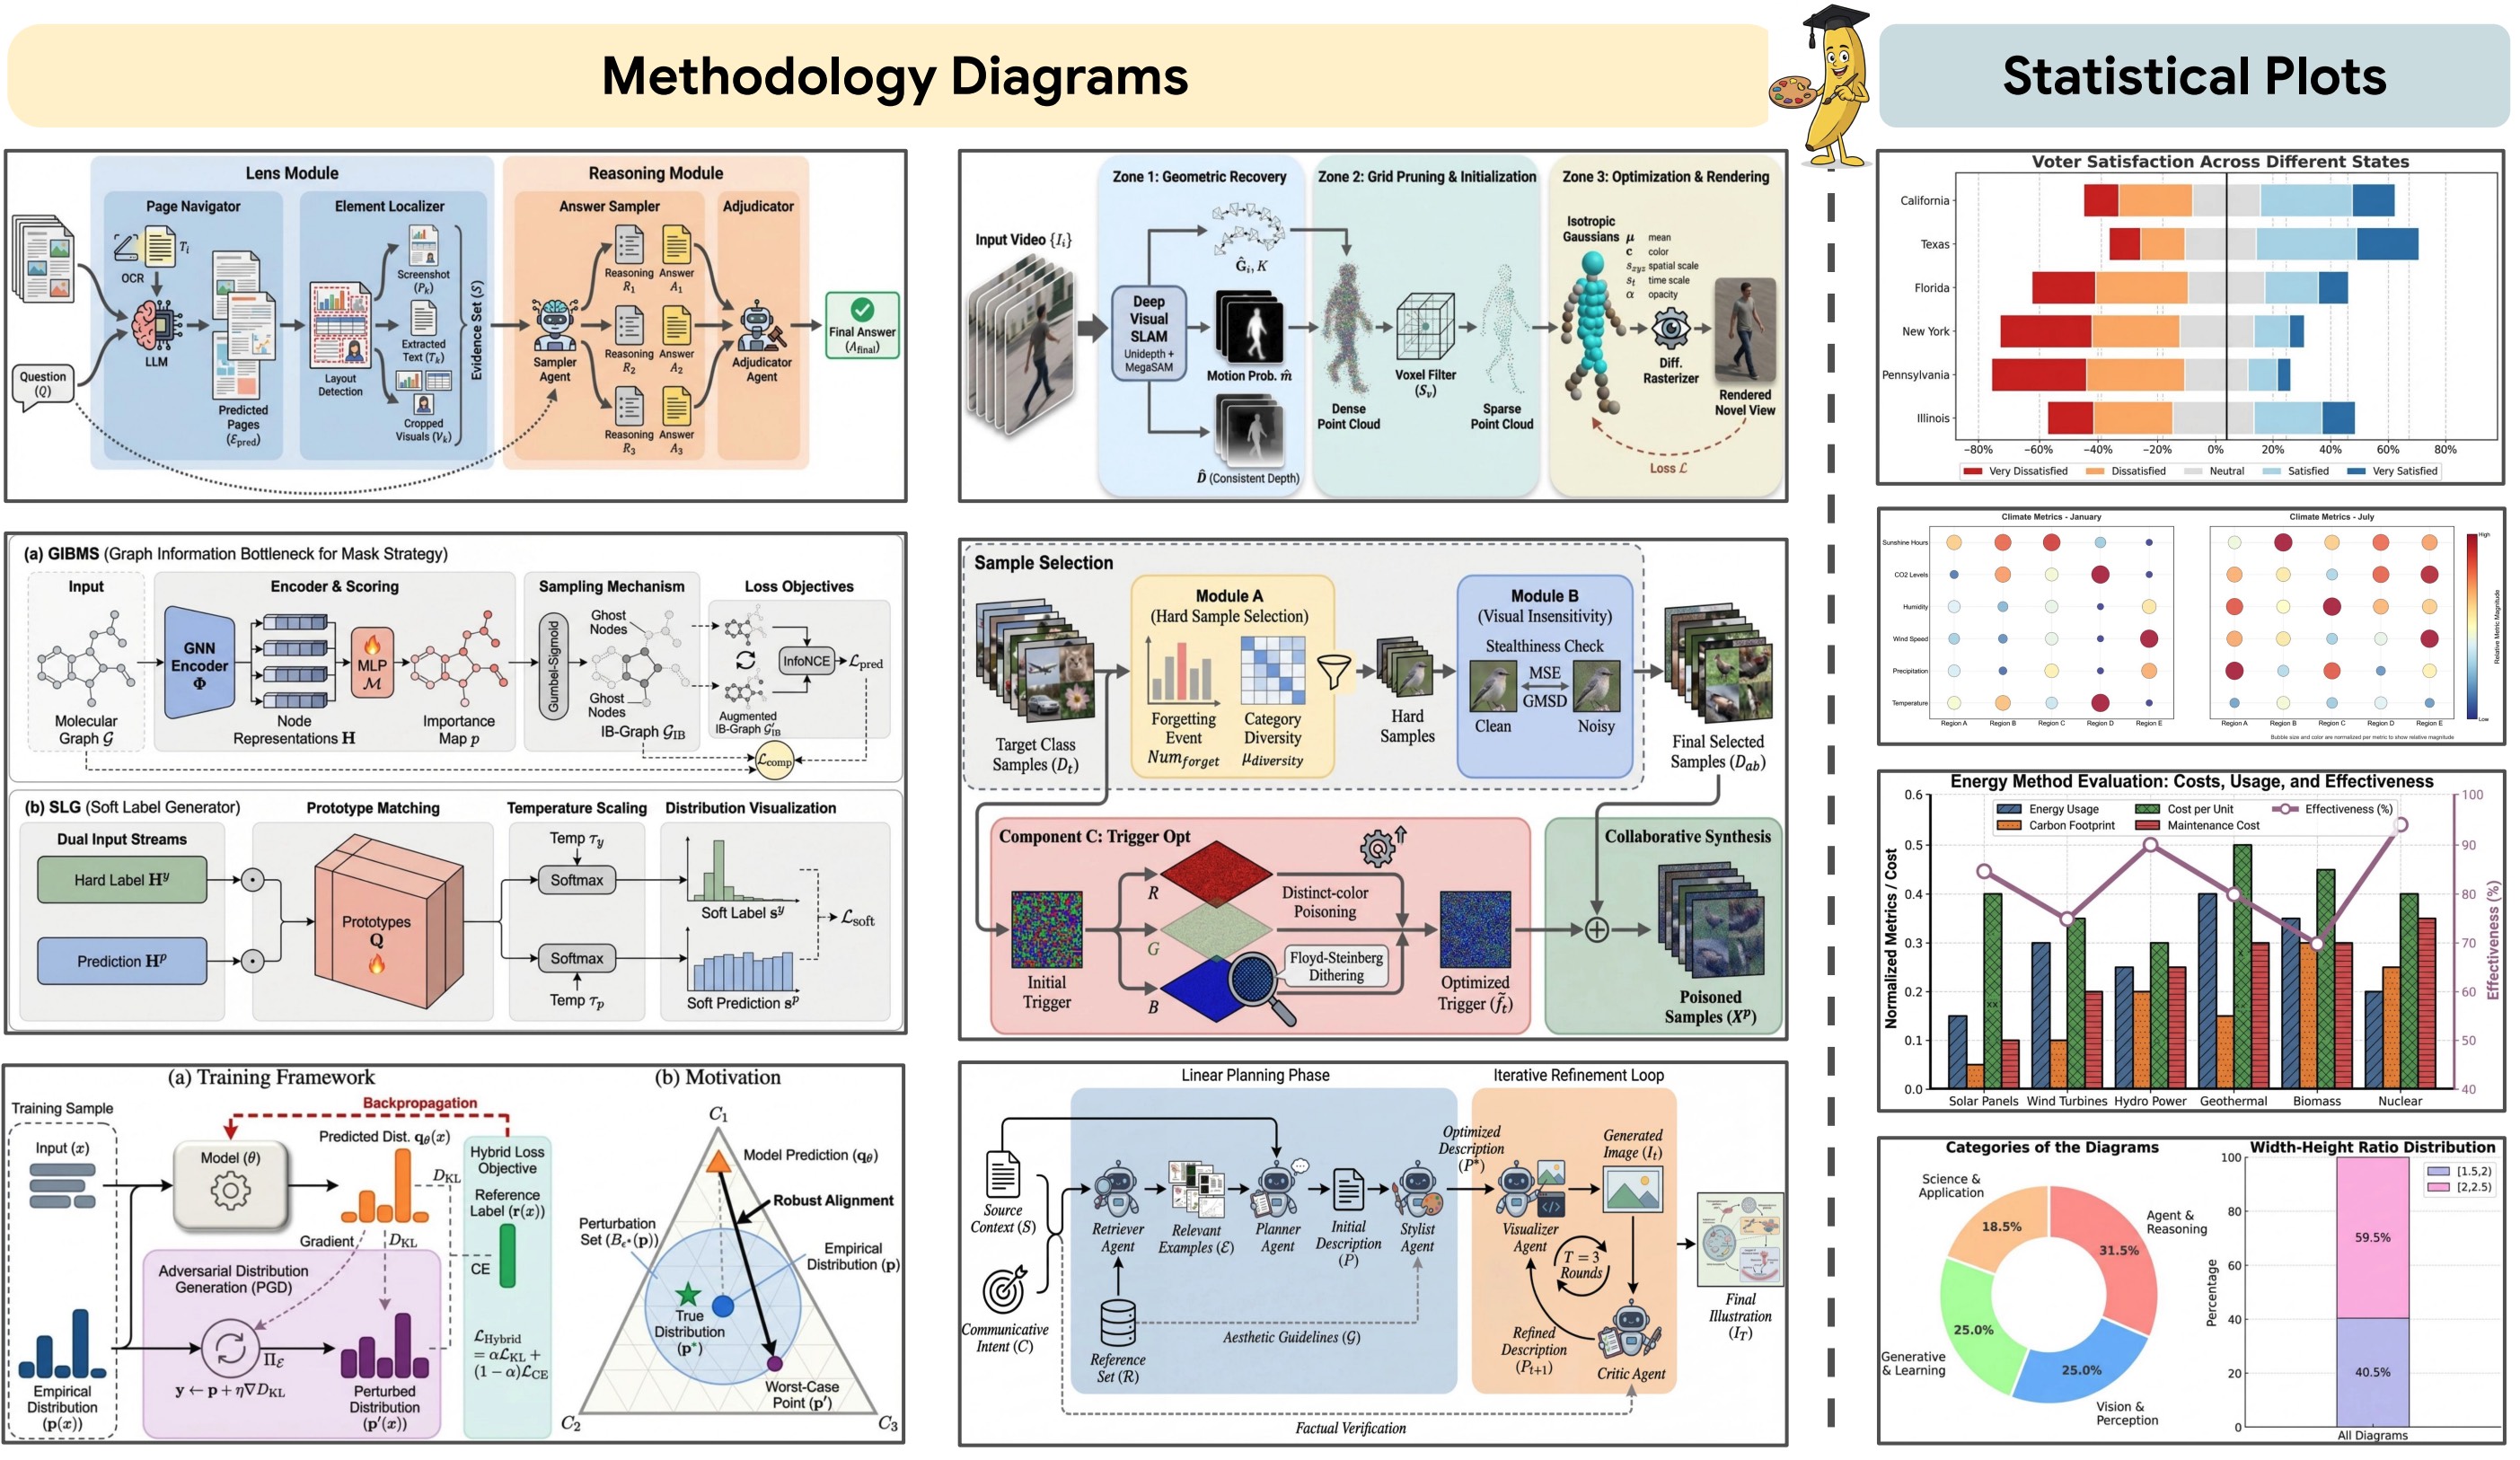
PaperBanana is a reference-driven multi-agent framework for automated academic illustration generation. Acting like a creative team of specialized agents, it transforms raw scientific content into publication-quality diagrams and plots through an orchestrated pipeline of Retriever, Planner, Stylist, Visualizer, and Critic agents. The framework leverages in-context learning from reference examples and iterative refinement to produce aesthetically pleasing and semantically accurate scientific illustrations.

Here are some example diagrams and plots generated by PaperBanana: Examples

Overview of PaperBanana

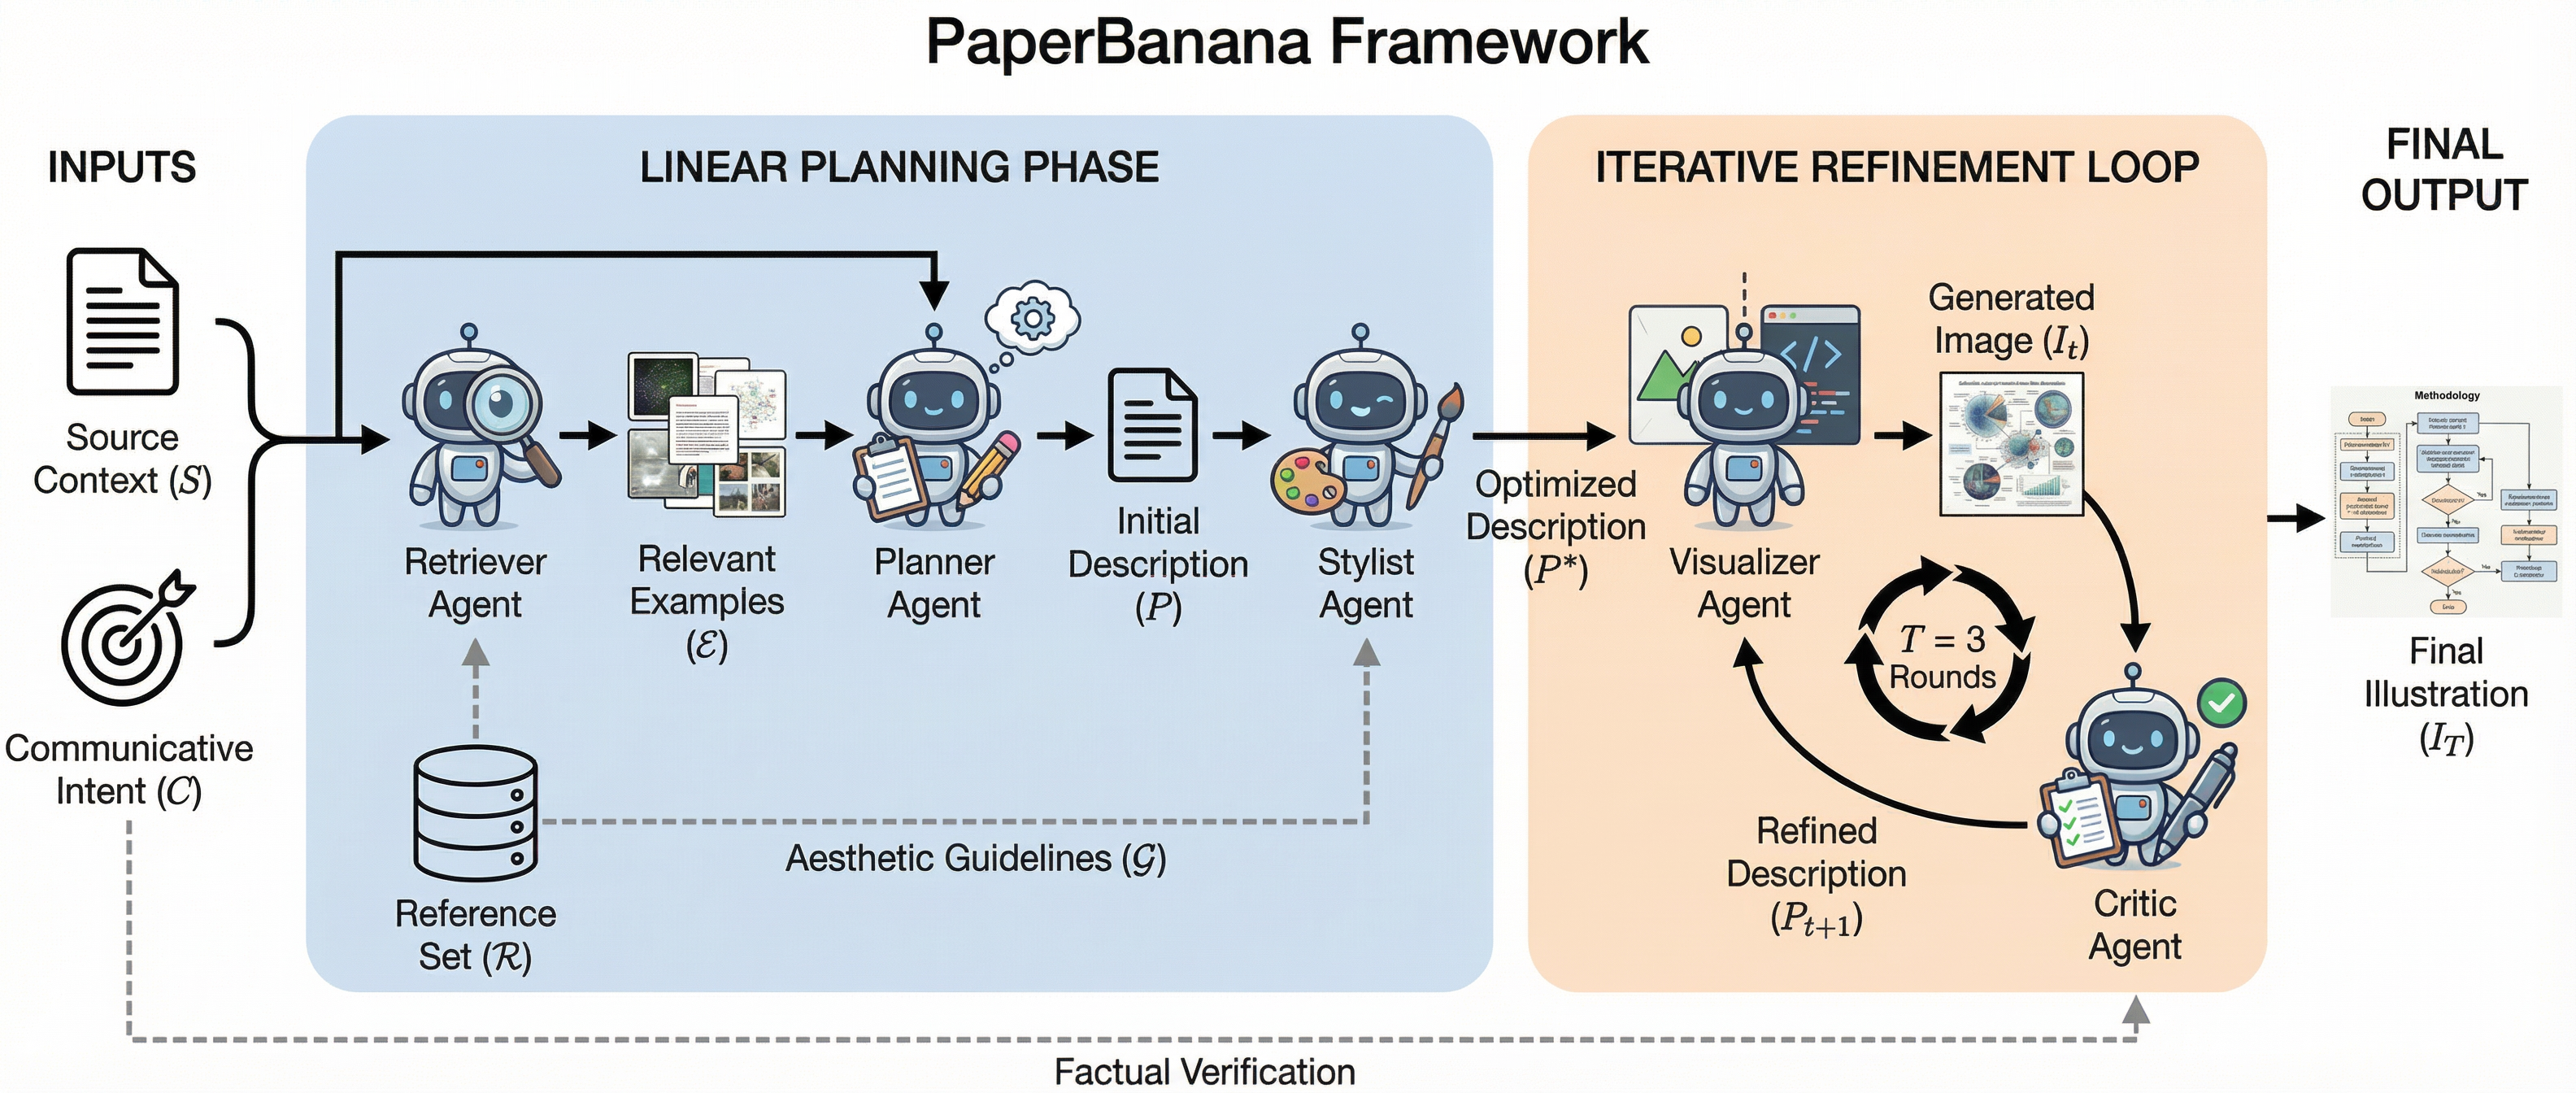
PaperBanana Framework

PaperBanana achieves high-quality academic illustration generation by orchestrating five specialized agents in a structured pipeline:

  1. Retriever Agent: Identifies the most relevant reference diagrams from a curated collection to guide downstream agents
  2. Planner Agent: Translates method content and communicative intent into comprehensive textual descriptions using in-context learning
  3. Stylist Agent: Refines descriptions to adhere to academic aesthetic standards using automatically synthesized style guidelines
  4. Visualizer Agent: Transforms textual descriptions into visual outputs using state-of-the-art image generation models
  5. Critic Agent: Forms a closed-loop refinement mechanism with the Visualizer through multi-round iterative improvements

Quick Start

Step1: Clone the Repo

git clone https://github.com/dwzhu-pku/PaperBanana.git
cd PaperBanana

Step2: Configuration

PaperBanana supports configuring API keys from a YAML configuration file or via environment variables.

We recommend duplicate the configs/model_config.template.yaml file into configs/model_config.yaml to externalize all user configurations. This file is ignored by git to keep your api keys and configurations secret. In model_config.yaml, remember to fill in the two model names (defaults.main_model_name and defaults.image_gen_model_name) and set at least one API key under api_keys—for example only google_api_key (Gemini), or only openrouter_api_key (OpenRouter). You do not need both; either one is enough. If both are configured, OpenRouter is preferred for routing when available.

Note that if you need to generate many candidates simultaneously, you will require an API key that supports high concurrency.

Step3: Downloading the Dataset

First download PaperBananaBench, then place it under the data directory (e.g., data/PaperBananaBench/). The framework is designed to function gracefully without the dataset by bypassing the Retriever Agent's few-shot learning capability. If interested in the original PDFs, please download them from PaperBananaDiagramPDFs.

Step4: Installing the Environment

  1. We use uv to manage Python packages. Please install uv following the instructions here.

  2. Create and activate a virtual environment

    uv venv # This will create a virtual environment in the current directory, under .venv/
    source .venv/bin/activate  # or .venv\Scripts\activate on Windows
    
  3. Install python 3.12

    uv python install 3.12
    
  4. Install required packages

    uv pip install -r requirements.txt
    

Launch PaperBanana

Try it online — no setup required:
👉 PaperBanana on Hugging Face Spaces

To get started, enter your API key (OpenRouter or Google Gemini), then configure your desired parameters (pipeline mode, number of candidates, aspect ratio, etc.), paste your method section text and figure caption, and click Generate.

You can also run the Gradio app locally:

python app.py

The Gradio Figure Size setting maps 1-3cm and 4-6cm to 1k, 7-9cm and 10-13cm to 2k, and 14-17cm to 4k for Gemini and OpenRouter image-generation calls. OpenAI gpt-image requests continue to use their existing fixed-size API path.

Option 2: Interactive Demo (Streamlit)

The easiest way to launch PaperBanana is via the interactive Streamlit demo:

streamlit run demo.py

The web interface provides two main workflows:

1. Generate Candidates Tab:

2. Refine Image Tab:

Option 3: Command-Line Interface

You can also run PaperBanana from the command line:

# Basic usage with default settings
python main.py

# Advanced usage with custom settings
python main.py \
  --dataset_name "PaperBananaBench" \
  --task_name "diagram" \
  --split_name "test" \
  --exp_mode "dev_full" \
  --retrieval_setting "auto"

# Legacy matplotlib plot-code generation with no few-shot retrieval
python main.py \
  --dataset_name "PaperBananaBench" \
  --task_name "plot" \
  --split_name "test" \
  --exp_mode "vanilla" \
  --retrieval_setting "none"

Available Options:

Experiment Modes:

Visualization Tools

View pipeline evolution and intermediate results:

streamlit run visualize/show_pipeline_evolution.py

View evaluation results:

streamlit run visualize/show_referenced_eval.py

Project Structure

├── .venv/
│   └── ...
├── data/
│   └── PaperBananaBench/
│       ├── diagram/
│       │   ├── images/
│       │   ├── pdfs/
│       │   ├── test.json
│       │   └── ref.json
│       └── plot/
├── agents/
│   ├── __init__.py
│   ├── base_agent.py
│   ├── retriever_agent.py
│   ├── planner_agent.py
│   ├── stylist_agent.py
│   ├── visualizer_agent.py
│   ├── critic_agent.py
│   ├── vanilla_agent.py
│   └── polish_agent.py
├── prompts/
│   ├── __init__.py
│   ├── diagram_eval_prompts.py
│   └── plot_eval_prompts.py
├── style_guides/
│   ├── generate_category_style_guide.py
│   └── ...
├── utils/
│   ├── __init__.py
│   ├── config.py
│   ├── paperviz_processor.py
│   ├── eval_toolkits.py
│   ├── generation_utils.py
│   └── image_utils.py
├── visualize/
│   ├── show_pipeline_evolution.py
│   └── show_referenced_eval.py
├── scripts/
│   ├── run_main.sh
│   ├── run_demo.sh
├── configs/
│   └── model_config.template.yaml
├── results/
│   ├── PaperBananaBench_diagram/
│   └── parallel_demo/
├── main.py
├── demo.py
└── README.md

Key Features

Multi-Agent Pipeline

Interactive Demo

Extensible Design

Community Supports

Around the release of this repo, we noticed several community efforts to reproduce this work. These efforts introduce unique perspectives that we find incredibly valuable. We highly recommend checking out these excellent contributions: (welcome to add if we missed something):

Additionally, alongside the development of this method, many other works have been exploring the same topic of automated academic illustration generation—some even enabling editable generated figures. Their contributions are essential to the ecosystem and are well worth your attention (likewise, welcome to add):

Overall, we are encouraged that the fundamental capabilities of current models have brought us much closer to solving the problem of automated academic illustration generation. With the community's continued efforts, we believe that in the near future we will have high-quality automated drawing tools to accelerate academic research iteration and visual communication.

We warmly welcome community contributions to make PaperBanana even better!

Contributors

Thanks to all contributors who helped improve PaperBanana, whether through code, bug reports, ideas, or feedback!

Dawei Zhu
Dawei Zhu

💻 🤔 📖
lemon-prog123
lemon-prog123

💻
memray
memray

💻
elpsykongloo
elpsykongloo

🐛 🤔
weathon
weathon

🐛
arashabadi
arashabadi

💻
Ludobico
Ludobico

💻
haosenwang1018
haosenwang1018

💻 🐛
stuinfla
stuinfla

💻 🤔
ReturnYG
ReturnYG

🤔
Mylszd
Mylszd

🤔 🔧
NielsRogge
NielsRogge

🤔
MinyuChan-vem
MinyuChan-vem

🐛
catallactics
catallactics

🤔
Rui Guo
Rui Guo

🐛
YXDBright
YXDBright

🤔
Yiming Shen
Yiming Shen

💻
Edom
Edom

💻
issyuNaN
issyuNaN

🐛

PaperBanana (dwzhu-pku/PaperBanana)

Searching Database…

What is this?PaperBanana is an open-source framework that turns raw scientific content into publication-quality diagrams and plots, acting like a creative team of five specialized agents: Retriever, Planner, Stylist, Visualizer and Critic.
Is it a framework, a web app, or a command-line tool?It's a Python framework you can use three ways: a Gradio web app (recommended), an interactive Streamlit demo, or a CLI. There's also a hosted version on Hugging Face Spaces you can try with no setup at all.
How do I set it up locally, and do I need to download any dataset?Clone the repo, copy configs/modelconfig.template.yaml to configs/modelconfig.yaml with your API key, install the Python 3.12 packages via uv, then launch Gradio or Streamlit. The PaperBananaBench dataset is optional; without it the Retriever just skips its few-shot examples.
Do I need my own API key to run it?Yes — at least one of Google Gemini or OpenRouter; either alone is enough, and OpenRouter is preferred if you configure both. For generating many candidates in parallel you will need a key that supports high concurrency.
What are its current limitations?The authors admit generation is not yet fully reliable for diverse, complex scenarios. The curated reference set covers mainly computer science, and code for generating statistical plots is still on the TODO list, so diagrams are the mature path today.
How does it make figures look academically polished?The Retriever finds similar examples from a curated reference collection for in-context learning, the Planner drafts a textual figure description, and automatically synthesized style guidelines shape the output; a Critic-Visualizer loop then refines the image over multiple rounds.
How many figure candidates can it generate, and can I improve one I like?Up to 20 candidates in parallel, shown in a grid with evolution timelines and exportable as PNGs or a batch ZIP. The Refine tab lets you upload any candidate (or your own diagram), describe changes, and upscale the result to 2K or 4K.
Can I run only part of the agent pipeline?Yes. Experiment modes range from vanilla (direct generation, no planning or refinement) to devfull with all five agents, with intermediate stops like devplanner and devplannercritic; demo modes run the same pipelines without evaluation.
Where did PaperBanana come from?It forked Google-Research's PaperVizAgent and keeps evolving it. The project is fully open source under the Apache-2.0 license with no commercial plans — the authors' stated goal is simply to benefit the research community.
Creator
dwzhu-pku
Size
14.6 MB
Stars
7.2K
Updated
CommitOct 18
Age
8mo
Commits · 90 Days
