Topics / #data-pipelines
Data-pipelines projects on GitHub
Building and orchestrating data processing pipelines.
As of , the most-starred Data-pipelines projects on GitHub are pathway (62.1K stars), airflow (47.2K stars) and data-engineering-zoomcamp (46.2K stars). GitHub.Locker tracks 9 Data-pipelines repositories with 247.1K stars combined. The fastest-growing on October 16 was data-engineering-zoomcamp, with +17 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +17
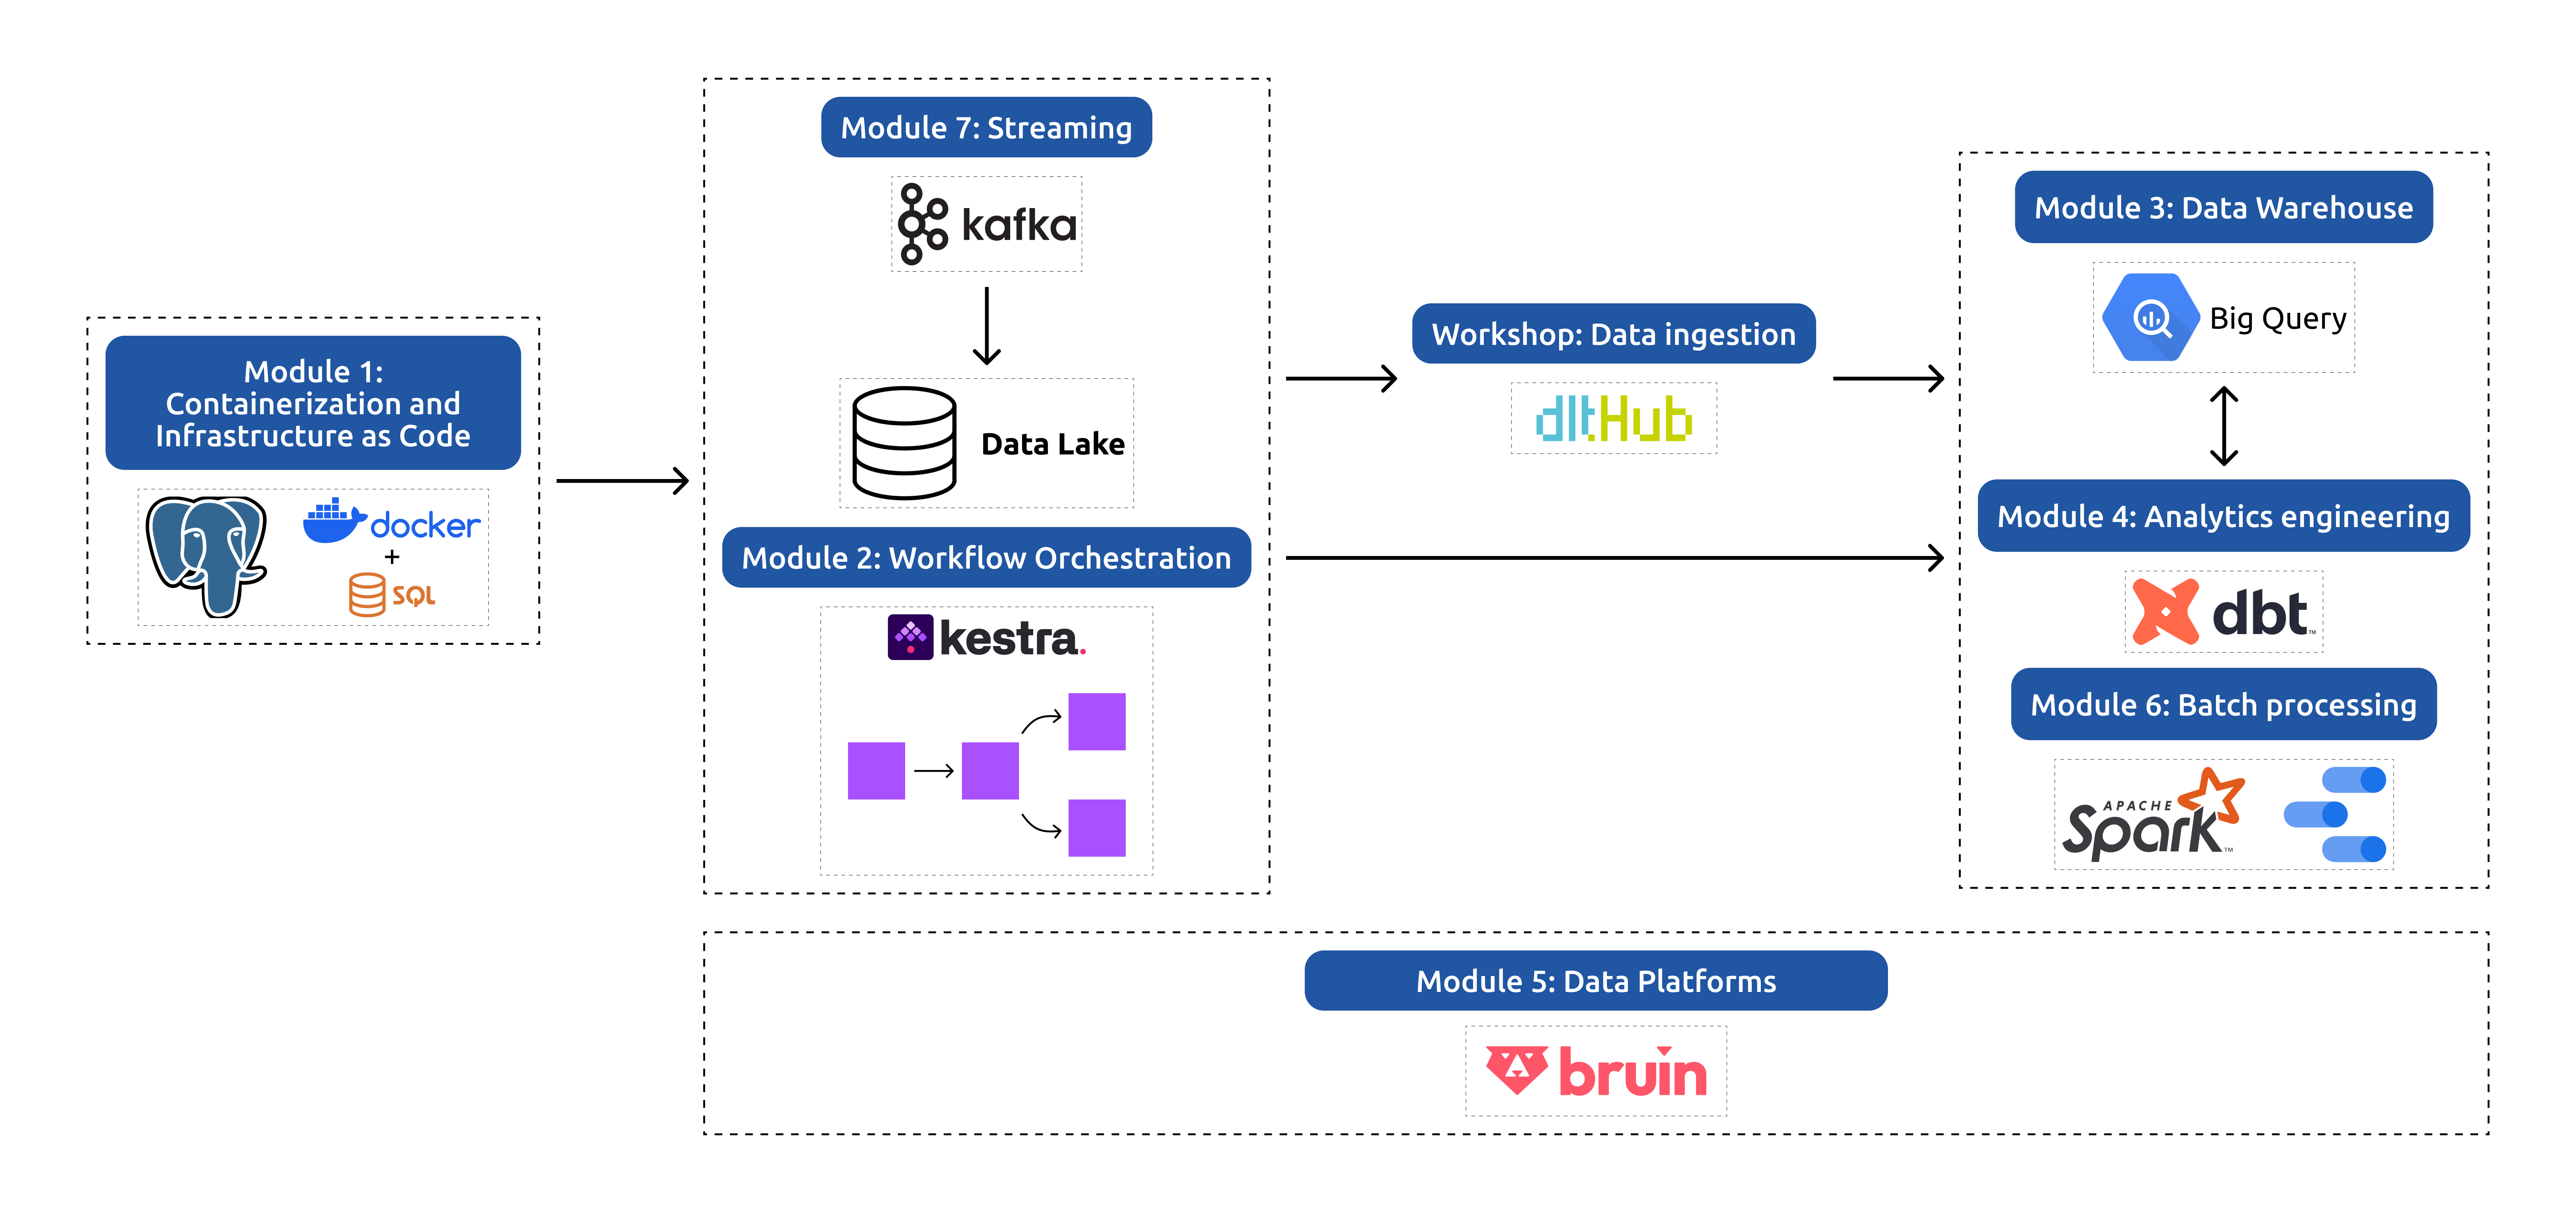
data-engineering-zoomcamp
DataTalksClub/data-engineering-zoomcamp · ★ 46.2KThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
 +10
kafka
apache/kafka · ★ 34KApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
 +7
airflow
apache/airflow · ★ 47.2KApache Airflow is a platform to programmatically author, schedule, and monitor workflows, defined as code using Python.
 +4
dagster
dagster-io/dagster · ★ 16.3KDagster is a cloud-native data pipeline orchestrator covering the whole development lifecycle: it builds, runs, and observes data assets like tables, datasets, ML models, and reports, with built-in lineage and observability.
The all-time top
9 projects · by stars
- 62.1K
 #1 · pathwaycom/pathway
pathway
Pathway is a Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG, with the same code usable for batch jobs, CI/CD tests, and live data streams.
- 47.2K#2 · apache/airflow
airflow
Apache Airflow is a platform to programmatically author, schedule, and monitor workflows, defined as code using Python.
- 46.2K#3 · DataTalksClub/data-engineering-zoomcamp
data-engineering-zoomcamp
This is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
- 4
kafka
34Kapache/kafka · JavaApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
- 5
dagster
16.3Kdagster-io/dagster · PythonDagster is a cloud-native data pipeline orchestrator covering the whole development lifecycle: it builds, runs, and observes data assets like tables, datasets, ML models, and reports, with built-in lineage and observability.
- 6
unstructured
15.6KUnstructured-IO/unstructured · HTMLUnstructured is an open-source ETL toolkit that converts complex documents like PDFs, Word docs, HTML and images into clean, structured data (JSON) ready for LLMs, RAG pipelines and vector databases.
- 7

dolphinscheduler
14.5Kapache/dolphinscheduler · JavaApache DolphinScheduler is a modern data orchestration platform for building and running complex data pipeline workflows with low-code, drag-and-drop tools.
- 8
kedro
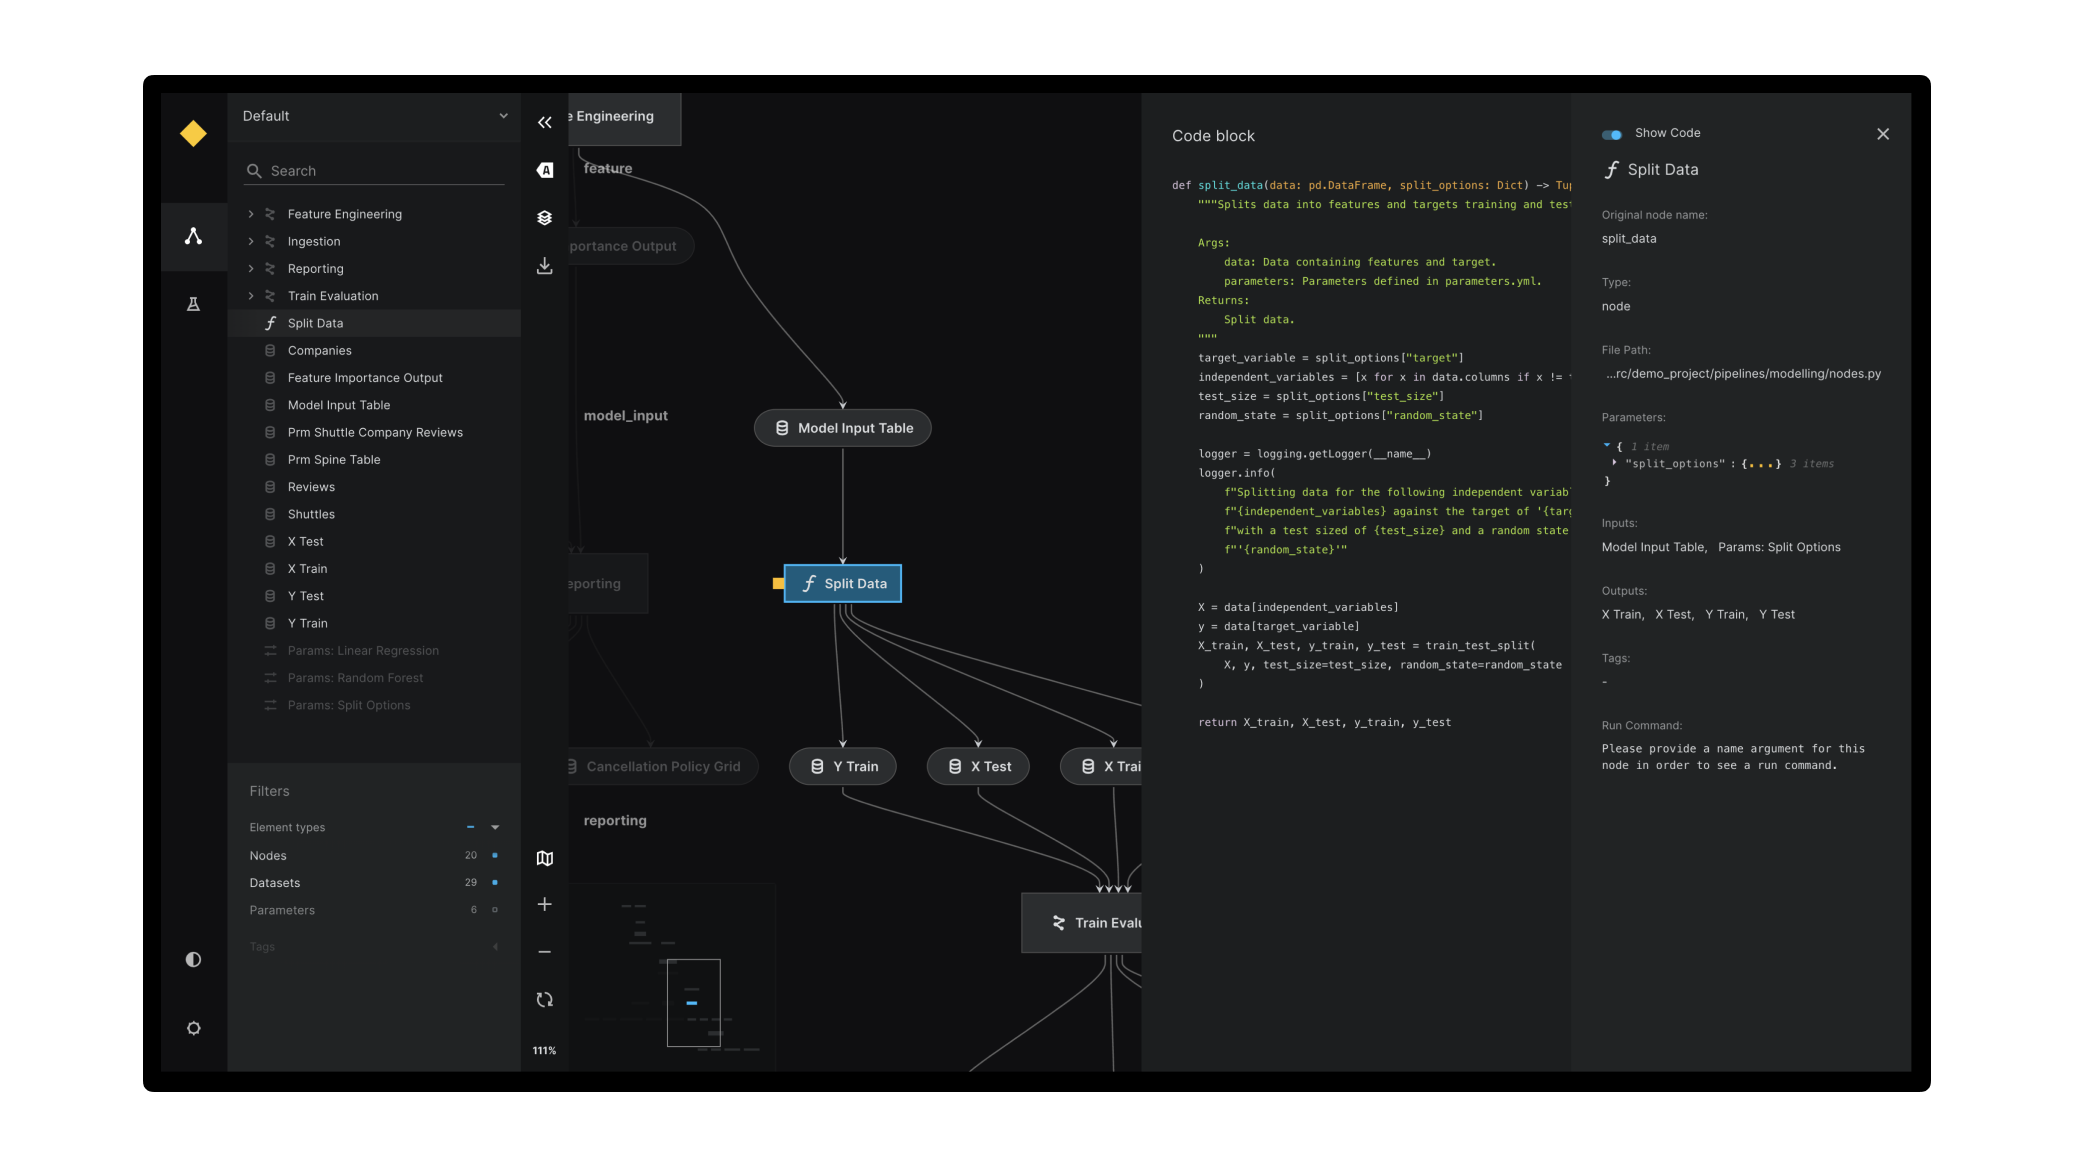
11Kkedro-org/kedro · PythonKedro is an open-source Python framework for building production-ready data engineering and data science pipelines, using software engineering best practices to make them reproducible, maintainable, and modular.
- 9

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.
Related topics
Often tagged together