Topics / #data-cleaning
Data-cleaning projects on GitHub
Tools that detect dataset errors and clean training data.
As of , the most-starred Data-cleaning projects on GitHub are great_expectations (11.9K stars), cleanlab (11.7K stars) and fiftyone (11.2K stars). GitHub.Locker tracks 5 Data-cleaning repositories with 45.3K stars combined. The fastest-growing on October 16 was fiftyone, with +3 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +3
fiftyone
voxel51/fiftyone · ★ 11.2KFiftyOne is an open-source tool for building high-quality datasets and computer vision models: you use it to visualize and label your visual data, evaluate models, and find and fix data quality issues.
 +2
great_expectations
fivetran/great_expectations · ★ 11.9KGX Core (Great Expectations) is a Python framework for testing, validating, and documenting the quality of your data. Its core concept is the 'Expectation' — an expressive unit test for your data, built from the collective experience of thousands of data quality deployments.
 +2
cleanlab
cleanlab/cleanlab · ★ 11.7KCleanlab is an open-source Python library that automatically finds issues in ML datasets — label errors, outliers, duplicates — using your existing models, so that fixing the data trains better models.
 +1
huashu-excel
alchaincyf/huashu-excel · ★ 439This is a Skill for AI coding agents that handles the entire Excel/data-analysis workflow: it profiles a messy spreadsheet, cleans it, aligns with the user on what to actually analyze, runs the analysis, reconciles the numbers against the sheet's own totals, and only then delivers a report.
The all-time top
5 projects · by stars
- 11.9K#1 · fivetran/great_expectations
great_expectations
GX Core (Great Expectations) is a Python framework for testing, validating, and documenting the quality of your data. Its core concept is the 'Expectation' — an expressive unit test for your data, built from the collective experience of thousands of data quality deployments.
- 11.7K#2 · cleanlab/cleanlab
cleanlab
Cleanlab is an open-source Python library that automatically finds issues in ML datasets — label errors, outliers, duplicates — using your existing models, so that fixing the data trains better models.
- 11.2K#3 · voxel51/fiftyone
fiftyone
FiftyOne is an open-source tool for building high-quality datasets and computer vision models: you use it to visualize and label your visual data, evaluate models, and find and fix data quality issues.
- 4
miller
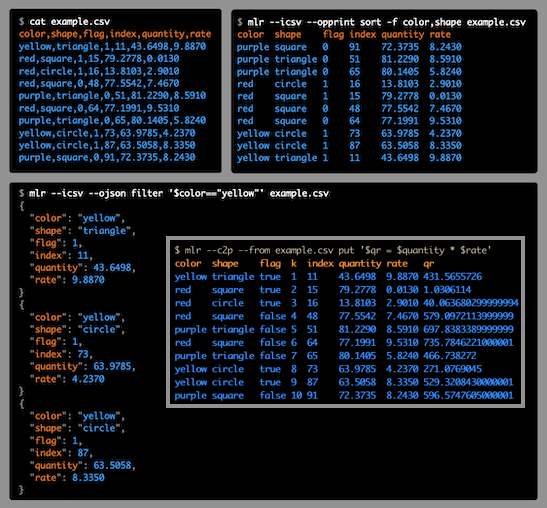
10Kjohnkerl/miller · GoMiller is a command-line toolkit like awk, sed, cut, join, and sort, but built for name-indexed data such as CSV, TSV, JSON, and JSON Lines: you address fields by name instead of counting column positions.
- 5
huashu-excel
439alchaincyf/huashu-excel · PythonThis is a Skill for AI coding agents that handles the entire Excel/data-analysis workflow: it profiles a messy spreadsheet, cleans it, aligns with the user on what to actually analyze, runs the analysis, reconciles the numbers against the sheet's own totals, and only then delivers a report.
Related topics
Often tagged together
- data-science231
- developer-tools2,924
- open-source5,666
- data-quality12
- linux4,184
- macos3,544
- python2,383
- windows3,403
- apache-2.01,434
- cli2,227
- cross-platform2,623
- tool1,295
- annotation18
- command-line-tool715
- data-analysis73
- data-validation8
- deep-learning737
- documentation426
- library1,587
- machine-learning916
- mlops47
- utility421