Topics / #stream-processing
Stream-processing projects on GitHub
Processing continuous data streams in real time.
As of , the most-starred Stream-processing projects on GitHub are pathway (62.1K stars), spark (44.2K stars) and mediapipe (37.3K stars). GitHub.Locker tracks 12 Stream-processing repositories with 324.4K stars combined. The fastest-growing on October 16 was spark, with +10 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +10
spark
apache/spark · ★ 44.2KApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
 +10
kafka
apache/kafka · ★ 34KApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
 +9
vector
vectordotdev/vector · ★ 22.7KAn open-source, high-performance observability data pipeline: it collects, transforms, and routes your logs and metrics to any vendors you choose, so you keep control of your observability data. It is maintained by Datadog's Community Open Source Engineering team.
 +6
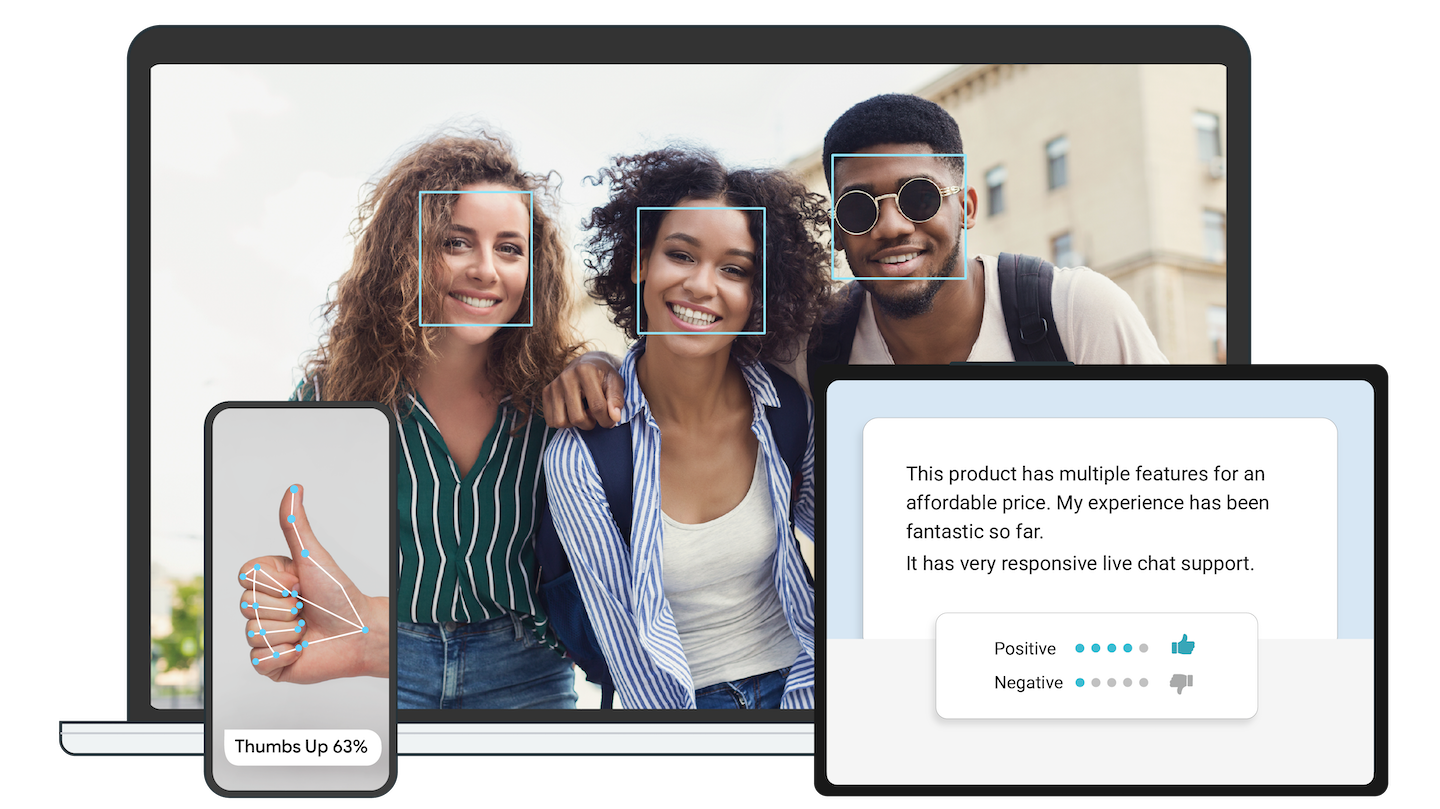
mediapipe
google-ai-edge/mediapipe · ★ 37.3KGoogle's open-source, cross-platform toolkit for on-device machine learning in live and streaming media: ready-made libraries and pre-trained models you plug straight into your own app.
The all-time top
12 projects · by stars
- 62.1K
 #1 · pathwaycom/pathway
pathway
Pathway is a Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG, with the same code usable for batch jobs, CI/CD tests, and live data streams.
- 44.2K#2 · apache/spark
spark
Apache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 37.3K#3 · google-ai-edge/mediapipe
mediapipe
Google's open-source, cross-platform toolkit for on-device machine learning in live and streaming media: ready-made libraries and pre-trained models you plug straight into your own app.
- 4
kafka
34Kapache/kafka · JavaApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
- 5
flink
26.4Kapache/flink · JavaApache Flink is an open source stream processing framework with powerful stream- and batch-processing capabilities, running your programs on its own distributed runtime.
- 6

TDengine
25.2Ktaosdata/TDengine · CTDengine is an open-source, high-performance, cloud-native, AI-powered time-series database built for IoT, Connected Cars, and Industrial IoT workloads, handling TB-to-PB scale data from billions of sensors.
- 7
vector
22.7Kvectordotdev/vector · RustAn open-source, high-performance observability data pipeline: it collects, transforms, and routes your logs and metrics to any vendors you choose, so you keep control of your observability data. It is maintained by Datadog's Community Open Source Engineering team.
- 8

questdb
17.4Kquestdb/questdb · JavaQuestDB is an open-source, low-latency time-series database on open formats: it ingests millions of events per second, computes on live data in milliseconds, and keeps years of history queryable through one SQL engine.
- 9

flink-learning
15.1Kzhisheng17/flink-learning · JavaA companion repo to a Chinese-language Apache Flink learning blog, packed with runnable example code, source-code analysis articles, and real-world project case studies (PV/UV stats, log storage, large-scale dedup, monitoring/alerting).
- 10

awesome-bigdata
14.7Koxnr/awesome-bigdataA curated list of frameworks, databases, tools, papers, and resources related to big data, covering everything from distributed processing engines to key-value stores and visualization tools.
- 11
awesome-system-design
12.6Kmadd86/awesome-system-designA curated list of articles, books, videos, and tools for learning System Design (distributed systems), useful both for interview prep and for designing real distributed/microservice applications.
- 12
redpanda
12.6Kredpanda-data/redpanda · C++Redpanda is a streaming data platform that is wire-compatible with the Apache Kafka API but is built from the ground up in C++ to be lighter, faster, and simpler to operate.
Related topics
Often tagged together
- distributed-systems270
- streaming273
- kafka44
- kubernetes316
- linux4,184
- open-source5,666
- big-data59
- macos3,544
- server1,459
- database473
- docker1,660
- java450
- machine-learning916
- python2,383
- real-time240
- self-hosted1,929
- sql206
- framework758
- high-performance141
- monitoring418
- analytics131
- apache-2.01,434
- cli2,227
- data-engineering56