Topics / #big-data
Big-data projects on GitHub
Processing datasets too large for single machines with distributed frameworks.
As of , the most-starred Big-data projects on GitHub are advanced-java (79.2K stars), elasticsearch (78.3K stars) and awesome-scalability (74.8K stars). GitHub.Locker tracks 59 Big-data repositories with 1.3M stars combined. The fastest-growing on October 16 was kestra, with +29 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +29
kestra
kestra-io/kestra · ★ 29.7KKestra is an open-source, event-driven orchestration platform for building data, AI, and infrastructure workflows. You describe them in declarative YAML and manage everything from a built-in web UI.
 +25
awesome-scalability
binhnguyennus/awesome-scalability · ★ 74.8KA curated, continuously updated reading list of articles, case studies, and talks from engineers at companies like Netflix, Uber, Facebook, and Amazon, showing concrete patterns for building scalable, reliable, and performant large-scale systems.
 +15
awesome-design-patterns
DovAmir/awesome-design-patterns · ★ 49.4KA curated list of links to resources about software and architecture design patterns, covering everything from language-specific patterns to cloud, serverless, microservices, IoT, big data, ML, databases, DevOps, mobile, front-end and security.
 +12
ClickHouse
ClickHouse/ClickHouse · ★ 50.5KClickHouse is an open-source column-oriented database management system for generating analytical data reports in real time.
The all-time top
59 projects · by stars
- 79.2K
#1 · doocs/advanced-java
advanced-java
A free, community-curated collection of in-depth Java backend interview questions and answers, covering message queues, search engines, caching, sharding, distributed systems, high availability, microservices, and big-data processing.
- 78.3K
 #2 · elastic/elasticsearch
elasticsearch
Elasticsearch is a distributed search and analytics engine, scalable data store, and vector database built for near real-time full-text search, vector search, and generative AI (RAG) use cases on production-scale data; it's the core of Elastic's Stack platform.
- 74.8K#3 · binhnguyennus/awesome-scalability
awesome-scalability
A curated, continuously updated reading list of articles, case studies, and talks from engineers at companies like Netflix, Uber, Facebook, and Amazon, showing concrete patterns for building scalable, reliable, and performant large-scale systems.
- 4
ClickHouse
50.5KClickHouse/ClickHouse · C++ClickHouse is an open-source column-oriented database management system for generating analytical data reports in real time.
- 5
awesome-design-patterns
49.4KDovAmir/awesome-design-patternsA curated list of links to resources about software and architecture design patterns, covering everything from language-specific patterns to cloud, serverless, microservices, IoT, big data, ML, databases, DevOps, mobile, front-end and security.
- 6

data-engineer-handbook
44.5KDataExpert-io/data-engineer-handbook · Jupyter NotebookA curated handbook of links and resources for learning data engineering: roadmaps, bootcamp materials, books, communities, company tooling lists, blogs, whitepapers, and a directory of data engineering content creators.
- 7
spark
44.2Kapache/spark · ScalaApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 8

kafka
34Kapache/kafka · JavaApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
- 9
kestra
29.7Kkestra-io/kestra · JavaKestra is an open-source, event-driven orchestration platform for building data, AI, and infrastructure workflows. You describe them in declarative YAML and manage everything from a built-in web UI.
- 10
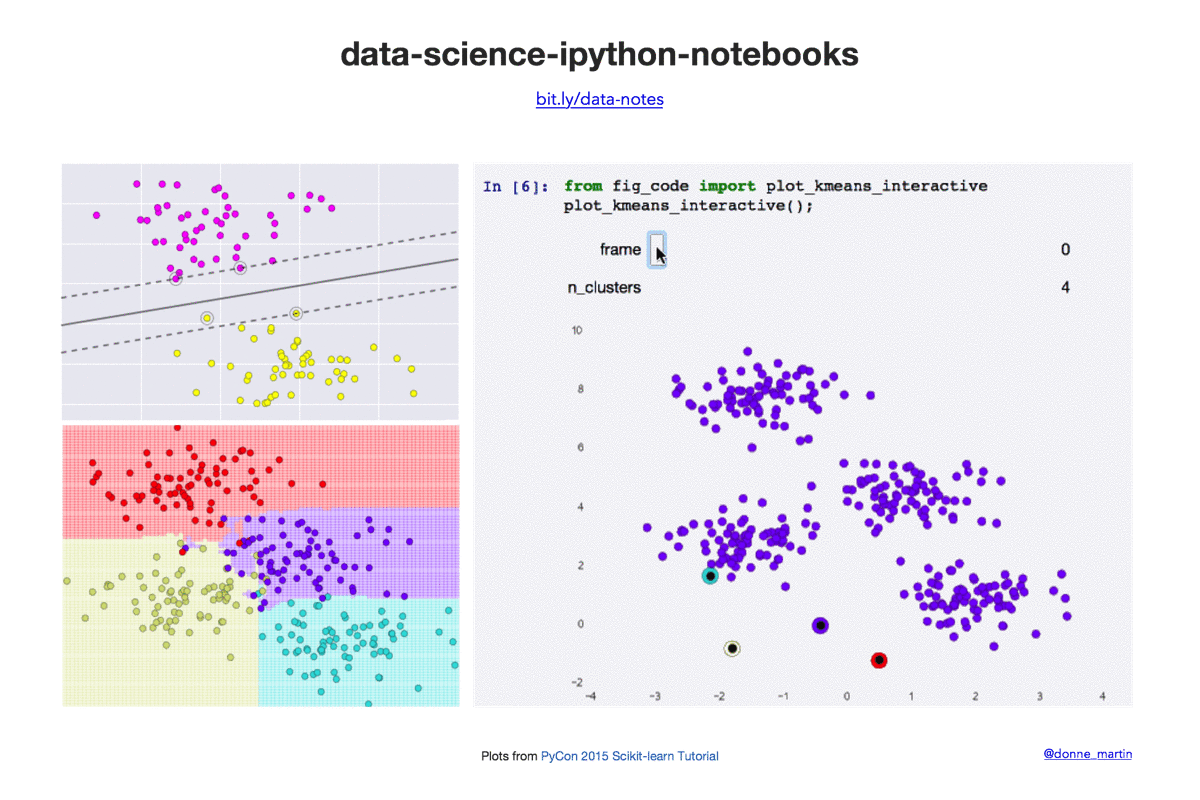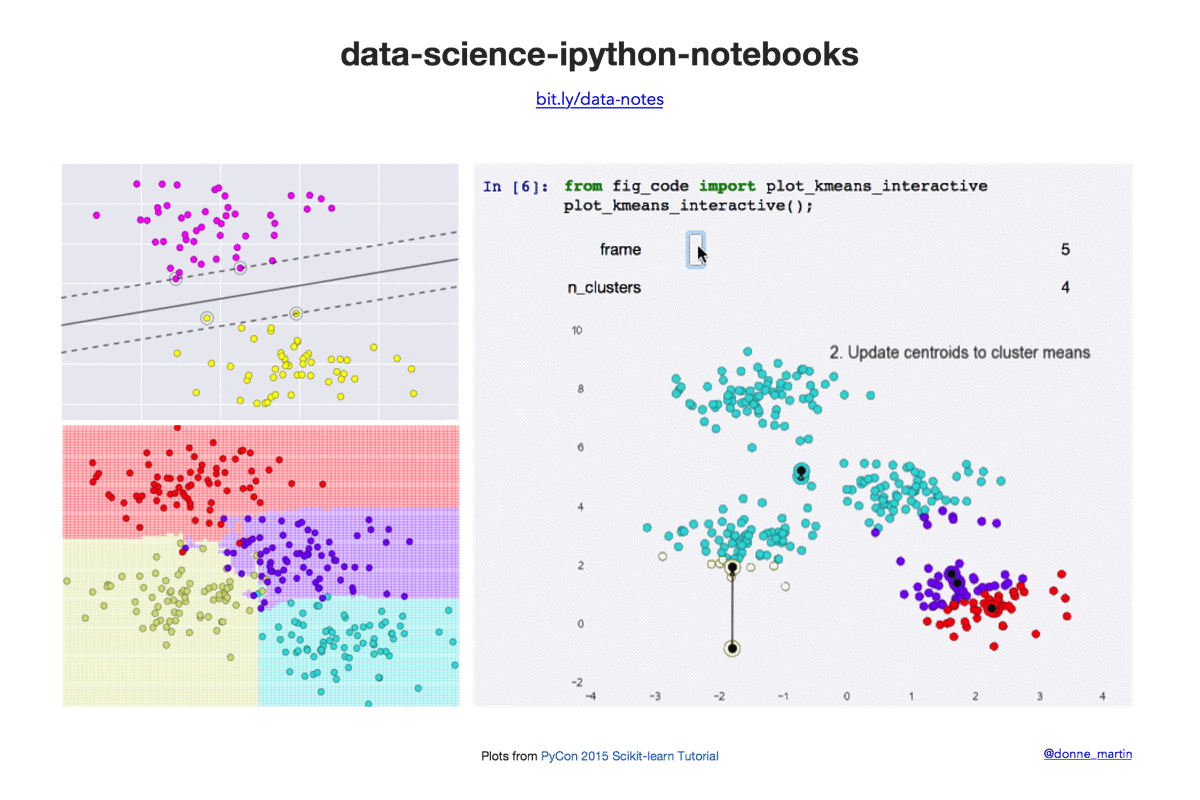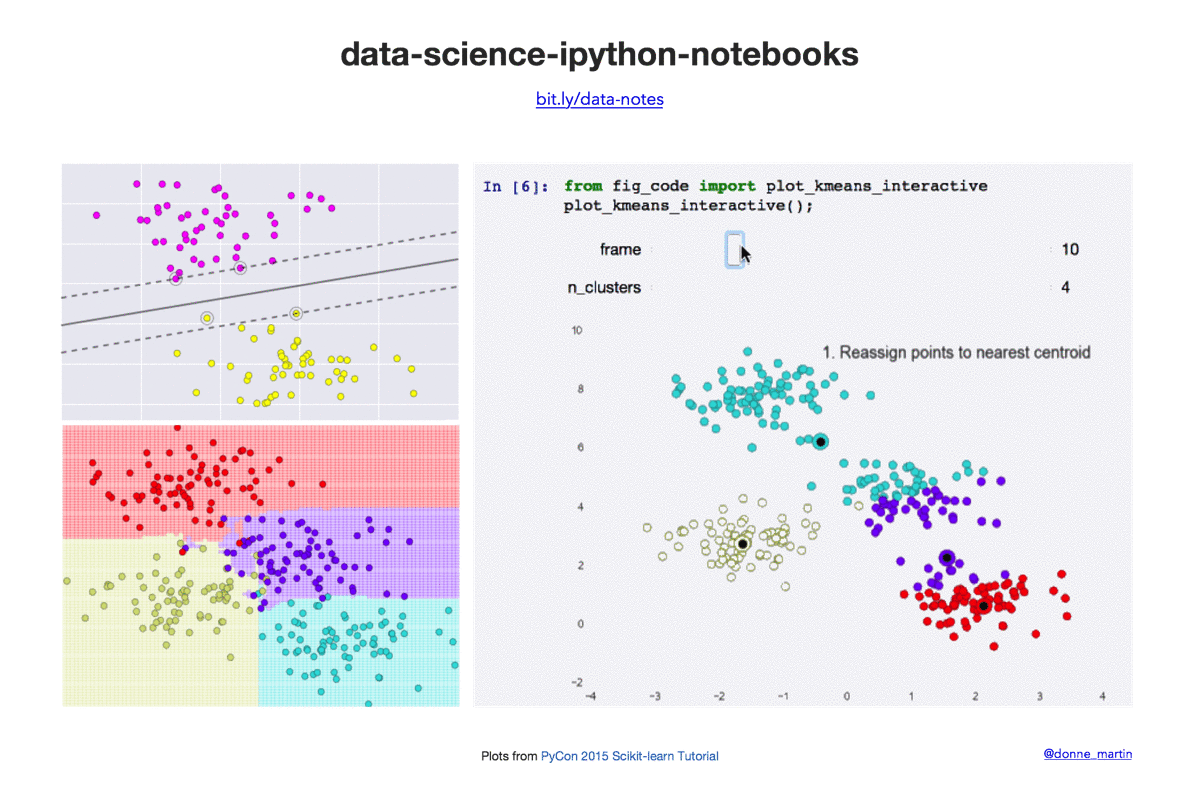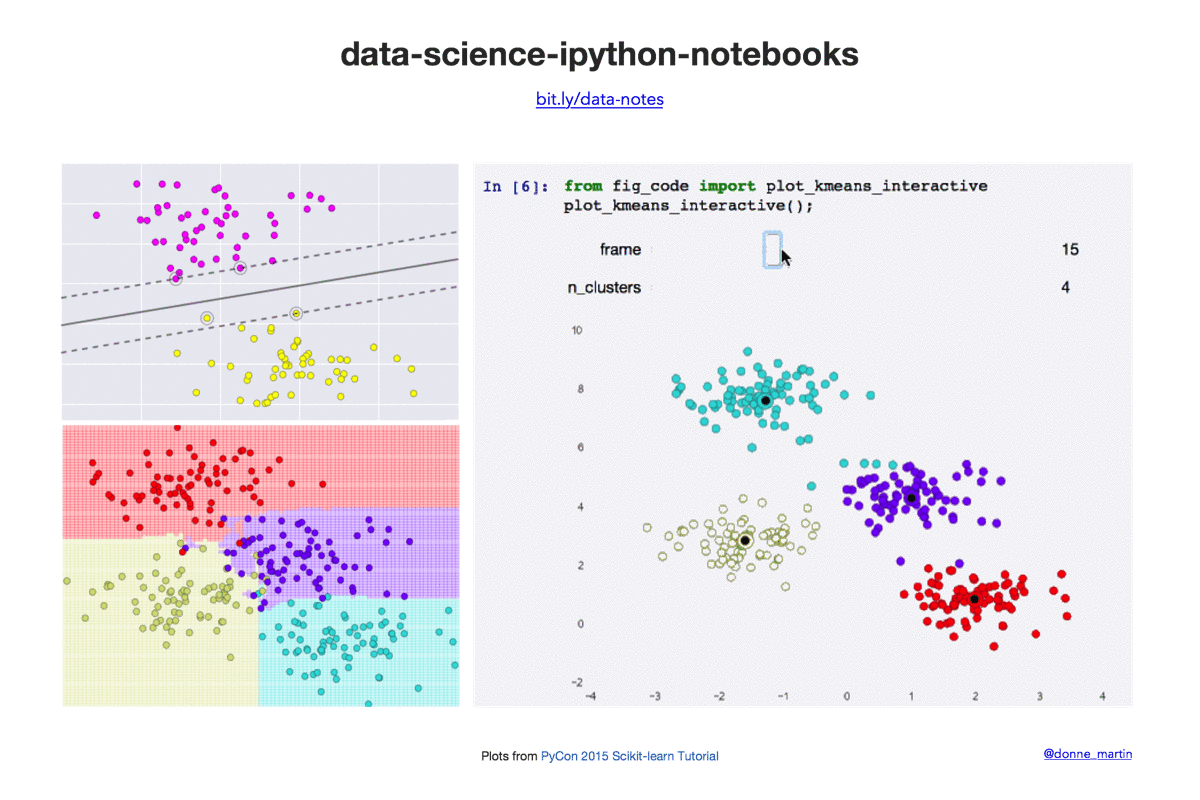
data-science-ipython-notebooks
29.4Kdonnemartin/data-science-ipython-notebooks · PythonA large curated collection of IPython/Jupyter notebooks covering the Python data science stack: deep learning (TensorFlow, Theano, Caffe, Keras), scikit-learn, statistics with SciPy, pandas, matplotlib, NumPy, Kaggle competition analyses, big data (Spark, Hadoop MapReduce, HDFS), AWS, and command-line essentials.
- 11

COVID-19
28.9KCSSEGISandData/COVID-19The COVID-19 data repository by Johns Hopkins University's Center for Systems Science and Engineering (CSSE) — the case data behind their widely used pandemic Visual Dashboard.
- 12
xgboost
28.9Kdmlc/xgboost · C++XGBoost is an optimized distributed gradient boosting library designed to be highly efficient, flexible and portable — it implements machine learning algorithms under the Gradient Boosting framework.
- 13
flink
26.4Kapache/flink · JavaApache Flink is an open source stream processing framework with powerful stream- and batch-processing capabilities, running your programs on its own distributed runtime.
- 14
timescaledb
23.7Ktimescale/timescaledb · CTimescaleDB is a PostgreSQL extension for high-performance real-time analytics on time-series and event data — sensor readings, financial ticks, application events. You work with it in regular SQL.
- 15
rocketmq
22.6Kapache/rocketmq · JavaApache RocketMQ is an open-source distributed messaging and streaming platform for building event-driven applications, with low latency, trillion-level capacity and flexible scalability.
- 16
thingsboard
22.6Kthingsboard/thingsboard · JavaThingsBoard is an open-source IoT platform for device management, data collection, processing, and visualization: connect devices, store their telemetry, and build dashboards on top.
- 17

skill-map
22KTeamStuQ/skill-map · HTMLA Geekbang-run open collection of skill maps for programmers: each map lays out the knowledge tree for one IT field and comes with learning paths and curated resources to guide what to learn next.
- 18
kibana
21.3Kelastic/kibana · TypeScriptKibana is the open source interface for querying, analyzing, visualizing, and managing your data stored in Elasticsearch — effectively the web window into an Elastic Stack deployment.
- 19

cube
21Kcube-js/cube · RustAn open-source semantic layer: define metrics, dimensions, joins and access rules once in code, and it serves them through SQL, REST and GraphQL APIs to BI tools, custom apps and AI agents.
- 20

architecture.of.internet-product
20.8Kdavideuler/architecture.of.internet-product · HTMLThis is a curated Chinese-language collection of real-world technical architecture documents from major internet companies — WeChat/Tencent, Taobao/Alibaba, Meituan-Dianping, Baidu, Qihoo 360, and global players like OpenAI, Google, Facebook, Amazon and eBay.
- 21

gun
19.1Kamark/gun · JavaScriptGUN is an open source cybersecurity protocol for syncing decentralized graph data — a peer-to-peer database that keeps app data in sync across browsers and devices, with no master server and no single source of truth.
- 22

luigi
18.8Kspotify/luigi · PythonLuigi is a Python package for building complex pipelines of batch jobs. It handles dependency resolution, workflow management, visualization, failure handling and command line integration.
- 23

VictoriaMetrics
17.9KVictoriaMetrics/VictoriaMetrics · GoVictoriaMetrics is a fast, cost-effective monitoring solution and time series database. It stores metrics long-term and can serve as storage for Prometheus or a drop-in replacement for Prometheus and Graphite in Grafana.
- 24

DataX
17.4Kalibaba/DataX · JavaDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
- 25
arrow
17.2Kapache/arrow · C++Apache Arrow is a universal columnar format plus a multi-language toolbox for fast data interchange and in-memory analytics — technologies that let data systems store, process, and move tabular data efficiently.
- 26

BigData-Notes
17Kheibaiying/BigData-Notes · JavaThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
- 27
tikv
16.9Ktikv/tikv · RustAn open-source, distributed, transactional key-value database. Unlike traditional NoSQL systems, it offers not only classical key-value APIs but also transactional APIs with ACID compliance.
- 28

presto
16.8Kprestodb/presto · JavaPresto is a distributed SQL query engine for running interactive analytic queries against big data sources.
- 29
ds-cheatsheets
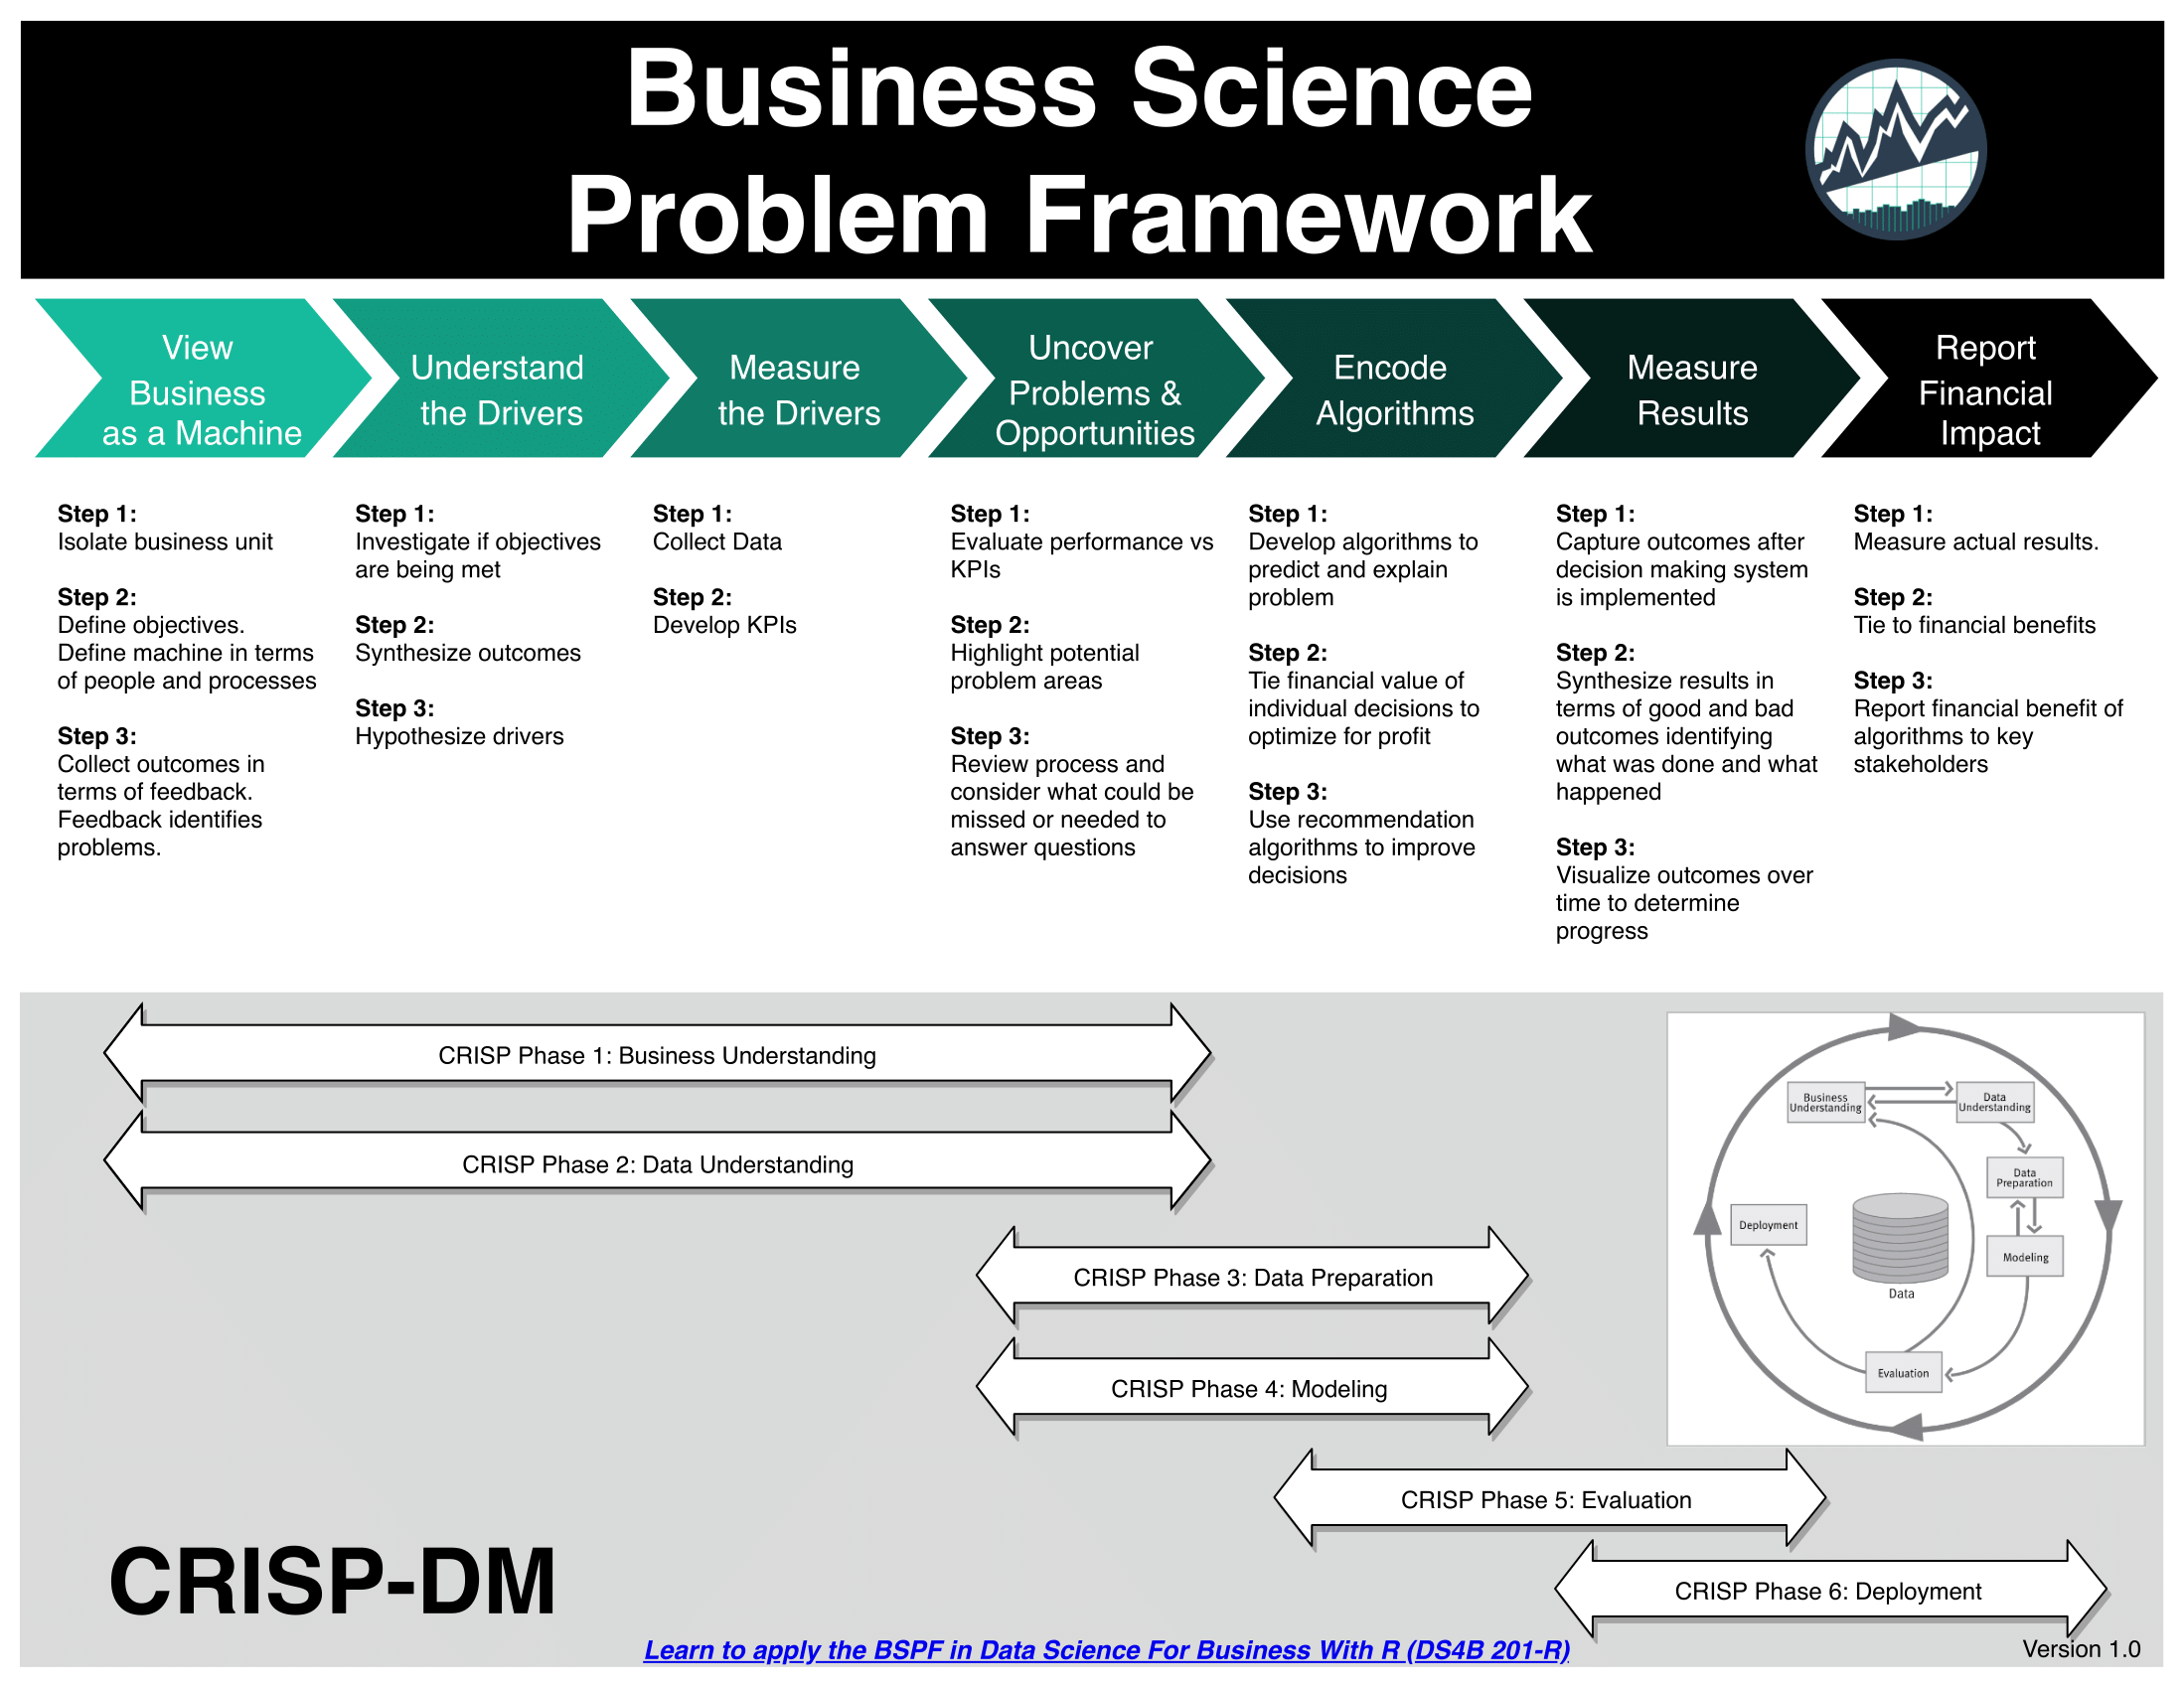
16.4KFavioVazquez/ds-cheatsheetsA curated list of data science cheatsheets covering Python, R, math, big data, machine learning, deep learning, SQL, and data visualization, meant to be a quick-reference collection rather than a tutorial.
- 30

doris
16.1Kapache/doris · JavaApache Doris is an open-source, real-time analytics and search database built on MPP architecture. It serves fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
- 31

scylladb
15.8Kscylladb/scylladb · C++Scylla is a real-time big data database — a distributed NoSQL data store that is API-compatible with Apache Cassandra and Amazon DynamoDB and built on the Seastar framework.
- 32
hadoop
15.7Kapache/hadoop · JavaApache Hadoop is the open-source big data platform for reliable, distributed storage and processing of very large data sets across clusters of machines.
- 33

Cookbook
15.5Kandkret/Cookbook · PythonA free online book (the Data Engineering Cookbook) that covers everything a data engineer needs to know, from basic engineering skills to advanced platform design, case studies and interview prep.
- 34

pulsar
15.3Kapache/pulsar · JavaApache Pulsar is a distributed publish-subscribe messaging platform built for horizontal scale, designed to handle millions of topics and millions of messages per second with strong ordering and durability guarantees.
- 35

flink-learning
15.1Kzhisheng17/flink-learning · JavaA companion repo to a Chinese-language Apache Flink learning blog, packed with runnable example code, source-code analysis articles, and real-world project case studies (PV/UV stats, log storage, large-scale dedup, monitoring/alerting).
- 36
logstash
15Kelastic/logstash · JavaLogstash is a server-side data processing pipeline, part of the Elastic Stack, that ingests data from many sources at once, transforms it, and sends it to a destination like Elasticsearch.
- 37

awesome-bigdata
14.7Koxnr/awesome-bigdataA curated list of frameworks, databases, tools, papers, and resources related to big data, covering everything from distributed processing engines to key-value stores and visualization tools.
- 38
druid
14.1Kapache/druid · JavaApache Druid is a high-performance real-time analytics database built to reduce the time between data arriving and being queryable, so dashboards and ad-hoc queries stay fast even under high concurrency.
- 39

dask
13.9Kdask/dask · PythonDask is a flexible parallel computing library for analytics — it runs Python data workloads as scheduled tasks so they can use many cores or machines instead of a single process.
- 40

OpenSearch
13.9Kopensearch-project/OpenSearch · JavaOpenSearch is an open-source, enterprise-grade search and observability suite built to search, analyze, and index unstructured data at scale.
- 41
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 42
trino
13.3Ktrinodb/trino · JavaTrino is a fast distributed SQL query engine for big data analytics — you run it as a server (or cluster) and query large datasets with standard SQL. It was formerly known as PrestoSQL.
- 43

data-engineer-roadmap
12.8Kdatastacktv/data-engineer-roadmapA roadmap that maps out the modern data engineering landscape, meant to serve as a study guide for people who want to become data engineers.
- 44
redpanda
12.6Kredpanda-data/redpanda · C++Redpanda is a streaming data platform that is wire-compatible with the Apache Kafka API but is built from the ground up in C++ to be lighter, faster, and simpler to operate.
- 45
predictionio
12.5Kapache/predictionio · ScalaApache PredictionIO is an open source machine learning server that lets developers and data scientists collect events, deploy algorithms, evaluate them, and query predictive results through REST APIs.
- 46
nebula
12.4Kvesoft-inc/nebula · C++NebulaGraph is an open-source distributed graph database built to handle large volumes of highly connected data with millisecond latency and quick horizontal scaling.
- 47

kafka-ui
12.3Kprovectus/kafka-ui · JavaA free, open-source web UI for monitoring and managing Apache Kafka clusters — a lightweight dashboard that makes your data flows observable and helps find and troubleshoot issues faster. Built by developers, for developers.
- 48

starrocks
12.2KStarRocks/starrocks · JavaStarRocks is an open-source, high-performance query engine for sub-second, ad-hoc analytics on data warehouses and data lakes, built as a Linux Foundation project.
- 49
kepler.gl
12Kkeplergl/kepler.gl · TypeScriptKepler.gl is a high-performance, web-based tool for visually exploring large-scale geolocation data sets, built on MapLibre GL and deck.gl.
- 50
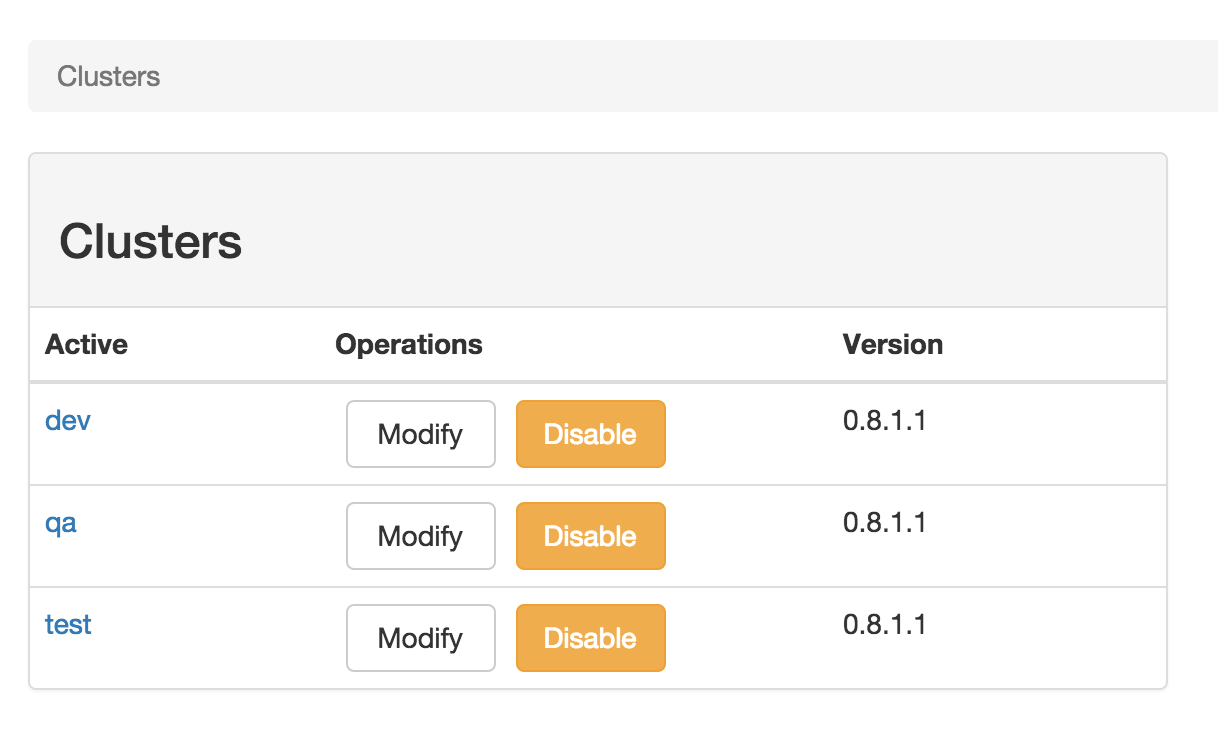
CMAK
11.9Kyahoo/CMAK · ScalaCMAK (Cluster Manager for Apache Kafka, formerly known as Kafka Manager) is a self-hosted web tool for managing Apache Kafka clusters, and it can handle multiple clusters from one interface.
- 51

quickwit
11.7Kquickwit-oss/quickwit · RustQuickwit is an open-source, cloud-native search engine built for observability - log management and distributed tracing - that runs sub-second search directly on cloud storage like S3.
- 52
from_coder_to_expert
11.2K0voice/from_coder_to_expertA curated Chinese collection of internal tech-sharing PDFs and PPTs from engineers at big Chinese tech companies, pitched as a path 'from coder to CTO', plus a weekly job-listing section.
- 53

cython
10.9Kcython/cython · CythonCython is an optimising compiler for Python: it translates your Python code into C/C++ and compiles it into fast native extension modules. It is the most widely used Python to C compiler.
- 54
modin
10.4Kmodin-project/modin · PythonModin is a drop-in replacement for pandas: you keep the same API and syntax, but your workflows run on all of your CPU cores instead of a single thread. Change one import line and your existing pandas code just runs faster.
- 55
metaflow
10.3KNetflix/metaflow · PythonMetaflow is an open-source Python framework for building, managing and deploying real-life AI and ML systems — from quick prototyping in notebooks to reliable production deployments.
- 56
3FS
10.3Kdeepseek-ai/3FS · C++3FS (Fire-Flyer File System) is a high-performance distributed file system built by DeepSeek to handle AI training and inference storage workloads at scale, pooling thousands of SSDs and hundreds of storage nodes behind RDMA networking into one shared storage layer.
- 57
cassandra
10.1Kapache/cassandra · JavaApache Cassandra is an open source, transactional distributed database — a highly-scalable partitioned row store built for linear scalability and proven fault-tolerance on commodity hardware or cloud infrastructure.
- 58
autumn-recruitment
263Akun-python/autumn-recruitment · Jupyter NotebookIt is a community-built, Chinese-language collection of Jupyter notebooks covering math foundations, data structures, machine learning, deep learning, LLMs, agents, AI infrastructure, speech, and data science, aimed at job-hunting ('autumn recruitment') interview prep in the LLM era.
- 59

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.
Related topics
Often tagged together
- open-source5,666
- distributed-systems270
- linux4,184
- server1,459
- apache-2.01,434
- database473
- self-hosted1,929
- java450
- docker1,660
- data-engineering56
- analytics131
- machine-learning916
- sql206
- python2,383
- data-science231
- kubernetes316
- macos3,544
- cloud443
- streaming273
- education933
- devops455
- kafka44
- monitoring418
- observability236