




What is this?
 Apache Druid is a high-performance real-time analytics database built to reduce the time between data arriving and being queryable, so dashboards and ad-hoc queries stay fast even under high concurrency.
Is this a library I embed, or a standalone database I run?It's a standalone distributed database server that you deploy and query, not a library you import into an app; you interact with it over HTTP/JDBC APIs or the built-in web console.
It's a standalone distributed database server that you deploy and query, not a library you import into an app; you interact with it over HTTP/JDBC APIs or the built-in web console.How do I get Druid running?Use the local quickstart or the Docker quickstart to spin up a single-node Druid cluster and start loading data.
Use the local quickstart or the Docker quickstart to spin up a single-node Druid cluster and start loading data.Does Druid have built-in Kubernetes support?Not directly in this repo — Kubernetes deployments are handled by the druid-operator, which lives in a separate repository rather than being bundled with Druid itself.
Not directly in this repo — Kubernetes deployments are handled by the druid-operator, which lives in a separate repository rather than being bundled with Druid itself.What platforms does Druid run on?Druid runs as a self-hosted server on Linux, and can be started locally or via the provided Docker quickstart.
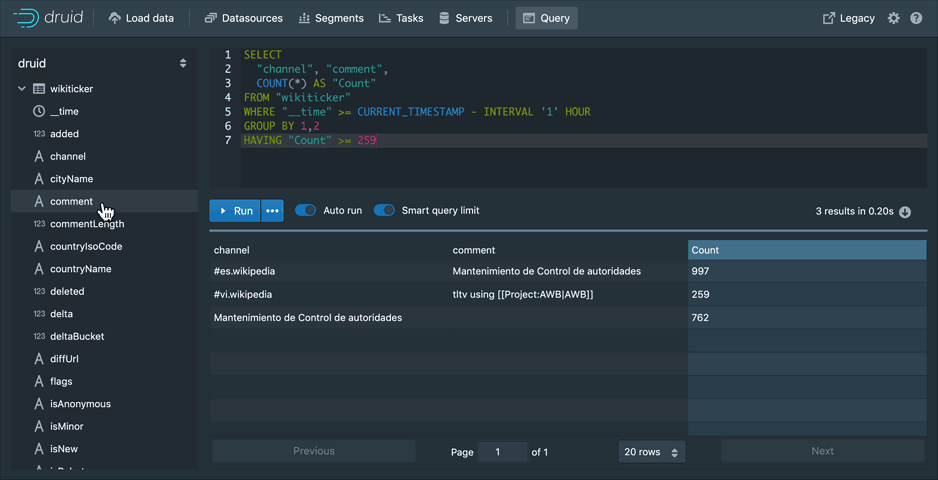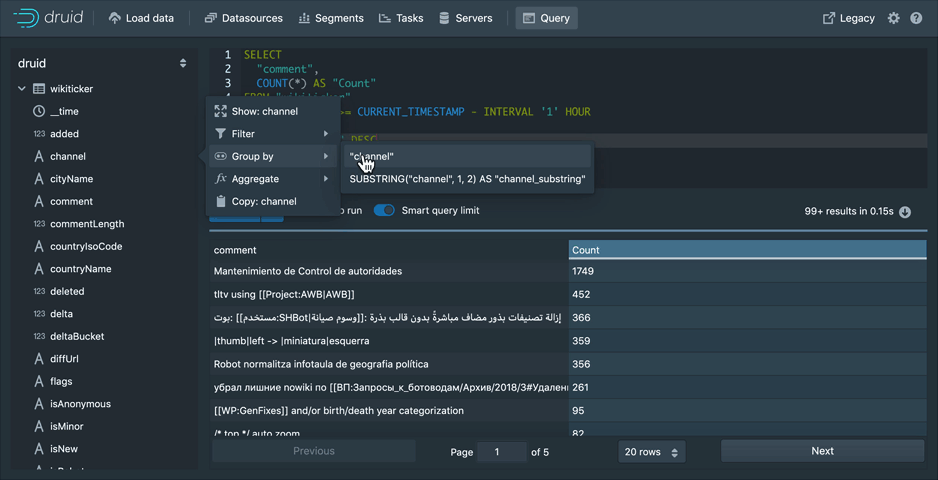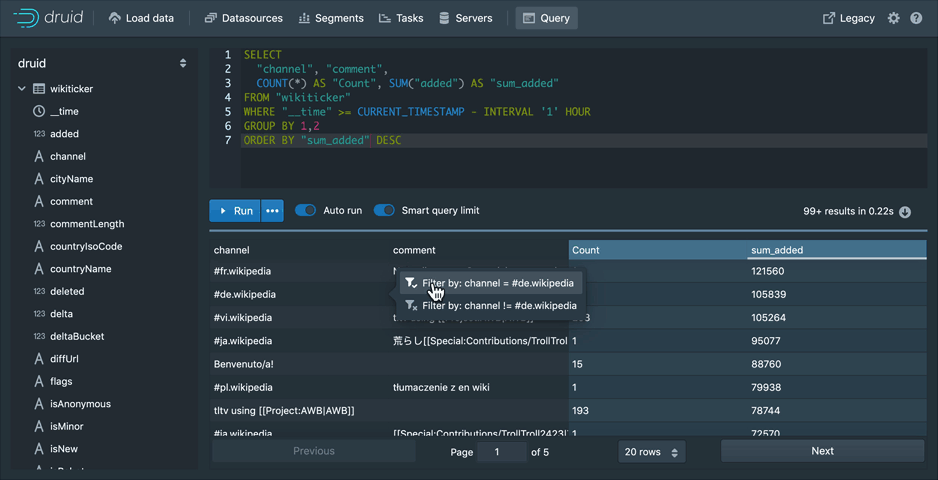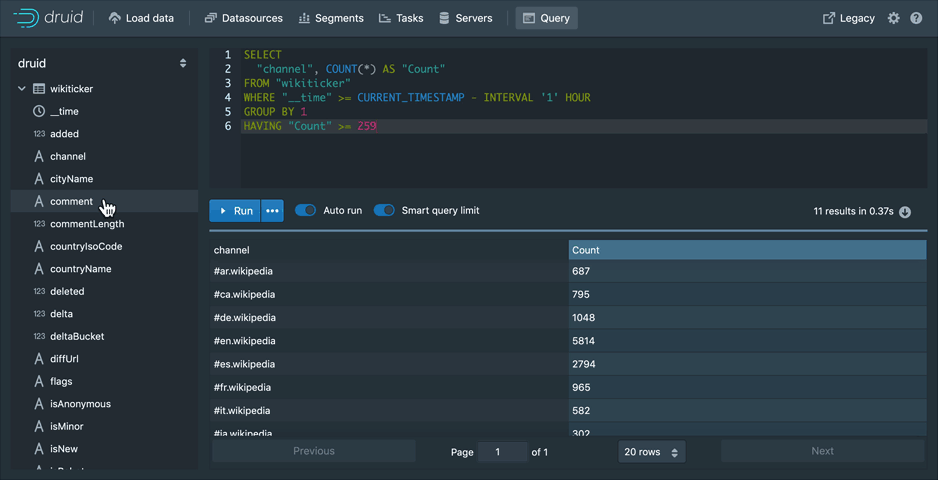
Druid runs as a self-hosted server on Linux, and can be started locally or via the provided Docker quickstart.How do I actually query data in Druid?You use the built-in query workbench to write DruidSQL or native JSON queries, or connect an external BI/SQL tool that supports Druid.
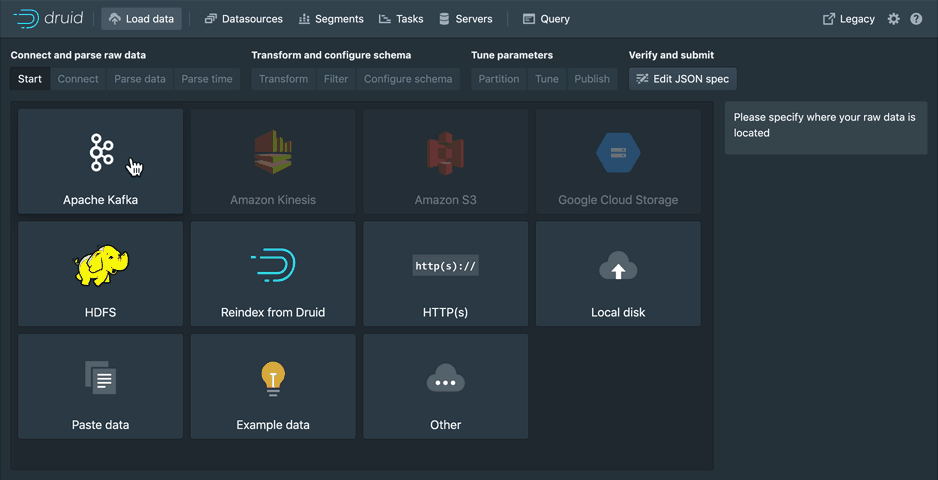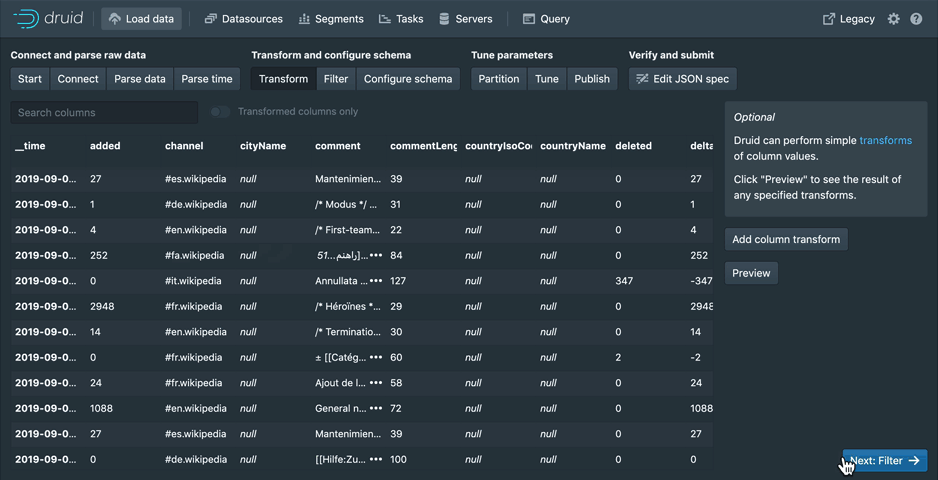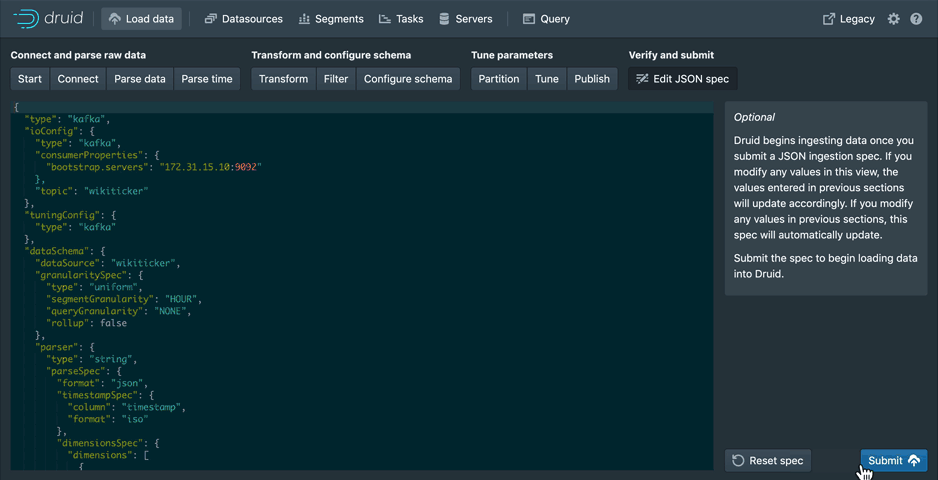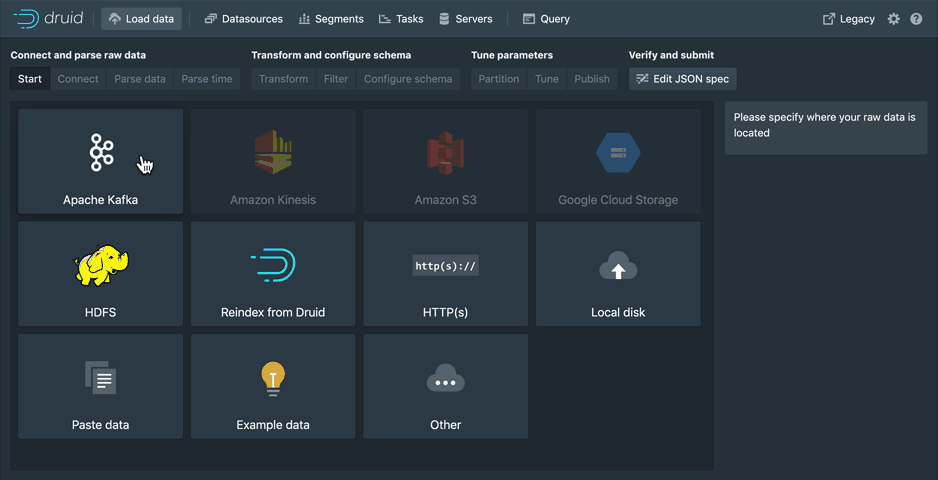
You use the built-in query workbench to write DruidSQL or native JSON queries, or connect an external BI/SQL tool that supports Druid.What can I do from the web console?Load streaming and batch data through a point-and-click wizard, monitor ingestion tasks and supervisors, and view datasources, segments and services, all backed by SQL system tables.
Load streaming and batch data through a point-and-click wizard, monitor ingestion tasks and supervisors, and view datasources, segments and services, all backed by SQL system tables.Why use Druid instead of a traditional data warehouse?Druid is optimized for fast ingest and fast queries, which makes it a good fit for powering UIs, ad-hoc operational queries, and high-concurrency workloads where a typical data warehouse is too slow.
Druid is optimized for fast ingest and fast queries, which makes it a good fit for powering UIs, ad-hoc operational queries, and high-concurrency workloads where a typical data warehouse is too slow.What are similar projects?trino, doris, starrocks, ClickHouse, oceanbase, tidb, questdb, timescaledb
trino, doris, starrocks, ClickHouse, oceanbase, tidb, questdb, timescaledbWhich topics is it in?olap, distributed-database, time-series, data-engineering, big-data, analytics, sql, real-time, distributed-systems, kubernetes, cloud, java
olap, distributed-database, time-series, data-engineering, big-data, analytics, sql, real-time, distributed-systems, kubernetes, cloud, java