Topics / #hadoop
Hadoop projects on GitHub
Distributed storage and batch processing built around the Hadoop ecosystem.
As of , the most-starred Hadoop projects on GitHub are spark (44.2K stars), data-science-ipython-notebooks (29.4K stars) and cat (18.9K stars). GitHub.Locker tracks 14 Hadoop repositories with 260.8K stars combined. The fastest-growing on October 16 was spark, with +10 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +10
spark
apache/spark · ★ 44.2KApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
 +5
trino
trinodb/trino · ★ 13.3KTrino is a fast distributed SQL query engine for big data analytics — you run it as a server (or cluster) and query large datasets with standard SQL. It was formerly known as PrestoSQL.
 +2
DataX
alibaba/DataX · ★ 17.4KDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
 +2
BigData-Notes
heibaiying/BigData-Notes · ★ 17KThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
The all-time top
14 projects · by stars
- 44.2K#1 · apache/spark
spark
Apache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 29.4K
 #2 · donnemartin/data-science-ipython-notebooks
data-science-ipython-notebooks
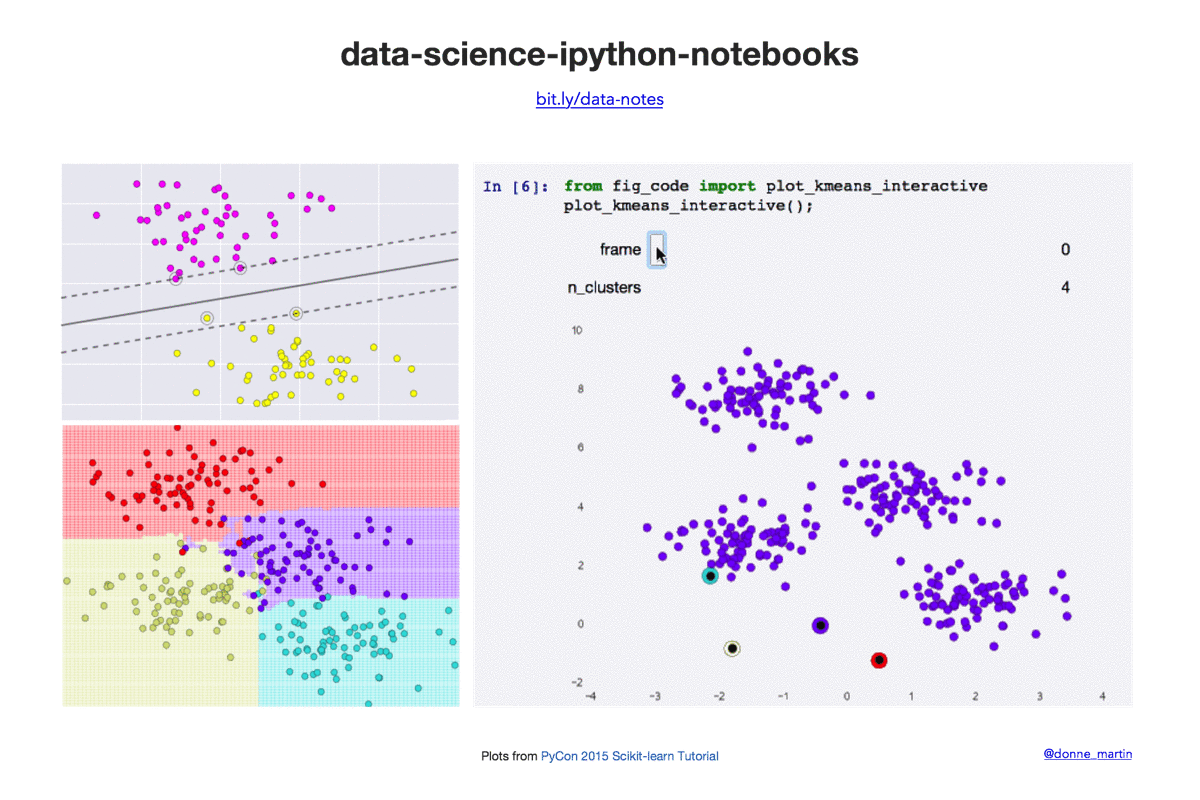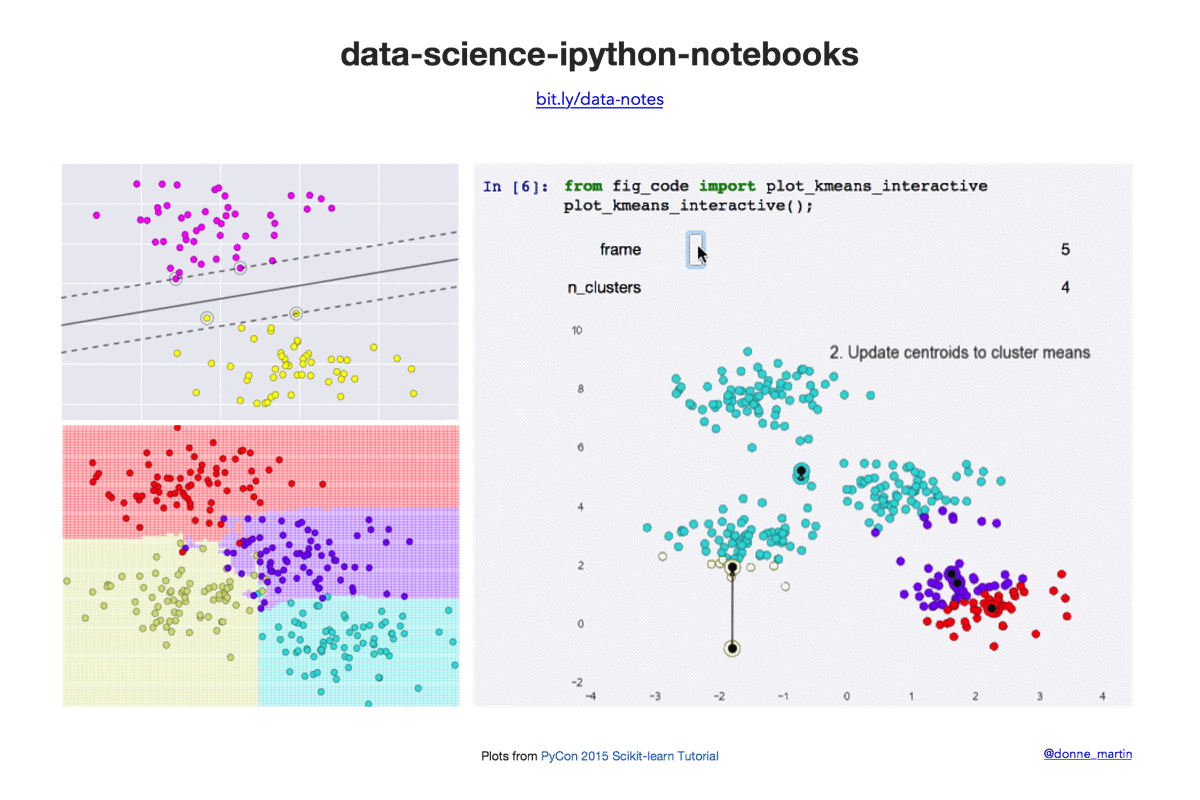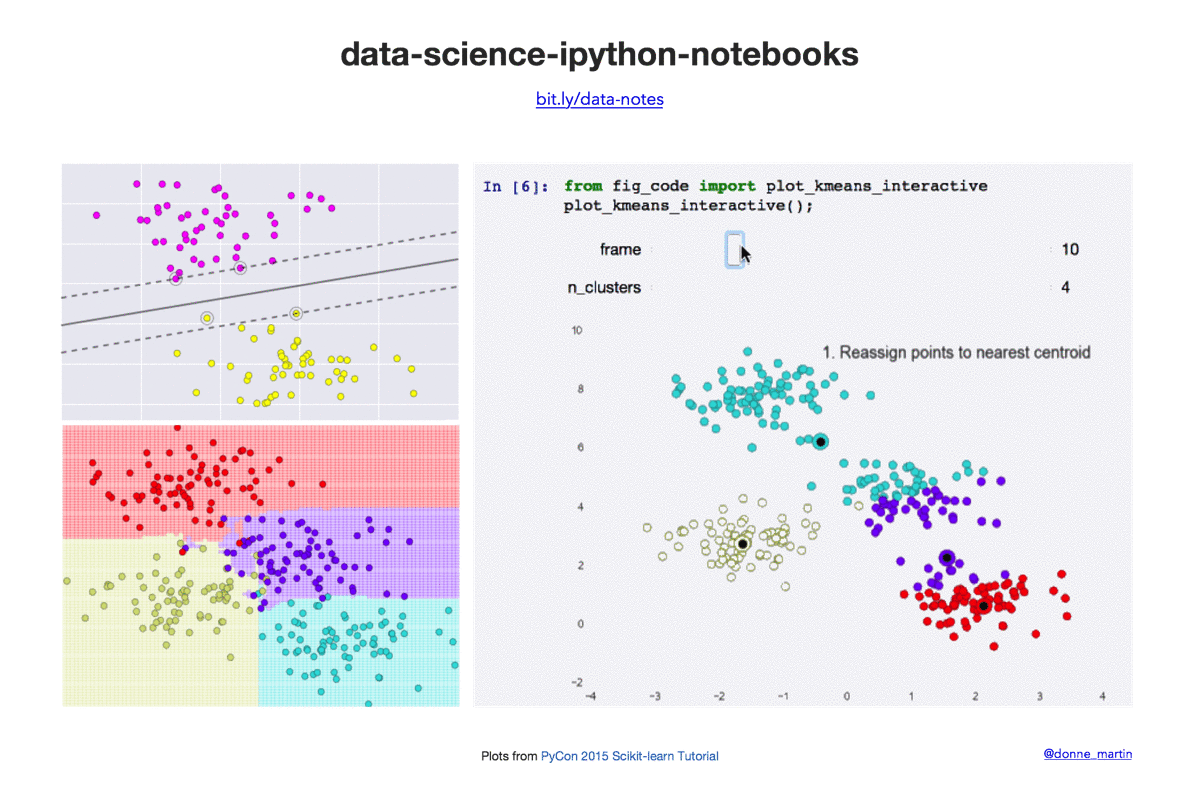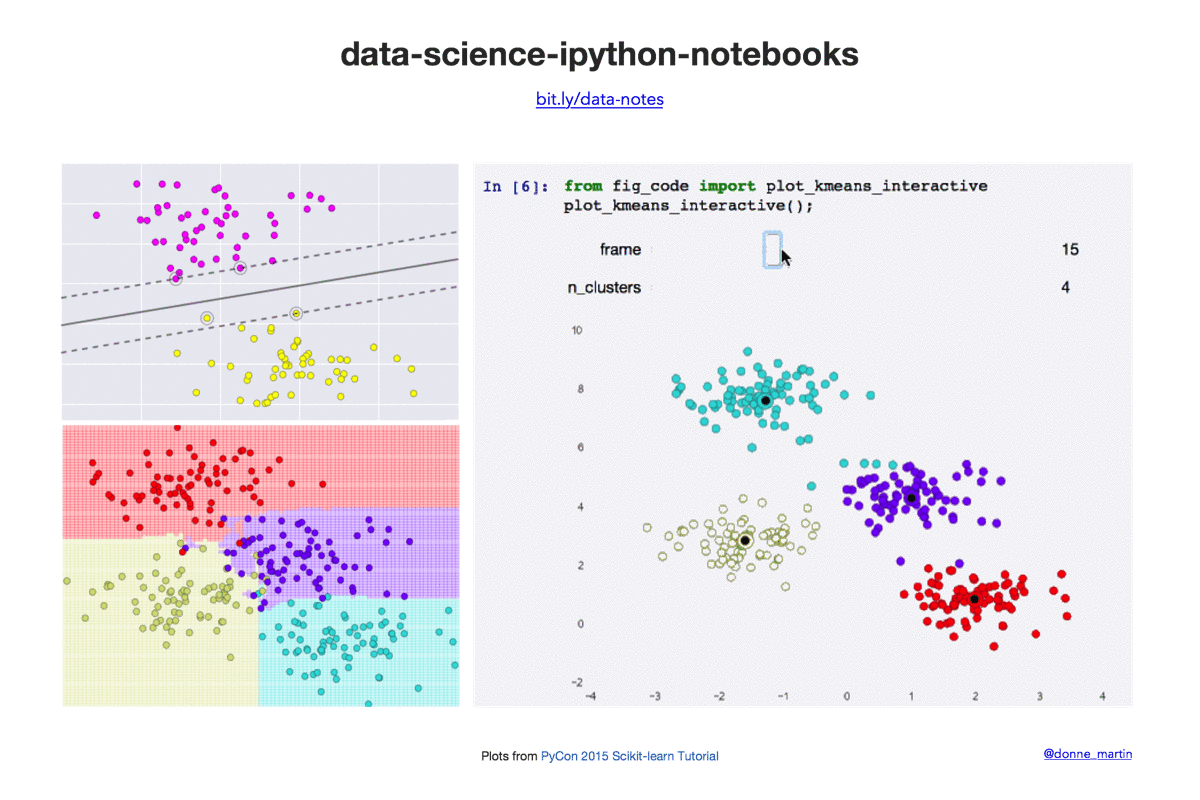
A large curated collection of IPython/Jupyter notebooks covering the Python data science stack: deep learning (TensorFlow, Theano, Caffe, Keras), scikit-learn, statistics with SciPy, pandas, matplotlib, NumPy, Kaggle competition analyses, big data (Spark, Hadoop MapReduce, HDFS), AWS, and command-line essentials.
- 18.9K
 #3 · dianping/cat
cat
CAT is an open-source real-time application monitoring platform (APM) written in Java at Meituan-Dianping. It collects performance metrics, health status and alerts from your services and turns them into live reports.
- 4

luigi
18.8Kspotify/luigi · PythonLuigi is a Python package for building complex pipelines of batch jobs. It handles dependency resolution, workflow management, visualization, failure handling and command line integration.
- 5

APIJSON
18.4KAPIJSON/APIJSON · JavaAPIJSON is a JSON-based communication protocol and ORM library that auto-provides CRUD APIs and documentation with no backend coding, while clients define exactly what JSON data and structure they get back.
- 6
DataX
17.4Kalibaba/DataX · JavaDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
- 7
BigData-Notes
17Kheibaiying/BigData-Notes · JavaThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
- 8

presto
16.8Kprestodb/presto · JavaPresto is a distributed SQL query engine for running interactive analytic queries against big data sources.
- 9
hadoop
15.7Kapache/hadoop · JavaApache Hadoop is the open-source big data platform for reliable, distributed storage and processing of very large data sets across clusters of machines.
- 10
deeplearning4j
14.3Kdeeplearning4j/deeplearning4j · JavaEclipse Deeplearning4J is a suite of JVM libraries for building, training and deploying deep learning applications, usable from Java, Scala, Kotlin and Clojure.
- 11
fluentd
13.6Kfluent/fluentd · RubyFluentd is an open-source log collector that sits at the center of your logging setup: it gathers events from many data sources and writes them to files, RDBMS, NoSQL, IaaS, SaaS, Hadoop and more.
- 12
trino
13.3Ktrinodb/trino · JavaTrino is a fast distributed SQL query engine for big data analytics — you run it as a server (or cluster) and query large datasets with standard SQL. It was formerly known as PrestoSQL.
- 13
predictionio
12.5Kapache/predictionio · ScalaApache PredictionIO is an open source machine learning server that lets developers and data scientists collect events, deploy algorithms, evaluate them, and query predictive results through REST APIs.
- 14
God-Of-BigData
10.6Kwangzhiwubigdata/God-Of-BigDataA curated Chinese-language knowledge base for learning big data engineering and passing big data interviews, covering Java fundamentals, distributed systems theory, and deep dives into Hadoop, Hive, Spark, Flink, HBase, Kafka, and Zookeeper.
Related topics
Often tagged together