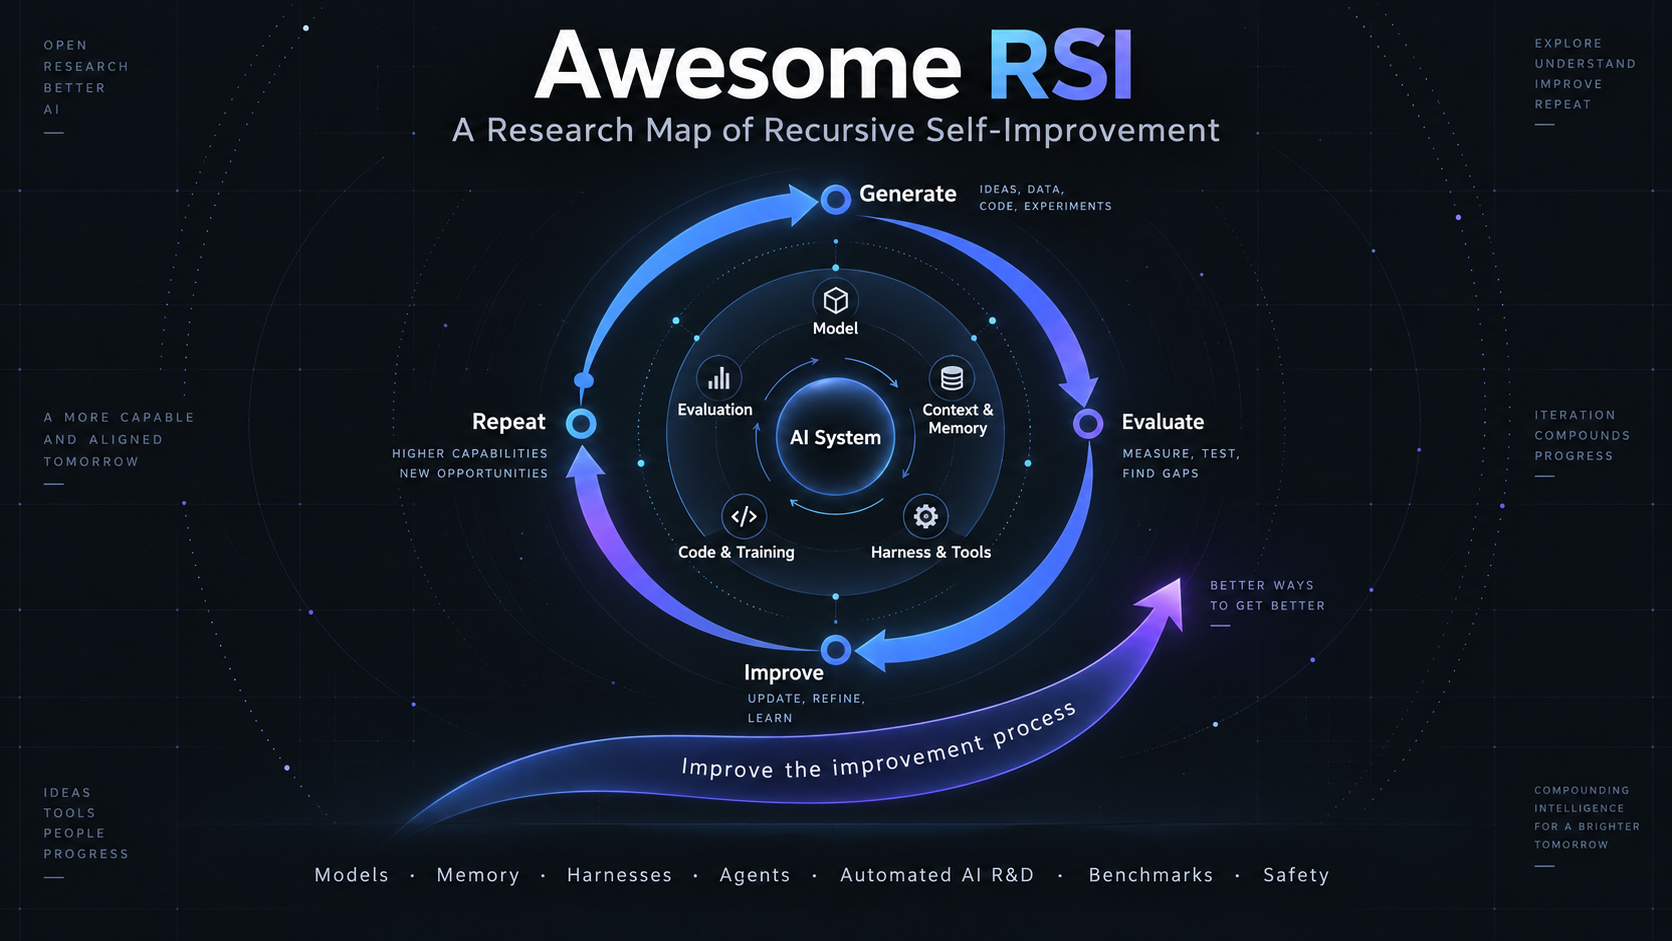
Awesome RSI (Recursive Self-Improvement) 
Recursive Self-Improvement (RSI) refers to processes in which AI systems improve their own capabilities and can also improve the mechanisms that generate subsequent improvements.
Recent progress in self-training, agent memory, harness optimization, embodied self-improvement, automated AI research, self-modifying coding agents, and evolutionary search has made RSI increasingly relevant as an empirical research direction rather than only a theoretical idea.
Awesome RSI collects and organizes important work across these areas, including model-level self-improvement, context and memory evolution, harness and scaffold evolution, embodied and physical self-improvement, multi-agent systems, automated AI research, benchmarks, and safety.
Not every work listed here demonstrates RSI in the strict sense. Some represent bounded self-improvement or enabling techniques that may contribute to more complete recursive systems.
If you are new to the topic, start with Fundamentals & Getting Started. If you already know the basics, explore the sections most relevant to your interests.
This is a community-maintained and evolving list. Contributions, missing papers, new benchmarks, frameworks, and suggestions for improving the taxonomy are very welcome.
The taxonomy is organizational rather than mutually exclusive; many systems span multiple layers and mechanisms.
Contents
Scope & Terminology
For this list, we use the following operational distinctions:
Self-refinement — improves the current output without a persistent change to the system.
Persistent self-improvement — changes to weights, memory, skills, prompts, harness, or code that carry into the next round.
Recursive self-improvement — the mechanism that produces improvements is itself the object of improvement.
RSI substrate — exposes an agent's own structure as a modifiable object, but does not necessarily form an automatic self-improvement loop by default.
Fundamentals & Getting Started
Foundational papers, formal treatments, and surveys that establish the vocabulary and core questions of RSI.
- A Survey of Self-Evolving Agents: On Path to Artificial Super Intelligence - Surveys what, when, and how foundation-model agents can evolve across models, memory, tools, and architectures. (TMLR 2026)
- Generalized Agent Iteration: One Formal Framework for Iterative Policy Improvement and Recursive Self-Improvement - Places iterative policy improvement and recursive self-improvement on one pair of axes, separating them by whether the improving mechanism is part of the agent and whether the evaluation standard is grounded outside it. (arXiv 2026)
- Recursive Self-Improvement in AI: From Bounded Self-Refinement to Autonomous Research Loops - Surveys recent self-improvement work by update target and loop closure while separating bounded refinement from open-ended RSI. (arXiv 2026)
- Self-evolving Embodied AI - Defines the self-evolving embodied AI paradigm across memory self-updating, task self-switching, environment self-prediction, embodiment self-adaptation, and model self-evolution, and systematically reviews work on each component. (arXiv 2026)
- Self-Improvements in Modern Agentic Systems: A Survey - Unifies self-improving agents through a system-level view of foundation-model and scaffold updates. (arXiv 2026)
- A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems - Organizes agent evolution around feedback loops, update targets, domain applications, evaluation, and safety. (arXiv 2025)
- A Survey on Self-Evolution of Large Language Models - Presents a four-stage taxonomy of experience acquisition, refinement, updating, and evaluation for self-evolving LLMs. (arXiv 2024)
- A Formulation of Recursive Self-Improvement and Its Possible Efficiency - Gives a formal definition of a restricted RSI system and analyzes when efficient recursive improvement is computable. (arXiv 2018)
- From Seed AI to Technological Singularity via Recursively Self-Improving Software - Defines RSI software, surveys prior approaches, and proposes convergence concepts and computational limits. (arXiv 2015)
- The Singularity: A Philosophical Analysis - Develops a rigorous philosophical case for an intelligence explosion and examines its assumptions and consequences. (Journal of Consciousness Studies 2010)
- Gödel Machines: Self-Referential Universal Problem Solvers Making Provably Optimal Self-Improvements - Defines a fully self-referential machine that rewrites itself after proving a modification improves expected utility. (Artificial General Intelligence book 2006)
- Optimal Ordered Problem Solver - Introduces an asymptotically optimal program-search system that reuses solutions to accelerate later problem solving. (Machine Learning 2004)
- Evolutionary Principles in Self-Referential Learning, or on Learning How to Learn: The Meta-Meta-... Hook - Describes early meta-evolution and self-referential learning mechanisms that recursively improve learning methods. (Diploma thesis 1987)
- Speculations Concerning the First Ultraintelligent Machine - Introduces the intelligence-explosion argument in which a machine capable of improving machine design triggers accelerating capability gains. (Advances in Computers 1965)
Model-level RSI
Methods that improve model weights or training behavior through self-generated feedback, data, or reasoning, including canonical enabling methods later reused in persistent self-improvement loops.
Self-Training & Self-Reward
Synthetic Data & Self-Distillation
Self-Play & Iterative Fine-tuning
Self-Taught Reasoning
Harness-level RSI
Methods that improve prompts, memory, verification, tools, or agent policies around a model.
Prompt & Program Optimization
Context & Memory Evolution
- Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models - Evolves context as a structured playbook through generation, reflection, and curation while avoiding destructive context collapse. (ICLR 2026)
- AnchorGUI: Asymmetric Memory for Dual-Scale Learning in GUI Navigation - Turns unexpected GUI outcomes into visual evidence for immediate correction and reusable strategies that help agents avoid repeating mistakes across attempts. (ECCV 2026)
- EvolveR: Self-Evolving LLM Agents through an Experience-Driven Lifecycle - Distills interaction trajectories into reusable strategic principles, retrieves them during future tasks, and reinforces the agent policy in a closed experience loop. (ICML 2026)
- From Procedural Skills to Strategy Genes: Towards Experience-Driven Test-Time Evolution - Compares experience representations across 4,590 controlled trials and finds that compact, editable Genes provide stronger test-time control and carry accumulated failure history better than documentation-oriented Skill packages. (arXiv 2026)
- Learning to Continually Learn via Meta-learning Agentic Memory Designs - Uses a meta-agent to discover executable memory schemas and retrieval and update mechanisms that continually improve from experience. (arXiv 2026)
- Meta Context Engineering via Agentic Skill Evolution - A bi-level framework that co-evolves context-engineering skills and context artifacts, replacing static context-engineering heuristics with agentic skill evolution. (ICML 2026)
- RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments - Coordinates curriculum, actor, and verifier agents to explore an unfamiliar environment and freezes reusable causal knowledge in memory, improving open-source models on OSWorld-v2 and Agent's Last Exam without parameter updates. (arXiv 2026)
- A-MEM: Agentic Memory for LLM Agents - Builds a dynamically linked note network whose organization evolves as an agent accumulates new experiences. (NeurIPS 2025)
- ExpeL: LLM Agents Are Experiential Learners - Extracts reusable insights from successful and failed trajectories and transfers them to future tasks without weight updates. (AAAI 2024)
- MemoryBank: Enhancing Large Language Models with Long-Term Memory - Maintains and selectively forgets long-term interaction memories so an agent can adapt its responses over time. (AAAI 2024)
- Reflexion: Language Agents with Verbal Reinforcement Learning - Improves agents across trials by storing natural-language reflections derived from task feedback. (NeurIPS 2023)
Harness & Scaffold Evolution
- Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses - Autonomously evolves tools, middleware, memory, and prompts through observable edits whose predictions are verified on later tasks. (arXiv 2026)
- AI4AI at Test-Time: Strong-to-Weak Capability Transfer via Harnesses - Uses stronger builder models to iteratively construct inference-time harnesses that transfer capability to weaker target models without parameter updates. (arXiv 2026)
- AutoHarness: Improving LLM Agents by Automatically Synthesizing a Code Harness - Synthesizes and iteratively refines executable harnesses from environment feedback, eliminating illegal actions across 145 TextArena games. (arXiv 2026)
- AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation - AutoRef iteratively optimizes the agent harness around frozen image generators for multi-reference generation tasks, including prompting, diverse drafting, failure diagnosis, revision, and selection. (arXiv 2026)
- Continual Harness: Online Adaptation for Self-Improving Foundation Agents - Refines prompts, sub-agents, skills, and memory online within a single continuous trajectory and extends the loop to model-weight co-learning. (arXiv 2026)
- EvoHarness-RL: Learning Self-Evolving Runtime Harness for Long-Horizon LLM Agents - Trains agents to construct and coordinate evolving Belief, Progress, and Experience state during long-horizon execution. (COLM 2026 LLA Workshop)
- Harness-Zero: Harness Distillation via Agent-as-Harness - Distills optimized harness behaviors into model weights through an agent-as-harness training loop, retaining harness-level gains at deployment without the harness at inference time. (arXiv 2026)
- MemoHarness: Agent Harnesses That Learn from Experience - Learns case-adaptive configurations across six harness control dimensions from execution diagnoses and a reusable experience bank. (arXiv 2026)
- MetaSkill-Evolve: Recursive Self-Improvement of LLM Agents via Two-Timescale Meta-Skill Evolution - Evolves task skills in a fast loop and the meta-skills governing its Analyzer, Retriever, Allocator, Proposer, and Evolver in a slower recursive loop. (arXiv 2026)
- ModularRSI: Modular and Generalizable Recursive Harness Self-Improvement - Splits the harness into five modules that evolve independently against 2,000 evolution tasks disjoint from the evaluation benchmarks, and contrasts same-task success and failure to localize which module is at fault. (arXiv 2026)
- RRSI: Regularized Recursive Self-Improvement of Agent Harnesses - Constrains the proposer with a temporally annealed edit budget and screens benchmark-specific proposals with a critic and pruner, so harness self-improvement keeps its out-of-distribution gains instead of memorizing the tasks it evolved on. (arXiv 2026)
- SkillOpt: Executive Strategy for Self-Evolving Agent Skills - Trains a single skill document as the external state of a frozen agent, with a separate optimizer model proposing bounded edits accepted only on strict held-out validation gains. (arXiv 2026)
- SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness - Scales harness self-improvement across many environments for rollouts and keeps the four mechanisms that survive selection, spanning action execution, context compaction, observation handling, and delegated reading, cutting recorded token traffic by 44.7-49.0% on EdgeBench. (arXiv 2026)
Extensible Harness Substrates
Extensible agent runtimes that expose prompts, tools, skills, memory, plugins, or control flow as modifiable surfaces. These systems do not necessarily implement self-improvement by default, but can serve as substrates for RSI experiments.
General extensibility alone is insufficient. An RSI substrate should expose agent-relevant runtime components such as prompts, memory, skills, tools, or control flow as programmatically modifiable surfaces suitable for persistent self-modification experiments.
- Agent Zero - Open agentic framework whose prompts, tools, skills, plugins, and multi-agent profiles can be inspected, replaced, and extended.
- DeepSeek Harness - Open-source agent harness from DeepSeek AI built around an everything-is-a-plugin architecture.
- OpenClaw - Persistent agent runtime with workspace-scoped skills and a Skill Workshop where agents can draft reusable skill changes for review and application.
- Pi - Self-extensible coding-agent harness with a reusable agent runtime, terminal UI, and unified multi-provider LLM API.
Self-Verification & Self-Correction — Enabling Foundations
Primarily bounded self-refinement and verification methods that serve as building blocks for persistent self-improving systems.
Self-Evolving Agent Frameworks
- AgentFactory: A Self-Evolving Framework Through Executable Subagent Accumulation and Reuse - Preserves successful solutions as executable subagents and continually refines them from execution feedback for reuse on future tasks. (ACL 2026 System Demonstrations)
- EvoAgent: An Evolvable Agent Framework with Skill Learning and Multi-Agent Delegation - Accumulates structured skills through a feedback loop and delegates complex tasks through a hierarchy of sub-agents. (arXiv 2026)
- Hyperagents - Combines a task agent with an editable meta-agent whose self-modification procedure can itself evolve and transfer improvements across domains. (arXiv 2026)
- SIA: Self Improving AI with Harness & Weight Updates - Uses task feedback to update both an agent's harness and its model weights within one self-improving loop. (arXiv 2026)
- SkillRise: Agentic Reinforcement Learning for Cross-Task Skill Evolution - Alternates a single policy between solving tasks and curating a persistent, evolving skill document that later tasks inherit. (arXiv 2026)
- Alita-G: Self-Evolving Generative Agent for Agent Generation - Generates, abstracts, and curates reusable MCP tools from successful trajectories to turn a generalist agent into a domain specialist. (arXiv 2025)
- EvoAgentX: An Automated Framework for Evolving Agentic Workflows - Unifies workflow generation, execution, evaluation, and evolutionary optimization across agent prompts, tools, and topologies. (arXiv 2025)
- Gödel Agent: A Self-Referential Agent Framework for Recursive Self-Improvement - Lets an agent inspect and rewrite its own logic without relying on a fixed hand-designed optimization routine. (ACL 2025)
- MemEvolve: Meta-Evolution of Agent Memory Systems - Jointly evolves experiential knowledge and the architecture that encodes, stores, retrieves, and manages agent memory. (arXiv 2025)
- Self-evolving Agents with Reflective and Memory-Augmented Abilities - Combines iterative feedback, reflection, and forgetting-aware memory optimization for continual agent adaptation. (Neurocomputing 2025)
- Agent-Pro: Learning to Evolve via Policy-Level Reflection and Optimization - Refines an agent's beliefs and behavioral policy from interactive experience using reflection and search. (ACL 2024)
- Voyager: An Open-Ended Embodied Agent with Large Language Models - Builds an expanding skill library and uses environmental feedback for lifelong autonomous learning in Minecraft. (TMLR 2024)
Multi-Agent Self-Improvement
Systems that use interaction among multiple agents to improve reasoning, policies, or agent populations.
Co-Evolution
Inference-time Debate
Primarily current-run improvement via multi-agent debate, without persistent system change.
Coding / Software-Engineering Self-Improvement
Agents and training loops that improve code, software-engineering performance, or their own implementations.
Self-Modifying Coding Agents
Iterative Repair & Training
Mixes current-run repair loops with methods whose learned improvements persist into later iterations.
Automated AI R&D
Systems that automate parts of AI research and development, including experimentation, post-training, algorithm discovery, and the improvement of other AI systems.
- AutoResearch: Insight In, Hallucination Out - Connects grounded idea generation with coordinated execution agents that implement, diagnose, and independently review experiments before accepting research conclusions. (arXiv 2026)
- Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering - Connects execution-grounded operator training with long-horizon evolution in the open OpenMLE stack, using machine-learning engineering as an AI4AI testbed for RSI. (arXiv 2026)
- FT-Dojo: Towards Autonomous LLM Fine-Tuning with Language Agents - Turns data collection, training, evaluation, diagnosis, and strategy revision into an executable environment for autonomous fine-tuning agents. (arXiv 2026)
- LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling - Lets an LLM agent discover test-time scaling controllers for other LLMs inside a cheap execution-trace environment, with discovered strategies transferring across benchmarks and model scales. (arXiv 2026)
- MLEvolve: A Self-Evolving Framework for Automated Machine Learning Algorithm Discovery - Combines progressive graph search, retrospective memory, and hierarchical code generation for long-horizon end-to-end machine-learning algorithm discovery. (arXiv 2026)
- Recursive self-improvement of AI research agents - Makes a research agent's own code the object of optimization, so each accepted rewrite becomes the agent the next round edits, demonstrated in an eight-day autonomous run whose seven successive improvements transfer to four held-out benchmarks. (arXiv 2026)
- ScienceBuddy: Recursive-in-Recursive Self-Improvement for Interactive Scientific Agents - Couples an inner loop that evolves the harness with the model fixed to an outer loop that trains the model under the improved harness, so harness evolution shapes training experience and model learning creates new harness opportunities. (arXiv 2026)
- Towards End-to-End Automation of AI Research (The AI Scientist-v2) - Uses template-free agentic tree search to propose hypotheses, run experiments, analyze results, and write complete research papers. (Nature 2026)
- Towards Execution-Grounded Automated AI Research - Converts LLM pre-training and post-training into executable research environments where evolutionary search learns from experimental outcomes. (arXiv 2026)
- The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery - Automates idea generation, experimentation, paper writing, and review to create a reusable loop for machine-learning research. (arXiv 2024)
Embodied & Physical Self-Improvement
Systems that use interaction with physical or simulated environments to generate persistent improvements in robot policies, skills, harnesses, world models, or the research process around them.
- ASPIRE: Agentic /Skills Discovery for Robotics - Diagnoses failures from robot execution traces, edits code-as-policy, and stores validated repairs in a skill library for persistent reuse across tasks and embodiments at NVIDIA GEAR. (arXiv 2026)
- ENPIRE: Agentic Robot Policy Self-Improvement in the Real World - Uses a coding agent from NVIDIA GEAR, CMU, and UC Berkeley to run a real-robot autoresearch loop that resets, rolls out, verifies, edits policy, training-infrastructure, or algorithm code, and reruns, with scaling to robot fleets. (arXiv 2026)
- MineEvolve: Self-Evolution with Accumulated Knowledge for Long-Horizon Embodied Minecraft Agents - Converts successful experience into reusable skills and failures into executable guardrails that continually guide an LLM planner without model-parameter updates. (arXiv 2026)
- RISE: Self-Improving Robot Policy with Compositional World Model - Continuously generates imagined rollouts with a compositional world model, estimates their advantages, and updates the robot policy, with training code and pretrained dynamics models released. (RSS 2026)
- Self-Evolving Embodied Agents via Skill-Harness Evolution - Keeps model weights frozen while the same model acts as planner and optimizer, using environment rollouts to continually evolve reusable skills and a context-code harness. (arXiv 2026)
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL - Uses residual reinforcement learning to target VLA failure regions and generate recovery trajectories that are distilled back into a generalist policy, forming a data-to-policy self-improvement flywheel. (ICLR 2026)
Evolutionary & Open-Ended RSI
Evolutionary, quality-diversity, and open-ended processes that continually discover stronger solutions or learning systems.
- EnvHarness: Awakening Static Worlds for Agent Learning - Wraps static environments in programmable plug-in components synthesized from an agent's own failure trajectories, enabling continued co-evolution of the policy and its training environments. (arXiv 2026)
- PACEvolve: Enabling Long-Horizon Progress-Aware Consistent Evolution - Combines hierarchical context management, backtracking, and adaptive sampling to sustain collaborative long-horizon evolutionary search. (arXiv 2026)
- The Red Queen Gödel Machine: Co-Evolving Agents and Their Evaluators - Makes the evaluation criterion part of the search loop, holding it fixed within epochs while the utility is revised at epoch boundaries, and corrects reviewer over-acceptance of AI work with a co-evolved adversarial objective. (arXiv 2026)
- AlphaEvolve: A Coding Agent for Scientific and Algorithmic Discovery - Combines language-model code generation, automated evaluation, and evolutionary search to improve algorithms, including components used in AI training. (arXiv 2025)
- Higher Order and Self-Referential Evolution for Population-based Methods - Evolves mutation rates and higher-order meta-mutation rates, including a self-referential top-level parameter that modifies itself. (ICML 2024 AutoRL Workshop)
- Mathematical Discoveries from Program Search with Large Language Models - Introduces FunSearch, an evolutionary loop that pairs a frozen code model with evaluators to discover new programs and mathematical results. (Nature 2024)
- AutoML-Zero: Evolving Machine Learning Algorithms From Scratch - Evolves complete learning algorithms from elementary mathematical operations with minimal human design bias. (ICML 2020)
- AI-GAs: AI-Generating Algorithms, an Alternate Paradigm for Producing General Artificial Intelligence - Proposes open-ended systems that automatically generate environments, architectures, and learning algorithms. (arXiv 2019)
- Paired Open-Ended Trailblazer (POET): Endlessly Generating Increasingly Complex and Diverse Learning Environments and Their Solutions - Co-evolves environments and agents while transferring solutions between emerging challenges. (GECCO 2019)
- Learning to Learn by Gradient Descent by Gradient Descent - Meta-learns an optimizer whose recurrent update rule can replace a hand-designed optimization algorithm. (NeurIPS 2016)
- Quality Diversity: A New Frontier for Evolutionary Computation - Formalizes search for collections that are simultaneously diverse and high-performing within their niches. (Frontiers in Robotics and AI 2016)
- Illuminating Search Spaces by Mapping Elites - Introduces MAP-Elites for discovering a diverse archive of locally high-quality solutions. (arXiv 2015)
- POWERPLAY: Training an Increasingly General Problem Solver by Continually Searching for the Simplest Still Unsolvable Problem - Alternates between inventing new tasks and modifying a solver so its verified skill set continually expands. (Frontiers in Psychology 2013)
Safety, Alignment & Theory
Safety, stability, goal preservation, corrigibility, and oversight mechanisms for systems that modify or improve themselves over time.
- The Economics of Recursive Self-Improvement - Models the AI capability to AI R&D to stronger capability feedback path as an elasticity network and derives conditions for self-sustaining acceleration. (Elasticity Institute 2026)
- Evolutionary Safety of Recursive Self-Improving AI: Taxonomy, Risk Discovery, and Evaluation - Frames safety under persistent and recursive self-improvement as a property that changes, accumulates, and propagates across evolution, characterizes recurring failure modes from intent drift to evaluator drift, and derives governance principles for modification, selection, authorization, provenance, and recovery. (arXiv 2026)
- SAHOO: Safeguarded Alignment for High-Order Optimization Objectives in Recursive Self-Improvement - Monitors alignment drift during recursive self-improvement through goal-drift detection, constraint-preservation checks, and regression-risk analysis. (ICLR 2026 RSI Workshop)
- SEABench: Benchmarking Endogenous Misalignment In Self-Evolving Agents - Uses paired evolving and non-evolving agents to attribute downstream safety failures to earlier self-updates, finding failures on 43.9% of discovered sequences where the unevolved baselines fail none. (arXiv 2026)
- TamperBench: Systematically Stress-Testing LLM Safety Under Fine-Tuning and Tampering - Systematically stress-tests whether safety alignment is preserved under fine-tuning, weight-space modification, and representation tampering. (arXiv 2026)
- Your Agent May Misevolve: Emergent Risks in Self-evolving LLM Agents - Studies harmful drift across model, memory, tool, and workflow evolution pathways and proposes the concept of misevolution. (ICLR 2026)
- Escaping Model Collapse via Synthetic Data Verification: Near-term Improvements and Long-term Convergence - Studies when iterative training on self-generated data collapses and shows how external verification can stabilize self-improvement while exposing long-run limits. (arXiv 2025)
- Evaluating Goal Drift in Language Model Agents - Measures whether long-horizon agents gradually deviate from their assigned objectives under competing environmental pressures. (arXiv 2025)
- Performance of Bounded-Rational Agents With the Ability to Self-Modify - Shows that self-modification can amplify errors and gradually misalign bounded-rational agents even when ideal rational agents would preserve their objectives. (AAAI 2021 SafeAI Workshop)
- AGI Agent Safety by Iteratively Improving the Utility Function - Designs a safety mechanism that allows an agent's utility function to be iteratively updated while reducing incentives to manipulate the improvement process. (AGI 2020)
- Scalable Agent Alignment via Reward Modeling: A Research Direction - Outlines recursive reward modeling for supervising agents on tasks too complex for direct human evaluation. (arXiv 2018)
- Self-Modification of Policy and Utility Function in Rational Agents - Formalizes when rational agents preserve or modify their policies and utility functions and derives conditions under which self-modification remains goal-preserving. (AGI 2016)
- Intelligence Explosion Microeconomics - Models the returns and bottlenecks that determine whether recursive improvement accelerates, plateaus, or becomes explosive. (MIRI technical report 2013)
Supporting Safety Foundations
Introspection & Self-Modeling
Research on whether AI systems can model, diagnose, predict, and reason about their own behavior and internal states, capabilities that may support effective self-improvement.
Benchmarks & Evaluations
Benchmarks are separated into direct self-improvement evaluations, frontier-lab evaluation frameworks, and capability proxies. Proxy benchmarks are included only when they measure a bottleneck that directly constrains persistent or recursive self-improvement.
Direct RSI & Self-Improvement Evaluations
- LongWoF-Bench: Evaluating EvoMap Genes for Verifiable Long-Workflow Tasks - Provides 778 machine-verifiable long-workflow tasks and shows that Genes consolidated from verifier-confirmed trajectories outperform Skill packages across seven models, linking the gains to verified experience provenance. (arXiv 2026)
- PostTrainBench: Can LLM Agents Automate LLM Post-Training? - Gives autonomous agents one base model, one H100 GPU, and ten hours to research and execute the strongest post-training strategy they can find. (ICML 2026)
- RSI-Bench - Provides an open-source six-axis framework for measuring self-modification depth, improvement trajectories, operator discovery, adaptation, safety, and goal generation. (community framework 2026)
- RSIBench-Data - Isolates data-centric RSI by asking agents to iteratively improve training-data strategies against checkpoint feedback under a fixed post-training stack. (arXiv 2026)
Frontier Lab Self-Improvement & AI R&D Evaluation Frameworks
- Anthropic Autonomous AI R&D Evaluations - Defines the Responsible Scaling Policy AI R&D-4 capability threshold as fully automating the work of an entry-level, remote-only researcher and evaluates models and safeguards against it. (Anthropic Model Report 2026)
- Google DeepMind Frontier Safety Framework (FSF) ML R&D - Uses dedicated CCLs, TCLs, and evaluation protocols for Machine Learning R&D capabilities that could significantly accelerate or automate AI research and development. (Google DeepMind Blog 2026)
- OpenAI AI Self-Improvement Evaluations - Tracks AI Self-Improvement capability under the Preparedness Framework using Internal Research Debugging, KernelGen 1P, NanoGPT, PostTrainBench Lite, MLE-Bench Revised, and related evaluations aggregated into an RSI Index. (OpenAI System Card 2026)
AI R&D Capability Proxies
Agent Capability Proxies
- ARC-AGI-3: A New Challenge for Frontier Agentic Intelligence - Requires agents to explore unfamiliar interactive environments, infer goals, model environment dynamics, remember, and plan, measuring adaptive interaction and generalization bottlenecks for self-improvement. (arXiv 2026)
- Long-Horizon-Terminal-Bench - Evaluates agents on 46 terminal tasks requiring sustained execution across hundreds of episodes with dense intermediate rewards. (arXiv 2026)
- OSWorld 2.0 - Measures computer-use agents on 108 realistic end-to-end workflows whose median human completion time is about 1.6 hours. (arXiv 2026)
- MCPMark - Stress-tests realistic stateful MCP workflows across SaaS, development, browser, filesystem, and database environments with programmatic grading. (arXiv 2025)
- METR Task-Completion Time Horizon - Estimates the human-equivalent task duration at which an agent succeeds with a given probability on non-trivially parallelizable software tasks. (NeurIPS 2025)
- SWE-Bench Pro - Tests coding agents on 1,865 contamination-resistant enterprise tasks designed to require hours or days of professional software engineering. (arXiv 2025)
- TheAgentCompany - Evaluates agents on 175 cross-application workplace tasks inside a simulated software company with result and checkpoint grading. (NeurIPS 2025)
- SWE-bench - Provides reproducible real-world software issues used to evaluate coding agents and empirical self-modification systems such as DGM. (ICLR 2024)
- SWE-bench Verified - Supplies a human-validated subset that reduces broken or underspecified tasks when measuring iterative coding-agent improvements. (OpenAI benchmark 2024)
Self-Modifying / Self-Evolving Systems
- AgentFactory - Self-evolving framework that accumulates and reuses executable subagents to improve future task solving.
- Darwin Gödel Machine - Official self-modifying coding-agent implementation with open-ended archive-based evolution.
- Gödel Agent - Official implementation of Gödel Agent: A Self-Referential Agent Framework for Recursive Self-Improvement.
- Hermes Agent - Self-improving personal agent with a built-in learning loop that creates and refines skills from experience.
- HyperAgents - Self-referential agent framework in which an editable meta-agent improves itself and the task agent for computable objectives.
- SEAL - Official code for language models that generate their own adaptation data and update instructions.
- SIA - Self-improving AI framework that iteratively updates an agent harness and, when configured, the target model's weights.
Harness / Memory / Skill Evolution
- ACE - Official implementation of Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models.
- ALMA - Official implementation of Learning to Continually Learn via Meta-learning Agentic Memory Designs.
- Continual Harness - Self-improving agent harness that adapts online from experience while maintaining a continuous environment trajectory.
- EvoAgentX - Self-evolving agent framework for automatically building, evaluating, and optimizing agentic workflows.
- EvolveR - Self-evolving LLM-agent framework that improves through a closed-loop, experience-driven lifecycle.
- Gear - Uses execution traces and benchmark feedback to iteratively optimize agent prompts, tools, and workflows, retaining versioned harness candidates for later rounds.
- harness-zero - Official implementation of Harness-Zero: Harness Distillation via Agent-as-Harness.
- Letta Code - Memory-first coding-agent harness whose long-lived agents rewrite context and learn skills from experience.
- Memento-Skills - Self-evolving agent framework that retrieves, evaluates, repairs, and rewrites persistent skills through reflective learning.
- meta-context-engineering - Official implementation of Meta Context Engineering via Agentic Skill Evolution.
- Mnemoverse Memory - MCP server for a hosted persistent-memory engine that re-ranks an agent's recall from reported outcomes, so what helped or misled on one task changes what is returned on later ones.
- Raven - Multi-agent harness built for recursive self-improvement that splits its agent loop into Memory, Planning, Capability, and Action strategy modules, which an experimental Curator rewrites per agent and installs only after verification.
- Reef - Continual-learning serving infrastructure that records agent interactions, turns matched feedback into model-weight or harness updates, and publishes accepted updates as versioned artifacts.
- ReMe - Local-first agent memory system that consolidates conversations and resources into persistent, evolving Markdown knowledge for reuse across agents.
- Voyager - Embodied lifelong-learning agent with automatic curriculum, iterative prompting, and a reusable skill library.
Automated Search / AI R&D
- ADAS - Official implementation of a meta-agent that searches over executable agent designs.
- AI Scientist - End-to-end system for generating machine-learning ideas, running experiments, and writing research papers.
- autoresearch - Runs an autonomous loop that edits an LLM training program, trains for five minutes, and keeps only changes that improve validation bits per byte.
- Evolutionary Model Merge - Evolves combinations of open models in parameter and data-flow space.
- FunSearch - Reference implementation of LLM-guided evolutionary program search with executable evaluators.
- MLEvolve - Self-evolving multi-agent framework for end-to-end machine-learning algorithm discovery using progressive search and experience-driven memory.
- OpenEvolve - Open-source evolutionary coding agent inspired by AlphaEvolve-style program optimization.
- POET - Reference implementation for co-evolving environments and their paired agents.
Blog Posts & Discussions
- A Taxonomy of Self-Evolving Agents - Distinguishes Model, Harness, and Artifact evolution, complementing this list's own taxonomy. (2026)
- Hyra: A simple yet effective scaffold for general discovery - Tencent Hunyuan report on Hyra-1.0, a recursively self-improving agent for performance-oriented research and engineering tasks, with produced research artifacts open-sourced in a companion repository. (2026)
- AI4AI at Scale: Building Open-Weight Deep Search Agents - Industry technical report on a bounded, verification-gated AI-for-AI loop where agent teams diagnose failures and apply scoped changes across data, post-training, runtime, and infrastructure, with accepted and rejected attempts banked as auditable experience. (2026)
- First Steps Toward Automated AI Research - Describes an automated research system that closes the full loop from idea proposal through implementation, experiments, validation, and selection of the next experiment, with three reported SOTA results and open-sourced artifacts. (2026)
- Harness Engineering for Self-Improvement - Survey of harness engineering as a near-term path to recursive self-improvement, covering harness design patterns, context and workflow optimization, self-improving harnesses, evolutionary search, and joint optimization with model weights. (2026)
- AlphaEvolve: A Gemini-Powered Coding Agent for Designing Advanced Algorithms - Google DeepMind explains AlphaEvolve's evaluator-guided evolution loop and its applications to computing and AI training. (2025)
- The Darwin Gödel Machine: AI That Improves Itself by Rewriting Its Own Code - Sakana AI explains DGM's empirical alternative to proof-based Gödel Machine self-modification. (2025)
- When AI Builds Itself - Anthropic analyzes early evidence, possible paths, and governance challenges for AI-driven AI development. (2025)
- The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery - Sakana AI presents its automated research pipeline, results, limitations, and open implementation. (2024)
- Evidence on Recursive Self-Improvement from Current ML - Reviews empirical evidence for and against strong returns from AI-assisted AI research. (2023)
- FunSearch: Making New Discoveries in Mathematical Sciences Using Large Language Models - Google DeepMind describes how evolutionary program search produced verifiable mathematical and algorithmic discoveries. (2023)
- Metalearning Machines Learn to Learn - Jürgen Schmidhuber traces self-referential meta-learning from 1987 through Gödel Machines and modern learned optimizers. (2020)
- Recursive Self-Improvement - The Alignment Forum overview connects self-improving AI to takeoff dynamics, seed AI, and control concerns. (2016)
Talks & Videos
- Awesome AI Agents - Broad directory of autonomous-agent projects and infrastructure that can serve as components or baselines for self-improving systems. (2023)
- Awesome AutoML Papers - Curated literature on automated model selection, architecture search, hyperparameter optimization, and related techniques. (2018)
- Awesome Self-Improving Agents - Focused bibliography of foundation-model agents that update their models, memory, tools, prompts, or workflows. (2024)
Contributing
Contributions are welcome. Please read the contribution guidelines before submitting a pull request.

 Awesome RSI is a curated research map of Recursive Self-Improvement (RSI): a taxonomy of papers, frameworks, benchmarks, and safety work on AI systems that improve their own capabilities and the mechanisms that generate further improvements.