Topics / #scraping
Scraping projects on GitHub
Web scraping frameworks and crawling techniques
As of , the most-starred Scraping projects on GitHub are firecrawl (192.8K stars), Python-100-Days (187.3K stars) and browser-use (118.4K stars). GitHub.Locker tracks 45 Scraping repositories with 1.3M stars combined. The fastest-growing on October 18 was Agent-Reach, with +409 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +409
Agent-Reach
Panniantong/Agent-Reach · ★ 99.2KAgent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
 +331
firecrawl
firecrawl/firecrawl · ★ 192.8KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +209
Scrapling
D4Vinci/Scrapling · ★ 88.5KScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
browser-use
browser-use/browser-use · ★ 118.4KBrowser Use is an open-source browser agent that lets AI models control a real web browser - navigating sites, filling forms, handling CAPTCHAs, and completing tasks like booking appointments.
The all-time top
45 projects · by stars
- 192.8K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 187.3K
 #2 · jackfrued/Python-100-Days
Python-100-Days
A free, day-by-day Python curriculum by Luo Hao (骆昊) that takes a complete beginner through 100 days of lessons covering core language fundamentals, file and database handling, web development with Django, web scraping, data analysis, and machine learning.
- 118.4K
#3 · browser-use/browser-use
browser-use
Browser Use is an open-source browser agent that lets AI models control a real web browser - navigating sites, filling forms, handling CAPTCHAs, and completing tasks like booking appointments.
- 4
Agent-Reach
99.2KPanniantong/Agent-Reach · PythonAgent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
- 5
Scrapling
88.5KD4Vinci/Scrapling · PythonScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 6
MediaCrawler
67.2KNanmiCoder/MediaCrawler · PythonA multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
- 7

scrapy
64.9Kscrapy/scrapy · PythonScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 8
you-get
56.9Ksoimort/you-get · PythonYou-Get is a tiny command-line utility that downloads media contents — videos, audios and images — from the web, for when there is no other handy way to save them.
- 9
maigret
39.2Ksoxoj/maigret · PythonMaigret is an OSINT command-line tool that builds a dossier on a person by checking for an account under a given username across thousands of websites and pulling together whatever profile info it finds, with no API keys required.
- 10
Scrapegraph-ai
31.9KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 11

cheerio
30.5Kcheeriojs/cheerio · TypeScriptCheerio is a fast, flexible library for parsing and manipulating HTML and XML. It implements a subset of the core jQuery API, so if you know jQuery selectors you already know most of it.
- 12
crawlee
26.2Kapify/crawlee · TypeScriptA web scraping and browser automation library for Node.js: you write crawlers in JavaScript or TypeScript to crawl sites, extract data (e.g. for AI, LLM and RAG pipelines) and save it to disk or cloud.
- 13

colly
25.6Kgocolly/colly · GoColly is a scraping and crawling framework for Go: a clean interface for writing any kind of crawler, scraper or spider that extracts structured data from websites, for things like data mining, processing or archiving.
- 14

proxy_pool
23.8Kjhao104/proxy_pool · PythonProxyPool is an open-source proxy IP pool for web spiders: it keeps harvesting free proxies from the web, checks that they work, stores the good ones in Redis and serves them to your crawler over a small HTTP API.
- 15
newsnow
22.1Knewsnext/newsnow · TypeScriptNewsNow is an open-source web app for elegantly reading real-time and trending news, aggregating hot stories from multiple sources into one clean, readable interface.
- 16

jsdom
21.7Kjsdom/jsdom · JavaScriptjsdom is a pure-JavaScript implementation of many web standards — notably the WHATWG DOM and HTML Standards — for use with Node.js. It emulates enough of a browser subset to be useful for testing and scraping real-world web applications.
- 17
automa
21.7KAutomaApp/automa · VueAutoma is a browser extension that automates your browser by connecting blocks into workflows — auto-fill forms, take screenshots, repeat tedious tasks, or scrape website data.
- 18

twint
16.4Ktwintproject/twint · PythonTwint is a Python tool for scraping Twitter data — tweets, followers, following, likes and more — without using Twitter's official API, so it isn't bound by API limits or sign-up requirements.
- 19

Jackett
16.2KJackett/Jackett · C#Jackett is a proxy server for torrent trackers: it takes queries from apps like Sonarr, Radarr, SickRage, CouchPotato, Mylar3, Lidarr, DuckieTV, qBittorrent, Nefarious and NZBHydra2, turns them into tracker-site-specific HTTP requests, parses the HTML or JSON replies, and sends the results back to the app that asked.
- 20

FlareSolverr
16KFlareSolverr/FlareSolverr · PythonIt is a proxy server that bypasses Cloudflare and DDoS-GUARD protection: it loads the site in a real Chrome browser, waits out the challenge, and hands back the HTML and cookies your own HTTP client can reuse.
- 21

goquery
15KPuerkitoBio/goquery · Gogoquery is a Go library that brings jQuery-like syntax and features to HTML parsing and manipulation, built on Go's net/html package and the cascadia CSS selector library.
- 22

requests-html
13.8Kpsf/requests-html · PythonRequests-HTML is a Python library for parsing and scraping HTML pages, built on top of the Requests library, adding jQuery-style CSS selectors, XPath support, and full JavaScript rendering.
- 23
SeleniumBase
13.1Kseleniumbase/SeleniumBase · PythonSeleniumBase is an all-in-one Python framework for browser automation — web crawling, testing, scraping, and stealth. Its CDP Mode bypasses bot-detection in Chromium-based browsers, and a Stealthy Playwright Mode extends that to Playwright.
- 24
wechat-article-exporter
13.1Kwechat-article/wechat-article-exporter · TypeScriptAn open-source batch downloader for WeChat Official Account articles: search any account by keyword and export its posts, including read counts and comment data.
- 25
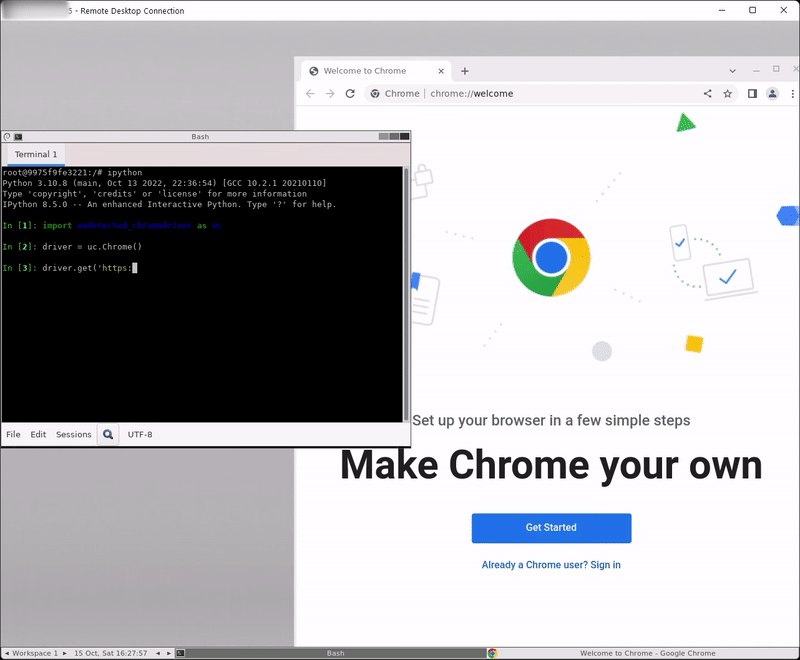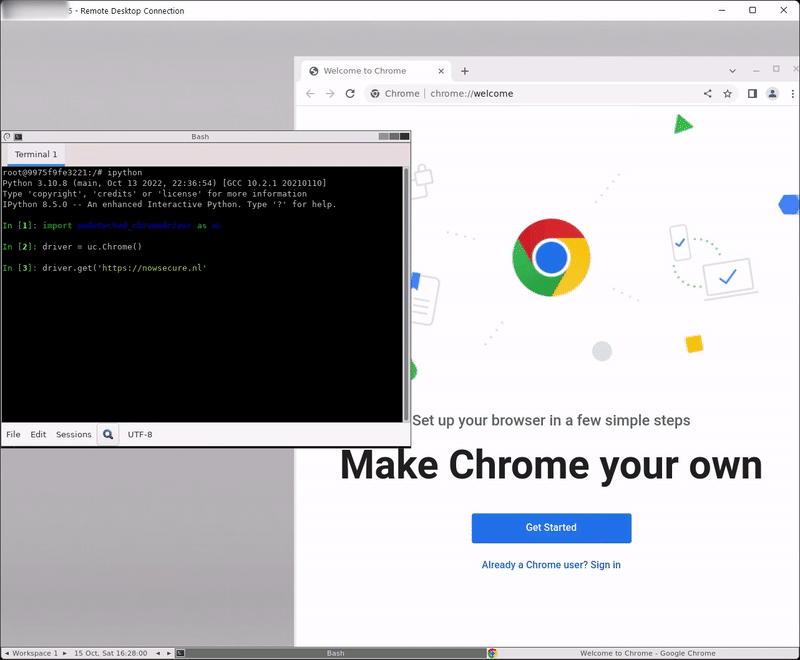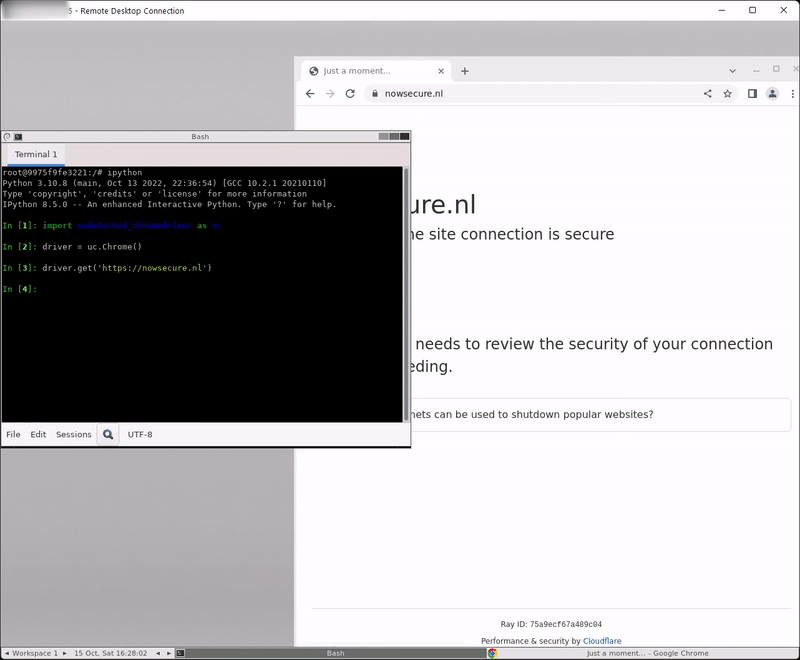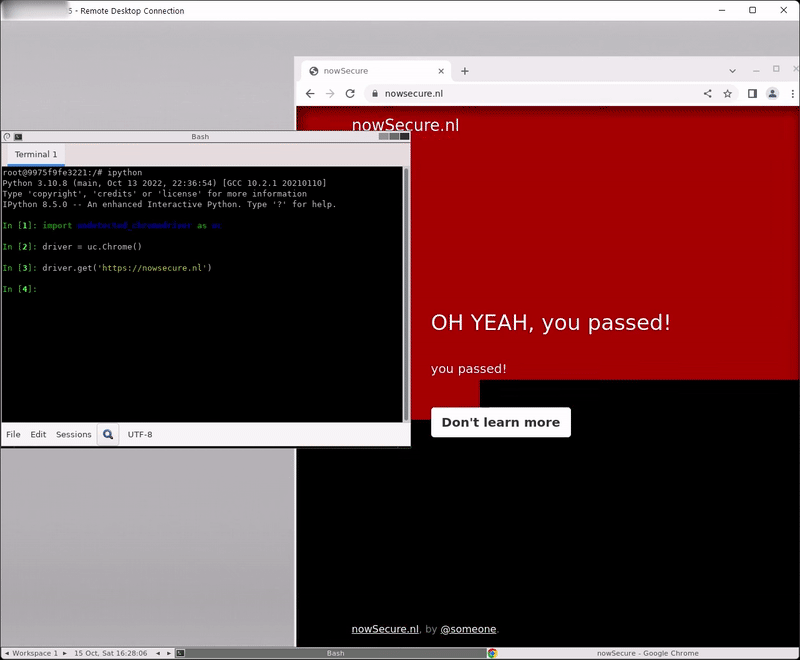
undetected-chromedriver
12.9Kultrafunkamsterdam/undetected-chromedriver · PythonIt is a patched Selenium Chromedriver for Python that automatically downloads and modifies the chromedriver binary so it evades anti-bot systems like Distil, Imperva, DataDome and Cloudflare IUAM.
- 26

camoufox
12.6Kdaijro/camoufox · PythonCamoufox is an open-source anti-detect browser, a Firefox fork built specifically for web scraping and AI agents that stays undetectable to anti-bot systems.
- 27

DrissionPage
12.5Kg1879/DrissionPage · PythonDrissionPage is a Python web automation tool that can control a browser, send and receive raw HTTP packets, or combine both in one workflow, giving you browser automation convenience together with requests-level efficiency.
- 28
reader
12.2Kjina-ai/reader · TypeScriptReader is a service that converts any URL into clean, LLM-friendly markdown by simply prefixing it with https://r.jina.ai/, and it also offers a web-search endpoint at https://s.jina.ai/ that returns readable content for the top search results instead of just titles and snippets.
- 29
camofox-browser
11.7Kjo-inc/camofox-browser · JavaScriptCamofox is a stealth headless browser server for AI agents: it wraps the Camoufox engine (a C++-patched Firefox) in a REST API that bypasses Cloudflare and bot detection, acting as a drop-in replacement for Puppeteer/Playwright.
- 30

webmagic
11.7Kcode4craft/webmagic · JavaWebMagic is a scalable web crawler framework for Java. It covers the whole crawler lifecycle — downloading, URL management, content extraction and persistence — to simplify building a specific crawler.
- 31
Python
10.9Kinjetlee/Python · PythonA personal grab-bag of standalone Python scripts and short tutorials the author wrote alongside blog posts: web scraping, WeChat official account development, Excel automation, SQL practice, and small utility hacks like remote shutdown.
- 32
avbook
10.1Kguyueyingmu/avbook · PHPA self-hosted AV (Japanese adult video) library: a PHP/Laravel web app with built-in crawlers for avmoo, javbus and javlibrary that builds a local, searchable database of movies and magnet links.
- 33
google-maps-scraper
6.6Kgosom/google-maps-scraper · GoA free, open-source tool that scrapes Google Maps to extract business leads such as name, address, phone, website, rating, reviews, email, and GPS coordinates.
- 34

cli
6.2Kbrightdata/cli · TypeScriptIt is the official Bright Data CLI, a command-line tool that scrapes, searches, and extracts structured web data directly from your terminal using Bright Data's API.
- 35

social-media-research-skills
4.1KScrapeCreators/social-media-research-skills · PythonA collection of 13 AI agent skills for social media research - finding outlier posts, mining comments, tearing down competitors, analyzing ad libraries, and tracking trends across TikTok, Instagram, YouTube, Reddit, X, LinkedIn and more, powered by the ScrapeCreators API.
- 36
scraping-apis-for-devs
3.9Kcporter202/scraping-apis-for-devs · JavaScriptA giant categorized directory of 2,622 ready-to-use scraping APIs for pulling data from websites, social media, e-commerce sites, job boards, real estate listings and more, so you don't have to build scrapers from scratch.
- 37
untidetect-tools
2KTheGP/untidetect-toolsA curated markdown list maintained by the author of their own anti-detect project, tracking anti-detect/humanizing browsers, browser-automation and fingerprint-spoofing libraries, captcha solvers, SMS-activation services, and proxy providers used to avoid bot and fingerprint detection.
- 38

invisible_puppeteer
1.4Kfeder-cr/invisible_puppeteer · PythonThis is a Python port of Puppeteer that runs on a patched, anti-detect Firefox build so sites using reCAPTCHA, hCaptcha or Cloudflare Turnstile can't tell it's a bot, letting you scrape and automate without hitting captchas.
- 39
reverse-api-engineer
1.4Kkalil0321/reverse-api-engineer · PythonReverse API Engineer is an agent that browses a website (manually or via an AI-driven browser), captures the network traffic it makes, and uses an AI model to generate a working typed API client from the endpoints it actually used.
- 40

turnstile-bypass
502Sophomoresty/turnstile-bypass · PythonA cross-platform tool that drives a real, headed Chrome browser to solve a Cloudflare Turnstile widget and get past Cloudflare's interstitial 'waiting room' page, returning a token or a cfclearance cookie as JSON.
- 41

patchright-enhanced
501whaleyxbt/patchright-enhanced · TypeScriptIt's a stealth browser automation toolkit built on top of Patchright (a patched Playwright) aimed at QA testing, monitoring, scraping, and penetration testing. It focuses on producing clean Chrome sessions that get past WAFs like Cloudflare, Kasada, and DataDome out of the box.
- 42

tiktok-signature
398n1tr00-10/tiktok-signature · PythonThis is a Python library that generates the signatures TikTok's Web API requires on requests — X-Gnarly, X-Bogus, and X-Dynosaur — matching SDK version 5.1.2 (build 1.0.0.316).
- 43
captcha-api
257jamespolyakov9829/captcha-api · PythonA dependency-free Python client and CLI for the Clearance captcha-solving API, giving one interface to solve both the Cloudflare Challenge ('Just a moment.' interstitial) and the Turnstile widget.
- 44
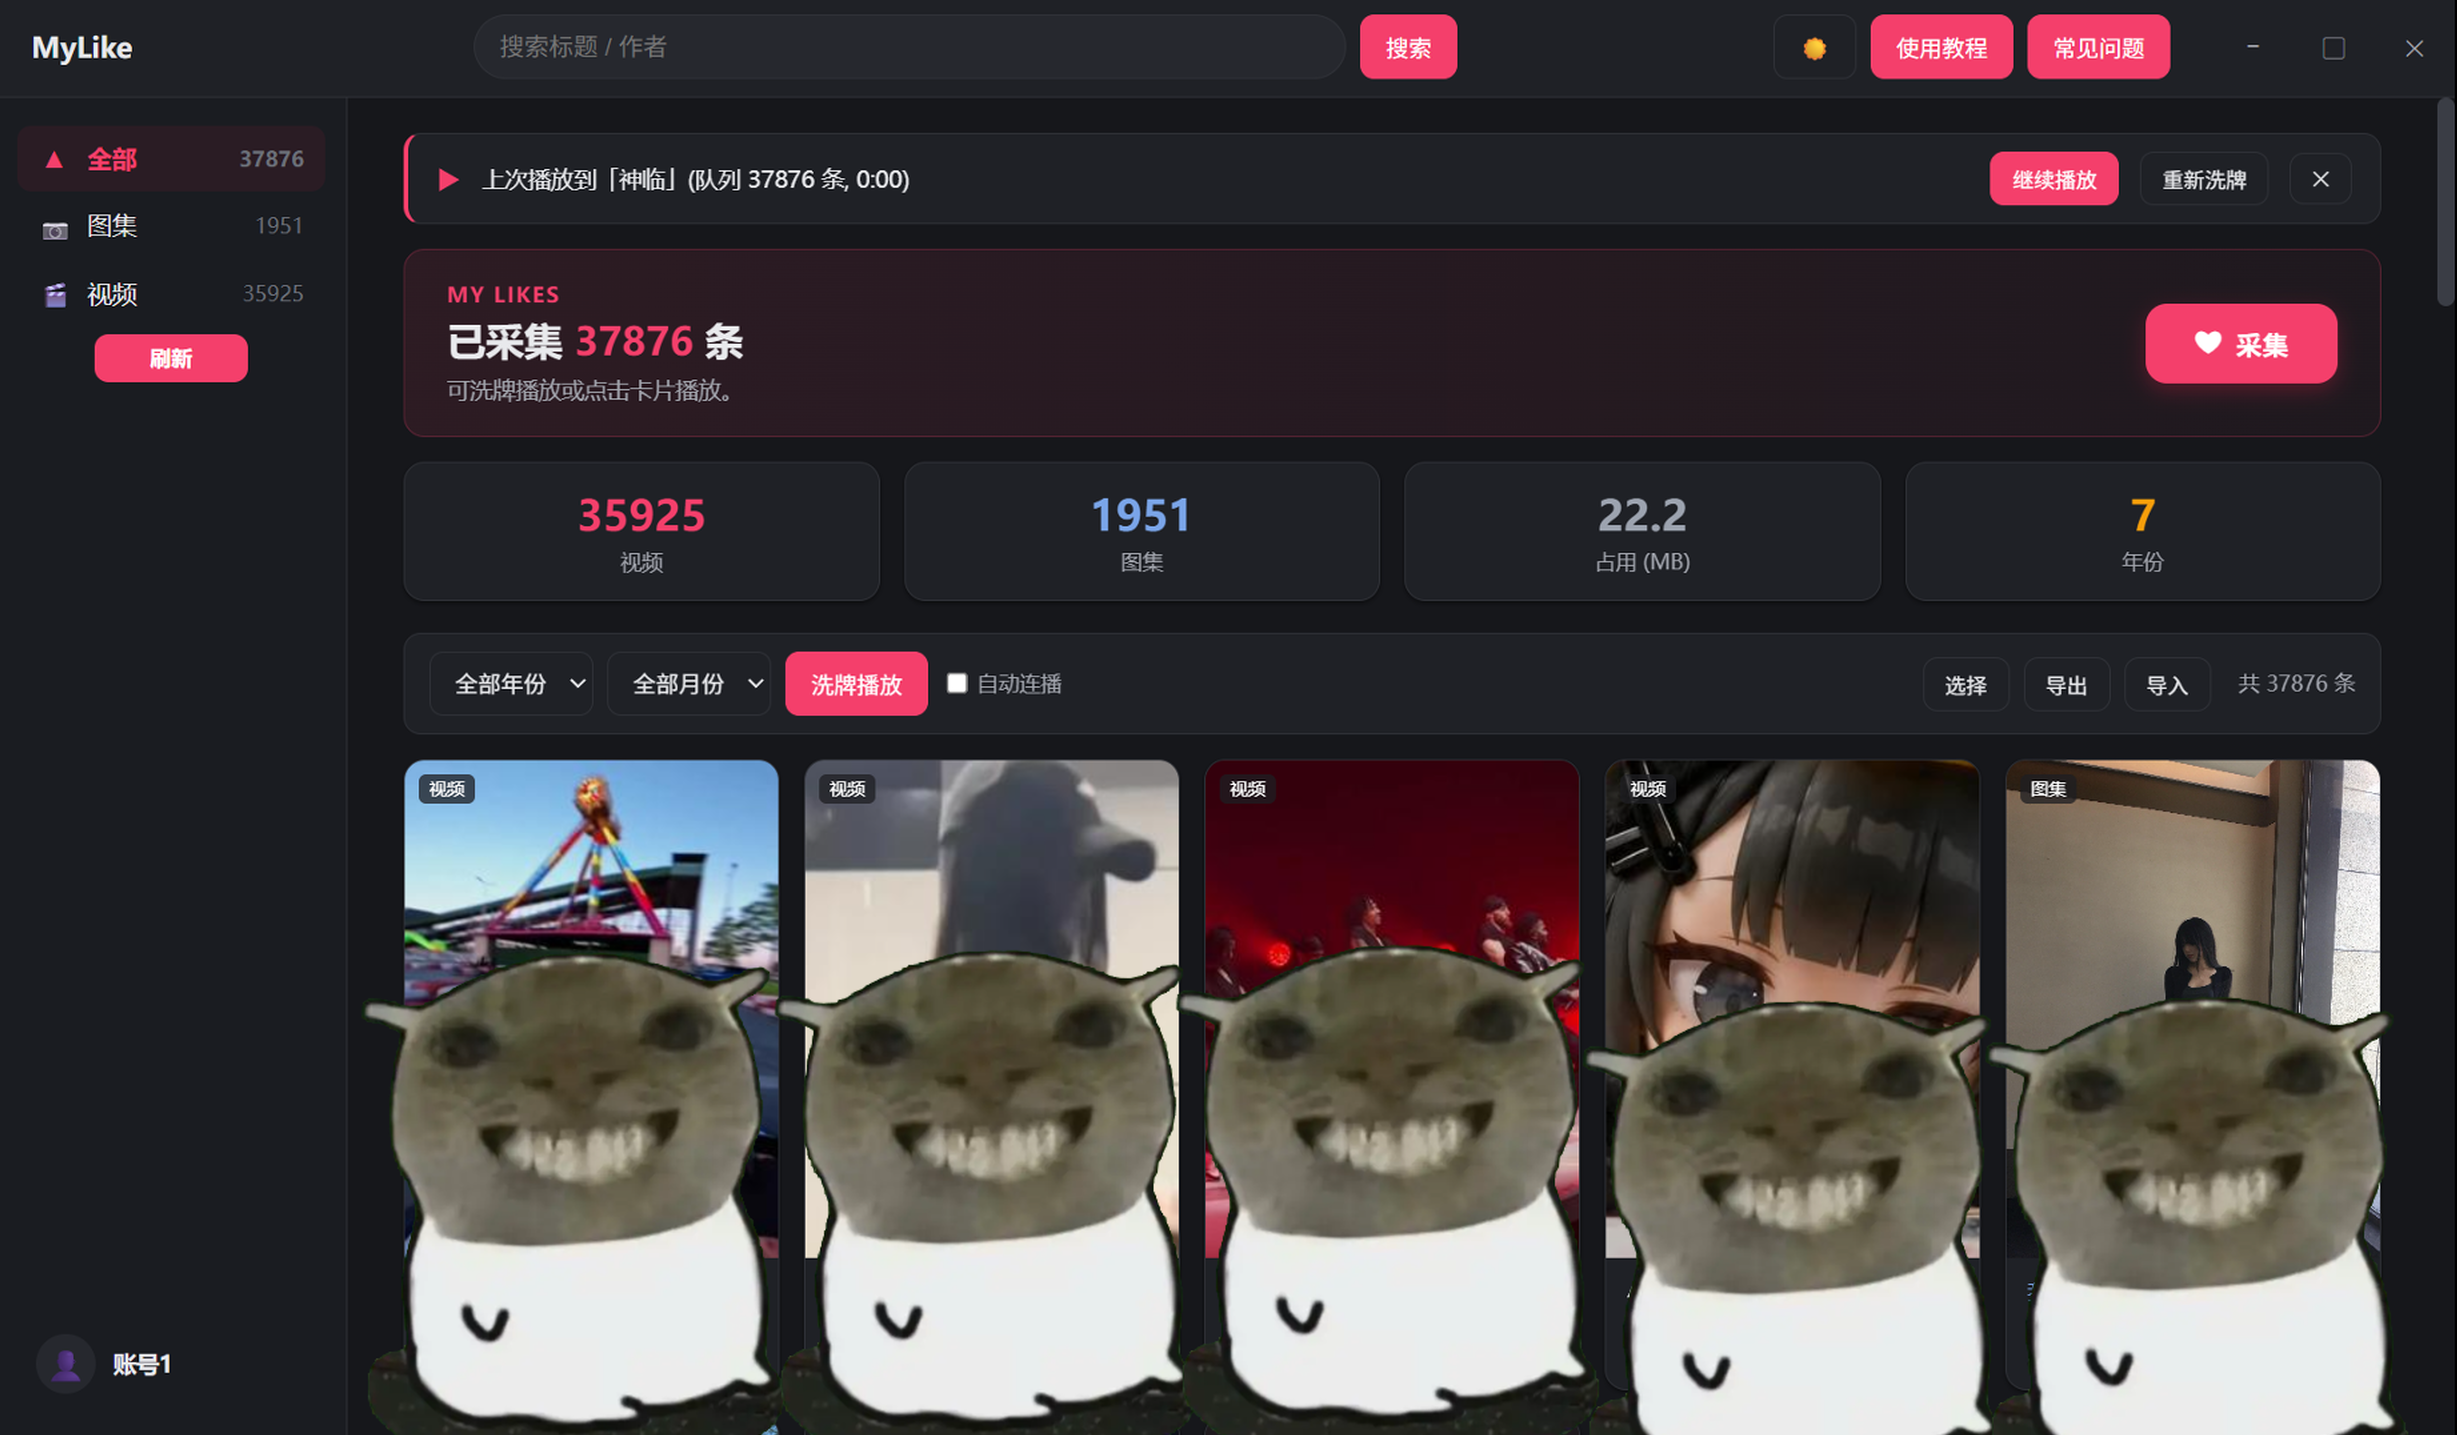
douyin-favorite-MyLike
209Hannah2227/douyin-favorite-MyLike · C#MyLike is a Windows desktop app that downloads your entire Douyin (Chinese TikTok) 'liked videos' list to your computer so you can filter, search, and shuffle-play it locally, without the Douyin app, even with tens of thousands of items.
- 45

solari-cookbook
191solari-sdk/solari-cookbook · PythonA cookbook of small, runnable example programs for Solari, a service that gives you cloud browsers, sandboxes, and desktop VMs behind a single API key.
Related topics
Often tagged together