Topics / #webscraping
Webscraping projects on GitHub
Programmatic extraction of data from web pages
As of , the most-starred Webscraping projects on GitHub are firecrawl (192.5K stars), Scrapling (88.3K stars) and huginn (50.1K stars). GitHub.Locker tracks 14 Webscraping repositories with 490.4K stars combined. The fastest-growing on October 17 was firecrawl, with +311 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +311
firecrawl
firecrawl/firecrawl · ★ 192.5KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +188
Scrapling
D4Vinci/Scrapling · ★ 88.3KScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
 +48
Scrapegraph-ai
ScrapeGraphAI/Scrapegraph-ai · ★ 31.9KScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
 +39
camoufox
daijro/camoufox · ★ 12.6KCamoufox is an open-source anti-detect browser, a Firefox fork built specifically for web scraping and AI agents that stays undetectable to anti-bot systems.
The all-time top
14 projects · by stars
- 192.5K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 88.3K#2 · D4Vinci/Scrapling
Scrapling
Scrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 50.1K
 #3 · huginn/huginn
huginn
Huginn lets you build 'agents' that watch the web for events and act on your behalf — a self-hosted, hackable alternative to IFTTT or Zapier.
- 4

CloakBrowser
32.3KCloakHQ/CloakBrowser · PythonA stealth Chromium browser for web scraping and automation — a real Chromium binary with fingerprints patched at the C++ source level, wrapped as a drop-in Playwright/Puppeteer replacement so antibot systems score it as a normal browser.
- 5
Scrapegraph-ai
31.9KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 6
gpt-researcher
30.1Kassafelovic/gpt-researcher · PythonAn open-source autonomous agent that runs deep research on any task across the web and your local documents, producing detailed, factual research reports with citations.
- 7
maxun
17.9Kgetmaxun/maxun · TypeScriptMaxun is an open-source no-code web data platform that turns any website into structured, reliable data: it handles extraction, crawling, scraping, search and AI-powered data extraction.
- 8

ani-cli
14Kpystardust/ani-cli · Shellani-cli is a command-line tool that scrapes an anime streaming site and lets you search for and play anime episodes directly from the terminal, alone or with friends via syncplay.
- 9
camoufox
12.6Kdaijro/camoufox · PythonCamoufox is an open-source anti-detect browser, a Firefox fork built specifically for web scraping and AI agents that stays undetectable to anti-bot systems.
- 10

DrissionPage
12.5Kg1879/DrissionPage · PythonDrissionPage is a Python web automation tool that can control a browser, send and receive raw HTTP packets, or combine both in one workflow, giving you browser automation convenience together with requests-level efficiency.
- 11
invisible_selenium
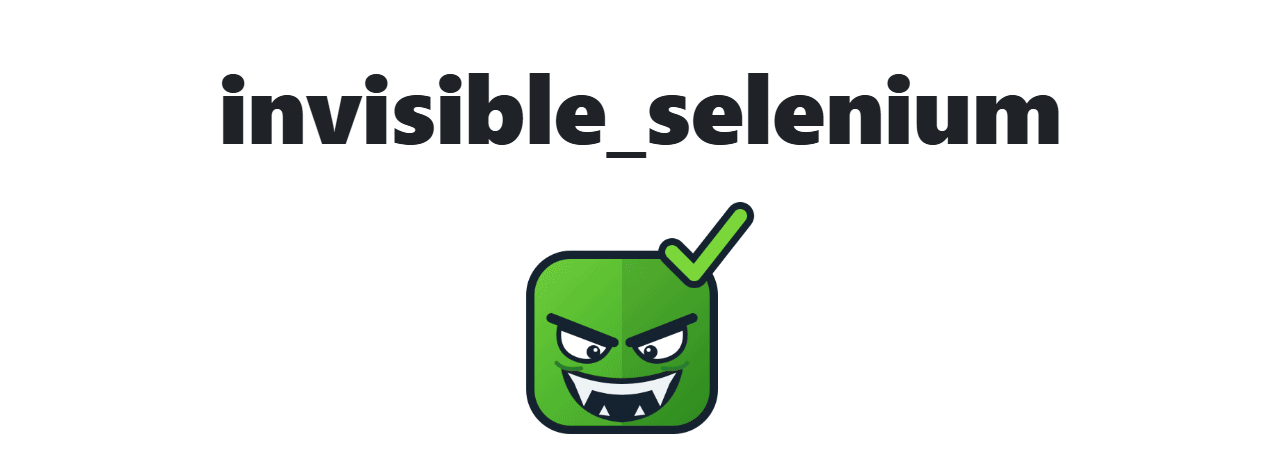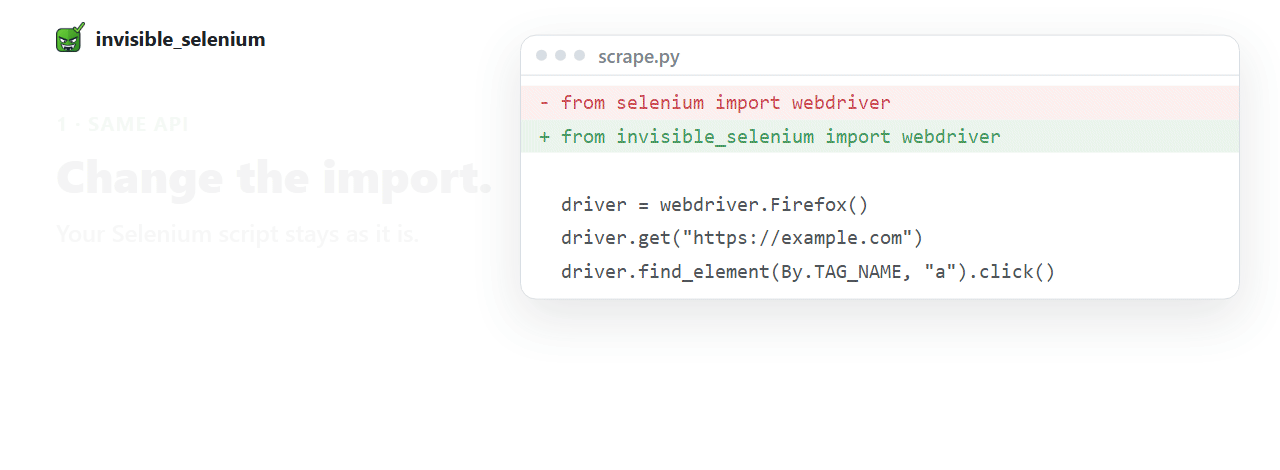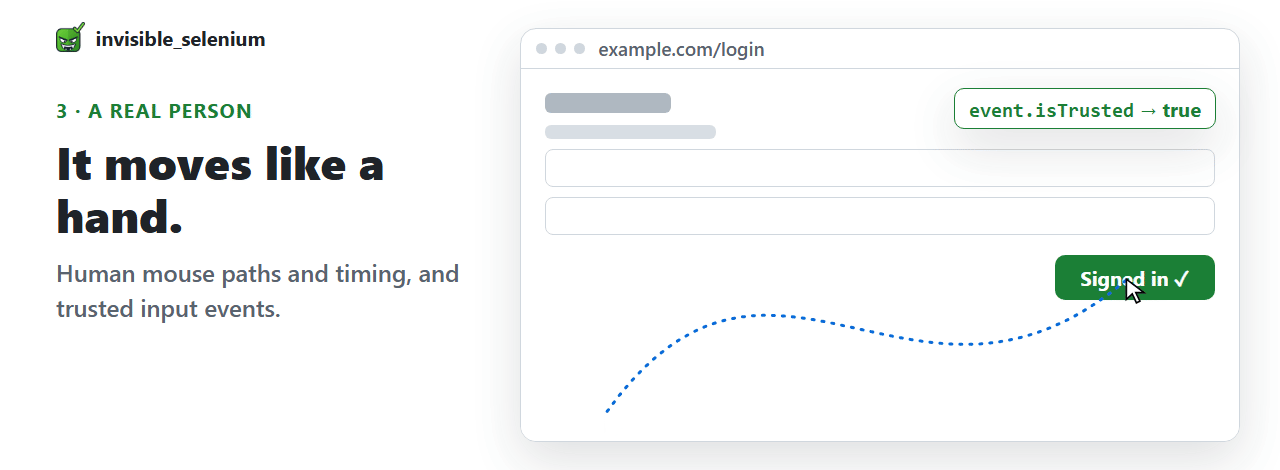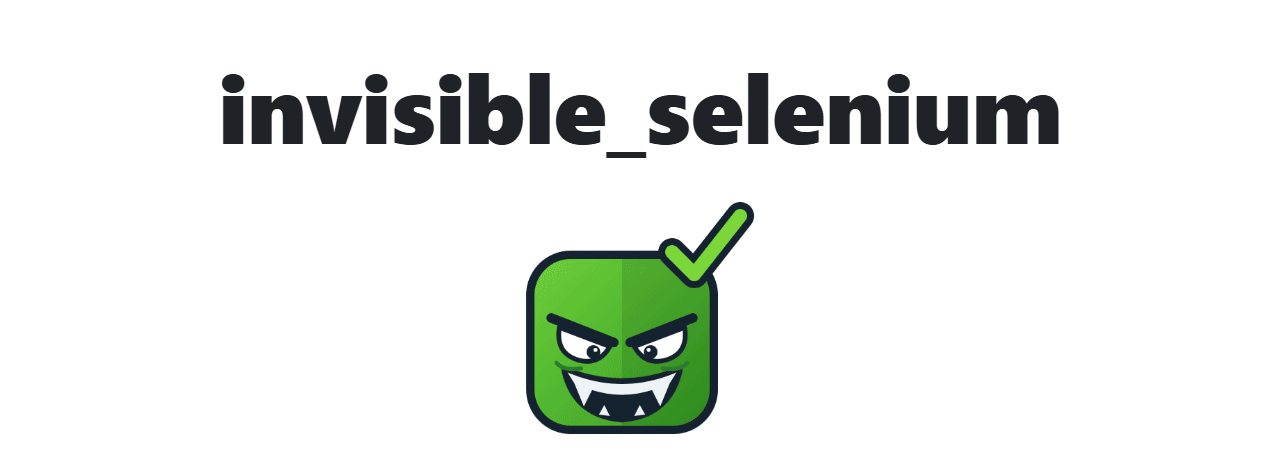
3Kfeder-cr/invisible_selenium · PythonA drop-in replacement for Selenium that runs on a C++-patched, anti-detect Firefox with an undetectable browser fingerprint and humanized mouse/input actions, so anti-bot systems and captchas (reCAPTCHA, hCaptcha, Cloudflare Turnstile) don't flag it as automation.
- 12

invisible_playwright_mcp
2.8Kfeder-cr/invisible_playwright_mcp · PythonThis is dots, a Playwright MCP server that gives AI agents a real, patched Firefox browser so they can browse the web without being flagged by anti-bot systems or captchas.
- 13

invisible_puppeteer
1.4Kfeder-cr/invisible_puppeteer · PythonThis is a Python port of Puppeteer that runs on a patched, anti-detect Firefox build so sites using reCAPTCHA, hCaptcha or Cloudflare Turnstile can't tell it's a bot, letting you scrape and automate without hitting captchas.
- 14
ovobrowser
1Kovobrowsersupport/ovobrowserThis is a Chromium build whose fingerprint evasion is patched directly into the C++ source and compiled into the binary, so bot-detection scripts see a normal Chrome instead of a JS-injected stealth layer like playwright-stealth.
Related topics
Often tagged together
- automation1,184
- web-scraping159
- linux4,181
- python2,397
- browser-automation188
- open-source5,666
- windows3,401
- docker1,657
- mit3,311
- playwright123
- ai-agents1,295
- cli2,227
- proxy382
- scraping44
- ai1,955
- antidetect-browser13
- macos3,544
- scraper42
- self-hosted1,926
- stealth-browser11
- web2,447
- anti-detect9
- anti-detect-browser10
- bot-detection17