Topics / #pdf-parser
PDF parser projects on GitHub
Tools that extract text, tables, and structure from PDF documents, often for AI pipelines.
As of , the most-starred PDF parser projects on GitHub are PaddleOCR (91.3K stars), MinerU (81.9K stars) and opendataloader-pdf (29.7K stars). GitHub.Locker tracks 7 PDF parser repositories with 255.8K stars combined. The fastest-growing on October 16 was PaddleOCR, with +62 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +62
PaddleOCR
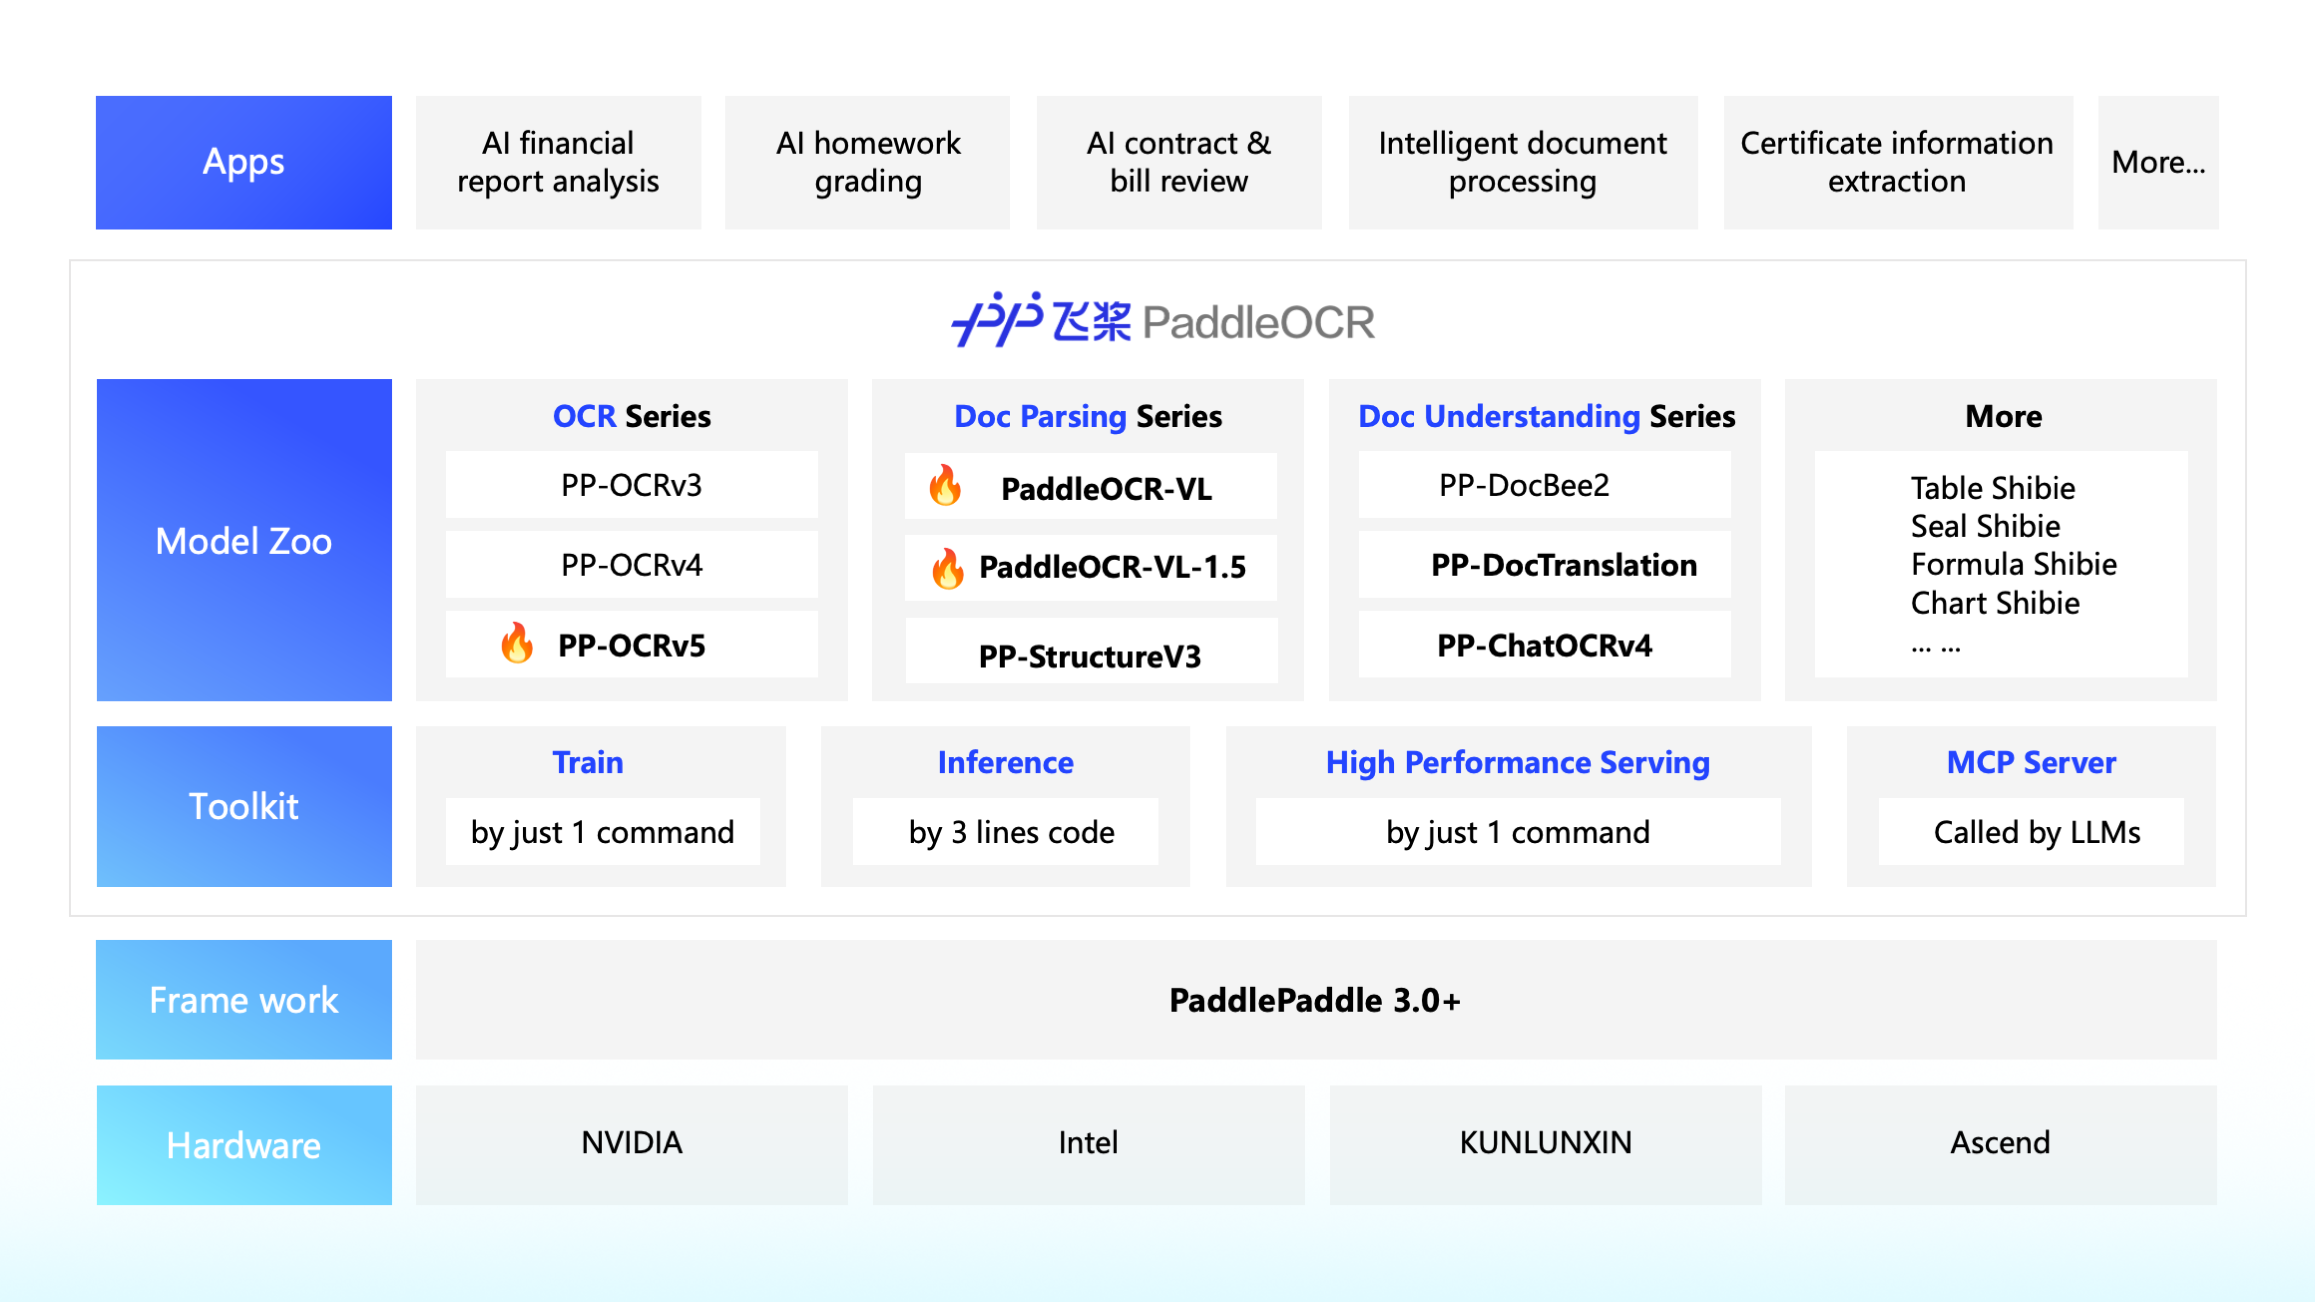
PaddlePaddle/PaddleOCR · ★ 91.3KPaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
 +46
MinerU
opendatalab/MinerU · ★ 81.9KMinerU is a high-accuracy document parsing engine that converts PDF, DOCX, PPTX, XLSX, images and web pages into structured Markdown or JSON, built for LLM, RAG and agent workflows.
 +12
opendataloader-pdf
opendataloader-project/opendataloader-pdf · ★ 29.7KAn open-source PDF parser built for AI pipelines: it turns PDFs into Markdown, JSON (with bounding boxes) and HTML, and can auto-tag untagged PDFs into screen-reader-ready Tagged PDFs.
liteparse
run-llama/liteparse · ★ 12.9KLiteParse is a standalone open-source PDF parser focused on fast, lightweight parsing: it extracts spatial text with bounding boxes and outputs Markdown, JSON, or Text, all running locally with no cloud or LLM calls.
The all-time top
7 projects · by stars
- 91.3K#1 · PaddlePaddle/PaddleOCR
PaddleOCR
PaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
- 81.9K#2 · opendatalab/MinerU
MinerU
MinerU is a high-accuracy document parsing engine that converts PDF, DOCX, PPTX, XLSX, images and web pages into structured Markdown or JSON, built for LLM, RAG and agent workflows.
- 29.7K#3 · opendataloader-project/opendataloader-pdf
opendataloader-pdf
An open-source PDF parser built for AI pipelines: it turns PDFs into Markdown, JSON (with bounding boxes) and HTML, and can auto-tag untagged PDFs into screen-reader-ready Tagged PDFs.
- 4

pdf-inspector
19.7Kfirecrawl/pdf-inspector · RustA fast Rust library from Firecrawl that inspects PDFs: it classifies each file as text-based, scanned, image-based, or mixed, extracts position-aware text, and converts it to clean Markdown without OCR by default.
- 5
liteparse
12.9Krun-llama/liteparse · RustLiteParse is a standalone open-source PDF parser focused on fast, lightweight parsing: it extracts spatial text with bounding boxes and outputs Markdown, JSON, or Text, all running locally with no cloud or LLM calls.
- 6

pypdf
10.3Kpy-pdf/pypdf · PythonA free and open-source pure-python PDF library: it splits, merges, crops and transforms the pages of PDF files, and can add custom data, viewing options and passwords to them.
- 7

nougat
10.1Kfacebookresearch/nougat · PythonNougat (Neural Optical Understanding for Academic Documents) is a PDF parser for academic papers that converts them into markdown text while correctly understanding LaTeX math equations and tables.
Related topics
Often tagged together