Topics / #web-scraping
Web-scraping projects on GitHub
Extracting structured data from websites with crawlers and parsers.
As of , the most-starred Web-scraping projects on GitHub are firecrawl (192.2K stars), Python-100-Days (187.2K stars) and browser-use (118.2K stars). GitHub.Locker tracks 158 Web-scraping repositories with 3.2M stars combined. The fastest-growing on October 16 was ai-job-search, with +1.2K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +1.2K
ai-job-search
MadsLorentzen/ai-job-search · ★ 48.9KAn AI-powered job application framework built on top of Claude Code. You fork it, fill in your profile, and Claude evaluates job postings, tailors your CV, writes cover letters, and preps you for interviews, all running locally on your own machine.
 +513
Agent-Reach
Panniantong/Agent-Reach · ★ 98.4KAgent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
 +334
firecrawl
firecrawl/firecrawl · ★ 192.2KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +317
moli
lexmount/moli · ★ 19.1KMoli is a production-ready headless browser for AI agents, built in Rust. It helps agents fetch and extract web pages, search the web, and automate browser tasks through the CLI, CDP, WebDriver Classic, or WebDriver BiDi.
The all-time top
Top 100 of 158 · by stars
- 192.2K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 187.2K
 #2 · jackfrued/Python-100-Days
Python-100-Days
A free, day-by-day Python curriculum by Luo Hao (骆昊) that takes a complete beginner through 100 days of lessons covering core language fundamentals, file and database handling, web development with Django, web scraping, data analysis, and machine learning.
- 118.2K
#3 · browser-use/browser-use
browser-use
Browser Use is an open-source browser agent that lets AI models control a real web browser - navigating sites, filling forms, handling CAPTCHAs, and completing tasks like booking appointments.
- 4
Agent-Reach
98.4KPanniantong/Agent-Reach · PythonAgent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
- 5

playwright
97.9Kmicrosoft/playwright · TypeScriptPlaywright is a framework for web testing and automation that drives Chromium, Firefox, and WebKit through a single API, usable in test suites, automation scripts, and as a tool for AI agents.
- 6
puppeteer
95.7Kpuppeteer/puppeteer · TypeScriptPuppeteer is a JavaScript library that gives you a high-level API to control Chrome or Firefox programmatically, either over the DevTools Protocol or WebDriver BiDi.
- 7

Scrapling
88.1KD4Vinci/Scrapling · PythonScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 8

crawl4ai
85.7Kunclecode/crawl4ai · PythonCrawl4AI is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG pipelines, AI agents, and data extraction workflows.
- 9
30-Days-Of-Python
76.4KAsabeneh/30-Days-Of-Python · PythonA free 30-day structured curriculum for learning Python from scratch, covering everything from basic syntax to building web APIs and working with databases.
- 10
MediaCrawler
67KNanmiCoder/MediaCrawler · PythonA multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
- 11

scrapy
64.9Kscrapy/scrapy · PythonScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 12
you-get
56.9Ksoimort/you-get · PythonYou-Get is a tiny command-line utility that downloads media contents — videos, audios and images — from the web, for when there is no other handy way to save them.
- 13

huginn
50.1Khuginn/huginn · RubyHuginn lets you build 'agents' that watch the web for events and act on your behalf — a self-hosted, hackable alternative to IFTTT or Zapier.
- 14
ai-job-search
48.9KMadsLorentzen/ai-job-search · PythonAn AI-powered job application framework built on top of Claude Code. You fork it, fill in your profile, and Claude evaluates job postings, tailors your CV, writes cover letters, and preps you for interviews, all running locally on your own machine.
- 15
RSSHub
46.5KDIYgod/RSSHub · TypeScriptRSSHub is an open-source RSS feed generator that turns content from thousands of sites and apps (Bilibili, Twitter/X, Instagram, YouTube, Telegram, Spotify, and more) into RSS feeds you can subscribe to in any reader.
- 16
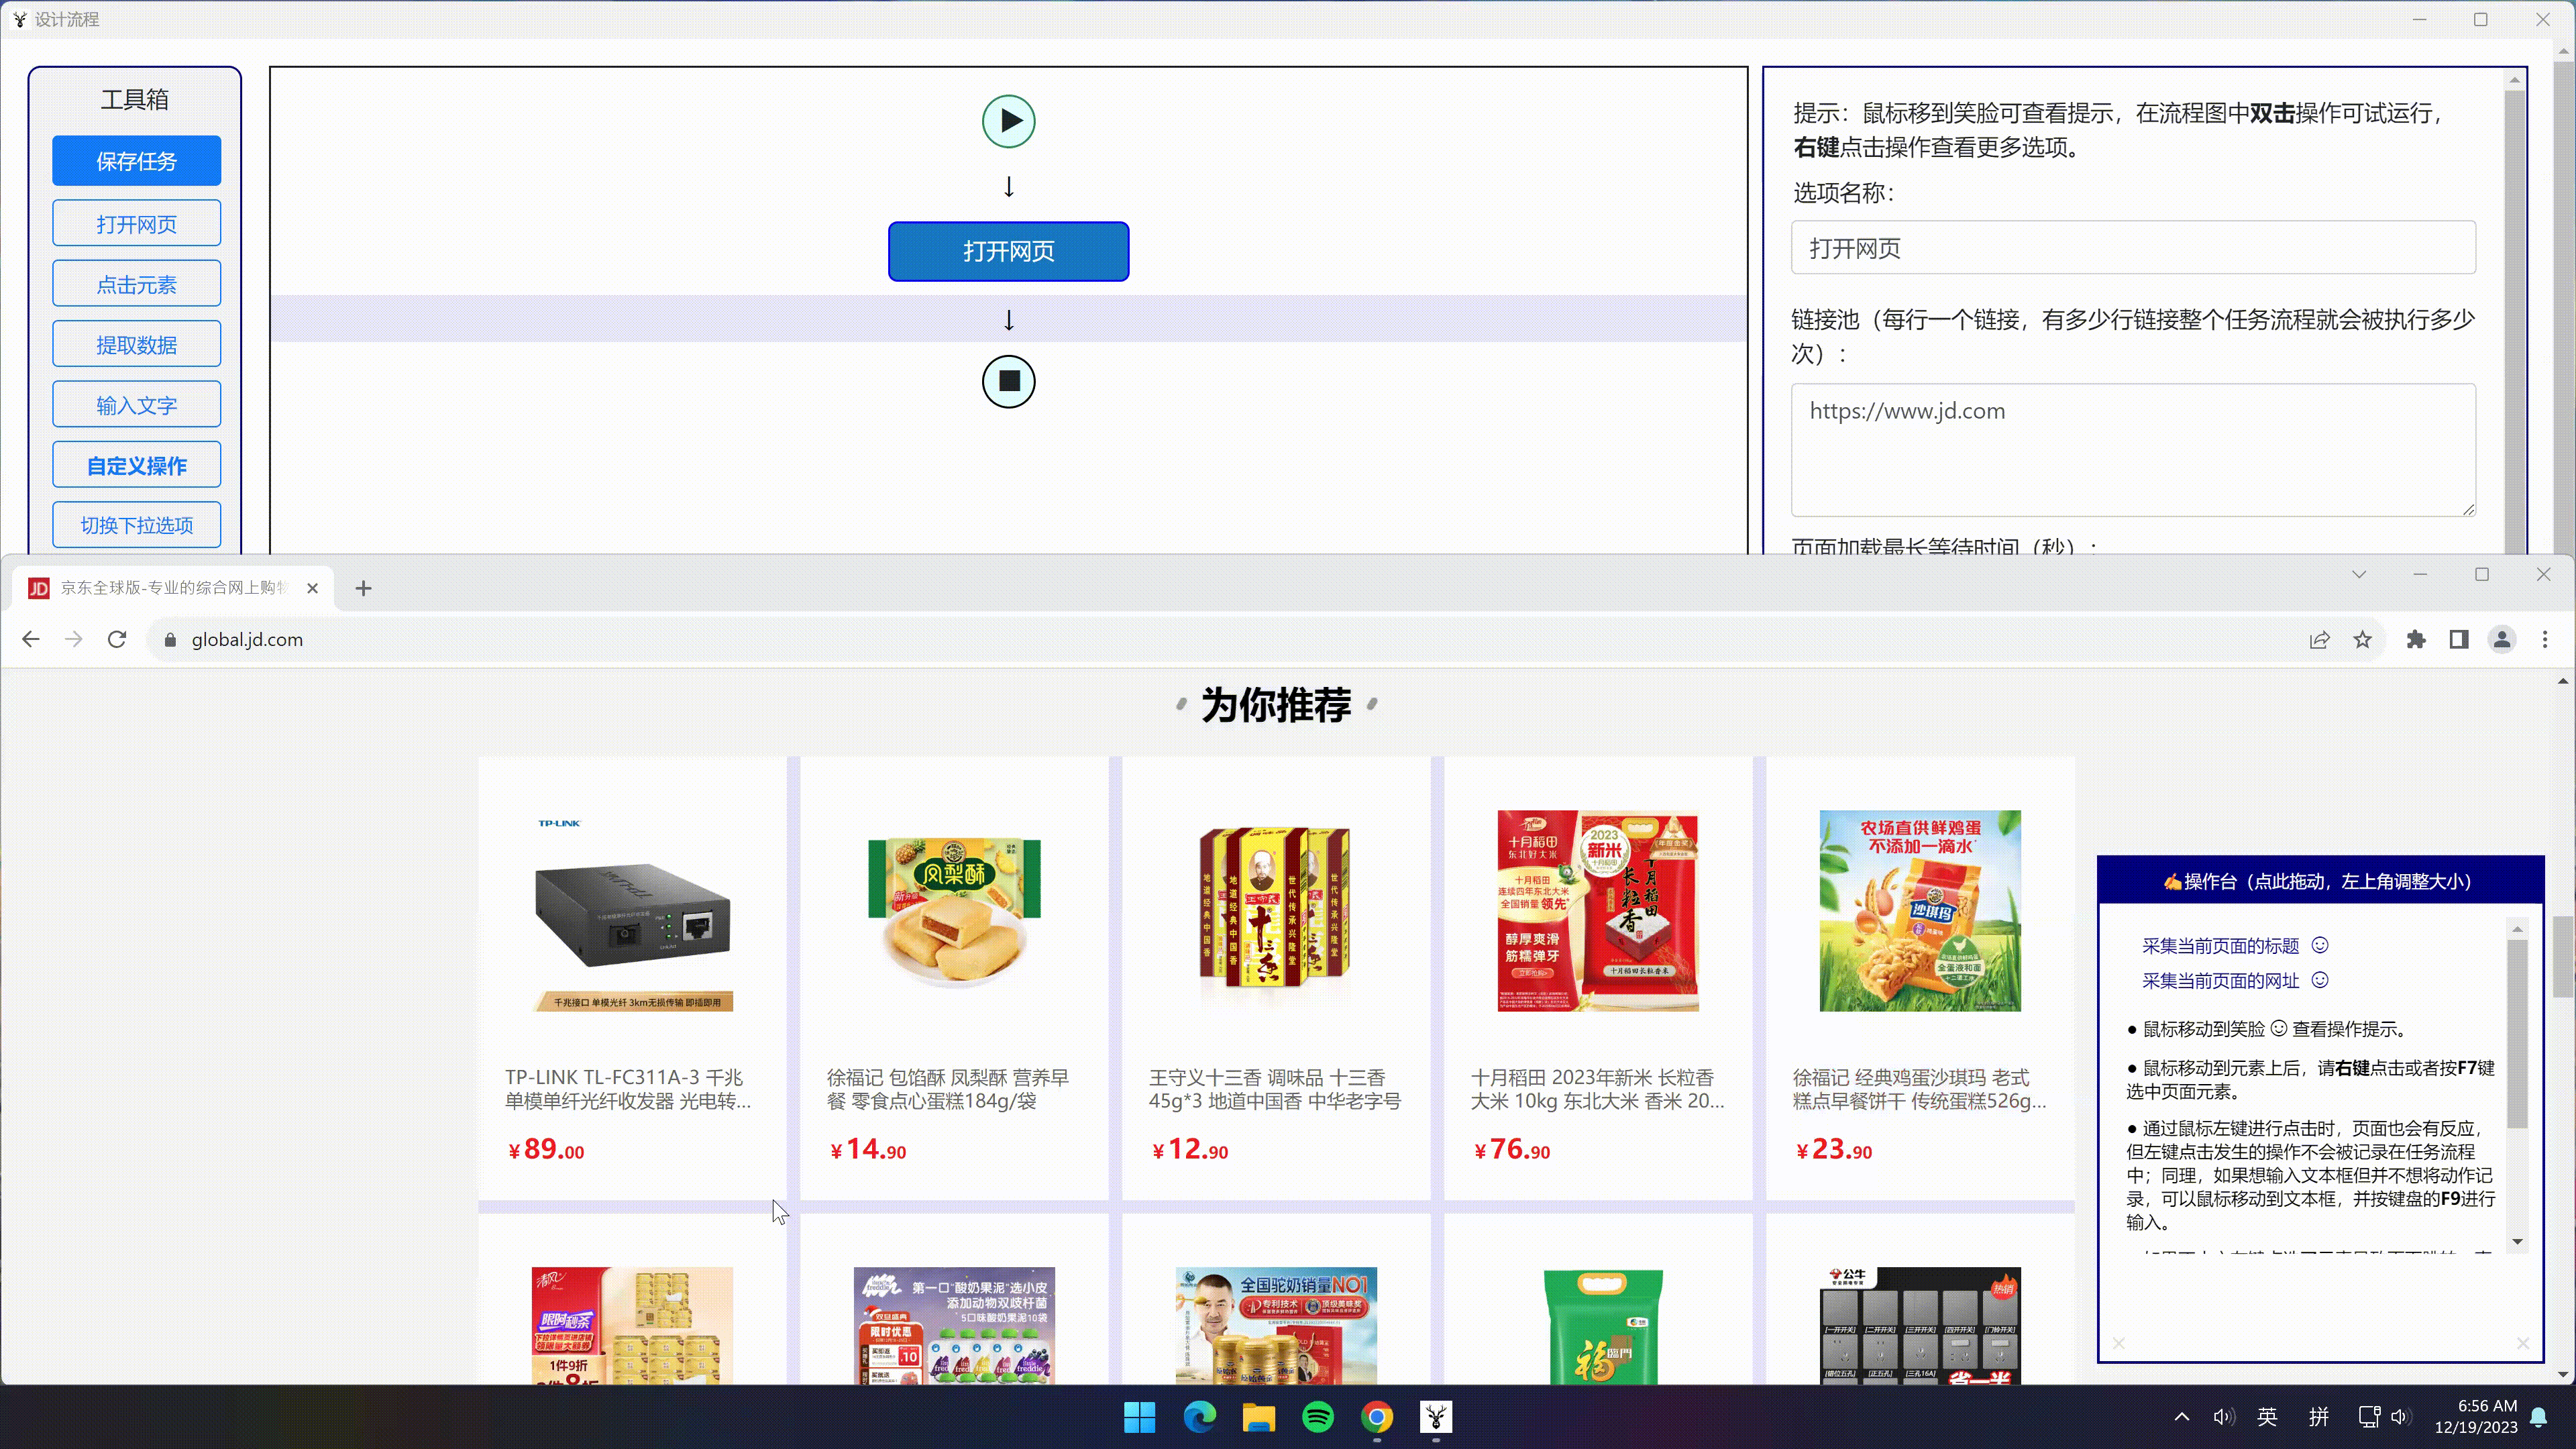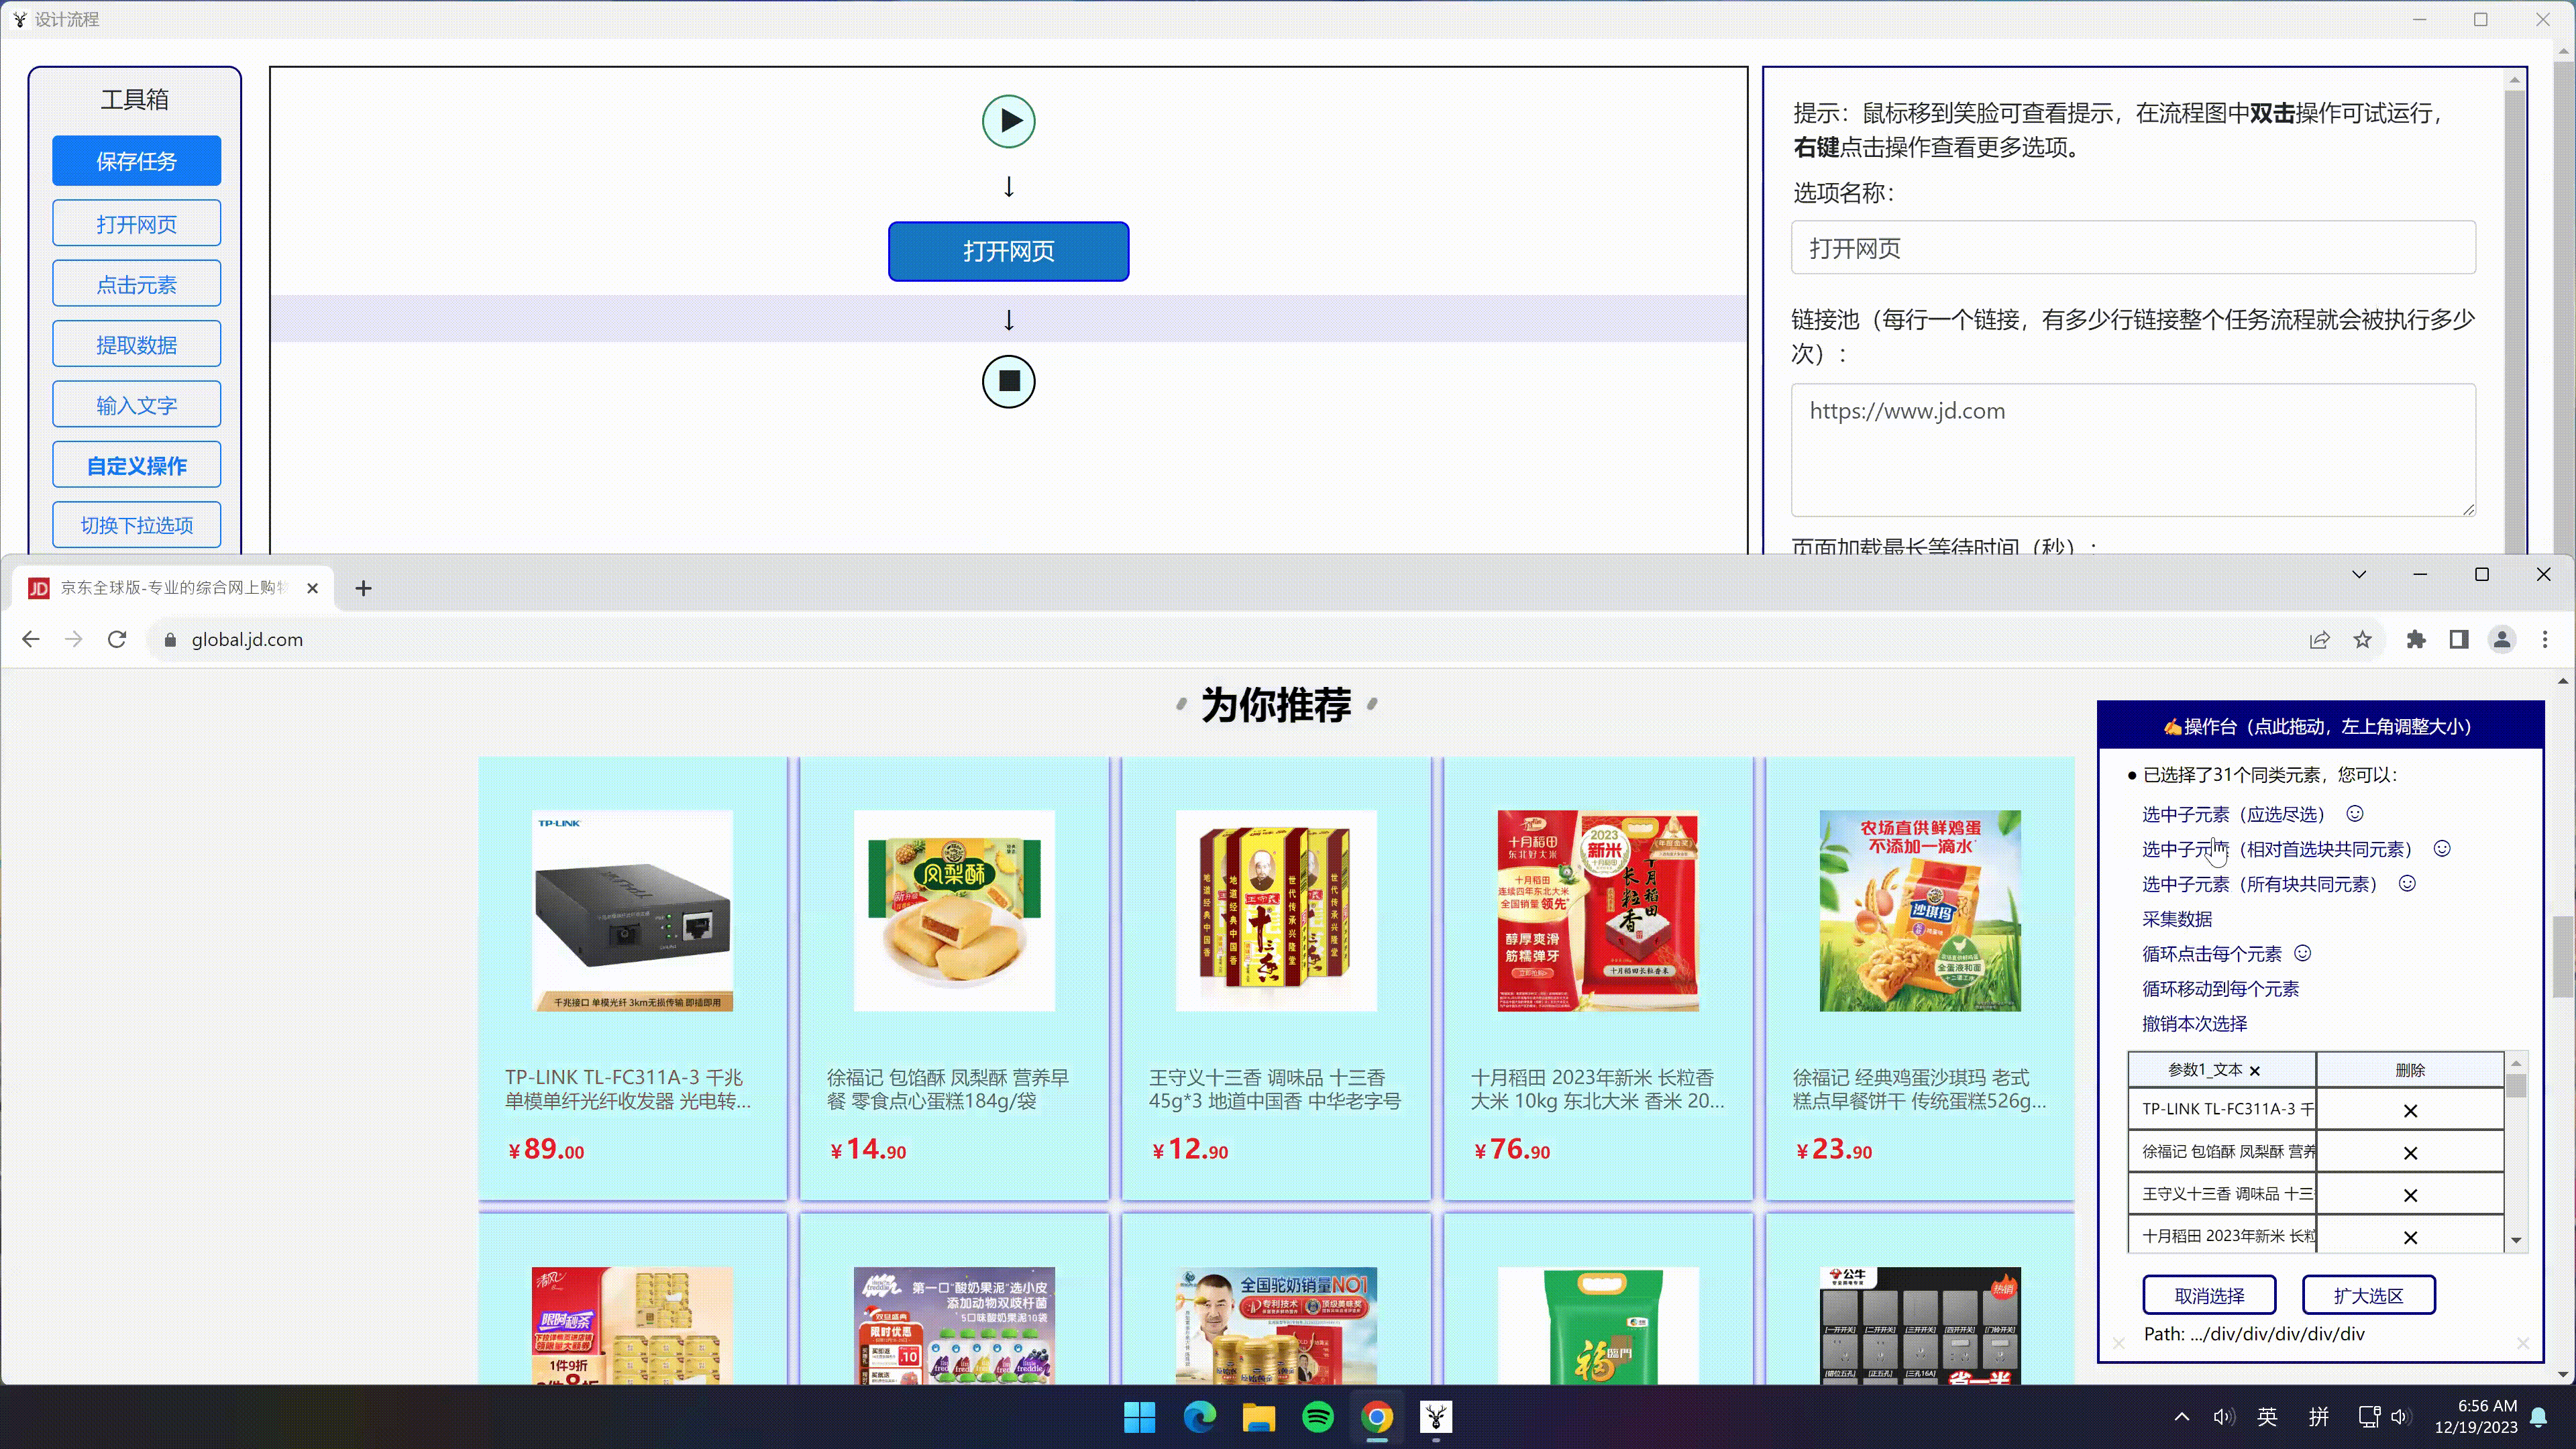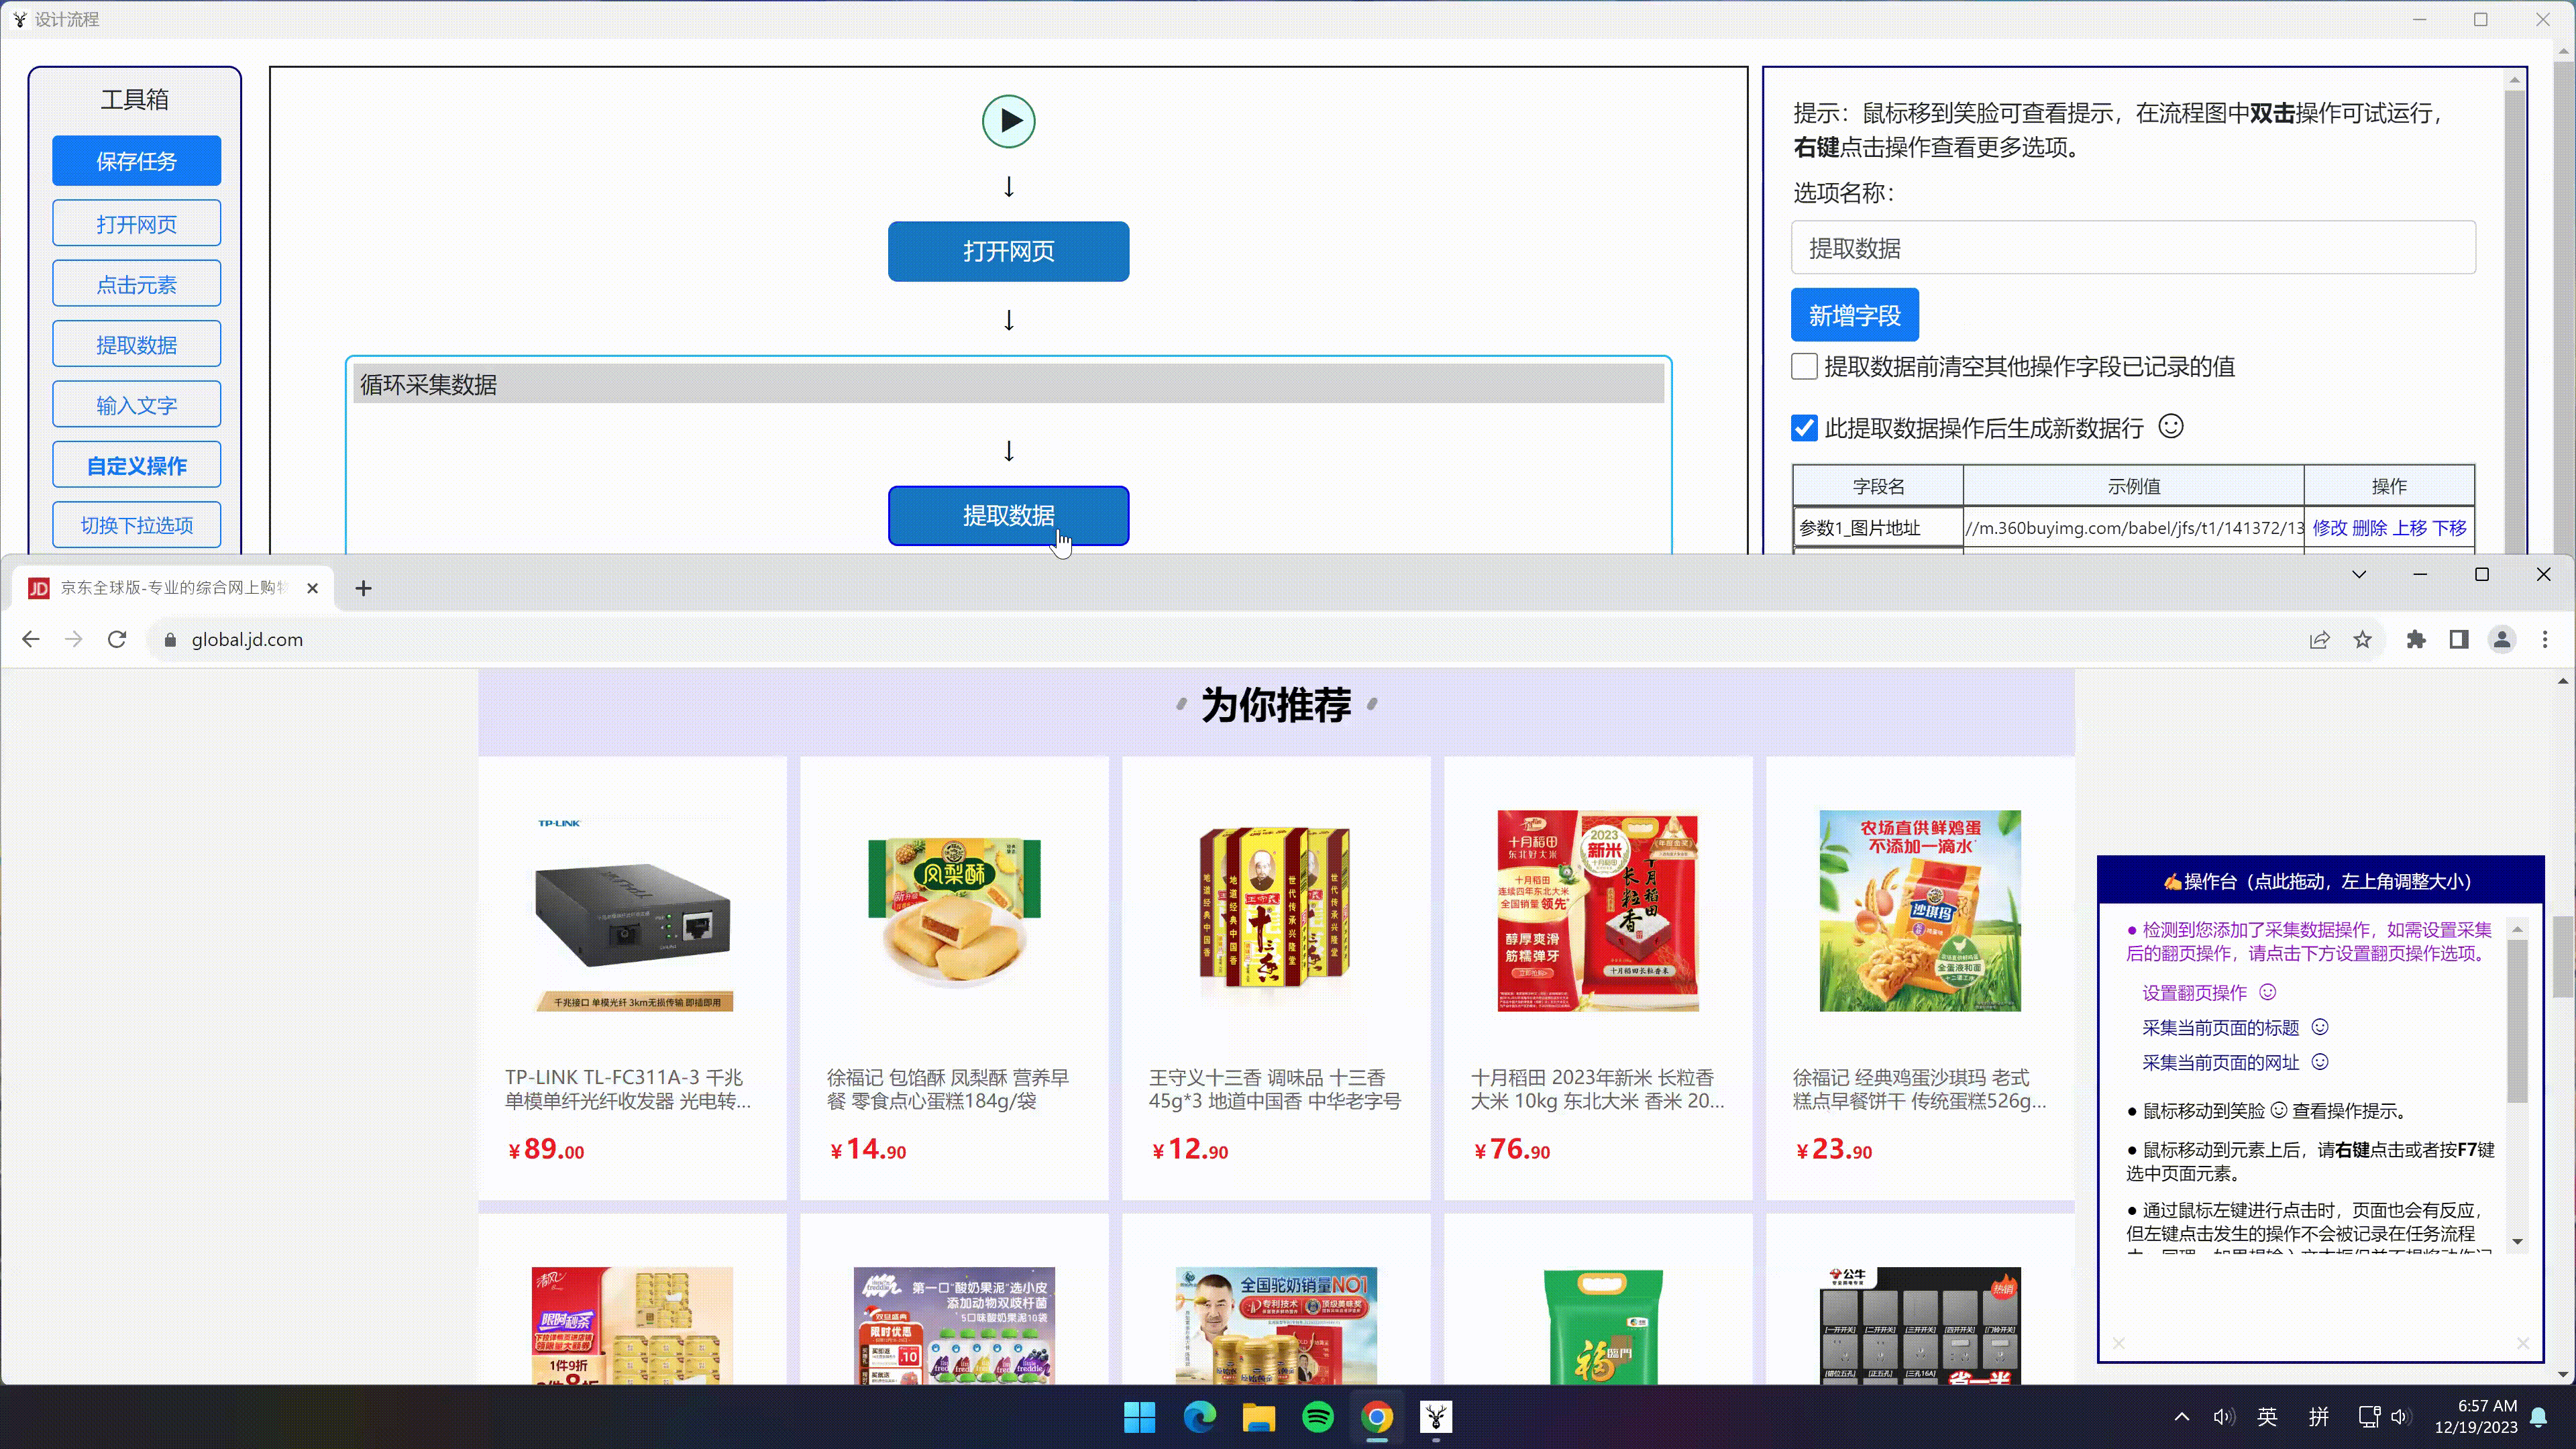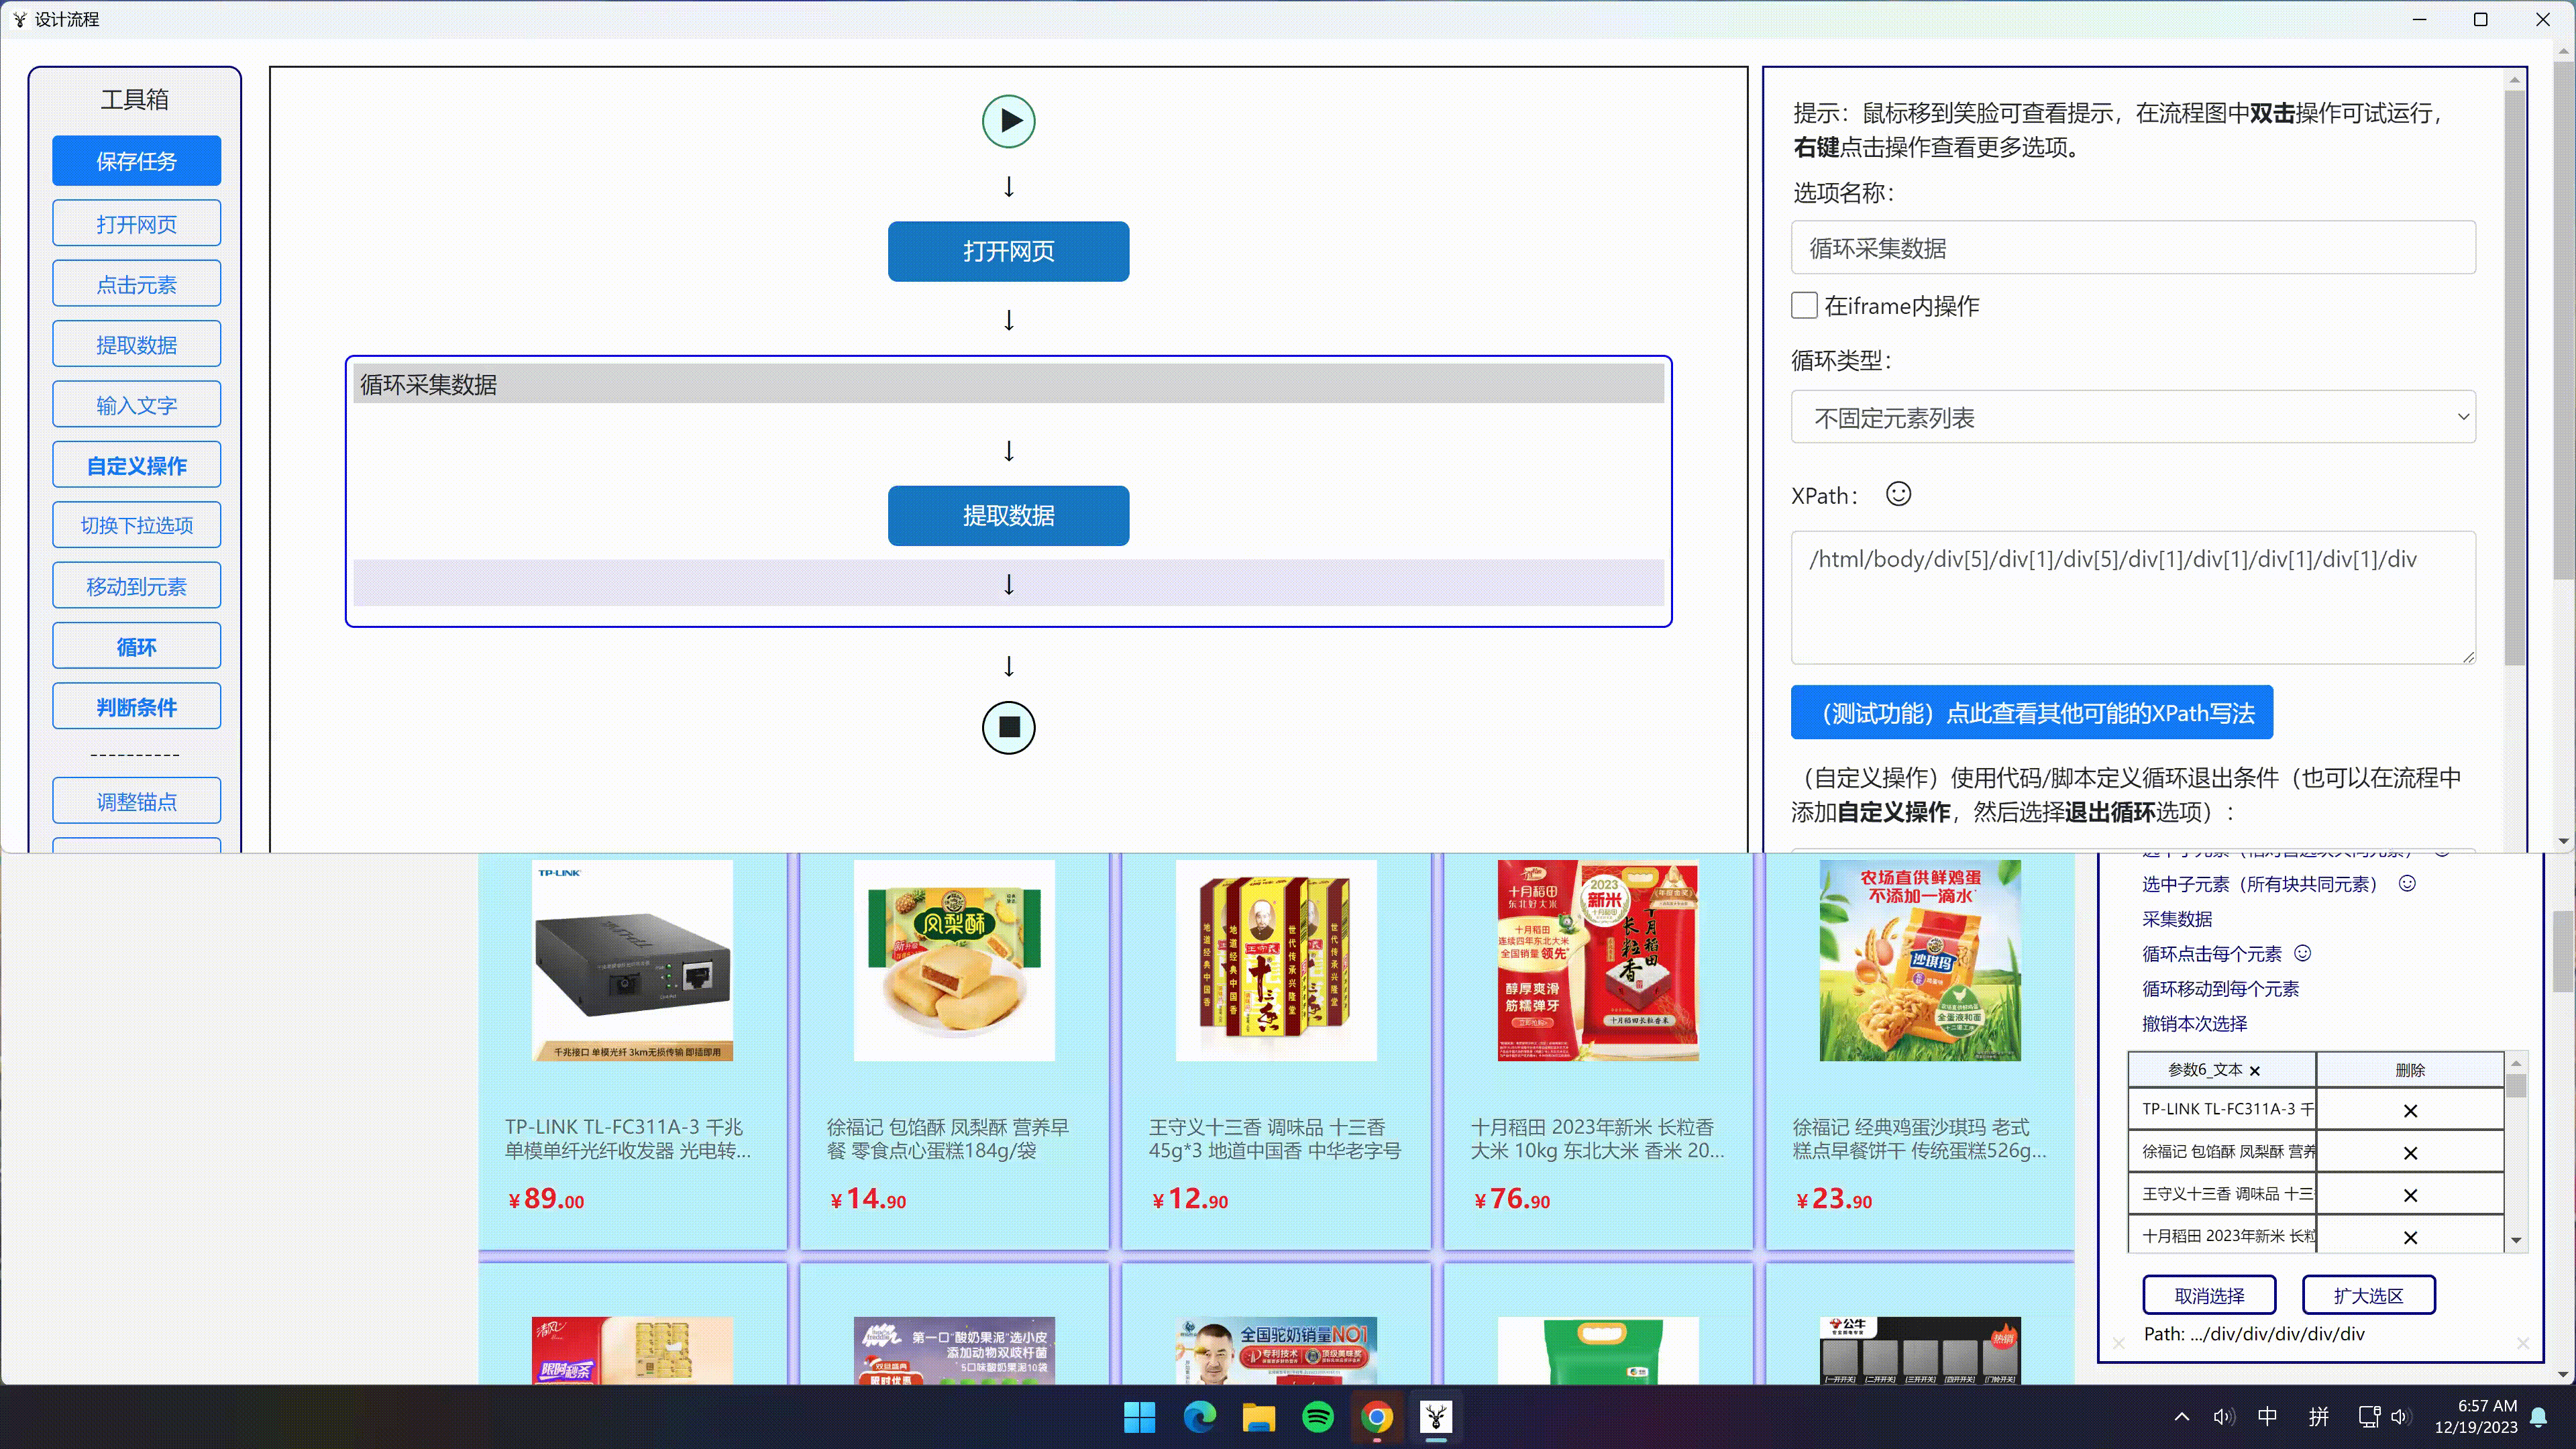
EasySpider
44.7KNaiboWang/EasySpider · JavaScriptEasySpider (易采集) is a visual, no-code web crawler and browser automation tool. You select elements on a webpage with clicks instead of writing code, and it designs and runs the scraping/testing task for you.
- 17

agent-browser
44.1Kvercel-labs/agent-browser · Rustagent-browser is a browser automation CLI purpose-built for AI agents, shipped as a fast native Rust binary that drives Chrome for scripted or agentic web interaction.
- 18
BettaFish
42.4K666ghj/BettaFish · PythonBettaFish (Chinese name 'Weiyu'/微舆) is a from-scratch multi-agent public opinion analysis system that monitors social media and large volumes of public comments, then produces reports to help break information bubbles and support decision-making.
- 19
maigret
39.2Ksoxoj/maigret · PythonMaigret is an OSINT command-line tool that builds a dossier on a person by checking for an account under a given username across thousands of websites and pulling together whatever profile info it finds, with no API keys required.
- 20
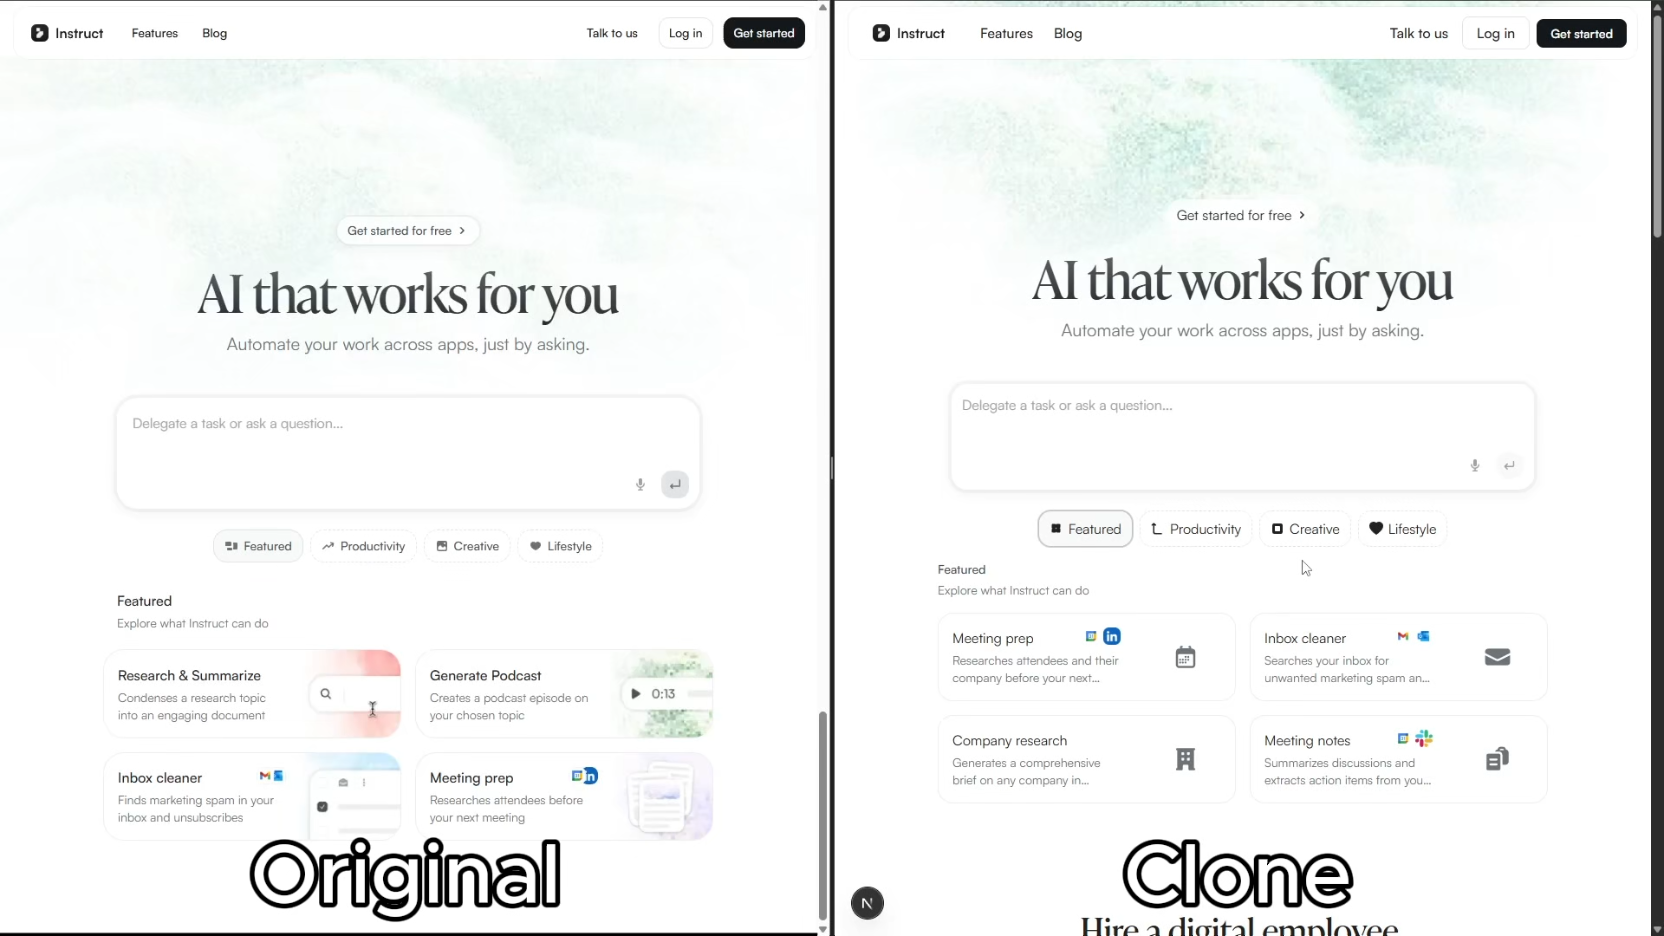
ai-website-cloner-template
36.9KJCodesMore/ai-website-cloner-template · TypeScriptA GitHub template that lets an AI coding agent clone any website into a working Next.js project just by giving it the URL.
- 21

browser
36.6Klightpanda-io/browser · ZigLightpanda is a headless browser built from scratch in Zig for AI agents and automation, not a fork of Chromium or WebKit.
- 22
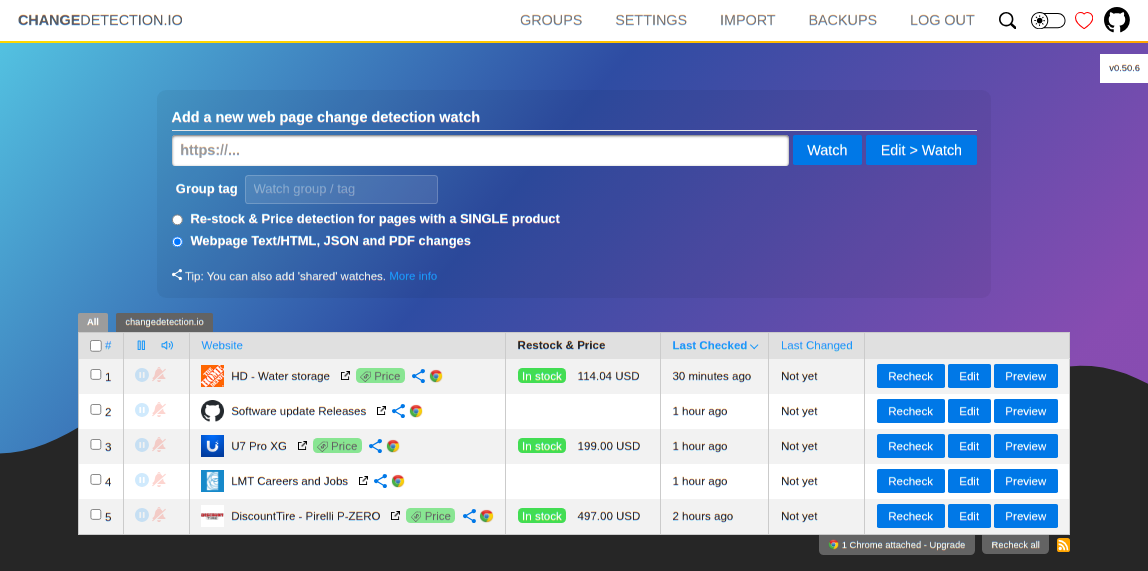
changedetection.io
35.1Kdgtlmoon/changedetection.io · Pythonchangedetection.io monitors websites for changes and sends you alerts when content updates, prices drop, items restock, or pages get defaced.
- 23

CloakBrowser
32.2KCloakHQ/CloakBrowser · PythonA stealth Chromium browser for web scraping and automation — a real Chromium binary with fingerprints patched at the C++ source level, wrapped as a drop-in Playwright/Puppeteer replacement so antibot systems score it as a normal browser.
- 24

MoneyPrinterV2
32.1KFujiwaraChoki/MoneyPrinterV2 · PythonMoneyPrinterV2 (MPV2) is a Python toolkit that automates ways to make money online, including a Twitter bot, a YouTube Shorts automator, Amazon affiliate marketing, and automated cold outreach to local businesses.
- 25
Scrapegraph-ai
31.8KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 26

awesome-python-cn
30.7Kjobbole/awesome-python-cn · MakefileThis is a curated Chinese-language directory of Python resources, covering web frameworks, web scraping, database drivers, data visualization, image processing, NLP, and many other categories.
- 27

cheerio
30.5Kcheeriojs/cheerio · TypeScriptCheerio is a fast, flexible library for parsing and manipulating HTML and XML. It implements a subset of the core jQuery API, so if you know jQuery selectors you already know most of it.
- 28

OpenCLI
30.3Kjackwener/OpenCLI · JavaScriptOpenCLI turns websites, browser sessions, Electron apps, and local tools into deterministic CLI commands — and lets AI agents drive your logged-in Chrome to navigate, fill forms, click, and extract data.
- 29

phantomjs
29.4Kariya/phantomjs · C++PhantomJS is a headless WebKit scriptable with JavaScript: a real browser engine that loads and manipulates web pages without any visible browser window.
- 30

obscura
29Kh4ckf0r0day/obscura · RustAn open-source headless browser engine written in Rust, built for web scraping and AI agent automation. It runs real JavaScript via an embedded V8 and supports the Chrome DevTools Protocol.
- 31
open-lovable
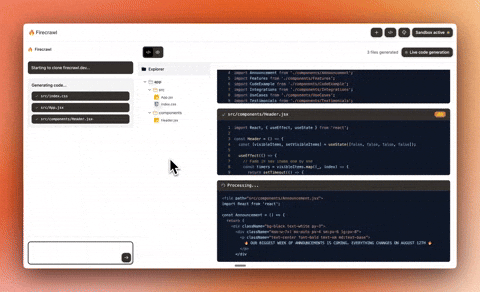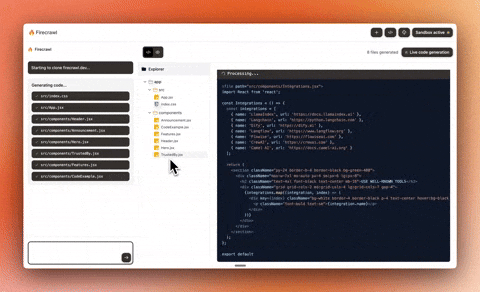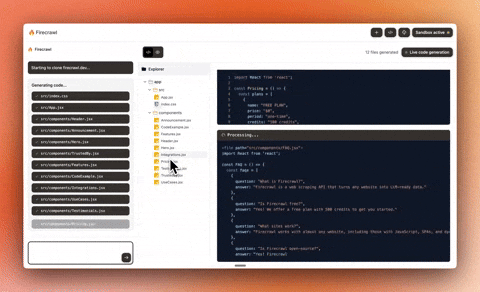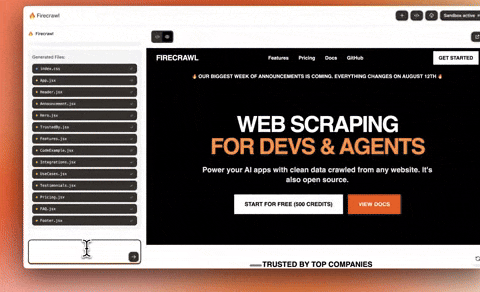
28.7Kfirecrawl/open-lovable · TypeScriptOpen Lovable is a chat-driven tool that lets you point it at any website and have an AI rebuild it as a modern React app in seconds. It's an open-source example app built by the Firecrawl team to show off AI-powered site cloning.
- 32

crawlee
26.2Kapify/crawlee · TypeScriptA web scraping and browser automation library for Node.js: you write crawlers in JavaScript or TypeScript to crawl sites, extract data (e.g. for AI, LLM and RAG pipelines) and save it to disk or cloud.
- 33

ChromeAppHeroes
25.9Kzhaoolee/ChromeAppHeroes · JavaScriptIt is a curated Chinese-language guide (手册) to excellent Chrome extensions, where each entry gets a short write-up explaining what the extension does and why it is useful.
- 34
stagehand
25.7Kbrowserbase/stagehand · TypeScriptStagehand is an SDK for building browser agents — code or AI agents that drive a real browser to extract data and interact with any website, with SDKs for TypeScript, Python, and Go.
- 35

colly
25.6Kgocolly/colly · GoColly is a scraping and crawling framework for Go: a clean interface for writing any kind of crawler, scraper or spider that extracts structured data from websites, for things like data mining, processing or archiving.
- 36
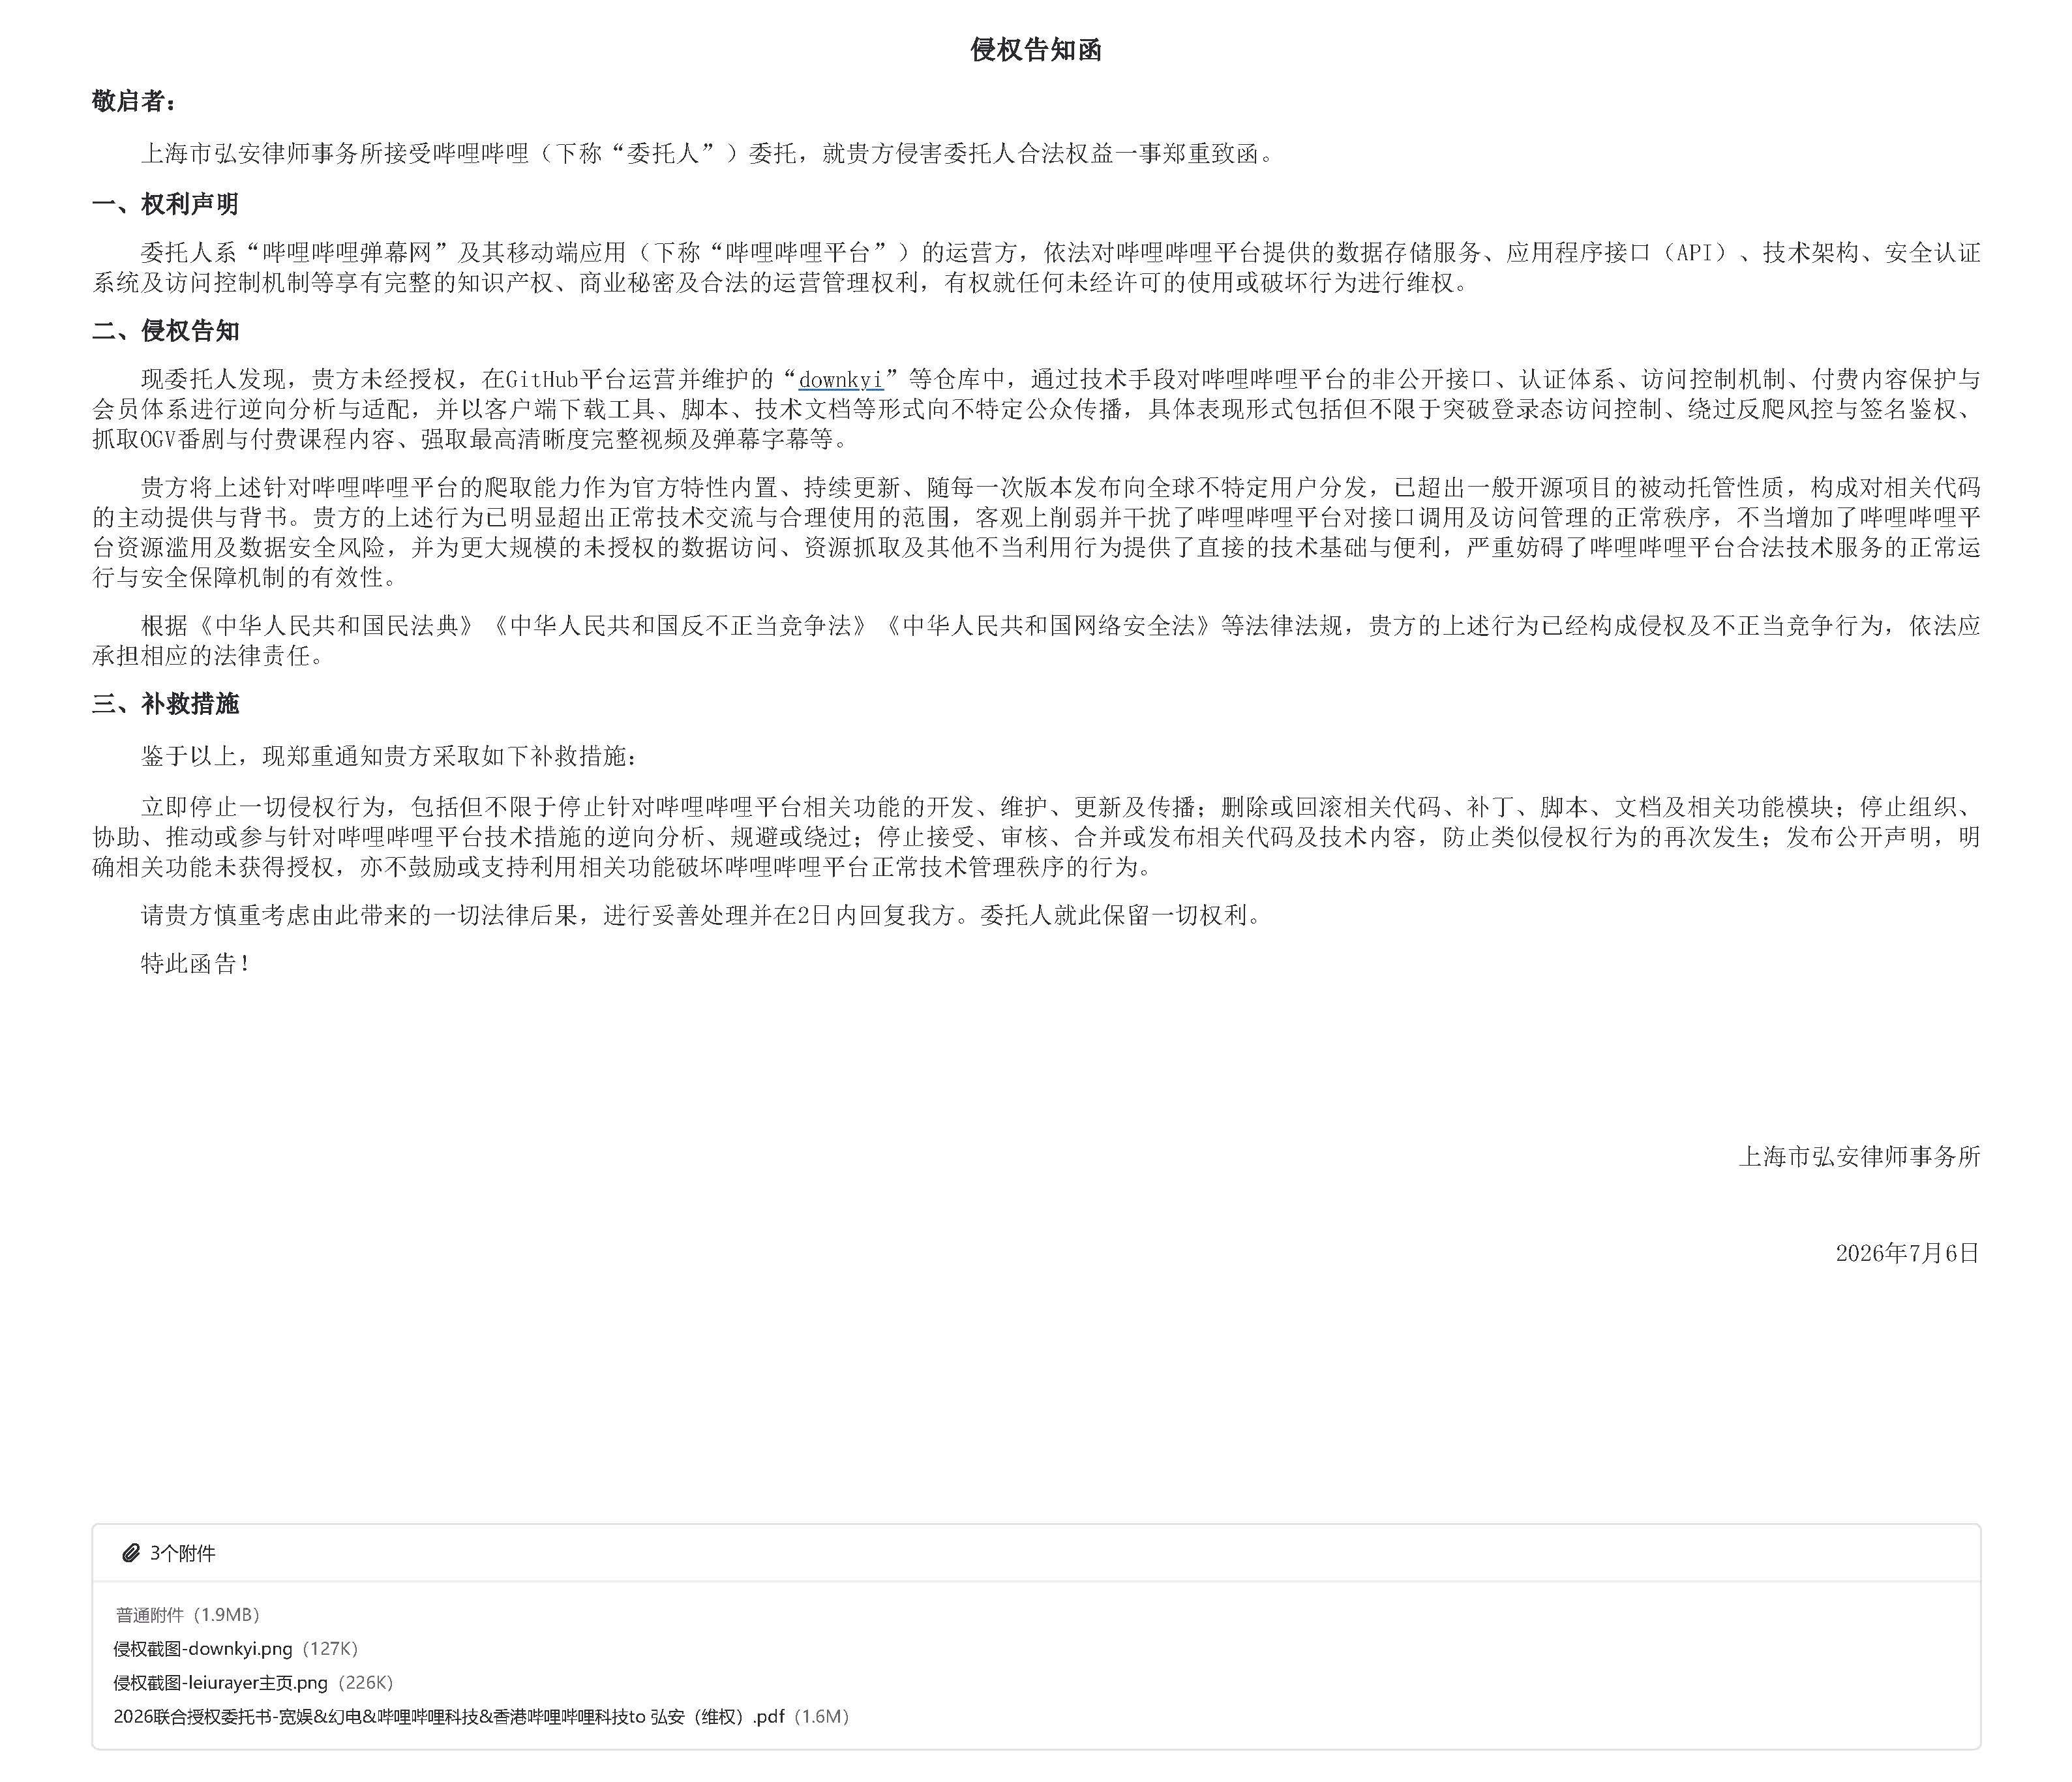
downkyi
24.4Kleiurayer/downkyiDownkyi (下载姬) was a desktop GUI tool for downloading videos, subtitles, and danmaku from the Chinese video platform Bilibili (B站) by reverse-engineering its private APIs and bypassing login authentication and anti-scraping protections. The repository has since been permanently shut down and is no longer maintained.
- 37
social-analyzer
24.3Kqeeqbox/social-analyzer · JavaScriptSocial-Analyzer is an OSINT tool that searches and correlates a person's profile across roughly 1000 social media sites and websites, available as a CLI, an API, and a web app.
- 38

proxy_pool
23.8Kjhao104/proxy_pool · PythonProxyPool is an open-source proxy IP pool for web spiders: it keeps harvesting free proxies from the web, checks that they work, stores the good ones in Redis and serves them to your crawler over a small HTTP API.
- 39
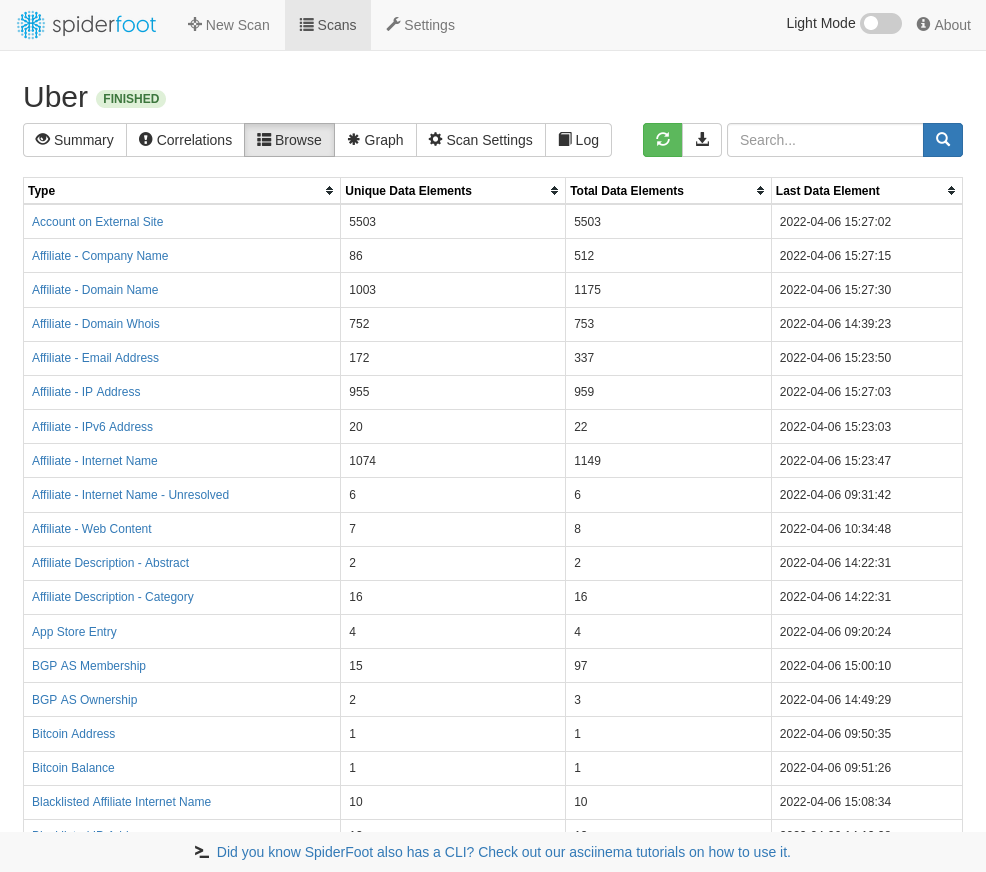
spiderfoot
23.5Ksmicallef/spiderfoot · PythonOpen source OSINT automation — it collects intelligence on a target for threat intel and attack surface mapping, whether you are doing red team recon or checking what your organisation has exposed.
- 40

gpt-crawler
22.4KBuilderIO/gpt-crawler · TypeScriptA crawler that scrapes a website (one or multiple URLs) and turns the pages into a knowledge file you can upload to OpenAI to build a custom GPT or assistant.
- 41
learn_python3_spider
22.2Kwistbean/learn_python3_spider · PythonA free Chinese-language tutorial series that teaches Python web scraping from zero — 30+ numbered lessons and mitmproxy guides, from first packet capture to distributed crawling, with source code for the practice projects.
- 42
automa
21.7KAutomaApp/automa · VueAutoma is a browser extension that automates your browser by connecting blocks into workflows — auto-fill forms, take screenshots, repeat tedious tasks, or scrape website data.
- 43

Douyin_TikTok_Download_API
20.7KEvil0ctal/Douyin_TikTok_Download_API · PythonA self-hosted data API for Douyin and TikTok: it pulls posts, author profiles, comments, search and playlists, downloads videos and image albums without a watermark, and exposes it all through a REST API, an MCP server, a CLI and a web console.
- 44

gallery-dl
20.1Kmikf/gallery-dl · Pythongallery-dl is a command-line program that downloads image galleries and collections from many image hosting sites.
- 45

python-spider
19.8KJack-Cherish/python-spider · PythonA collection of real-world Python web scraping projects, each targeting a specific Chinese site or app: Taobao, JD, NetEase Music, Bilibili, 12306 train tickets, Douyin, novel sites, manga sites and more.
- 46

deep-research
19.8Kdzhng/deep-research · TypeScriptAn AI-powered research assistant that digs into any topic iteratively: it combines search engines, web scraping, and large language models, refining its research direction as it goes.
- 47
moli
19.1Klexmount/moli · RustMoli is a production-ready headless browser for AI agents, built in Rust. It helps agents fetch and extract web pages, search the web, and automate browser tasks through the CLI, CDP, WebDriver Classic, or WebDriver BiDi.
- 48
maxun
17.9Kgetmaxun/maxun · TypeScriptMaxun is an open-source no-code web data platform that turns any website into structured, reliable data: it handles extraction, crawling, scraping, search and AI-powered data extraction.
- 49

katana
17.7Kprojectdiscovery/katana · GoKatana is a next-generation crawling and spidering framework from ProjectDiscovery: point it at URLs and it discovers endpoints, links and forms across a site.
- 50
Awesome-GitHub-Repo
17.3KWechat-ggGitHub/Awesome-GitHub-RepoA hand-curated Chinese-language collection of interesting and high-quality open-source GitHub projects, organized into thematic categories (AI, fun hacks, real-world practice projects, tools, learning resources) rather than by programming language.
- 51

pyspider
16.8Kbinux/pyspider · Pythonpyspider is a powerful web spider (crawler) system written in Python: you write crawling scripts in Python and manage your scraping projects through a built-in web interface.
- 52
SurfSense
16.5KMODSetter/SurfSense · PythonAn open-source, self-hostable NotebookLM alternative: agents pull structured data from the live web (Reddit, YouTube, Amazon and more) through connectors, and a built-in knowledge base keeps every finding searchable with citations.
- 53

node-lessons
16.4Kalsotang/node-lessons · JavaScriptA free, hands-on Node.js course (titled 'Node.js 包教不包会' — roughly 'Node.js: Taught, Not Guaranteed') by alsotang, built as a series of practical lessons rather than a textbook.
- 54

twint
16.4Ktwintproject/twint · PythonTwint is a Python tool for scraping Twitter data — tweets, followers, following, likes and more — without using Twitter's official API, so it isn't bound by API limits or sign-up requirements.
- 55

FreshRSS
16.3KFreshRSS/FreshRSS · PHPFreshRSS is a free, self-hosted RSS feed aggregator: it pulls all your news feeds into one web interface. It is lightweight and customizable, supports multiple users (with an anonymous reading mode), and ships both a client API and a CLI.
- 56

ChineseBQB
16.3Kzhaoolee/ChineseBQB · PythonChineseBQB is a huge open collection of Chinese internet memes and sticker images (emoji packs), organized into themed folders covering pop culture, celebrities, games, anime, and historical internet memes, plus an online tool to search and share them.
- 57
awesome-python-login-model
16.2KKr1s77/awesome-python-login-model · PythonA collection of Python 3 example scripts that simulate logging into popular websites — mostly Chinese ones like Zhihu, Bilibili, Weibo, JD (JingDong) and Taobao, plus Facebook and GitHub — together with a few simple crawlers. It is meant as a learning resource for login simulation and scraping techniques.
- 58

FlareSolverr
15.9KFlareSolverr/FlareSolverr · PythonIt is a proxy server that bypasses Cloudflare and DDoS-GUARD protection: it loads the site in a real Chrome browser, waits out the challenge, and hands back the HTML and cookies your own HTTP client can reuse.
- 59

tushare
15.5Kwaditu/tushare · PythonTuShare is a Python utility for crawling, cleaning and storing historical and realtime data for China's stock and futures markets, built for quant analysts and anyone learning data analysis.
- 60
headless-recorder
15.3Kcheckly/headless-recorder · JavaScriptHeadless Recorder is a Chrome extension that records your clicks and typing in the browser and generates a ready-to-run Playwright or Puppeteer script from them.
- 61

extensions
15.2Kkeiyoushi/extensions · HTMLThis is an extension repository that supplies manga source plugins for the Mihon Android manga reader app and its compatible forks, letting the app pull manga content from many different websites.
- 62

newspaper
15.2Kcodelucas/newspaper · PythonNewspaper3k is a Python 3 library that downloads, parses, and extracts the article text, authors, publish date, top image, and keywords/summary from news articles and news sites.
- 63

Skill_Seekers
15.2Kyusufkaraaslan/Skill_Seekers · PythonSkill Seekers converts documentation sites, GitHub repos, PDFs, videos, notebooks, wikis and other sources into structured knowledge assets, ready to power AI Skills (Claude, Gemini, OpenAI), RAG pipelines, and AI coding assistants.
- 64

goquery
15KPuerkitoBio/goquery · Gogoquery is a Go library that brings jQuery-like syntax and features to HTML parsing and manipulation, built on Go's net/html package and the cascadia CSS selector library.
- 65

dirsearch
15Kmaurosoria/dirsearch · PythonDirsearch is an advanced command-line web path brute-forcer used to discover hidden files and directories on websites for security testing.
- 66

ai-goofish-monitor
15KUsagi-org/ai-goofish-monitor · PythonA self-hosted monitoring system for Xianyu (闲鱼, China's largest secondhand marketplace) that scrapes listings with Playwright and uses AI to analyze and filter products in real time or on a schedule, with a full web management UI.
- 67
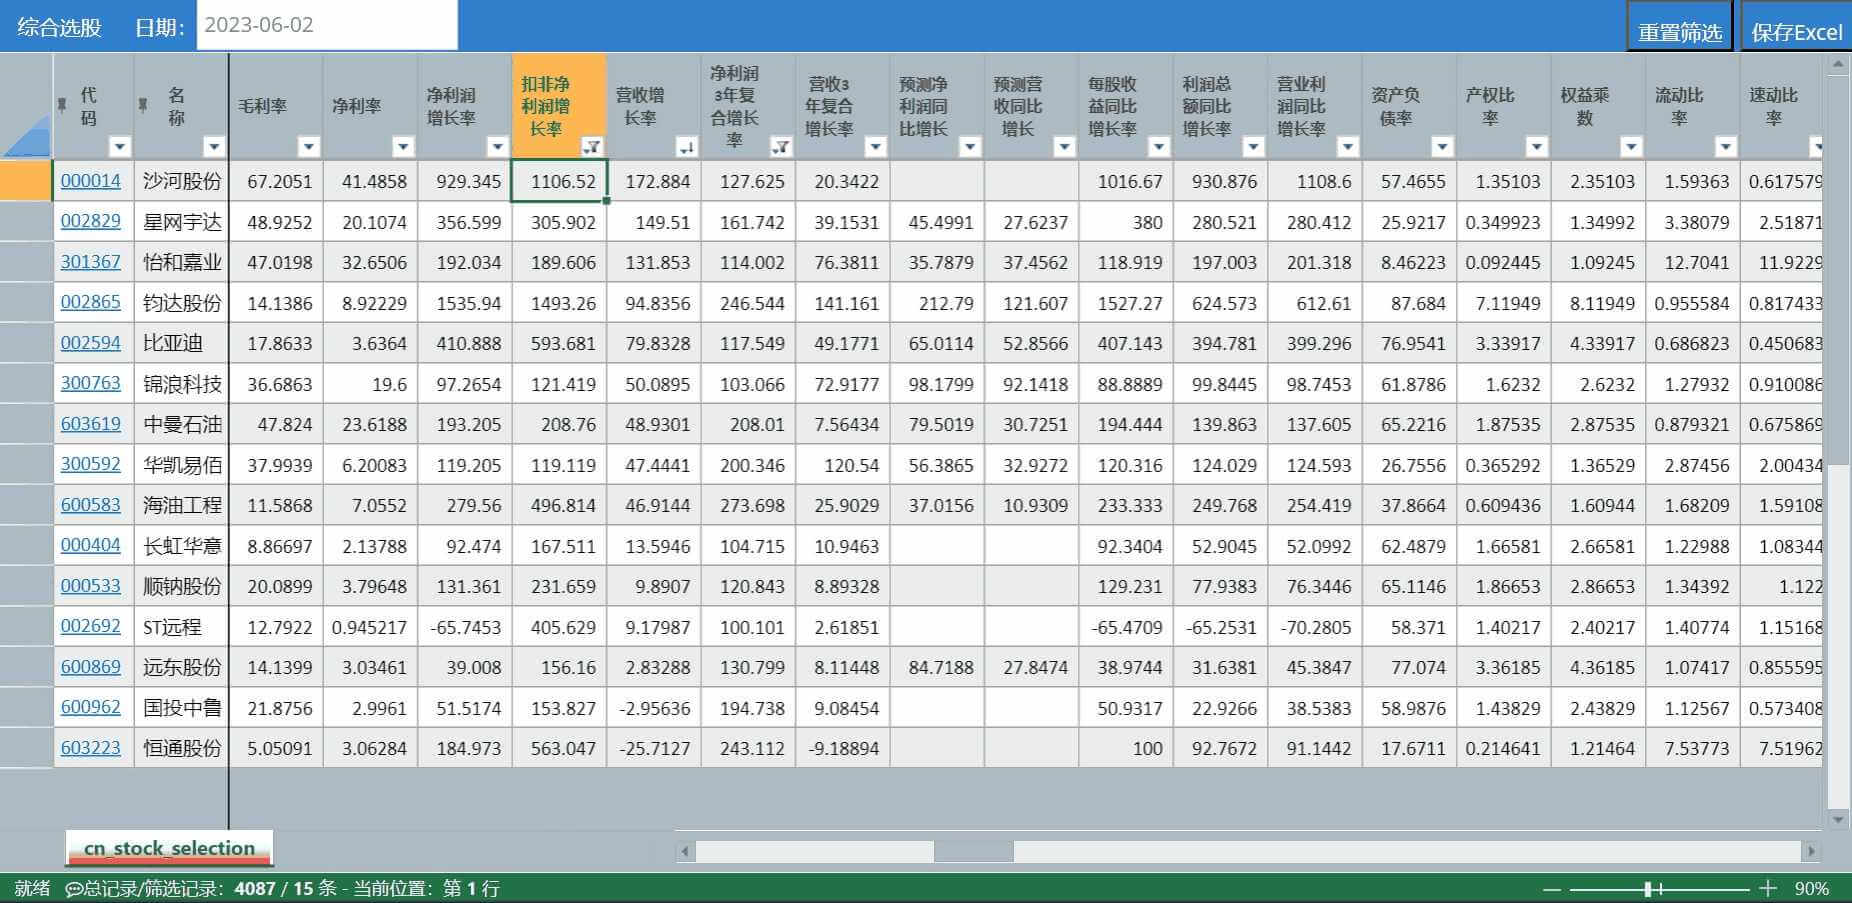
stock
14.8Kmyhhub/stock · PythonIt is a Python-based A-share stock quant system that scrapes daily stock and ETF data, computes technical indicators and chip (cost) distribution, recognizes 61 K-line patterns, runs multi-factor stock screening and strategies, backtests them, and can place automated trades, all viewable from a web UI on PC or mobile.
- 68

examples-of-web-crawlers
14.7Kshengqiangzhang/examples-of-web-crawlers · HTMLA collection of beginner-friendly Python web-scraping examples, mostly targeting Chinese sites like Taobao, Tmall, WeChat, WeChat Reading, Douban and QQ.
- 69

gron
14.5Ktomnomnom/gron · Gogron transforms JSON into discrete assignments (one path-value pair per line) so you can grep, sed, and diff JSON with normal command-line text tools.
- 70
nanobrowser
14.1Knanobrowser/nanobrowser · TypeScriptNanobrowser is an open-source Chrome extension that uses a multi-agent AI system to automate web browsing tasks, acting as a free alternative to OpenAI Operator.
- 71

browserless
13.8Kbrowserless/browserless · TypeScriptBrowserless is a service for running headless Chrome, Firefox, and Webkit browsers in Docker so you can drive Puppeteer/Playwright automation scripts without managing browser infrastructure yourself.
- 72

requests-html
13.8Kpsf/requests-html · PythonRequests-HTML is a Python library for parsing and scraping HTML pages, built on top of the Requests library, adding jQuery-style CSS selectors, XPath support, and full JavaScript rendering.
- 73

show-me-the-code
13.7KYixiaohan/show-me-the-codeA collection of practical Python exercises ('one small program every day') by Yixiaohan, covering real-world tasks like generating activation codes, scraping images, resizing photos, parsing HTML, encrypting passwords, and building small web apps.
- 74

instaloader
13.6Kinstaloader/instaloader · PythonInstaloader downloads pictures and videos from Instagram profiles, hashtags, stories, feeds, and saved media, along with captions, comments, geotags, and other metadata.
- 75

chromedp
13.3Kchromedp/chromedp · Gochromedp is a Go library that drives any browser supporting the Chrome DevTools Protocol — a faster, simpler way to automate Chrome from Go code, with no external dependencies.
- 76

Photon
13.3Ks0md3v/Photon · PythonPhoton is a fast web crawler built for OSINT (open-source intelligence) gathering, extracting URLs, emails, social media accounts, secret keys, subdomains and more while it crawls a target site.
- 77

chromeless
13.2Kschickling/chromeless · TypeScriptChromeless is a TypeScript library for automating Chrome from code: open sites, click elements, fill forms, take screenshots. Note that it is now deprecated in favor of Puppeteer.
- 78
SeleniumBase
13.1Kseleniumbase/SeleniumBase · PythonSeleniumBase is an all-in-one Python framework for browser automation — web crawling, testing, scraping, and stealth. Its CDP Mode bypasses bot-detection in Chromium-based browsers, and a Stealthy Playwright Mode extends that to Playwright.
- 79

tutorials
13.1KMorvanZhou/tutorials · PythonThis is a large collection of beginner-friendly Python tutorials by MorvanZhou (莫烦Python) covering machine learning, deep learning, reinforcement learning and related tools, each tutorial paired with a video lesson.
- 80

XHS-Downloader
13KJoeanAmier/XHS-Downloader · JavaScriptXHS-Downloader is a tool for extracting share links and downloading posts (images, videos, live photos and covers) from Xiaohongshu (XiaoHongShu / RedNote).
- 81
undetected-chromedriver
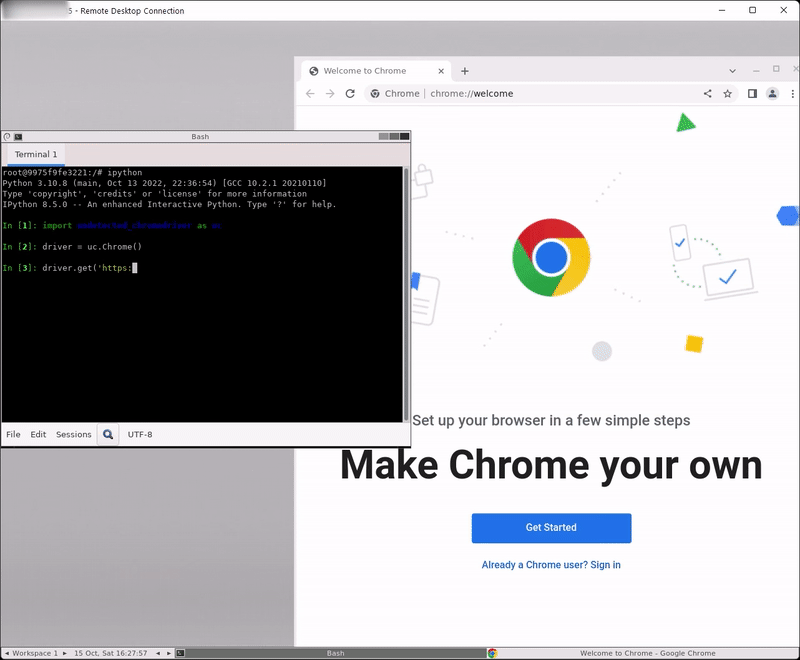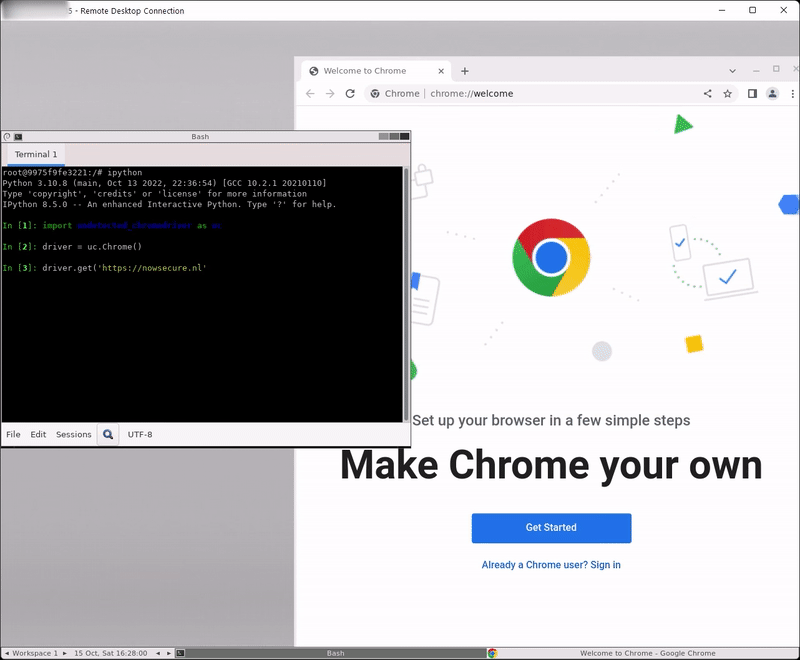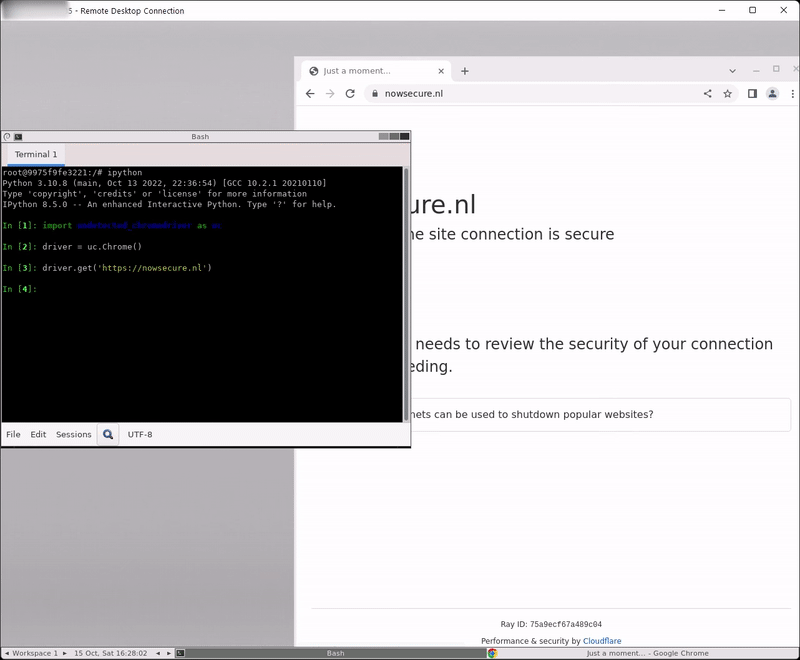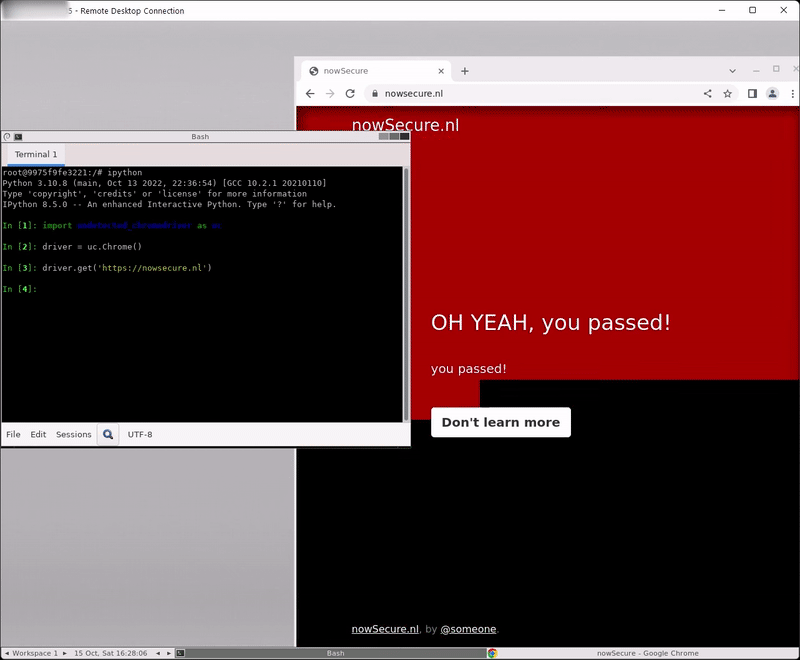
12.9Kultrafunkamsterdam/undetected-chromedriver · PythonIt is a patched Selenium Chromedriver for Python that automatically downloads and modifies the chromedriver binary so it evades anti-bot systems like Distil, Imperva, DataDome and Cloudflare IUAM.
- 82

nsfw_data_scraper
12.6Kalex000kim/nsfw_data_scraper · ShellThis is a collection of shell scripts that scrapes and aggregates tens of thousands of images across 5 categories (porn, hentai, sexy, neutral, drawings) to build a labeled dataset for training an NSFW image classifier.
- 83

DrissionPage
12.5Kg1879/DrissionPage · PythonDrissionPage is a Python web automation tool that can control a browser, send and receive raw HTTP packets, or combine both in one workflow, giving you browser automation convenience together with requests-level efficiency.
- 84

Yuedu
12.5KXIU2/YueduThis is a personal collection of 'book sources' (JSON parsing rule files) for the Chinese novel-reading app '阅读' (Legado). The sources tell the app how to search, list chapters, and extract text from various free novel websites.
- 85
crawlab
12.3Kcrawlab-team/crawlab · GoCrawlab is an open-source distributed web crawler management platform: you upload spiders written in any language, run them across a cluster of machines, and manage tasks, schedules and results from a web UI.
- 86
reader
12.2Kjina-ai/reader · TypeScriptReader is a service that converts any URL into clean, LLM-friendly markdown by simply prefixing it with https://r.jina.ai/, and it also offers a web-search endpoint at https://s.jina.ai/ that returns readable content for the top search results instead of just titles and snippets.
- 87

PythonPark
11.9KJack-Cherish/PythonPark · PythonA free, Chinese-language self-study guide to programming built around Python and AI: curated tutorials and videos on data structures, machine learning, deep learning, web scraping, interviews, and programmer life.
- 88

chinese-xinhua
11.7Kpwxcoo/chinese-xinhua · PythonA Chinese Xinhua Dictionary database (中华新华字典数据库): four JSON datasets with 31,648 idioms, 264,434 words, 16,142 characters and 14,032 xiehouyu (two-part allegorical sayings), collected from the web.
- 89

webmagic
11.7Kcode4craft/webmagic · JavaWebMagic is a scalable web crawler framework for Java. It covers the whole crawler lifecycle — downloading, URL management, content extraction and persistence — to simplify building a specific crawler.
- 90
camofox-browser
11.6Kjo-inc/camofox-browser · JavaScriptCamofox is a stealth headless browser server for AI agents: it wraps the Camoufox engine (a C++-patched Firefox) in a REST API that bypasses Cloudflare and bot detection, acting as a drop-in replacement for Puppeteer/Playwright.
- 91
apify-mcp-server
11.6Kapify/apify-mcp-server · TypeScriptThe Apify MCP Server lets AI agents and assistants extract data from websites like social media, search engines, maps, and e-commerce sites by giving them access to thousands of ready-made scrapers and automation tools from the Apify Store.
- 92

jsoup
11.4Kjhy/jsoup · Javajsoup is an open-source Java library for working with real-world HTML and XML: it fetches URLs, parses them to a DOM, and lets you extract and manipulate data.
- 93
magnetW
11.3Kxiandanin/magnetW · JavaScriptmagnetW is a desktop app (built with Electron and Vue) for searching magnet/torrent links; it scrapes results from source sites for personal research use. The project is now deprecated and no longer maintained.
- 94
claude-engineer
11.2KDoriandarko/claude-engineer · PythonClaude Engineer is a self-improving AI assistant framework built on Claude 3.5 Sonnet that can generate and manage its own tools during a conversation, expanding its own capabilities over time. It ships with both a CLI and a web interface for software development tasks.
- 95

geo-seo-claude
11.1Kzubair-trabzada/geo-seo-claude · PythonA GEO-first SEO skill for Claude Code that audits and optimizes websites for AI-powered search engines like ChatGPT, Claude, Perplexity, Gemini, and Google AI Overviews, alongside traditional SEO.
- 96
nopecha-extension
11KNopeCHALLC/nopecha-extensionNopeCHA is a browser extension that automatically detects and solves CAPTCHAs on any page, powered by multimodal AI running through the NopeCHA API platform.
- 97

Python
10.9Kinjetlee/Python · PythonA personal grab-bag of standalone Python scripts and short tutorials the author wrote alongside blog posts: web scraping, WeChat official account development, Excel automation, SQL practice, and small utility hacks like remote shutdown.
- 98
bbot
10.7Kblacklanternsecurity/bbot · PythonBBOT is a recursive internet scanner for hackers — it automates recon, bug bounty work and attack surface management (ASM), inspired by Spiderfoot.
- 99
pinchtab
10.4Kpinchtab/pinchtab · GoAn HTTP server that gives AI agents direct control over Chrome: they navigate pages, extract structured content and interact with the DOM through a small local daemon instead of raw screenshots.
- 100
avbook
10.1Kguyueyingmu/avbook · PHPA self-hosted AV (Japanese adult video) library: a PHP/Laravel web app with built-in crawlers for avmoo, javbus and javlibrary that builds a local, searchable database of movies and magnet links.
Showing the 100 most-starred of 158. See every one in the catalog.
Related topics
Often tagged together