Topics / #scraper
Scraper projects on GitHub
Tools for extracting structured data from websites
As of , the most-starred Scraper projects on GitHub are firecrawl (192.2K stars), crawl4ai (85.7K stars) and MediaCrawler (67K stars). GitHub.Locker tracks 42 Scraper repositories with 990.1K stars combined. The fastest-growing on October 16 was firecrawl, with +334 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +334
firecrawl
firecrawl/firecrawl · ★ 192.2KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +159
apify-mcp-server
apify/apify-mcp-server · ★ 11.6KThe Apify MCP Server lets AI agents and assistants extract data from websites like social media, search engines, maps, and e-commerce sites by giving them access to thousands of ready-made scrapers and automation tools from the Apify Store.
 +60
MediaCrawler
NanmiCoder/MediaCrawler · ★ 67KA multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
 +55
crawl4ai
unclecode/crawl4ai · ★ 85.7KCrawl4AI is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG pipelines, AI agents, and data extraction workflows.
The all-time top
42 projects · by stars
- 192.2K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 85.7K#2 · unclecode/crawl4ai
crawl4ai
Crawl4AI is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG pipelines, AI agents, and data extraction workflows.
- 67K#3 · NanmiCoder/MediaCrawler
MediaCrawler
A multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
- 4

scrapy
64.9Kscrapy/scrapy · PythonScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 5

huginn
50.1Khuginn/huginn · RubyHuginn lets you build 'agents' that watch the web for events and act on your behalf — a self-hosted, hackable alternative to IFTTT or Zapier.
- 6
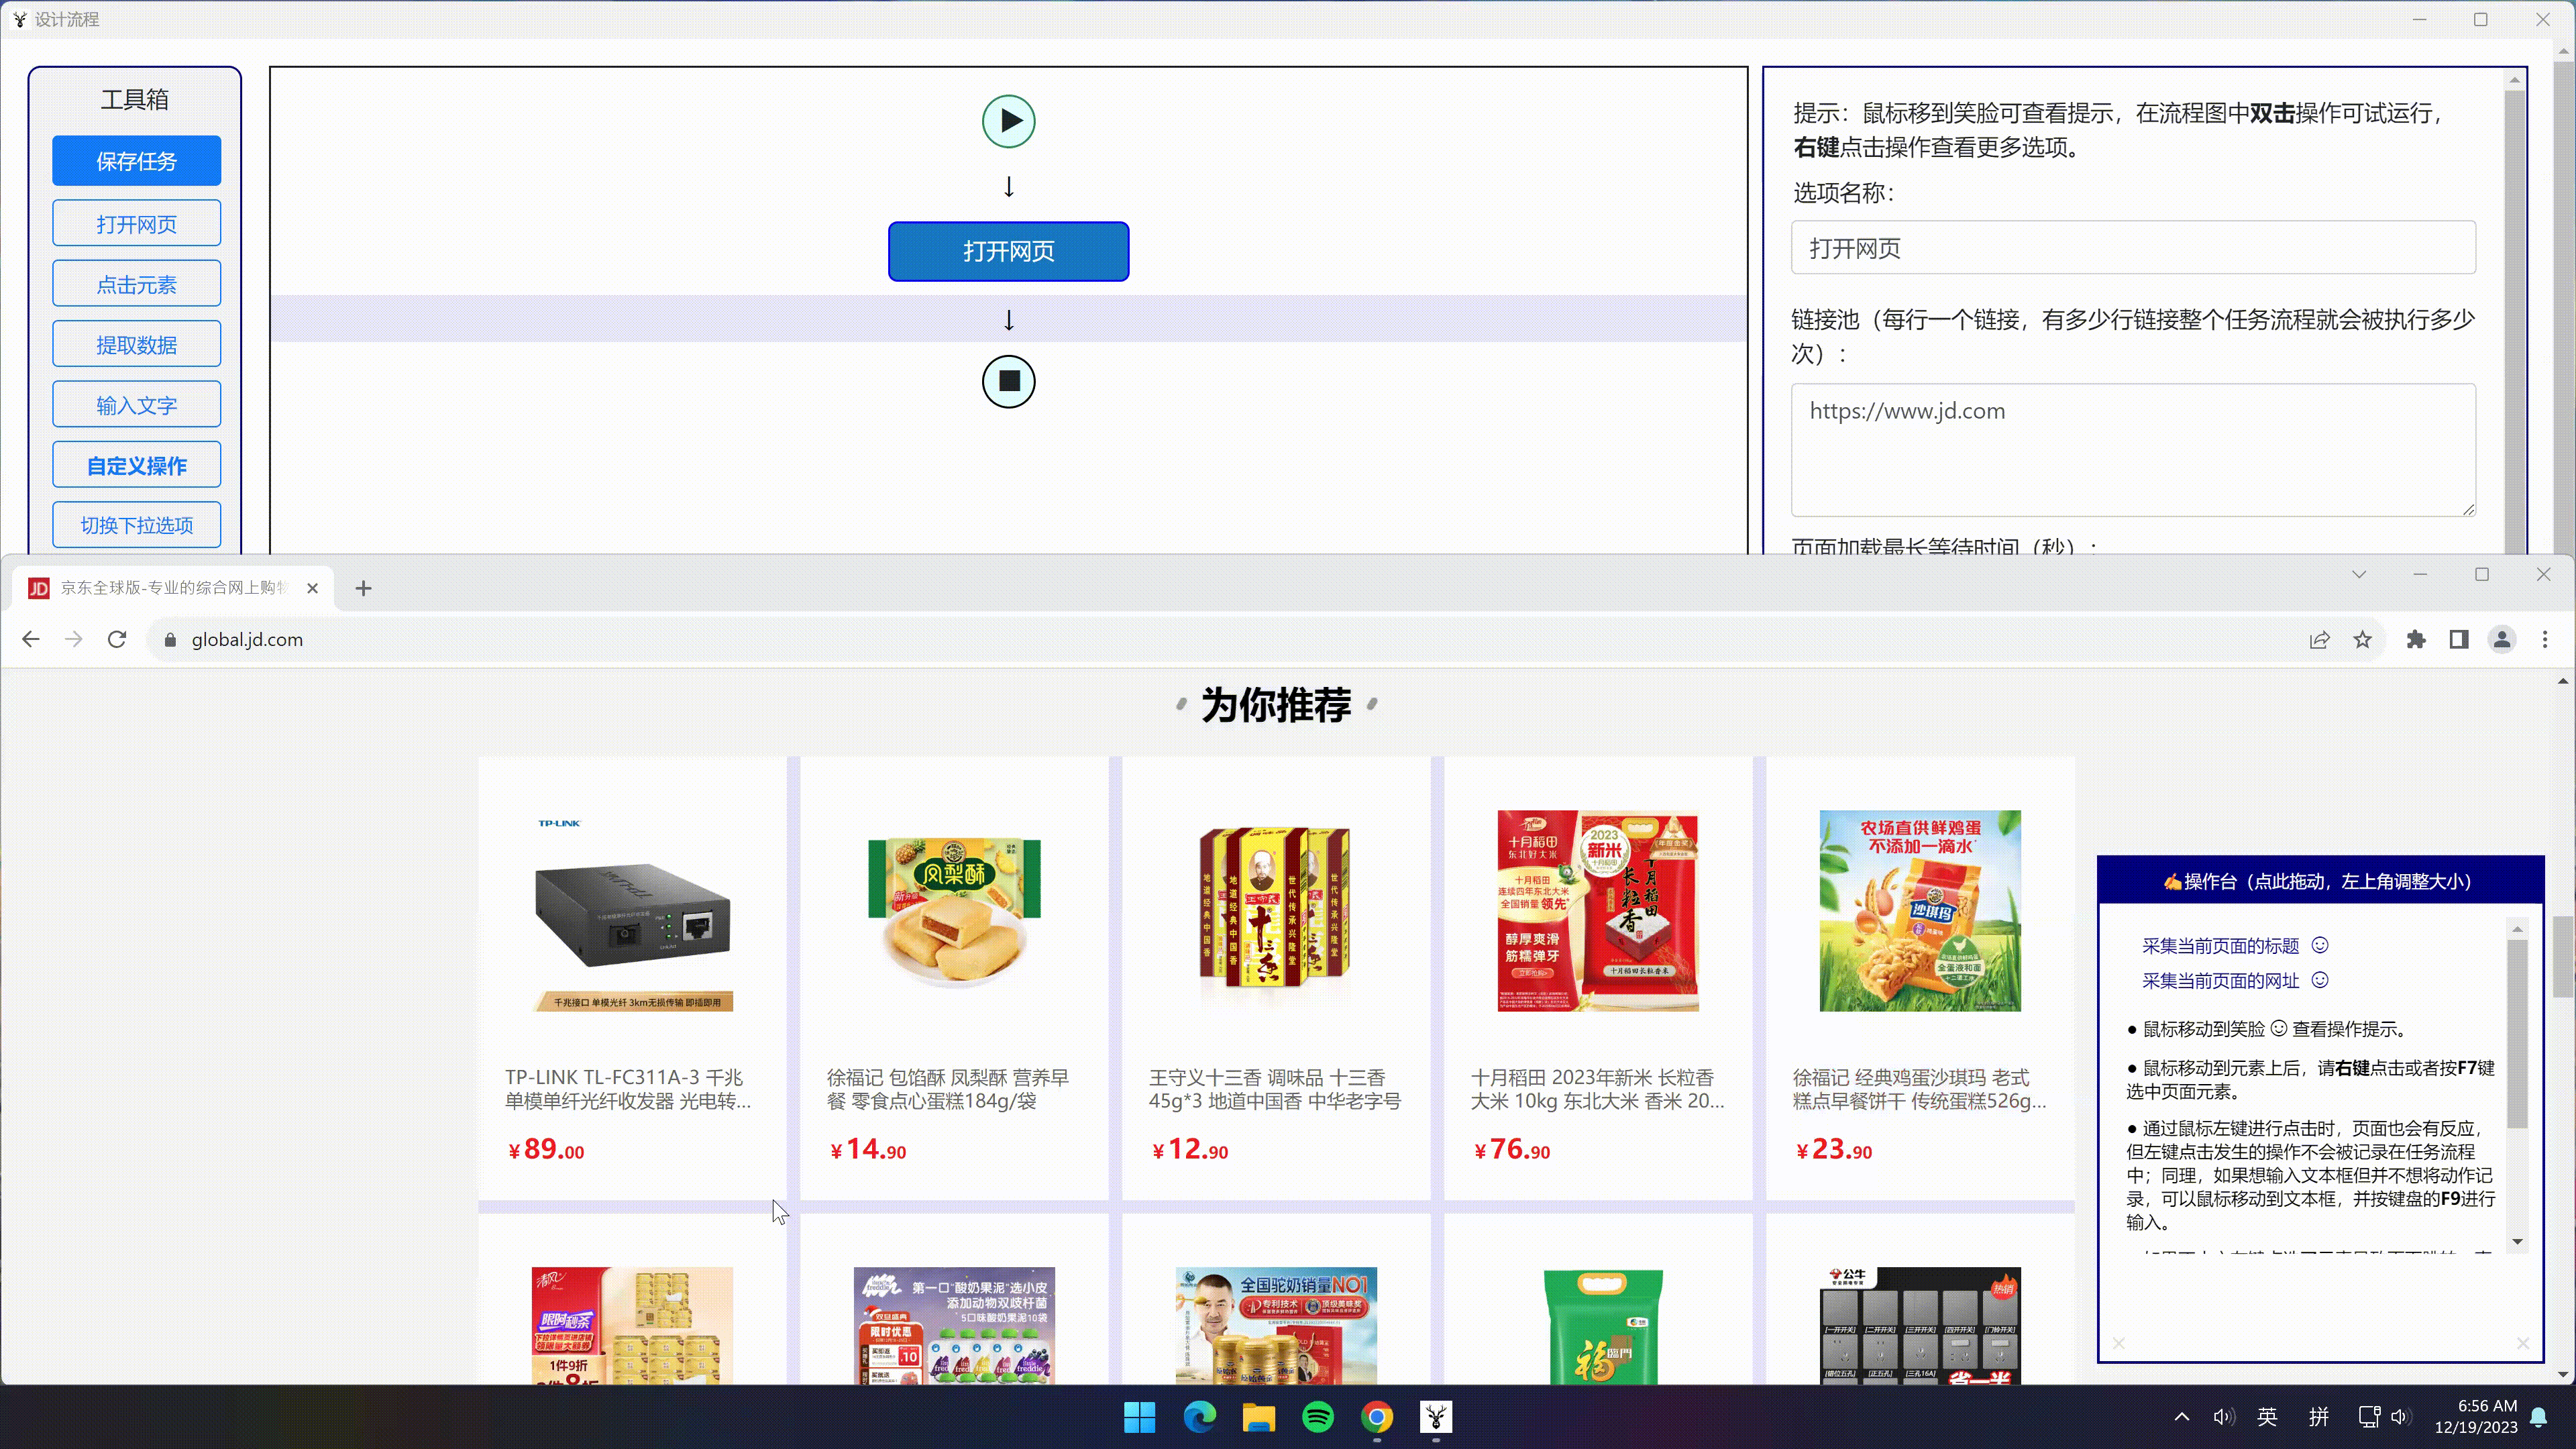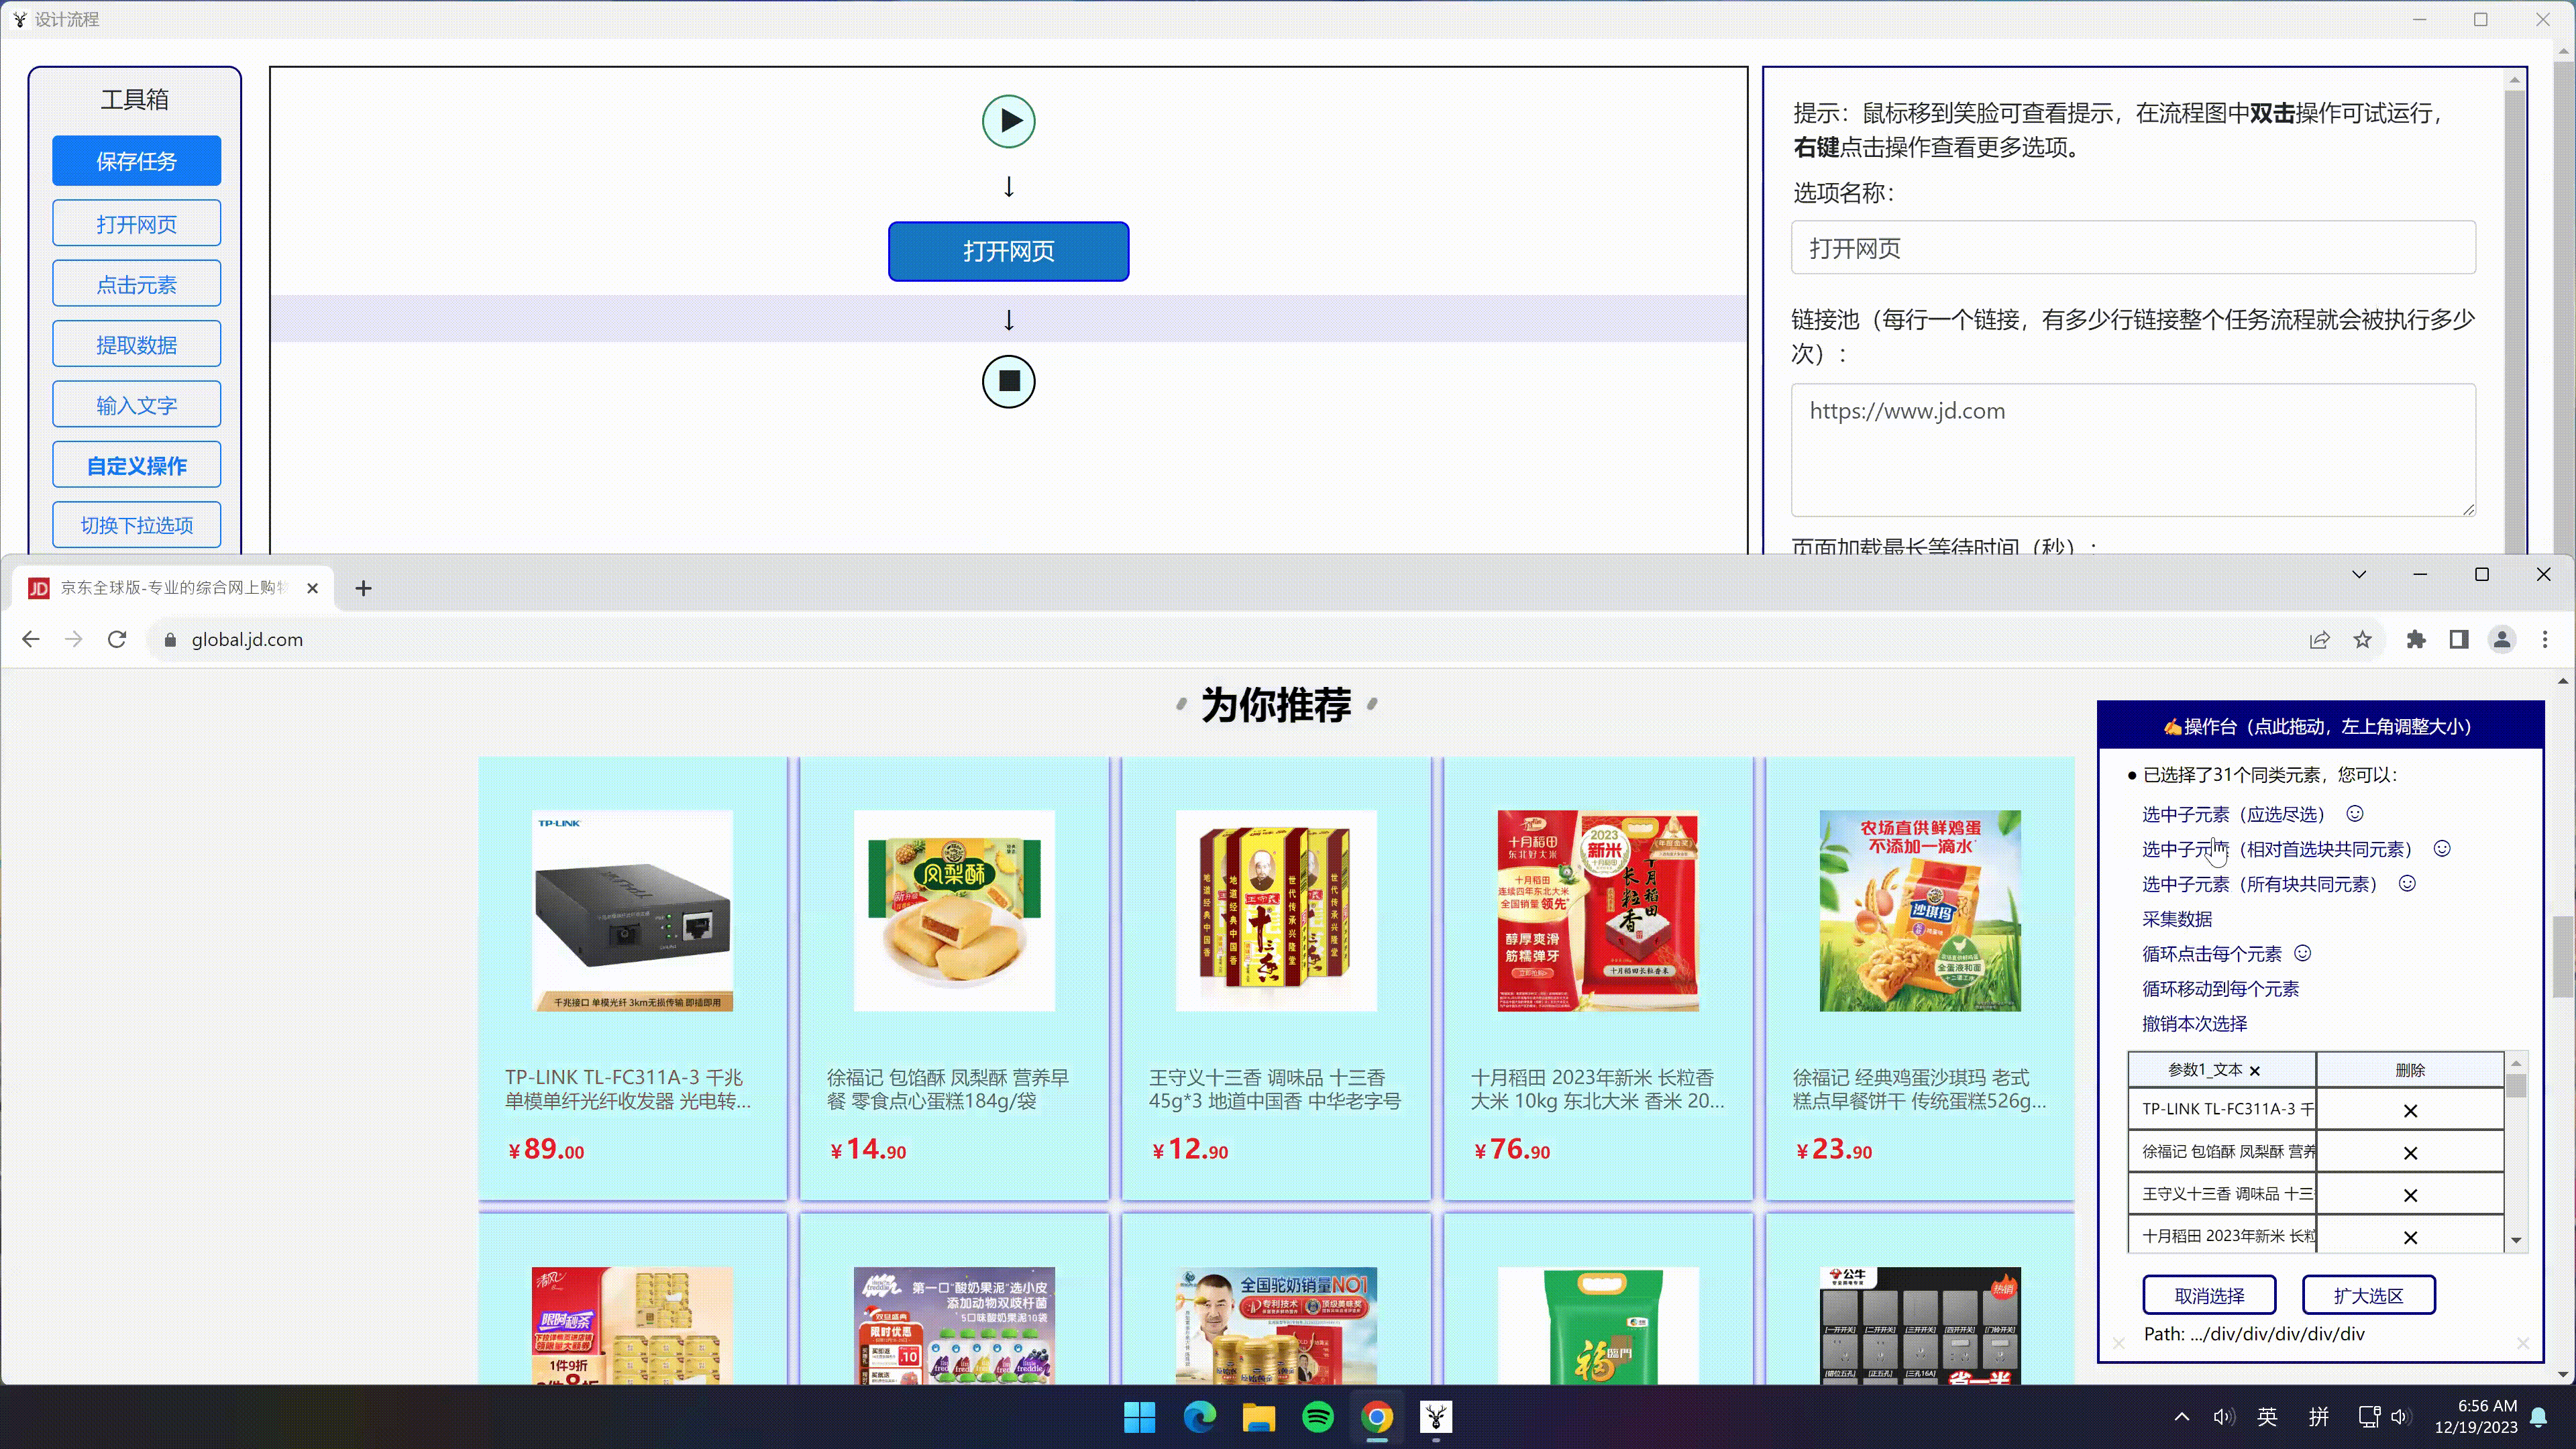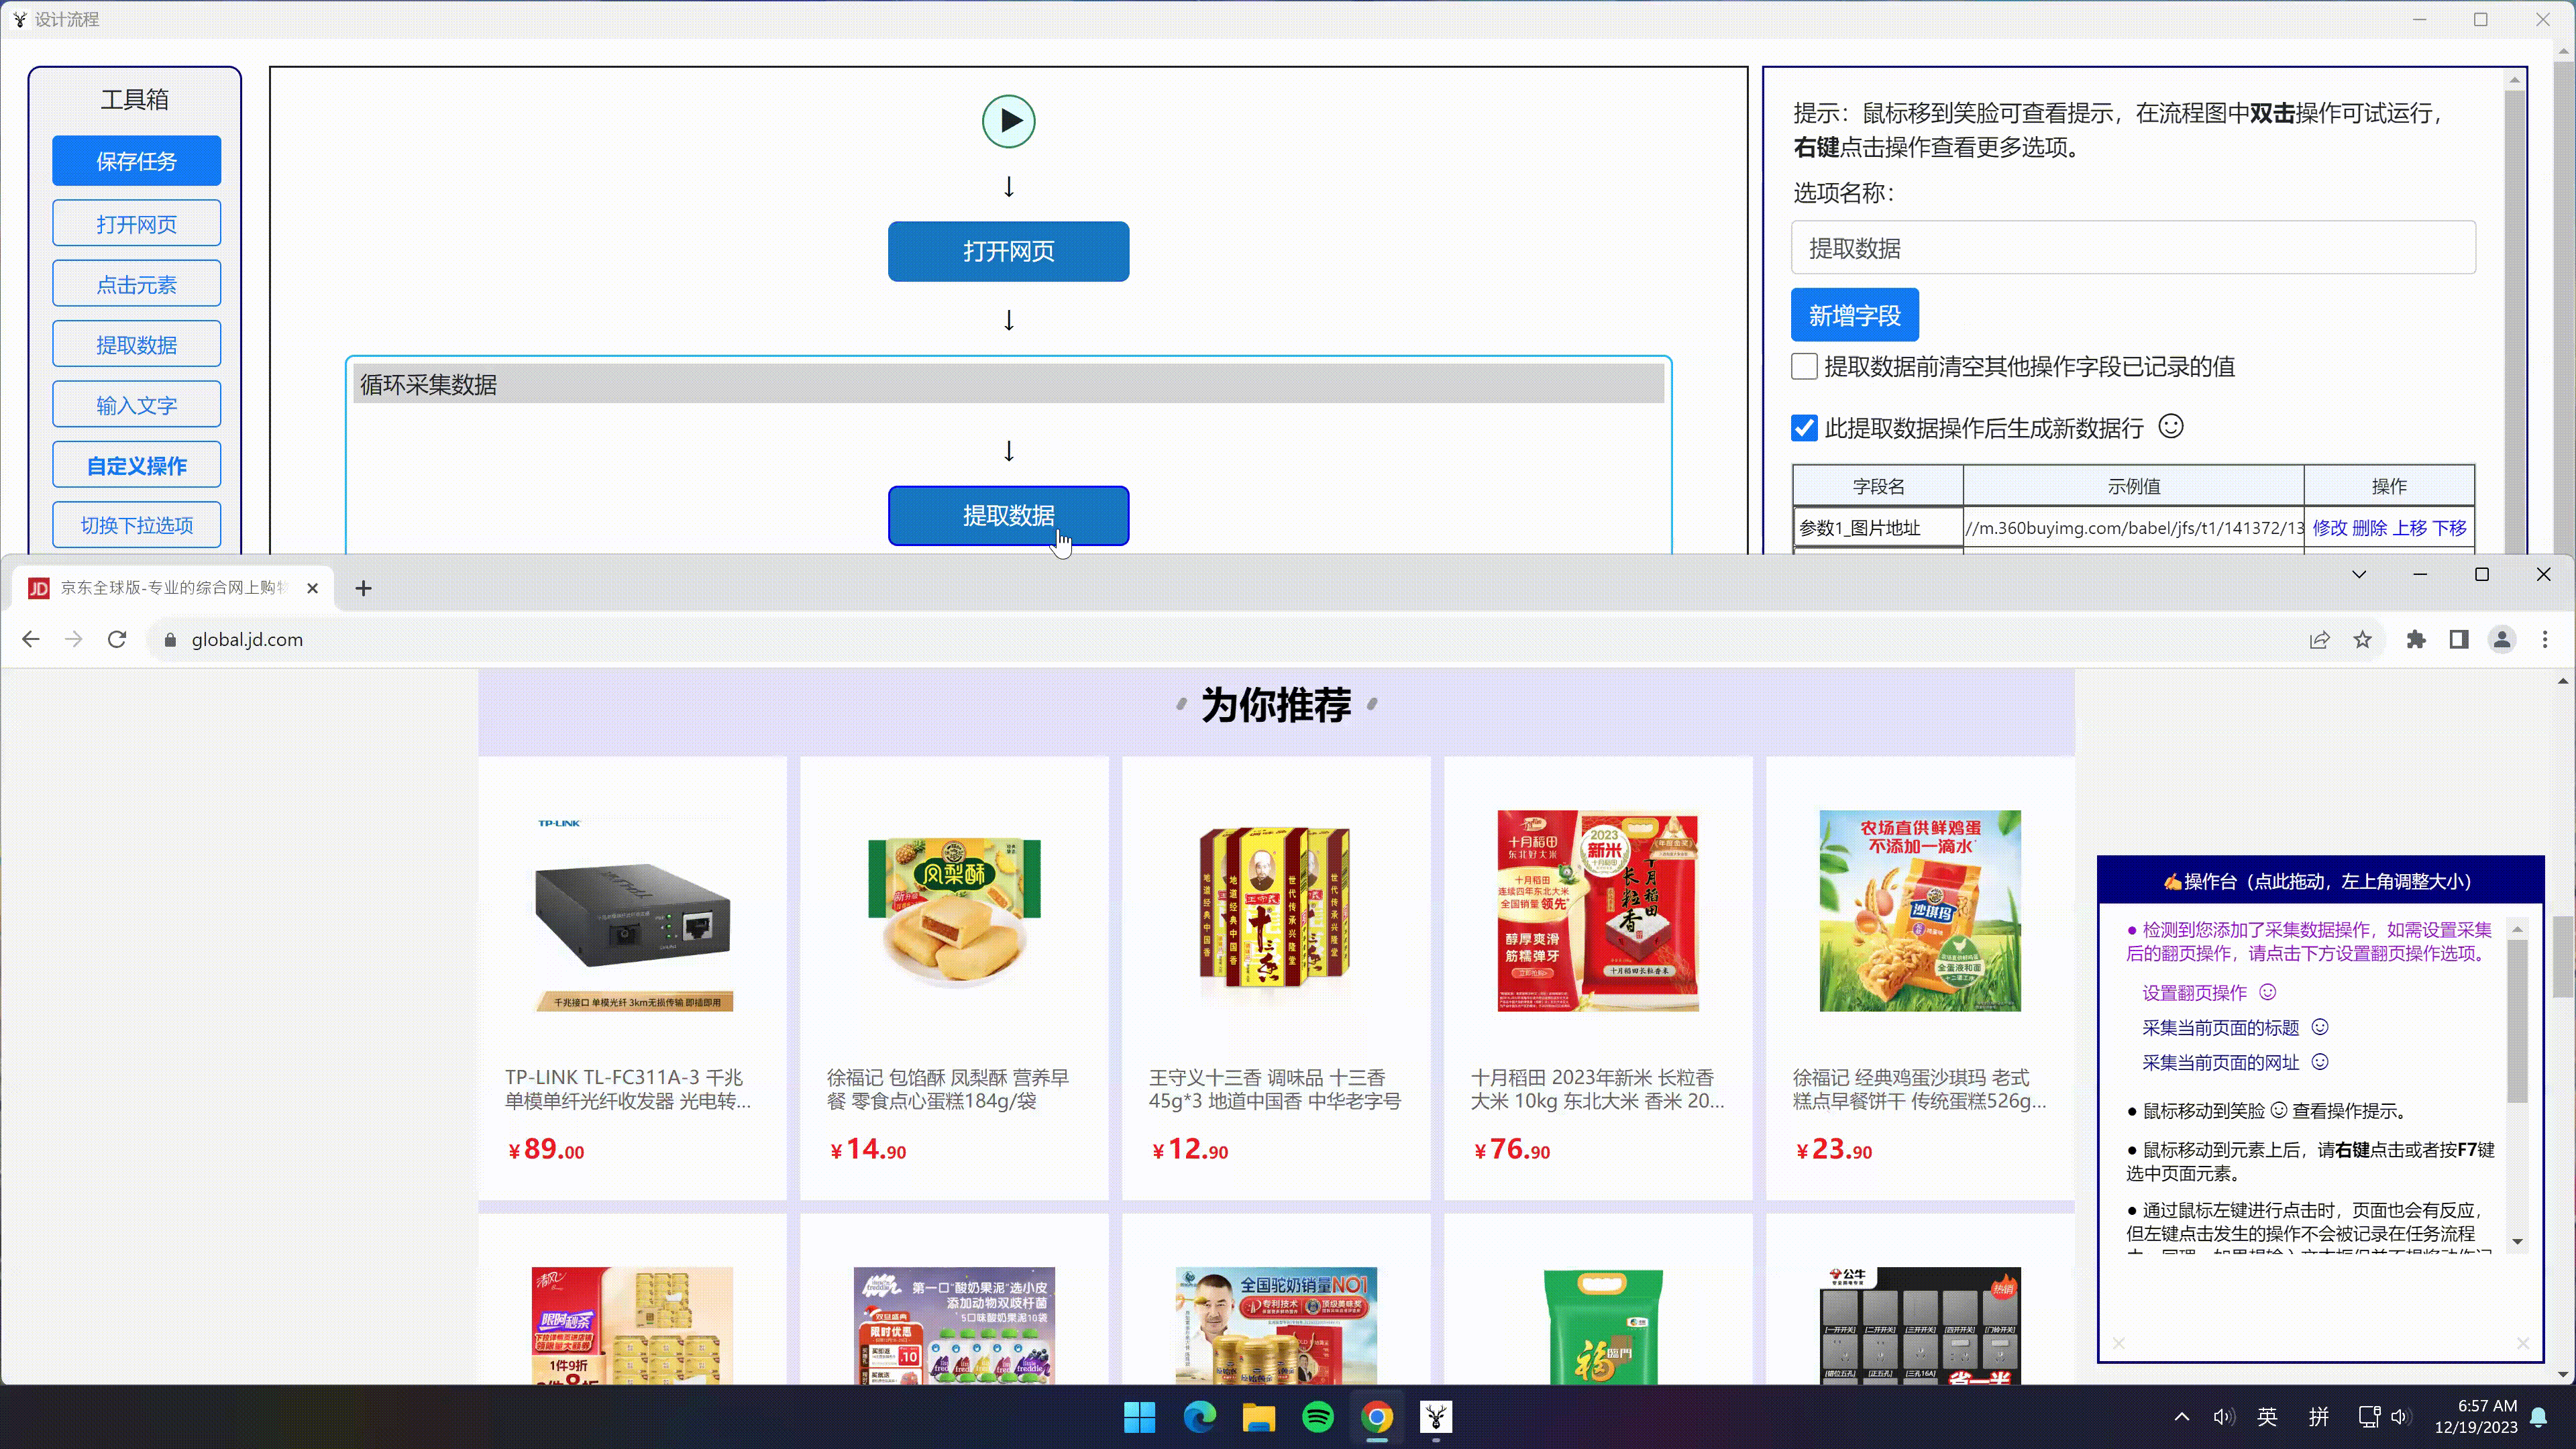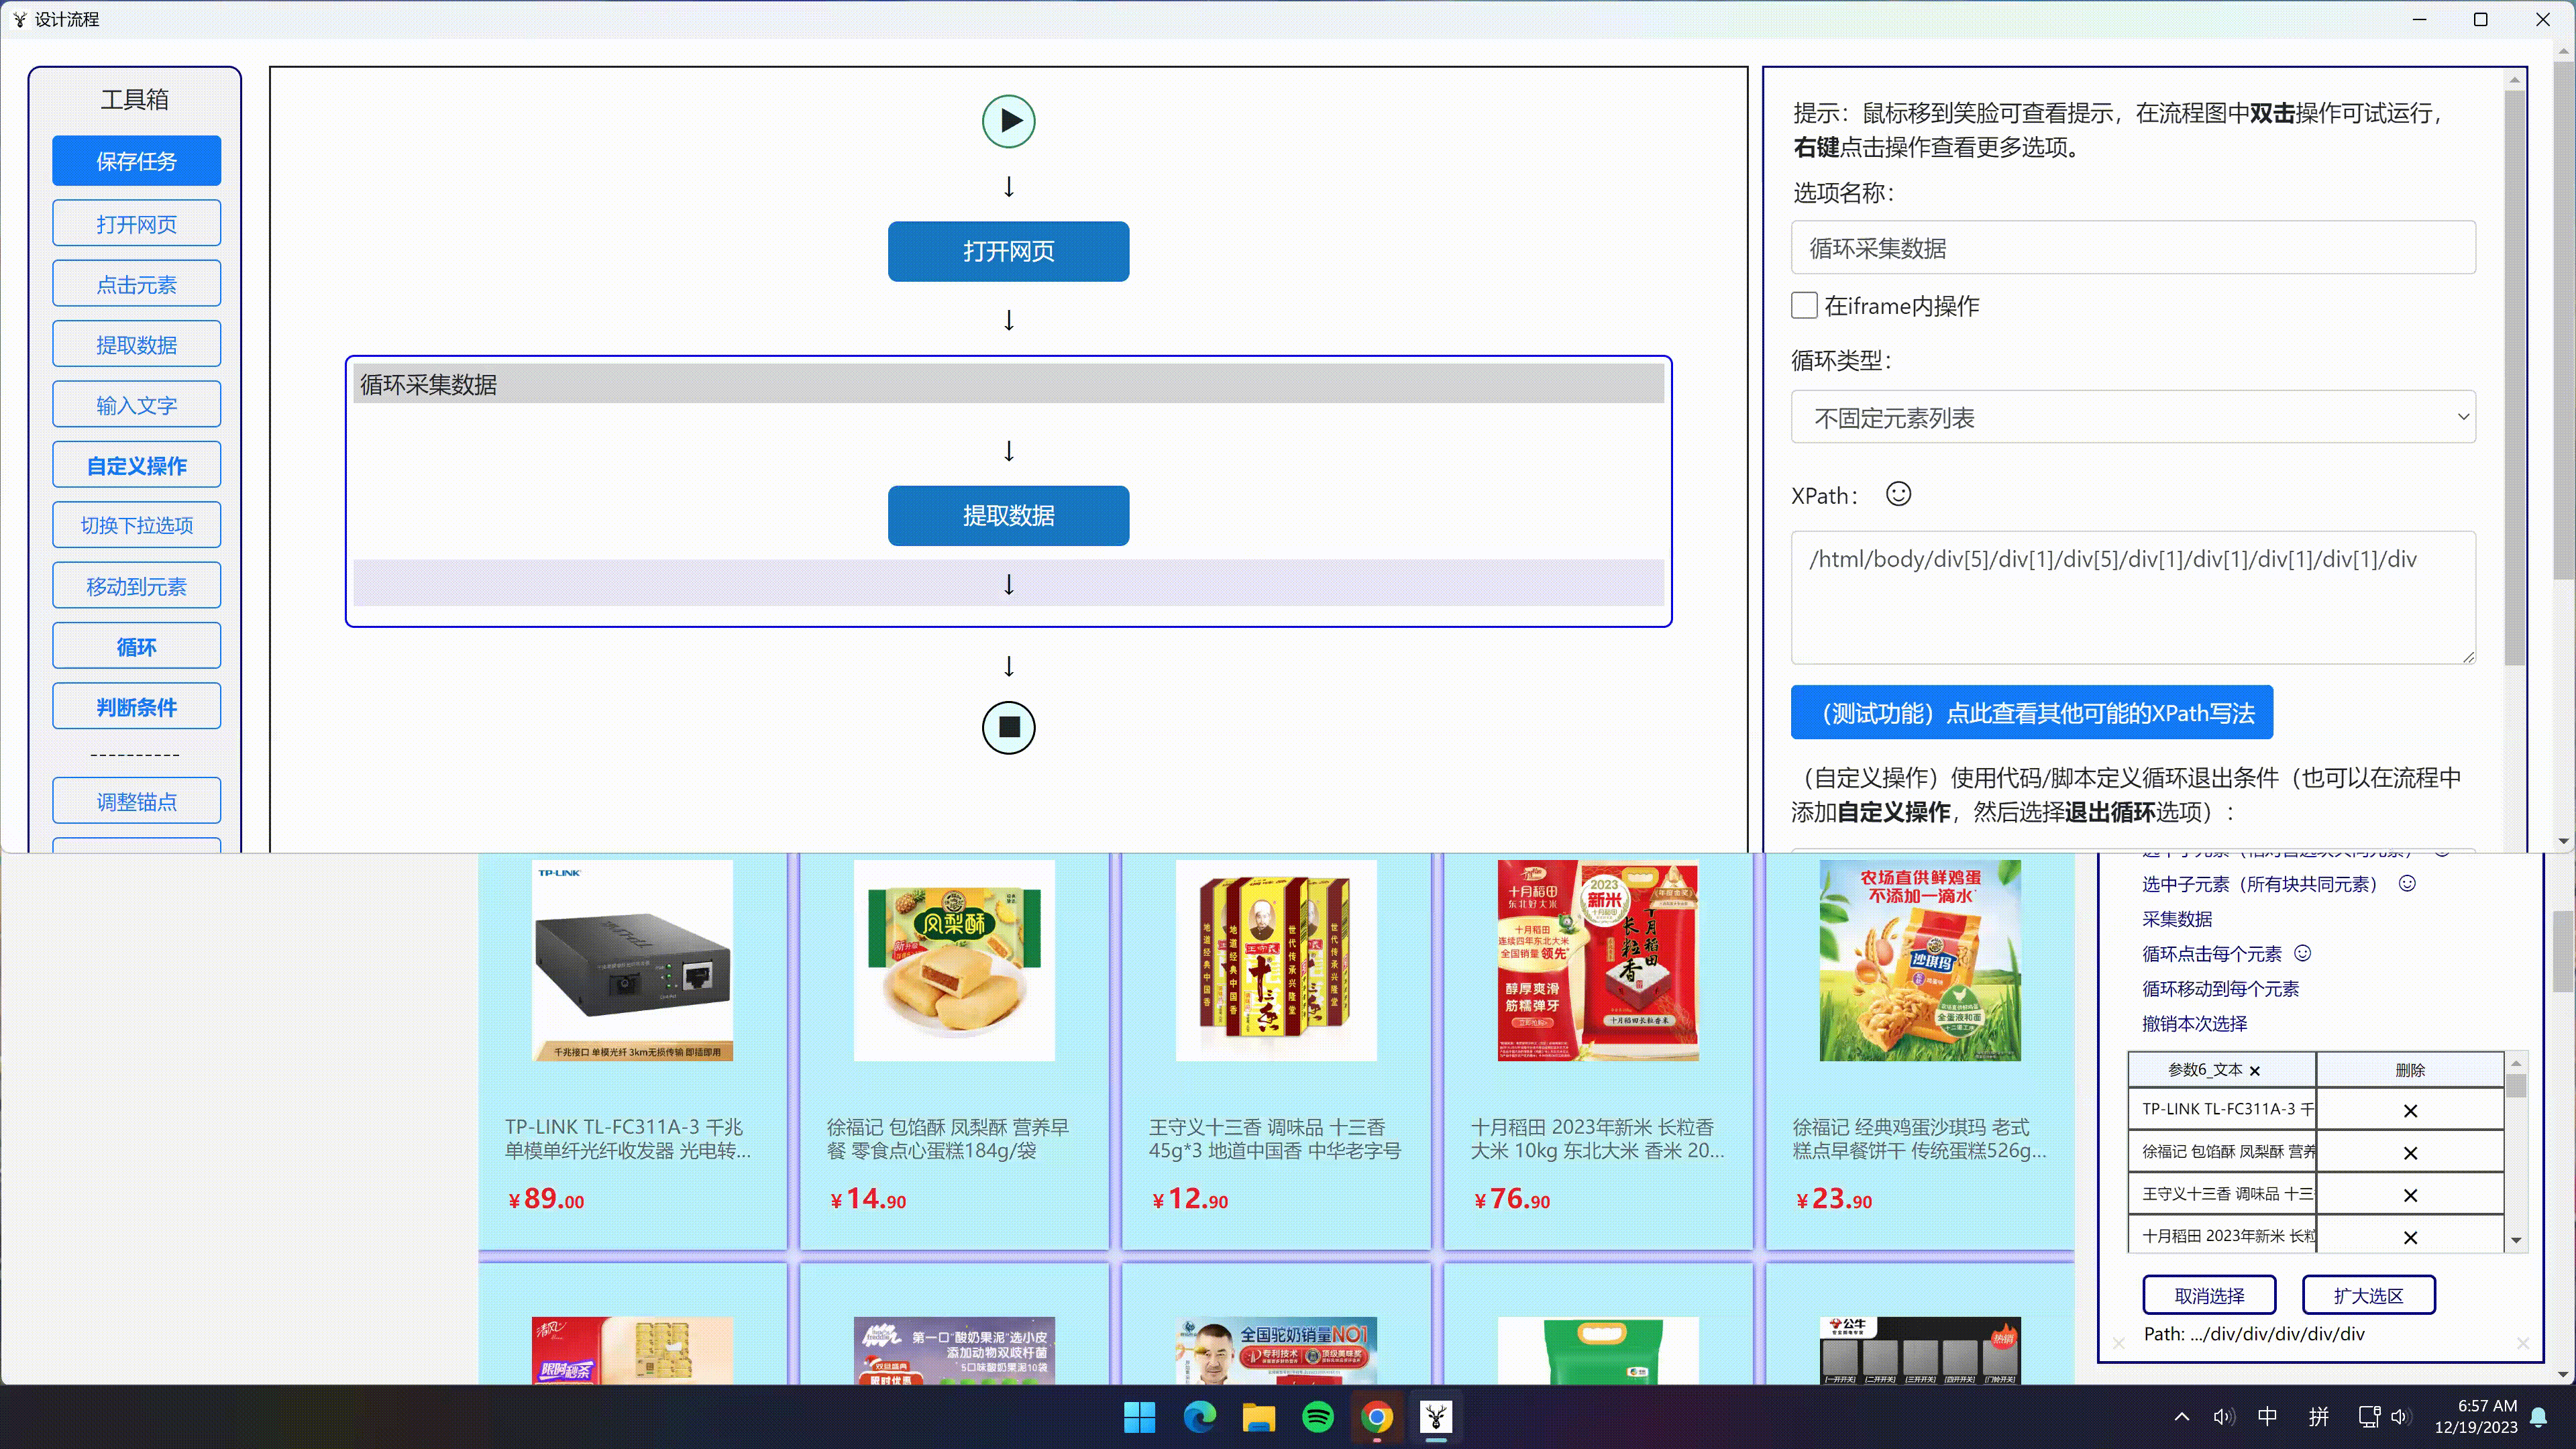
EasySpider
44.7KNaiboWang/EasySpider · JavaScriptEasySpider (易采集) is a visual, no-code web crawler and browser automation tool. You select elements on a webpage with clicks instead of writing code, and it designs and runs the scraping/testing task for you.
- 7
Scrapegraph-ai
31.8KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 8

lux
31.8Kiawia002/lux · GoLux is a fast and simple video downloader built with Go — a CLI tool that grabs videos, images and audio from sites like YouTube, bilibili, Douyin, Youku and iQiyi.
- 9

cheerio
30.5Kcheeriojs/cheerio · TypeScriptCheerio is a fast, flexible library for parsing and manipulating HTML and XML. It implements a subset of the core jQuery API, so if you know jQuery selectors you already know most of it.
- 10

crawlee
26.2Kapify/crawlee · TypeScriptA web scraping and browser automation library for Node.js: you write crawlers in JavaScript or TypeScript to crawl sites, extract data (e.g. for AI, LLM and RAG pipelines) and save it to disk or cloud.
- 11

colly
25.6Kgocolly/colly · GoColly is a scraping and crawling framework for Go: a clean interface for writing any kind of crawler, scraper or spider that extracts structured data from websites, for things like data mining, processing or archiving.
- 12

gpt-crawler
22.4KBuilderIO/gpt-crawler · TypeScriptA crawler that scrapes a website (one or multiple URLs) and turns the pages into a knowledge file you can upload to OpenAI to build a custom GPT or assistant.
- 13
automa
21.7KAutomaApp/automa · VueAutoma is a browser extension that automates your browser by connecting blocks into workflows — auto-fill forms, take screenshots, repeat tedious tasks, or scrape website data.
- 14

Douyin_TikTok_Download_API
20.7KEvil0ctal/Douyin_TikTok_Download_API · PythonA self-hosted data API for Douyin and TikTok: it pulls posts, author profiles, comments, search and playlists, downloads videos and image albums without a watermark, and exposes it all through a REST API, an MCP server, a CLI and a web console.
- 15

gallery-dl
20.1Kmikf/gallery-dl · Pythongallery-dl is a command-line program that downloads image galleries and collections from many image hosting sites.
- 16

python-spider
19.8KJack-Cherish/python-spider · PythonA collection of real-world Python web scraping projects, each targeting a specific Chinese site or app: Taobao, JD, NetEase Music, Bilibili, 12306 train tickets, Douyin, novel sites, manga sites and more.
- 17
maxun
17.9Kgetmaxun/maxun · TypeScriptMaxun is an open-source no-code web data platform that turns any website into structured, reliable data: it handles extraction, crawling, scraping, search and AI-powered data extraction.
- 18
TikTokDownloader
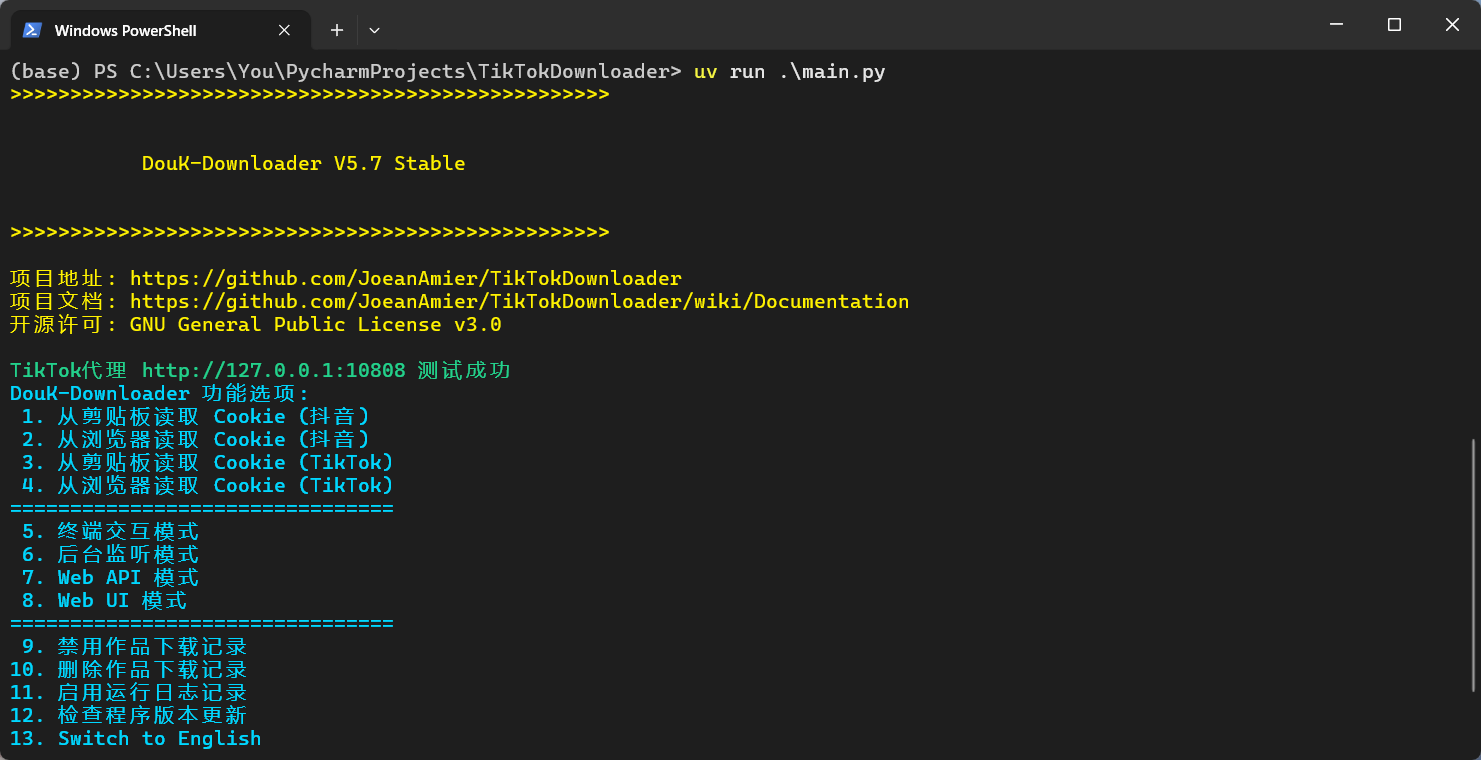
16.9KJoeanAmier/TikTokDownloader · JavaScriptDouK-Downloader (formerly TikTokDownloader) is a tool for downloading videos, images and live streams from Douyin (Chinese TikTok) and TikTok, and for collecting platform data such as account details, comments and search results.
- 19

pyspider
16.8Kbinux/pyspider · Pythonpyspider is a powerful web spider (crawler) system written in Python: you write crawling scripts in Python and manage your scraping projects through a built-in web interface.
- 20

twint
16.4Ktwintproject/twint · PythonTwint is a Python tool for scraping Twitter data — tweets, followers, following, likes and more — without using Twitter's official API, so it isn't bound by API limits or sign-up requirements.
- 21

newspaper
15.2Kcodelucas/newspaper · PythonNewspaper3k is a Python 3 library that downloads, parses, and extracts the article text, authors, publish date, top image, and keywords/summary from news articles and news sites.
- 22

instaloader
13.6Kinstaloader/instaloader · PythonInstaloader downloads pictures and videos from Instagram profiles, hashtags, stories, feeds, and saved media, along with captions, comments, geotags, and other metadata.
- 23

nsfw_data_scraper
12.6Kalex000kim/nsfw_data_scraper · ShellThis is a collection of shell scripts that scrapes and aggregates tens of thousands of images across 5 categories (porn, hentai, sexy, neutral, drawings) to build a labeled dataset for training an NSFW image classifier.
- 24

DrissionPage
12.5Kg1879/DrissionPage · PythonDrissionPage is a Python web automation tool that can control a browser, send and receive raw HTTP packets, or combine both in one workflow, giving you browser automation convenience together with requests-level efficiency.
- 25
crawlab
12.3Kcrawlab-team/crawlab · GoCrawlab is an open-source distributed web crawler management platform: you upload spiders written in any language, run them across a cluster of machines, and manage tasks, schedules and results from a web UI.
- 26

chinese-xinhua
11.7Kpwxcoo/chinese-xinhua · PythonA Chinese Xinhua Dictionary database (中华新华字典数据库): four JSON datasets with 31,648 idioms, 264,434 words, 16,142 characters and 14,032 xiehouyu (two-part allegorical sayings), collected from the web.
- 27

webmagic
11.7Kcode4craft/webmagic · JavaWebMagic is a scalable web crawler framework for Java. It covers the whole crawler lifecycle — downloading, URL management, content extraction and persistence — to simplify building a specific crawler.
- 28
apify-mcp-server
11.6Kapify/apify-mcp-server · TypeScriptThe Apify MCP Server lets AI agents and assistants extract data from websites like social media, search engines, maps, and e-commerce sites by giving them access to thousands of ready-made scrapers and automation tools from the Apify Store.
- 29
nopecha-extension
11KNopeCHALLC/nopecha-extensionNopeCHA is a browser extension that automatically detects and solves CAPTCHAs on any page, powered by multimodal AI running through the NopeCHA API platform.
- 30
avbook
10.1Kguyueyingmu/avbook · PHPA self-hosted AV (Japanese adult video) library: a PHP/Laravel web app with built-in crawlers for avmoo, javbus and javlibrary that builds a local, searchable database of movies and magnet links.
- 31
API-mega-list
7.8Kcporter202/API-mega-list · JavaScriptAPI Mega List is a massive README directory of ready-to-use APIs for building apps and automations, listing 11,860 core directory APIs plus 318 sponsored partner API listings across 24 categories.
- 32

search-plugins
7.1Kqbittorrent/search-plugins · PythonA community-maintained collection of Python search plugins that plug into qBittorrent's built-in search tab, letting it query different torrent sites directly.
- 33
google-maps-scraper
6.5Kgosom/google-maps-scraper · GoA free, open-source tool that scrapes Google Maps to extract business leads such as name, address, phone, website, rating, reviews, email, and GPS coordinates.
- 34

Website-downloader
6KAhmadIbrahiim/Website-downloader · HTMLA self-hosted Node.js app that downloads the complete source code of any website, including its JavaScript, stylesheets, and images, so you can keep an offline copy.
- 35
botasaurus
5.8Komkarcloud/botasaurus · PythonBotasaurus is an all-in-one Python web scraping framework built to make scrapers that pass bot-detection checks, including Cloudflare WAF, BrowserScan, Fingerprint, Datadome, and Cloudflare Turnstile CAPTCHA.
- 36
job-ops
4KDaKheera47/job-ops · TypeScriptJobOps is a self-hosted pipeline that applies DevOps-style automation to job hunting: it searches multiple job boards from one screen, scores how well each job fits you, tailors your CV, checks visa sponsorship status, and tracks every application in one dashboard.
- 37
scraping-apis-for-devs
3.9Kcporter202/scraping-apis-for-devs · JavaScriptA giant categorized directory of 2,622 ready-to-use scraping APIs for pulling data from websites, social media, e-commerce sites, job boards, real estate listings and more, so you don't have to build scrapers from scratch.
- 38

FreePEP
1.3Ksiknet/FreePEP · PythonFreePEP is an automation tool that parses, batch-downloads, and converts electronic textbooks from the PEP (People's Education Press) platform into high-resolution PDF files.
- 39

amane
803sqzw-x/amane · PythonAmane is a personal video library manager for the AI era: it watches your media folders, automatically scrapes metadata from multiple sources, and lets you browse the result through a web poster wall with an AI assistant for search and organization.
- 40

gate
505hezhanleiok/gate · PythonIt automates scraping VPN Gate's SSTP home-broadband/datacenter nodes, verifies each one with a checker Worker, groups them by country, and publishes an auto-rotating node list that edgetunnel can pull as chained proxy entries.
- 41
Instagram-Downloader
441hoaianle/Instagram-Downloader · JavaScriptA Chrome extension that downloads photos and videos from Instagram posts, TV, reels, stories, and highlights directly from the page you're viewing.
- 42

tiktok-signature
399n1tr00-10/tiktok-signature · PythonThis is a Python library that generates the signatures TikTok's Web API requires on requests — X-Gnarly, X-Bogus, and X-Dynosaur — matching SDK version 5.1.2 (build 1.0.0.316).
Related topics
Often tagged together