Topics / #spider
Spider projects on GitHub
Web spiders and crawler programs
As of , the most-starred Spider projects on GitHub are EasySpider (44.7K stars), colly (25.6K stars) and proxy_pool (23.8K stars). GitHub.Locker tracks 11 Spider repositories with 187.9K stars combined. The fastest-growing on October 16 was Douyin_TikTok_Download_API, with +45 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +45
Douyin_TikTok_Download_API
Evil0ctal/Douyin_TikTok_Download_API · ★ 20.7KA self-hosted data API for Douyin and TikTok: it pulls posts, author profiles, comments, search and playlists, downloads videos and image albums without a watermark, and exposes it all through a REST API, an MCP server, a CLI and a web console.
 +13
catbus
cv-cat/catbus · ★ 431catbus is a command-line tool that lets you talk to 10 major Chinese and international platforms (Xiaohongshu, Douyin, TikTok, Bilibili, Kuaishou, Weibo, Xianyu, Taobao, JD, X) through one consistent set of commands and JSON output, instead of learning each platform's own API.
 +12
DouyinLiveRecorder
ihmily/DouyinLiveRecorder · ★ 11.1KDouyinLiveRecorder is a Python tool that records live streams from 40+ platforms (Douyin, TikTok, Kuaishou, Huya, Douyu, YouTube, Bilibili, Xiaohongshu, Twitch, and many more) continuously and can watch multiple rooms at once.
 +10
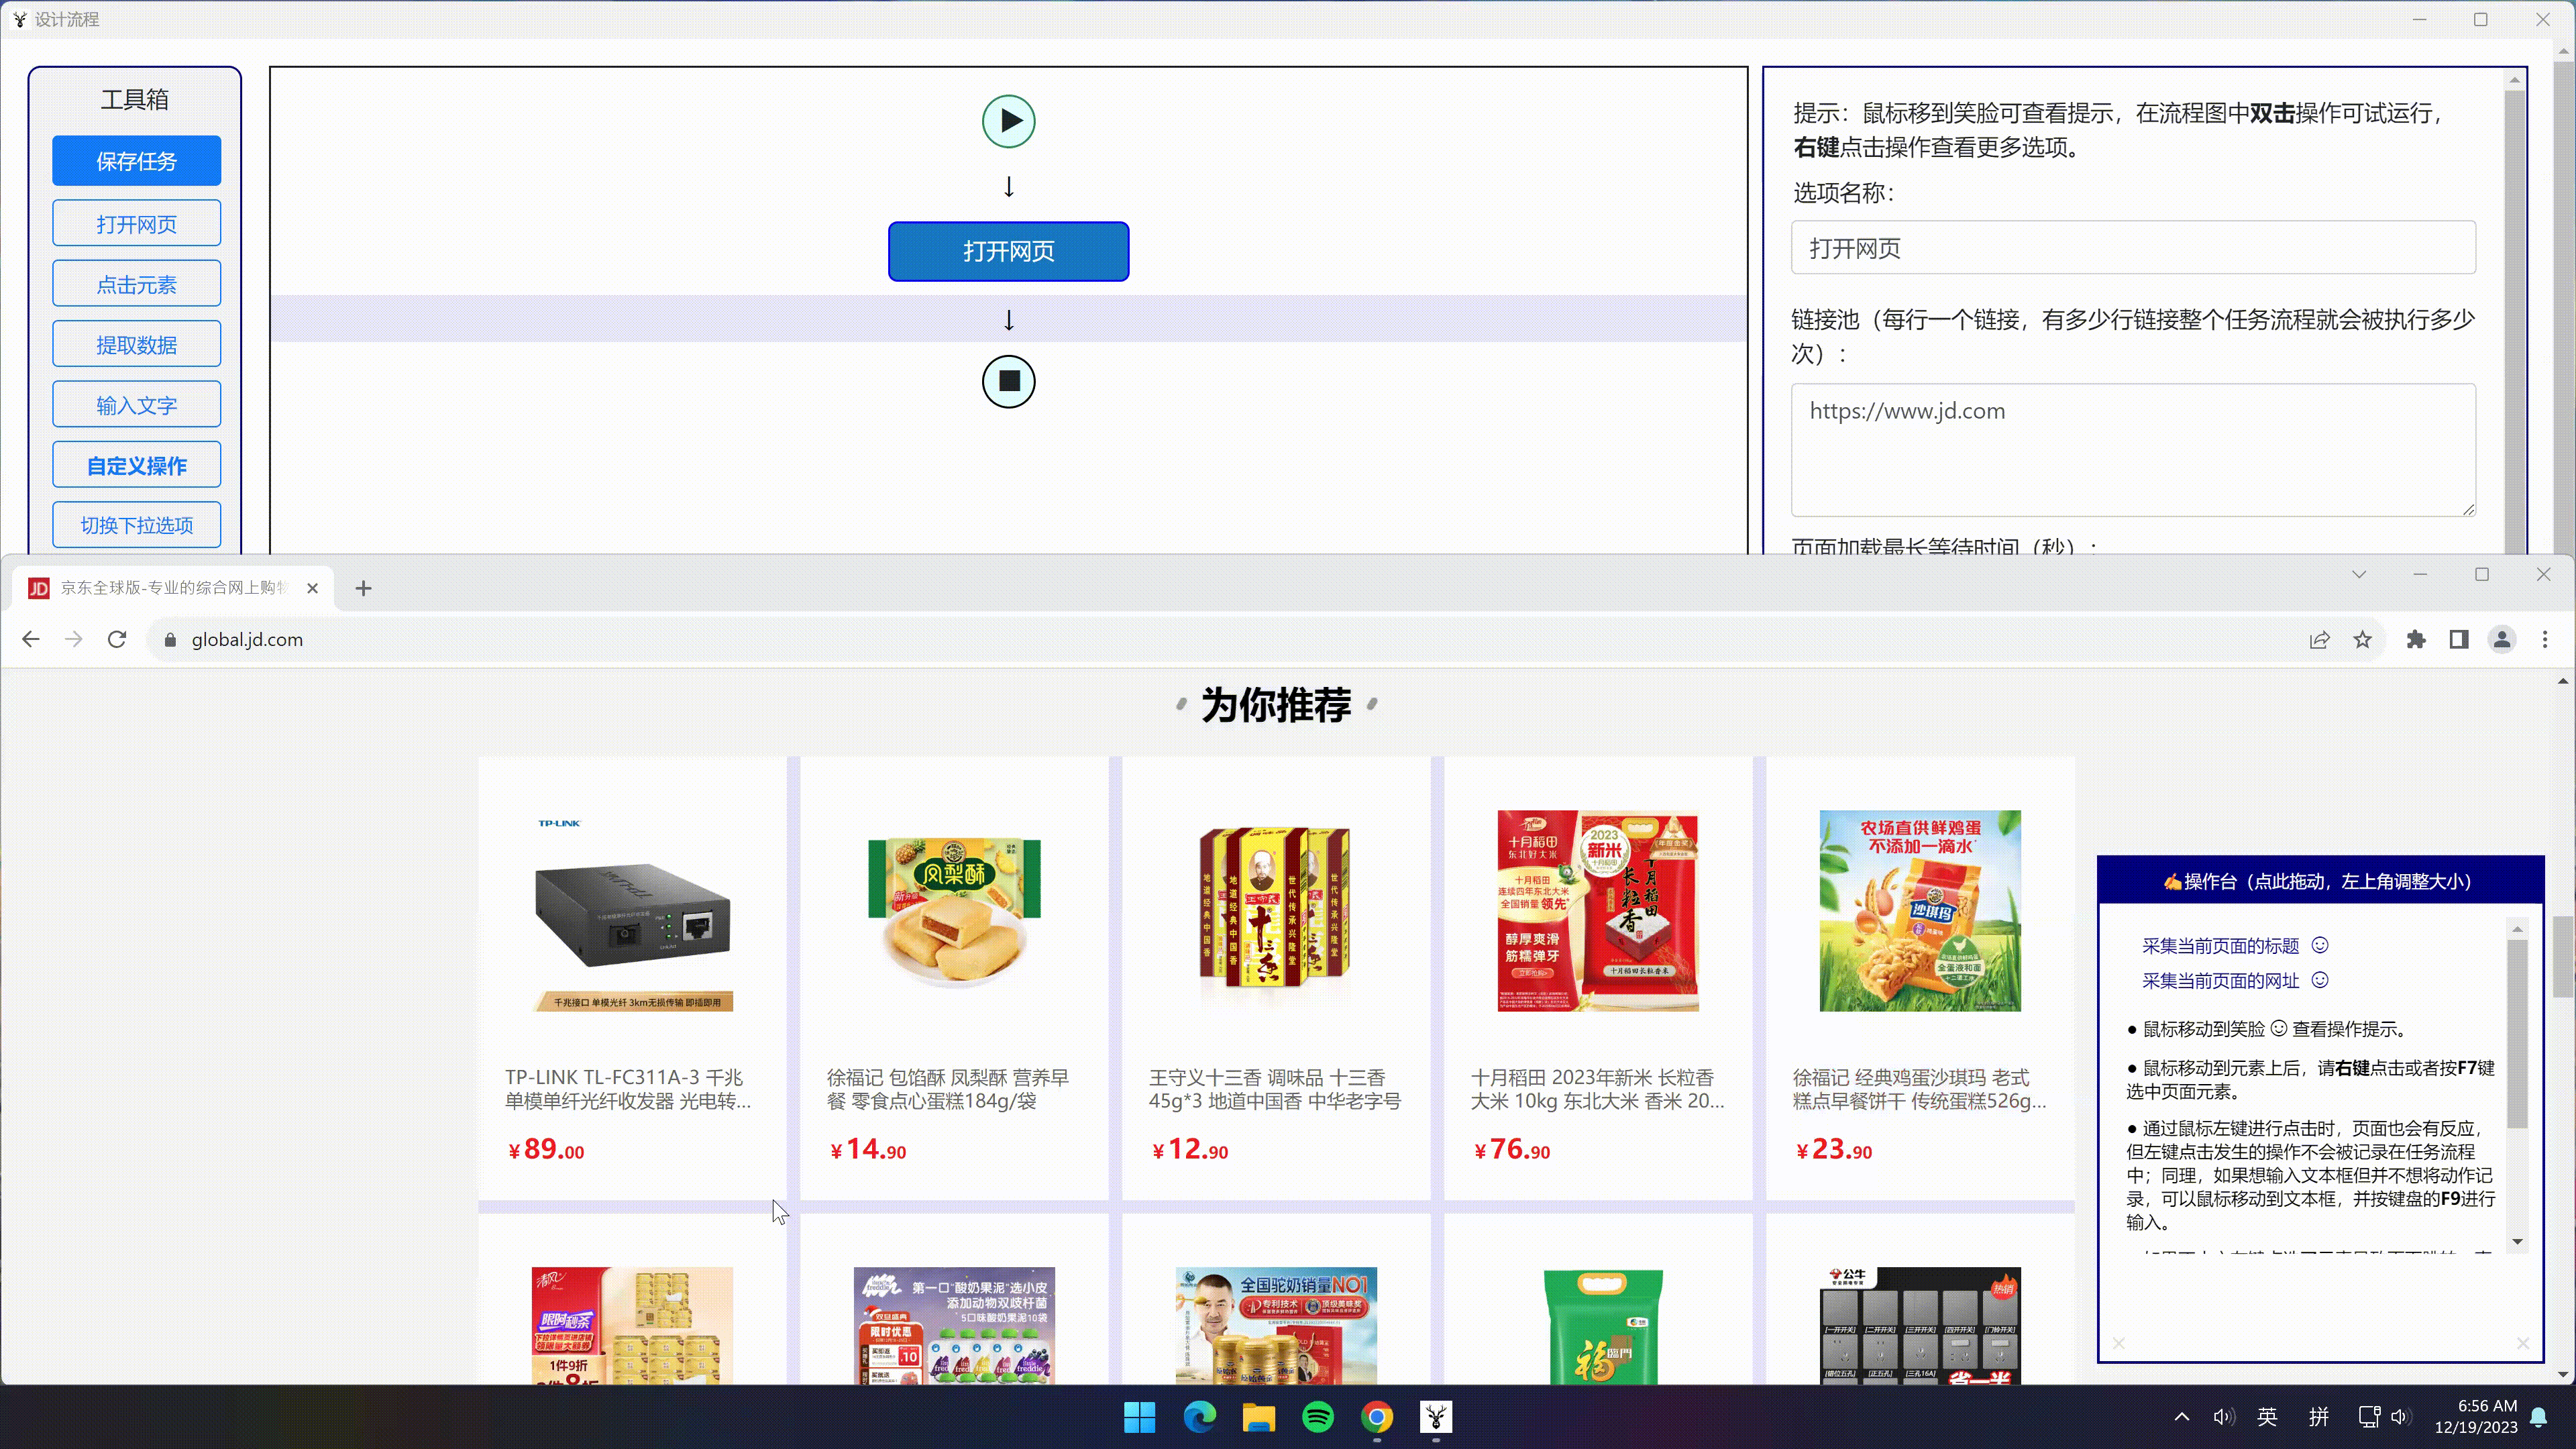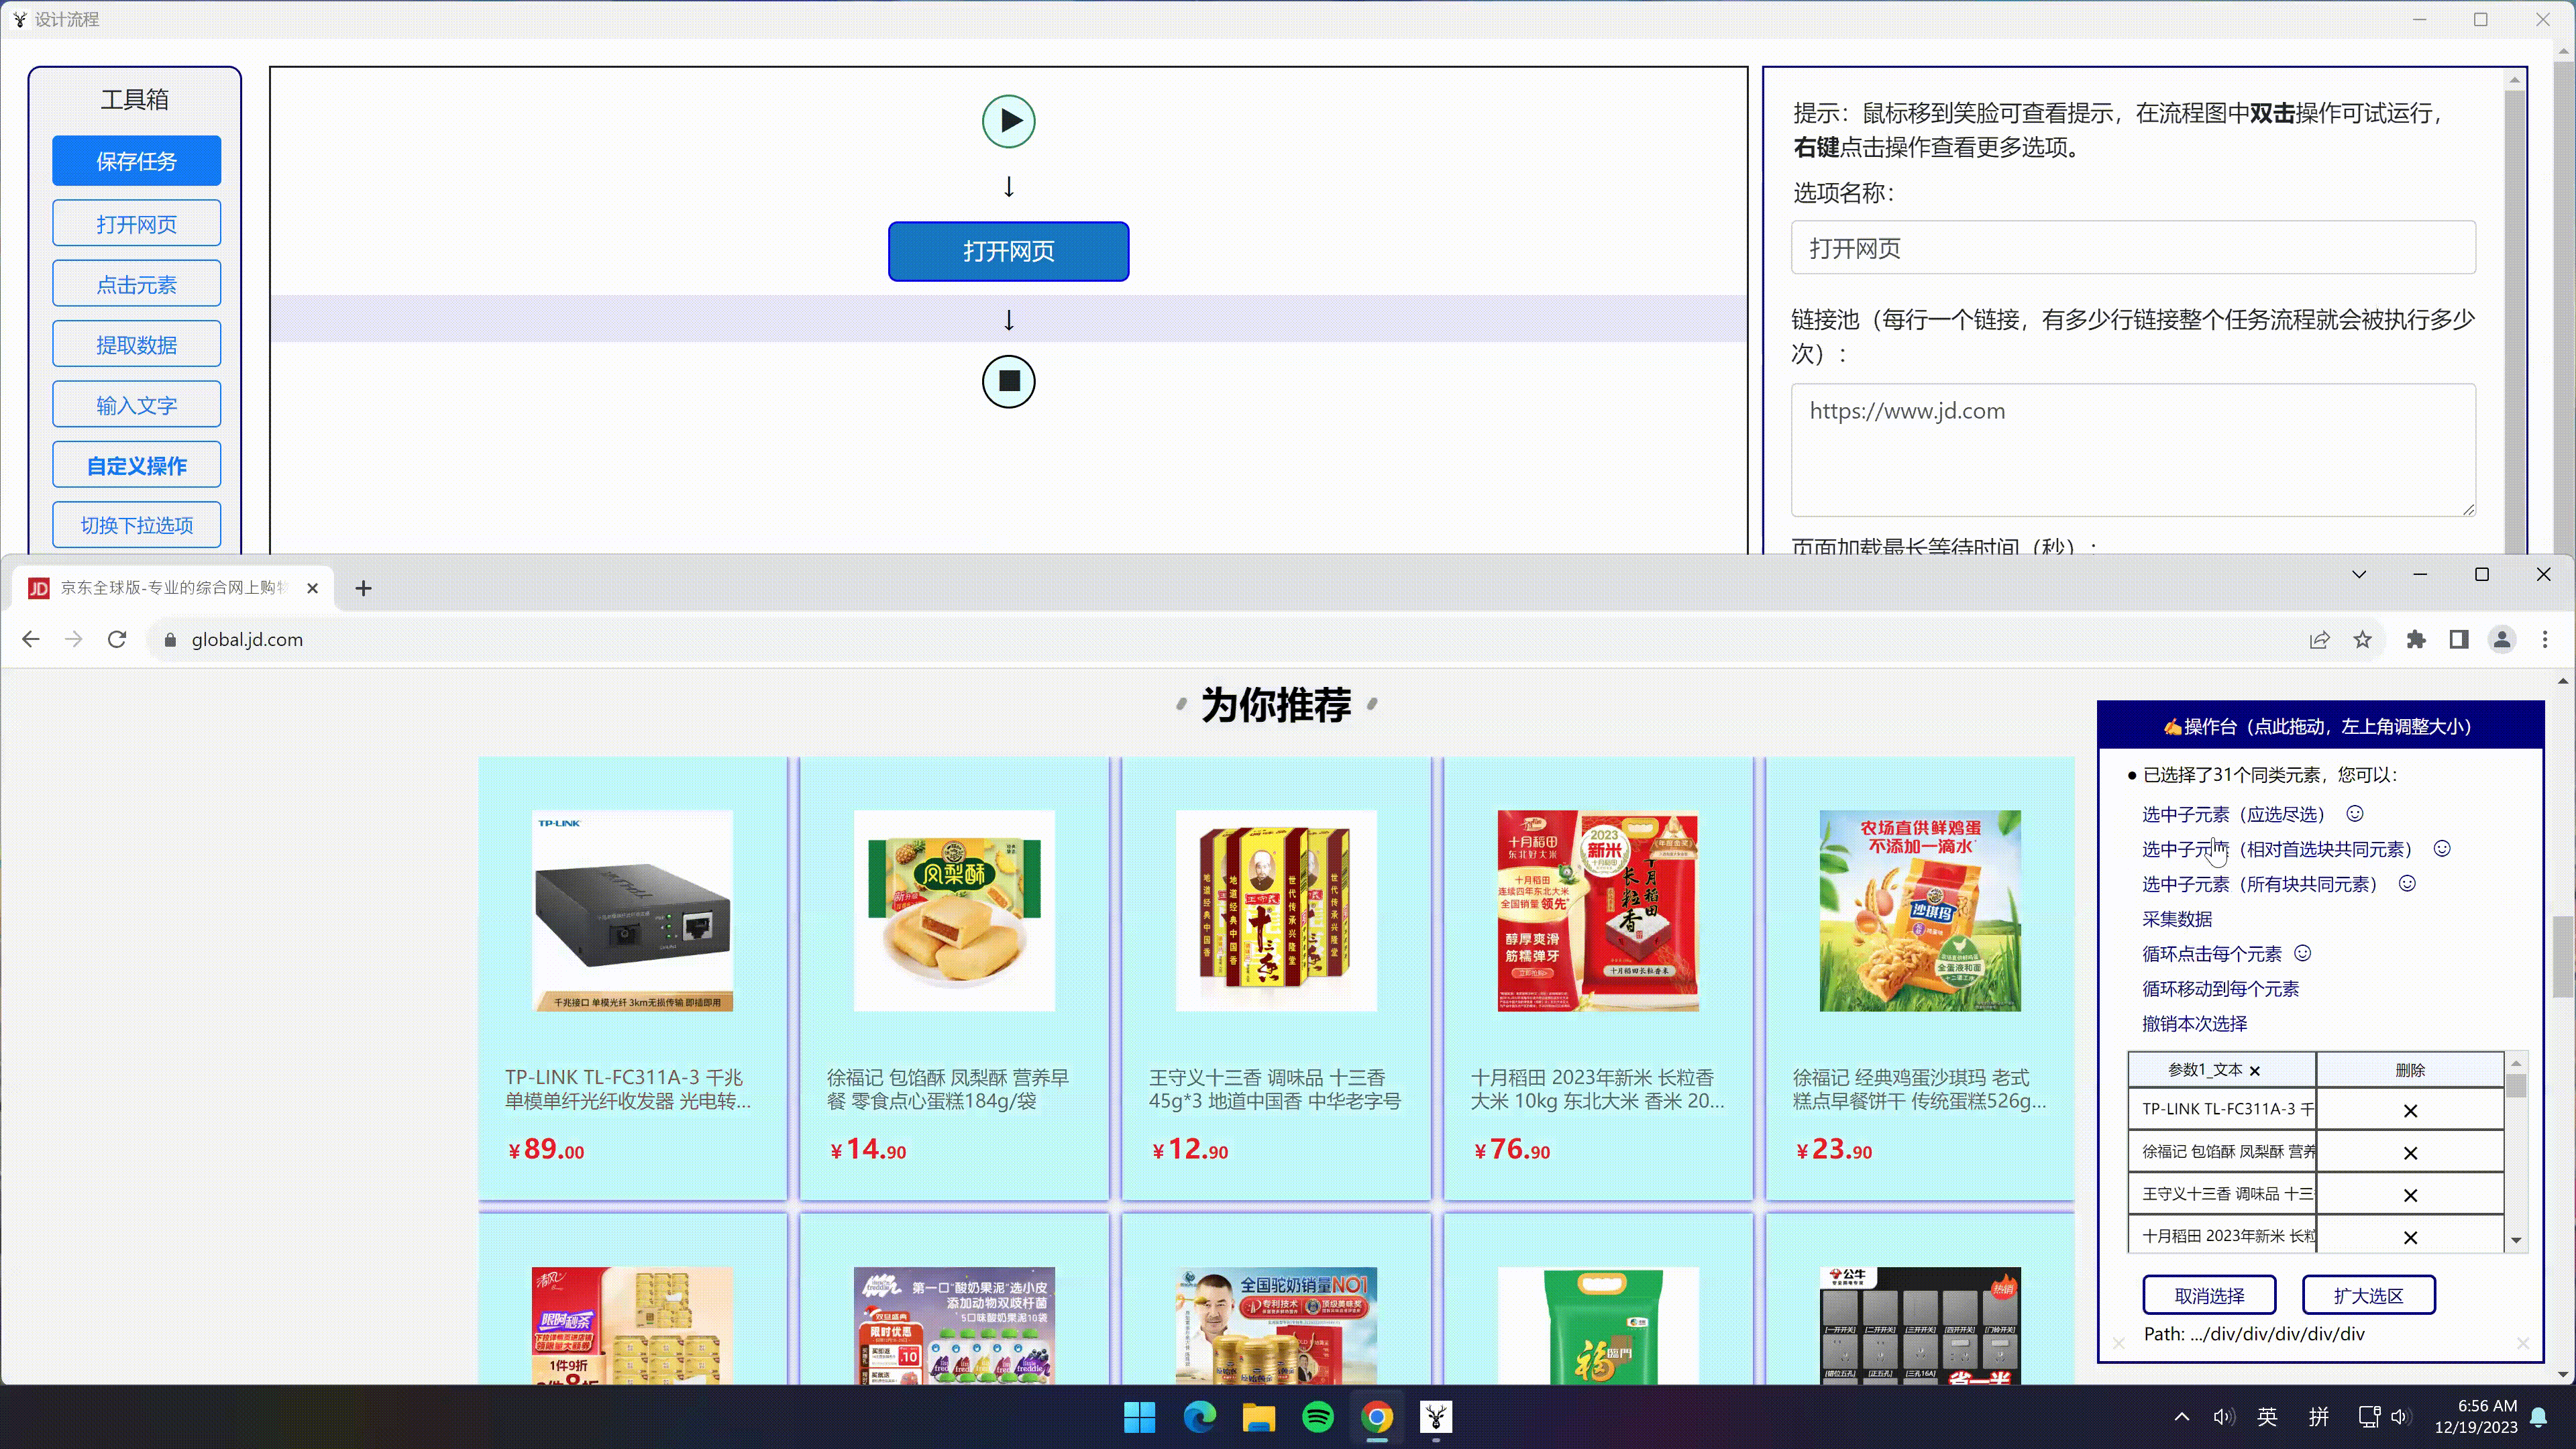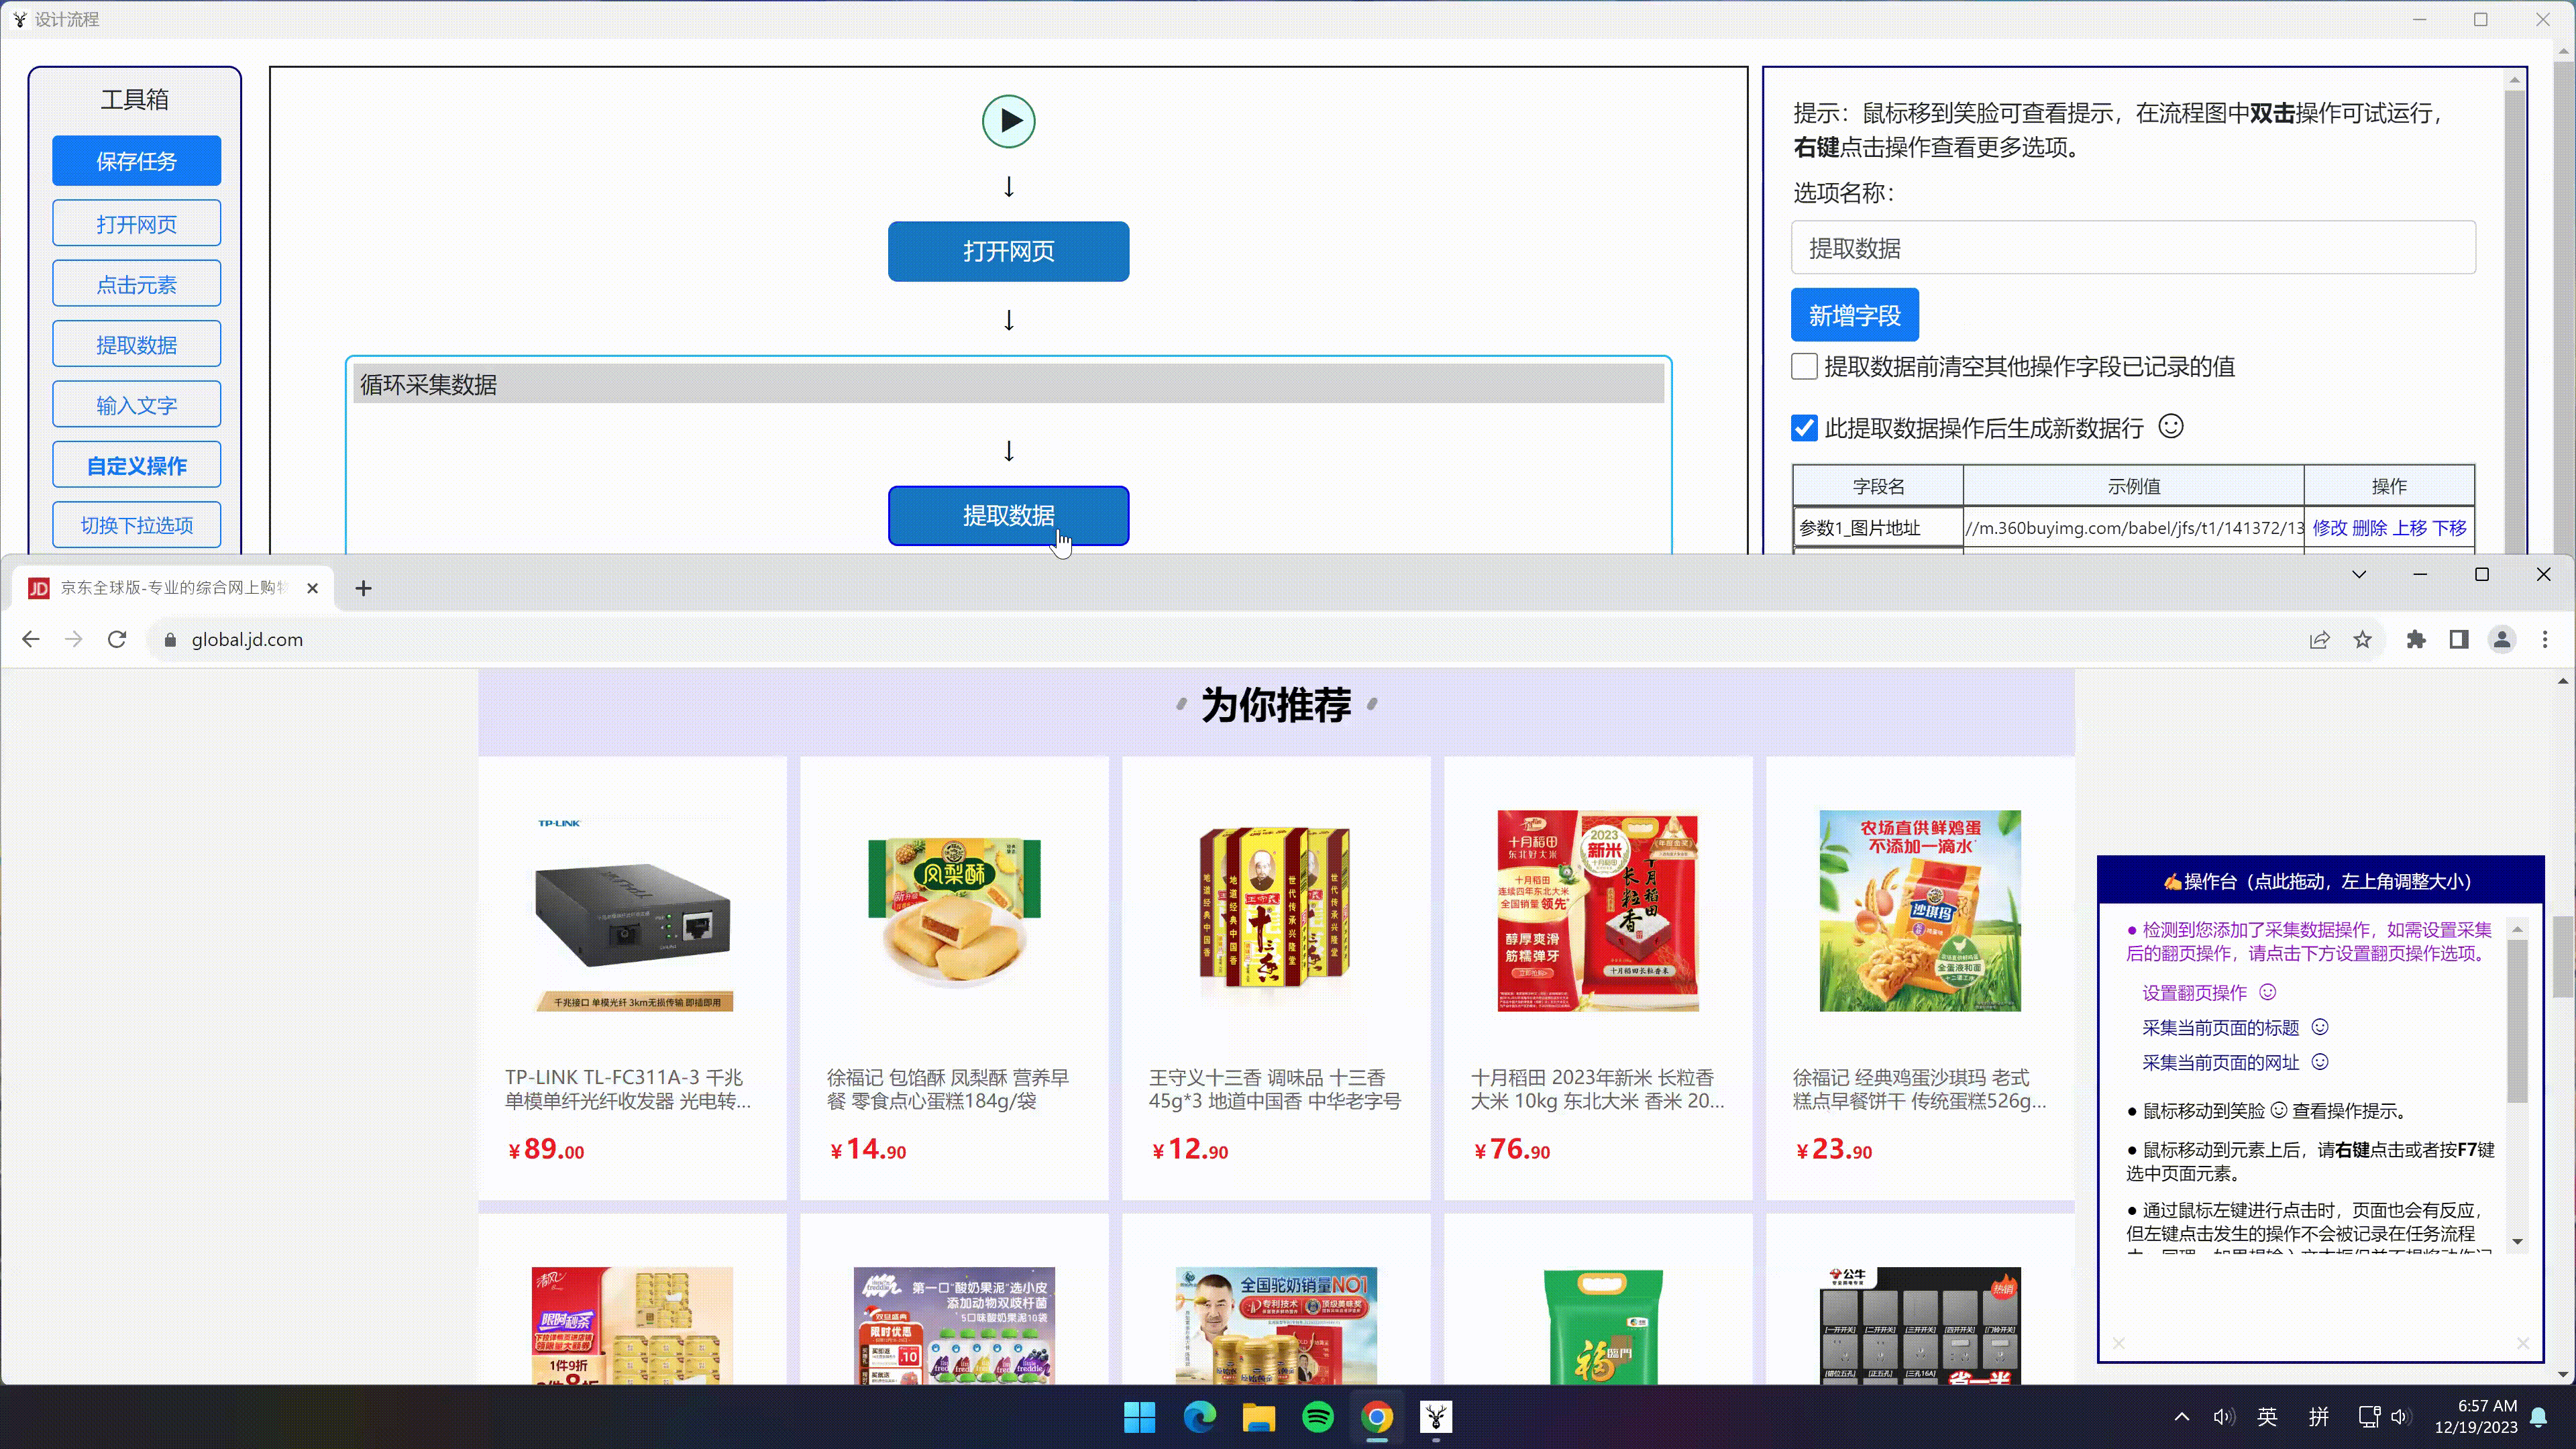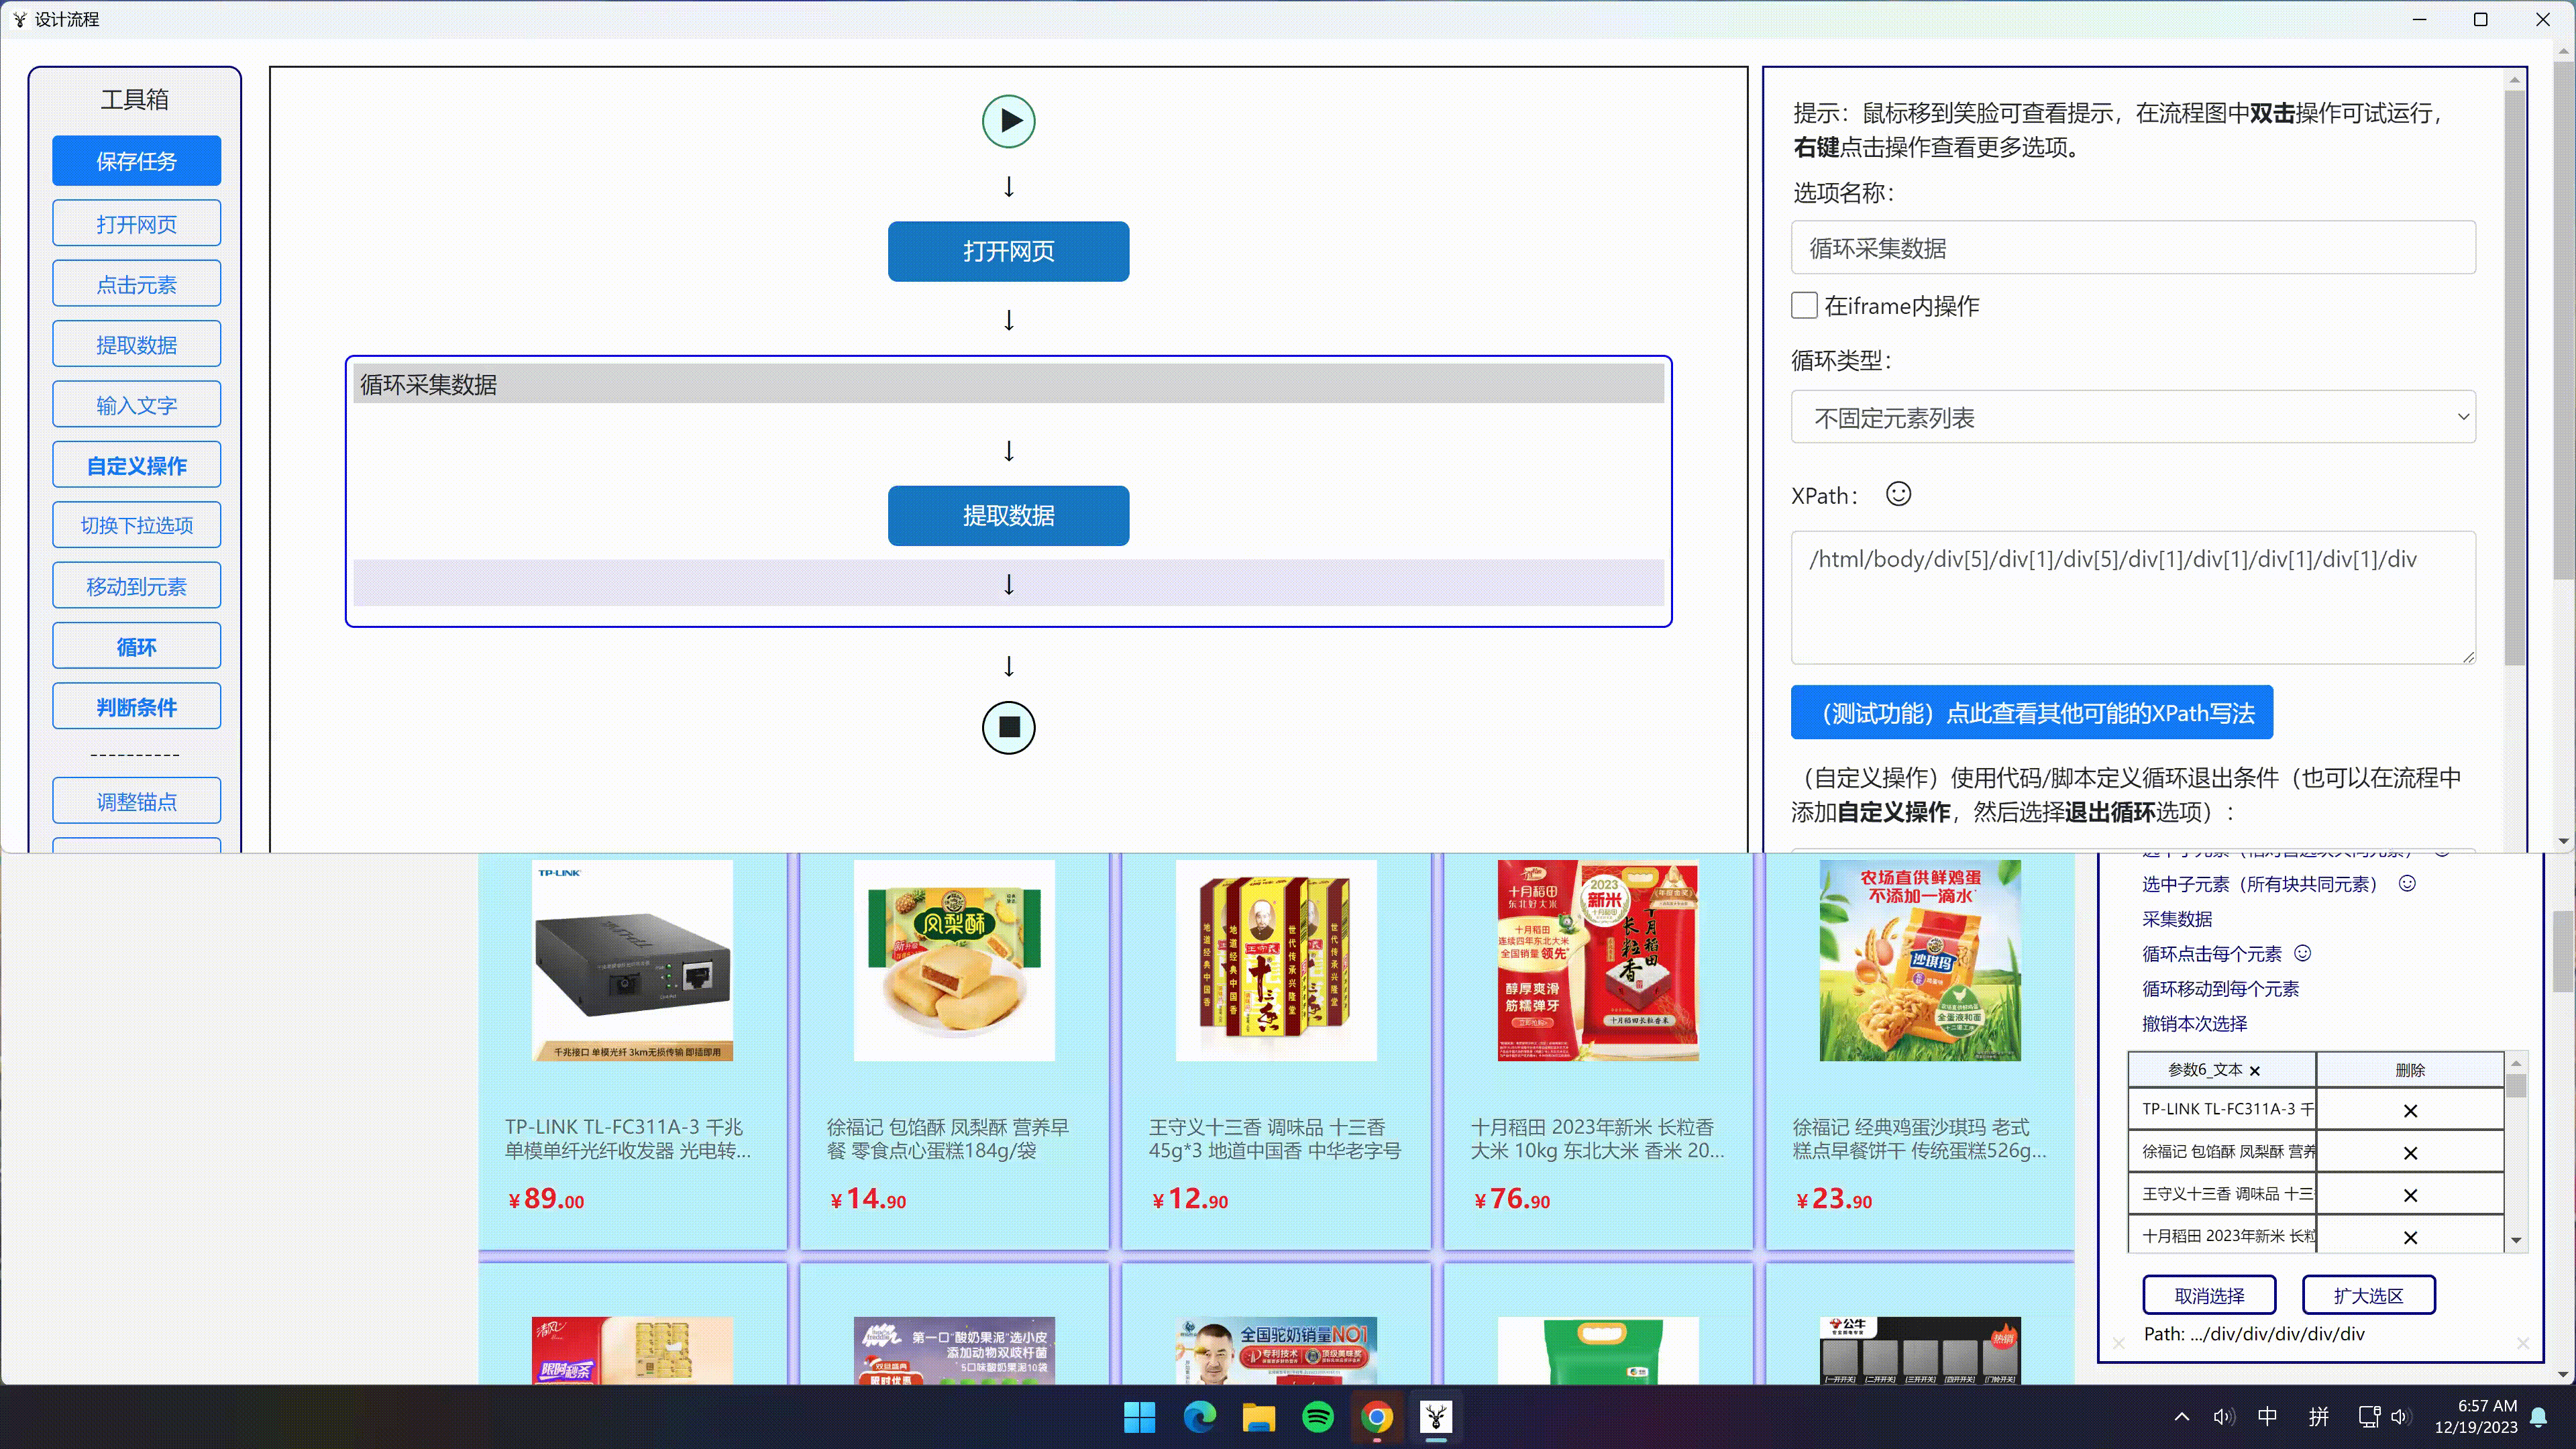
EasySpider
NaiboWang/EasySpider · ★ 44.7KEasySpider (易采集) is a visual, no-code web crawler and browser automation tool. You select elements on a webpage with clicks instead of writing code, and it designs and runs the scraping/testing task for you.
The all-time top
11 projects · by stars
- 44.7K#1 · NaiboWang/EasySpider
EasySpider
EasySpider (易采集) is a visual, no-code web crawler and browser automation tool. You select elements on a webpage with clicks instead of writing code, and it designs and runs the scraping/testing task for you.
- 25.6K
 #2 · gocolly/colly
colly
Colly is a scraping and crawling framework for Go: a clean interface for writing any kind of crawler, scraper or spider that extracts structured data from websites, for things like data mining, processing or archiving.
- 23.8K
 #3 · jhao104/proxy_pool
proxy_pool
ProxyPool is an open-source proxy IP pool for web spiders: it keeps harvesting free proxies from the web, checks that they work, stores the good ones in Redis and serves them to your crawler over a small HTTP API.
- 4
Douyin_TikTok_Download_API
20.7KEvil0ctal/Douyin_TikTok_Download_API · PythonA self-hosted data API for Douyin and TikTok: it pulls posts, author profiles, comments, search and playlists, downloads videos and image albums without a watermark, and exposes it all through a REST API, an MCP server, a CLI and a web console.
- 5

examples-of-web-crawlers
14.7Kshengqiangzhang/examples-of-web-crawlers · HTMLA collection of beginner-friendly Python web-scraping examples, mostly targeting Chinese sites like Taobao, Tmall, WeChat, WeChat Reading, Douban and QQ.
- 6

Photon
13.3Ks0md3v/Photon · PythonPhoton is a fast web crawler built for OSINT (open-source intelligence) gathering, extracting URLs, emails, social media accounts, secret keys, subdomains and more while it crawls a target site.
- 7
crawlab
12.3Kcrawlab-team/crawlab · GoCrawlab is an open-source distributed web crawler management platform: you upload spiders written in any language, run them across a cluster of machines, and manage tasks, schedules and results from a web UI.
- 8

spider-flow
11.4Kssssssss-team/spider-flow · JavaSpider-flow is a next-generation crawler platform that lets you design web scraping workflows as flowcharts instead of writing code.
- 9
DouyinLiveRecorder
11.1Kihmily/DouyinLiveRecorder · PythonDouyinLiveRecorder is a Python tool that records live streams from 40+ platforms (Douyin, TikTok, Kuaishou, Huya, Douyu, YouTube, Bilibili, Xiaohongshu, Twitch, and many more) continuously and can watch multiple rooms at once.
- 10
avbook
10.1Kguyueyingmu/avbook · PHPA self-hosted AV (Japanese adult video) library: a PHP/Laravel web app with built-in crawlers for avmoo, javbus and javlibrary that builds a local, searchable database of movies and magnet links.
- 11
catbus
431cv-cat/catbus · TypeScriptcatbus is a command-line tool that lets you talk to 10 major Chinese and international platforms (Xiaohongshu, Douyin, TikTok, Bilibili, Kuaishou, Weibo, Xianyu, Taobao, JD, X) through one consistent set of commands and JSON output, instead of learning each platform's own API.
Related topics
Often tagged together