Topics / #tesseract
Tesseract projects on GitHub
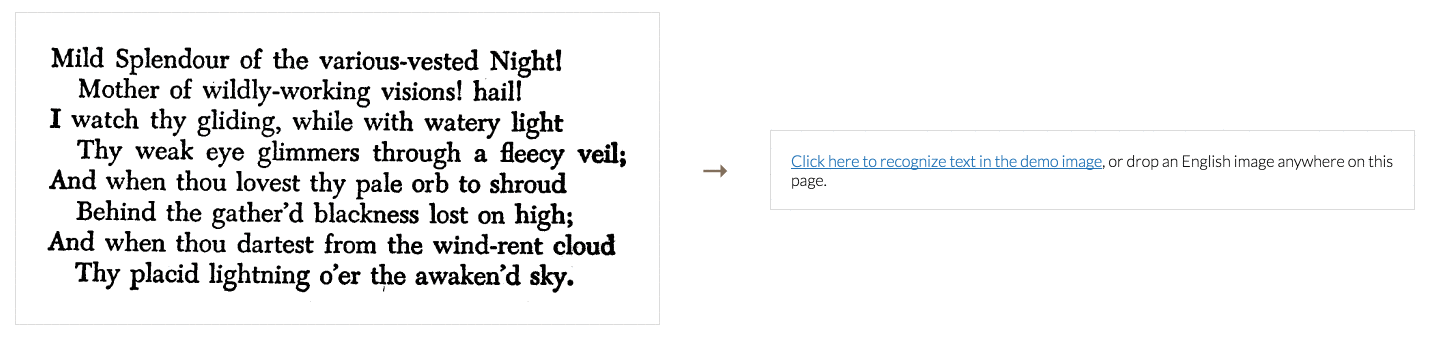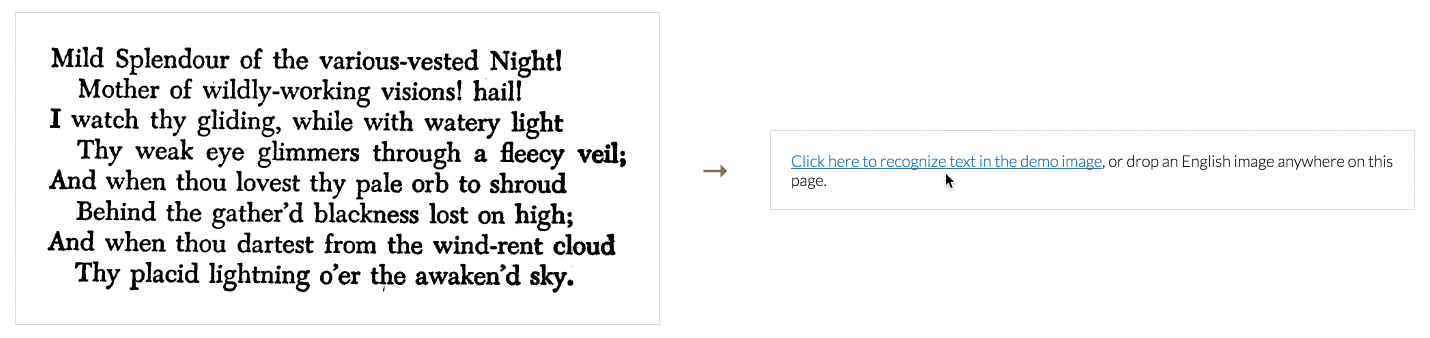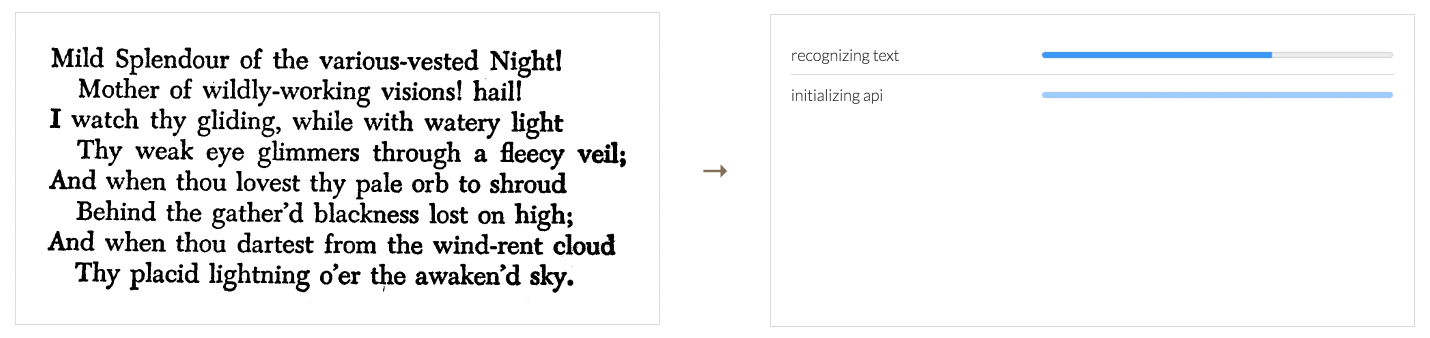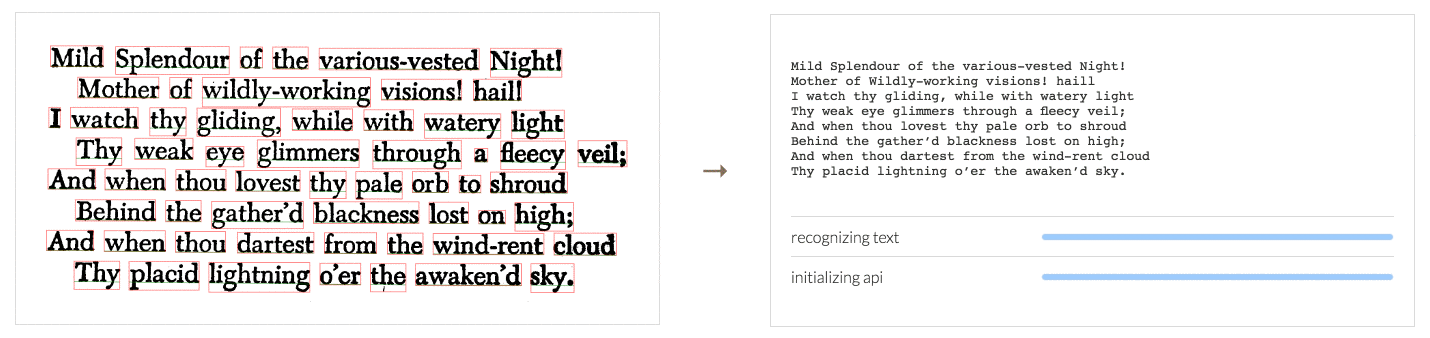
Open source OCR engine for recognizing text in images and scanned documents.
As of , the most-starred Tesseract projects on GitHub are tesseract (77K stars), tesseract.js (38.8K stars) and OCRmyPDF (35.1K stars). GitHub.Locker tracks 5 Tesseract repositories with 162.2K stars combined. The fastest-growing on October 16 was OCRmyPDF, with +15 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +15
OCRmyPDF
ocrmypdf/OCRmyPDF · ★ 35.1KOCRmyPDF adds an OCR text layer to scanned PDF files so the text becomes searchable and copy-pasteable, while keeping the original image intact.
 +11
tesseract
tesseract-ocr/tesseract · ★ 77KTesseract is an open source OCR engine: it ships as the libtesseract library plus a command line program called tesseract that reads text out of images.
 +6
PyMuPDF
pymupdf/PyMuPDF · ★ 10.9KPyMuPDF is a high-performance Python library for extracting, analyzing, converting, rendering, and manipulating PDF and other document formats, built on the MuPDF C engine.
 +1
tesseract.js
naptha/tesseract.js · ★ 38.8KTesseract.js is a pure JavaScript OCR library that extracts text from images in more than 100 languages, running the Tesseract engine compiled to WebAssembly.
The all-time top
5 projects · by stars
- 77K#1 · tesseract-ocr/tesseract
tesseract
Tesseract is an open source OCR engine: it ships as the libtesseract library plus a command line program called tesseract that reads text out of images.
- 38.8K#2 · naptha/tesseract.js
tesseract.js
Tesseract.js is a pure JavaScript OCR library that extracts text from images in more than 100 languages, running the Tesseract engine compiled to WebAssembly.
- 35.1K#3 · ocrmypdf/OCRmyPDF
OCRmyPDF
OCRmyPDF adds an OCR text layer to scanned PDF files so the text becomes searchable and copy-pasteable, while keeping the original image intact.
- 4
PyMuPDF
10.9Kpymupdf/PyMuPDF · PythonPyMuPDF is a high-performance Python library for extracting, analyzing, converting, rendering, and manipulating PDF and other document formats, built on the MuPDF C engine.
- 5
ocr-it
423thiagotigaz/ocr-it · JavaScriptOCR It is a Chrome and Firefox extension for reading paginated documents trapped in a viewer that won't let you select text — a scanned book, a slide deck, a PDF, or any reader. You pin a screen region once, then each hotkey press screenshots that rectangle, OCRs it offline, and appends the text to a running transcript.
Related topics
Often tagged together
- ocr131
- open-source5,666
- pdf287
- cross-platform2,623
- image-processing242
- library1,587
- linux4,184
- macos3,544
- multilingual214
- privacy886
- windows3,403
- apache-2.01,434
- browser404
- cli2,227
- command-line424
- computer-vision384
- deep-learning737
- developer-tools2,924
- document-processing141
- javascript1,842
- python2,383
- text-processing40
- wasm183
- web2,447