



这是什么?
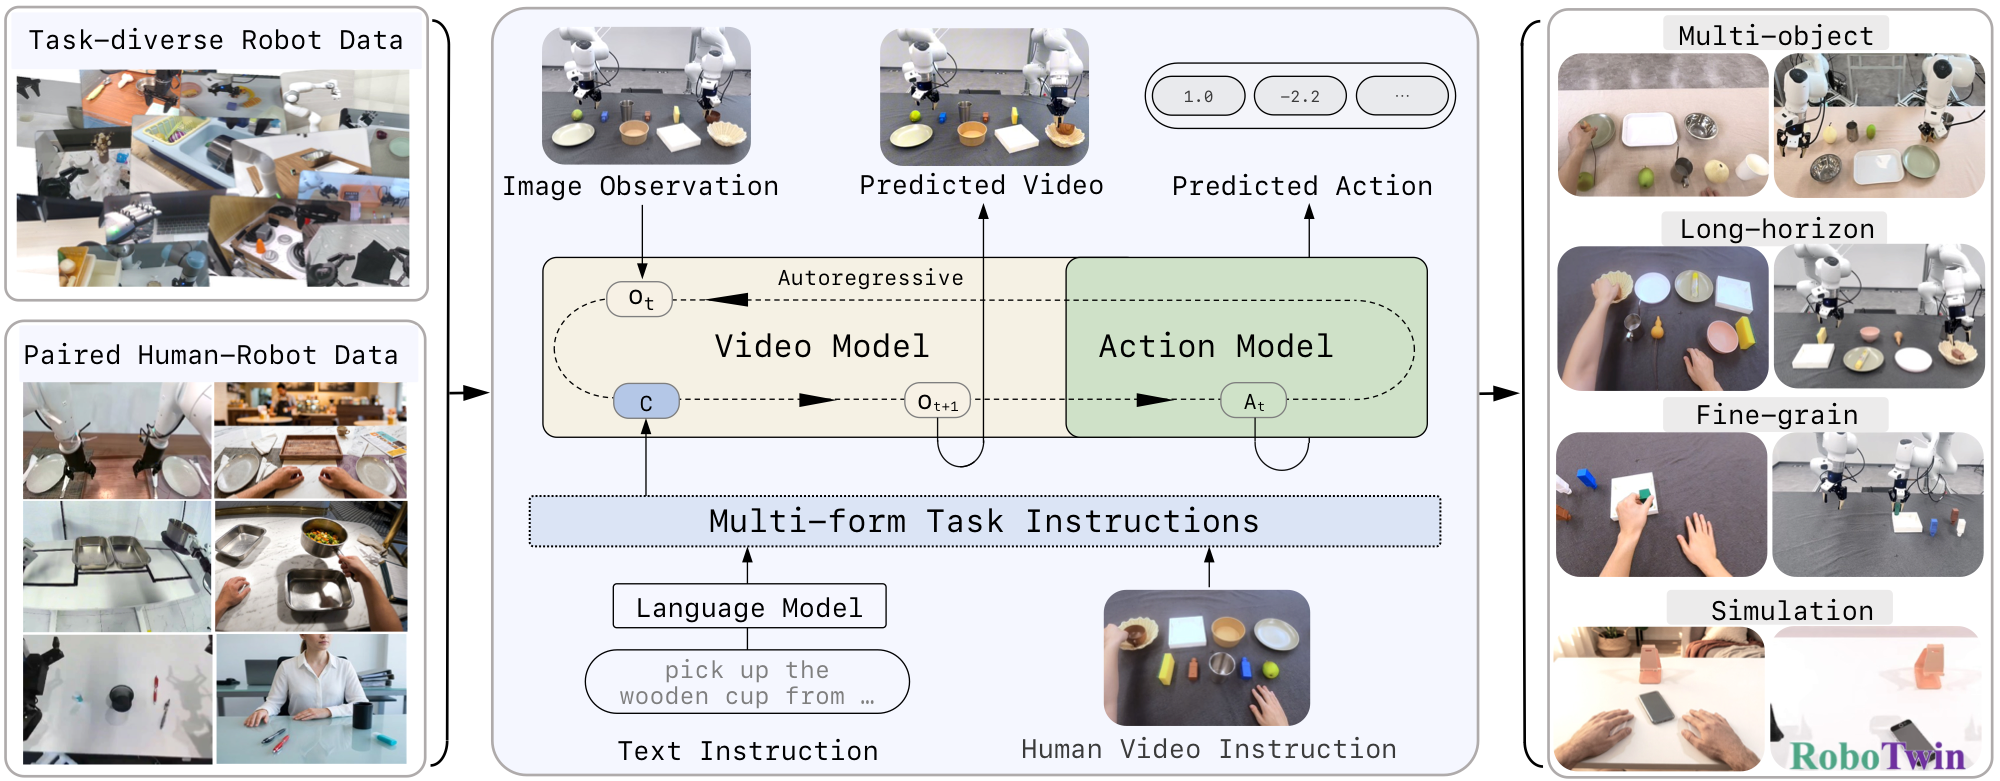
 Zero-WAM 是一种面向零样本跨任务机器人操作的研究方法:它是一个因果视频-动作策略,学习上下文式的世界-动作建模,能从语言指令或人类演示视频中预测未来的机器人观测和可执行动作。
这是一个我能运行的可用代码库,还是目前只是一篇论文?目前它只是一篇论文。代码、训练好的模型和训练数据都尚未发布,各项均标注为预计 2026 年 9 月 15 日之前发布。
目前它只是一篇论文。代码、训练好的模型和训练数据都尚未发布,各项均标注为预计 2026 年 9 月 15 日之前发布。我现在要怎么亲自试用 Zero-WAM?现在还运行不了。该仓库目前只托管论文(arXiv:2608.26103);在本 README 撰写时,代码、预训练模型权重和训练数据都尚未发布。
现在还运行不了。该仓库目前只托管论文(arXiv:2608.26103);在本 README 撰写时,代码、预训练模型权重和训练数据都尚未发布。它真的能把每个操作任务都解决得很好吗?不能。尽管在七个未见过的 RoboTwin 2.0 任务上平均零样本成功率跃升至 46.95%,但有些任务仍然非常难:「Stack blocks three」任务的成功率只有 9.00%,而基线方法为 0%。
不能。尽管在七个未见过的 RoboTwin 2.0 任务上平均零样本成功率跃升至 46.95%,但有些任务仍然非常难:「Stack blocks three」任务的成功率只有 9.00%,而基线方法为 0%。这是面向什么人的?面向从事操作策略以及上下文学习/基于视频学习研究的机器人学和机器学习研究者,而不是想找现成机器人控制器的最终用户,因为目前还没有任何可运行的东西。
面向从事操作策略以及上下文学习/基于视频学习研究的机器人学和机器学习研究者,而不是想找现成机器人控制器的最终用户,因为目前还没有任何可运行的东西。HumanGen 是什么?为什么它很重要?HumanGen 是一条数据管线,把按任务采样的机器人轨迹转换成配对的人类演示视频,在 8.6K 个任务上产出 74.2K 个人类-机器人上下文学习(ICL)配对,使策略能够从人类视频提示中学习,而无需收集更多机器人数据。
HumanGen 是一条数据管线,把按任务采样的机器人轨迹转换成配对的人类演示视频,在 8.6K 个任务上产出 74.2K 个人类-机器人上下文学习(ICL)配对,使策略能够从人类视频提示中学习,而无需收集更多机器人数据。与之前的工作相比,Zero-WAM 的表现如何?在七个未见过的 RoboTwin 2.0 任务上,Zero-WAM 取得 46.95% 的平均零样本成功率,比 LingBot-VA 的 17.45% 高出 29.50 个百分点,也远超 WAN-Action 的 10.98%。
在七个未见过的 RoboTwin 2.0 任务上,Zero-WAM 取得 46.95% 的平均零样本成功率,比 LingBot-VA 的 17.45% 高出 29.50 个百分点,也远超 WAN-Action 的 10.98%。为什么用人类视频而不是只用语言来充当任务指令?人类演示视频作为视觉任务规范比纯文本更丰富、更精确,让因果视频-动作策略能通过观看人类如何完成任务,来推断在未见过的任务上该做什么。
人类演示视频作为视觉任务规范比纯文本更丰富、更精确,让因果视频-动作策略能通过观看人类如何完成任务,来推断在未见过的任务上该做什么。Zero-WAM 用了多少训练数据?它把五个公开机器人数据集按任务多样性重采样后的结果(超过 6K 个任务,每个 epoch 约 400K 条轨迹),与 HumanGen 生成的 74.2K 个人类-机器人 ICL 配对结合起来,后者涵盖外部、内部、仿真和真实世界等来源。
它把五个公开机器人数据集按任务多样性重采样后的结果(超过 6K 个任务,每个 epoch 约 400K 条轨迹),与 HumanGen 生成的 74.2K 个人类-机器人 ICL 配对结合起来,后者涵盖外部、内部、仿真和真实世界等来源。What are similar projects?RoboICL, OpenWAM, flex-pi, video-prediction-policy-2, Motus2, Embodied-AI-Start, Code-as-World, EasyWAM
RoboICL, OpenWAM, flex-pi, video-prediction-policy-2, Motus2, Embodied-AI-Start, Code-as-World, EasyWAMWhich topics is it in?in-context-learning, vision-language-models, world-action-model, vla, data-pipeline, robot, world-models, embodied-ai, arxiv, vision-language-model, paper, robotics
in-context-learning, vision-language-models, world-action-model, vla, data-pipeline, robot, world-models, embodied-ai, arxiv, vision-language-model, paper, robotics