Flex-π: A Multi-Stream World-Action Model with Compute Flexibility
Ge Yan*,
Jinghao Liu*,
Yuzhi Fan*,
Lei Cai,
Minwen Liao,
Jesse Zhang†,
Dieter Fox†
University of Washington · Allen Institute for AI
*Equal contribution · †Equal advising

🔥 Overview
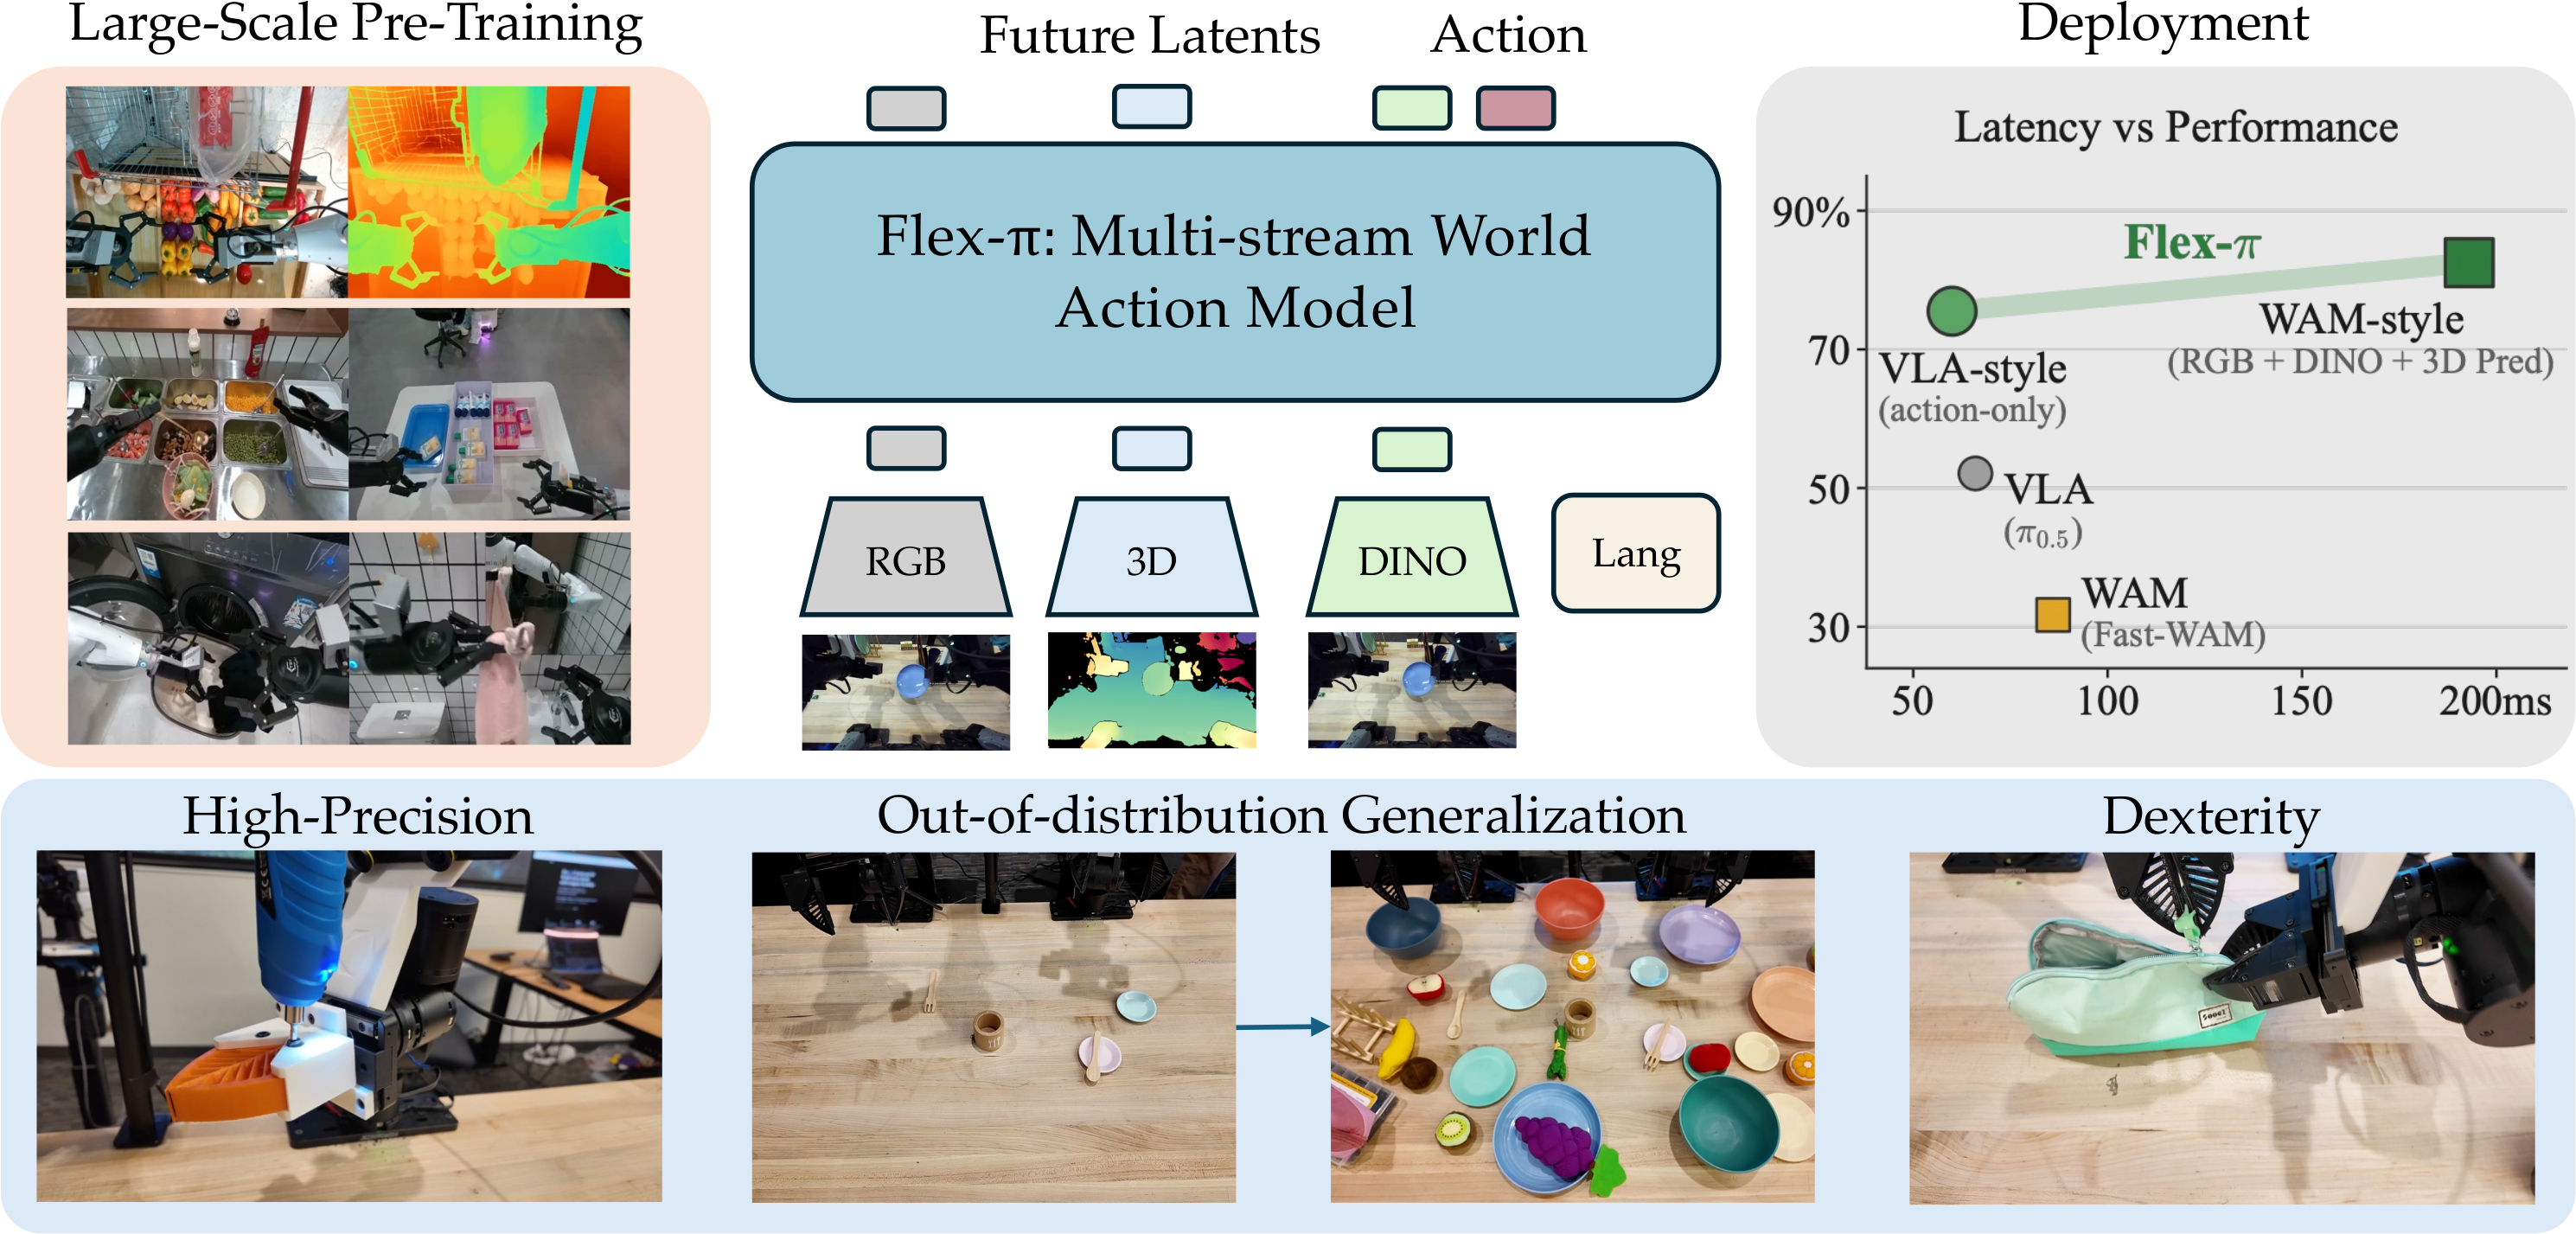
Flex-π is a 6B-parameter world-action model for robot manipulation. It jointly
predicts future RGB, 3D pointmaps, DINOv3 semantics, and actions in
training, then deploys as a VLA, as a full world-action model, or as anything in
between — all from a single checkpoint. Most world-action models predict one thing,
future RGB latents: a strong prior, but one trained to reconstruct pixels, carrying no
explicit signal for the 3D geometry or object semantics that manipulation actually needs.
Geometry and semantics arrive through frozen, off-the-shelf encoders — and the Wan-2.2
video VAE, trained only on RGB pixels, turns out to encode 3D pointmaps
almost losslessly. All three become token streams in one shared latent space,
co-denoised with actions inside a Mixture-of-Transformers. Training then drops visual
streams at random and makes the model generate the ones it never saw as input —
cross-modality forcing — so the backbone has to internalize each modality from the
others. What comes out is one checkpoint that runs any subset of streams, in and
out — action-only at 60 ms, full joint generation at 193 ms, anywhere in between, all
selected by a runtime flag.
Key Features
- One checkpoint, any regime. 56 deployable combinations of observed and generated
streams from one set of weights, from VLA latency to full joint generation. Any input,
any output, no retraining — depth sensor optional.
- VLA latency, WAM performance. Action-only runs at ~60 ms/call on an RTX 5090 —
faster than every baseline we compare against, and still ahead of all of them on every
real-world task. Generating the visual futures too costs latency and wins more.
- Real-world precision and dexterity. Ahead of π0.5, ManiFlow and Fast-WAM
on all five bimanual YAM tasks — 2.3× the success rate of the strongest — including
an eight-stage gripper self-repair whose tightest insertion leaves ±0.25 mm of
clearance, and the most robust to unseen objects and clutter.
- Learns from fewer demonstrations. The world-action objective stands in for data:
1.9–4.5× the success of the baselines at 50–100 RoboTwin demos per
task, and on the real robot half the demonstrations still beat every baseline trained on
all of them. At full data: 94.6% on RoboTwin's 50 tasks, up to 99.2% on LIBERO.
✨ News
📋 Table of Contents
📦 Model Download
We plan to release large-scale checkpoints pre-trained on YAM, AgiBot World, and
DROID. Stay tuned!
💻 Requirements
Linux x86_64, CUDA 12.8, Python 3.10.
| Mode |
Memory |
GPUs |
| Inference, deployment |
16–26 GB |
1 × RTX 4090 / 5090 |
| Training |
80 GB each |
4–8 × A100 80GB / H100 / H200 |
Inference peaks are measured on an RTX 5090; the top of the range is the TensorRT
stack. The launchers assume 8 GPUs; 4 is the floor, and proportionally slower. LoRA
fine-tuning, which would lower that floor, is planned.
🔧 Installation
git clone --recurse-submodules https://github.com/geyan21/flex-pi.git
cd flex-pi
Then follow docs/INSTALL.md — conda, uv and Docker recipes for
the one environment that covers training, evaluation and deployment, plus the weights
and the simulators. Everything after this point runs from the repository root.
Repository layout
flex-pi/
├── docs/
│   ├── INSTALL.md              # conda / uv / Docker, weights, verification
│   ├── OVERVIEW.md             # architecture and training/eval workflow
│   ├── TRAINING.md             # end-to-end training guide (every launcher knob)
│   ├── LIBERO.md               # LIBERO 4-suite training + evaluation
│   ├── ROBOTWIN.md             # RoboTwin 2.0 training + evaluation
│   ├── YAM.md                  # real-world training + robot deployment
│   └── INFERENCE_OPTIMIZATION.md   # measured latency per stack + engine builds
├── src/flexpi/
│   ├── models/
│   │   ├── flexpi.py            # the Flex-π model
│   │   ├── backbone.py          # multi-stream backbone
│   │   ├── mot.py               # Mixture-of-Transformers core
│   │   ├── action_dit.py        # action expert (~1B)
│   │   ├── dino_encoder.py      # frozen DINOv3 tokenizer
│   │   ├── pointmap_encoder.py  # pointmap → shared VAE latent space
│   │   ├── wan_video_{dit,vae,text_encoder}.py
│   │   └── helpers/flex_joint.py  # per-sample stream/joint sampling
│   ├── datasets/lerobot/        # multi-camera LeRobot dataset + processors
│   ├── trainer.py               # AdamW + cosine + bf16 + DeepSpeed ZeRO
│   └── runtime.py               # create_flexpi() factory
├── configs/
│   ├── model/flexpi.yaml        # architecture + flex_joint knobs
│   ├── data/                    # dataset presets, one per benchmark
│   │   ├── {robotwin,libero,yam}.yaml       # what the task configs select
│   │   └── {robotwin,libero}_nodepth.yaml   # same, minus the depth stream
│   ├── task/                    # training presets (see table below)
│   ├── train.yaml               # training defaults
│   └── sim_{robotwin,libero}.yaml, real_yam.yaml   # evaluation defaults
├── scripts/
│   ├── train.py                        # Hydra entry point
│   ├── train_flexpi_{robotwin,libero,yam}.sh   # per-benchmark launchers
│   ├── preprocess_action_dit_backbone.py
│   ├── precompute_text_embeds.py
│   ├── serve_yam_flexpi.py             # real-robot WebSocket policy server
│   ├── serve_flexpi_yam.sh             # its launcher (edit config block, run)
│   ├── da3_depth/                      # add DA3 depth to an RGB-only dataset
│   └── inference_opt/                  # TensorRT export + latency benchmarks
├── experiments/
│   ├── robotwin/    # eval manager + RoboTwin policy wrapper
│   ├── libero/      # eval entry points + 4-suite summariser
│   └── yam/         # real-robot client, bridges, action smoothing
└── third_party/
    ├── RoboTwin/    # vendored eval harness (see README.vendor.md)
    └── LIBERO/      # submodule
🧩 Model Preparation
Run once, before the first training run.
cd flex-pi                      # the project directory
mkdir -p checkpoints
export DIFFSYNTH_MODEL_BASE_PATH="$(pwd)/checkpoints"
Then fetch the weights — Wan2.2-TI2V-5B plus the resampled ActionDiT backbone, the
T5 text-embedding cache, and DINOv3. Refer to
docs/INSTALL.md §2.
📊 Data Preparation
Every dataset is published at huggingface.co/flex-pi,
ready to train on as downloaded. To build your own instead, the layout to match is a
LeRobot v2.1 dataset with canonical camera keys — docs/TRAINING.md §1.2.
| Benchmark |
Repository |
| LIBERO |
libero_mujoco3.3.2_depth — all four suites |
| RoboTwin 2.0 |
robotwin_3d, plus robotwin_3d_text_embeds_cache to skip the T5 precompute |
| Real-world YAM |
one per task — put_plate_on_the_rack, sort_utensils, kitchen_organization, soft_bag_zipping, self_repair_gripper_bc, self_repair_gripper_dagger |
huggingface-cli download flex-pi/libero_mujoco3.3.2_depth \
  --repo-type dataset --local-dir ./data/libero_mujoco3.3.2_depth
🚀 Training
Each benchmark has a launcher that wraps accelerate launch scripts/train.py with
DeepSpeed ZeRO-1. Edit the config block at the top of one — GPUs, batch size, epochs,
dataset paths — and run it.
# RoboTwin
bash scripts/train_flexpi_robotwin.sh

# LIBERO 4-suite
bash scripts/train_flexpi_libero.sh

# Real-world YAM bimanual
DATASET_DIRS="[./data/<your_yam_set>]" bash scripts/train_flexpi_yam.sh
They default to 8 GPUs and write to
runs/<task_config>/<run_id>_<regime_tag>/ — the config.yaml and
dataset_stats.json that evaluation reads back land there beside the checkpoints.
Every knob and recipe is in docs/TRAINING.md, and each
benchmark has an end-to-end guide: RoboTwin ·
LIBERO · YAM.
🎯 Evaluation
Both need their simulator installed
(docs/INSTALL.md §4). Match the GPU
count to your machine.
RoboTwin 2.0
huggingface-cli download flex-pi/flexpi-robotwin --local-dir runs/flexpi-robotwin

# then set these two lines at the top of scripts/eval_flexpi_robotwin.sh:
#   CKPT="./runs/flexpi-robotwin/checkpoints/weights/step_048060.pt"
#   DATASET_STATS="./runs/flexpi-robotwin/dataset_stats.json"

bash scripts/eval_flexpi_robotwin.sh
The defaults are the full-joint regime; setting the three INFER_JOINT_* flags to
false gives action-only. A full sweep is 50 tasks × 2 phases × 100
episodes.
LIBERO
huggingface-cli download flex-pi/flexpi-libero-fulljoint-star \
  --local-dir runs/flexpi-libero-fulljoint-star

CKPT=$(ls runs/flexpi-libero-fulljoint-star/checkpoints/weights/*.pt) \
DATASET_STATS=runs/flexpi-libero-fulljoint-star/dataset_stats.json \
GPUS=0,1,2,3,4,5,6,7 \
  bash scripts/eval_flexpi_libero_4suite.sh
It shards the 40 tasks across the GPUs and writes summary_4suite.{csv,json}. A
partial sweep is reported as INCOMPLETE rather than averaged silently.
Protocol, knobs and troubleshooting: RoboTwin
· LIBERO ·
YAM.
🔀 Inference Regimes
infer_joint_* picks what gets generated, infer_present_* what gets encoded
as input — 56 combinations from one checkpoint. An unset flag takes the trained
default.
# action only — the fast path
python experiments/robotwin/run_robotwin_manager.py task=... ckpt=... \
  +EVALUATION.infer_joint_video=false \
  +EVALUATION.infer_joint_dino=false \
  +EVALUATION.infer_joint_pointmap=false

# full joint generation — the accurate path
python experiments/robotwin/run_robotwin_manager.py task=... ckpt=... \
  +EVALUATION.infer_joint_video=true \
  +EVALUATION.infer_joint_dino=true \
  +EVALUATION.infer_joint_pointmap=true
The eval launchers wrap these as INFER_JOINT_* / INFER_PRESENT_*, with the full
regime table in their headers.
🦾 Real-World Deployment
The policy runs as a WebSocket server; the robot client sends observations and
receives action chunks.
conda activate flexpi
export DIFFSYNTH_MODEL_BASE_PATH=/path/to/wan22_weights
python scripts/serve_yam_flexpi.py \
    --ckpt-path <run>/checkpoints/weights/step_NNNNNN.pt \
    --default-prompt "<language instruction>"
dataset_stats.json and config.yaml are picked up next to the checkpoint.
scripts/serve_flexpi_yam.sh wraps this with the regime
(--infer-joint-* / --infer-present-*) and TensorRT knobs already wired up.
The msgpack wire contract a client must speak, and the reference bridge, live in
experiments/yam/flexpi_policy/.
docs/YAM.md covers the three serving configurations, that wire
contract, and the rules that have caused emergency stops on real hardware.
⚡ Inference Optimization
Training-free — the same checkpoint, made faster. ms/call on an RTX 5090 at four
denoise steps:
| Stack |
full joint |
action only |
| eager PyTorch |
447 |
132 |
| torch.compile — the default |
360 |
60 |
| + TensorRT joint engine |
230 |
— |
| + TensorRT KV-split engines |
193 |
— |
TensorRT is optional and applies to the joint path only; everything runs without it.
scripts/inference_opt/benchmark_flex_latency.py reproduces
the table, and docs/INFERENCE_OPTIMIZATION.md has the
engine builds and the server knobs.
📜 License
MIT — see LICENSE. Vendored third-party code keeps its own
license; see third_party/*/README.vendor.md.
🙏 Acknowledgements
Flex-π builds on Wan2.2 for the video
backbone and VAE, DINOv3 for semantic
features, and Depth Anything 3
for pointmap annotation. The RoboTwin evaluation harness is adapted from the
RoboTwin repository, and the
codebase inherits structure from
Fast-WAM. Pre-training data comes from
AgiBot World, and the real-robot
YAM data collection and control run on
raiden. We thank all of these teams for
releasing their work.
📖 Citation
@article{yan2026flexpi,
  title   = {Flex-$\pi$: A Multi-Stream World-Action Model with Compute Flexibility},
  author  = {Yan, Ge and Liu, Jinghao and Fan, Yuzhi and Cai, Lei and Liao, Minwen
             and Zhang, Jesse and Fox, Dieter},
  journal = {arXiv preprint arXiv:2608.10860},
  year    = {2026},
  url     = {https://arxiv.org/abs/2608.10860}
}

 Flex-π is a 6B-parameter world-action model for robot manipulation that jointly predicts future RGB, 3D pointmaps, DINOv3 semantics, and actions from one checkpoint, so it can deploy as a VLA, a full world model, or anything in between.