
ds4 README

The project's README from github.com/antirez/ds4. As one markdown file: README.md.

DwarfStar logo

DwarfStar aims to be the best way to run a few excellent large language models on consumer hardware (that is, hardware that people can actually own). To reach this goal, we are building a small native inference engine optimized first for DeepSeek V4 Flash (including the experimental vision model), and additionally GLM 5.2 and 5.3, GLM 5.3 Flash and DeepSeek V4 PRO. The code is self-contained and deliberately narrow, not a general GGUF runner: you need to use the GGUF files the project produces, that are part of the project itself.

We test things in integration: model loading, prompt rendering, tool calls, KV state, the HTTP server, and the coding agent are built and tested together. The repository also includes tools and data for GGUF, imatrix, quality, and speed.

Supported hardware

This project would not exist without llama.cpp and GGML, make sure to read the acknowledgements section, a big thank you to Georgi Gerganov and all the other contributors.

Model support is intentionally opportunistic. The project follows the best open weights for useful local machine sizes, especially 128 GB laptops and 256/512 GB workstations. A model may be removed when a better replacement arrives.

So, what can I do with this software?

Motivations

AI full disclosure

Acknowledgements to llama.cpp and GGML

ds4.c does not link against GGML, but it exists thanks to the path opened by the llama.cpp project and the kernels, quantization formats, GGUF ecosystem, and hard-won engineering knowledge developed there. We are thankful and indebted to llama.cpp and its contributors. Their implementation, kernels, tests, and design choices were an essential reference while building this DeepSeek V4 specific inference path. Some source-level pieces are retained or adapted here under the MIT license: GGUF quant layouts and tables, CPU quant/dot logic, and certain kernels. For this reason, and because we are genuinely grateful, we keep the GGML authors copyright notice in our LICENSE file.

Status

The software is currently very fast changing. Consider it beta quality. Before each release, a big QA run is executed, however instabilities and regressions are definitely possible.

How to use this project?

I (Salvatore) believe that the way projects should be shipped and used changed because of AI. The main differences today are:

  1. With AI, users can modify the software in significant ways with low efforts, costs, and even lacking deep domain knowledge about the task they want to accomplish. For instance, a DwarfStar user with a specific hardware setup can ask a coding agent to improve the inference speed of this software for the specific hardware setup, asking the model to reach the maximum prefill and generation speed without impacting correctness, and also asking to do a deep QA pass.
  2. Similiarly, because of "1", software may be shipped in a different way than before. It must be more a working template for the biggest use cases, without trying to cover every possible setup. If DwarfStar showcases a few good implementations of tensor parallel execution, the code will work as a rail for implementing the same feature in specific conditions, for a new model, and so forth.

So, while this project attempts to be usable for the featured models and the most common hardware setups, I ask you, if you have access to coding agents, to consider using coding agents as an interface to discover the project, make modifications, create personalized setups. This way you can likely do more than what we ship, and certain things that are not documented or implemented, and that you require, are potentially very easy to achieve.

Start Here

git clone https://github.com/antirez/ds4.git
cd ds4

Choose your build. The platform guides cover prerequisites, memory sizing, and hardware-specific setups:

Platform guide Build
Metal on Apple Silicon make
DGX Spark make cuda-spark
Strix Halo / Framework Desktop make strix-halo
One or more CUDA cards, including Ada/L40S make cuda-generic

For a first run on a 96 or 128 GB machine, download DeepSeek V4 Flash Q2:

./download_model.sh ds4f-q2

Downloads go in gguf/. Repeat the command to resume an interrupted download. Leave memory for the context and runtime buffers as well as the model. See other models or use SSD streaming on a smaller Mac.

Everyday Use

Once built and with a model downloaded:

./ds4
./ds4 -p "Explain Redis streams in one paragraph."
./ds4-agent
./ds4-server --ctx 32768

The default model is ds4flash.gguf, a link updated by main-model downloads. Pass -m FILE to choose explicitly. Commands normally run from the repository root; use --chdir /path/to/ds4 when launching elsewhere.

The server listens at http://127.0.0.1:8000 by default; see serving for API access and multiple sessions.

The interactive CLI keeps a multi-turn conversation. Use /help, /read FILE, /ctx N, and /quit. Ctrl+C interrupts generation and returns to the prompt. Run each binary with --help for its full options.

Native coding agent

ds4-agent runs inference directly, without a separate HTTP server. It keeps the token history and live model state together, shows prefill progress, and uses the model's native tool format. DeepSeek and GLM have their own templates.

Use /hints on for occasional, brief explanations of the programming choices behind the work, and /hints off to stop them. Changes take effect at the next conversation boundary without rebuilding the cached context. New and resumed sessions start with hints off.

Sessions are stored in ~/.ds4/kvcache:

Command Action
/save Save the current session
/list List saved sessions
/switch <sha> Resume a session
/del <sha> Delete a saved session
/strip <sha> Keep text and title, removing the large KV payload

Compatible local KV snapshots avoid rebuilding the prompt. Stripped sessions and network TP restores require prefill. Sessions containing images cannot yet be saved. Saved conversations and traces may contain private information.

For Pi, OpenCode, Codex CLI, or Claude Code, use ds4-server instead and follow the client setup guide.

Models, images, and speculation

Models and vision lists the supported downloads and memory requirements. DeepSeek Vision Experimental uses a different checkpoint from Flash 0731; GLM 5.3 Flash adds vision to the same text model.

With the matching encoder passed as --vision FILE, use /read image.png in the CLI or view_image in the native agent.

Speculative decoding is opt-in. GLM uses --mtp; Flash DSpark needs a matching support GGUF. It can improve generation, but not every workload benefits. Read speculative decoding for setup and the difference between default opportunistic sampling and --mtp-exact-sampling.

Output and power

Thinking is enabled by default. Use --nothink or /nothink for direct answers, and --think or /think to enable it again. The normal sampling defaults are temperature 1, top-p 1, and min-p 0.05; --temp 0 selects greedy output.

For DeepSeek, --power N trades throughput for lower sustained GPU load. The default is 100. GLM currently requires --power 100.

DeepSeek Flash and GLM 5.3 Flash also support directional steering. Load a vector with --dir-steering-file FILE; /steer F adjusts its scale for subsequent tokens in a local CLI or agent session, without rebuilding the existing KV cache. See steering documentation.

--prefix-file FILE preloads complete USER: / ASSISTANT: pairs before the live conversation. A turn marker must start a line, roles must alternate, and the last turn must be ASSISTANT:.

Capability Evaluation

ds4-eval runs embedded capability regression tests against a real GGUF. These are DwarfStar integration checks, not official leaderboard scores.

./ds4-eval -m ds4flash.gguf --trace /tmp/ds4-eval.txt
./ds4-eval -m ds4flash.gguf --suite hard-smoke
./ds4-eval -m ds4flash.gguf --suite hard --retry-incomplete

The default suite is core; --suite all runs core and hard cases. --list-cases lists tests without loading a model. --plain selects non-interactive output, and --regrade-trace FILE scores an existing trace without generating again. Sources and licenses are in EVAL_DATA.md. For inference correctness and release checks, read testing.

Speed

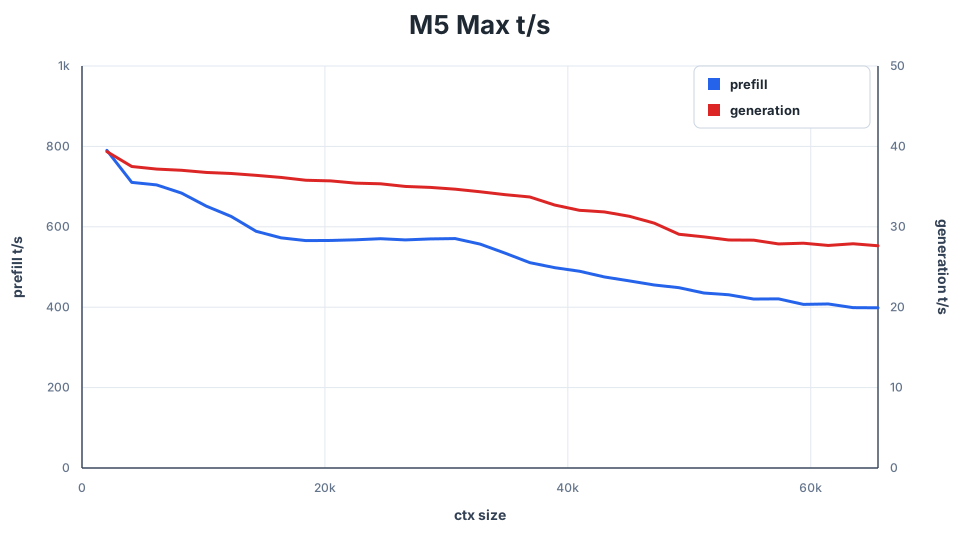
This recorded DeepSeek V4 Flash Q2 sweep uses an M5 Max with 128 GB RAM, 2048-token continued-prefill intervals, and 128 greedy generation tokens per frontier. It is a baseline, not a fresh benchmark of every commit.

M5 Max Flash Q2 throughput

See performance and benchmarking for the full numbers, DGX Spark results, comparison conditions, and benchmark commands.

Detailed Guides

Read CONTRIBUTING.md before sending a pull request.

The DwarfStar logo was designed by hand by Salvatore Sanfilippo, made more graphical with AI, and manually reworked by Ben Gnomino, whose human touch made it rock.

ds4 (antirez/ds4)

Searching Database…

23.9K ·GitHub
Что это такое?DwarfStar (ds4) — небольшой автономный движок локального инференса, специализированный на запуске DeepSeek V4 Flash и PRO, а также GLM 5.2/5.3, на потребительском железе: Mac с большим объёмом памяти, видеокартах NVIDIA и системах AMD Strix Halo.
Это универсальный запускатель GGUF-моделей вроде llama.cpp?Нет, он намеренно узкий: работает только с GGUF-файлами, которые создаёт сам проект, а не с любыми GGUF-моделями, потому что он собран и протестирован как единая система вокруг нескольких конкретных моделей.
Как собрать и запустить?Выберите команду сборки для своего железа: 'make' для Metal на Apple Silicon, 'make cuda-spark' для DGX Spark, 'make cuda-generic' для других карт CUDA или 'make strix-halo' для ROCm. Затем скачайте модель, например DeepSeek V4 Flash Q2, в папку gguf/ и запустите бинарный файл.
Какое железо нужно для запуска?Mac с 96 ГБ оперативной памяти или больше для Metal, видеокарты NVIDIA с CUDA (включая DGX Spark и Ada Lovelace/L40S для конфигураций с несколькими GPU) или система ROCm, например Framework Desktop с Strix Halo; на более слабых машинах можно перейти на потоковую загрузку с SSD.
Достаточно ли стабилен проект для ежедневного использования?Проект называет себя бета-качеством и быстро меняющимся; хотя перед каждым релизом проходит проверка качества, нестабильность и регрессии всё ещё возможны.
Что-то из моих диалогов сохраняется локально, и это безопасно?Сессии сохраняются локально в ~/.ds4/kvcache, и проект предупреждает, что в этих сохранённых данных может содержаться личная информация.
В чём разница между CLI, ds4-agent и ds4-server?Интерактивный CLI поддерживает многоходовой диалог для общения с моделью, ds4-agent запускает инференс напрямую как нативного агента для написания кода, используя собственный формат вызова инструментов модели, а ds4-server предоставляет HTTP API для внешних клиентов.
Можно ли запускать модели, которые не помещаются в память видеокарты или в оперативную память?Да, потоковая загрузка с SSD позволяет запускать модели, превышающие объём оперативной памяти, включая полную GLM 5.x на системах с 128 ГБ, передавая веса с быстрых локальных SSD с приемлемой скоростью.
Можно ли объединить несколько машин, чтобы запускать более крупные модели?Да, два Mac с 128 ГБ памяти, соединённые через RDMA, могут запускать 4-битные DeepSeek Flash или GLM 5.3 Flash с тензорным параллелизмом, а конвейерный параллелизм позволяет связывать системы в цепочку и объединять их оперативную память.
Зачем создавать новый движок, а не использовать llama.cpp?DwarfStar намеренно узкий и автономный, настроен специально под DeepSeek V4 Flash/PRO и GLM 5.x на потребительском железе с большим объёмом памяти, а не пытается быть универсальным запускателем GGUF для любых моделей.
Creator
antirez
Size
32.9 MB
Stars
23.9K
Updated
CommitOct 07
Age
5mo
Commits · 90 Days