ZDTaichu5.0-9B
English | 简体中文
Blog | ModelScope | Hugging Face
Model Downloads
Introduction
ZDTaichu5.0-9B is a multimodal foundation model for general visual understanding, spatial reasoning, agentic tool use, and embodied-AI research. It combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder, supports text, images and videos with any-resolution visual input.
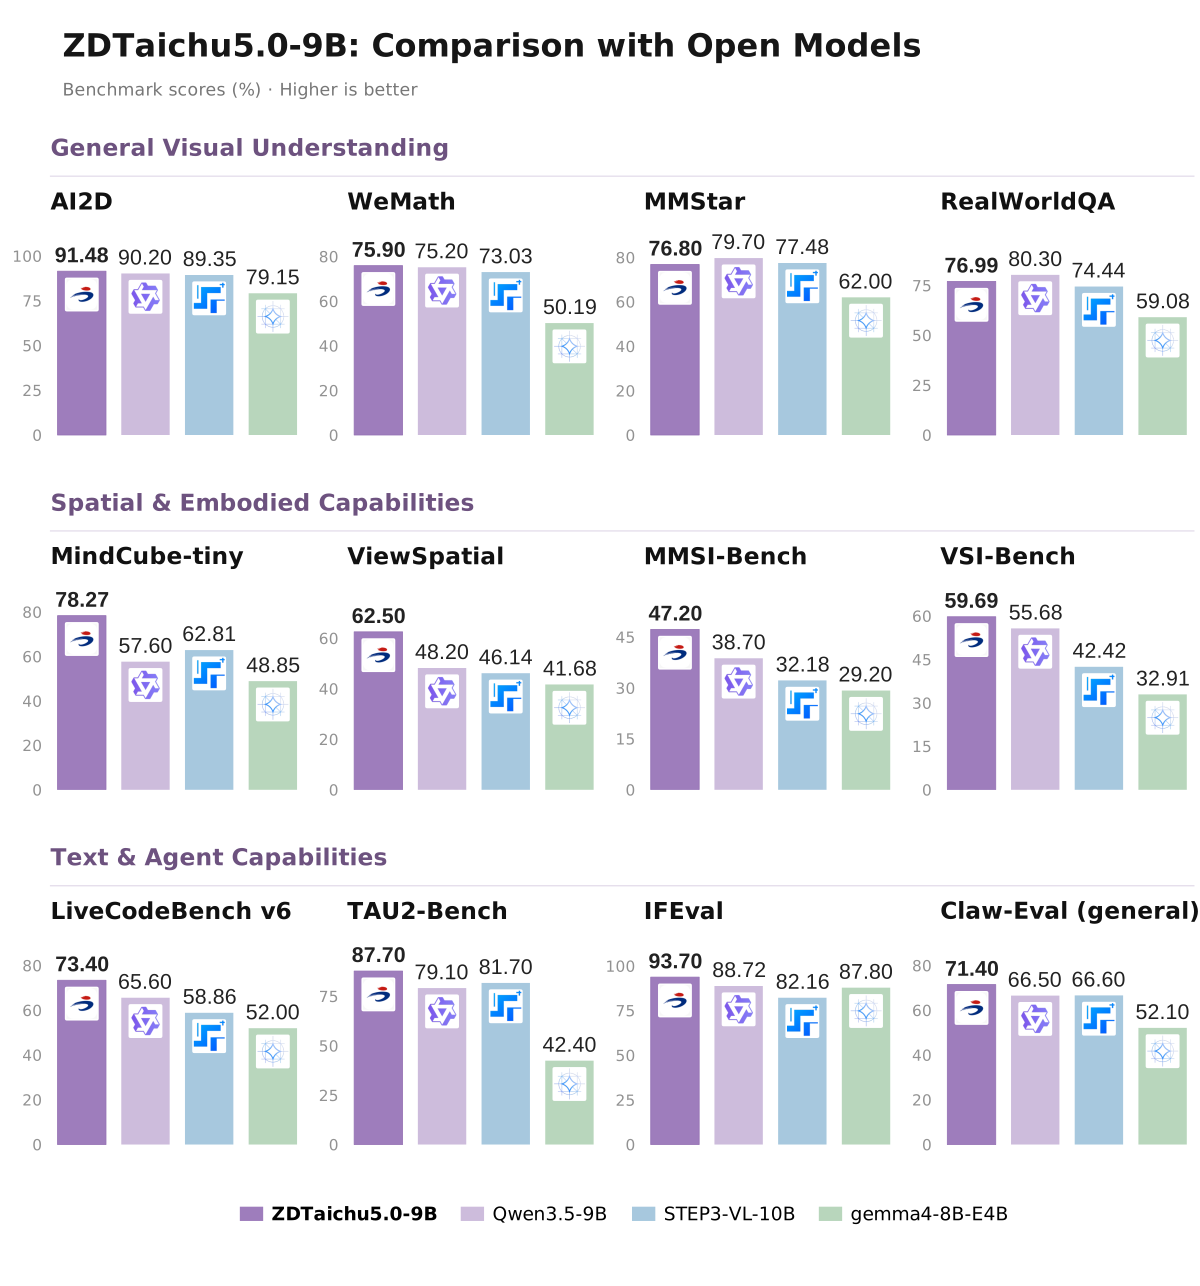
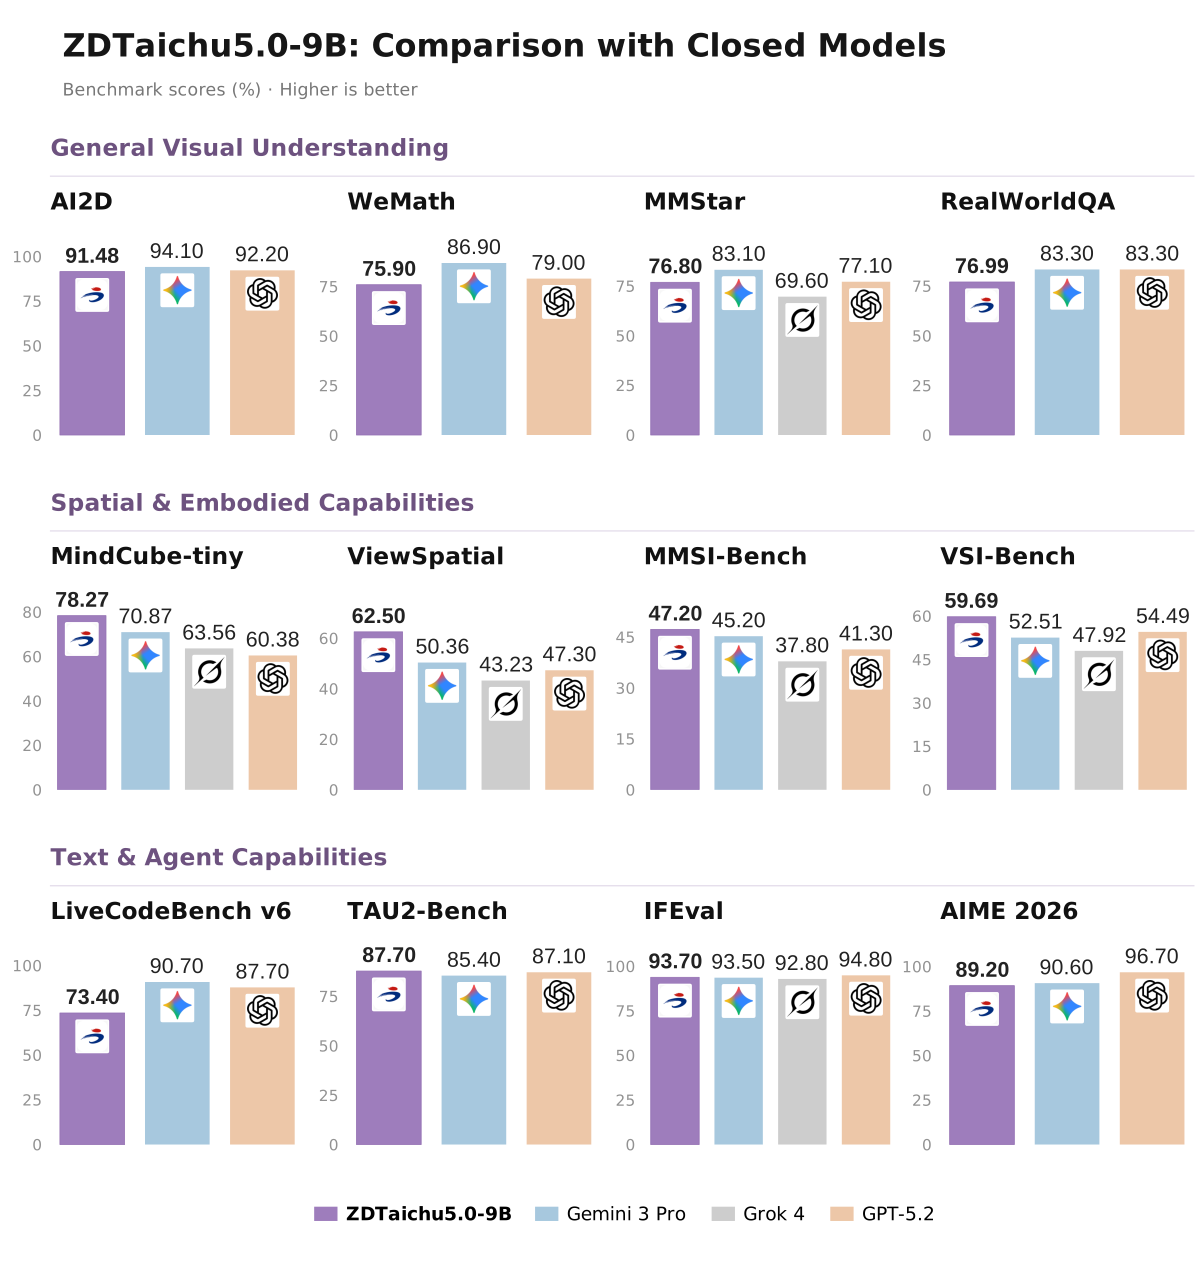
Within the 10B-scale general-purpose VLMs compared in this release blog, ZDTaichu5.0-9B retains first-tier general visual understanding while supporting spatial reasoning, high-level embodied VLM reasoning, and agent tasks under the reported evaluation settings. Rather than trading broad visual competence for specialization, it layers a more comprehensive spatial, embodied, and agent capability profile on top of a strong general-vision foundation.
The model accepts text, one or more images, and video. It is designed for:
- general image, document, chart, diagram, and OCR understanding;
- visual mathematics and knowledge-grounded visual question answering;
- fine-grained 2D relations, multi-view association, 3D scene understanding, perspective taking, and mental transformation;
- multi-step and multi-turn tool use;
- spatial perception, affordance understanding, and planning for VLA and embodied-AI adaptation.
More demos and showcases are provided at
Blog.
Highlights
- Strong general vision and broad capabilities: remains in the leading group of 10B-scale general-purpose VLMs across images, documents, charts, diagrams, OCR, visual mathematics, multiple images and video, while extending to spatial reasoning, high-level embodied understanding and multi-step agent tasks.
- Leading spatial reasoning and embodied understanding: leads spatial capability among the compared 10B-scale general-purpose VLMs, with strong results on SparBench, ViewSpatial, MMSI-Bench and MindCube-tiny. Scores of 48 on ERQA and 56 on RoboSpatial cover scene reasoning, affordances and interaction-oriented understanding.
- Strongest agent capability among the compared 10B-scale general-purpose VLMs: leads the reported TAU2-Bench (87.7) and Claw-Eval (71.4) comparisons, and reaches 93.7 on IFEval.
- Entropy-Gated Adaptive Recurrent Reasoning: Dynamically allocates additional recurrent refinement steps in latent space to more challenging tokens, enabling greater computational depth where needed and improving reasoning performance on complex tasks. Details could be found Here
Benchmark Results
The two figures compare ZDTaichu5.0-9B with open and closed models across general visual understanding, spatial and embodied capabilities, and agent and text capabilities.
Comparison with open models
Comparison with closed models
Spatial and embodied reasoning
| Area |
Benchmark |
ZDTaichu5.0-9B |
Qwen3.5-9B |
STEP3-VL-10B |
gemma4-8B-E4B |
Gemini 3 Pro |
Grok 4 |
GPT-5.2 |
| Basic spatial perception |
CV-Bench |
86.82 |
87.19 |
83.49 |
68.10 |
90.07 |
— |
86.84 |
| 3DSRBench |
60.96 |
56.78 |
55.01 |
53.62 |
68.92 |
54.93 |
60.20 |
| SparBench |
51.82 |
50.79 |
45.68 |
28.50 |
48.74 |
44.76 |
55.07 |
| Complex spatial reasoning |
ViewSpatial |
62.50 |
48.20 |
46.14 |
41.68 |
50.36 |
43.23 |
47.30 |
| MMSI-Bench |
47.20 |
38.70 |
32.18 |
29.20 |
45.20 |
37.80 |
41.30 |
| MindCube-tiny |
78.27 |
57.60 |
62.81 |
48.85 |
70.87 |
63.56 |
60.38 |
| Embodied interaction |
ERQA |
48.00 |
41.50 |
47.75 |
30.20 |
66.00 |
— |
59.80 |
| RoboSpatial |
56.00 |
54.10 |
52.86 |
49.43 |
57.40 |
— |
43.78 |
| VSI-Bench |
59.69 |
55.68 |
42.42 |
32.91 |
52.51 |
47.92 |
54.49 |
General visual understanding
| Area |
Benchmark |
ZDTaichu5.0-9B |
Qwen3.5-9B |
STEP3-VL-10B |
gemma4-8B-E4B |
Gemini 3 Pro |
Grok 4 |
GPT-5.2 |
| Multi modal Reasoning |
MathVista Mini |
84.50 |
85.70 |
83.97 |
65.30 |
87.90 |
72.50 |
83.10 |
| WeMath |
75.90 |
75.20 |
73.03 |
50.19 |
86.90 |
— |
79.00 |
| MathVerse Mini Vision Only |
76.40 |
84.14 |
74.60 |
53.55 |
— |
— |
— |
| General VQA |
MMStar |
76.80 |
79.70 |
77.48 |
62.00 |
83.10 |
69.60 |
77.10 |
| AI2D |
91.48 |
90.20 |
89.35 |
79.15 |
94.10 |
— |
92.20 |
| RealWorldQA |
76.99 |
80.30 |
74.44 |
59.08 |
83.30 |
— |
83.30 |
| OCR |
OCRBench |
85.50 |
89.20 |
86.75 |
76.90 |
90.40 |
— |
80.70 |
Language, reasoning, and agents
| Area |
Benchmark |
ZDTaichu5.0-9B |
Qwen3.5-9B |
STEP3-VL-10B |
gemma4-8B-E4B |
Gemini 3 Pro |
Grok 4 |
GPT-5.2 |
| Knowledge |
MMLU-Pro |
77.20 |
82.50 |
76.02 |
69.40 |
89.80 |
85.90 |
87.40 |
| MMLU-Redux |
88.40 |
91.10 |
86.50 |
85.30 |
95.90 |
86.22 |
95.00 |
| Instruction following |
IFEval |
93.70 |
88.72 |
82.16 |
87.80 |
93.50 |
92.80 |
94.80 |
| IFBench |
69.00 |
64.50 |
41.49 |
34.70 |
70.40 |
53.70 |
75.40 |
| Reasoning and coding |
AIME 2025 |
86.70 |
83.75 |
87.66 |
41.30 |
95.00 |
91.70 |
100.00 |
| AIME 2026 |
89.20 |
87.92 |
88.75 |
42.50 |
90.60 |
— |
96.70 |
| HMMT Feb 2025 |
84.20 |
83.20 |
78.18 |
26.70 |
97.30 |
90.00 |
99.40 |
| HMMT Feb 2026 |
72.70 |
73.48 |
63.64 |
33.70 |
86.36 |
— |
96.97 |
| LiveCodeBench v6 |
73.40 |
65.60 |
58.86 |
52.00 |
90.70 |
— |
87.70 |
| General agent |
TAU2-Bench† |
87.70 |
79.10 |
81.70 |
42.40 |
85.40 |
— |
87.10 |
| Claw-Evalgeneral Avg† |
71.40 |
66.50 |
66.60 |
52.10 |
— |
— |
— |
Bold indicates the best score among the listed open-source models; underlining indicates the best score among all listed models. Scores leading both comparisons are both bold and underlined. Tied best scores receive the same marking. Missing scores are excluded from the comparison.
† Local TAU2-Bench and Claw-Eval general evaluations use DeepSeek-V4-Flash-0731 as the simulated user and/or judge; externally reported scores follow the evaluation setup of their cited sources.
‡ Publicly reported external score. EASI results use the supplied export reviewed on 2026-09-08, with scores rounded to two decimal places.
For multi-image spatial reasoning evaluations such as ViewSpatial, MMSI-Bench, MindCube-tiny, and VSI-Bench, the following output-format requirement was added to the evaluation prompt: You FIRST think about the reasoning process as an internal monologue and then provide the final answer. The reasoning process MUST BE enclosed within tags. The final answer MUST BE put in \boxed{}.
Quickstart
Installation
Install a recent version of Hugging Face Transformers together with the standard multimodal dependencies:
pip install tranformer==5.3.0 torch==2.10.0 torchvision==0.25.0 accelerate timm
Offline inference
export CUDA_VISIBLE_DEVICES=0
import os

import torch
from transformers import AutoModel, AutoProcessor

model_id = os.environ["ZDTAICHU_MODEL_ID"]
processor = AutoProcessor.from_pretrained(
    model_id,
    trust_remote_code=True,
    use_fast=False,
)
model = AutoModel.from_pretrained(
    model_id,
    trust_remote_code=True,
    torch_dtype=torch.bfloat16,
    device_map="auto",
    attn_implementation="sdpa",
).eval()

messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "image": "floorplan.png"},
            {"type": "text", "text": "Which room is directly to the left of the kitchen?"},
        ],
    }
]
inputs = processor.from_messages(messages, return_tensors="pt").to(model.device)
with torch.inference_mode():
    output_ids = model.generate(**inputs, max_new_tokens=1024, do_sample=False)
generated_ids = output_ids[:, inputs["input_ids"].shape[1] :]
print(processor.batch_decode(generated_ids, skip_special_tokens=True)[0])
Online Serving
We adapted the vLLM v0.26.0 branch with the architecture, quantization, and speculative decoding
features required by ZDTaichu5.0, supporting both Docker and source deployment:
Docker (recommended)
- Docker image:
registry-dx.wair.ac.cn/taichu-public/vllm-openai:v0.26.0.zdtaichu_5_0
- CUDA ≥ 12.9,Nvidia Driver ≥ 575.51.03
docker run -d \
  -e CUDA_VISIBLE_DEVICES=0 --gpus all \
  --privileged --ipc=host \
  -p 18050:8000 \
  registry-dx.wair.ac.cn/taichu-public/vllm-openai:v0.26.0.zdtaichu_5_0 \
  TaichuAI/ZDTaichu5.0-9B \
    --max-model-len 220000 \
    --served-model-name zdtaichu \
    --mamba-ssm-cache-dtype float32 \
    --gdn-prefill-backend triton \
    --trust-remote-code \
    --tensor-parallel-size 1 \
    --generation-config vllm
Install from source
git clone -b v0.26.0-zdtaichu https://github.com/Taichu-AI/vllm.git
cd vllm
pip install -e .

vllm serve TaichuAI/ZDTaichu5.0-9B \
  --max-model-len 220000 \
  --served-model-name zdtaichu \
  --mamba-ssm-cache-dtype float32 \
  --gdn-prefill-backend triton \
  --trust-remote-code \
  --tensor-parallel-size 1 \
  --generation-config vllm
The server exposes an OpenAI-compatible endpoint at http://<host>:18050/v1. The examples below use the
requests library (pip install requests):
Setup
import base64
import requests

URL = "http://<host>:18050/v1/chat/completions"


def data_url(path: str, mime: str) -> str:
    """Encode a local file as a base64 data URI."""
    with open(path, "rb") as f:
        return f"data:{mime};base64," + base64.b64encode(f.read()).decode()


def chat(body: dict) -> str:
    resp = requests.post(URL, json=body, timeout=600)
    resp.raise_for_status()
    return resp.json()["choices"][0]["message"]["content"]

#Text-only input

body = {
    "model": "zdtaichu",
    "messages": [{"role": "user", "content": "Hello"}],
    "temperature": 1.0,
    "top_p": 0.95,
    "top_k": 20,
}
print(chat(body))

#Image input (local file, base64)

body = {
    "model": "zdtaichu",
    "messages": [
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Which room is directly to the left of the kitchen?"},
                {"type": "image_url", "image_url": {"url": data_url("floorplan.png", "image/png")}},
            ],
        }
    ],
    "temperature": 0,
    "top_p": 0.95,
    "top_k": 20,
}
print(chat(body))

#Video input (local file, base64)

body = {
    "model": "zdtaichu",
    "messages": [
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "Please describe the video."},
                {"type": "video_url", "video_url": {"url": data_url("example.mp4", "video/mp4")}},
            ],
        }
    ],
    "media_io_kwargs": {
        "video": {
            "num_frames": 8,
        },
    },
}
print(chat(body))
media_io_kwargs.video.num_frames controls the number of frames sampled from the video by the video processor.
Recommended sampling parameters
| Task |
temperature |
top_p |
top_k |
| Spatial reasoning and grounding |
0 |
0.95 |
20 |
| Other tasks |
1.0 |
0.95 |
20 |
Reasoning and tool-call parsing arguments (optional)
To enable reasoning output and tool calls, add the following arguments to the launch command:
--reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder
License
The model weights in this repository are made available under the NVIDIA Open Model License Agreement, with the Qwen3.5 Apache-2.0 license and all other third-party notices retained.
Acknowledgements
This model builds on the Qwen3.5 language architecture and NVIDIA C-RADIO vision encoder family. Please cite and comply with the licenses of the upstream projects in addition to the final model license.
Citation
@misc{zdtaichu_5_0_9b,
  title  = {ZDTaichu5.0-9B: A Multimodal Foundation Model for Visual and Spatial Reasoning, Agents, and Embodied AI},
  author = {{ZDTaichu5.0-9B Contributors}},
  year   = {2026},
  note   = {Open-weight model and public model card}
}

 ZDTaichu5.0-9B 是一个多模态基础模型,将 Qwen3.5-9B 语言骨干与 C-RADIOv4-H 视觉编码器结合,面向通用视觉理解、空间推理、具身智能研究和智能体工具使用。