Topics / #vision-language
Vision-language projects on GitHub
Models combining visual and textual understanding, including language-grounded object detection
As of , the most-starred Vision-language projects on GitHub are CLIP (34.5K stars), TaskMatrix (34K stars) and MiniGPT-4 (25.6K stars). GitHub.Locker tracks 8 Vision-language repositories with 118.3K stars combined. The fastest-growing on October 16 was Valen, with +16 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +16
Valen
Liuziyu77/Valen · ★ 843Valen (万澜) is a multimodal decision model that adds visual perception to System One-style decision-making: it scores candidate actions against text, images and video using a task instruction, instead of generating free-form answers.
 +5
CLIP
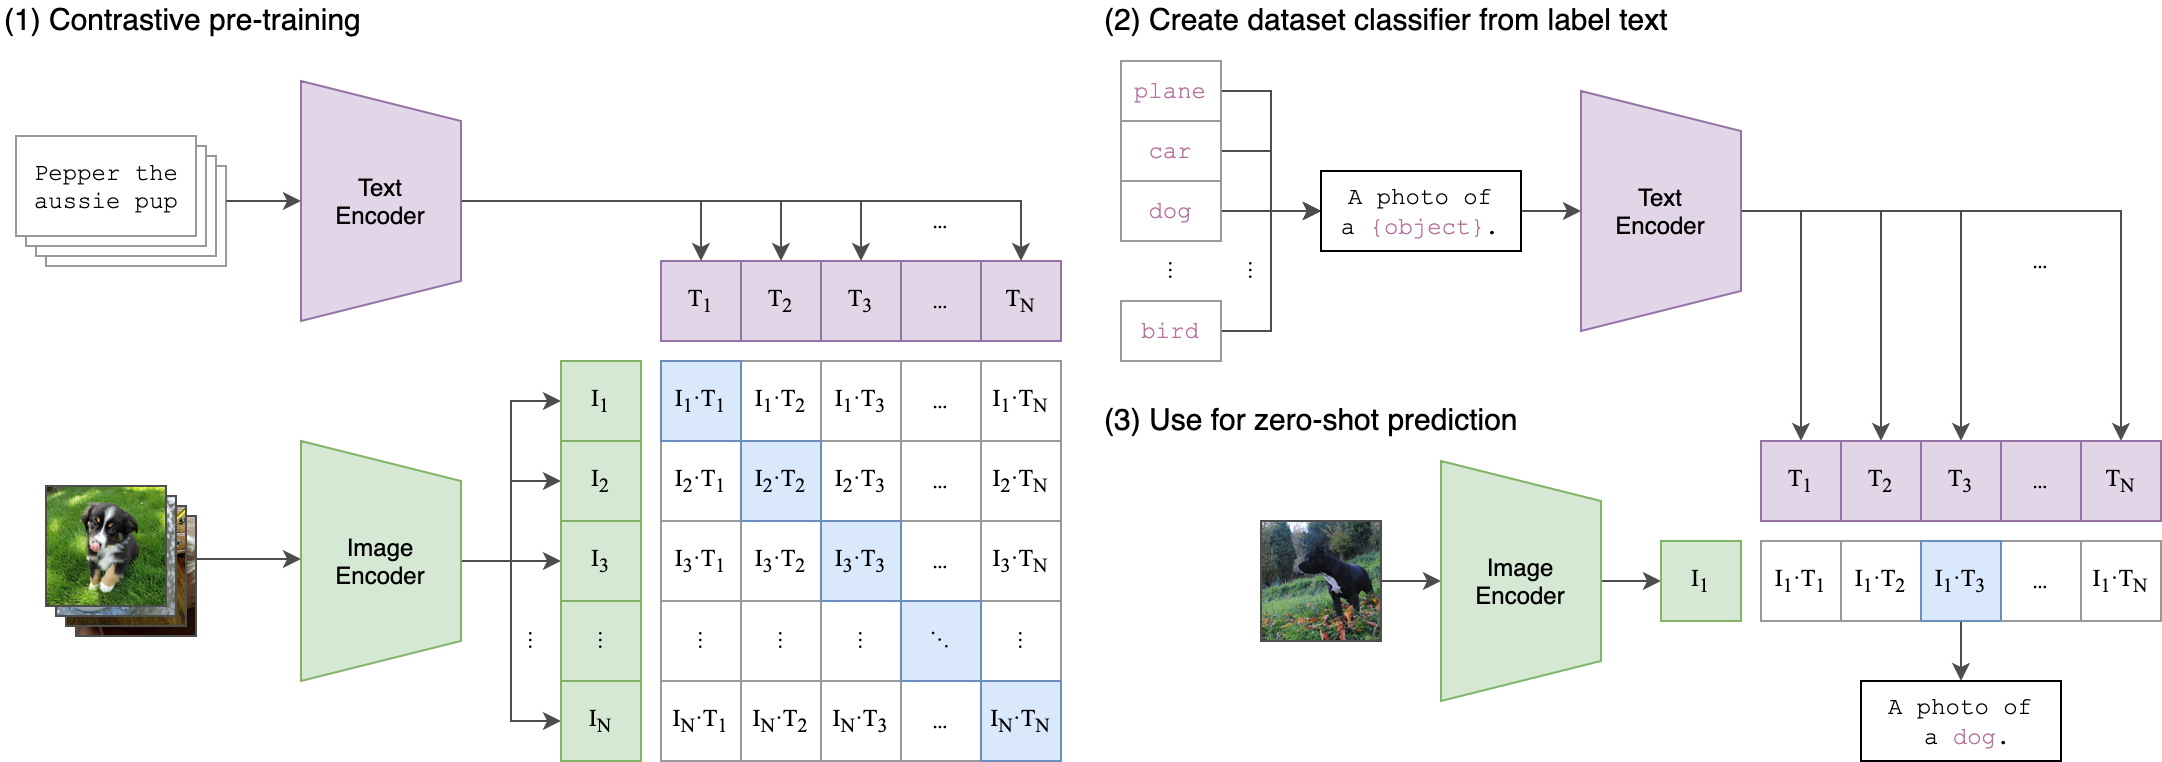
openai/CLIP · ★ 34.5KCLIP is a neural network trained on many (image, text) pairs: given an image, it predicts the most relevant text snippet in natural language, zero-shot, without directly optimizing for the task.
 +3
GroundingDINO
IDEA-Research/GroundingDINO · ★ 10.7KAn open-set object detection model from IDEA-Research (ECCV 2024): give it an image plus a text prompt and it finds the objects your words describe. This repo is the official PyTorch implementation with pretrained models.
 +1
lift
datalab-to/lift · ★ 1.2Klift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
The all-time top
8 projects · by stars
- 34.5K#1 · openai/CLIP
CLIP
CLIP is a neural network trained on many (image, text) pairs: given an image, it predicts the most relevant text snippet in natural language, zero-shot, without directly optimizing for the task.
- 34K
 #2 · chenfei-wu/TaskMatrix
TaskMatrix
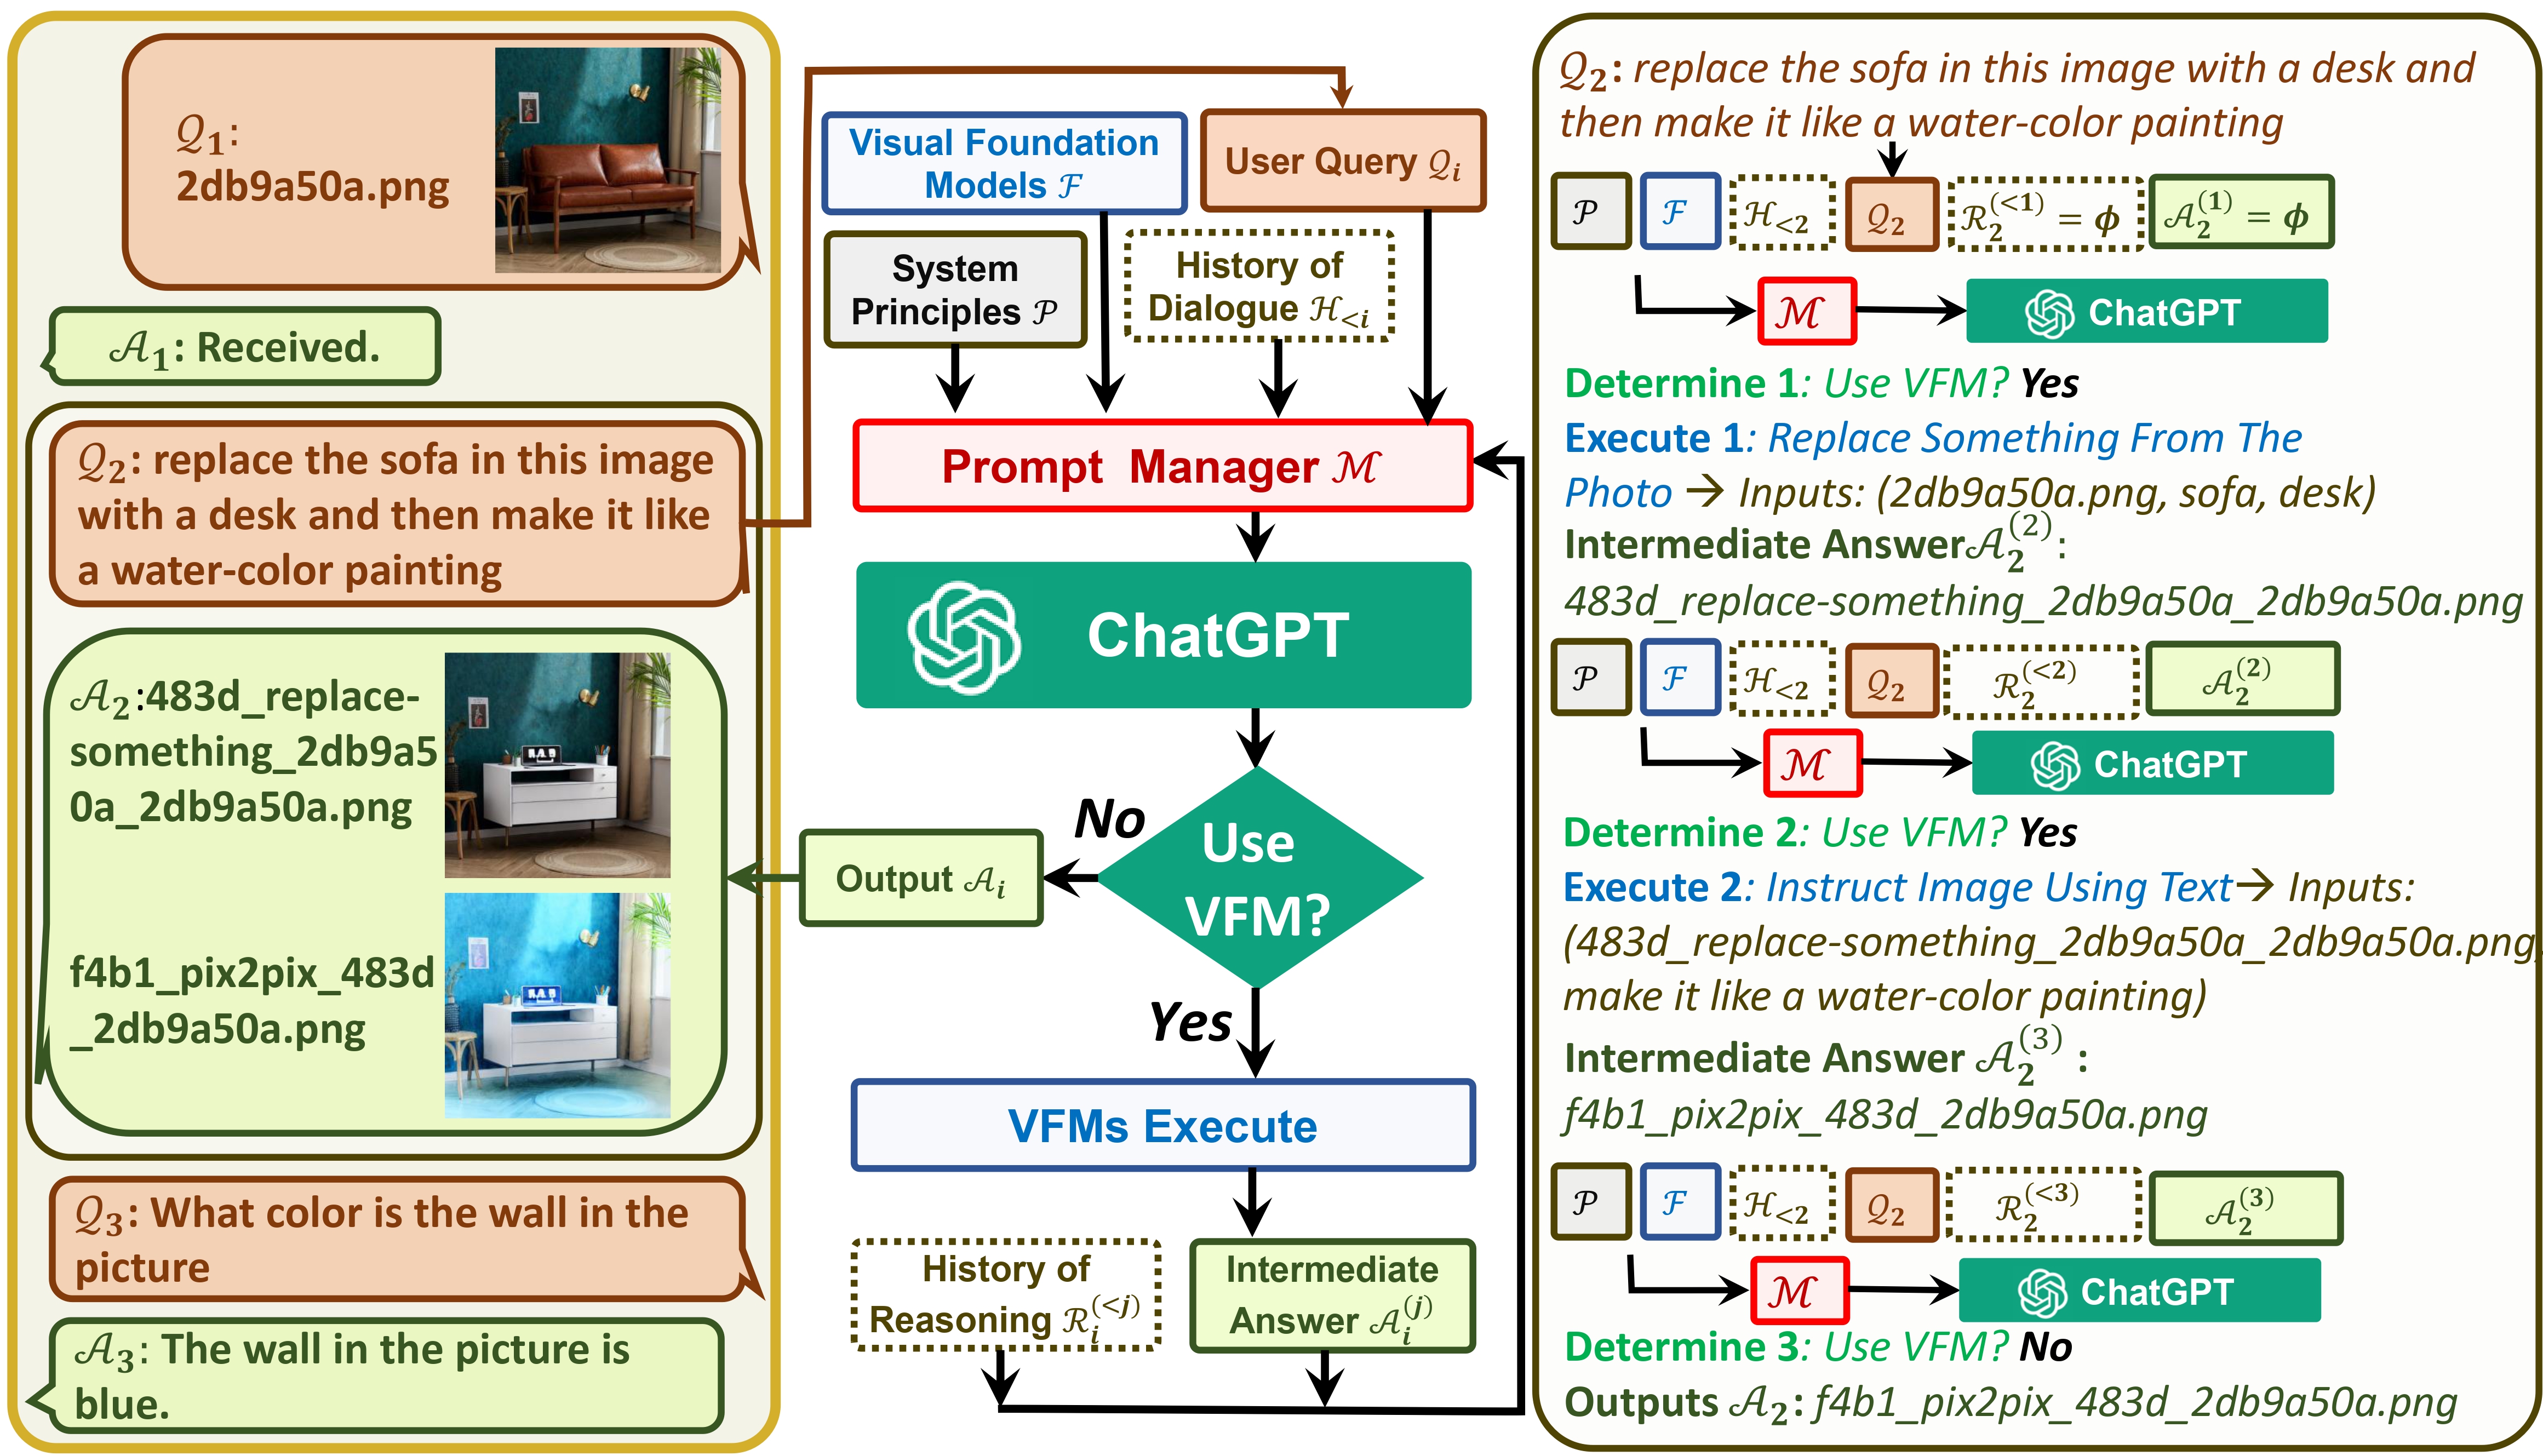
TaskMatrix (also known as Visual ChatGPT) connects ChatGPT to a set of Visual Foundation Models so you can send and receive images while chatting, letting the LLM draw, edit, and analyze pictures.
- 25.6K
 #3 · Vision-CAIR/MiniGPT-4
MiniGPT-4
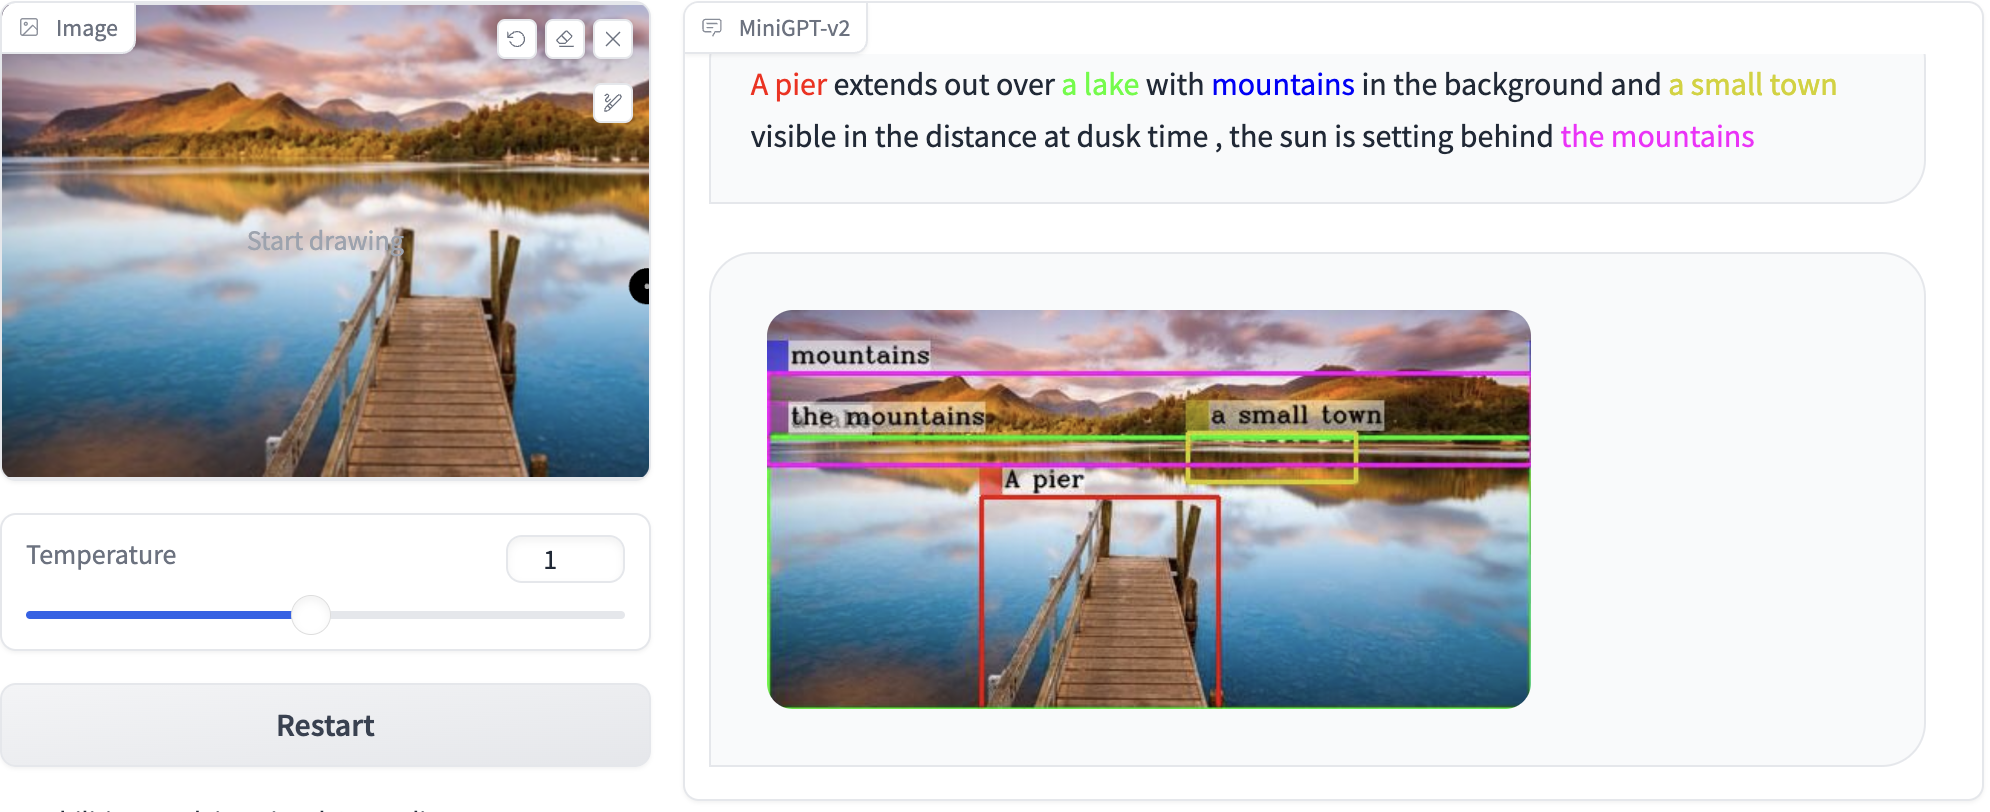
This is the open-sourced research code for MiniGPT-4 and MiniGPT-v2, two vision-language models that use a large language model as the interface for understanding and chatting about images.
- 4

LAVIS
11.3Ksalesforce/LAVIS · Jupyter NotebookLAVIS is a Python deep learning library for language-and-vision research, offering a unified interface to 10+ multimodal tasks, 20+ datasets, and 30+ pretrained foundation models like BLIP, BLIP-2, ALBEF, and CLIP.
- 5
GroundingDINO
10.7KIDEA-Research/GroundingDINO · PythonAn open-set object detection model from IDEA-Research (ECCV 2024): give it an image plus a text prompt and it finds the objects your words describe. This repo is the official PyTorch implementation with pretrained models.
- 6
lift
1.2Kdatalab-to/lift · Pythonlift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
- 7
Valen
843Liuziyu77/Valen · Jupyter NotebookValen (万澜) is a multimodal decision model that adds visual perception to System One-style decision-making: it scores candidate actions against text, images and video using a task instruction, instead of generating free-form answers.
- 8
RoboICL
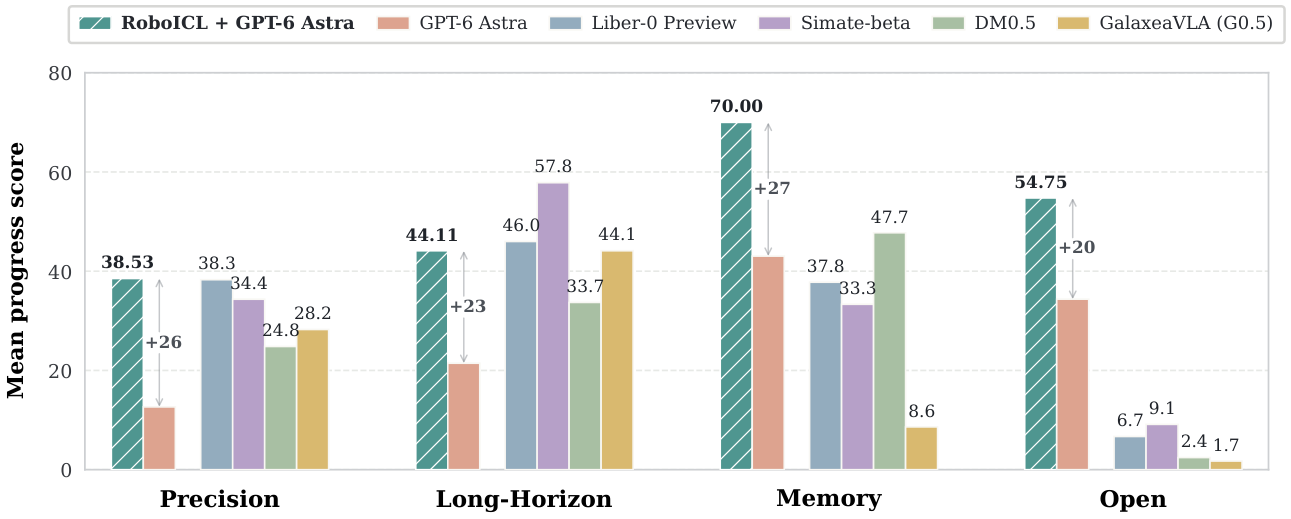
268Mosi-AI/RoboICL · PythonRoboICL is a research framework that lets a frozen, general-purpose vision-language model (GPT-6 Astra) control a robot in simulation purely through in-context learning, without training a dedicated robot policy.
Related topics
Often tagged together
- computer-vision384
- python2,383
- deep-learning737
- gpu789
- multimodal189
- research764
- huggingface362
- ai1,955
- cuda396
- linux4,184
- llm1,483
- machine-learning916
- pytorch419
- vlm34
- apache-2.01,434
- inference327
- jupyter notebook176
- large-language-models213
- library1,587
- academic-research209
- artificial-intelligence267
- benchmark431
- bsd280
- chatbot272