316 ·GitHub
What is this?
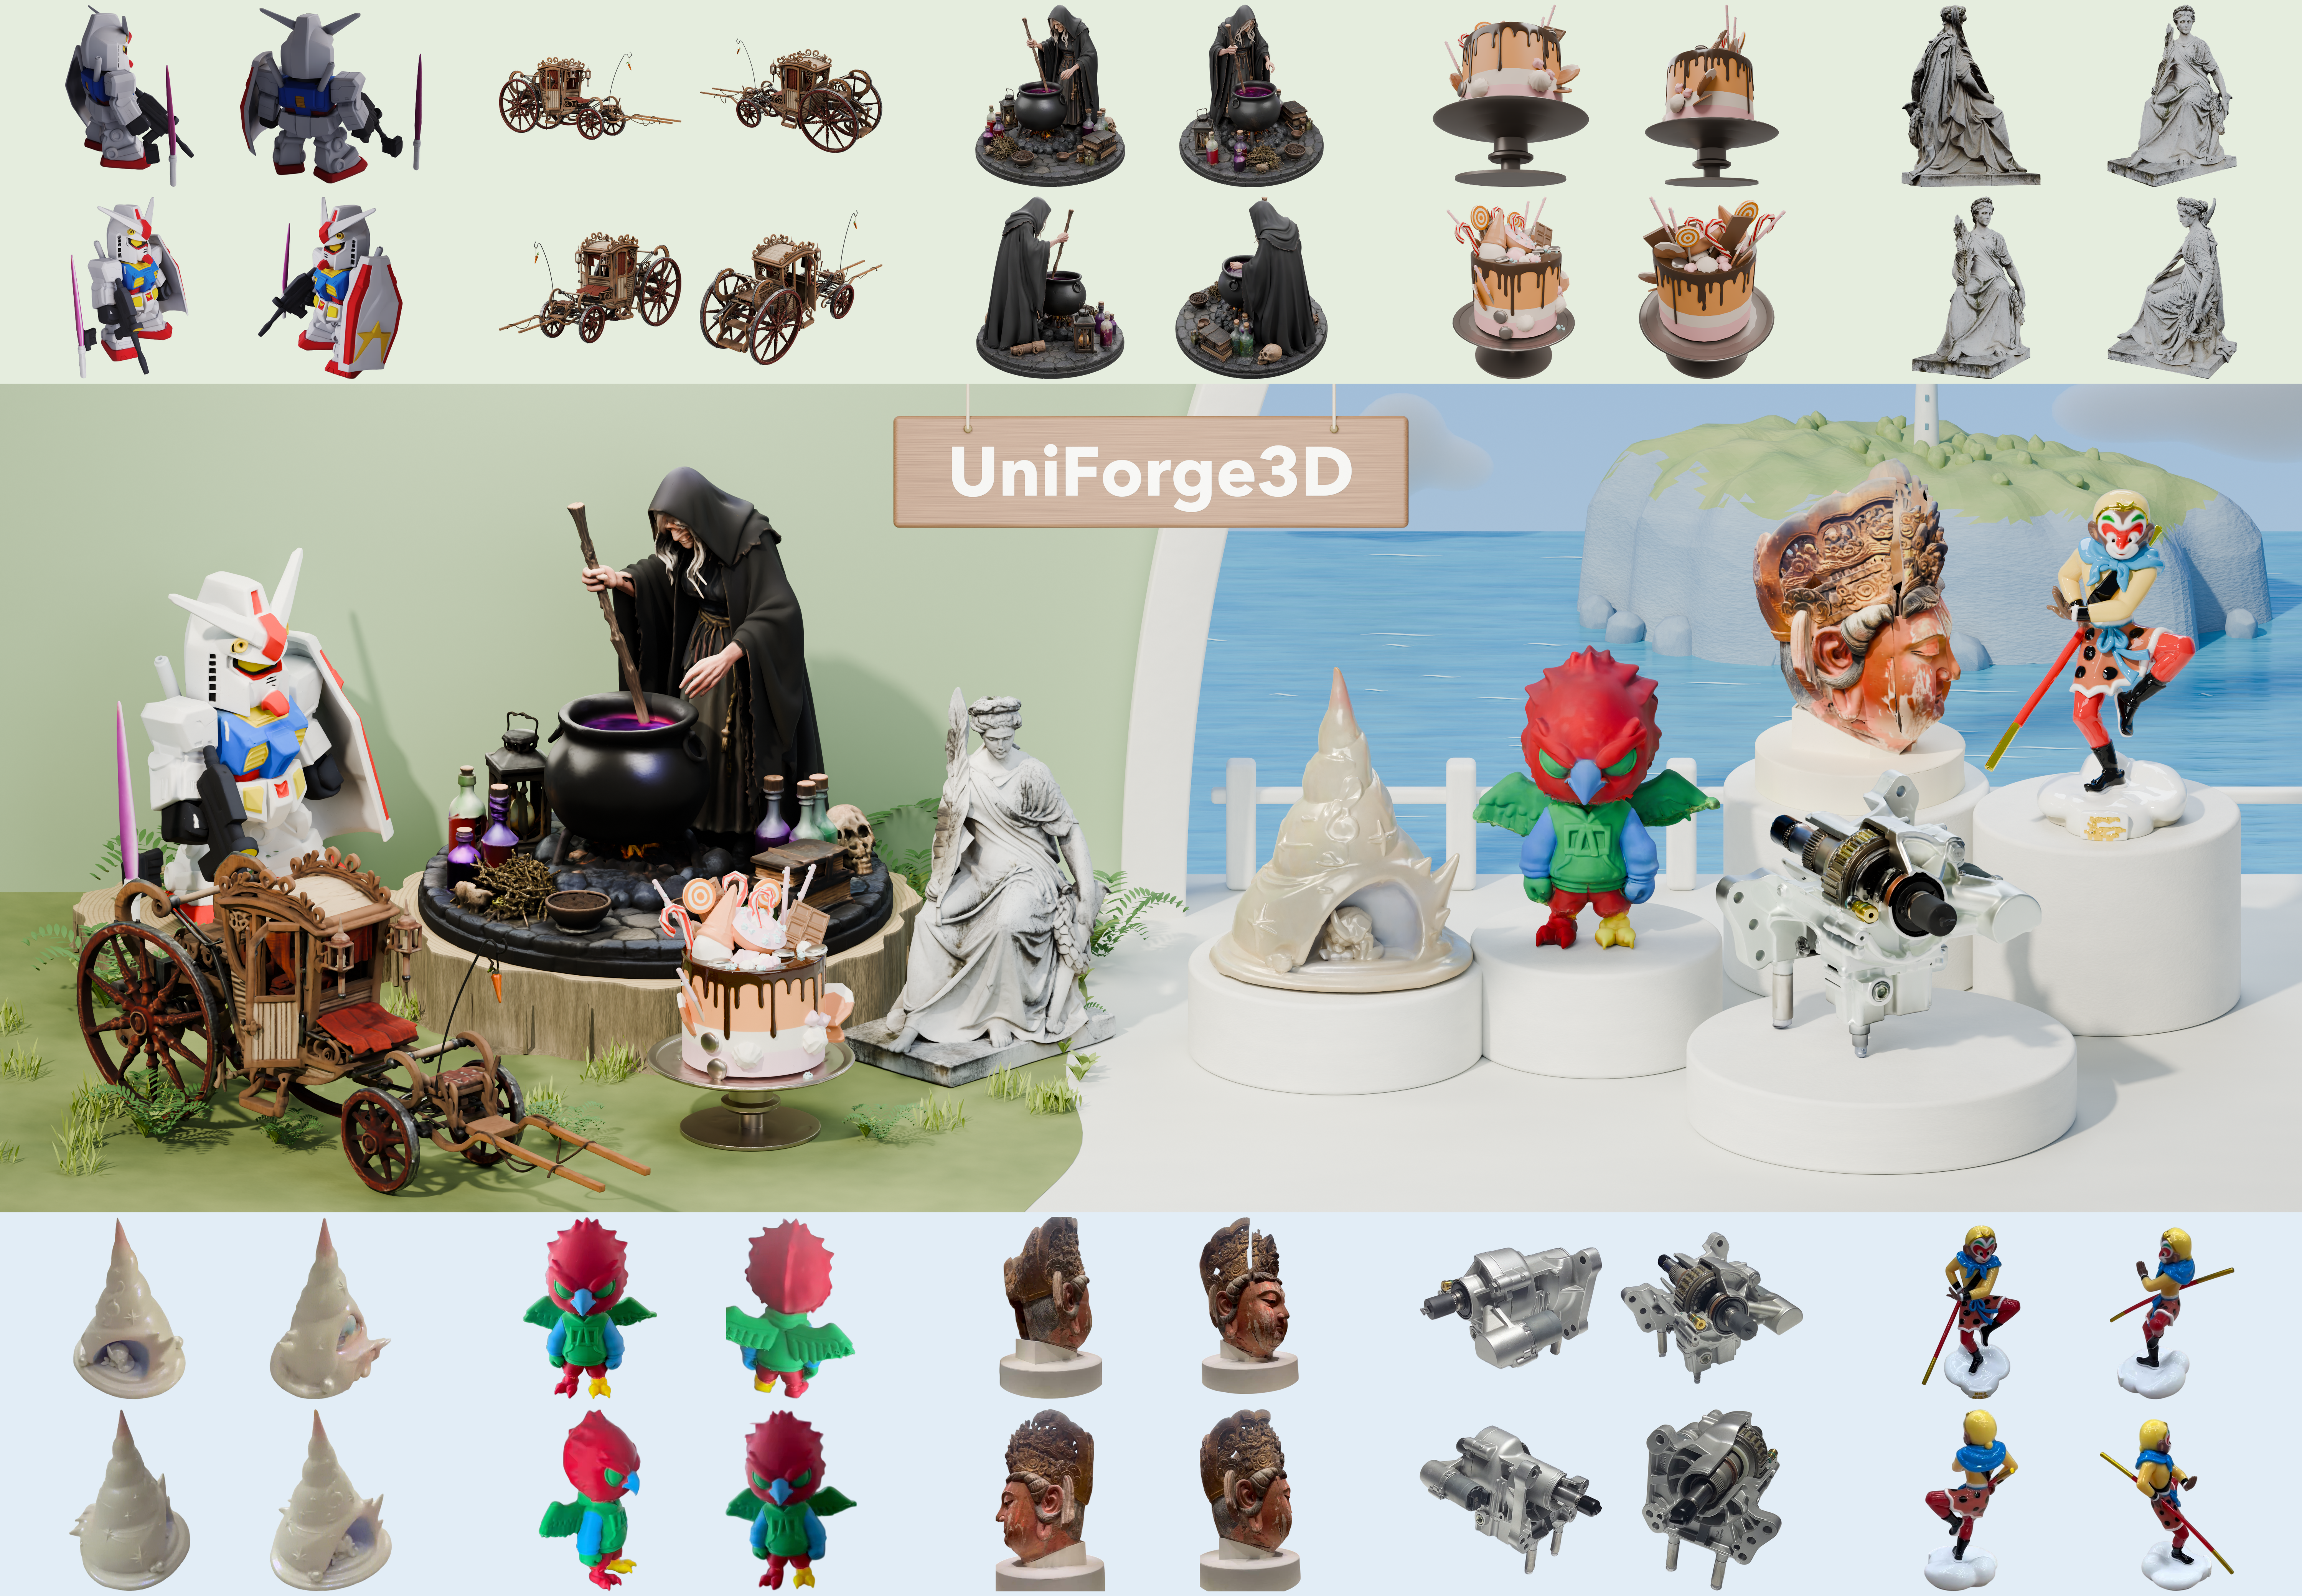
 UniForge3D is the official code release for a research paper that generates complete 3D assets from sparse, unposed multi-view images, jointly modeling reconstruction and generation in a shared anchor-guided space.
Is this a ready-to-use app or a research codebase?It is a research codebase accompanying an academic paper — you run inference scripts against a pretrained model rather than using a packaged application or GUI.
It is a research codebase accompanying an academic paper — you run inference scripts against a pretrained model rather than using a packaged application or GUI.How do I run inference on my own images?Place the multi-view images of each object directly in a separate folder under the assets/ directory, then run all cases using the provided pretrained model.
Place the multi-view images of each object directly in a separate folder under the assets/ directory, then run all cases using the provided pretrained model.Does it rely on other models to work?Yes, the implementation is built on top of TRELLIS.2 and VGGT, so those components are part of the underlying pipeline even though exact package requirements aren't listed.
Yes, the implementation is built on top of TRELLIS.2 and VGGT, so those components are part of the underlying pipeline even though exact package requirements aren't listed.Do I need multiple photos of an object, or does one image work?It needs multiple (sparse) views of the object rather than a single photo, though the views don't need to be pre-posed — the model is designed to handle unposed multi-view input.
It needs multiple (sparse) views of the object rather than a single photo, though the views don't need to be pre-posed — the model is designed to handle unposed multi-view input.What does 'structure-guided view selection' actually do?It's a mechanism that chooses which generated views to trust so the final 3D asset preserves the fine details that were actually observed in the input images, rather than hallucinating them from the anchor space alone.
It's a mechanism that chooses which generated views to trust so the final 3D asset preserves the fine details that were actually observed in the input images, rather than hallucinating them from the anchor space alone.Who worked on this research?The paper lists authors from Peking University, Math Magic, and the Hong Kong University of Science and Technology.
The paper lists authors from Peking University, Math Magic, and the Hong Kong University of Science and Technology.What makes this different from typical multi-view 3D reconstruction tools?Instead of treating reconstruction and generation as separate stages, UniForge3D unifies them in one shared anchor-guided representation, letting it both reconstruct observed geometry and generate missing parts of the 3D asset in the same space.
Instead of treating reconstruction and generation as separate stages, UniForge3D unifies them in one shared anchor-guided representation, letting it both reconstruct observed geometry and generate missing parts of the 3D asset in the same space.What are similar projects?WorldSculpt, Mira-Scene, TRELLIS.2, ml-sharp, sam-3d-objects, vggt, pointdit, shap-e
WorldSculpt, Mira-Scene, TRELLIS.2, ml-sharp, sam-3d-objects, vggt, pointdit, shap-eWhich topics is it in?generative-model, image-to-3d, 3d-generation, 3d-reconstruction, model, pretrained-models, paper, 3d, academic-research, artificial-intelligence, inference, generative-ai
generative-model, image-to-3d, 3d-generation, 3d-reconstruction, model, pretrained-models, paper, 3d, academic-research, artificial-intelligence, inference, generative-ai