

Что это такое?
 EAGLE-4 — это метод спекулятивного декодирования, который ускоряет инференс LLM. В этом репозитории находится eagle-harness, пакет, который позволяет серверным движкам использовать черновые модели EAGLE-4 без изменения вывода модели.
Это отдельный сервер или пакет, который подключается к движку вроде SGLang?Это eagle-harness, пакет, который добавляет EAGLE-4 в уже существующие серверные движки (SGLang, vLLM, TokenSpeed). Сам он не является новым движком: он стоит между движком и черновой моделью.
Это eagle-harness, пакет, который добавляет EAGLE-4 в уже существующие серверные движки (SGLang, vLLM, TokenSpeed). Сам он не является новым движком: он стоит между движком и черновой моделью.Как это запустить?Запустите сервер SGLang с готовым Docker-образом или установите eagle-harness через pip под Python 3.12, затем укажите движку черновую модель EAGLE-4 и отправляйте запросы, когда в логе появится сообщение ready.
Запустите сервер SGLang с готовым Docker-образом или установите eagle-harness через pip под Python 3.12, затем укажите движку черновую модель EAGLE-4 и отправляйте запросы, когда в логе появится сообщение ready.Нужна ли особая конфигурация GPU?Быстрый старт собран и протестирован на одном NVIDIA B300 под Linux с драйвером CUDA 13. Замеры ускорения выполнялись на четырёх GPU B300, а AMD MI355X тоже поддерживается через порт на ROCm.
Быстрый старт собран и протестирован на одном NVIDIA B300 под Linux с драйвером CUDA 13. Замеры ускорения выполнялись на четырёх GPU B300, а AMD MI355X тоже поддерживается через порт на ROCm.Есть ли известные ограничения или пробелы в поддержке оборудования?В репозитории есть отдельная таблица поддержки с данными о токенах в секунду, проверках корректности и известных ограничениях для каждого движка и GPU, так как поведение и ускорение зависят от оборудования, размера батча и нагрузки.
В репозитории есть отдельная таблица поддержки с данными о токенах в секунду, проверках корректности и известных ограничениях для каждого движка и GPU, так как поведение и ускорение зависят от оборудования, размера батча и нагрузки.EAGLE-4 — открытое ПО?Нет: исходный код доступен, но лицензия не одобрена OSI, поэтому это не открытое ПО. Коммерческое использование бесплатно при выручке ниже 20 миллионов долларов США в течение 12 месяцев, а любое использование для «Competing Offering» требует отдельной коммерческой лицензии независимо от выручки.
Нет: исходный код доступен, но лицензия не одобрена OSI, поэтому это не открытое ПО. Коммерческое использование бесплатно при выручке ниже 20 миллионов долларов США в течение 12 месяцев, а любое использование для «Competing Offering» требует отдельной коммерческой лицензии независимо от выручки.Меняет ли спекулятивное декодирование ответы модели?Нет, EAGLE-4 проверяет черновики по целевой модели, поэтому результат совпадает с тем, что дал бы запуск без спекуляции, только быстрее.
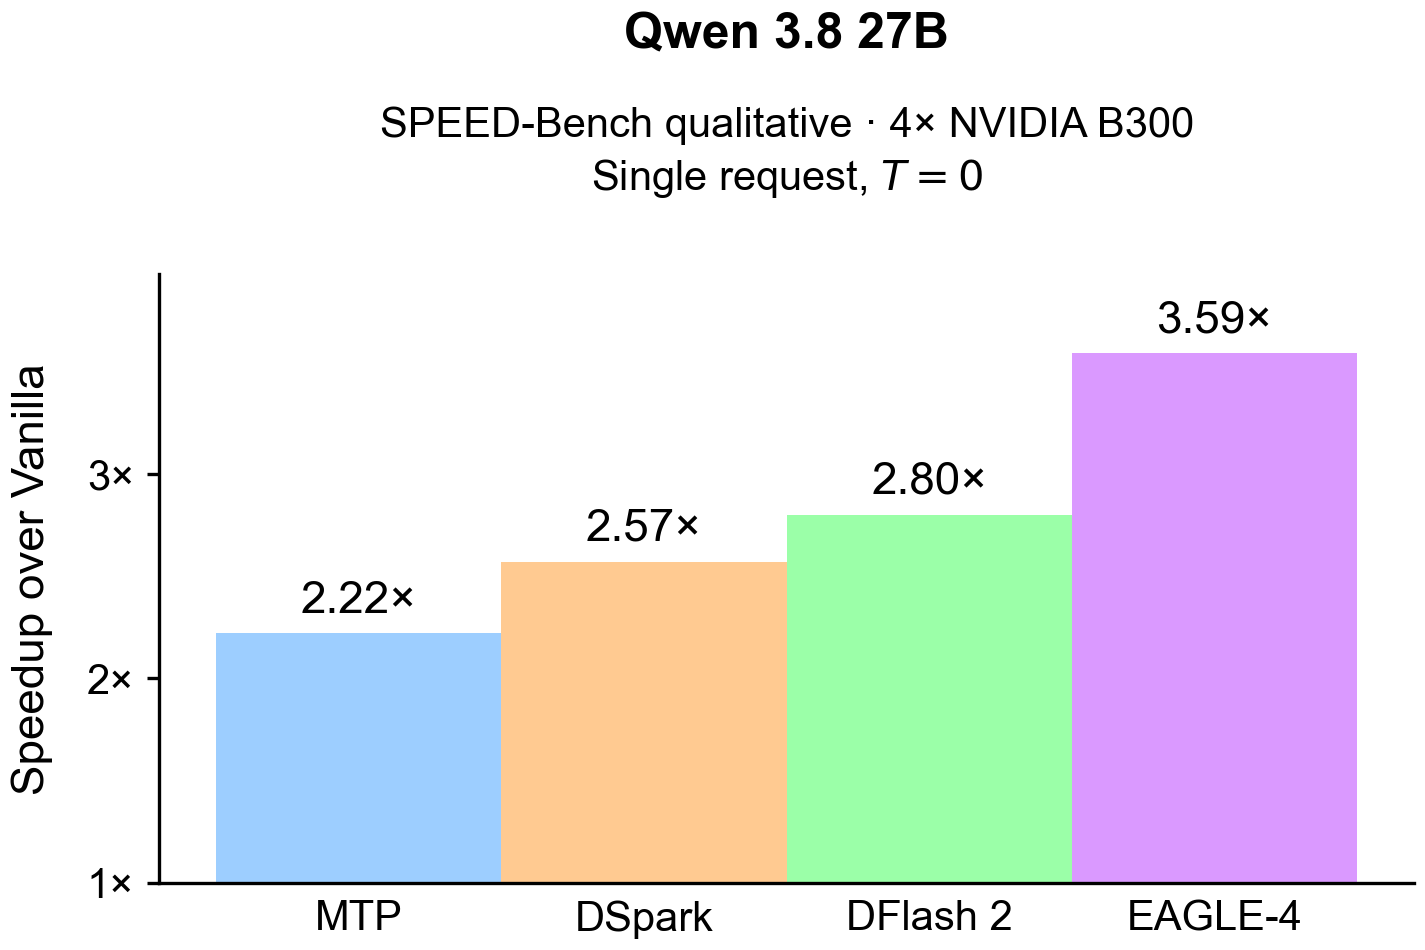
Нет, EAGLE-4 проверяет черновики по целевой модели, поэтому результат совпадает с тем, что дал бы запуск без спекуляции, только быстрее.Насколько быстрее работает инференс с EAGLE-4?До 3,42x для одного запроса в SGLang на Qwen3.8-27B на четырёх GPU B300. При большем числе одновременных запросов прирост меньше, но всё же заметен (1,1–2x).
До 3,42x для одного запроса в SGLang на Qwen3.8-27B на четырёх GPU B300. При большем числе одновременных запросов прирост меньше, но всё же заметен (1,1–2x).Что именно eagle-harness решает во время работы?Он решает, на сколько шагов вперёд делать спекуляцию, используя измеренные затраты для вашего размера батча, оборудования и нагрузки, а не фиксированную глубину спекуляции.
Он решает, на сколько шагов вперёд делать спекуляцию, используя измеренные затраты для вашего размера батча, оборудования и нагрузки, а не фиксированную глубину спекуляции.Работает ли это только с SGLang?Нет, поддерживаются также vLLM и TokenSpeed. Для каждого движка есть отдельные руководства с точными измеренными командами.
Нет, поддерживаются также vLLM и TokenSpeed. Для каждого движка есть отдельные руководства с точными измеренными командами.Какие есть похожие проекты?tokenspeed, qwen3.8-Flash-DGX, LMCache, alzeo, project-maya, Hyperloom, DeepInfer, GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark
tokenspeed, qwen3.8-Flash-DGX, LMCache, alzeo, project-maya, Hyperloom, DeepInfer, GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-SparkВ каких он темах?fair-source, sglang, amd-gpu, rocm, speculative-decoding, model-serving, amd, inference-engine, llm-inference, vllm, large-language-models, inference
fair-source, sglang, amd-gpu, rocm, speculative-decoding, model-serving, amd, inference-engine, llm-inference, vllm, large-language-models, inference- Автор
- eagle-hq
- Размер
- 2.6 MB
- Звёзды
- 1.3K
- Обновлён
- КоммитNov 11Релизv0.1.5Nov 01
- Возраст
- 29 д
- Коммиты · 90 дней