Что это?
 Qwen3.8-Flash-Next — открытая мультимодальная фундаментальная модель Mixture-of-Experts от команды Qwen в Alibaba; она же служит ранним превью архитектуры, которую Alibaba планирует использовать в готовящейся семье моделей Qwen4.
Это приложение-чатбот или просто сырые веса модели, которые придётся разворачивать самому?Это просто выпущенные веса модели, а не упакованное приложение. Вы скачиваете их с Hugging Face Hub или ModelScope и запускаете через фреймворк инференса вроде transformers, vLLM, SGLang или llama.cpp.
Это просто выпущенные веса модели, а не упакованное приложение. Вы скачиваете их с Hugging Face Hub или ModelScope и запускаете через фреймворк инференса вроде transformers, vLLM, SGLang или llama.cpp.Как запустить его локально?Скачайте веса через huggingface download или git clone (или modelscope download), затем поднимите сервер с помощью CLI transformers serve, vLLM или SGLang и получите эндпоинт API, совместимый с OpenAI.
Скачайте веса через huggingface download или git clone (или modelscope download), затем поднимите сервер с помощью CLI transformers serve, vLLM или SGLang и получите эндпоинт API, совместимый с OpenAI.Какое железо или фреймворк нужны для запуска?Нужен серверный фреймворк вроде transformers, vLLM, SGLang, llama.cpp, MLX (Apple Silicon) или Unsloth, плюс достаточно памяти GPU для MoE-модели на 125B параметров с 6B активных параметров на токен.
Нужен серверный фреймворк вроде transformers, vLLM, SGLang, llama.cpp, MLX (Apple Silicon) или Unsloth, плюс достаточно памяти GPU для MoE-модели на 125B параметров с 6B активных параметров на токен.Можно ли запустить полную модель на одной потребительской GPU?Не в полной точности — это MoE-модель на 125B параметров, рассчитанная на развёртывание через фреймворки вроде vLLM или SGLang на серьёзном железе, хотя есть квантизованные GGUF-сборки для llama.cpp и MLX-сборки для Apple Silicon для более лёгких конфигураций.
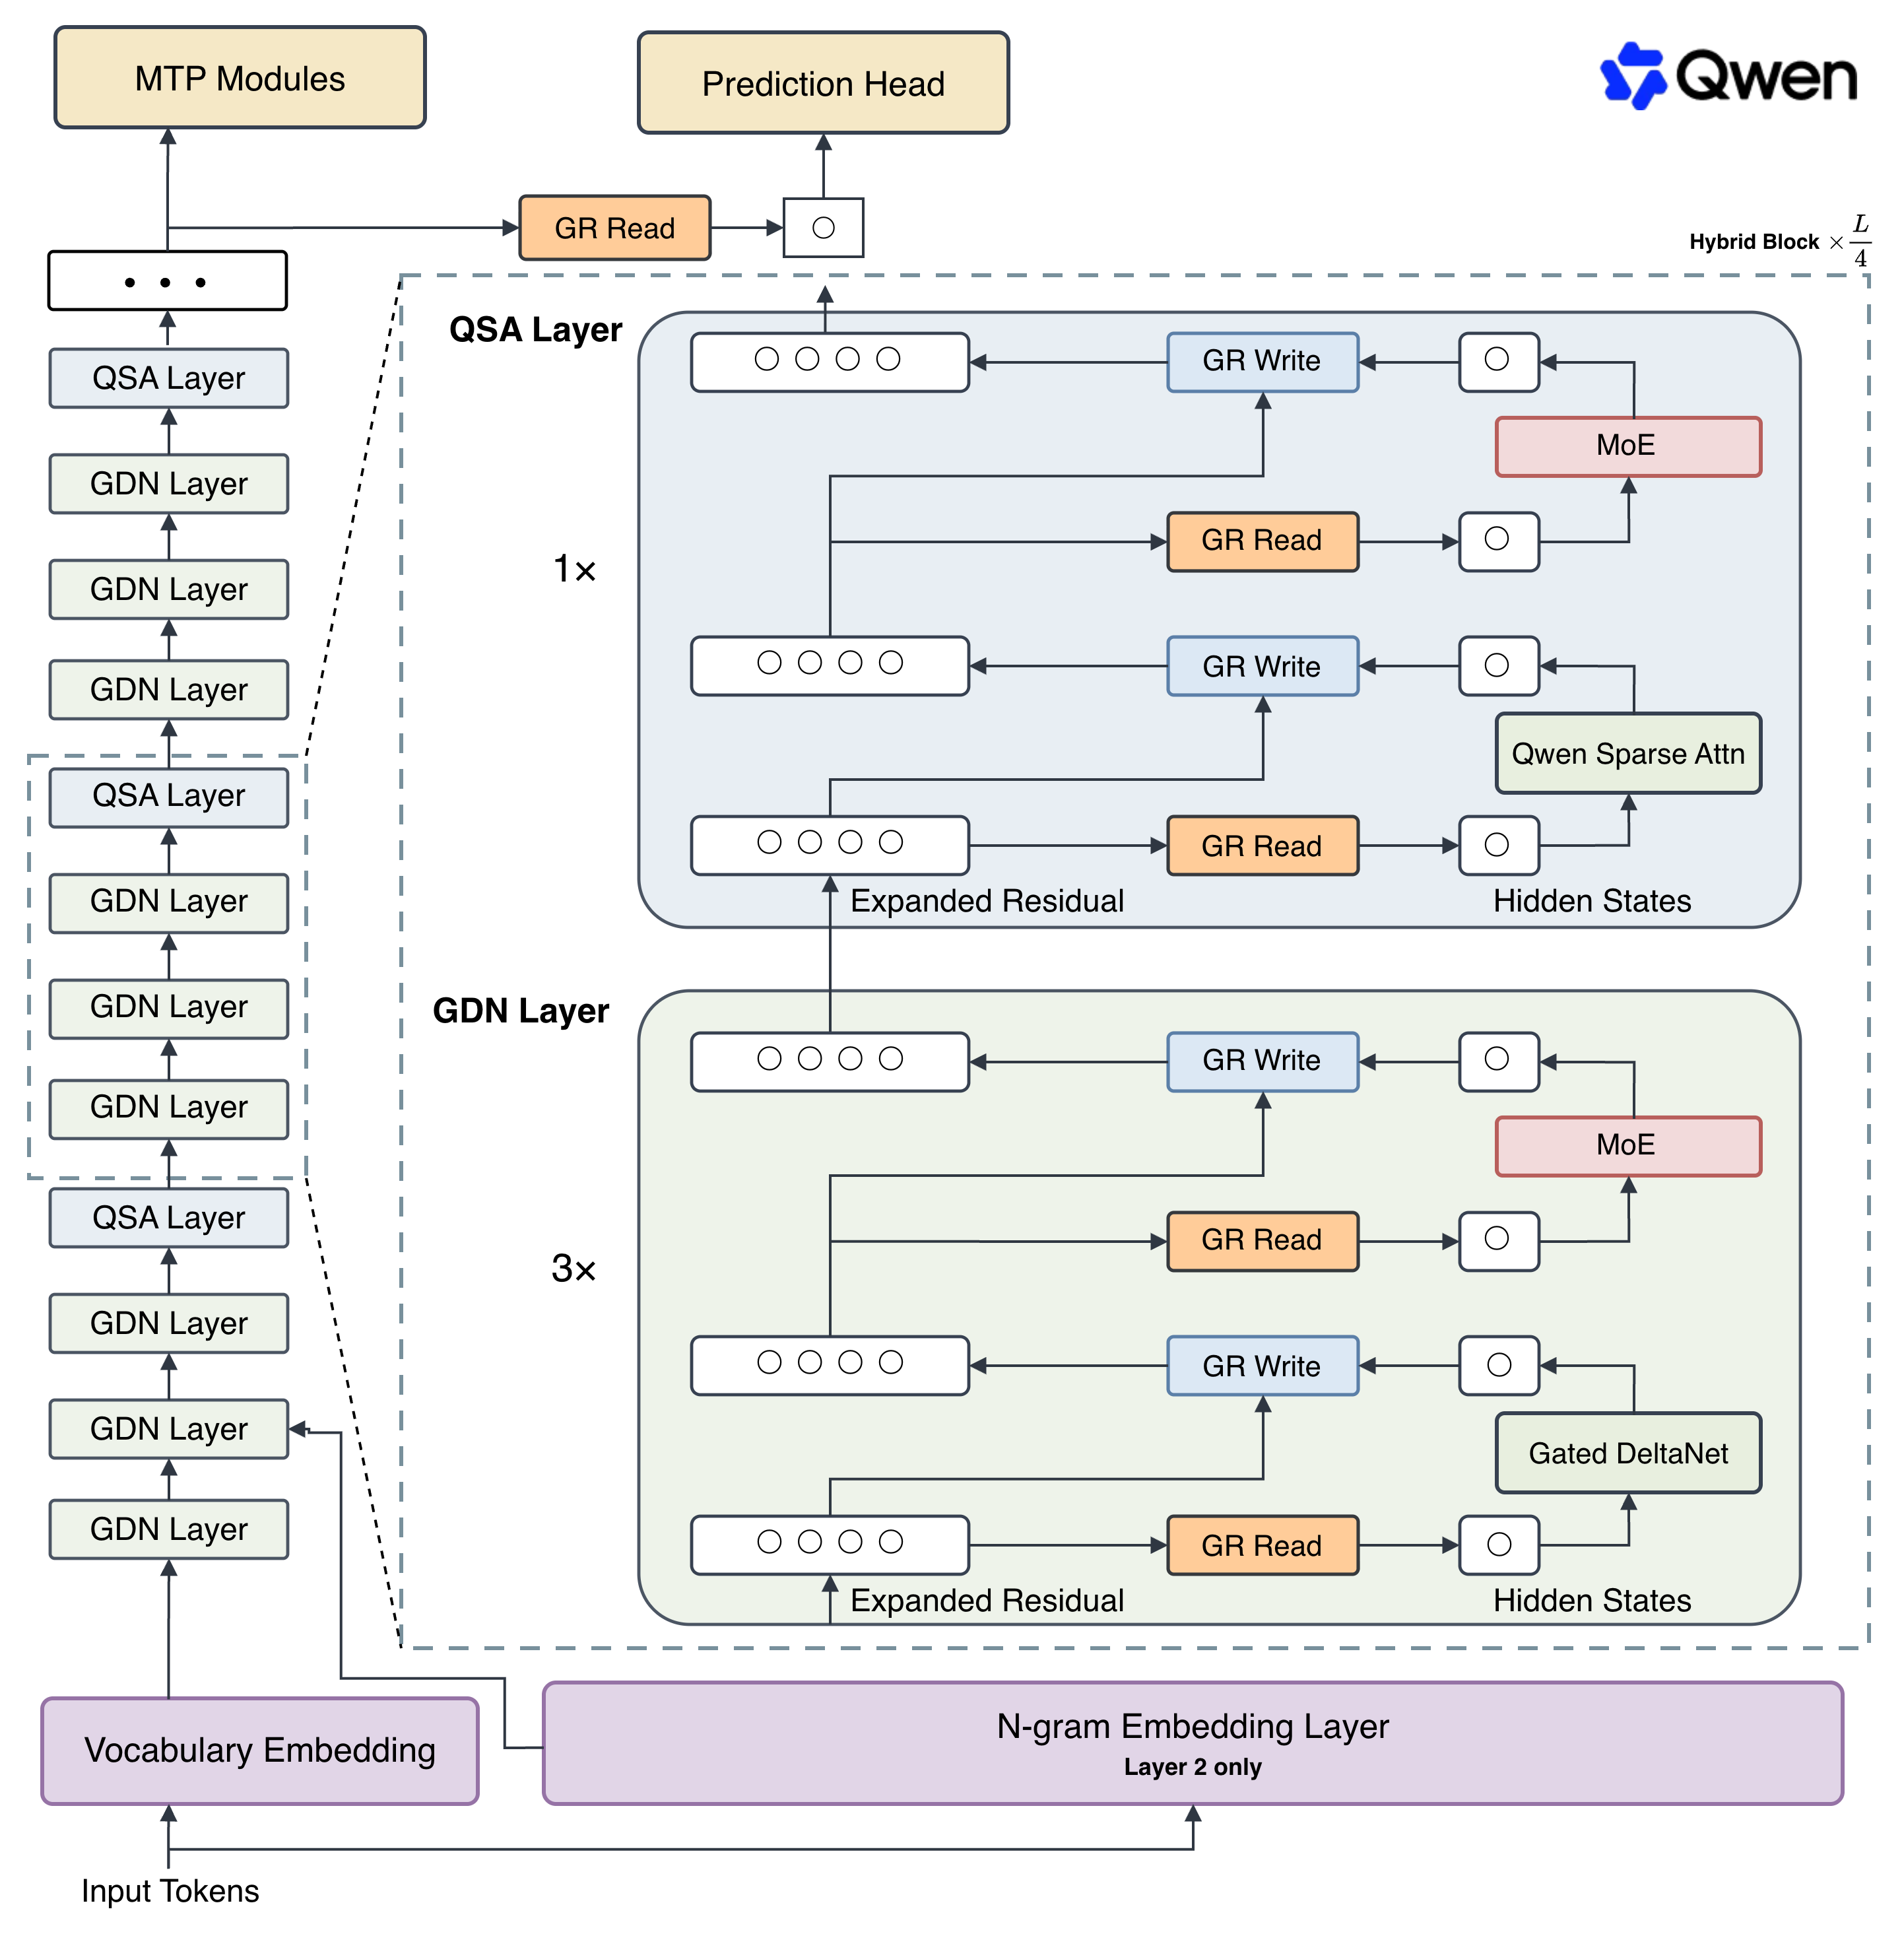
Не в полной точности — это MoE-модель на 125B параметров, рассчитанная на развёртывание через фреймворки вроде vLLM или SGLang на серьёзном железе, хотя есть квантизованные GGUF-сборки для llama.cpp и MLX-сборки для Apple Silicon для более лёгких конфигураций.Чем архитектура отличается от предыдущих моделей Qwen?Она обновляет attention гибридом Gated DeltaNet + Qwen Sparse Attention, расширяет residual-поток до 4 гейтованных ветвей (Gated Residual), добавляет таблицу N-gram Embedding для дешёвого наращивания ёмкости и обучается оптимизатором Muon для лучшей стабильности.
Она обновляет attention гибридом Gated DeltaNet + Qwen Sparse Attention, расширяет residual-поток до 4 гейтованных ветвей (Gated Residual), добавляет таблицу N-gram Embedding для дешёвого наращивания ёмкости и обучается оптимизатором Muon для лучшей стабильности.Можно попробовать, не хостя его самому?Да — он питает новый режим 'Standard' на QwenWork, доступен через совместимый с OpenAI/Anthropic Qwen API на QwenCloud и может использоваться через терминального агента Qwen Code.
Да — он питает новый режим 'Standard' на QwenWork, доступен через совместимый с OpenAI/Anthropic Qwen API на QwenCloud и может использоваться через терминального агента Qwen Code.Как он соотносится с Qwen3.7-Plus?Обучение стоит примерно в 9 раз дешевле, чем у Qwen3.7-Plus, при более сильных способностях в кодинге и офисных задачах.
Обучение стоит примерно в 9 раз дешевле, чем у Qwen3.7-Plus, при более сильных способностях в кодинге и офисных задачах.Могу ли я сам дообучить эту модель?Да, README рекомендует фреймворки обучения вроде Unsloth, Swift или Llama-Factory для дообучения через SFT, DPO или GRPO.
Да, README рекомендует фреймворки обучения вроде Unsloth, Swift или Llama-Factory для дообучения через SFT, DPO или GRPO.What are similar projects?Qwen3.8, vllm, Qwen3, unsloth, StartLux-Decision, Hy4-preview, airllm, jeeves
Qwen3.8, vllm, Qwen3, unsloth, StartLux-Decision, Hy4-preview, airllm, jeevesWhich topics is it in?dpo, sft, grpo, alibaba, qwen3, open-weights, model, mlx, foundation-models, inference-engine, mixture-of-experts, attention-mechanism
dpo, sft, grpo, alibaba, qwen3, open-weights, model, mlx, foundation-models, inference-engine, mixture-of-experts, attention-mechanism