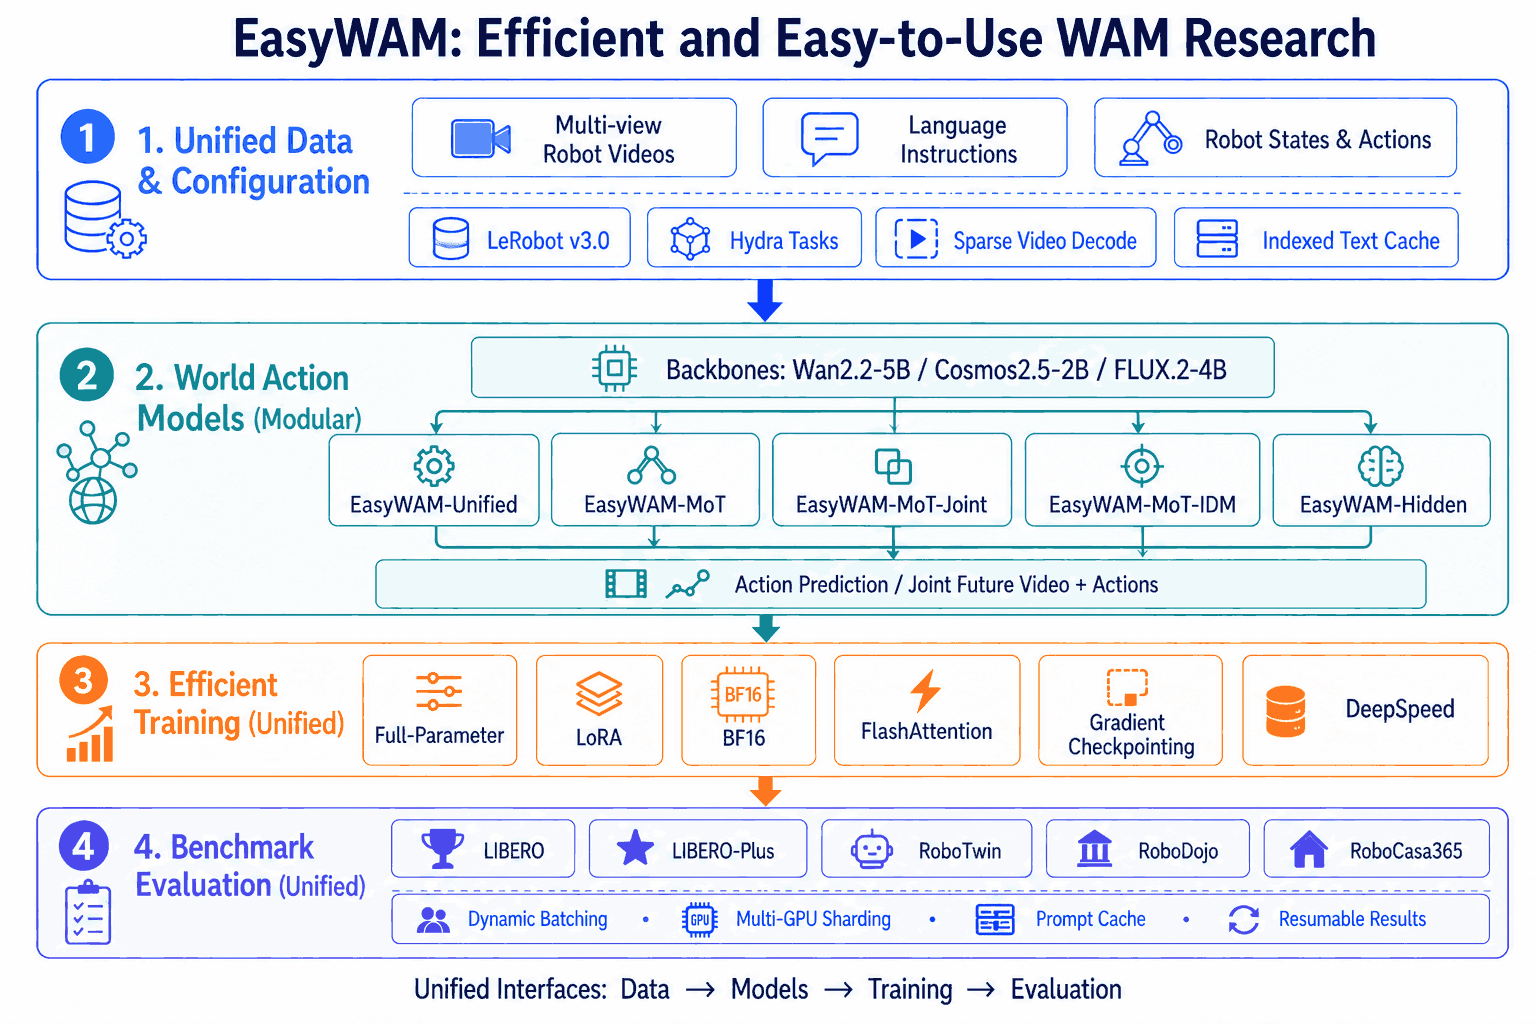
EasyWAM is a unified research codebase designed to make World Action Model development efficient, reproducible, and easy to extend. It connects model implementation, data processing, distributed training, parameter-efficient fine-tuning, and large-scale evaluation through a consistent workflow.
🧩 Unified and modular design. Modular model components share consistent data, training, checkpoint, and evaluation interfaces, making new WAM designs easier to integrate.
⚡ Efficient computation. Efficiency is a first-class design goal in EasyWAM. It natively integrates FlashAttention 2/3/4 to accelerate attention workloads and provides complete LoRA support from parameter-efficient training and checkpointing to merged inference. BF16, gradient checkpointing, DeepSpeed ZeRO, and PyTorch SDPA fallback further improve speed, memory usage, and compatibility.
🚄 Optimized end-to-end pipeline. EasyWAM streamlines every stage of training and inference. Sparse video decoding, indexed text caches, persistent workers, prompt caching, and resumable evaluation eliminate repeated work and deliver substantial speedups across both training and inference.
🛠️ Easy-to-use workflows. Hydra-based configuration, standardized training and evaluation recipes, distributed launchers, automatic GPU sharding, and result summaries keep common workflows straightforward.
🌟 Hope: We hope EasyWAM will become an efficient and easy-to-use codebase for World Action Model research, enabling researchers to explore WAMs more quickly and easily. More models and benchmarks will be continuously added and supported. We warmly welcome contributions from the community to help make EasyWAM better. If you encounter any problems or have suggestions for improving EasyWAM, please open an issue. We will continue to refine and improve EasyWAM.
📰 News
[2026-08] EasyWAM is released with unified training and evaluation workflows for World Action Models.
🤖 Supported Models and Benchmarks
🧠 Models
EasyWAM-Unified. A single-backbone architecture that places video, action, and robot-state tokens in one Video DiT to jointly predict future video and actions. The architecture is based on DreamZero.
EasyWAM-MoT. A dual-backbone model with separate Video DiT and Action DiT experts whose tokens interact through shared mixed self-attention. It performs action-only prediction and is based on FastWAM.
EasyWAM-MoT-Joint. A dual-backbone model that jointly denoises video and action tokens through shared mixed self-attention.
EasyWAM-MoT-IDM. A dual-backbone model that uses teacher-forced conditional video for action prediction.
EasyWAM-Hidden. A dual-backbone architecture that uses intermediate Video DiT features as conditional input to a separate Action DiT. The architecture is based on DiT4DiT.
All efficiency results reported below use Wan2.2-TI2V-5B as the backbone. Actual training time may vary with the CPU and GPU configuration; these figures are provided for reference only. Please refer to the efficiency configuration guide to choose settings appropriate for your machine and improve training and inference efficiency.
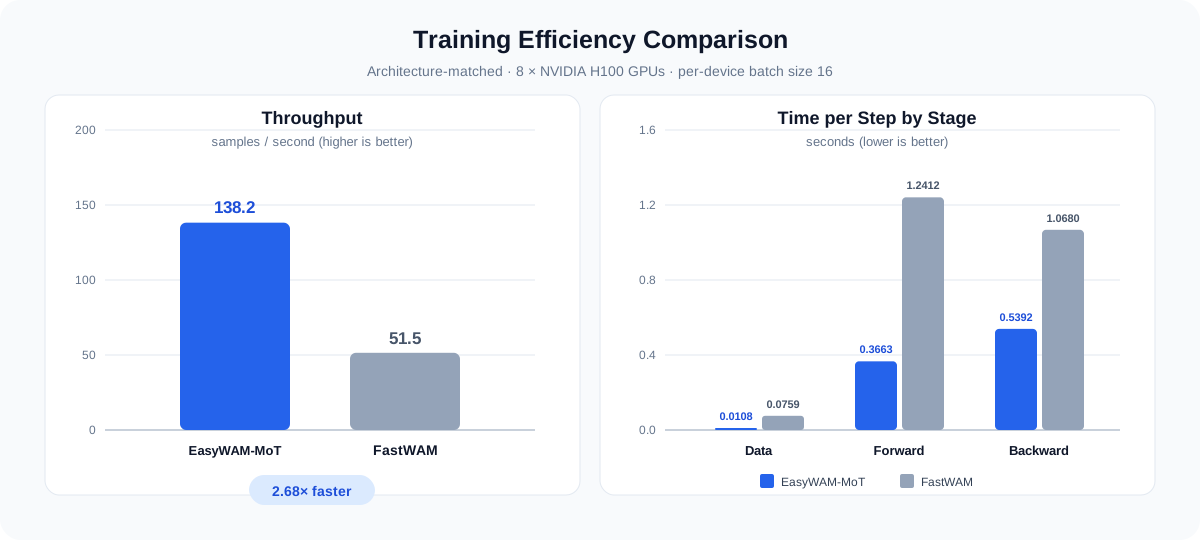
EasyWAM-MoT and FastWAM use the same model architecture, enabling an architecture-matched comparison between the EasyWAM training framework and the original FastWAM codebase. Measured on 8 × NVIDIA H100 GPUs with a per-device batch size of 16, EasyWAM-MoT achieves 121.9 samples/s, a 2.37× throughput improvement over FastWAM's 51.5 samples/s. It also reduces data, forward, and backward time per step by 66.0%, 58.4%, and 54.7%, respectively.
Framework
Throughput (samples/s) ↑
Data Time (s) ↓
Forward Time (s) ↓
Backward Time (s) ↓
EasyWAM-MoT
121.9
0.0258
0.5162
0.4842
FastWAM
51.5
0.0759
1.2412
1.0680
On LIBERO, training for 20,000 steps takes approximately 6 hours with EasyWAM, compared with approximately 14 hours using the original FastWAM codebase—a 57.1% reduction in overall training time.
🌟 Hope: Training and evaluating World Action Models often requires substantial computational resources. EasyWAM aims to lower this barrier with an efficient and lightweight codebase, enabling researchers to train models, run evaluations, and iterate quickly even with limited compute. Through continuous efficiency improvements, we hope researchers can devote more of their resources to model and algorithm innovation and that more members of the community can participate in WAM research.
Run the following commands from the project root. The paths match the values in
configs/model/backbone/wan22.yaml and configs/model/backbone/cosmos25.yaml.
mkdir -p checkpoints

# Wan2.2 video DiT, VAE, UMT5 encoder, and tokenizer
huggingface-cli download Wan-AI/Wan2.2-TI2V-5B --local-dir checkpoints/Wan2.2-TI2V-5B

# Cosmos post-trained 2B video DiT and its Wan2.1 video tokenizer
huggingface-cli download nvidia/Cosmos-Predict2.5-2B \
  --include "base/post-trained/81edfebe-bd6a-4039-8c1d-737df1a790bf_ema_bf16.pt" "tokenizer.pth" \
  --local-dir checkpoints/Cosmos-Predict2.5-2B

# Reason1 text encoder and tokenizer used to build the Cosmos text cache
huggingface-cli download nvidia/Cosmos-Reason1-7B --local-dir checkpoints/Cosmos-Reason1-7B
After downloading and generating ActionDiT initialization weights, the files used by
the default configs are:
The launchers accept Hydra overrides directly. Set the number of local processes through NPROC_PER_NODE:
# DeepSpeed ZeRO-1 on 8 local GPUs
NPROC_PER_NODE=8 bash scripts/train_zero1.sh task=libero_easywam_mot_wan22

# MoT, MoT-Joint, and MoT-IDM each have a corresponding Cosmos25 task config
NPROC_PER_NODE=8 bash scripts/train_zero1.sh \
  task=libero_easywam_mot_cosmos25

# DeepSpeed ZeRO-2 LoRA training on 4 local GPUs
NPROC_PER_NODE=4 bash scripts/train_zero2.sh task=robotwin_easywam_unified_wan22_lora
scripts/train_zero2_offload.sh enables ZeRO-2 CPU offload. Multi-node runs additionally use NNODES, NODE_RANK, MASTER_ADDR, and MASTER_PORT.
The managers default to 8 GPUs. Override MULTIRUN.num_gpus and MULTIRUN.max_tasks_per_gpu to match your machine. See the benchmark guides for installation, data layout, checkpoint examples, filtering, and resume behavior.
EasyWAM/
├── configs/          # Data, model, task, training, and evaluation configs
├── docs/             # Repository documents
│   ├── README.md      # Documentation index
│   ├── blogs/        # Architecture blogs
│   ├── configurations/ # Configuration guides
│   └── instructions/   # Integration and benchmark guides
├── experiments/      # Benchmark evaluators
├── scripts/          # Training, preprocessing, and caching entrypoints
├── src/              # Models, data pipeline, runtime, and trainer
├── checkpoints/      # External and trained checkpoints
├── data/             # Local datasets and text caches
└── runs/             # Training outputs
🤝 Contributing
EasyWAM is built with the community. You can help by fixing bugs, improving documentation, adding model or benchmark support, or sharing ideas that make World Action Model research more accessible.
Report a bug: Open an Issue with reproduction steps, configuration details, and relevant logs.
Propose a feature or improvement: Open an Issue to discuss the scope and approach before starting a substantial change.
Submit a pull request: Keep changes focused, update documentation when needed, and describe how you verified the change.
We are happy to welcome contributions in any form. If you would like to contribute or help build EasyWAM together, please email [email protected]. See docs/CONTRIBUTING.md for the contribution guidelines.
🙏 Acknowledgements
This project builds on code from FastWAM, and draws inspiration and references from DreamZero and DiT4DiT. Thanks to all the teams above for their valuable contributions to the open-source community.
📝 Citation
We welcome you to cite EasyWAM's experimental results and codebase in your research. If EasyWAM is useful in your research, please cite:
@misc{easywam2026,
  title  = {EasyWAM: A Unified and Efficient Framework for Training and Evaluating World Action Models},
  author = {EasyWAM-Team},
  year   = {2026},
  url    = {https://github.com/OpenMOSS/EasyWAM}
}
Star History
EasyWAM (OpenMOSS/EasyWAM)
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
Searching Database…
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
Что это?EasyWAM — единая исследовательская кодовая база для обучения, дообучения и оценки World Action Models (WAM) — моделей, которые совместно предсказывают будущее видео и действия робота для исследований embodied AI и робототехники.
Это готовый контроллер робота или исследовательский фреймворк для создания WAM?Это исследовательский фреймворк, а не plug-and-play контроллер робота — он предоставляет реализации моделей, рецепты обучения и пайплайны оценки, чтобы исследователи могли строить, дообучать и бенчмаркать свои World Action Models.
Как обучить или оценить модель с его помощью?Скачайте веса предобученных бэкбонов и чекпоинты из коллекции OpenMOSS-Team/EasyWAM на Hugging Face, заранее вычислите текстовые эмбеддинги для датасета бенчмарка, затем запустите скрипты обучения или оценки с переопределениями Hydra и переменными окружения вроде NPROCPERNODE для распределённых запусков.
Нужна ли особая конфигурация GPU?Нужны Python с PyTorch и GPU с поддержкой CUDA; в приведённых бенчмарках использовались 8×NVIDIA H100. FlashAttention 2/3/4 опционален и ускоряет attention, откатываясь к PyTorch SDPA, если он не установлен.
Сколько вычислений на самом деле требует обучение?Даже с оптимизациями EasyWAM обучение модели LIBERO на 20 000 шагов занимает около 6 часов на 8 GPU H100 — быстрее, чем 14 часов в исходной кодовой базе FastWAM, но всё же серьёзная нагрузка на несколько GPU, не то, что запускают на ноутбуке.
Для кого это на самом деле?Он создан для исследователей робототехники и embodied AI, которые хотят обучать, дообучать или бенчмаркать World Action Models, а не для разработчиков, которым нужен готовый развёртываемый продукт.
Какие бэкбоны поддерживает EasyWAM?Сейчас он поддерживает Wan2.2-TI2V-5B и Cosmos-Predict2.5-2B как бэкбоны видеодиффузии, плюс FLUX.2 Klein-4B для варианта, совместимого с ImageWAM.
На каких бенчмарках можно проводить оценку?EasyWAM поставляется с рецептами обучения и оценки для LIBERO, LIBERO-Plus (вариант с упором на устойчивость) и RoboTwin.
Какие архитектуры моделей включены?EasyWAM-Unified использует единый бэкбон Video DiT для совместного предсказания видео и действий, а EasyWAM-MoT, EasyWAM-MoT-Joint, EasyWAM-MoT-IDM и EasyWAM-Hidden используют раздельных DiT-экспертов для видео и действий с разными схемами взаимодействия.
Насколько EasyWAM быстрее исходного кода FastWAM?На 8×H100 EasyWAM-MoT достигает 121,9 сэмплов/с против 51,5 сэмплов/с у FastWAM — рост пропускной способности в 2,37 раза — и сокращает общее время обучения LIBERO примерно на 57%.




 EasyWAM — единая исследовательская кодовая база для обучения, дообучения и оценки World Action Models (WAM) — моделей, которые совместно предсказывают будущее видео и действия робота для исследований embodied AI и робототехники.