SuperMimic-Reproduced
The official implementation is now available: HybridRobotics/supermimic (Apache-2.0, released 2026-11-10 by the paper's authors, also built on mjlab). If you want to use or build on SuperMimic, start there.
This repository is an independent reproduction written from the paper alone, before the official code existed. It is kept as a record of that reproduction: the design decisions, the experiment log, the full-set BONES-SEED results and the released checkpoint. It shares no code with the official implementation and is no longer actively developed.
An independent, from-scratch reproduction of SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model (arXiv:2610.28480, CoRL 2026) for the Unitree G1, built on mjlab / MuJoCo Warp. At the time this was written no official code had been released; everything here (motion library, differentiable FK, world model, BPTT trainer, return-based reset sampling, data-parallel training, Appendix-F benchmark) is implemented from the paper.
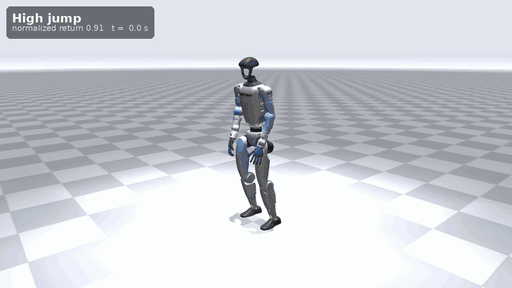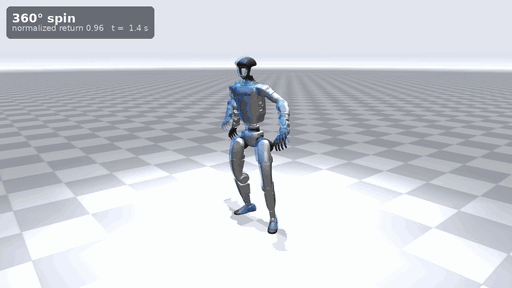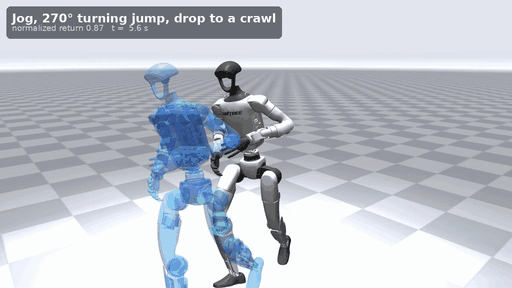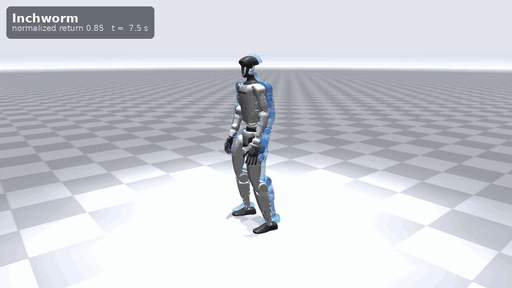
One policy, trained with the paper's observation layout on the full BONES-SEED set (129.9k clips) in 7.1 h on 4×RTX 5090. Solid robot: the policy in simulation (MuJoCo Warp, deterministic Appendix-F protocol). Blue ghost: the reference motion. Clips: high jump, getting up from lying face-down, 360° spin, one-leg hopping, a jog into a 270° turning jump and a drop to a crawl, inchworm. A longer cut with 18 motions (also dance turns, frog jumps, push-ups, kneeling, moonwalk, …) is in media/g1_boneseed_showcase.mp4.
Headline results
Evaluation follows the paper's Appendix F: every clip is played once from its first frame, deterministic policy, no noise, no domain randomization; normalized return = Σ step reward / (0.1 × steps), 1.0 is perfect tracking; a clip fails when the training termination fires.
| Benchmark |
Ours |
Paper |
| BONES-SEED, full set, paper observations (4×RTX 5090, 7.1 h ≈ 28 GPU·h, 100k iterations) |
0.930 normalized return, 145 / 129,491 failures (0.11 %) |
>0.90, 25 / 129,514 (0.02 %) on 1×H100 in 3 h; 0 failures on 2×H100 in 9.8 h |
| LAFAN1, 40 whole clips (100–300 s), paper observations (1×5090) |
0.56–0.59, 3–9 / 40 failures (three independent runs) |
0.82 on 1×H100 in 1.2 h (Fig. 4a) |
| LAFAN1, 40 whole clips, + anchor-relative observations (1×5090, 3.3 h) |
0.904, 3 / 40 failures |
not comparable (extra observation) |
| World-model 8-step open-loop normalized error |
0.0065–0.0099 |
0.007–0.011 |
Other measurements: 4096 environments simulate at ~2×10⁵ env-steps/s on one 5090; one compiled imagination forward+backward (batch 2048, H=32) takes 0.33 s; 4-GPU data parallelism (explicit gradient all-reduce, no NVLink) reaches 91 % scaling efficiency.
Three findings that the numbers above depend on:
- Proprioception-only observations drift on long clips. The paper's policy observation (Table A.1) has no state estimate. On whole 100–300 s LAFAN1 clips the yaw error exceeds 15° within ~9 s, after which the world-frame root and velocity reward terms cannot be earned; the whole-clip return saturates at ~0.58 in three independent runs. Adding BeyondMimic's anchor-relative pose (9 extra goal dims) lifts it to 0.904. BONES-SEED clips are short (median 5.8 s), so the same policy design reaches 0.93 there. We therefore report BONES-SEED with the paper's observations as the headline and label the anchor-observation runs as not comparable.
- The paper's name filter includes acrobatics. Our first filter kept SONIC's acrobatics keywords (cartwheel, handstand, safety roll, …), giving 129,943 clips vs the paper's 129,514. Those 452 clips account for 350 of our 495 failures (handstand 134/134, cartwheel 108/120). With the keywords restored the count is 129,491 (23 off the paper) and the failure rate 0.11 %; the filter script now matches.
- The remaining gap is concentrated in flips. Of the 145 failures, all 54 flip clips fail (the paper reports 1 failure on 44 flips after 3 h). Training return had plateaued at 0.81 with the learning rate not yet decayed (stopped at 100k of 320k scheduled iterations); longer training with the cosine decay is the obvious next step.
The headline checkpoint (100k iterations, 223 MB) is attached to the GitHub release e8-boneseed-100k; it loads directly into scripts/eval_benchmark.py, scripts/play.py and the media scripts below.
Full per-experiment logs (configs, curves, checkpoints, failure breakdowns, dead ends) are in docs/EXPERIMENTS.md (Chinese).
What is implemented
Paper section → code. Everything is torch; nothing from rsl_rl.
| Paper |
Implementation |
| Appendix E data: LAFAN1 (2.45 h) and BONES-SEED (142k CSV → 129.9k clips / 264 h after name + feasibility filters) |
scripts/data/csv_to_npz_batch.py, filter_bones_seed.py, build_library.py; src/supermimic/data/ (own vectorized slerp: mjlab's returns early on near-identical quaternions and lags the pose by a frame) |
| Multi-clip motion library, K=10 future-frame goal, return-based reset sampling over 1 s bins (50 % uniform / 40 % softmax(−25 G/Gmax) / 10 % memory) |
src/supermimic/envs/mdp/motion_library.py (fp16 compact library kept on GPU with online FK), commands.py |
| Table A.1–A.4 observations, BeyondMimic reward (8 terms), termination (|Δh| > 0.25 m or tilt > 0.8), sim context ξ = friction / joint offsets / torso CoM |
src/supermimic/envs/mdp/{observations,rewards,terminations}.py, sim_context.py, state_io.py |
| Differentiable G1 FK (positions and velocities), matches MuJoCo to 1e-10 in fp64 |
src/supermimic/kinematics/g1_fk.py |
| World model: MLP dynamics on heading-canonical features with explicit integration, learned termination head, analytic reward and observation heads through the FK; k=8 autoregressive loss (Eq. 1) |
src/supermimic/world_model/ |
Imagination: H=32 BPTT actor update with survival weighting and critic bootstrap (Eq. 2), TD(λ=0.95) critic (Eq. 3), torch.compiled fwd+bwd |
src/supermimic/imagination/ |
| Algorithm A.1 loop, UTD 0.4, Table A.5/A.6 hyper-parameters, cosine LR decay, torchrun data parallelism (one simulator per rank, explicit all-reduce, lr × √world) |
src/supermimic/training/loop.py, src/supermimic/scripts/train.py |
| Appendix F benchmark, push test, drift diagnostic, interactive replay |
src/supermimic/eval/benchmark.py, scripts/eval_benchmark.py, eval_push.py, diag_drift.py, play.py |
Deviations and choices the paper leaves open (U1–U20 in docs/PAPER_SPEC.md, decisions D1–D20 in docs/REPRODUCTION_PLAN.md) are recorded with their reasons; the ones that changed after measurement are in the experiment log. Not done: velocity interface and distillation, PPO baselines, the H×critic ablation, ONNX export, real-robot deployment.
Setup
Python 3.12 with uv. Pinned: torch 2.14.1+cu130, mujoco 3.16, warp 1.18, mjlab commit 8bb2bc9 (see [tool.uv.sources] in pyproject.toml). Tested on RTX 5090 (driver 580). If your system PYTHONPATH carries other Python packages (e.g. ROS), prefix commands with env -u PYTHONPATH.
uv sync --group dev
env -u PYTHONPATH uv run pytest tests -q
Data
Neither dataset is redistributed here.
| Dataset |
Source |
Result |
| LAFAN1, 40 clips retargeted to the G1 (30 fps CSV) |
HF lvhaidong/LAFAN1_Retargeting_Dataset, folder g1/ |
data/npz/lafan1/, 2.451 h |
| BONES-SEED, 142,220 clips (120 fps CSV) |
HF bones-studio/seed, g1.tar.gz |
50 Hz npz → name + feasibility filter → 129,491 clips → fp16 compact library data/library/bones_seed_compact.pt (6.7 GB, resident on GPU) |
uv run python scripts/data/csv_to_npz_batch.py --help
uv run python scripts/data/filter_bones_seed.py --help
uv run python scripts/data/build_library.py --help
Training
# LAFAN1, paper observations, one GPU
env -u PYTHONPATH uv run sm-train --run-name lafan1 --data.npz-dir data/npz/lafan1 \
  --env.num-envs 4096 --policy-trainer.batch-size 4096 --schedule.max-hours 3

# BONES-SEED, full set, 4 GPUs (one process per GPU; this is the headline run)
env -u PYTHONPATH uv run torchrun --nproc_per_node 4 -m supermimic.scripts.train --run-name boneseed \
  --data.library data/library/bones_seed_compact.pt --env.num-envs 4096 --policy-trainer.batch-size 2048

# Options: --env.anchor-obs (BeyondMimic anchor-relative observation, deviates from the paper), --resume <ckpt>
Defaults follow Table A.5/A.6: 4096 environments, H=32, UTD 0.4, γ=0.99, critic 5 epochs × 4 minibatches, 10 world-model batches per update, cosine decay to 0.03× over 250k iterations. Logs go to TensorBoard under logs/<run>/tb; checkpoints every --schedule.checkpoint-interval iterations.
# Appendix F whole-clip benchmark (shard over GPUs with --clip-list, merge with scripts/merge_benchmark_shards.py)
env -u PYTHONPATH uv run python scripts/eval_benchmark.py --ckpt logs/boneseed/ckpt_latest.pt --npz-dir data/npz/bones_seed --num-envs 1024

# Interactive replay (native MuJoCo viewer, or viser in the browser without a display)
env -u PYTHONPATH uv run python scripts/play.py --ckpt logs/boneseed/ckpt_latest.pt --npz-dir data/npz/bones_seed --clips high_jump_R_001__A450

# Record deterministic rollouts and render them (solid = policy, ghost = reference); the GIF above was made this way
env -u PYTHONPATH uv run python scripts/media/record_rollout.py --ckpt logs/boneseed/ckpt_latest.pt \
  --npz-dir data/npz/bones_seed --clips high_jump_R_001__A450 fancy_spin_R_001__A430_M --out media/rollouts.npz
MUJOCO_GL=glfw env -u PYTHONPATH uv run python scripts/media/render_rollout.py --traj media/rollouts.npz --out-dir media/clips \
  --segments high_jump_R_001__A450:0:3 fancy_spin_R_001__A430_M:0.5:4.5 --titles "high_jump_R_001__A450=High jump" --concat media/showcase.mp4
ffmpeg -i media/showcase.mp4 -vf "fps=10,scale=560:-1,split[a][b];[a]palettegen=max_colors=64[p];[b][p]paletteuse=dither=bayer" media/showcase.gif
Repository layout
src/supermimic/
  config.py            TrainConfig (tyro CLI: data / env / world_model / policy / wm_trainer / policy_trainer / schedule)
  data/                CSV → 50 Hz npz conversion, replay buffer, simulator recorder
  envs/                mjlab ManagerBasedRlEnv config: multi-clip motion command, return-based resets, full-state I/O, sim context
    mdp/               motion_library (fp16 compact library + online FK), commands, observations, rewards, terminations
  kinematics/          differentiable G1 position + velocity FK (torch)
  world_model/         canonical-state MLP dynamics, termination head, analytic reward/observation heads, trainer
  imagination/         imagined rollouts, Eq. 2 objective + GAE critic targets, BPTT policy trainer, torch.compile wrapper
  policy/              MotionEncoder (680 → 32) + policy / critic MLPs
  training/            main loop (Algorithm A.1), cosine LR, data parallelism (torchrun, explicit all-reduce)
  eval/                Appendix F benchmark
  scripts/train.py     training entry point (sm-train)
scripts/               data pipeline, benchmark, push test, drift diagnostic, replay viewer, media, throughput benchmarks
tests/                 numerical parity (FK, analytic heads, world model, imagination, motion conversion) and smoke tests
docs/                  PAPER_SPEC, REPRODUCTION_PLAN, REVIEW_LOG, EXPERIMENTS (Chinese)
media/                 demo GIF / mp4 rendered from the headline checkpoint
Documentation
The design documents are in Chinese; a full Chinese version of this README follows the English one below.
| File |
Content |
| docs/PAPER_SPEC.md |
Every number, equation and protocol in the paper transcribed; the "unspecified" list U1–U20 |
| docs/REPRODUCTION_PLAN.md |
Plan: goals, environment, design decisions D1–D20, repo skeleton, phased steps, tests, budget, risks |
| docs/REVIEW_LOG.md |
Self-review and two adversarial reviews of the plan |
| docs/EXPERIMENTS.md |
Experiment log: configuration, curves, evaluation, decisions that deviated from the plan, pitfalls |
Engineering notes
- mjlab's
csv_to_npz quaternion slerp returns early when consecutive frames are almost identical (pose lags by a frame); the converter here uses its own vectorized slerp (matches scipy to 1e-9).
- MuJoCo Warp's solver-overflow
printf is a compile-time constant; it must be disabled after put_model and before graph capture, otherwise early policies trigger it every step and the simulation runs 10× slower.
- Under torchrun MuJoCo Warp always lands on the first visible GPU;
scripts/train.py sets CUDA_VISIBLE_DEVICES per rank.
- Resuming from a checkpoint restarts the replay-buffer warm-up relative to the resume point (the headline run was resumed once after an accidental kill).
Attribution and license
- Method: Q. Liao, Y. Shao, J. Long, K. Zakka, R. Horowitz, P. Abbeel, K. Sreenath, SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model, CoRL 2026, arXiv:2610.28480. This is an independent re-implementation, not affiliated with the authors.
- Official code: HybridRobotics/supermimic (Apache-2.0). This reproduction predates it, was written from the paper alone, and contains no code from it.
- mjlab, MuJoCo and MuJoCo Warp are used unmodified under their own licenses. LAFAN1 motions (Ubisoft La Forge, CC BY-NC-ND 4.0), their G1 retargets and the BONES-SEED data are not redistributed; the demo media show reference motions for illustration only and are not covered by this repository's license.
- Code: MIT, Copyright (c) 2026 Yuxi Liu.
中文版
原作者的官方实现已开源:HybridRobotics/supermimic(Apache-2.0,2026-11-10 由论文作者发布,同样基于 mjlab)。想使用或在 SuperMimic 上继续开发,请以官方版本为准。
本仓库是官方代码发布前、仅依据论文做的独立复现,保留下来作为记录:设计决策、实验日志、BONES-SEED 全量结果和已发布的检查点。与官方实现没有代码上的关系,后续不再主动开发。
从零复现 SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model(arXiv:2610.28480,CoRL 2026),目标机器人 Unitree G1,底座 mjlab / MuJoCo Warp。编写时论文尚未公开代码,这里的动作库、可微 FK、世界模型、BPTT 训练器、基于回报的重置采样、多卡训练、Appendix F 评测全部按论文自己实现,不使用 rsl_rl。
开头的 GIF:同一个策略,按论文的观测口径在 BONES-SEED 全量(12.99 万条)上训练,四卡 RTX 5090 共 7.1 h。实体 = 仿真中的策略(MuJoCo Warp,Appendix F 的确定性协议),蓝色半透明 = 参考动作。片段依次为:高跳、趴着起身、原地 360° 旋转、单腿跳、慢跑接 270° 转体跳再趴下爬行、尺蠖爬行。18 段的完整版在 media/g1_boneseed_showcase.mp4。
主要结果
评测协议为论文 Appendix F:每条 clip 从首帧整条确定性播放,无噪声、无域随机化;归一化回报 = Σ每步奖励 / (0.1 × 步数),1.0 为完美跟踪;"失败" = 训练终止条件触发。
| 基准 |
本仓库 |
论文 |
| BONES-SEED 全量,论文观测(4×RTX 5090,7.1 h ≈ 28 GPU·h,10 万次迭代) |
0.930,145 / 129,491 失败(0.11%) |
>0.90,25 / 129,514(0.02%),1×H100 3 h;2×H100 9.8 h 为 0 失败 |
| LAFAN1 40 条整条(100–300 s),论文观测(1×5090) |
0.56–0.59,3–9 / 40 失败(三次独立 run) |
0.82,1×H100 1.2 h(Fig. 4a) |
| LAFAN1 40 条整条,+ 锚点相对观测(1×5090,3.3 h) |
0.904,3 / 40 失败 |
不可比(多了观测项) |
| 世界模型 8 步开环归一化误差 |
0.0065–0.0099 |
0.007–0.011 |
其他:4096 环境在一张 5090 上约 2×10⁵ env-steps/s;编译后一次想象 fwd+bwd(批 2048,H=32)0.33 s;四卡数据并行(显式梯度 all-reduce,无 NVLink)效率 91%。
上面的数字建立在三个结论上:
- 纯本体观测在长 clip 上会漂移。 论文 Table A.1 的策略观测没有状态估计。在整条 100–300 s 的 LAFAN1 上,偏航误差约 9 s 内超过 15°,之后世界系的根部与速度奖励项拿不到,整条回报在三个独立 run 里一致封顶 ~0.58;加上 BeyondMimic 的锚点相对位姿(goal 组追加 9 维)可到 0.904。BONES-SEED 的 clip 很短(中位 5.8 s),同样的设计能到 0.93。因此正式结果以论文观测口径的 BONES-SEED 为准,锚点观测的 run 标为不可比。
- 论文的名字过滤包含杂技类。 最初的过滤保留了 SONIC 关键词表里的杂技项(cartwheel、handstand、safety roll 等),得到 129,943 条而论文是 129,514 条;这 452 条贡献了 495 个失败中的 350 个(handstand 134/134、cartwheel 108/120)。加回关键词后为 129,491 条(与论文差 23 条)、失败率 0.11%,过滤脚本已同步。
- 剩余差距集中在翻转类。 145 个失败里 54 条 flip 全部失败(论文 3 h 后 44 条 flip 只失败 1 条)。训练回报在 0.81 平台、学习率尚未衰减(计划 32 万次迭代,10 万次即停),延长训练让余弦衰减生效是最直接的下一步。
正式检查点(10 万次迭代,223 MB)挂在 GitHub release e8-boneseed-100k,可直接用于 scripts/eval_benchmark.py、scripts/play.py 和录制脚本。
每个实验的配置、曲线、评测、失败构成和踩坑见 docs/EXPERIMENTS.md。
实现内容
论文章节 → 代码(全部 torch):
| 论文 |
实现 |
| Appendix E 数据:LAFAN1(2.45 h)与 BONES-SEED(14.2 万 CSV → 名字 + 可行性过滤后 12.99 万条 / 264 h) |
scripts/data/csv_to_npz_batch.py、filter_bones_seed.py、build_library.py;src/supermimic/data/(自己的向量化 slerp:mjlab 的在相邻帧几乎相同时提前返回、姿态滞后一帧) |
| 多 clip 动作库、K=10 未来帧目标、1 s 分桶的回报重置采样(50% 均匀 / 40% softmax(−25 G/Gmax) / 10% 记忆) |
src/supermimic/envs/mdp/motion_library.py(fp16 紧凑库常驻显存、在线 FK)、commands.py |
| Table A.1–A.4 观测、BeyondMimic 8 项奖励、终止(|Δh| > 0.25 m 或 tilt > 0.8)、sim context ξ = 摩擦 / 关节偏置 / 躯干质心 |
src/supermimic/envs/mdp/{observations,rewards,terminations}.py、sim_context.py、state_io.py |
| 可微 G1 FK(位置与速度),fp64 下与 MuJoCo 一致到 1e-10 |
src/supermimic/kinematics/g1_fk.py |
| 世界模型:朝向规范化特征上的 MLP 动力学 + 显式积分、学习式终止头、经 FK 的解析奖励/观测头;k=8 自回归损失(Eq. 1) |
src/supermimic/world_model/ |
想象:H=32 BPTT 策略更新(生存加权 + critic 自举,Eq. 2)、TD(λ=0.95) critic(Eq. 3)、torch.compile 的 fwd+bwd |
src/supermimic/imagination/ |
| Algorithm A.1 主循环、UTD 0.4、Table A.5/A.6 超参、余弦学习率、torchrun 数据并行(每 rank 一个仿真器、显式 all-reduce、lr × √卡数) |
src/supermimic/training/loop.py、src/supermimic/scripts/train.py |
| Appendix F 评测、推力测试、漂移诊断、交互回放 |
src/supermimic/eval/benchmark.py、scripts/eval_benchmark.py、eval_push.py、diag_drift.py、play.py |
论文未指明之处(U1–U20,见 docs/PAPER_SPEC.md)和设计决策(D1–D20,见 docs/REPRODUCTION_PLAN.md)都记录了理由;实测后改动的决定在实验日志里。未做:速度接口与蒸馏、PPO 基线、H×critic 消融、ONNX 导出、真机。
环境、数据、训练、评测
命令与英文版相同,见上文 Setup / Data / Training / Evaluation and media 四节。要点:
- Python 3.12 +
uv;固定 torch 2.14.1+cu130、mujoco 3.16、warp 1.18、mjlab 8bb2bc9;在 RTX 5090(驱动 580)上验证。系统 PYTHONPATH 若带有其他 Python 包(例如 ROS),命令前加 env -u PYTHONPATH。
- 数据不随仓库分发:LAFAN1 来自 HF
lvhaidong/LAFAN1_Retargeting_Dataset 的 g1/;BONES-SEED 来自 HF bones-studio/seed 的 g1.tar.gz,转 50 Hz npz → 过滤 → fp16 紧凑库(6.7 GB,常驻显存)。
- 训练默认超参按 Table A.5/A.6;多卡用
torchrun --nproc_per_node 4 -m supermimic.scripts.train,一进程一卡。
- 录制与渲染:
scripts/media/record_rollout.py 按 Appendix F 协议记录每步的机器人与参考 qpos,scripts/media/render_rollout.py 用 MuJoCo 离屏渲染(实体 = 策略,半透明 = 参考),--segments 选时间窗、--titles 写标题、--concat 拼接。
文档
工程备注
- mjlab 的
csv_to_npz 四元数 slerp 在相邻帧几乎相同时会提前返回(姿态滞后一帧),本仓库用自己的向量化 slerp(与 scipy 一致到 1e-9)。
- MuJoCo Warp 的 solver 溢出 printf 是编译期常量,必须在
put_model 后、图捕获前关闭,否则早期策略每步触发、仿真慢 10×。
- torchrun 下 MuJoCo Warp 总在第一张可见卡上,
scripts/train.py 按 rank 设置 CUDA_VISIBLE_DEVICES。
- 续训时回放缓冲区的预热相对续训点重新计数(正式 run 曾因误杀续训过一次)。
致谢与许可
- 方法:Q. Liao, Y. Shao, J. Long, K. Zakka, R. Horowitz, P. Abbeel, K. Sreenath, SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model, CoRL 2026, arXiv:2610.28480。本仓库为独立复现,与作者无关。
- 官方代码:HybridRobotics/supermimic(Apache-2.0)。本复现早于官方代码,仅依据论文编写,不含其任何代码。
- mjlab、MuJoCo、MuJoCo Warp 按各自许可原样使用。LAFAN1 动作(Ubisoft La Forge,CC BY-NC-ND 4.0)、其 G1 重定向数据和 BONES-SEED 数据均不随仓库分发;演示视频中的参考动作仅作展示,不在本仓库许可范围内。
- 代码:MIT,Copyright (c) 2026 Yuxi Liu。

 这是对 SuperMimic 论文(arXiv:2610.28480)的独立从零复现。它结合了可微分的学习型世界模型与短视野 BPTT 演员-评论家方法,用于在 Unitree G1 人形机器人上进行全身动作跟踪,基于 mjlab/MuJoCo Warp 构建。