
OpenKB: Open LLM Knowledge Base
Scale to long documents • Reasoning-based retrieval • Native multi-modality • No Vector DB
📢 Recent Updates
- Google Open Knowledge Format (OKF): Wiki pages follow the Google OKF specification for knowledge sharing.
- Entity Pages: People, orgs, places, and products as dedicated wiki pages, auto-extracted and kept in sync.
📑 What is OpenKB
OpenKB (Open Knowledge Base) is an open-source system (in CLI) that compiles raw documents into a structured, interlinked wiki-style knowledge base using LLMs, powered by PageIndex's vectorless, reasoning-based retrieval for long documents.
The idea is based on a concept described by Andrej Karpathy: LLMs generate summaries, concept pages, and cross-references, all maintained automatically. Knowledge compounds over time instead of being re-derived on every query.
Why not traditional RAG?
Traditional RAG rediscovers knowledge from scratch on every query. Nothing accumulates. OpenKB compiles knowledge once into a persistent wiki, then keeps it current. Cross-references already exist, contradictions are flagged, and synthesis reflects everything consumed.
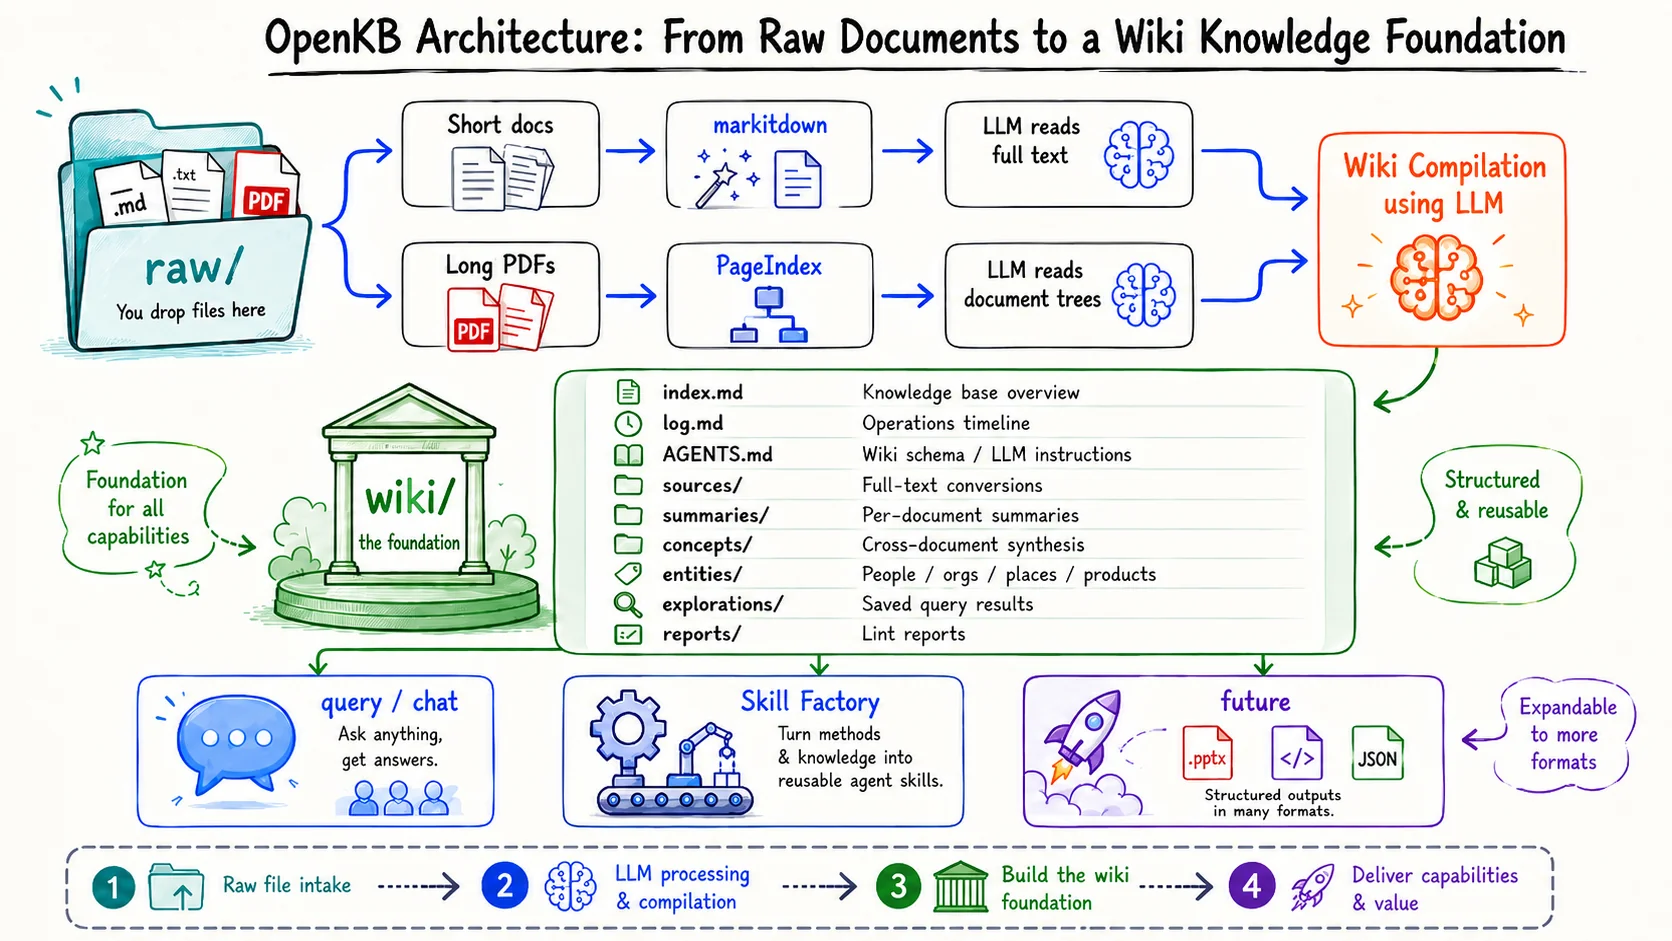
OpenKB has two layers: a wiki foundation that compiles and maintains your knowledge, and generators (query / chat / Skill Factory) that turn it into useful output. See Usage for the full command list.
Features
- Broad format support: PDF, Word, Markdown, PowerPoint, HTML, Excel, CSV, text, URLs, and more.
- Scales to long documents: Long and complex documents are handled via PageIndex tree indexing, enabling accurate, vectorless, context-aware retrieval.
- Native multi-modality: Retrieves and understands figures, tables, and images, not just text.
- Compiled wiki: The LLM compiles your documents into summaries, concept pages, entity pages, and cross-links, all kept in sync.
- Query & chat: One-off questions or multi-turn conversations over your wiki, with persisted sessions to resume.
- Skill Factory: Distills redistributable agent skills from your wiki.
- OKF-ready: Wiki pages follow the Google OKF specification for knowledge sharing.
- Obsidian-compatible: The wiki is plain
.md files with cross-links. Opens in Obsidian for graph view.
- Knowledge Workbench (Web UI): A bundled web UI served at
/ to browse the KB, upload and compile documents, and stream queries and chats — all in the browser.
🚀 Getting Started
Install
pip install openkb
Other install options:
Latest from GitHub:
pip install git+https://github.com/VectifyAI/OpenKB.git
Install from source (editable, for development):
git clone https://github.com/VectifyAI/OpenKB.git
cd OpenKB
pip install -e .
Quick Start
# 1. Create a directory for your knowledge base
mkdir my-kb && cd my-kb

# 2. Initialize the knowledge base
openkb init

# 3. Add documents
openkb add paper.pdf
openkb add ~/papers/                            # Add a whole directory
openkb add https://arxiv.org/pdf/2509.11420     # Or fetch from a URL

# 4. Ask a question
openkb query "What are the main findings?"

# 5. Or chat interactively
openkb chat

# (Optional) Turn the wiki into other outputs
openkb skill new my-expert "Reason like an expert on <your-topic>"   # a portable agent skill
openkb visualize                                                     # an interactive knowledge graph
openkb deck new my-deck "An intro deck on <your-topic>"              # slides — a single-file HTML deck
Set up your LLM
OpenKB supports multiple LLM providers (OpenAI, Claude, Gemini, etc.) via LiteLLM (pinned to a safe version).
Set your model during openkb init or in .openkb/config.yaml using the provider/model LiteLLM format (e.g. anthropic/claude-sonnet-4-6). OpenAI models can omit the prefix (e.g. gpt-5.4).
Create a .env file with your LLM API key:
LLM_API_KEY=your_llm_api_key
Subscription-based providers that authenticate via OAuth device flow (e.g. chatgpt/*, github_copilot/*) need no API key; OpenKB skips the missing-key warning for them.
Knowledge Workbench (Web UI)
OpenKB ships a bundled web UI, served by the REST API at /. Install the API extra and start the server — no configuration needed:
pip install "openkb[web]"
openkb-web                       # serves the API + Workbench at http://127.0.0.1:7566/
Open http://127.0.0.1:7566/ for the Workbench. Auth is off by default (local-first); set OPENKB_API_TOKEN to require a bearer token before exposing the server. See the full Web UI guide.
Working on the UI itself? Run the Vite dev server with cd frontend && npm install && npm run dev (it proxies /api to a running openkb-web), or npm run build to regenerate the bundled openkb/web/.
🧩 How OpenKB Works
Architecture
Short vs Long Document Handling
|
Short documents |
Long documents (PDF ≥ 20 pages) |
| Convert |
markitdown → Markdown |
PageIndex → tree index + summaries |
| Images |
Extracted inline (pymupdf) |
Extracted by PageIndex |
| LLM reads |
Full text |
Document trees |
| Result |
summary + concepts |
summary + concepts |
Short documents are read in full by the LLM. Long PDFs are processed by PageIndex into a hierarchical tree index. The LLM reads the tree instead of the full text, enabling accurate and scalable retrieval for long documents.
Knowledge Compilation
When you add a document, the LLM:
- Generates a summary page
- Reads existing concept and entity pages
- Creates or updates concepts with cross-document synthesis
- Creates or updates entity pages (people, orgs, places, products)
- Updates the index and log
A single source might touch 10--15 wiki pages. Knowledge accumulates: each document enriches the existing wiki rather than sitting in isolation.
⚙️ Usage
OpenKB commands fall into two layers: the wiki foundation (compile + manage your knowledge) and generators (turn that wiki into useful output). Each links to a concrete walkthrough — a real artifact OpenKB generated from one sample paper (browse them all in examples/).
Layer 1: 🧱 Wiki Foundation — compile and maintain
| Command |
Description |
openkb init |
Initialize a new knowledge base (interactive) |
openkb add <file_or_dir_or_URL> |
Add files, directories, or URLs and compile to wiki (URL content type is auto-detected) |
openkb list |
List indexed documents and concepts |
openkb status |
Show knowledge base stats |
openkb watch |
Watch raw/ and auto-compile new files |
openkb lint |
Run structural and knowledge health checks |
More wiki commands:
| Command |
Description |
openkb remove <doc> |
Remove a document and clean up its wiki pages, images, registry, and PageIndex state (--dry-run to preview, --keep-raw / --keep-empty to retain artifacts) |
openkb recompile [<doc>] [--all] |
Re-run the compile pipeline on already-indexed docs without re-indexing. Regenerates summaries and rewrites concept pages; manual edits are overwritten (--dry-run to preview, --refresh-schema to also update wiki/AGENTS.md) |
openkb feedback ["msg"] |
File feedback by opening a prefilled GitHub issue (--type bug/feature/question to tag it) |
→ Example: the everyday loop walked through end to end — examples/commands/.
Layer 2: 💡 Generators — turn the wiki into output
A "generator" reads from the compiled wiki and produces something usable: an answer, a conversation, a skill folder. The wiki is the substrate; generators are the surfaces.
| Command |
Output |
Example |
openkb query "question" |
A grounded answer with citations (--save to persist to wiki/explorations/) |
query & save |
openkb chat |
Interactive multi-turn session over the wiki (--resume, --list, --delete to manage sessions) |
chat |
openkb visualize |
A self-contained interactive knowledge graph at output/visualize/graph.html — 3D, mind-map, and radial views |
visualize |
openkb skill new <skill-name> "<intent>" |
Distill a redistributable agent skill from your wiki (see Skill Factory below) |
skills |
openkb deck new <name> "<intent>" |
Generate a single-file HTML slide deck (--skill picks a theme, --critique runs a quality pass) |
slides |
(i) 💬 Query & Chat — ask the wiki
openkb query "..." answers a single question with a grounded, cited answer from your wiki. openkb chat is interactive, an ongoing multi-turn session over the same wiki (--resume, --list, --delete to manage sessions). → Walked through with real saved output in examples/commands/ (query) and examples/chat/ (chat).
Inside a chat, type / to access slash commands (Tab to complete).
More slash commands:
/help: list available commands/status: show knowledge base status/list: list all documents/add <path>: add a document or directory without leaving the chat/skill new <skill-name> "<intent>": compile a skill from this chat (see below)/deck new <name> "<intent>": generate an HTML slide deck from the wiki/critique <path>: run the HTML critic over an existing deck/save [name]: export the transcript to wiki/explorations//clear: start a fresh session (the current one stays on disk)/lint: run knowledge base lint/exit: exit (Ctrl-D also works)
(ii) 🛠 Skill Factory — drop in a book; out comes a digital expert.
openkb skill new distills a portable agent skill from your wiki that Claude Code, Codex, and Gemini can install and load natively. Drop in a book's worth of papers; out comes a specialist other agents can call on. → A real generated skill, plus install / share / eval / rollback, is walked through in examples/skills/.
More skill commands:
| Command |
Output |
openkb skill validate [name] |
Validate compiled skills (auto-runs after skill new) |
openkb skill eval <name> |
Check the skill triggers on the right prompts |
openkb skill history <name> / openkb skill rollback <name> |
Version history + rollback for skills |
🔧 Configuration
Settings
OpenKB settings are initialized by openkb init and stored in .openkb/config.yaml:
model: gpt-5.4                   # LLM model (any LiteLLM-supported provider)
language: en                     # Wiki output language
pageindex_threshold: 20          # PDF pages threshold for PageIndex
The full settings reference — entity_types, OAuth providers (chatgpt/*, github_copilot/*), and LiteLLM tuning (timeouts for slow local runtimes like Ollama / LM Studio, drop_params, GitHub Copilot headers, install notes) — is in examples/configuration/.
PageIndex Setup
Long-document retrieval is a known challenge for LLMs. PageIndex solves this with vectorless, reasoning-based retrieval, by building a hierarchical tree index that lets LLMs reason over the index for context-aware retrieval.
PageIndex runs locally by default using the open-source version, with no external dependencies required.
Cloud Support (Optional):
For large or complex PDFs, PageIndex Cloud can be used to access additional capabilities, including:
- OCR support for scanned PDFs (via hosted VLM models)
- Faster structure generation
- Scalable indexing for large documents
Set PAGEINDEX_API_KEY in your .env to enable cloud features:
PAGEINDEX_API_KEY=your_pageindex_api_key
→ Example: local vs. cloud indexing, and importing a cloud-indexed doc — examples/pageindex-cloud/.
AGENTS.md
The wiki/AGENTS.md file defines wiki structure and conventions. It's the LLM's instruction manual for maintaining the wiki. Customize it to change how your wiki is organized.
The LLM reads AGENTS.md from disk at runtime, so your edits take effect immediately.
🔌 Integrations
Using with Obsidian
The wiki is a directory of Markdown files with [[wikilinks]]. Obsidian renders it natively.
- Open
wiki/ as an Obsidian vault
- Browse summaries, concepts, and explorations
- Use graph view to see knowledge connections
- Use Obsidian Web Clipper to add web articles to
raw/
Using with Claude Code / Codex / Gemini CLI
OpenKB ships a SKILL.md so any agent can read your compiled wiki. No extra runtime, no MCP setup, just install the skill once.
Claude Code:
/plugin marketplace add VectifyAI/OpenKB
/plugin install openkb@vectify
OpenAI Codex CLI:
(no marketplace command yet; manual symlink)
git clone https://github.com/VectifyAI/OpenKB.git ~/openkb-src
mkdir -p ~/.agents/skills
ln -s ~/openkb-src/skills/openkb ~/.agents/skills/openkb
Gemini CLI:
gemini skills install https://github.com/VectifyAI/OpenKB.git --path skills/openkb --consent
The skill is read-only. It won't run openkb add, remove, or lint --fix without you asking. See skills/openkb/SKILL.md for the full instruction set.
REST API
OpenKB ships a FastAPI service for HTTP clients. Install with pip install -e ".[web]", then start with python -m openkb.api. The interactive API reference is at /docs (importable into Postman).
See the full REST API reference for endpoints, auth, and SSE streaming.
🧭 Learn More
Compared to Karpathy's Approach
|
Karpathy's workflow |
OpenKB |
| Short documents |
LLM reads directly |
markitdown → LLM reads |
| Long documents |
Context limits, context rot |
PageIndex tree index |
| Input sources |
Web clipper → .md |
PDF, Word, PPT, Excel, HTML, text, CSV, .md, URLs |
| Wiki compilation |
LLM agent |
LLM agent (same) |
| Entity extraction |
Manual |
Automatic (people, orgs, places, products) |
| Q&A |
Query over wiki |
|

 OpenKB is an open-source CLI system that compiles raw documents into a structured, interlinked wiki-style knowledge base using LLMs, so knowledge accumulates over time instead of being re-derived on every query.