19.6K ·GitHub
What is this?
 KTransformers is a research framework for efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing, letting huge MoE models run on hardware that doesn't have enough VRAM to hold them entirely on GPU.
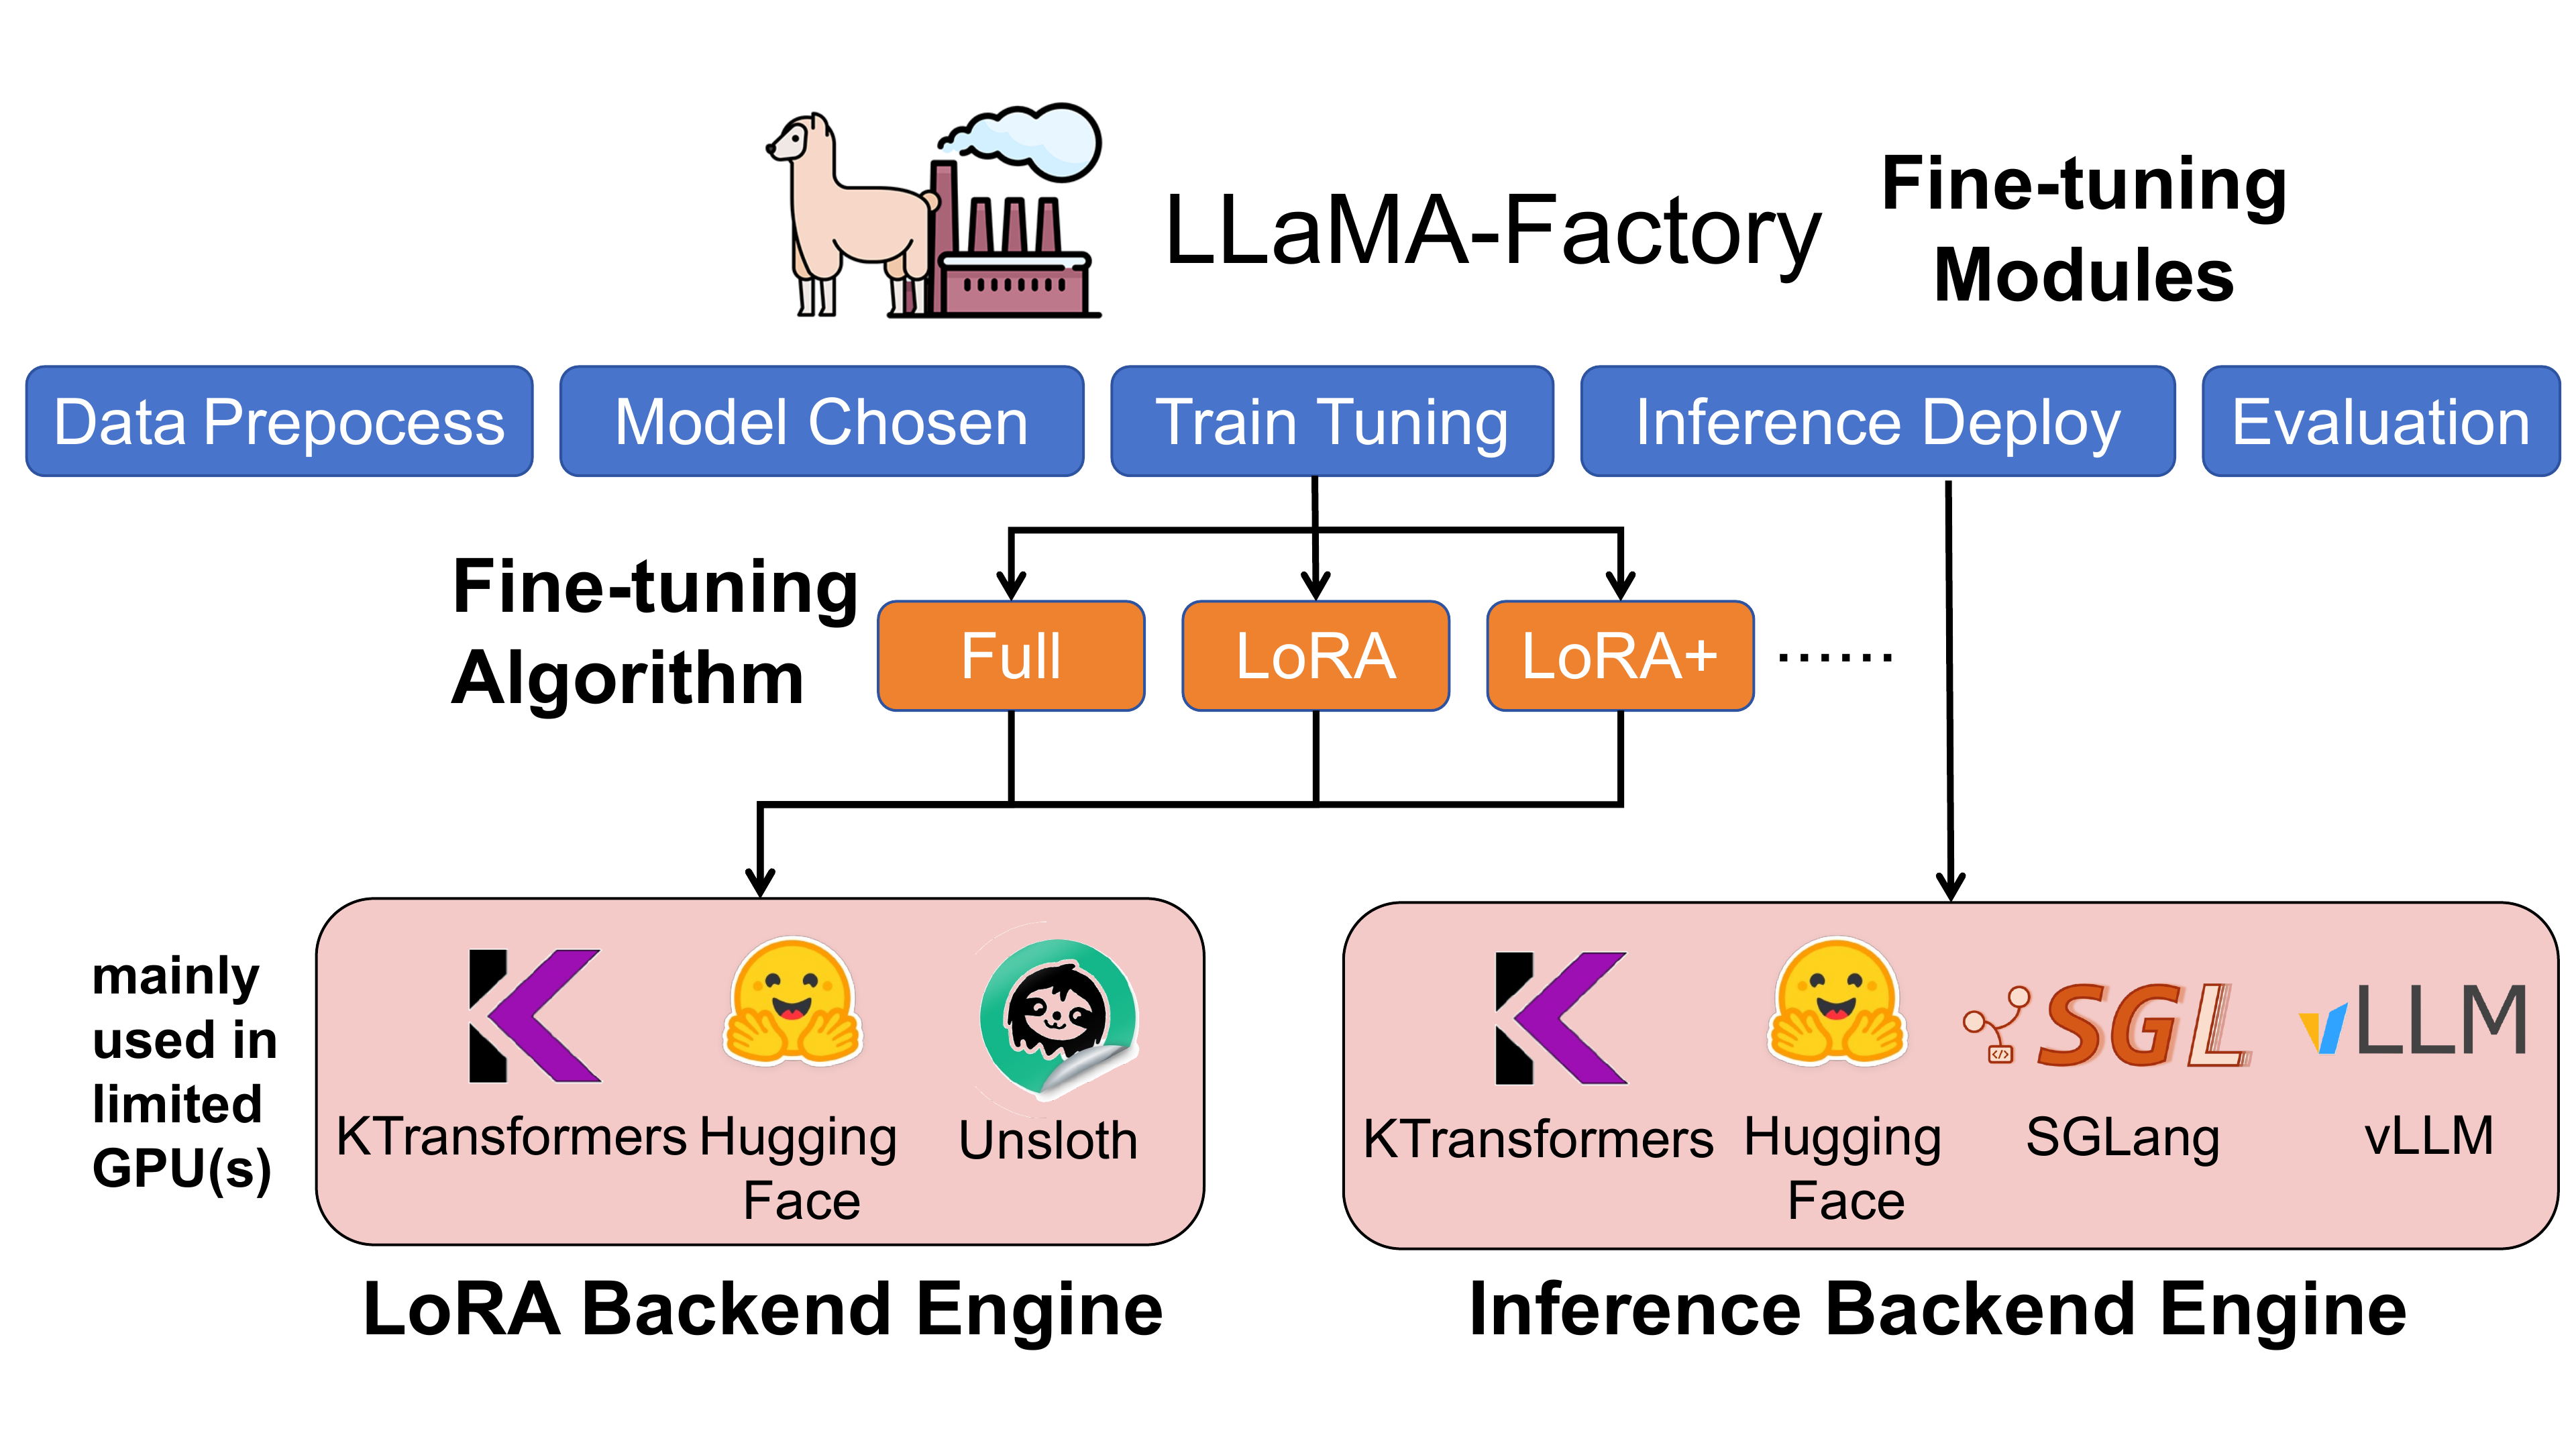
Is this a standalone chat app or something I plug into my own serving stack?It's a framework/kernel library, not an app: you integrate its 'kt-kernel' Python API into inference servers like SGLang for serving, or into LlamaFactory for fine-tuning.
It's a framework/kernel library, not an app: you integrate its 'kt-kernel' Python API into inference servers like SGLang for serving, or into LlamaFactory for fine-tuning.How do I get inference or fine-tuning running with it?The repo provides separate Quick Start entry points for Inference (via the kt-kernel Python API, often paired with SGLang) and SFT (via the LlamaFactory integration and the MoE Fine-Tuning Cookbook).
The repo provides separate Quick Start entry points for Inference (via the kt-kernel Python API, often paired with SGLang) and SFT (via the LlamaFactory integration and the MoE Fine-Tuning Cookbook).What hardware do I need to actually use it?It needs CPUs with AMX or AVX512/AVX2 instructions for the quantized kernels, plus a GPU (NVIDIA, AMD via ROCm, Intel Arc, or Ascend NPU); running the largest models like DeepSeek-R1 can require up to 382GB of DRAM or multiple GPUs.
It needs CPUs with AMX or AVX512/AVX2 instructions for the quantized kernels, plus a GPU (NVIDIA, AMD via ROCm, Intel Arc, or Ascend NPU); running the largest models like DeepSeek-R1 can require up to 382GB of DRAM or multiple GPUs.Are there hardware limits I should know about before trying it?Some features were originally restricted to Intel CPUs with AMX; LoRA fine-tuning only recently gained support for plain AVX512 x86 CPUs (including AMD servers) without needing AMX, so older setups may miss newer optimizations.
Some features were originally restricted to Intel CPUs with AMX; LoRA fine-tuning only recently gained support for plain AVX512 x86 CPUs (including AMD servers) without needing AMX, so older setups may miss newer optimizations.Does it run on Windows, or only Linux servers?It runs natively on Windows as well as Linux, and supports multiple GPU backends including NVIDIA, AMD (ROCm), Intel Arc, and Ascend NPU.
It runs natively on Windows as well as Linux, and supports multiple GPU backends including NVIDIA, AMD (ROCm), Intel Arc, and Ascend NPU.What inference speed can I expect for DeepSeek-R1?With 8×L20 GPUs plus a Xeon Gold 6454S CPU, KTransformers reaches about 227.85 tokens/s total throughput and 87.58 tokens/s output throughput at 8-way concurrency for DeepSeek-R1-0528 (FP8).
With 8×L20 GPUs plus a Xeon Gold 6454S CPU, KTransformers reaches about 227.85 tokens/s total throughput and 87.58 tokens/s output throughput at 8-way concurrency for DeepSeek-R1-0528 (FP8).Can I fine-tune a huge MoE model on just one consumer GPU?Yes — Qwen3-30B-A3B can be fine-tuned using roughly 24GB of GPU memory on a single RTX 4090, while DeepSeek-V3/R1 fine-tune using about 80GB total across 4x RTX 4090s.
Yes — Qwen3-30B-A3B can be fine-tuned using roughly 24GB of GPU memory on a single RTX 4090, while DeepSeek-V3/R1 fine-tune using about 80GB total across 4x RTX 4090s.Which models get day-0 support?Recent day-0 releases include GLM-5.3-flash, MiniMax-M3, GLM-5.2, Kimi-K2.5 and GLM-5, alongside ongoing support for DeepSeek-V3/R1, Qwen3 and experimental LLaMA 4.
Recent day-0 releases include GLM-5.3-flash, MiniMax-M3, GLM-5.2, Kimi-K2.5 and GLM-5, alongside ongoing support for DeepSeek-V3/R1, Qwen3 and experimental LLaMA 4.Which topics is it in?cpu-inference, intel, sglang, amd-gpu, rocm, cpu, mixture-of-experts, moe, llama, lora, llm-inference, high-performance
cpu-inference, intel, sglang, amd-gpu, rocm, cpu, mixture-of-experts, moe, llama, lora, llm-inference, high-performance