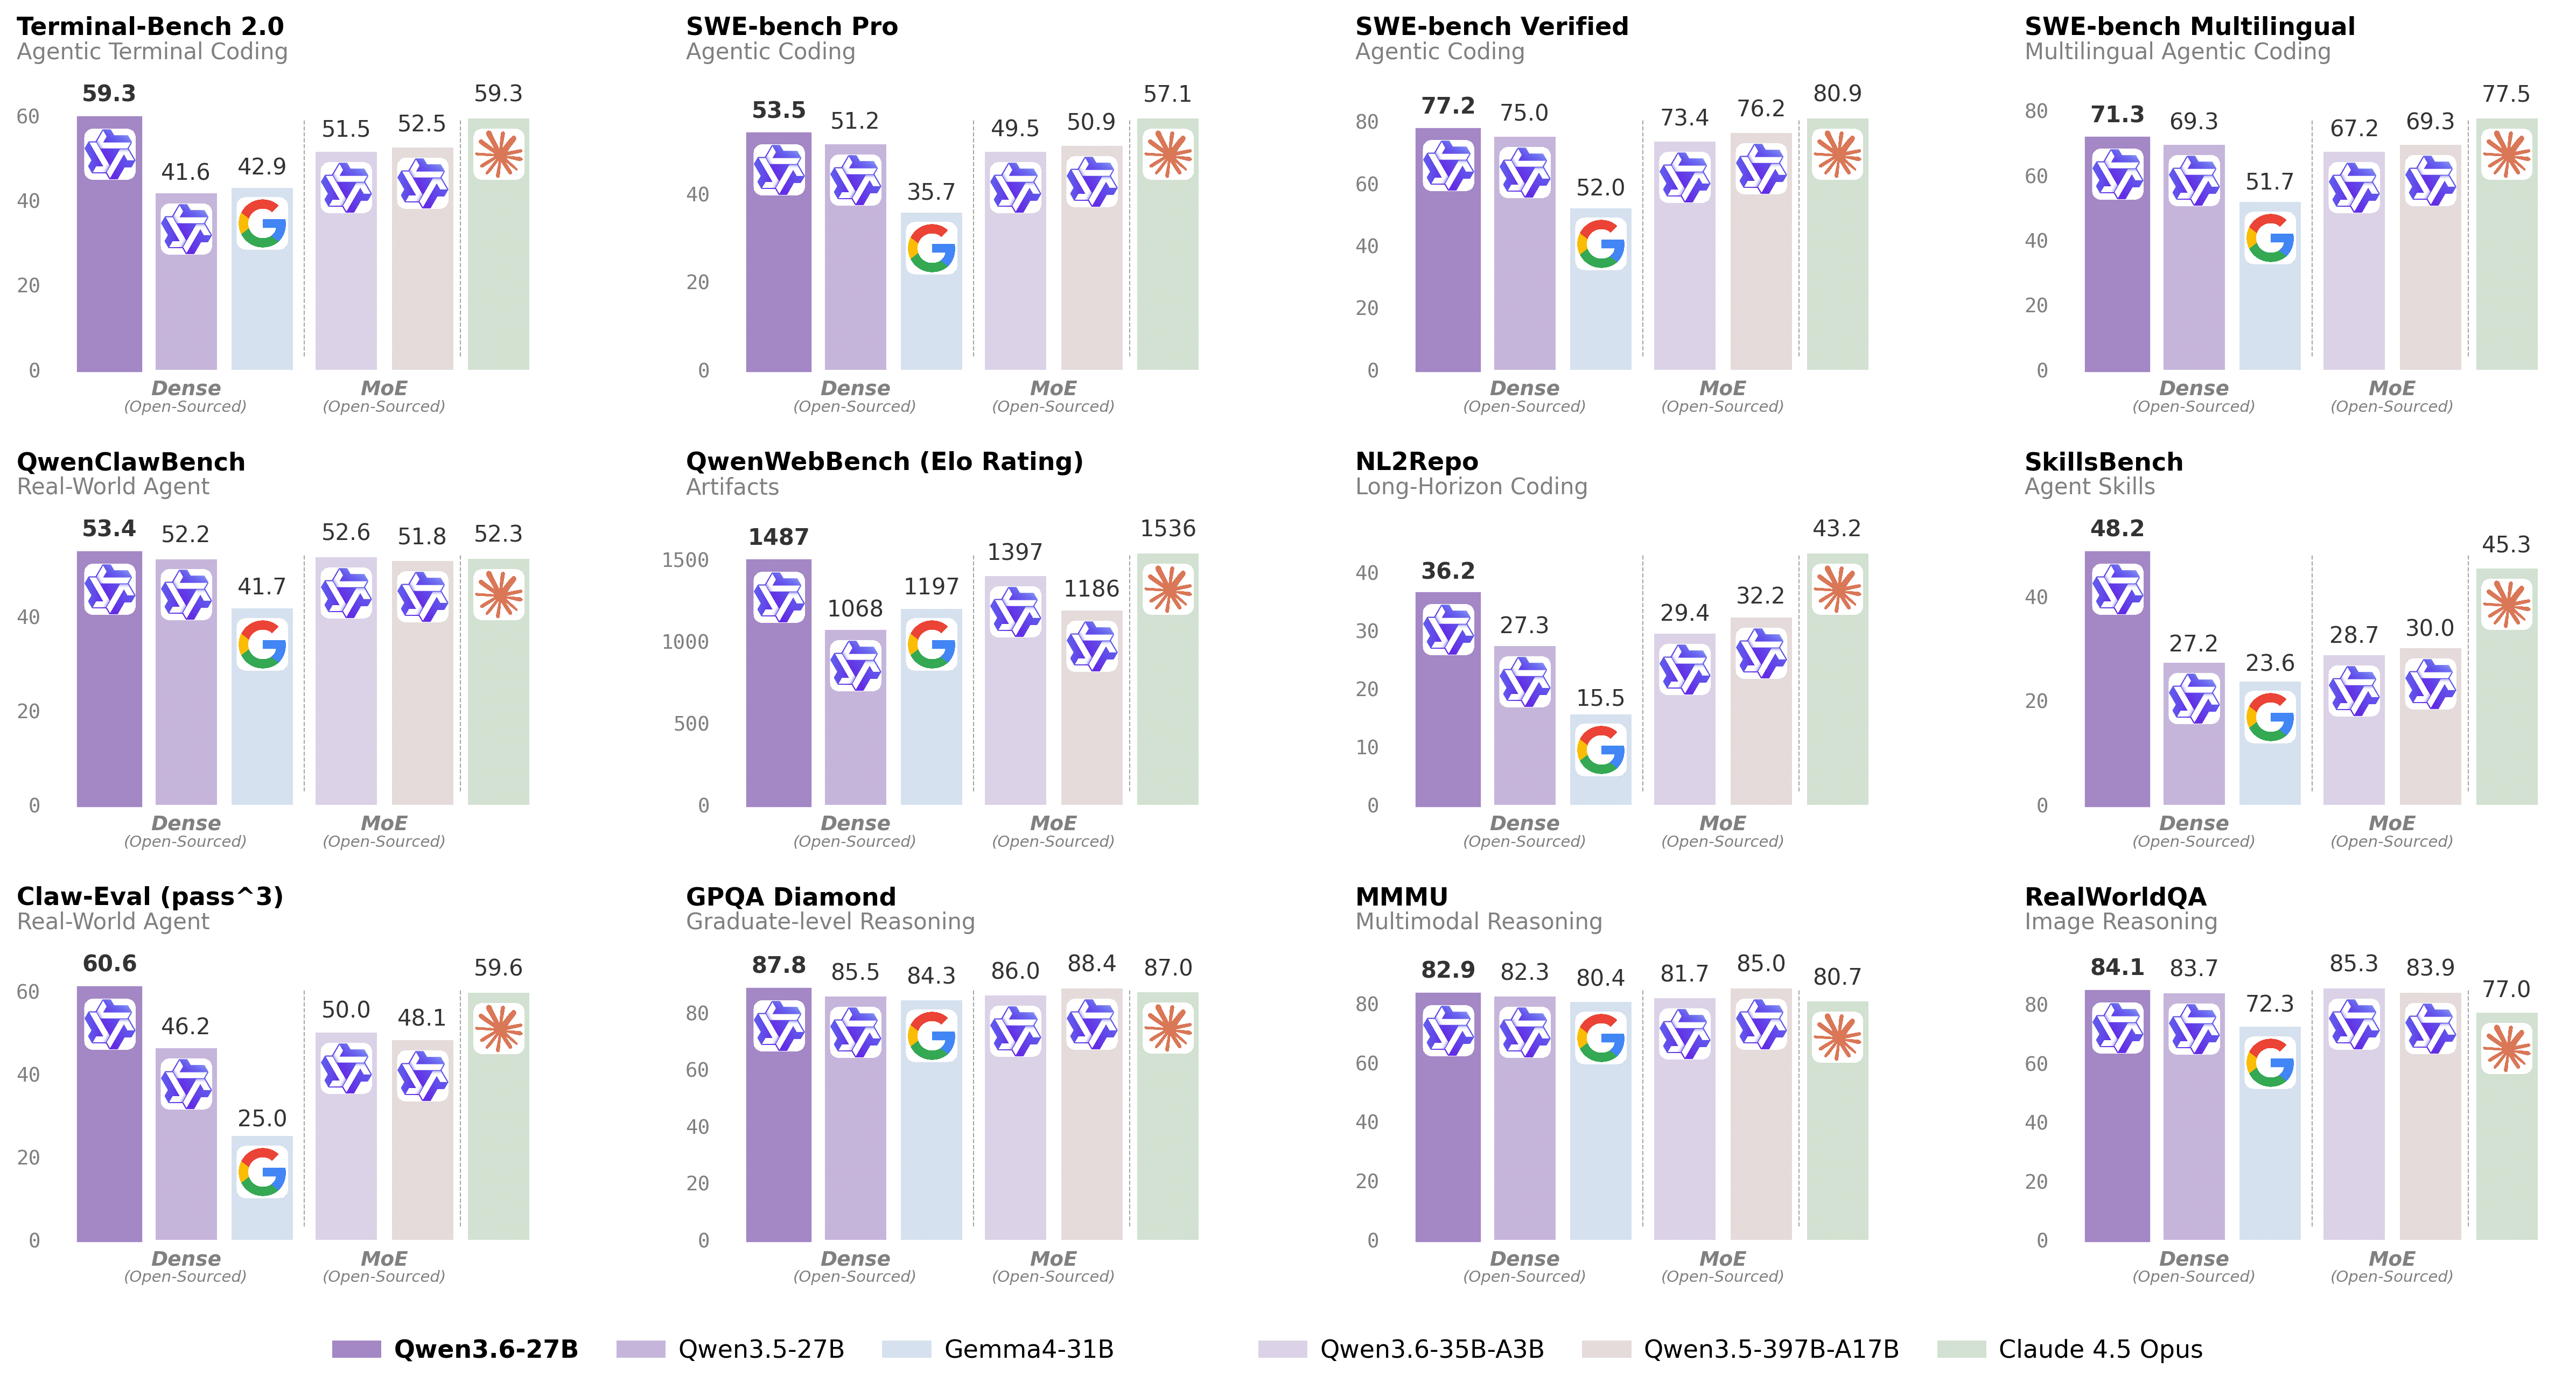
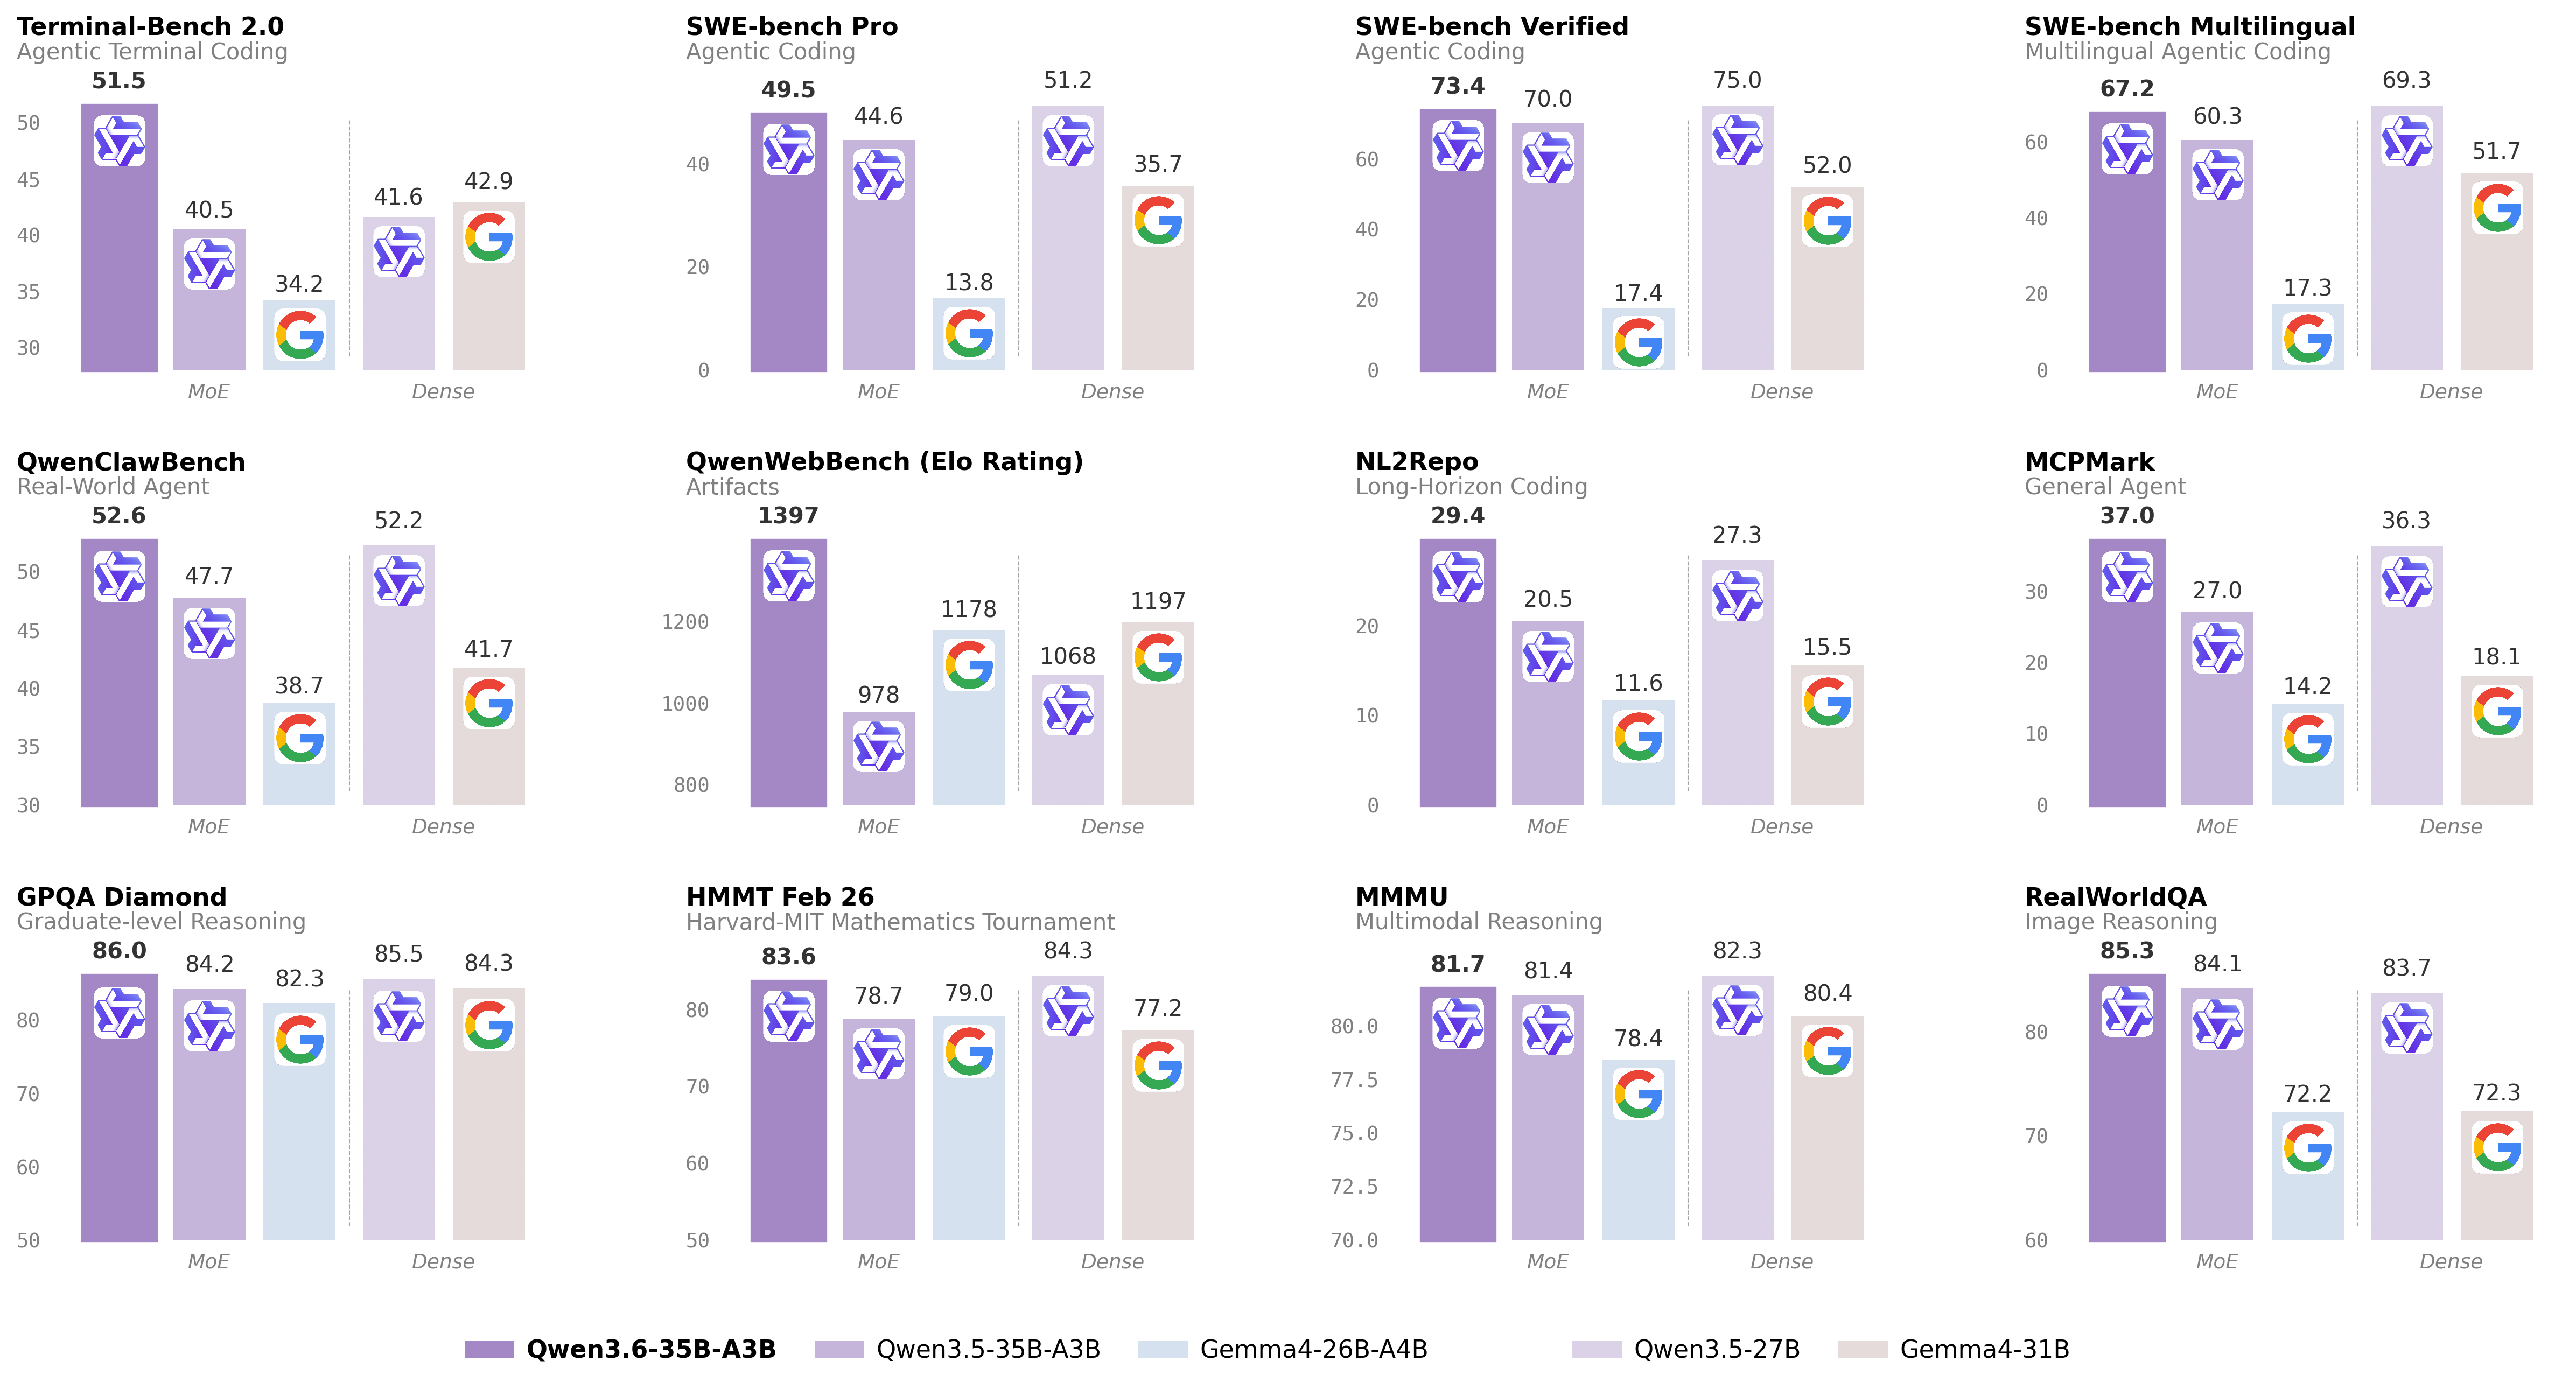


Что это такое?
 Qwen3.8 — новейший открытый релиз большой языковой модели от команды Qwen в Alibaba, часть серии Qwen3.5, куда входят также Qwen3.5 и Qwen3.6; ориентирован на кодинг, профессиональную работу, исследования и долгие агентные задачи.
Это готовое чат-приложение или просто веса моделей, которые я загружаю сам?Этот репозиторий — документация вокруг открытых весов моделей, а не упакованное приложение. Вы скачиваете веса (например, Qwen/Qwen3.8-27B) и запускаете их сами через фреймворк либо используете хостинговые инструменты Alibaba вроде Qwen Studio, Qwen API или Qwen Code.
Этот репозиторий — документация вокруг открытых весов моделей, а не упакованное приложение. Вы скачиваете веса (например, Qwen/Qwen3.8-27B) и запускаете их сами через фреймворк либо используете хостинговые инструменты Alibaba вроде Qwen Studio, Qwen API или Qwen Code.Как начать пользоваться Qwen3.8?Заберите веса из Hugging Face Hub или ModelScope и раздайте их локально с помощью Hugging Face Transformers (transformers serve), vLLM или SGLang, получив API-эндпоинт, совместимый с OpenAI; либо используйте хостинговые Qwen Studio или Qwen API, ничего не запуская самостоятельно.
Заберите веса из Hugging Face Hub или ModelScope и раздайте их локально с помощью Hugging Face Transformers (transformers serve), vLLM или SGLang, получив API-эндпоинт, совместимый с OpenAI; либо используйте хостинговые Qwen Studio или Qwen API, ничего не запуская самостоятельно.Какие инструменты инференса реально умеют запускать Qwen3.8?Модель поддерживают SGLang, vLLM и TokenSpeed для серверного развёртывания, llama.cpp для лёгкого локального инференса и mlx-lm/mlx-vlm на Apple Silicon; дообучение поддерживается через Unsloth, Swift и Llama-Factory.
Модель поддерживают SGLang, vLLM и TokenSpeed для серверного развёртывания, llama.cpp для лёгкого локального инференса и mlx-lm/mlx-vlm на Apple Silicon; дообучение поддерживается через Unsloth, Swift и Llama-Factory.Он работает на Mac с Apple Silicon или нужна GPU от Nvidia?Mac с Apple Silicon поддерживаются через mlx-lm (только текст) и mlx-vlm (зрение + текст); на другом железе используйте квантованные GGUF-сборки с llama.cpp или полноточные веса с vLLM/SGLang, хотя в README минимальные требования к GPU не указаны.
Mac с Apple Silicon поддерживаются через mlx-lm (только текст) и mlx-vlm (зрение + текст); на другом железе используйте квантованные GGUF-сборки с llama.cpp или полноточные веса с vLLM/SGLang, хотя в README минимальные требования к GPU не указаны.Лицензия Apache-2.0 в этом репозитории — она же и для самих весов модели?Нет — лицензия Apache-2.0 покрывает сам репозиторий, а веса моделей идут со своим файлом лицензии, размещённым рядом с весами на Hugging Face Hub или ModelScope; его нужно проверить отдельно.
Нет — лицензия Apache-2.0 покрывает сам репозиторий, а веса моделей идут со своим файлом лицензии, размещённым рядом с весами на Hugging Face Hub или ModelScope; его нужно проверить отдельно.В каких размерах выходит Qwen3.8?Среди выпущенных размеров Qwen3.8-27B и куда более крупная модель Qwen3.8-2.4T-A95B типа mixture-of-experts, обе опубликованы на Hugging Face Hub и ModelScope.
Среди выпущенных размеров Qwen3.8-27B и куда более крупная модель Qwen3.8-2.4T-A95B типа mixture-of-experts, обе опубликованы на Hugging Face Hub и ModelScope.Чем Qwen3.8 отличается от Qwen3.6 и Qwen3.5?Qwen3.8 — первый открытый релиз, достигший уровня Qwen-Max, построен на архитектуре Qwen3.5 с более сильным агентным исполнением; Qwen3.6 сосредоточился на стабильности агентного кодинга и сохранении размышлений; Qwen3.5 ввёл унифицированную vision-language MoE-базу с гибридным вниманием.
Qwen3.8 — первый открытый релиз, достигший уровня Qwen-Max, построен на архитектуре Qwen3.5 с более сильным агентным исполнением; Qwen3.6 сосредоточился на стабильности агентного кодинга и сохранении размышлений; Qwen3.5 ввёл унифицированную vision-language MoE-базу с гибридным вниманием.Можно дообучить Qwen3.8 самому?Да, команда рекомендует дообучать модели с помощью Unsloth, Swift или Llama-Factory методами вроде SFT, DPO или GRPO.
Да, команда рекомендует дообучать модели с помощью Unsloth, Swift или Llama-Factory методами вроде SFT, DPO или GRPO.Qwen3.8 понимает изображения или только текст?Базовая архитектура Qwen3.5 обучалась с early fusion на триллионах мультимодальных токенов, давая понимание изображений вместе с текстом; сборки со зрением доступны через mlx-vlm и GGUF-релизы llama.cpp.
Базовая архитектура Qwen3.5 обучалась с early fusion на триллионах мультимодальных токенов, давая понимание изображений вместе с текстом; сборки со зрением доступны через mlx-vlm и GGUF-релизы llama.cpp.What are similar projects?Qwen3.8-Flash-Next, NeoHorse, Hy-MT2, DeepSeek-V3, halo, Qwen3, unsloth, Hy4-preview
Qwen3.8-Flash-Next, NeoHorse, Hy-MT2, DeepSeek-V3, halo, Qwen3, unsloth, Hy4-previewWhich topics is it in?alibaba, sglang, open-weights, mlx, mixture-of-experts, moe, gguf, pretrained-models, transformers, vllm, fine-tuning, multimodal
alibaba, sglang, open-weights, mlx, mixture-of-experts, moe, gguf, pretrained-models, transformers, vllm, fine-tuning, multimodal