Towards Unified Latent VLA for Whole-body Loco-manipulation Control


✒️ Haoran Jiang*, Jin Chen*, Qingwen Bu, Li Chen, Modi Shi, Yanjie Zhang, Delong Li, Chuanzhe Suo, Chuang Wang, Zhihui Peng†, Hongyang Li†
📧 Primary Contact: Haoran Jiang ([email protected]).
🔥 Highlights
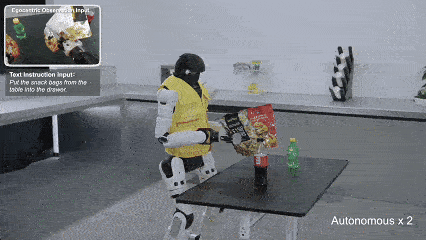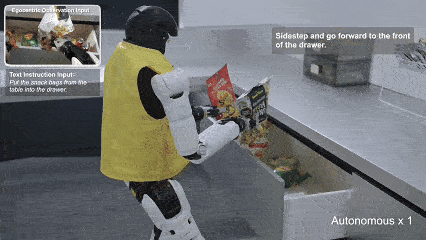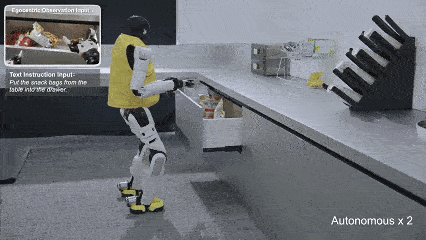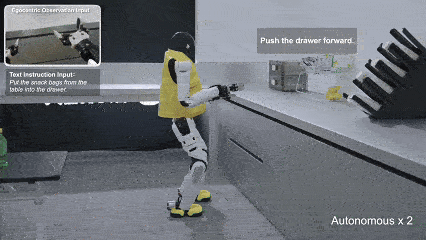
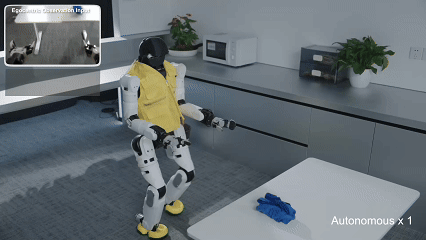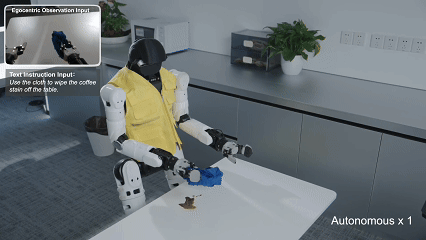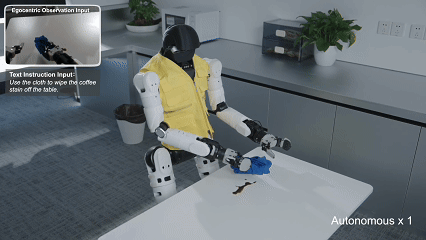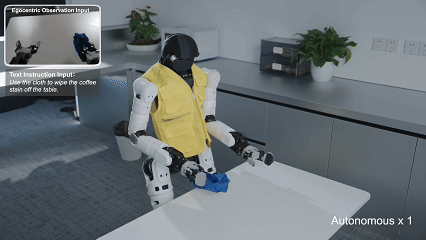
- A Vision-Language-Action framework for closed-loop humanoid loco-manipulation control in large space.
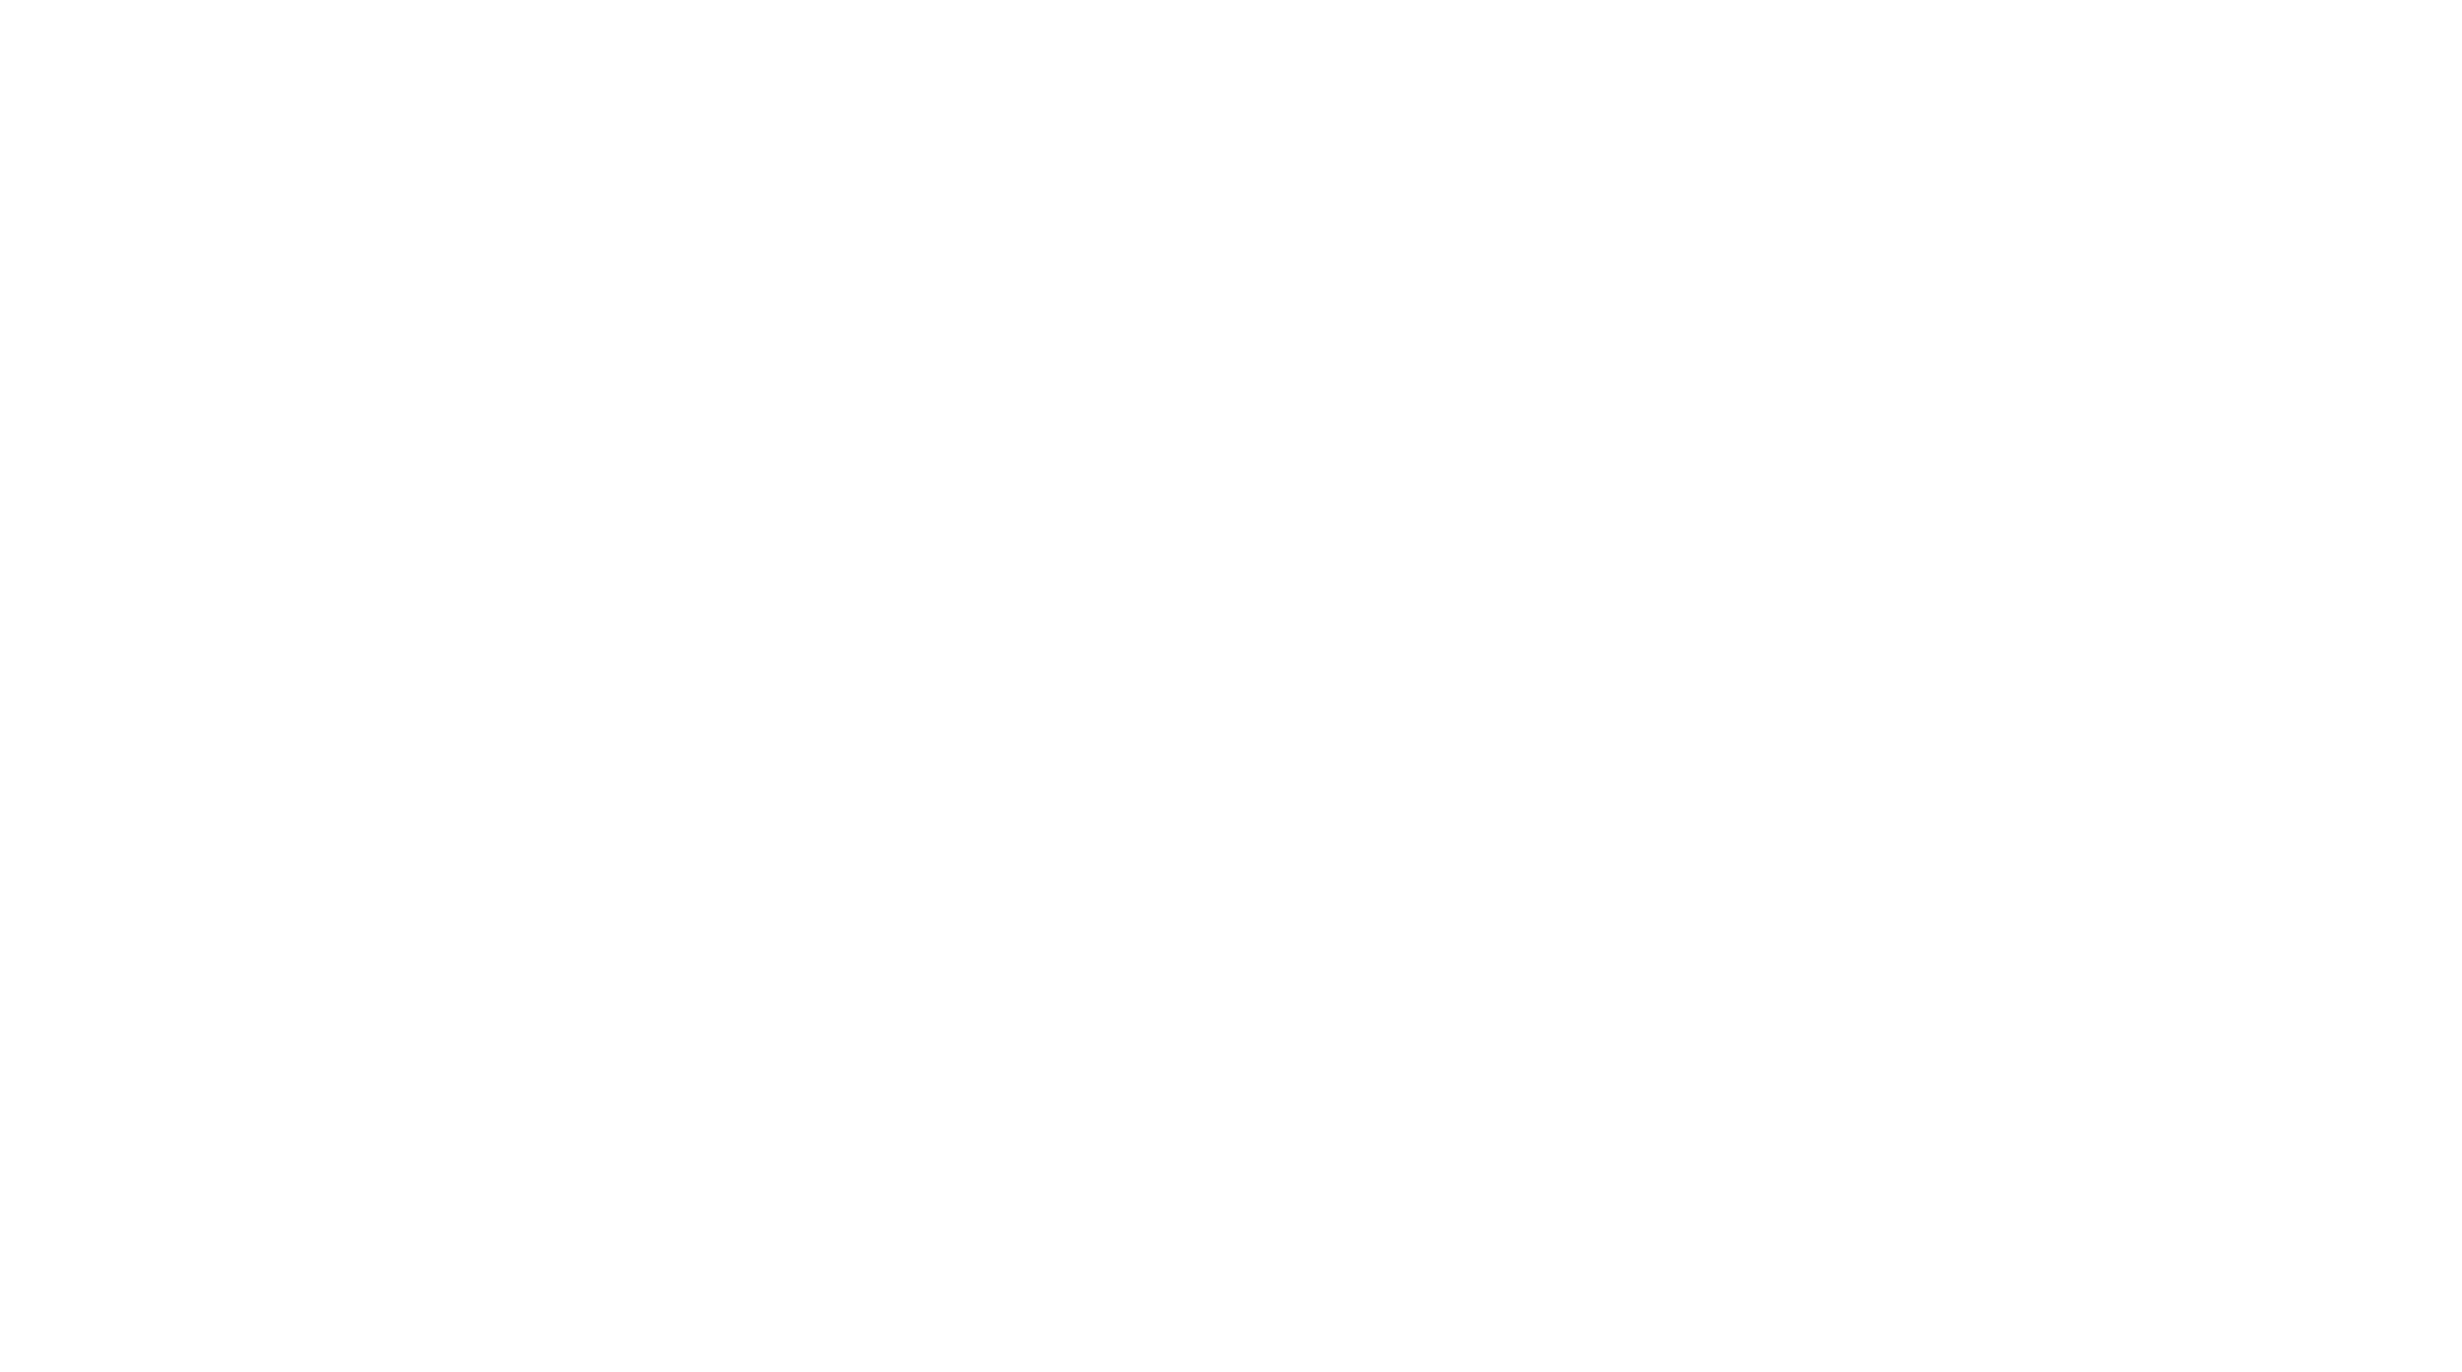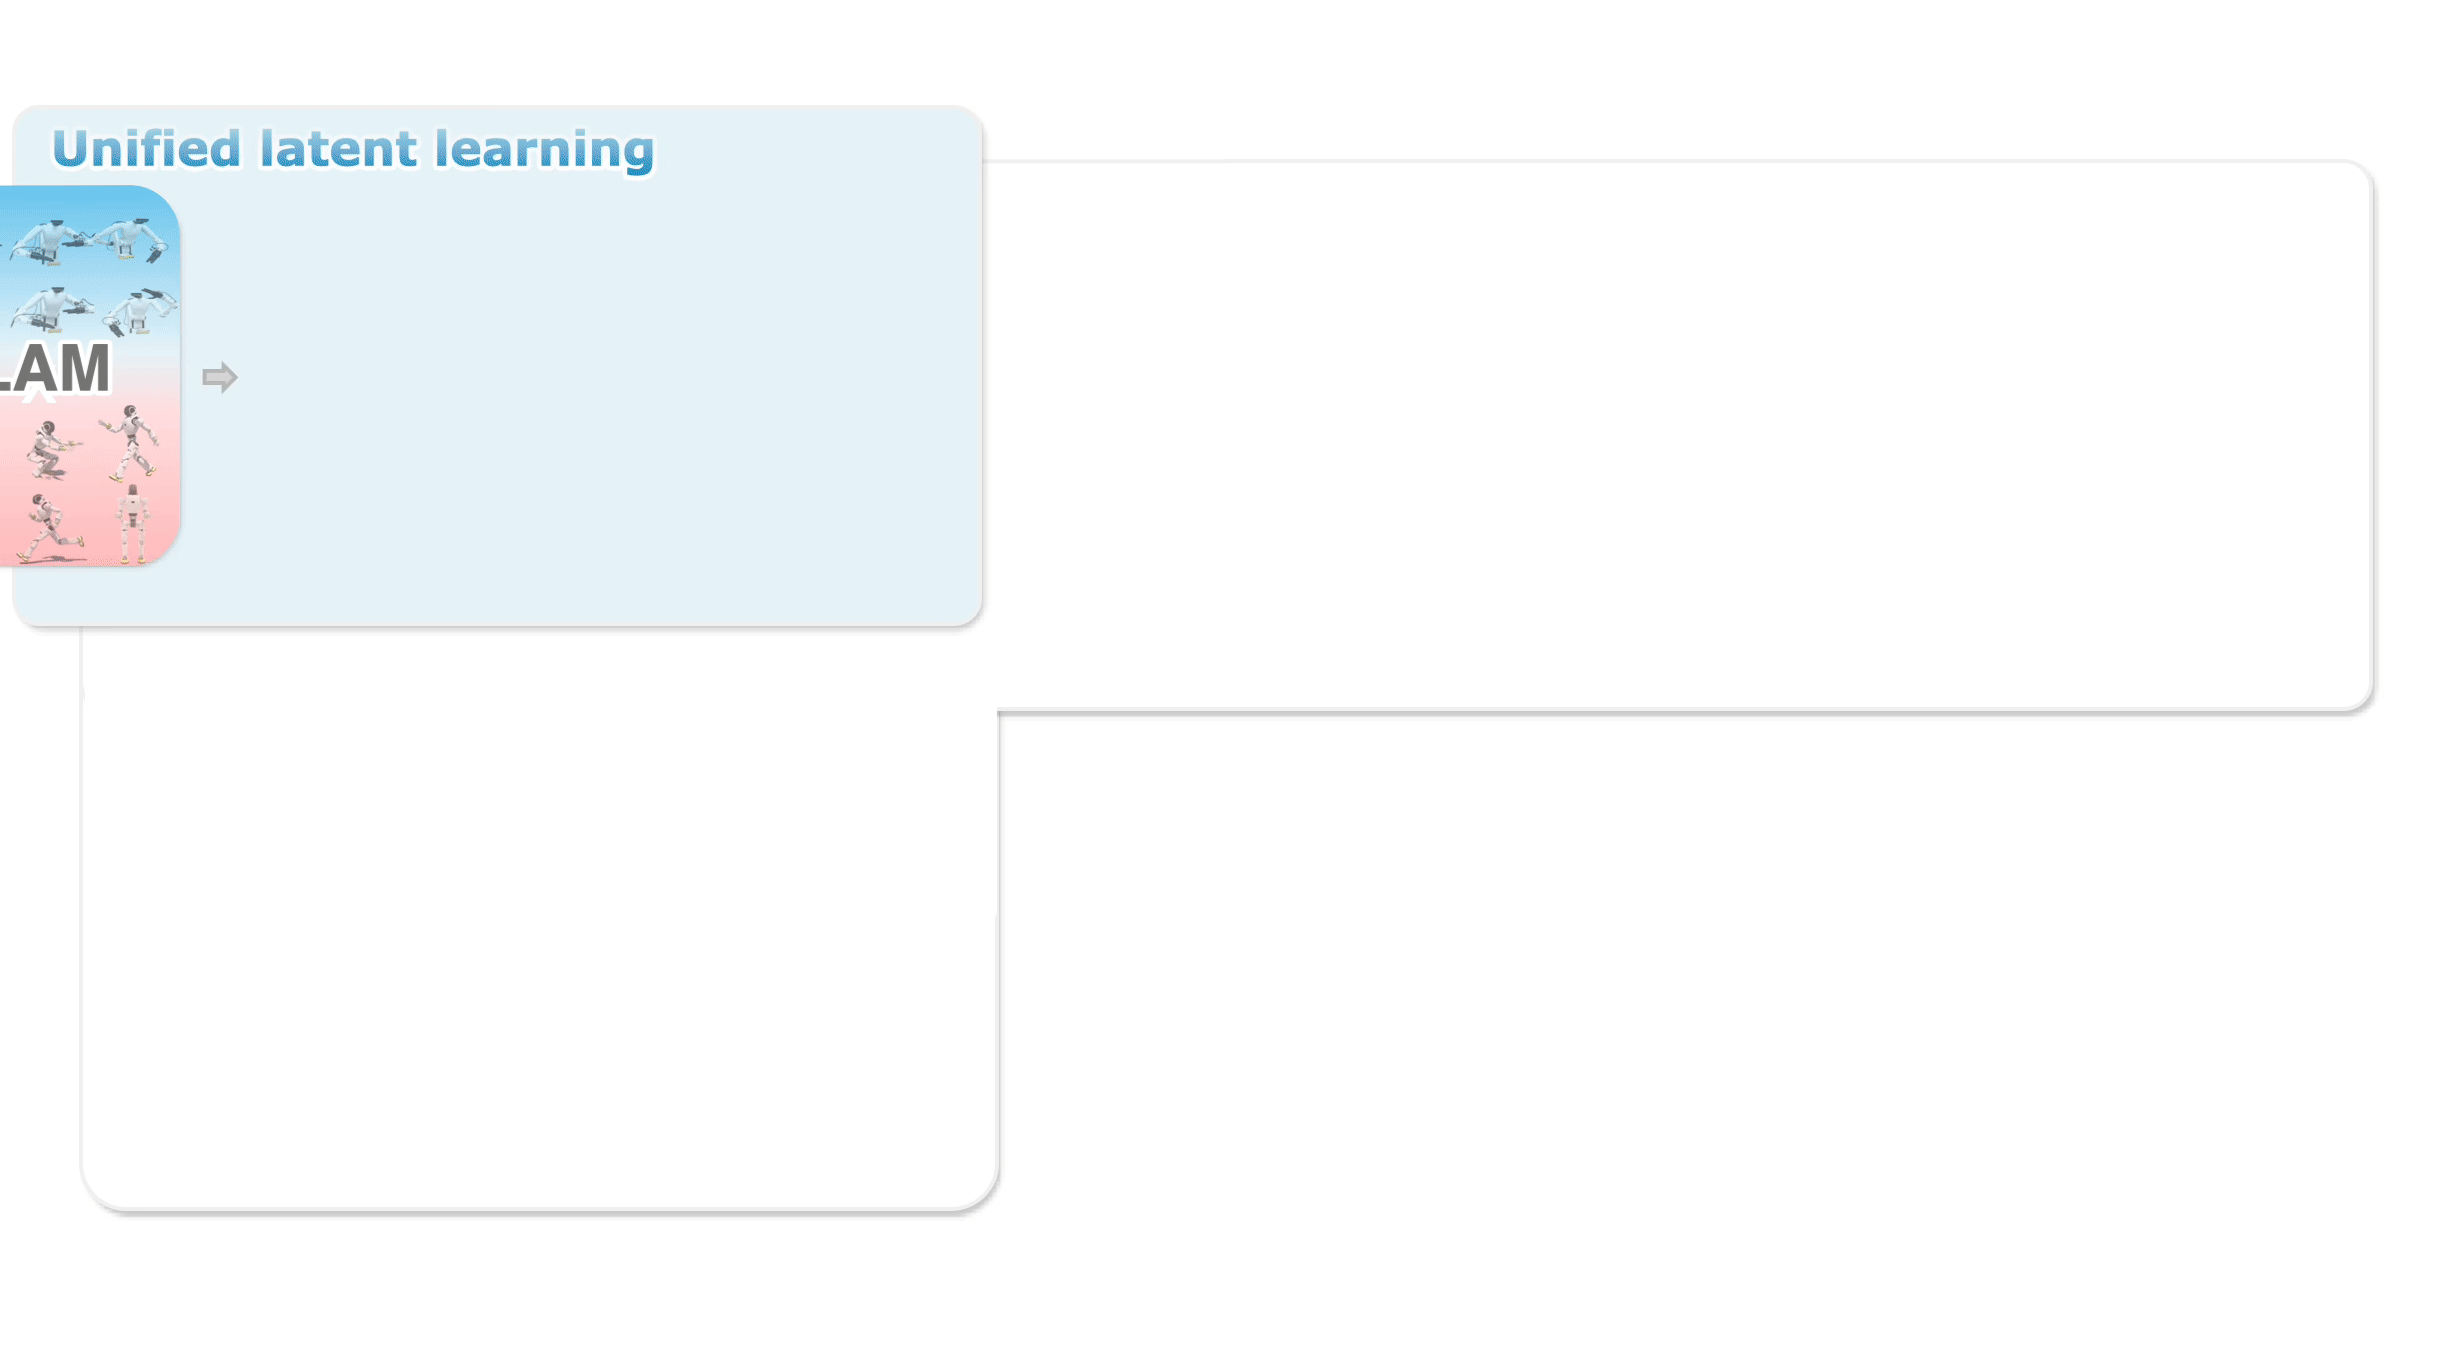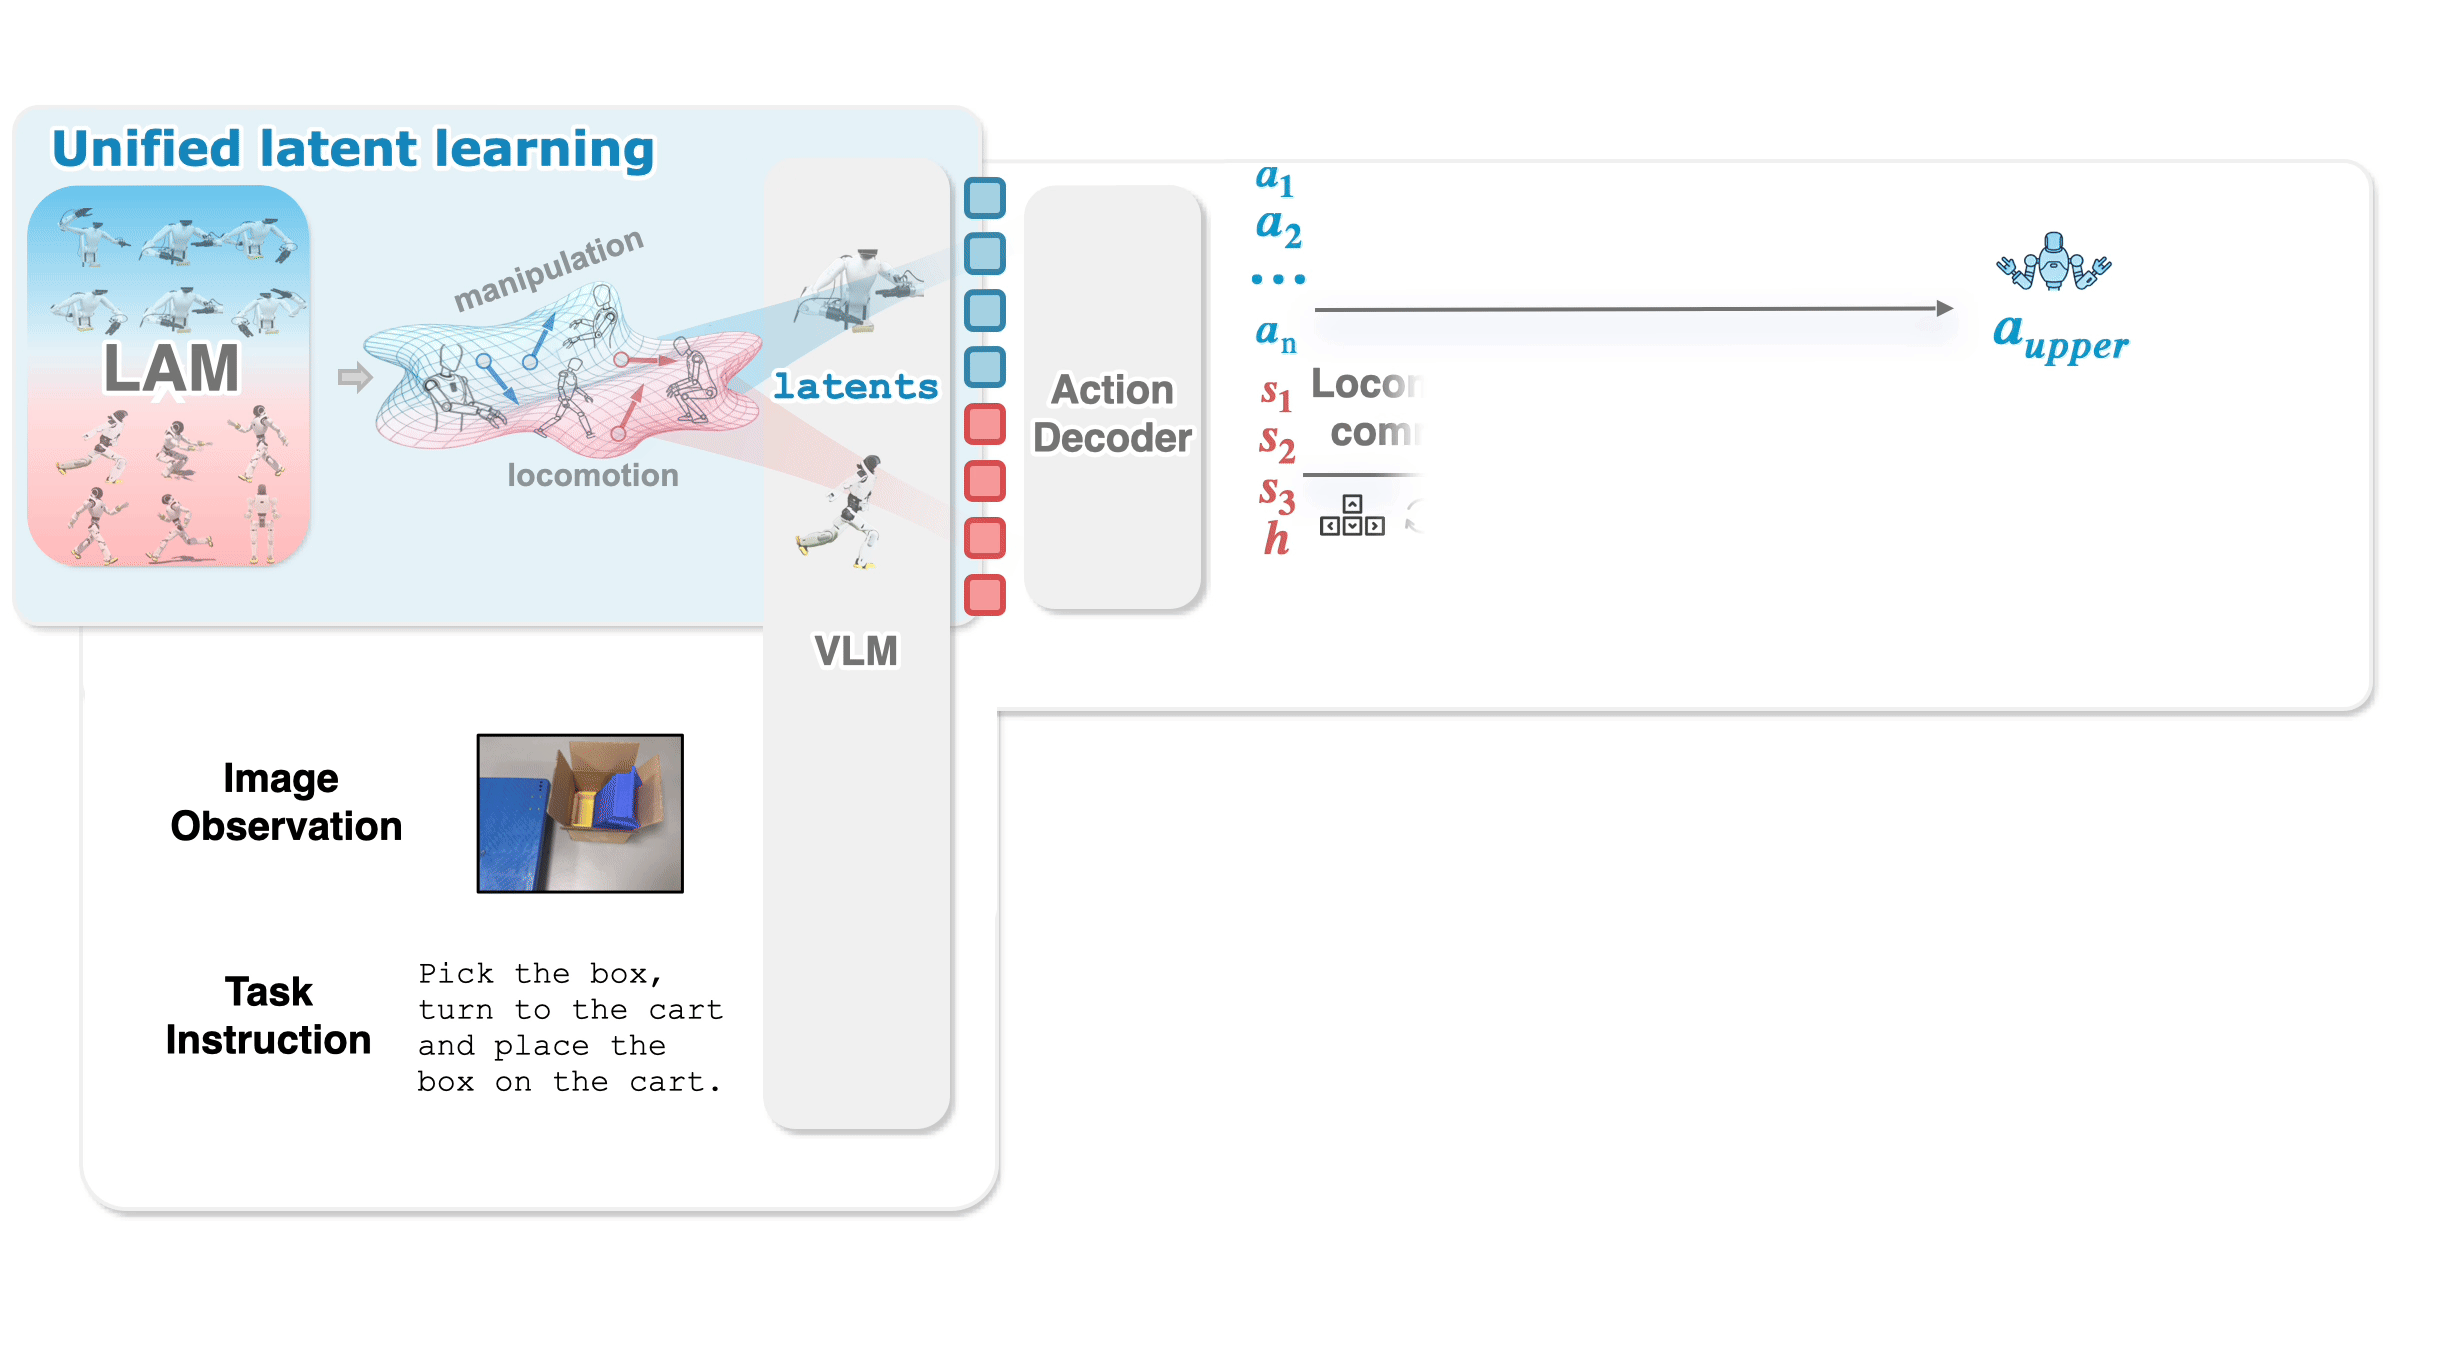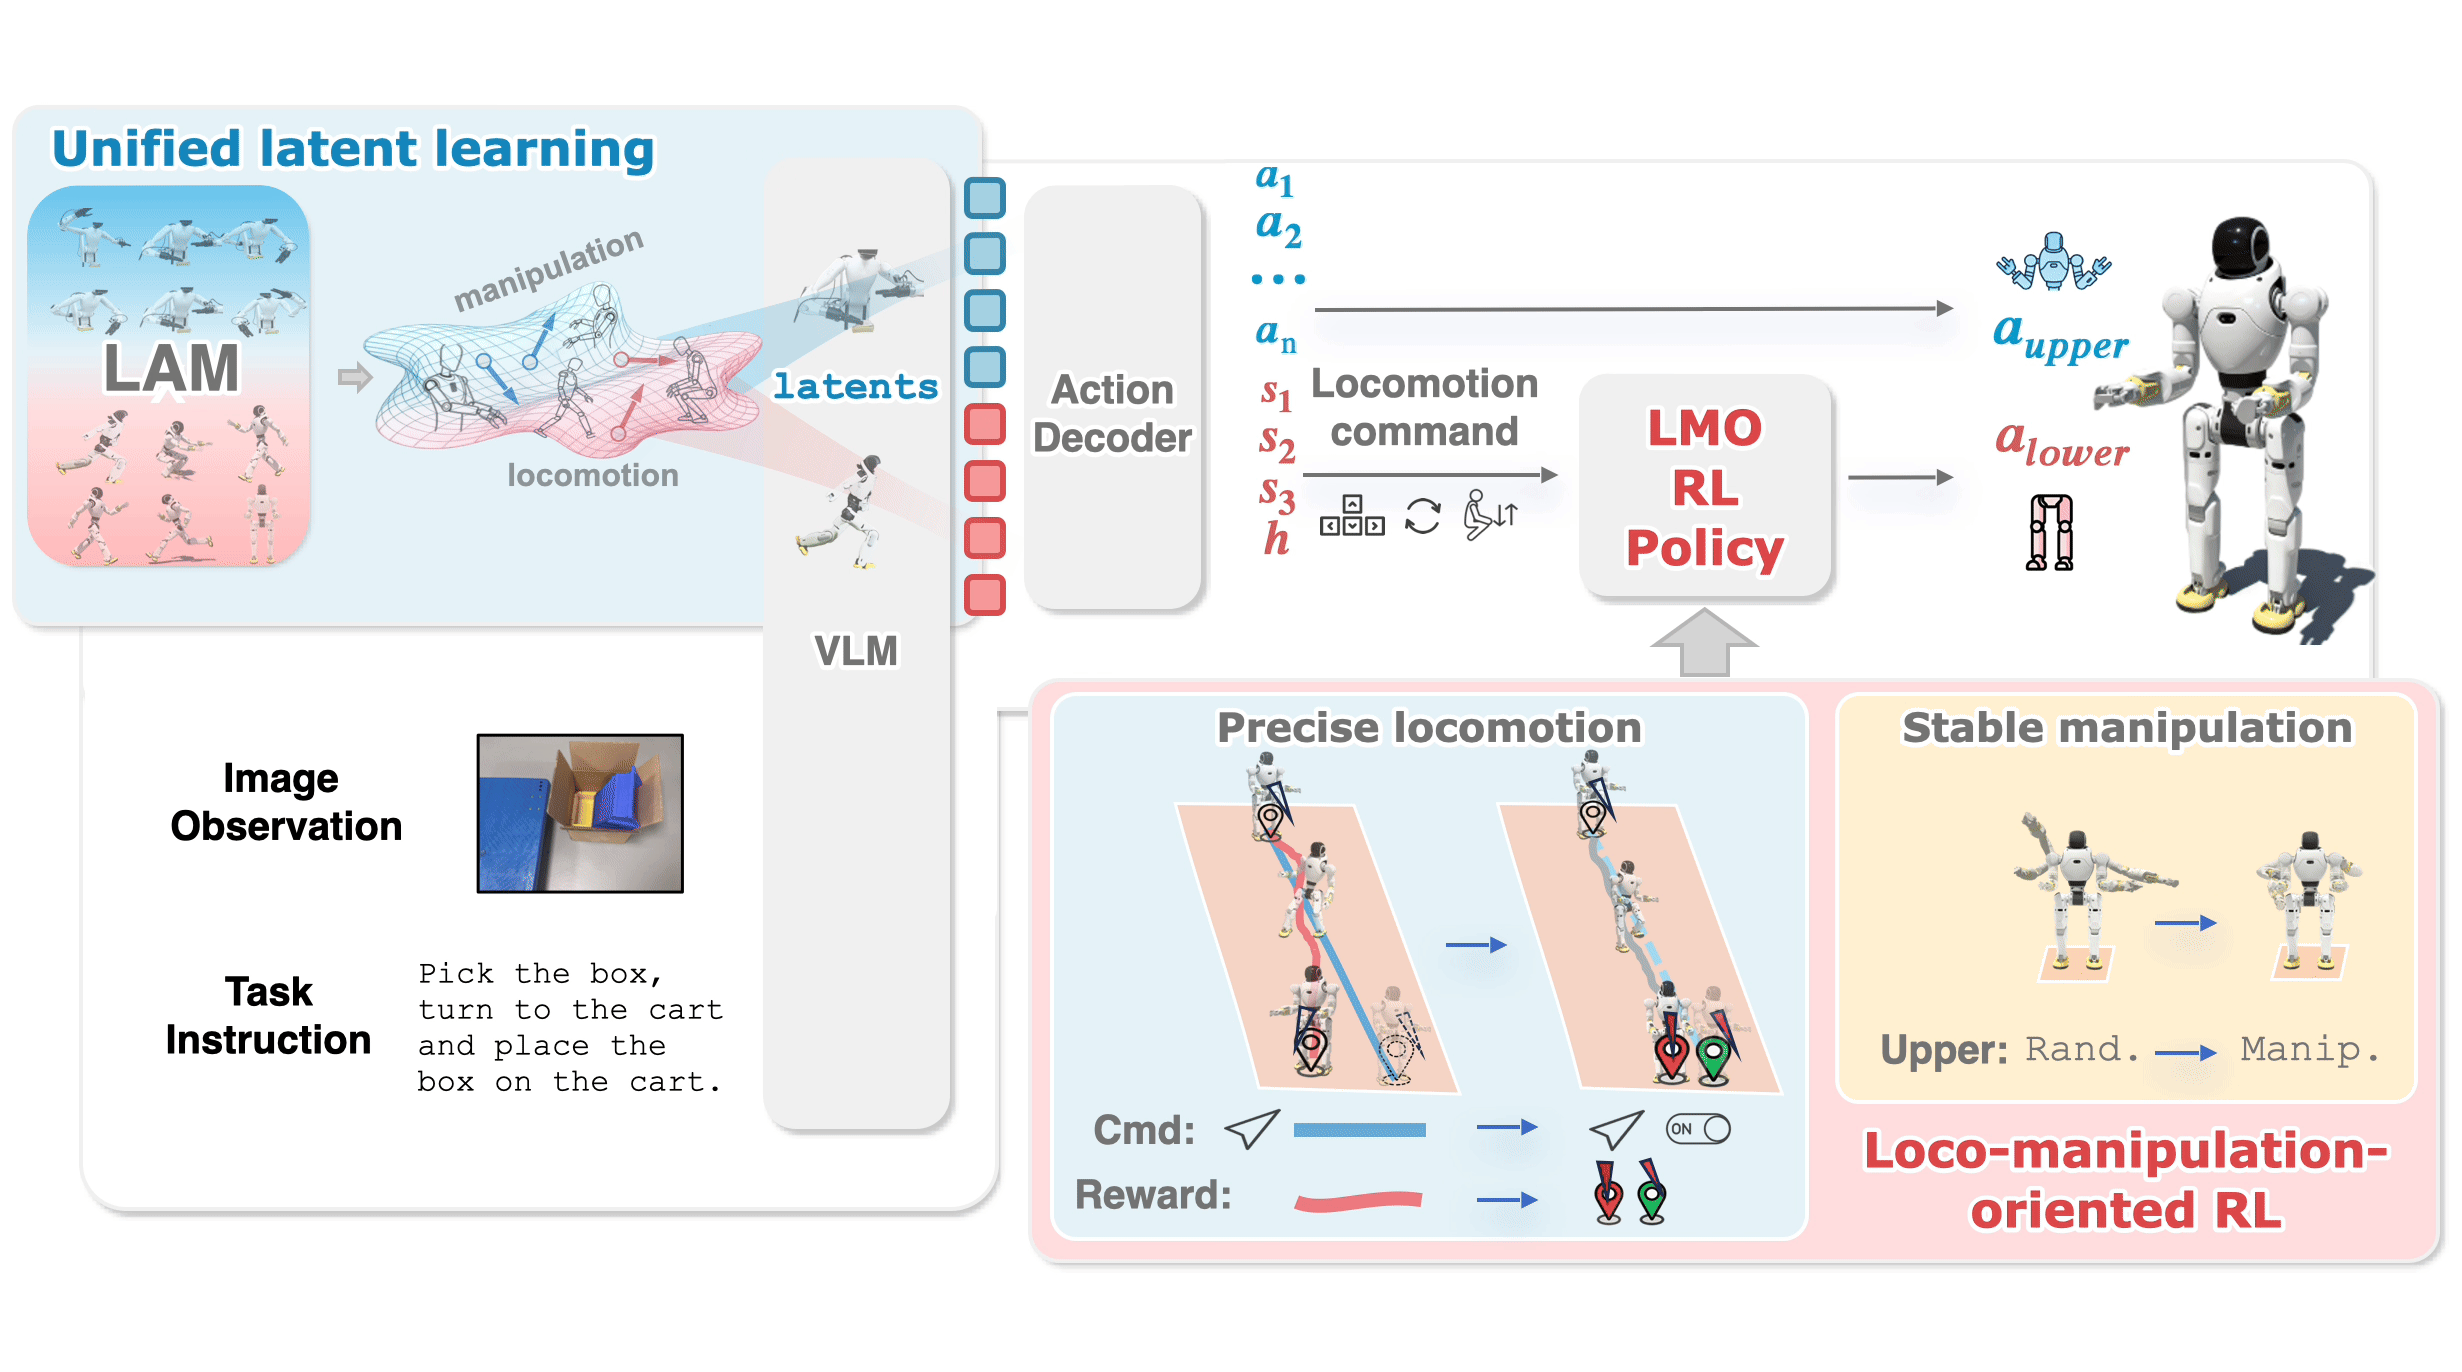
- A novel approach for learning unified latent actions from manipulation and manipulation-aware locomotion videos without action annotations.
- A locomotion-oriented reinforcement learning policy that enables precise and stable whole-body coordination under disturbances.
📋 Overview
WholeBodyVLA is a unified Vision-Language-Action framework for large-space humanoid loco-manipulation. It learns unified latent actions from action-free egocentric videos through a Latent Action Model (LAM), and employs a loco-manipulation-oriented (LMO) RL policy for precise and stable whole-body coordination. The system encodes egocentric images and language instructions into latent action tokens, which are decoded into dual-arm joint actions and locomotion commands, enabling end-to-end control for complex loco-manipulation tasks.
See more on project website.
📝 Note: We currently have no concrete timeline for open-sourcing the codebase. This repository now serves as a collection of resources and references for the whole-body humanoid VLA research community. We welcome discussion and collaboration!
Let's go for VLA on humanoids!
Awesome Vision–Language–Action for Humanoid Robots
A curated list of research on Vision–Language–Action (VLA) models and related for humanoid robots, with a focus on loco-manipulation task.
Continuously updating...
Perception & Planning for Humanoids
Vision-Based Perception for Planning
Manipulation
- [arXiv 2026.02, Demo] EgoHumanoid: Unlocking In-the-Wild Loco-Manipulation with Robot-Free Egocentric Demonstration
- [arXiv 2026.02, Demo] Humanoid Manipulation Interface: Humanoid Whole-Body Manipulation from Robot-Free Demonstrations [umi data]
- [arXiv 2026.02] HiWET: Hierarchical World-Frame End-Effector Tracking for Long-Horizon Humanoid Loco-Manipulation
- [arXiv 2026.01, Demo, Code] Coordinated Humanoid Manipulation with Choice Policies [hand-eye coordination]
- [ICLR 2026, arXiv 2025.12, Demo] WholeBodyVLA: Towards Unified Latent VLA for Whole-body Loco-manipulation Control [unified latent learning]
- [arXiv 2025.12, Demo] Opening the Sim-to-Real Door for Humanoid Pixel-to-Action Policy Transfer [visual RL, sim-to-real]
- [arXiv 2025.11, Demo] VIRAL: Visual Sim-to-Real at Scale for Humanoid Loco-Manipulation [visual RL, sim-to-real]
- [arXiv 2025.11, Demo] HMC: Learning Heterogeneous Meta-Control for Contact-Rich Loco-Manipulation
- [arXiv 2025.11, Demo, Code] PhysHSI: Towards a Real-World Generalizable and Natural Humanoid-Scene Interaction System [LiDAR+AprilTag+SLAM]
- [arXiv 2025.10, Demo] DemoHLM: From One Demonstration to Generalizable Humanoid Loco-Manipulation [FoundationPose++]
- [arXiv 2025.10, Demo] HumanoidExo: Scalable Whole-Body Humanoid Manipulation via Wearable Exoskeleton
- [arXiv 2025.10, Data] Humanoid Everyday: A Comprehensive Robotic Dataset for Open-World Humanoid Manipulation [humanoid manipulation dataset]
- [arXiv 2025.09, Demo, Code] VisualMimic: Visual Humanoid Loco-Manipulation via Motion Tracking and Generation
- [arXiv 2025.09, Demo] StageACT: Stage-Conditioned Imitation for Robust Humanoid Door Opening
- [arXiv 2025.09, Demo, Code] TrajBooster: Boosting Humanoid Whole-Body Manipulation via Trajectory-Centric Learning
- [CoRL 2025, arXiv 2025.06, Demo] SLAC: Simulation-Pretrained Latent Action Space for Whole-Body Real-World RL [real-world RL]
- [arXiv 2025.06, Demo] SkillBlender: Towards Versatile Humanoid Whole-Body Loco-Manipulation via Skill Blending
- [RA-L 2025, arXiv 2025.05, Demo, Code] Unleashing Humanoid Reaching Potential via Real-world-Ready Skill Space
- [Humanoids 2025, arXiv 2025.05, Demo, Code] H2-COMPACT: Human-Humanoid Co-Manipulation via Adaptive Contact Trajectory Policies
- [arXiv 2025.06, Demo] Humanoid Agent via Embodied Chain-of-Action Reasoning with Multimodal Foundation Models for Zero-Shot Loco-Manipulation
- [CoRL 2025, arXiv 2025.03, Demo, Code] BEHAVIOR Robot Suite: Streamlining Real-World Whole-Body Manipulation for Everyday Household Activities
- [arXiv 2025.03, Demo] Being-0: A Humanoid Robotic Agent with Vision-Language Models and Modular Skills [modular skill]
- [Survey, arXiv 2025.01] Humanoid Locomotion and Manipulation: Current Progress and Challenges in Control, Planning, and Learning
- [IROS 2025, arXiv 2024.10, Demo, Code] Generalizable Humanoid Manipulation with 3D Diffusion Policies
- [arXiv 2024.09, Demo] Opt2Skill: Imitating Dynamically-feasible Whole-Body Trajectories for Versatile Humanoid Loco-Manipulation
- [arXiv 2024.06, Demo] HYPERmotion: Learning Hybrid Behavior Planning for Autonomous Loco-manipulation
Other Tasks
- [arXiv 2026.12] Learning Soccer Skills for Humanoid Robots: A Progressive Perception-Action Framework
- [arXiv 2025.12] Learning Agile Striker Skills for Humanoid Soccer Robots from Noisy Sensory Input [YOLOv8]
- [arXiv 2025.12, Demo] Learning Vision-Driven Reactive Soccer Skills for Humanoid Robots [YOLOv8]
- [arXiv 2025.11, Demo] GentleHumanoid: Learning Upper-body Compliance for Contact-rich Human and Object Interaction
- [arXiv 2025.10, Demo, Code] Ego-Vision World Model for Humanoid Contact Planning [depth, world model]
- [CoRL 2025, arXiv 2025.08, Demo, Code] Hand-Eye Autonomous Delivery: Learning Humanoid Navigation, Locomotion and Reaching
- [arXiv 2025.06, Demo] LeVERB: Humanoid Whole-Body Control with Latent Vision-Language Instruction [LeVERB-Bench]
- [arXiv 2025.02] Humanoid-VLA: Towards Universal Humanoid Control with Visual Integration
MoCap-Based Planning
- [arXiv 2026.02, Demo] HumanX: Toward Agile and Generalizable Humanoid Interaction Skills from Human Videos
- [arXiv 2025.11] Humanoid Whole-Body Badminton via Multi-Stage Reinforcement Learning
- [arXiv 2025.10, Demo, Code] Humanoid Goalkeeper: Learning from Position Conditioned Task-Motion Constraints
- [arXiv 2025.10, Demo] ResMimic: From General Motion Tracking to Humanoid Whole-body Loco-Manipulation via Residual Learning
- [arXiv 2025.09, Demo, Code] HDMI: Learning Interactive Humanoid Whole-Body Control from Human Videos
- [arXiv 2025.09, Demo, Code] OmniRetarget: Interaction-Preserving Data Generation for Humanoid Whole-Body Loco-Manipulation and Scene Interaction
- [arXiv 2025.09, Demo] Towards Versatile Humanoid Table Tennis: Unified Reinforcement Learning with Prediction Augmentation
- [arXiv 2025.08, Demo] HITTER: A HumanoId Table TEnnis Robot via Hierarchical Planning and Learning
- [arXiv 2025.05, Demo, Code] FALCON: Learning Force-Adaptive Humanoid Loco-Manipulation
- [arXiv 2024.10] Whole-Body Dynamic Throwing with Legged Manipulators
- [CoRL 2024, arXiv 2024.06, Demo, Code] WoCoCo: Learning Whole-Body Humanoid Control with Sequential Contacts
Generative Motion and Trajectory Planning
- [arXiv, Code] HY-Motion 1.0: Scaling Flow Matching Models for 3D Motion Generation [motion generation foundation model]
- [arXiv, Code] FRoM-W1: Towards General Humanoid Whole-Body Control with Language Instructions
- [Demo, Code] TextOp: Real-time Interactive Text-Driven Humanoid Robot Motion Generation and Control
- [arXiv 2025.11] Unveiling the Impact of Data and Model Scaling on High-Level Control for Humanoid Robots
- [arXiv 2025.11, Demo] SONIC: Supersizing Motion Tracking for Natural Humanoid Whole-Body Control [GENMO]
- [arXiv 2025.11, Demo] From Language To Locomotion: Retargeting-free Humanoid Control via Motion Latent Guidance
- [arXiv 2025.09, Demo, Code] DreamControl: Human-Inspired Whole-Body Humanoid Control for Scene Interaction via Guided Diffusion
- [arXiv 2025.04] Physically Consistent Humanoid Loco-Manipulation using Latent Diffusion Models
- [arXiv 2025.04, Demo] LangWBC: Language-directed Humanoid Whole-Body Control via End-to-end Learning
- [CoRL 2024, arXiv 2024.10, Demo] Harmon: Whole-Body Motion Generation of Humanoid Robots from Language Descriptions
- [arXiv 2024.10] EMOTION: Expressive Motion Sequence Generation for Humanoid Robots with In-Context Learning
- [ACM SIGGRAPH Asia 2024, PDF, Demo] Robot Motion Diffusion Model: Motion Generation for Robotic Characters
Whole-Body Controller for Loco-Manipulation
Behavior Foundation Models / Universal Whole-Body Tracking
[arXiv 2026.02] MOSAIC: Bridging the Sim-to-Real Gap in Generalist Humanoid Motion Tracking and Teleoperation with Rapid Residual Adaptation
[arXiv 2026.02, Demo, Code] TextOp: Real-time Interactive Text-Driven Humanoid Robot Motion Generation and Control
[arXiv 2026.02, Demo] Humanoid Manipulation Interface: Humanoid Whole-Body Manipulation from Robot-Free Demonstrations
[arXiv 2026.01, Demo] Robust and Generalized Humanoid Motion Tracking
[arXiv 2025.12, Demo, Code] UniAct: Unified Motion Generation and Action Streaming for Humanoid Robots
[arXiv 2026.01, Demo, Code] FRoM-W1: Towards General Humanoid Whole-Body Control with Language Instructions
[arXiv 2025.12, Demo] CHIP: Adaptive Compliance for Humanoid Control through Hindsight Perturbation
[ICRA 2026, arXiv 2025.11, Demo] Agility Meets Stability: Versatile Humanoid Control with Heterogeneous Data [synthetic motion data, scalable learning]
[arXiv 2025.11, Demo] SONIC: Supersizing Motion Tracking for Natural Humanoid Whole-Body Control [scalable learning]
[ICLR 2026, arXiv 2025.11, Demo, GitHub] BFM-Zero: A Promptable Behavioral Foundation Model for Humanoid Control Using Unsupervised Reinforcement Learning [unsupervised RL]
[arXiv 2025.11, Demo, Code] TWIST2: Scalable, Portable, and Holistic Humanoid Data Collection System [whole-body data collection]
[arXiv 2025.10, Code] Retargeting Matters: General Motion Retargeting for Humanoid [motion data retargeting]
[blog, Code] HoloMotion: A Foundation Model for Whole-Body Humanoid Control
[arXiv 2025.09, Demo, Code] OmniRetarget: Interaction-Preserving Data Generation for Humanoid Whole-Body Loco-Manipulation and Scene Interaction [Humanoid-Scene Interaction]
[arXiv 2025.09, Demo, Code] KungfuBot2: Learning Versatile Motion Skills for Humanoid Whole-Body Control
[arXiv 2025.09, Demo, Code] Track Any Motions under Any Disturbances
[arXiv 2025.09, Demo] Behavior Foundation Model for Humanoid Robots
[arXiv 2025.08, Demo, Code] BeyondMimic: From Motion Tracking to Versatile Humanoid Control via Guided Diffusion
[arXiv 2025.07, Demo] UniTracker: Learning Universal Whole-Body Motion Tracker for Humanoid Robots
[NeurIPS 2025, arXiv 2025.06, Demo] From Experts to a Generalist: Toward General Whole-Body Control for Humanoid Robots
[arXiv 2025.06, Demo, Code] GMT: General Motion Tracking for Humanoid Whole-Body Control
[CoRL 2025, arXiv 2025.06, Demo, Code] CLONE: Closed-Loop Whole-Body Humanoid Teleoperation for Long-Horizon Tasks [Sparse Input, Global Tracking]
[CoRL 2025, arXiv 2025.05, Demo, Code] TWIST: Teleoperated Whole-Body Imitation System
[arXiv 2024.12, Demo] ExBody2: Advanced Expressive Humanoid Whole-Body Control
[ICRA 2025, arXiv 2024.10, Demo, Code] HOVER: Versatile Neural Whole-Body Controller for Humanoid Robots [Versatile Control Input]
[CoRL 2024, arXiv 2024.06, Demo, Code] HumanPlus: Humanoid Shadowing and Imitation from Humans
[IROS 2024, arXiv 2024.06, Demo, Code] OmniH2O: Universal and Dexterous Human-to-Humanoid Whole-Body Teleoperation and Learning
[IROS 2024, arXiv 2024.03, Demo, Code] Learning Human-to-Humanoid Real-Time Whole-Body Teleoperation
[RSS 2024, arXiv 2024.02, Demo, Code] Expressive Whole-Body Control for Humanoid Robots
Upper-Body Centric
- [arXiv 2026.02] HiWET: Hierarchical World-Frame End-Effector Tracking for Long-Horizon Humanoid Loco-Manipulation
- [arXiv 2026.02, Demo] Scalable and General Whole-Body Control for Cross-Humanoid Locomotion
- [arXiv 2026.02, Demo] RPL: Learning Robust Humanoid Perceptive Locomotion on Challenging Terrains
- [arXiv 2026.01] PILOT: A Perceptive Integrated Low-level Controller for Loco-manipulation over Unstructured Scenes
- [arXiv 2025.12, Demo] WholeBodyVLA: Towards Unified Latent VLA for Whole-body Loco-manipulation Control [unified latent learning]
- [arXiv 2025.12, Demo] Opening the Sim-to-Real Door for Humanoid Pixel-to-Action Policy Transfer [visual RL, sim-to-real]
- [arXiv 2025.11, Demo] VIRAL: Visual Sim-to-Real at Scale for Humanoid Loco-Manipulation [visual RL, sim-to-real]
- [arXiv 2025.11, Demo] HMC: Learning Heterogeneous Meta-Control for Contact-Rich Loco-Manipulation
- [arXiv 2025.10, Demo] COLA: Learning Human-Humanoid Coordination for Collaborative Object Carrying
- [arXiv 2025.10] Thor: Towards Human-Level Whole-Body Reactions for Intense Contact-Rich Environments
- [arXiv 2025.07, Demo] ULC: A Unified and Fine-Grained Controller for Humanoid Loco-Manipulation
- [arXiv 2025.05, Demo, Code] Hold My Beer: Learning Gentle Humanoid Locomotion and End-Effector Stabilization Control
- [RSS 2025, arXiv 2025.05, Demo] AMO: Adaptive Motion Optimization for Hyper-Dexterous Humanoid Whole-Body Control
- [arXiv 2025.05, Demo, Code] FALCON: Learning Force-Adaptive Humanoid Loco-Manipulation
- [NeurIPS 2025, arXiv 2025.04, Demo] Adversarial Locomotion and Motion Imitation for Humanoid Policy Learning
- [RSS 2025, arXiv 2025.02, Demo, Code] HOMIE: Humanoid Loco-Manipulation with Isomorphic Exoskeleton Cockpit
Hardware Design
Data Collection Systems
- [arXiv 2025.11, GitHub] TWIST2: Scalable, Portable, and Holistic Humanoid Data Collection System [XR Humanoid Robot Whole Body Teleoperation]
- [arXiv 2025.11, GitHub] OSMO: Open-Source Tactile Glove for Human-to-Robot Skill Transfer [tactile glove]
- [arXiv 2025.10] ActiveUMI: Robotic Manipulation with Active Perception from Robot-Free Human Demonstrations
- [arXiv 2025.10] HumanoidExo: Scalable Whole-Body Humanoid Manipulation via Wearable Exoskeleton [force feedback exoskeleton]
- [CoRL 2025, arXiv 2025.09, GitHub] exUMI: Extensible Robot Teaching System with Action-aware Task-agnostic Tactile Representation [Organic combination of XR and UMI]
- [CoRL 2025, arXiv 2025.05, Hardware] DexUMI: Using Human Hand as the Universal Manipulation Interface for Dexterous Manipulation [UMI For Dexterous Hands]
- [CoRL 2025, arXiv 2025.05, Code] TWIST: Teleoperated Whole-Body Imitation System
- [RSS 2025, arXiv 2025.02, Hardware] HOMIE: Humanoid Loco-Manipulation with Isomorphic Exoskeleton Cockpit [upper body exoskeleton, throttle speed and direction control]
- [CoRL 2025, arXiv 2024.09, Code] FastUMI: A Scalable and Hardware-Independent Universal Manipulation Interface with Dataset [Improved version of UMI]
- [CoRL 2024, arXiv 2024.08, Hardware] ACE: A Cross-Platform Visual-Exoskeletons System for Low-Cost Dexterous Teleoperation [cross-platform visual-exoskeletons]
- [CoRL 2024, arXiv 2024.07, Code] UMI on Legs: Making Manipulation Policies Mobile with Manipulation-Centric Whole-body Controllers [UMI on robot dogs]
- [CoRL 2024, arXiv 2024.07, Code] Open-TeleVision: Teleoperation with Immersive Active Visual Feedback [XR humanoid robot teleoperation]
- [IROS 2025, arXiv 2024.07, Code] Bunny-VisionPro: Real-Time Bimanual Dexterous Teleoperation for Imitation Learning [XR robot teleoperation, tactile vibration feedback]
- [RSS 2024, arXiv 2024.02, Code, Hardware] Universal Manipulation Interface: In-The-Wild Robot Teaching Without In-The-Wild Robots [UMI's foundational work]
Capability Extension
- [arXiv 2025.12] Gait-Adaptive Perceptive Humanoid Locomotion with Real-Time Under-Base Terrain Reconstruction [downward-facing depth camera]
- [arXiv 2025.11] Gallant: Voxel Grid-based Humanoid Locomotion and Local-navigation across 3D Constrained Terrains [LiDARs]
- [arXiv 2025.11, Hardware] TWIST2: Scalable, Portable, and Holistic Humanoid Data Collection System [TWIST2 Neck]
- [arXiv 2025.10] DemoHLM: From One Demonstration to Generalizable Humanoid Loco-Manipulation [2-DoF neck]
- [CoRL 2025, arXiv 2025.08] Hand-Eye Autonomous Delivery: Learning Humanoid Navigation, Locomotion and Reaching [navigation camera + reaching camera]
- [ICRA 2025, arXiv 2025.06, GitHub] Robot-free Visuo-Tactile Data Collection System and Dataset [visuo-tactile]
- [RSS 2025, arXiv 2025.05] AMO: Adaptive Motion Optimization for Hyper-Dexterous Humanoid Whole-Body Control [3-DoF active head]
- [arXiv 2025.02, Hardware] ToddlerBot: Open-Source ML-Compatible Humanoid Platform for Loco-Manipulation [Low-cost Humanoid Robot]
- [ICRA 2025, arXiv 2024.12] Mobile-TeleVision: Predictive Motion Priors for Humanoid Whole-Body Control
- [CoRL 2024, arXiv 2024.07] Open-TeleVision: Teleoperation with Immersive Active Visual Feedback [3-DoF active head]
- [IROS 2024, arXiv 2024.07, Code] Learning Human-to-Humanoid Real-Time Whole-Body Teleoperation. [ZED mini odometry]
Generalist Vision–Language–Action Models
Manipulation
- [arXiv 2026.02, GitHub] χ₀: Resource-Aware Robust Manipulation via Taming Distributional Inconsistencies
- [arXiv 2026.02] DreamDojo: A Generalist Robot World Model from Large-Scale Human Videos
- [pdf 2026.02] World Action Models are Zero-shot Policies [DreamZero]
- [arXiv 2026.02, GitHub] RDT2: Enabling Zero-Shot Cross-Embodiment Generalization by Scaling Up UMI Data
- [arXiv 2026.01, GitHub] LingBot-VLA: A Pragmatic VLA Foundation Model
- [arXiv 2025.12] mimic-video: Video-Action Models for Generalizable Robot Control Beyond VLAs
- [blog 2025.11] π*0.6: a VLA that Learns from Experience
- [blog 2025.12, GitHub] GR00T N1.6: An Improved Open Foundation Model for Generalist Humanoid Robots
- [Survey, PDF] Intelligent Robot Manipulation Requires Self-Directed Learning
- [blog 2025.11] Embodied Foundation Models That Scale with Physical Interaction
- [arXiv 2025.11, GitHub] RynnVLA-002: A Unified Vision-Language-Action and World Model
- [arXiv 2025.11, GitHub] NORA-1.5: A Vision-Language-Action Model Trained using World Model and Action-based Preference Reward
- [arXiv 2025.11] EchoVLA: Robotic Vision-Language-Action Model with Synergistic Declarative Memory for Mobile Manipulation [VLA for Mobile Manipulation]
- [arXiv 2025.10, GitHub] X-VLA: Soft-Prompted Transformer as Scalable Cross-Embodiment Vision-Language-Action Model
- [arXiv 2025.09, GitHub] Igniting VLMs toward the Embodied Space [WALL-OSS]
- [blog 2025.08] Large Behavior Models and Atlas Find New Footing
- [arXiv 2025.08, GitHub] Genie Envisioner: A Unified World Foundation Platform for Robotic Manipulation [GE-Act]
- [arXiv 2025.07] A Careful Examination of Large Behavior Models for Multitask Dexterous Manipulation
- [arXiv 2025.07] GR-3 Technical Report
- [arXiv 2025.06, GitHub] SmolVLA: A vision-language-action model for affordable and efficient robotics
- [CoRL 2025, arXiv 2025.05, GitHub] GraspVLA: a Grasping Foundation Model Pre-trained on Billion-scale Synthetic Action Data
- [CoRL 2025, arXiv 2025.05, GitHub] Mobi-π: Mobilizing Your Robot Learning Policy [VLA for Mobile Manipulation]
- [arXiv 2025.04, GitHub] π0.5: A Vision-Language-Action Model with Open-World Generalization
- [arXiv 2025.03, GitHub] GR00T N1: An Open Foundation Model for Generalist Humanoid Robots
- [IROS 2025, arXiv 2025.03, GitHub] AgiBot World Colosseo: A Large-scale Manipulation Platform for Scalable and Intelligent Embodied Systems [large-scale manipulation dataset, GO-1]
- [CVPR 2025, arXiv 2025.03, GitHub] MoManipVLA: Transferring Vision-language-action Models for General Mobile Manipulation [VLA for Mobile Manipulation]
- [arXiv 2025.03] Gemini Robotics: Bringing AI into the Physical World
- [arXiv 2025.02, GitHub] DexGraspVLA: A Vision-Language-Action Framework Towards General Dexterous Grasping
- [arXiv 2025.02, GitHub] DexVLA: Vision-Language Model with Plug-In Diffusion Expert for General Robot Control
- [RSS 2025, arXiv 2025.02, GitHub] Fine-Tuning Vision-Language-Action Models: Optimizing Speed and Success [OpenVLA-OFT]
- [ICLR 2025, arXiv 2024.10, GitHub] RDT-1B: a Diffusion Foundation Model for Bimanual Manipulation
- [blog 2025.02] Helix: A Vision-Language-Action Model for Generalist Humanoid Control
Learning from Human Videos
- [arXiv 2026.02] DreamDojo: A Generalist Robot World Model from Large-Scale Human Videos
- [IROS 2025, arXiv 2025.11] Let Me Show You: Learning by Retrieving from Egocentric Video for Robotic Manipulation
- [arXiv 2025.10, GitHub] Scalable Vision-Language-Action Model Pretraining for Robotic Manipulation with Real-Life Human Activity Videos
- [arXiv 2025.09, GitHub] MimicDreamer: Aligning Human and Robot Demonstrations for Scalable VLA Training
- [arXiv 2025.09, GitHub] RynnVLA-001: Using Human Demonstrations to Improve Robot Manipulation
- [arXiv 2025.09, GitHub] Generalist Robot Manipulation beyond Action Labeled Data
- [arXiv 2025.09] VLBiMan: Vision-Language Anchored One-Shot Demonstration Enables Generalizable Bimanual Robotic Manipulation
- [ICCV 2025, arXiv 2025.08, GitHub] AR-VRM: Imitating Human Motions for Visual Robot Manipulation with Analogical Reasoning
- [arXiv 2025.07, GitHub] H-RDT: Human Manipulation Enhanced Bimanual Robotic Manipulation
- [arXiv 2025.07, GitHub] Being-H0: Vision-Language-Action Pretraining from Large-Scale Human Videos
- [arXiv 2025.07, GitHub] EgoVLA: Learning Vision-Language-Action Models from Egocentric Human Videos
- [arXiv 2025.06, GitHub] Human2LocoMan: Learning Versatile Quadrupedal Manipulation with Human Pretraining
- [arXiv 2025.05, GitHub] EgoDex: Learning Dexterous Manipulation from Large-Scale Egocentric Video
- [RSS 2025, arXiv 2025.05, GitHub] UniVLA: Learning to Act Anywhere with Task-centric Latent Actions
- [arXiv 2025.05] Learning Generalizable Robot Policy with Human Demonstration Video as a Prompt
- [arXiv 2025.03, GitHub] ZeroMimic: Distilling Robotic Manipulation Skills from Web Videos
- [ICLR 2025, arXiv 2024.10, GitHub] Latent Action Pretraining from Videos
- [CoRL 2024, arXiv 2024.10, GitHub] EgoMimic: Scaling Imitation Learning via Egocentric Video
- [CVPR 2025, arXiv 2024.06, GitHub] Mitigating the Human-Robot Domain Discrepancy in Visual Pre-training for Robotic Manipulation
- [CoRL 2024, arXiv 2024.05] Vision-based Manipulation from Single Human Video with Open-World Object Graphs
- [CoRL 2022, arXiv 2022.03, GitHub] R3M: A Universal Visual Representation for Robot Manipulation
Navigation
- [arXiv 2026.02, Demo] Sparse Video Generation Propels Real-World Beyond-the-View Vision-Language Navigation
- [arXiv 2025.12, GitHub] Ground Slow, Move Fast: A Dual-System Foundation Model for Generalizable Vision-and-Language Navigation [fast-slow system]
- [2025.09, GitHub] A Video-based Vision-Language-Action Model for Unifying Embodied Navigation Tasks [large-scale data]
- [arXiv 2025.09] Embodied Navigation Foundation Model [multi-view, UAV]
- [arXiv 2025.08, GitHub] NavA3: Understanding Any Instruction, Navigating Anywhere, Finding Anything
- [arXiv 2025.08] CorrectNav: Self-Correction Flywheel Empowers Vision-Language-Action Navigation Model
- [arXiv 2025.07, GitHub] StreamVLN: Streaming Vision-and-Language Navigation via SlowFast Context Modeling [use KV-cache to accelerate the inference]
- [ICCV 2025, arXiv 2025.07, GitHub] Move to Understand a 3D Scene: Bridging Visual Grounding and Exploration for Efficient and Versatile Embodied Navigation [combine exploration and exploitation]
- [arXiv 2025.06, GitHub] VLN-R1: Vision-Language Navigation via Reinforcement Fine-Tuning [GRPO fine-tuned model]
- [arXiv 2025.05, GitHub] TrackVLA: Embodied Visual Tracking in the Wild [use video-based VLM to generate tracking; tracking task]
- [arXiv 2025.05, GitHub] NavDP: Learning Sim-to-Real Navigation Diffusion Policy with Privileged Information Guidance [use diffusion to generate action]
- [RSS 2025, arXiv 2025.04, GitHub] Learned Perceptive Forward Dynamics Model for Safe and Platform-aware Robotic Navigation [cross-platform]
- [RSS 2025, arXiv 2024.12, GitHub] NaVILA: Legged Robot Vision-Language-Action Model for Navigation [use RL to design low-level control; cross embodiment]
- [RSS 2025, arXiv 2024.12, GitHub] A Video-based Vision-Language-Action Model for Unifying Embodied Navigation Tasks [upgrade from NaVid]
- [CVPR 2025, arXiv 2024.12, GitHub] Navigation World Models [action-input-based]
- [ICCV 2025, arXiv 2024.12, GitHub] CogNav: Cognitive Process Modeling for Object Goal Navigation with LLMs [human cognitive process]
- [ECCV 2024, arXiv 2024.07, GitHub] NavGPT-2: Unleashing Navigational Reasoning Capability for Large Vision-Language Models [GPT fine-tuned]
- [RSS 2024, arXiv 2024.02, GitHub] NaVid: Video-based VLM Plans the Next Step for Vision-and-Language Navigation [end-to-end VLM-based navigation]
- [RSS 2024, arXiv 2023.11, GitHub] GOAT: GO to Any Thing [multi-modal, lifelong navigation]
- [CVPR 2018, arXiv 2017.11, GitHub] Vision-and-Language Navigation: Interpreting Visually-grounded Navigation Instructions in Real Environments [R2R dataset]
References
We refer to and recommend several curated paper lists and repositories:
Contributors
This project is contributed by:
Jin Chen,
Yucheng Huang,
Haoran Jiang,
Yixuan Pan,
Shijia Peng,
Jialong Zeng,
Hai Zhang.
All names are listed in alphabetical order by last name.
Citation
If you find this repository helpful, please consider citing:
@article{jiang2025wholebodyvla,
  title={WholeBodyVLA: Towards Unified Latent VLA for Whole-Body Loco-Manipulation Control},
  author={Jiang, Haoran and Chen, Jin and Bu, Qingwen and Chen, Li and Shi, Modi and Zhang, Yanjie and Li, Delong and Suo, Chuanzhe and Wang, Chuang and Peng, Zhihui and Li, Hongyang},
  journal={arXiv preprint arXiv:2512.11047},
  year={2025}
}
@article{chen2025intelligent,
  title={Intelligent Robot Manipulation Requires Self-Directed Learning},
  author={Chen, Li and Sima, Chonghao and Chitta, Kashyap and Loquercio, Antonio and Luo, Ping and Ma, Yi and Li, Hongyang},
  year={2025}
}
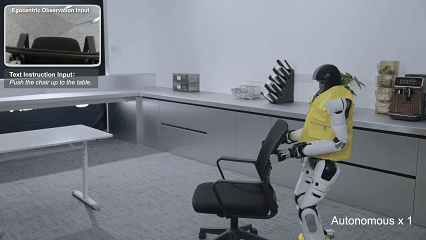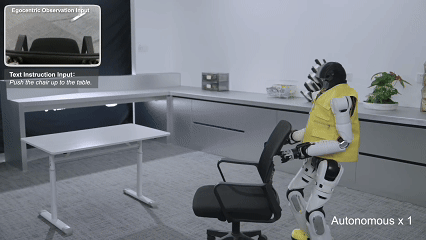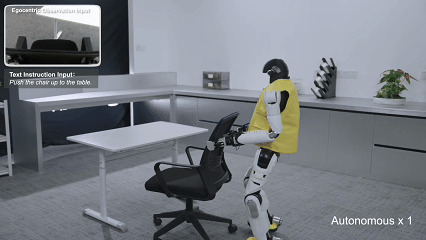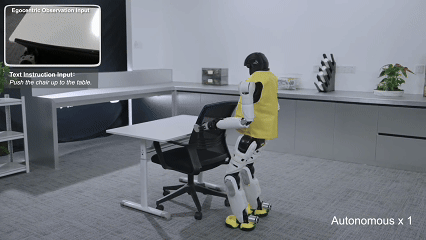

 WholeBodyVLA is an ICLR 2026 research project introducing a unified Vision-Language-Action framework for closed-loop humanoid whole-body loco-manipulation control, and this repository doubles as a curated, continuously updated list of VLA papers for humanoid robots.