

MiniCPM-V README

The project's README from github.com/OpenBMB/MiniCPM-V. As one markdown file: README.md.

A Pocket-Sized MLLM for Ultra-Efficient Image and Video Understanding on Your Phone

中文 | English

feishu Feishu (Lark)  |   Discord Discord  |   📚 MiniCPM Wiki

MiniCPM-V 4.6 🤗 🤖 📱 | MiniCPM-o 4.5 🤗 📞 🤖 | 📄 Technical Report | 🍳 Cookbook | 🌐 API

MiniCPM-V and MiniCPM-o are multimodal LLM series designed for strong performance and efficient deployment on devices. MiniCPM-V focuses on efficient vision-language understanding across image, video and text inputs. MiniCPM-o extends the family toward real-time end-to-end omnimodal interaction with streaming video and audio inputs plus text and speech outputs. The most notable models in the series currently include:

News


Click to view more news.
  • [2026.05.07] 📢📢📢 We release the MiniCPM-o 4.5 technical report, introducing the key techniques behind its real-time full-duplex omni-modal interaction. Read it here.

  • [2026.02.05] 📢📢📢 We note the web demo may experience latency issues due to network conditions. We are working actively to provide a Docker image for local deployment of the real-time interactive Demo as soon as possible. Please stay tuned!

  • [2025.09.18] 📢📢📢 MiniCPM-V 4.5 technical report is now released! See here.

  • [2025.09.01] ⭐️⭐️⭐️ MiniCPM-V 4.5 has been officially supported by llama.cpp, vLLM, and LLaMA-Factory. You are welcome to use it directly through these official channels! Support for additional frameworks such as Ollama and SGLang is actively in progress.

  • [2025.08.02] 🚀🚀🚀 We open-source MiniCPM-V 4.0, which outperforms GPT-4.1-mini-20250414 in image understanding. It advances popular features of MiniCPM-V 2.6, and largely improves the efficiency. We also open-source the iOS App on iPhone and iPad. Try it now!

  • [2025.06.20] ⭐️⭐️⭐️ Our official Ollama repository is released. Try our latest models with one click!

  • [2025.01.24] 📢📢📢 MiniCPM-o 2.6 technical report is released! See here.

  • [2025.01.23] 💡💡💡 MiniCPM-o 2.6 is now supported by Align-Anything, a framework by PKU-Alignment Team for aligning any-to-any modality large models with human intentions. It supports DPO and SFT fine-tuning on both vision and audio. Try it now!

  • [2025.01.19] 📢 ATTENTION! We are currently working on merging MiniCPM-o 2.6 into the official repositories of llama.cpp, Ollama, and vllm. Until the merge is complete, please USE OUR LOCAL FORKS of llama.cpp, Ollama, and vllm. Using the official repositories before the merge may lead to unexpected issues.

  • [2025.01.17] We have updated the usage of MiniCPM-o 2.6 int4 quantization version and resolved the model initialization error. Click here and try it now!

  • [2025.01.13] 🔥🔥🔥 We open-source MiniCPM-o 2.6, which matches GPT-4o-202405 on vision, speech and multimodal live streaming. It advances popular capabilities of MiniCPM-V 2.6, and supports various new fun features. Try it now!

  • [2024.08.15] We now also support multi-image SFT. For more details, please refer to the document.

  • [2024.08.14] MiniCPM-V 2.6 now also supports fine-tuning with the SWIFT framework!

  • [2024.08.17] 🚀🚀🚀 MiniCPM-V 2.6 is now fully supported by official llama.cpp! GGUF models of various sizes are available here.

  • [2024.08.10] 🚀🚀🚀 MiniCPM-Llama3-V 2.5 is now fully supported by official llama.cpp! GGUF models of various sizes are available here.

  • [2024.08.06] 🔥🔥🔥 We open-source MiniCPM-V 2.6, which outperforms GPT-4V on single image, multi-image and video understanding. It advances popular features of MiniCPM-Llama3-V 2.5, and can support real-time video understanding on iPad. Try it now!

  • [2024.08.03] MiniCPM-Llama3-V 2.5 technical report is released! See here.

  • [2024.07.19] MiniCPM-Llama3-V 2.5 supports vLLM now! See here.

  • [2024.06.03] Now, you can run MiniCPM-Llama3-V 2.5 on multiple low VRAM GPUs(12 GB or 16 GB) by distributing the model's layers across multiple GPUs. For more details, check this link.

  • [2024.05.28] 🚀🚀🚀 MiniCPM-Llama3-V 2.5 now fully supports its feature in llama.cpp and Ollama! Please pull the latest code of our provided forks (llama.cpp, Ollama). GGUF models in various sizes are available here. MiniCPM-Llama3-V 2.5 series is not supported by the official repositories yet, and we are working hard to merge PRs. Please stay tuned!

  • [2024.05.28] 💫 We now support LoRA fine-tuning for MiniCPM-Llama3-V 2.5, using only 2 V100 GPUs! See more statistics here.

  • [2024.05.25] MiniCPM-Llama3-V 2.5 now supports streaming outputs and customized system prompts. Try it here!

  • [2024.05.24] We release the MiniCPM-Llama3-V 2.5 gguf, which supports llama.cpp inference and provides a 6~8 token/s smooth decoding on mobile phones. Try it now!

  • [2024.05.23] 🔍 We've released a comprehensive comparison between Phi-3-vision-128k-instruct and MiniCPM-Llama3-V 2.5, including benchmark evaluations, multilingual capabilities, and inference efficiency 🌟📊🌍🚀. Click here to view more details.

  • [2024.05.20] We open-soure MiniCPM-Llama3-V 2.5, it has improved OCR capability and supports 30+ languages, representing the first end-side MLLM achieving GPT-4V level performance! We provide efficient inference and simple fine-tuning. Try it now!

  • [2024.04.23] MiniCPM-V-2.0 supports vLLM now! Click here to view more details.

  • [2024.04.18] We create a HuggingFace Space to host the demo of MiniCPM-V 2.0 at here!

  • [2024.04.17] MiniCPM-V-2.0 supports deploying WebUI Demo now!

  • [2024.04.15] MiniCPM-V-2.0 now also supports fine-tuning with the SWIFT framework, with streaming inference enabled!

  • [2024.04.12] We open-source MiniCPM-V 2.0, which achieves comparable performance with Gemini Pro in understanding scene text and outperforms strong Qwen-VL-Chat 9.6B and Yi-VL 34B on OpenCompass, a comprehensive evaluation over 11 popular benchmarks. Click here to view the MiniCPM-V 2.0 technical blog.

  • [2024.03.14] MiniCPM-V now supports fine-tuning with the SWIFT framework. Thanks to Jintao for the contribution!

  • [2024.03.01] MiniCPM-V can now be deployed on Mac!

  • [2024.02.01] We open-source MiniCPM-V and OmniLMM-12B, which support efficient end-side deployment and powerful multimodal capabilities correspondingly.

Contents

MiniCPM-V 4.6

MiniCPM-V 4.6 is our most edge-deployment-friendly model to date. The model is built based on SigLIP2-400M and the Qwen3.5-0.8B LLM. It inherits the strong single-image, multi-image, and video understanding capabilities of MiniCPM-V family, while significantly improving computation efficiency. It also introduces mixed 4x/16x visual token compression. Notable features of MiniCPM-V 4.6 include:

Evaluation

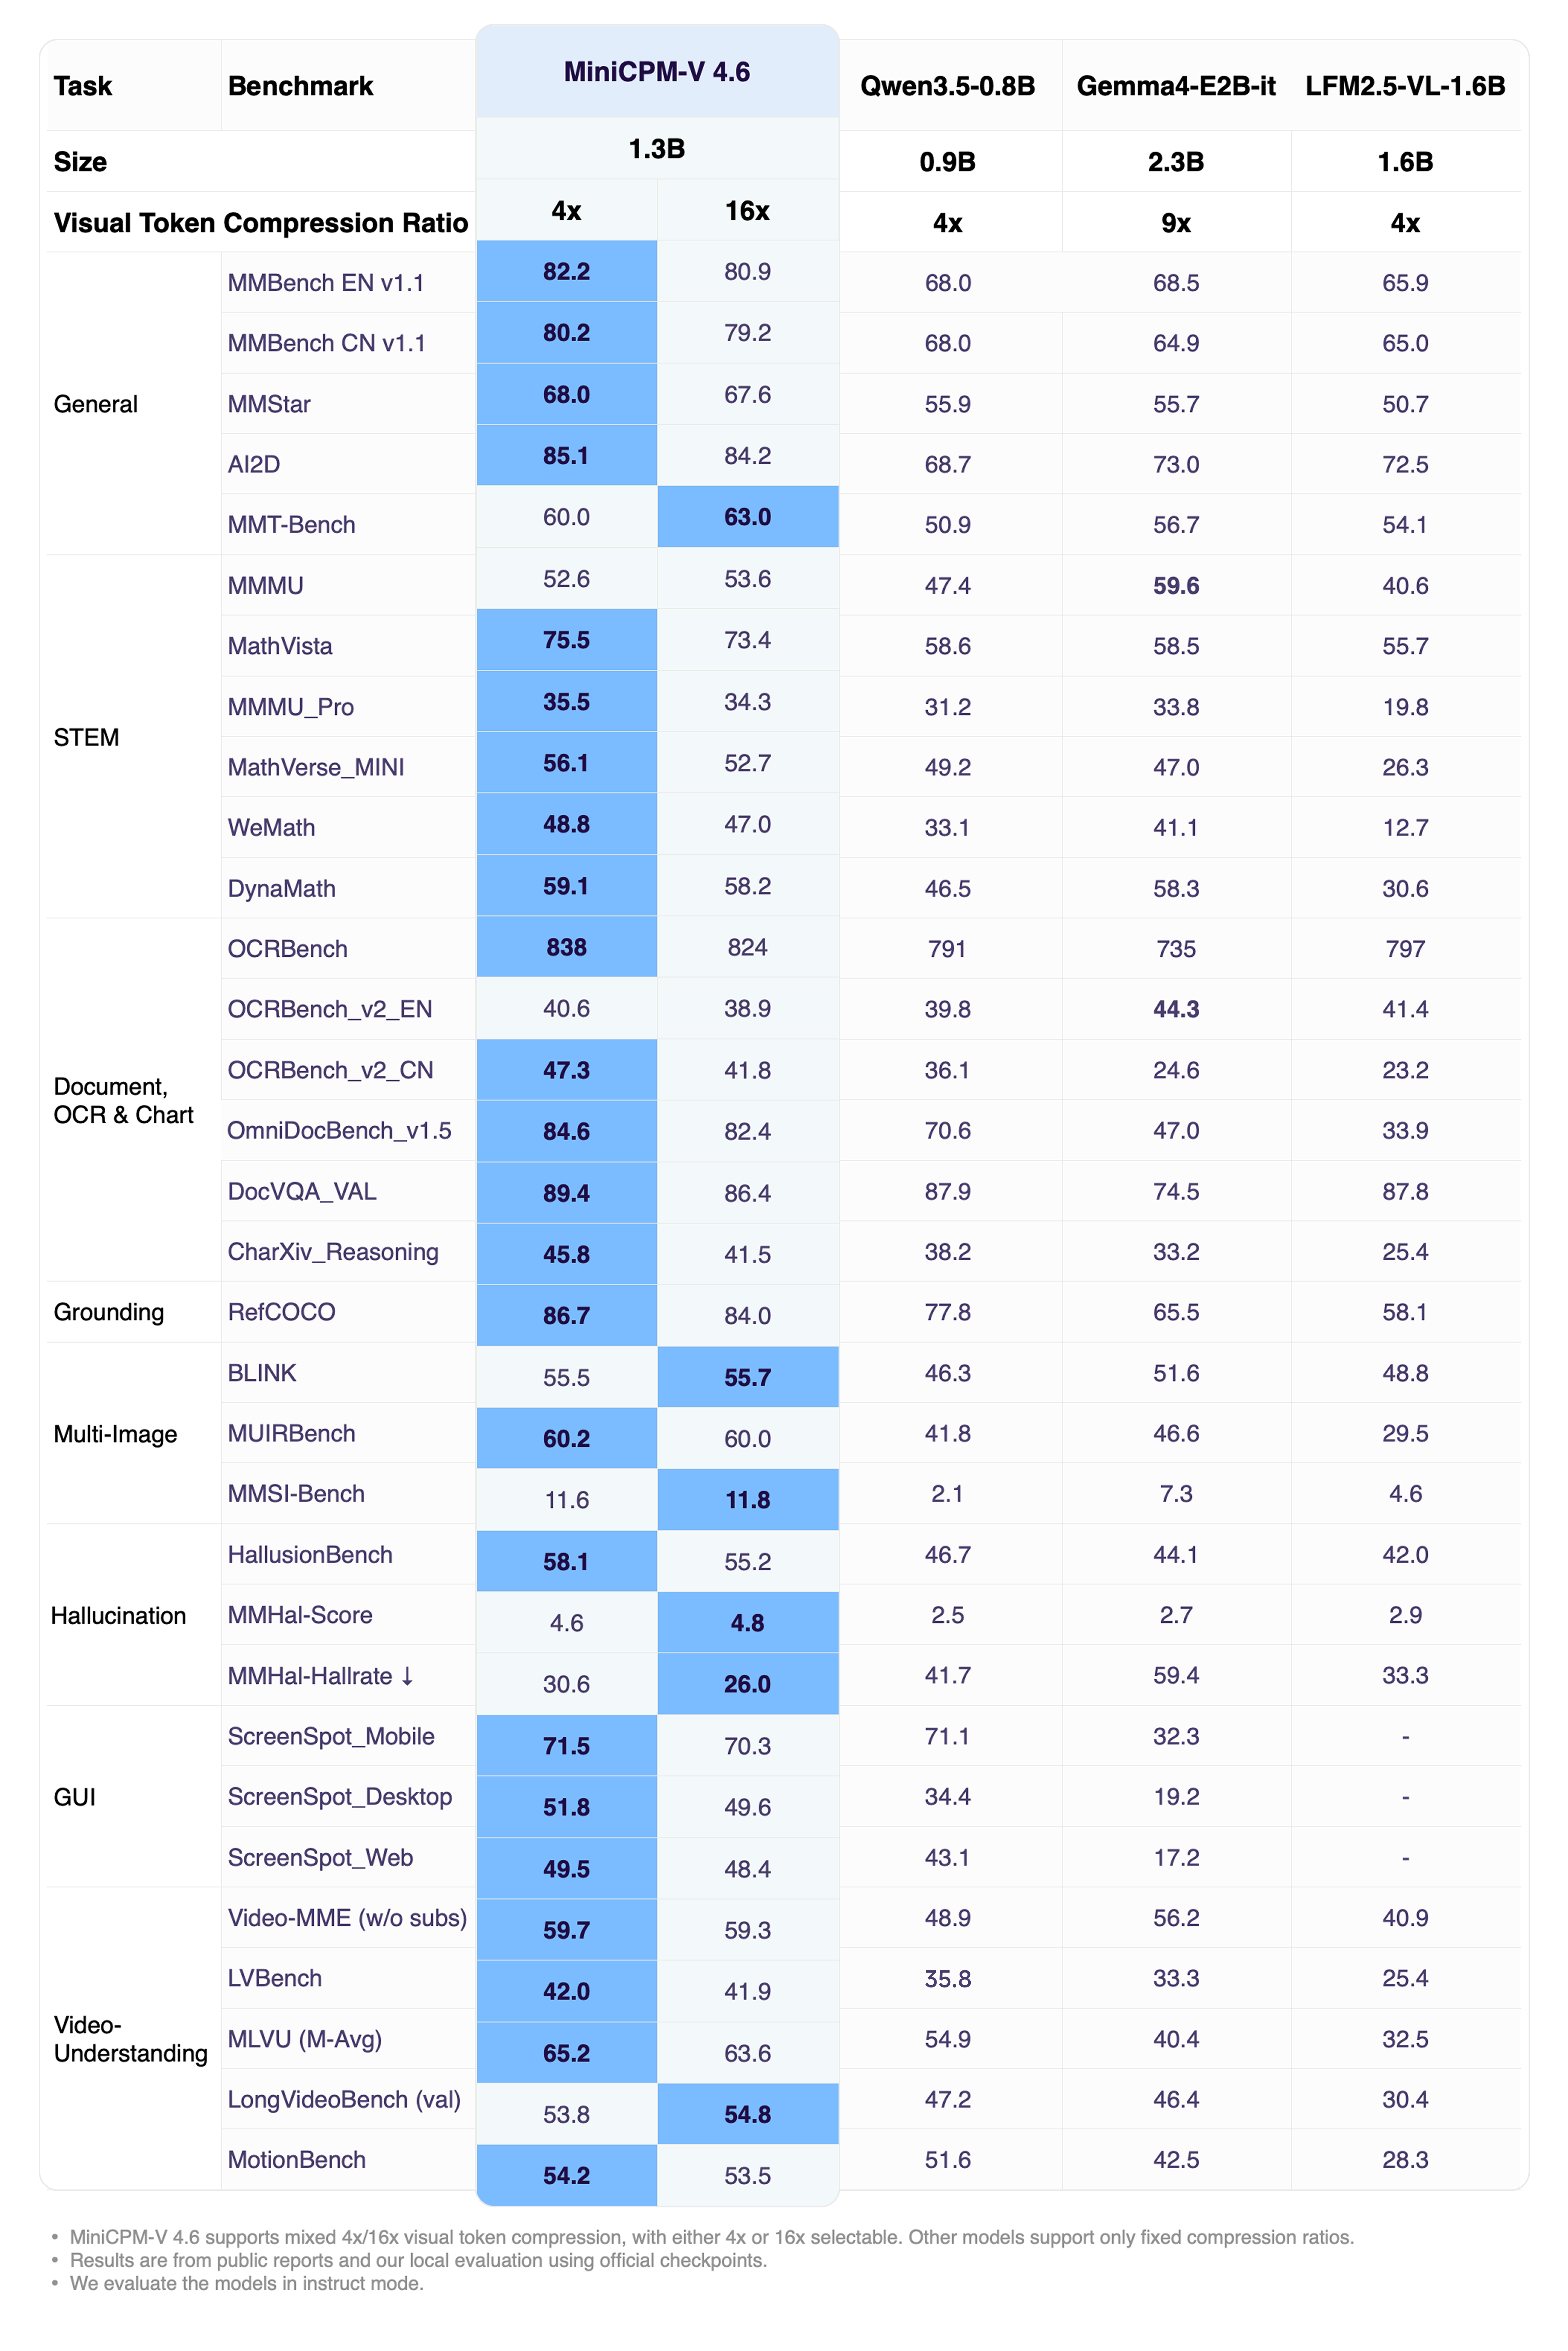
Overall Performance (Instruct)

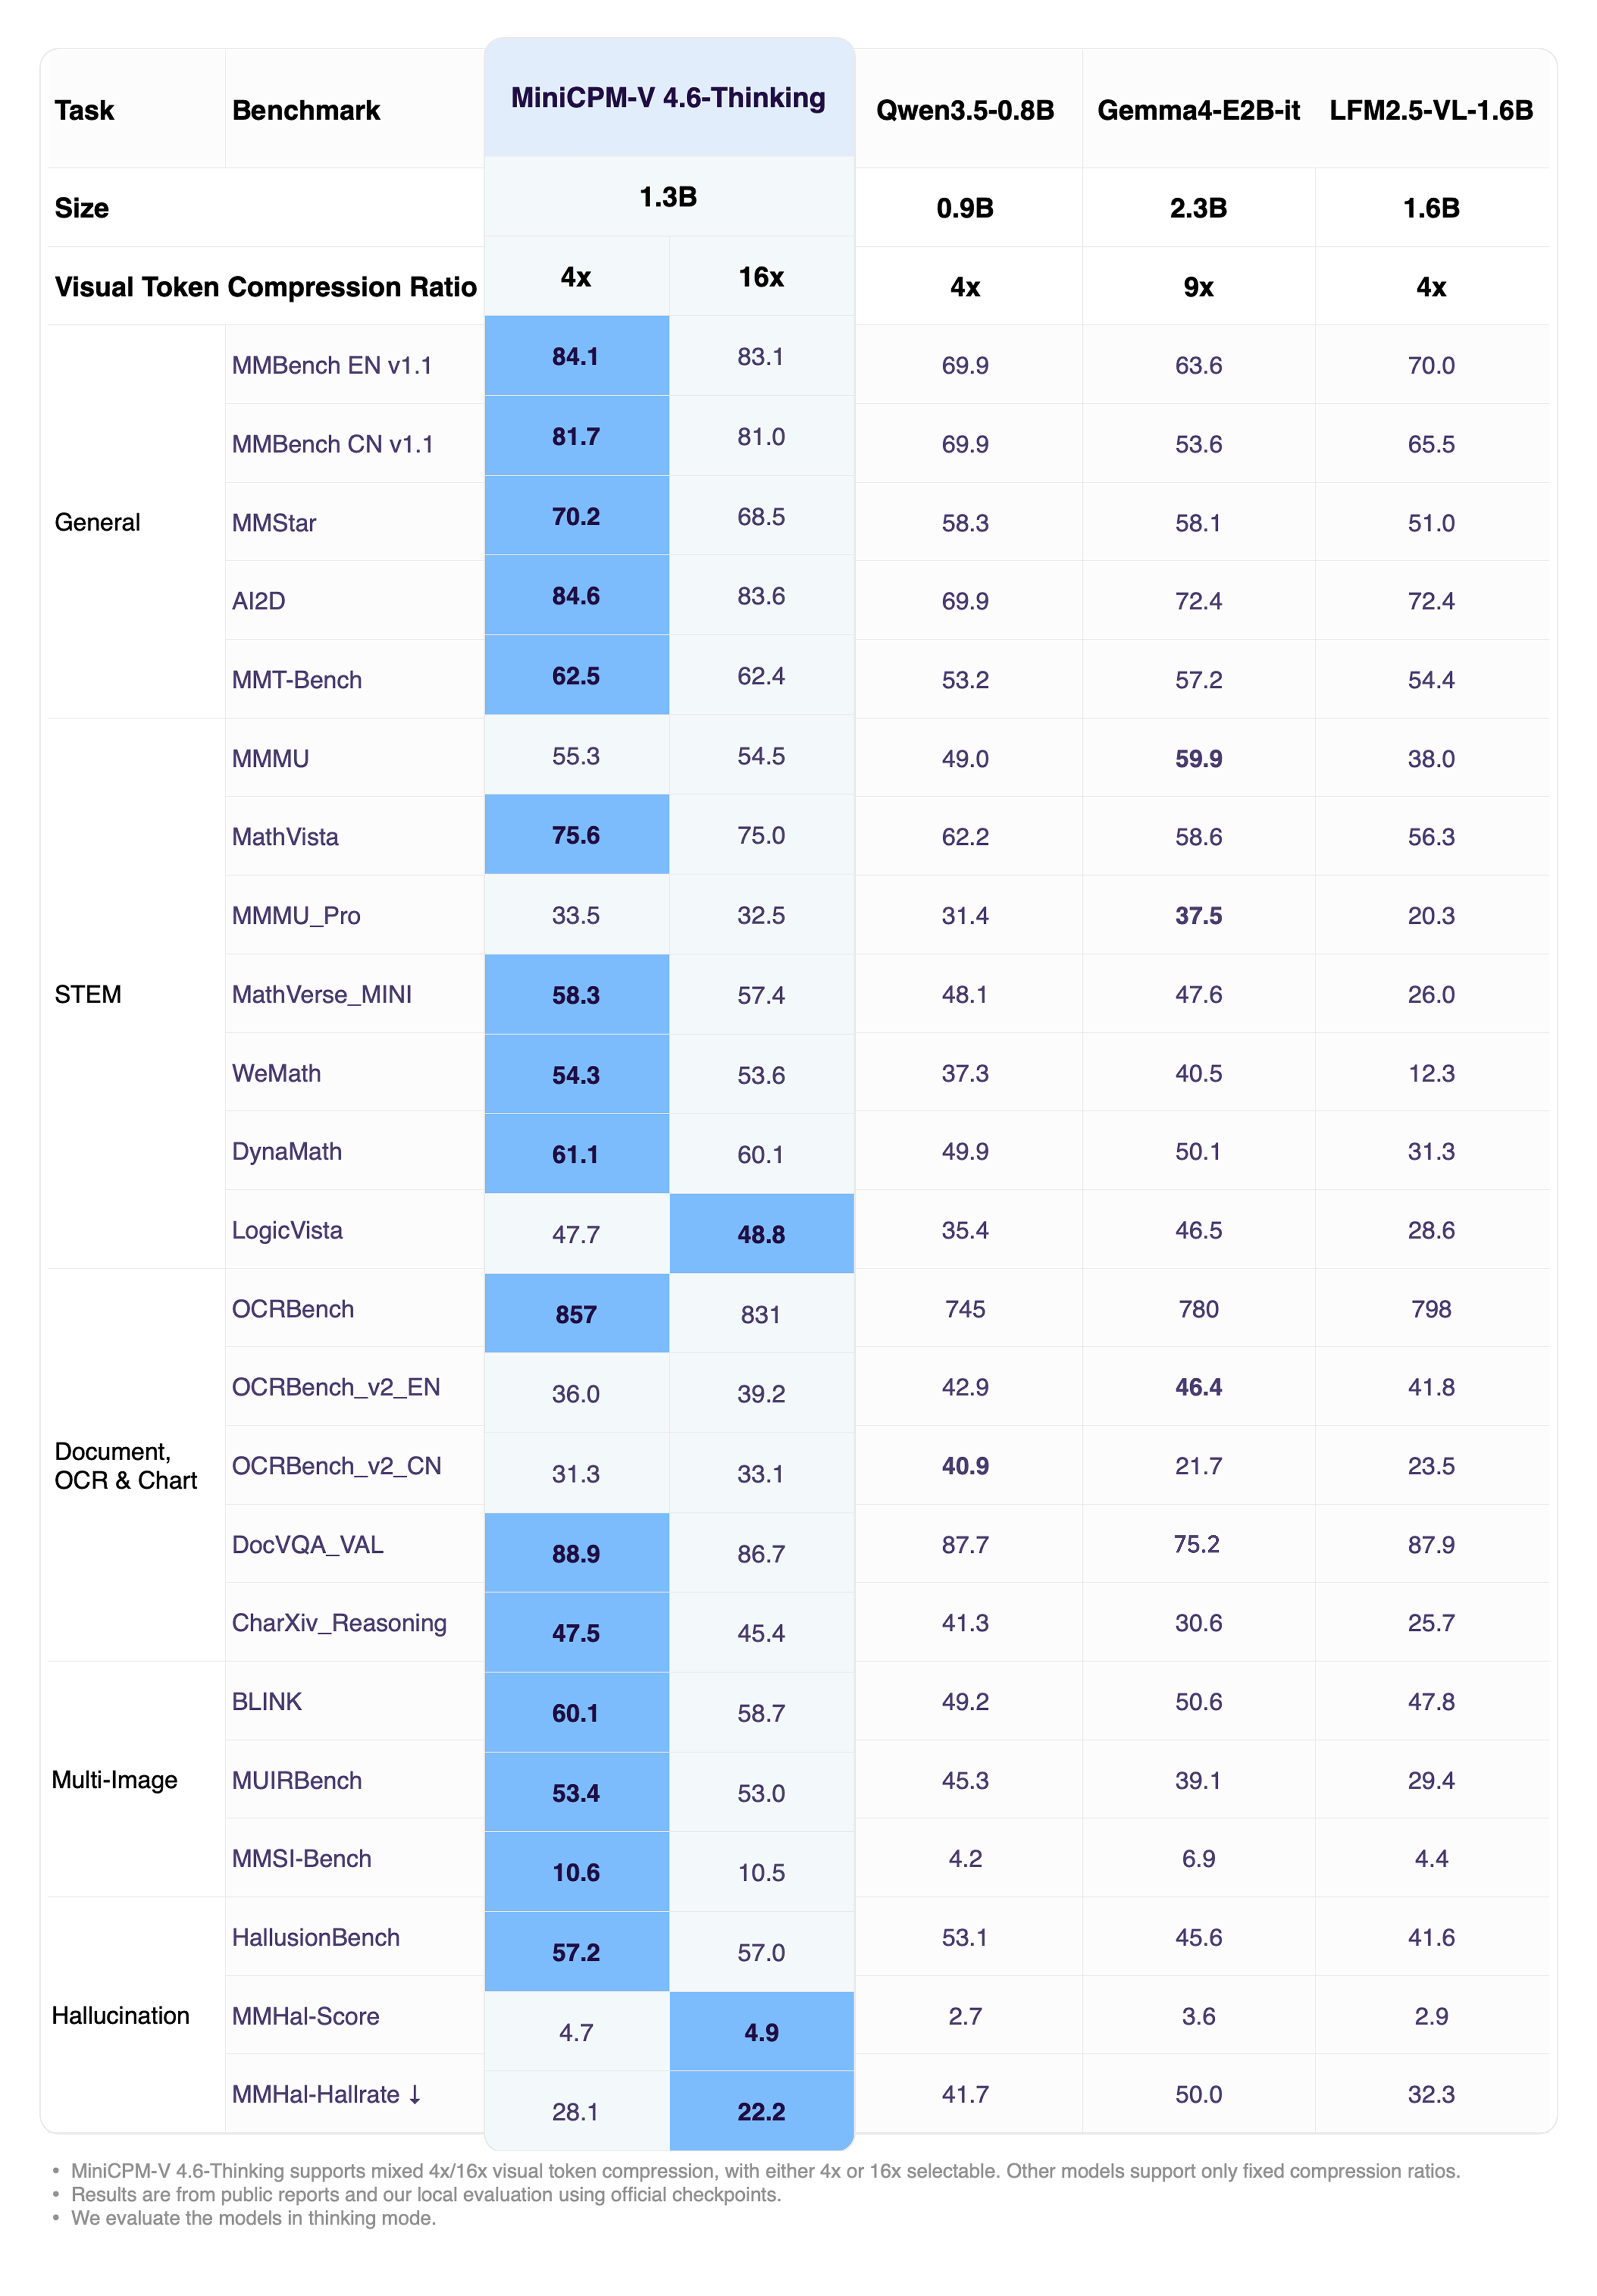
Click to view MiniCPM-V 4.6-Thinking performance.


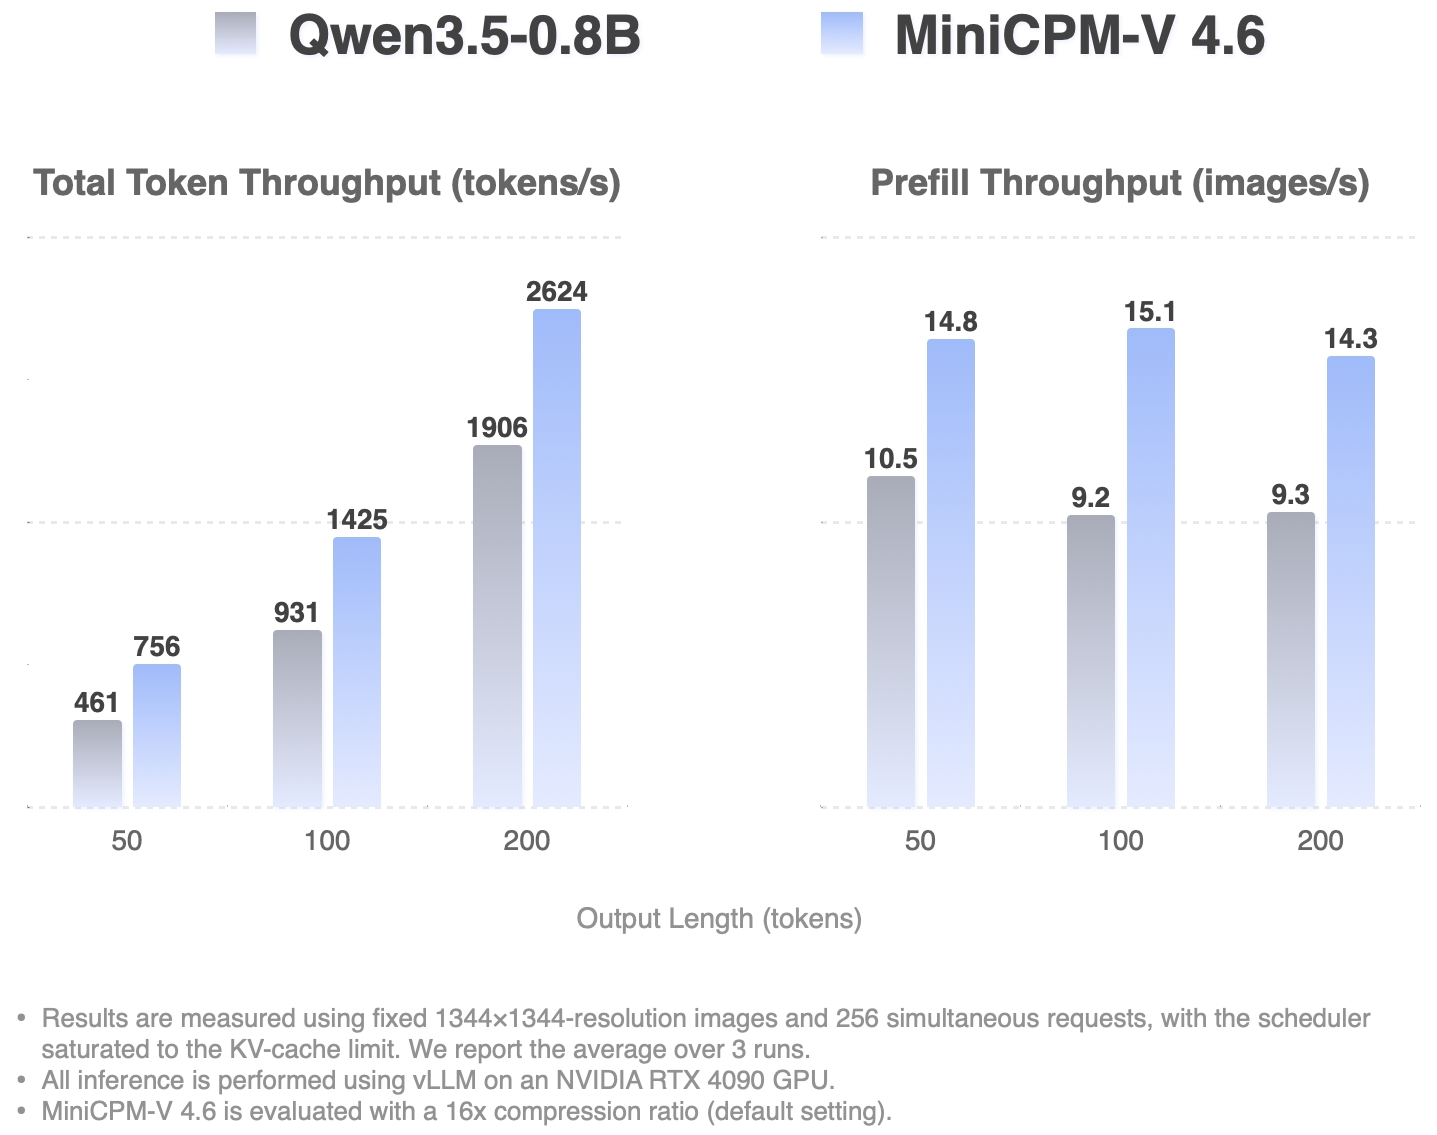
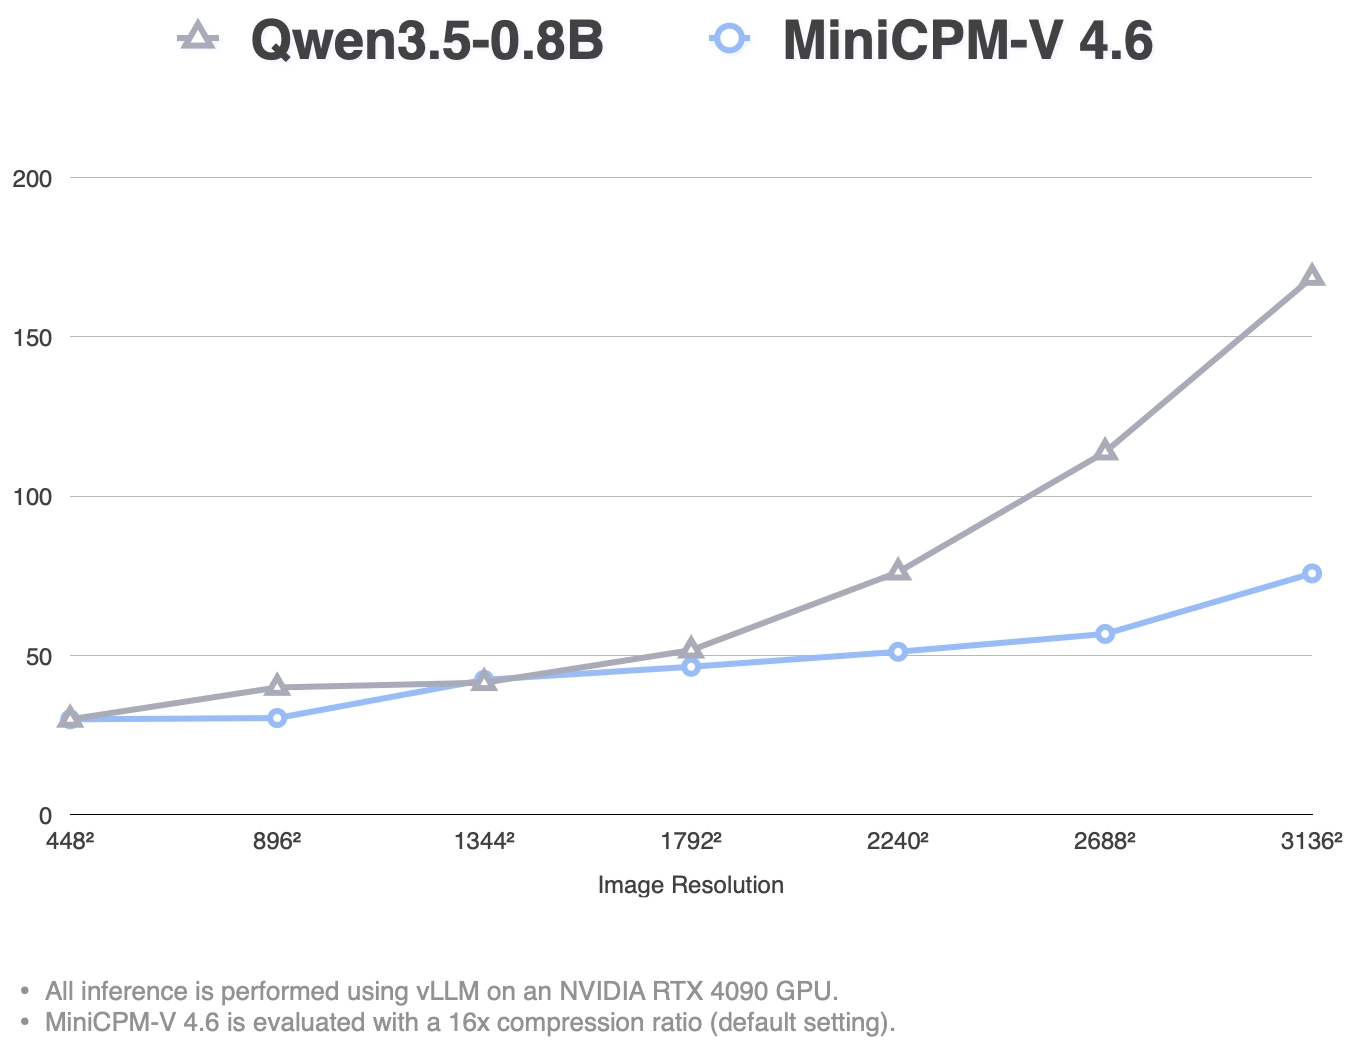
MiniCPM-V 4.6 Inference Efficiency

High-Concurrency Throughput Single Request TTFT (ms)

Examples

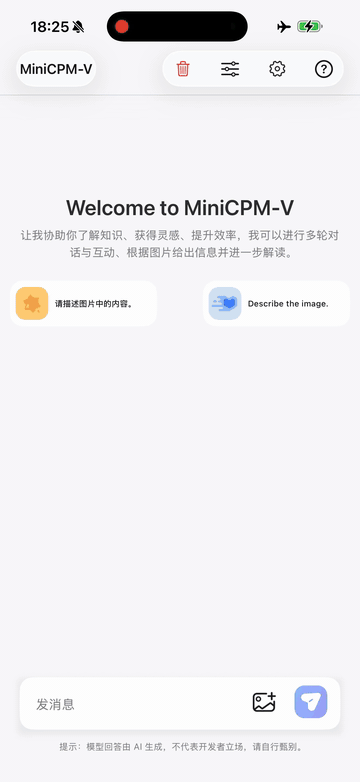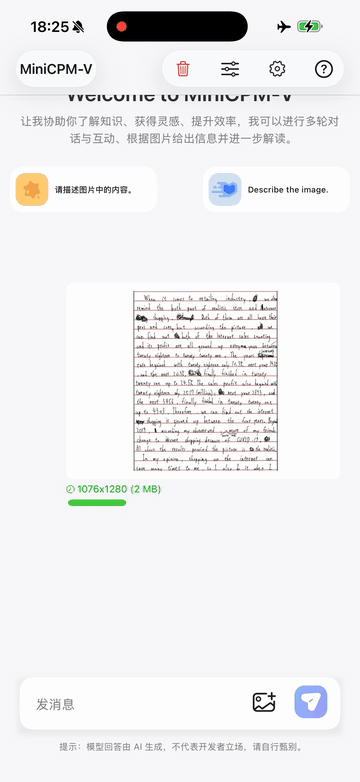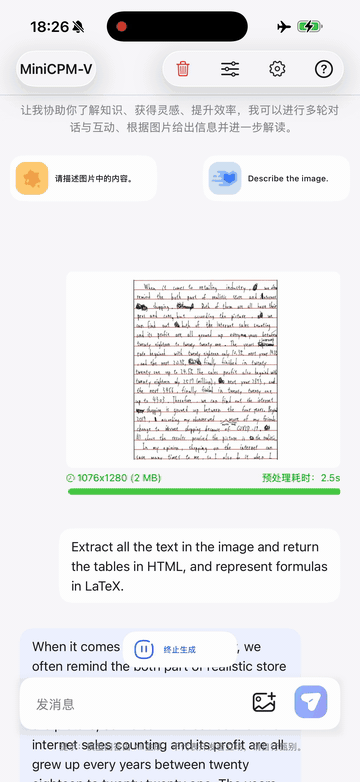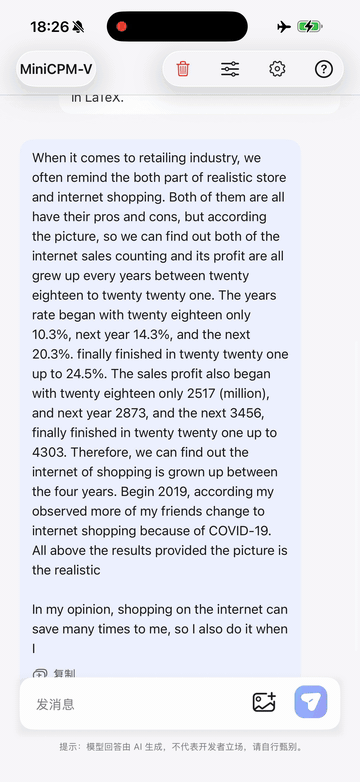
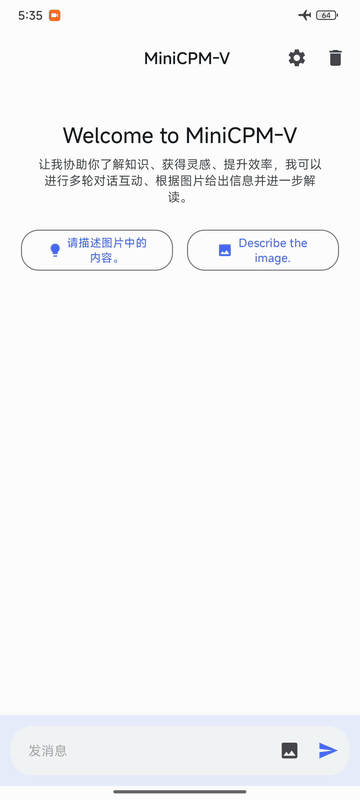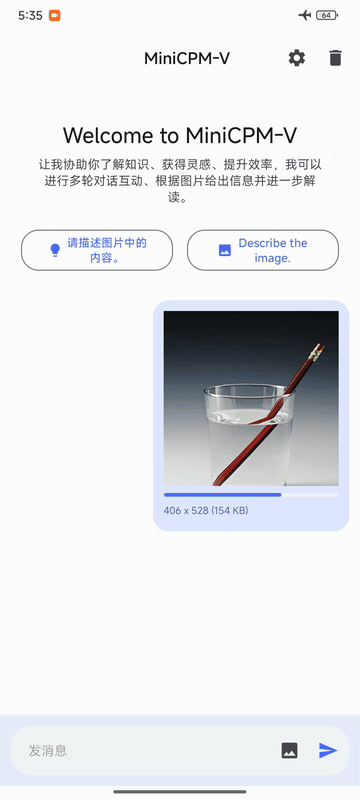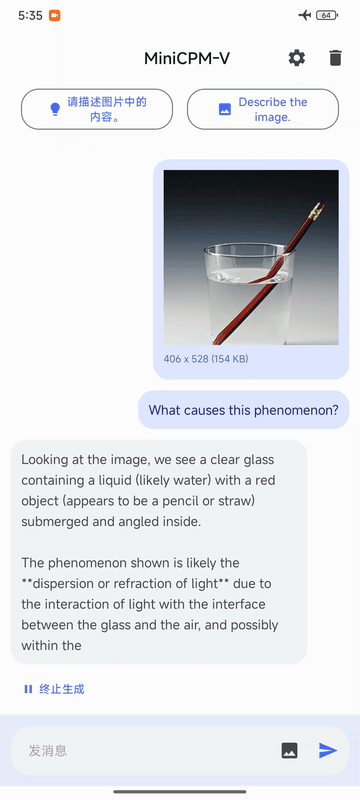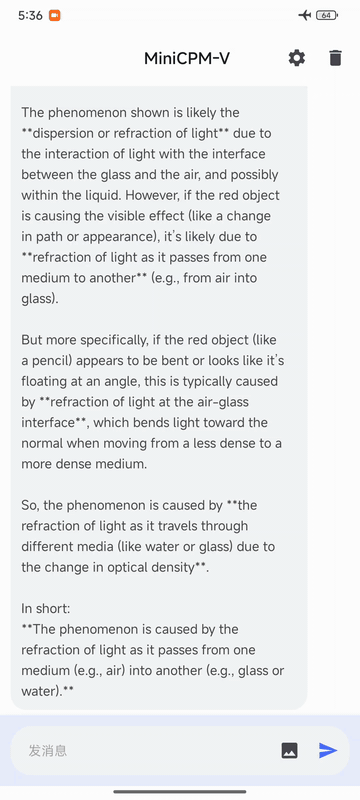
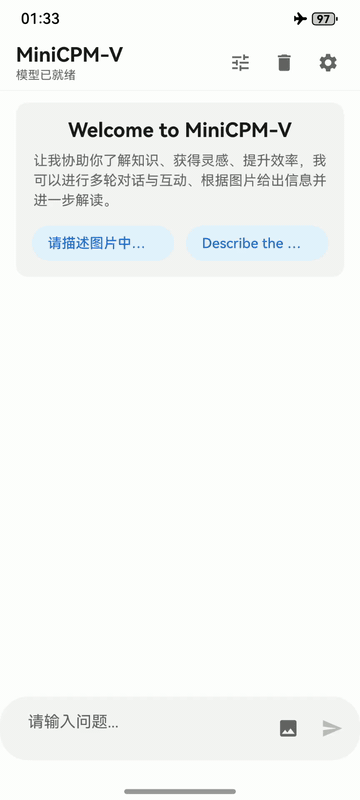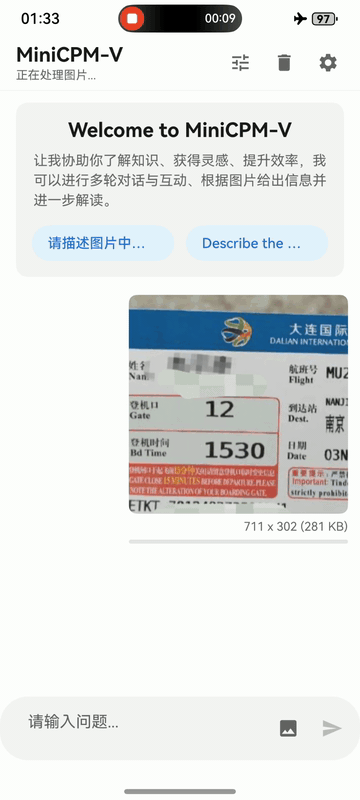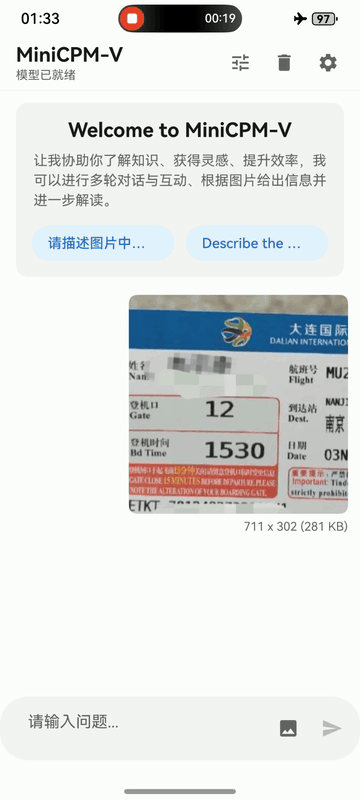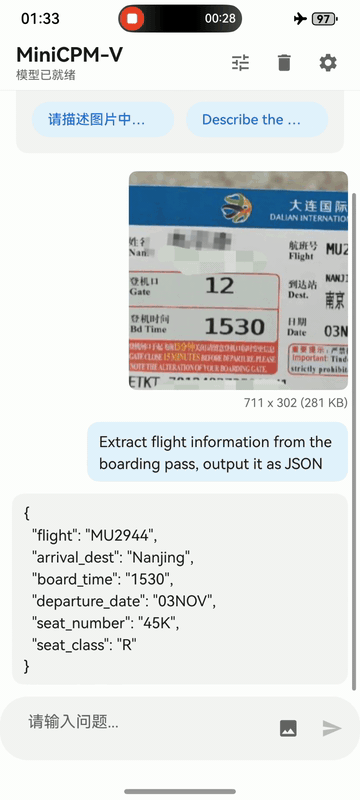
MiniCPM-V 4.6 can be deployed across three mainstream end-side platforms — iOS, Android and HarmonyOS. The clips below are raw screen recordings on phone devices without edition.

iPhone
iPhone 17 Pro Max
Android
Redmi K70
HarmonyOS
HUAWEI nova 14

Usages

Inference with Transformers

Click to show inference examples with Transformers.
Installation
pip install "transformers[torch]>=5.7.0" torchvision torchcodec

Note on CUDA compatibility: torchcodec (used for video decoding) may have compatibility issues with certain CUDA versions. For example, torch>=2.11 bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such as RuntimeError: Could not load libtorchcodec. Two workarounds:

  1. Replace torchcodec with PyAV — supports both image and video inference without CUDA version constraints:
    pip install "transformers[torch]>=5.7.0" torchvision av
    
  2. Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
    pip install "transformers>=5.7.0" torchvision torchcodec --index-url https://download.pytorch.org/whl/cu128
    
Load Model
from transformers import AutoModelForImageTextToText, AutoProcessor

model_id = "openbmb/MiniCPM-V-4.6"

processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
    model_id, torch_dtype="auto", device_map="auto"
)

# Flash Attention 2 is recommended for better acceleration and memory saving,
# especially in multi-image and video scenarios.
# model = AutoModelForImageTextToText.from_pretrained(
#     model_id,
#     torch_dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )
Image Inference
messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"},
            {"type": "text

MiniCPM-V (OpenBMB/MiniCPM-V)

Searching Database…

26.8K ·GitHub
这是什么?OpenBMB 推出的一系列可装进口袋的多模态 AI 模型(MiniCPM-V 和 MiniCPM-o),专为在本地设备甚至手机上运行而设计——能理解图片、视频和文本,o 系列还能处理语音。
它是应用、模型还是服务?它不是面向普通用户的应用,而是开放权重的模型加 Python 推理代码:你可以通过 Ollama、llama.cpp、vLLM 或 Transformers 来运行,也可以调用托管 API。另外还有开源的 iOS 应用和实时网页演示。
我怎么把它跑起来?最快的办法:从 Ollama 官方模型库拉取 MiniCPM-V 4.6。也可以用 Transformers 加载,在 llama.cpp 里运行 GGUF 版本,或者直接用 API;常见场景在 Cookbook 和文档站点里都有说明。
安装时有什么坑需要提前知道?通过 torchcodec 解码视频会和某些 CUDA 版本冲突(torch>=2.11 自带 CUDA 13.1);可以换成 PyAV,或者固定 CUDA 版本。另外网络不好的话,实时网页演示也可能卡顿。
它到底能在哪些设备和系统上运行?三大主流手机系统都支持——iOS、Android 和鸿蒙(HarmonyOS),端侧适配代码已经开源,还有开源的 iOS 应用可用于 iPhone 和 iPad。在电脑上则可以通过 Ollama 或 llama.cpp 运行。
如果它在我设备上运行,我的数据会留在本地吗?会——它是端侧部署,你输入的图片、视频和音频都留在你的手机或电脑上。如果不想在本地跑任何东西,也可以选择托管 API 服务。
我的笔记本或手机跑得动吗,还是需要大显卡?跑 MiniCPM-V 4.6 不需要大显卡:它只有 1.3B 参数,目标就是手机和边缘设备,在消费级显卡上也能微调。9B 的 MiniCPM-o 4.5 更吃资源,实时演示则需要 Mac 或显卡。
MiniCPM-o 和 MiniCPM-V 有什么区别?MiniCPM-V 负责高效的图片、视频和文本理解。MiniCPM-o 更进一步:可以实时流式输入视频和音频,输出文本和语音,还支持全双工实时对话——它能同时看、听和说。
1.3B 的模型到底能有多强?在 Artificial Analysis Intelligence Index 上,MiniCPM-V 4.6 拿到 13 分,Qwen3.5-0.8B 只有 10 分,而且它每个回答消耗的 token 少得多,还超过了更大的 Ministral 3 3B。MiniCPM-o 4.5 在视觉和语音方面接近 Gemini 2.5 Flash。
全双工实际用起来是什么意思?输出流(语音和文本)与实时输入流(视频和音频)互不阻塞,所以模型可以一边看、一边听、一边说话,还能主动行动,比如在没人提示的情况下主动提醒你某件事。
我可以用自己的数据微调它吗?可以——它能接入 SWIFT 和 LLaMA-Factory 这类微调生态,Align-Anything 还支持在视觉和音频上做 DPO 和 SFT。量化版本提供 GGUF、BNB、AWQ 和 GPTQ 格式。
What are similar projects?VoxCPM, InternVL, MiniCPM, Qwen3-VL, unsloth, MOSS-TTS, decider, Qwen3
Creator
OpenBMB
Size
796.2 MB
Stars
26.8K
Age
2y
Commits · 90 Days