这是什么?
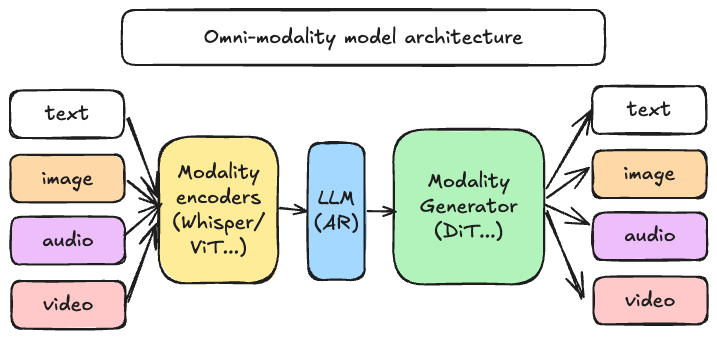
 vLLM-Omni 是一个推理与服务框架,它把 vLLM 的能力从纯文本大语言模型扩展到全模态模型,可处理文本、图像、音频、视频和动作等输出。
这是可以自己部署的框架,还是托管服务?它是一个自托管的服务框架:你需要自己运行它,它会提供一个兼容 OpenAI 的 API 服务器,而不是你注册使用的云服务。
它是一个自托管的服务框架:你需要自己运行它,它会提供一个兼容 OpenAI 的 API 服务器,而不是你注册使用的云服务。我该怎么把它跑起来?你可以按照项目的 Installation 和 Quickstart 文档操作;同时也提供基于最新 main 分支构建的每日 CUDA Docker 镜像,便于快速部署。
你可以按照项目的 Installation 和 Quickstart 文档操作;同时也提供基于最新 main 分支构建的每日 CUDA Docker 镜像,便于快速部署。运行它需要什么硬件?你需要 GPU 来进行模型推理;该框架主要面向 CUDA,同时也广泛支持 ROCm、XPU 和 NPU,底层依赖 PyTorch。
你需要 GPU 来进行模型推理;该框架主要面向 CUDA,同时也广泛支持 ROCm、XPU 和 NPU,底层依赖 PyTorch。版本发布稳定吗?版本发布与上游 vLLM 紧密绑定。从 0.14.0 开始,每个偶数次要版本的 vLLM 都会对应发布一个稳定版本,所以你需要关注 vLLM 自身的版本发布节奏。
版本发布与上游 vLLM 紧密绑定。从 0.14.0 开始,每个偶数次要版本的 vLLM 都会对应发布一个稳定版本,所以你需要关注 vLLM 自身的版本发布节奏。它能支持哪些模型?它支持 Qwen3-Omni、MiniCPM-o、Cosmos3、HunyuanImage、BAGEL 等全模态模型,以及 Qwen3-TTS、CosyVoice3 等 TTS 模型,LTX-2、Wan2.2 等扩散图像和视频模型,还有 π0、GR00T-N1.7 等机器人策略和动作模型。
它支持 Qwen3-Omni、MiniCPM-o、Cosmos3、HunyuanImage、BAGEL 等全模态模型,以及 Qwen3-TTS、CosyVoice3 等 TTS 模型,LTX-2、Wan2.2 等扩散图像和视频模型,还有 π0、GR00T-N1.7 等机器人策略和动作模型。为什么不直接用原版 vLLM?原版 vLLM 只处理自回归的文本生成;vLLM-Omni 则在 vLLM 的 KV 缓存效率之上,增加了对非自回归的 Diffusion Transformer(扩散 Transformer)以及异构多模态流水线(文本、图像、音频、视频、动作)的支持。
原版 vLLM 只处理自回归的文本生成;vLLM-Omni 则在 vLLM 的 KV 缓存效率之上,增加了对非自回归的 Diffusion Transformer(扩散 Transformer)以及异构多模态流水线(文本、图像、音频、视频、动作)的支持。能处理实时语音对话吗?可以,它实现了全双工的实时服务,支持流式音频的输入和输出,例如 MiniCPM-o 系列就在使用这一功能。
可以,它实现了全双工的实时服务,支持流式音频的输入和输出,例如 MiniCPM-o 系列就在使用这一功能。What are similar projects?GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold, Qwen3.8-Flash-Next-Dual-DGX-Sparks, ZDTaichu5.0-9B, vllm, dgx-spark-qwen38, text-generation-inference, GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark, Model-Optimizer
GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold, Qwen3.8-Flash-Next-Dual-DGX-Sparks, ZDTaichu5.0-9B, vllm, dgx-spark-qwen38, text-generation-inference, GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark, Model-OptimizerWhich topics is it in?world-model, world-models, diffusion, model-serving, audio-generation, robotics, llm-inference, tts, vllm, quantization, multimodal, video-generation
world-model, world-models, diffusion, model-serving, audio-generation, robotics, llm-inference, tts, vllm, quantization, multimodal, video-generation