Table of Contents
- Introduction
- Model Summary
- Model Downloads
- Evaluation Results
- Chat Website & API Platform
- How to Run Locally
- License
- Citation
- Contact
1. Introduction
We present DeepSeek-V3, a strong Mixture-of-Experts (MoE) language model with 671B total parameters with 37B activated for each token.
To achieve efficient inference and cost-effective training, DeepSeek-V3 adopts Multi-head Latent Attention (MLA) and DeepSeekMoE architectures, which were thoroughly validated in DeepSeek-V2.
Furthermore, DeepSeek-V3 pioneers an auxiliary-loss-free strategy for load balancing and sets a multi-token prediction training objective for stronger performance.
We pre-train DeepSeek-V3 on 14.8 trillion diverse and high-quality tokens, followed by Supervised Fine-Tuning and Reinforcement Learning stages to fully harness its capabilities.
Comprehensive evaluations reveal that DeepSeek-V3 outperforms other open-source models and achieves performance comparable to leading closed-source models.
Despite its excellent performance, DeepSeek-V3 requires only 2.788M H800 GPU hours for its full training.
In addition, its training process is remarkably stable.
Throughout the entire training process, we did not experience any irrecoverable loss spikes or perform any rollbacks.

2. Model Summary
Architecture: Innovative Load Balancing Strategy and Training Objective
- On top of the efficient architecture of DeepSeek-V2, we pioneer an auxiliary-loss-free strategy for load balancing, which minimizes the performance degradation that arises from encouraging load balancing.
- We investigate a Multi-Token Prediction (MTP) objective and prove it beneficial to model performance.
It can also be used for speculative decoding for inference acceleration.
Pre-Training: Towards Ultimate Training Efficiency
- We design an FP8 mixed precision training framework and, for the first time, validate the feasibility and effectiveness of FP8 training on an extremely large-scale model.
- Through co-design of algorithms, frameworks, and hardware, we overcome the communication bottleneck in cross-node MoE training, nearly achieving full computation-communication overlap.
This significantly enhances our training efficiency and reduces the training costs, enabling us to further scale up the model size without additional overhead.
- At an economical cost of only 2.664M H800 GPU hours, we complete the pre-training of DeepSeek-V3 on 14.8T tokens, producing the currently strongest open-source base model. The subsequent training stages after pre-training require only 0.1M GPU hours.
Post-Training: Knowledge Distillation from DeepSeek-R1
- We introduce an innovative methodology to distill reasoning capabilities from the long-Chain-of-Thought (CoT) model, specifically from one of the DeepSeek R1 series models, into standard LLMs, particularly DeepSeek-V3. Our pipeline elegantly incorporates the verification and reflection patterns of R1 into DeepSeek-V3 and notably improves its reasoning performance. Meanwhile, we also maintain a control over the output style and length of DeepSeek-V3.
3. Model Downloads
| Model |
#Total Params |
#Activated Params |
Context Length |
Download |
| DeepSeek-V3-Base |
671B |
37B |
128K |
🤗 Hugging Face |
| DeepSeek-V3 |
671B |
37B |
128K |
🤗 Hugging Face |
[!NOTE]
The total size of DeepSeek-V3 models on Hugging Face is 685B, which includes 671B of the Main Model weights and 14B of the Multi-Token Prediction (MTP) Module weights.
To ensure optimal performance and flexibility, we have partnered with open-source communities and hardware vendors to provide multiple ways to run the model locally. For step-by-step guidance, check out Section 6: How_to Run_Locally.
For developers looking to dive deeper, we recommend exploring README_WEIGHTS.md for details on the Main Model weights and the Multi-Token Prediction (MTP) Modules. Please note that MTP support is currently under active development within the community, and we welcome your contributions and feedback.
4. Evaluation Results
Base Model
Standard Benchmarks
|
Benchmark (Metric) |
# Shots |
DeepSeek-V2 |
Qwen2.5 72B |
LLaMA3.1 405B |
DeepSeek-V3 |
|
Architecture |
- |
MoE |
Dense |
Dense |
MoE |
|
# Activated Params |
- |
21B |
72B |
405B |
37B |
|
# Total Params |
- |
236B |
72B |
405B |
671B |
| English |
Pile-test (BPB) |
- |
0.606 |
0.638 |
0.542 |
0.548 |
|
BBH (EM) |
3-shot |
78.8 |
79.8 |
82.9 |
87.5 |
|
MMLU (Acc.) |
5-shot |
78.4 |
85.0 |
84.4 |
87.1 |
|
MMLU-Redux (Acc.) |
5-shot |
75.6 |
83.2 |
81.3 |
86.2 |
|
MMLU-Pro (Acc.) |
5-shot |
51.4 |
58.3 |
52.8 |
64.4 |
|
DROP (F1) |
3-shot |
80.4 |
80.6 |
86.0 |
89.0 |
|
ARC-Easy (Acc.) |
25-shot |
97.6 |
98.4 |
98.4 |
98.9 |
|
ARC-Challenge (Acc.) |
25-shot |
92.2 |
94.5 |
95.3 |
95.3 |
|
HellaSwag (Acc.) |
10-shot |
87.1 |
84.8 |
89.2 |
88.9 |
|
PIQA (Acc.) |
0-shot |
83.9 |
82.6 |
85.9 |
84.7 |
|
WinoGrande (Acc.) |
5-shot |
86.3 |
82.3 |
85.2 |
84.9 |
|
RACE-Middle (Acc.) |
5-shot |
73.1 |
68.1 |
74.2 |
67.1 |
|
RACE-High (Acc.) |
5-shot |
52.6 |
50.3 |
56.8 |
51.3 |
|
TriviaQA (EM) |
5-shot |
80.0 |
71.9 |
82.7 |
82.9 |
|
NaturalQuestions (EM) |
5-shot |
38.6 |
33.2 |
41.5 |
40.0 |
|
AGIEval (Acc.) |
0-shot |
57.5 |
75.8 |
60.6 |
79.6 |
| Code |
HumanEval (Pass@1) |
0-shot |
43.3 |
53.0 |
54.9 |
65.2 |
|
MBPP (Pass@1) |
3-shot |
65.0 |
72.6 |
68.4 |
75.4 |
|
LiveCodeBench-Base (Pass@1) |
3-shot |
11.6 |
12.9 |
15.5 |
19.4 |
|
CRUXEval-I (Acc.) |
2-shot |
52.5 |
59.1 |
58.5 |
67.3 |
|
CRUXEval-O (Acc.) |
2-shot |
49.8 |
59.9 |
59.9 |
69.8 |
| Math |
GSM8K (EM) |
8-shot |
81.6 |
88.3 |
83.5 |
89.3 |
|
MATH (EM) |
4-shot |
43.4 |
54.4 |
49.0 |
61.6 |
|
MGSM (EM) |
8-shot |
63.6 |
76.2 |
69.9 |
79.8 |
|
CMath (EM) |
3-shot |
78.7 |
84.5 |
77.3 |
90.7 |
| Chinese |
CLUEWSC (EM) |
5-shot |
82.0 |
82.5 |
83.0 |
82.7 |
|
C-Eval (Acc.) |
5-shot |
81.4 |
89.2 |
72.5 |
90.1 |
|
CMMLU (Acc.) |
5-shot |
84.0 |
89.5 |
73.7 |
88.8 |
|
CMRC (EM) |
1-shot |
77.4 |
75.8 |
76.0 |
76.3 |
|
C3 (Acc.) |
0-shot |
77.4 |
76.7 |
79.7 |
78.6 |
|
CCPM (Acc.) |
0-shot |
93.0 |
88.5 |
78.6 |
92.0 |
| Multilingual |
MMMLU-non-English (Acc.) |
5-shot |
64.0 |
74.8 |
73.8 |
79.4 |
[!NOTE]
Best results are shown in bold. Scores with a gap not exceeding 0.3 are considered to be at the same level. DeepSeek-V3 achieves the best performance on most benchmarks, especially on math and code tasks.
For more evaluation details, please check our paper.
Context Window
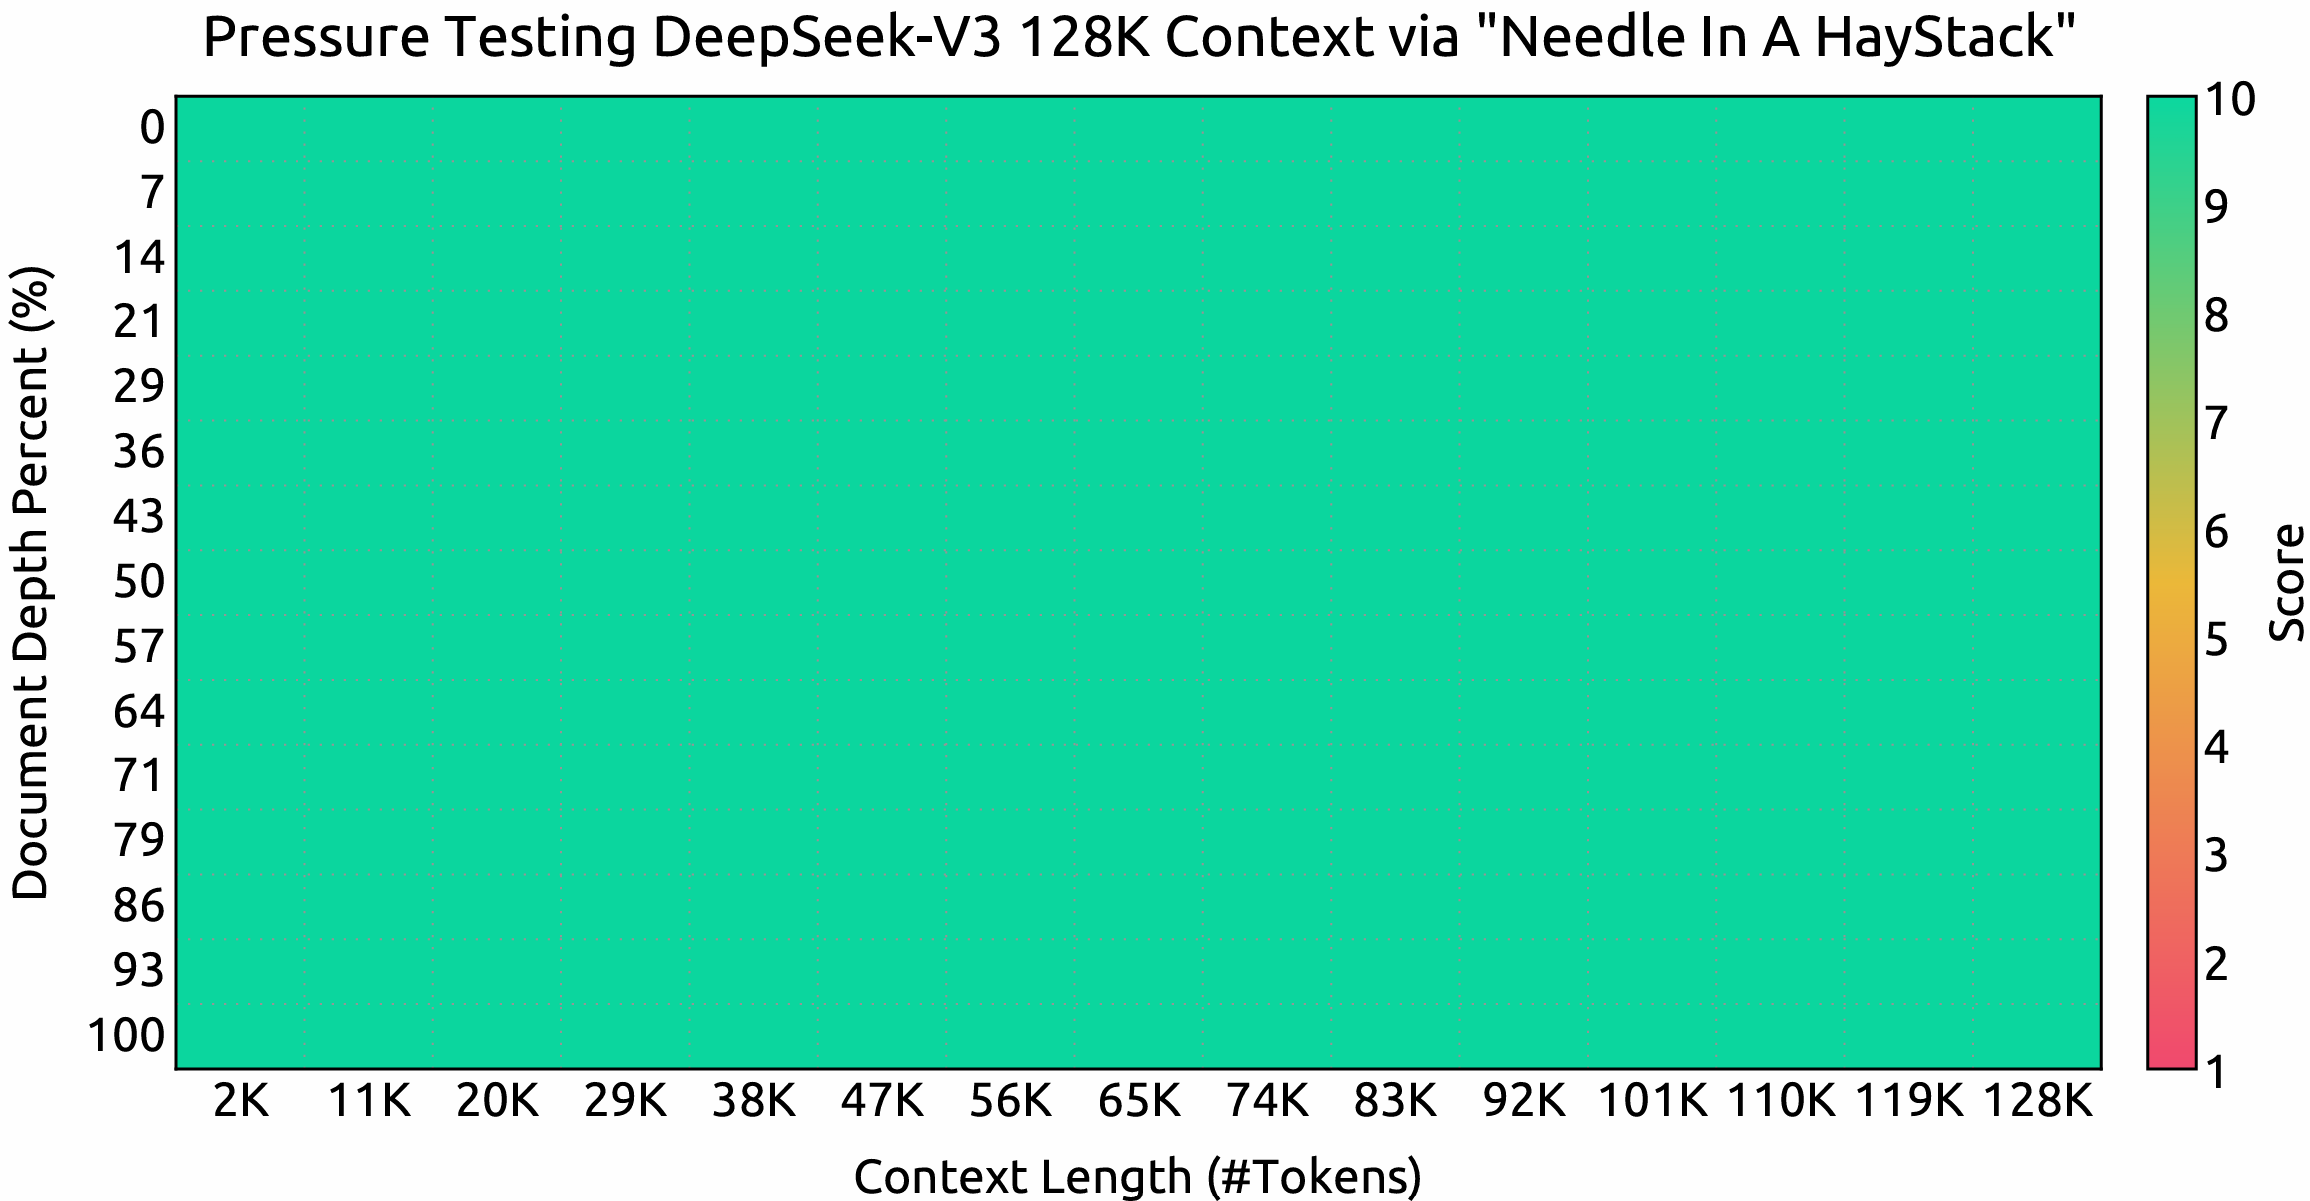
Evaluation results on the Needle In A Haystack (NIAH) tests. DeepSeek-V3 performs well across all context window lengths up to 128K.
Chat Model
Standard Benchmarks (Models larger than 67B)
|
Benchmark (Metric) |
DeepSeek V2-0506 |
DeepSeek V2.5-0905 |
Qwen2.5 72B-Inst. |
Llama3.1 405B-Inst. |
Claude-3.5-Sonnet-1022 |
GPT-4o 0513 |
DeepSeek V3 |
|
Architecture |
MoE |
MoE |
Dense |
Dense |
- |
- |
MoE |
|
# Activated Params |
21B |
21B |
72B |
405B |
- |
- |
37B |
|
# Total Params |
236B |
236B |
72B |
405B |
- |
- |
671B |
| English |
MMLU (EM) |
78.2 |
80.6 |
85.3 |
88.6 |
88.3 |
87.2 |
88.5 |
|
MMLU-Redux (EM) |
77.9 |
80.3 |
85.6 |
86.2 |
88.9 |
88.0 |
89.1 |
|
MMLU-Pro (EM) |
58.5 |
66.2 |
71.6 |
73.3 |
78.0 |
72.6 |
75.9 |
|
DROP (3-shot F1) |
83.0 |
87.8 |
76.7 |
88.7 |
88.3 |
83.7 |
91.6 |
|
IF-Eval (Prompt Strict) |
57.7 |
80.6 |
84.1 |
86.0 |
86.5 |
84.3 |
86.1 |
|
GPQA-Diamond (Pass@1) |
35.3 |
41.3 |
49.0 |
51.1 |
65.0 |
49.9 |
59.1 |
|
SimpleQA (Correct) |
9.0 |
10.2 |
9.1 |
17.1 |
28.4 |
38.2 |
24.9 |
|
FRAMES (Acc.) |
66.9 |
65.4 |
69.8 |
70.0 |
72.5 |
80.5 |
73.3 |
|
LongBench v2 (Acc.) |
31.6 |
35.4 |
39.4 |
36.1 |
41.0 |
48.1 |
48.7 |
| Code |
HumanEval-Mul (Pass@1) |
69.3 |
77.4 |
77.3 |
77.2 |
81.7 |
80.5 |
82.6 |
|
LiveCodeBench (Pass@1-COT) |
18.8 |
29.2 |
31.1 |
28.4 |
36.3 |
33.4 |
40.5 |
|
LiveCodeBench (Pass@1) |
20.3 |
28.4 |
28.7 |
30.1 |
32.8 |
34.2 |
37.6 |
|
Codeforces (Percentile) |
17.5 |
35.6 |
24.8 |
25.3 |
20.3 |
23.6 |
51.6 |
|
SWE Verified (Resolved) |
- |
22.6 |
23.8 |
24.5 |
50.8 |
38.8 |
42.0 |
|
Aider-Edit (Acc.) |
60.3 |
71.6 |
65.4 |
63.9 |
84.2 |
72.9 |
79.7 |
|
Aider-Polyglot (Acc.) |
- |
18.2 |
7.6 |
5.8 |
45.3 |
16.0 |
49.6 |
| Math |
AIME 2024 (Pass@1) |
4.6 |
16.7 |
23.3 |
23.3 |
16.0 |
9.3 |
39.2 |
|
MATH-500 (EM) |
56.3 |
74.7 |
80.0 |
73.8 |
78.3 |
74.6 |
90.2 |
|
CNMO 2024 (Pass@1) |
2.8 |
10.8 |
15.9 |
6.8 |
13.1 |
10.8 |
43.2 |
| Chinese |
CLUEWSC (EM) |
89.9 |
90.4 |
91.4 |
84.7 |
85.4 |
87.9 |
90.9 |
|
C-Eval (EM) |
78.6 |
79.5 |
86.1 |
61.5 |
76.7 |
76.0 |
86.5 |
|
C-SimpleQA (Correct) |
48.5 |
54.1 |
48.4 |
50.4 |
51.3 |
59.3 |
64.8 |
[!NOTE]
All models are evaluated in a configuration that limits the output length to 8K. Benchmarks containing fewer than 1000 samples are tested multiple times using varying temperature settings to derive robust final results. DeepSeek-V3 stands as the best-performing open-source model, and also exhibits competitive performance against frontier closed-source models.
Open Ended Generation Evaluation
| Model |
Arena-Hard |
AlpacaEval 2.0 |
| DeepSeek-V2.5-0905 |
76.2 |
50.5 |
| Qwen2.5-72B-Instruct |
81.2 |
49.1 |
| LLaMA-3.1 405B |
69.3 |
40.5 |
| GPT-4o-0513 |
80.4 |
51.1 |
| Claude-Sonnet-3.5-1022 |
85.2 |
52.0 |
| DeepSeek-V3 |
85.5 |
70.0 |
[!NOTE]
English open-ended conversation evaluations. For AlpacaEval 2.0, we use the length-controlled win rate as the metric.
You can chat with DeepSeek-V3 on DeepSeek's official website: chat.deepseek.com
We also provide OpenAI-Compatible API at DeepSeek Platform: platform.deepseek.com
6. How to Run Locally
DeepSeek-V3 can be deployed locally using the following hardware and open-source community software:
- DeepSeek-Infer Demo: We provide a simple and lightweight demo for FP8 and BF16 inference.
- SGLang: Fully support the DeepSeek-V3 model in both BF16 and FP8 inference modes, with Multi-Token Prediction coming soon.
- LMDeploy: Enables efficient FP8 and BF16 inference for local and cloud deployment.
- TensorRT-LLM: Currently supports BF16 inference and INT4/8 quantization, with FP8 support coming soon.
- vLLM: Support DeepSeek-V3 model with FP8 and BF16 modes for tensor parallelism and pipeline parallelism.
- LightLLM: Supports efficient single-node or multi-node deployment for FP8 and BF16.
- AMD GPU: Enables running the DeepSeek-V3 model on AMD GPUs via SGLang in both BF16 and FP8 modes.
- Huawei Ascend NPU: Supports running DeepSeek-V3 on Huawei Ascend devices in both INT8 and BF16.
Since FP8 training is natively adopted in our framework, we only provide FP8 weights. If you require BF16 weights for experimentation, you can use the provided conversion script to perform the transformation.
Here is an example of converting FP8 weights to BF16:
cd inference
python fp8_cast_bf16.py --input-fp8-hf-path /path/to/fp8_weights --output-bf16-hf-path /path/to/bf16_weights
[!NOTE]
Hugging Face's Transformers has not been directly supported yet.
6.1 Inference with DeepSeek-Infer Demo (example only)
System Requirements
[!NOTE]
Linux with Python 3.10 only. Mac and Windows are not supported.
Dependencies:
torch==2.4.1
triton==3.0.0
transformers==4.46.3
safetensors==0.4.5
Model Weights & Demo Code Preparation
First, clone our DeepSeek-V3 GitHub repository:
git clone https://github.com/deepseek-ai/DeepSeek-V3.git
Navigate to the inference folder and install dependencies listed in requirements.txt. Easiest way is to use a package manager like conda or uv to create a new virtual environment and install the dependencies.
cd DeepSeek-V3/inference
pip install -r requirements.txt
Download the model weights from Hugging Face, and put them into /path/to/DeepSeek-V3 folder.
Model Weights Conversion
Convert Hugging Face model weights to a specific format:
python convert.py --hf-ckpt-path /path/to/DeepSeek-V3 --save-path /path/to/DeepSeek-V3-Demo --n-experts 256 --model-parallel 16
Run
Then you can chat with DeepSeek-V3:
torchrun --nnodes 2 --nproc-per-node 8 --node-rank $RANK --master-addr $ADDR generate.py --ckpt-path /path/to/DeepSeek-V3-Demo --config configs/config_671B.json --interactive --temperature 0.7 --max-new-tokens 200
Or batch inference on a given file:
torchrun --nnodes 2 --nproc-per-node 8 --node-rank $RANK --master-addr $ADDR generate.py --ckpt-path /path/to/DeepSeek-V3-Demo --config configs/config_671B.json --input-file $FILE
6.2 Inference with SGLang (recommended)
SGLang currently supports MLA optimizations, DP Attention, FP8 (W8A8), FP8 KV Cache, and Torch Compile, delivering state-of-the-art latency and throughput performance among open-source frameworks.
Notably, SGLang v0.4.1 fully supports running DeepSeek-V3 on both NVIDIA and AMD GPUs, making it a highly versatile and robust solution.
SGLang also supports multi-node tensor parallelism, enabling you to run this model on multiple network-connected machines.
Multi-Token Prediction (MTP) is in development, and progress can be tracked in the optimization plan.
Here are the launch instructions from the SGLang team: https://github.com/sgl-project/sglang/tree/main/benchmark/deepseek_v3
6.3 Inference with LMDeploy (recommended)
LMDeploy, a flexible and high-performance inference and serving framework tailored for large language models, now supports DeepSeek-V3. It offers both offline pipeline processing and online deployment capabilities, seamlessly integrating with PyTorch-based workflows.
For comprehensive step-by-step instructions on running DeepSeek-V3 with LMDeploy, please refer to here: https://github.com/InternLM/lmdeploy/issues/2960
6.4 Inference with TRT-LLM (recommended)
TensorRT-LLM now supports the DeepSeek-V3 model, offering precision options such as BF16 and INT4/INT8 weight-only. Support for FP8 is currently in progress and will be released soon. You can access the custom branch of TRTLLM specifically for DeepSeek-V3 support through the following link to experience the new features directly: https://github.com/NVIDIA/TensorRT-LLM/tree/main/examples/deepseek_v3.
6.5 Inference with vLLM (recommended)
vLLM v0.6.6 supports DeepSeek-V3 inference for FP8 and BF16 modes on both NVIDIA and AMD GPUs. Aside from standard techniques, vLLM offers pipeline parallelism allowing you to run this model on multiple machines connected by networks. For detailed guidance, please refer to the vLLM instructions. Please feel free to follow the enhancement plan as well.
6.6 Inference with LightLLM (recommended)
LightLLM v1.0.1 supports single-machine and multi-machine tensor parallel deployment for DeepSeek-R1 (FP8/BF16) and provides mixed-precision deployment, with more quantization modes continuously integrated. For more details, please refer to LightLLM instructions. Additionally, LightLLM offers PD-disaggregation deployment for DeepSeek-V2, and the implementation of PD-disaggregation for DeepSeek-V3 is in development.
6.7 Recommended Inference Functionality with AMD GPUs
In collaboration with the AMD team, we have achieved Day-One support for AMD GPUs using SGLang, with full compatibility for both FP8 and BF16 precision. For detailed guidance, please refer to the SGLang instructions.
6.8 Recommended Inference Functionality with Huawei Ascend NPUs
The MindIE framework from the Huawei Ascend community has s


 DeepSeek-V3 — это языковая модель с открытыми весами и архитектурой Mixture-of-Experts (MoE): в ней 671 млрд параметров, но на каждый токен активируется только 37 млрд. Модель создана для эффективного и при этом высокопроизводительного инференса и на многих тестах сопоставима с ведущими закрытыми моделями.