
Что это такое?
 Strata запускает Qwen3.8-Flash-Next, ИИ-модель на 125 миллиардов параметров, на обычном игровом ПК с одной видеокартой NVIDIA (12–24 ГБ видеопамяти) и 64 ГБ оперативной памяти. Есть установщик в один клик для Windows и Linux.
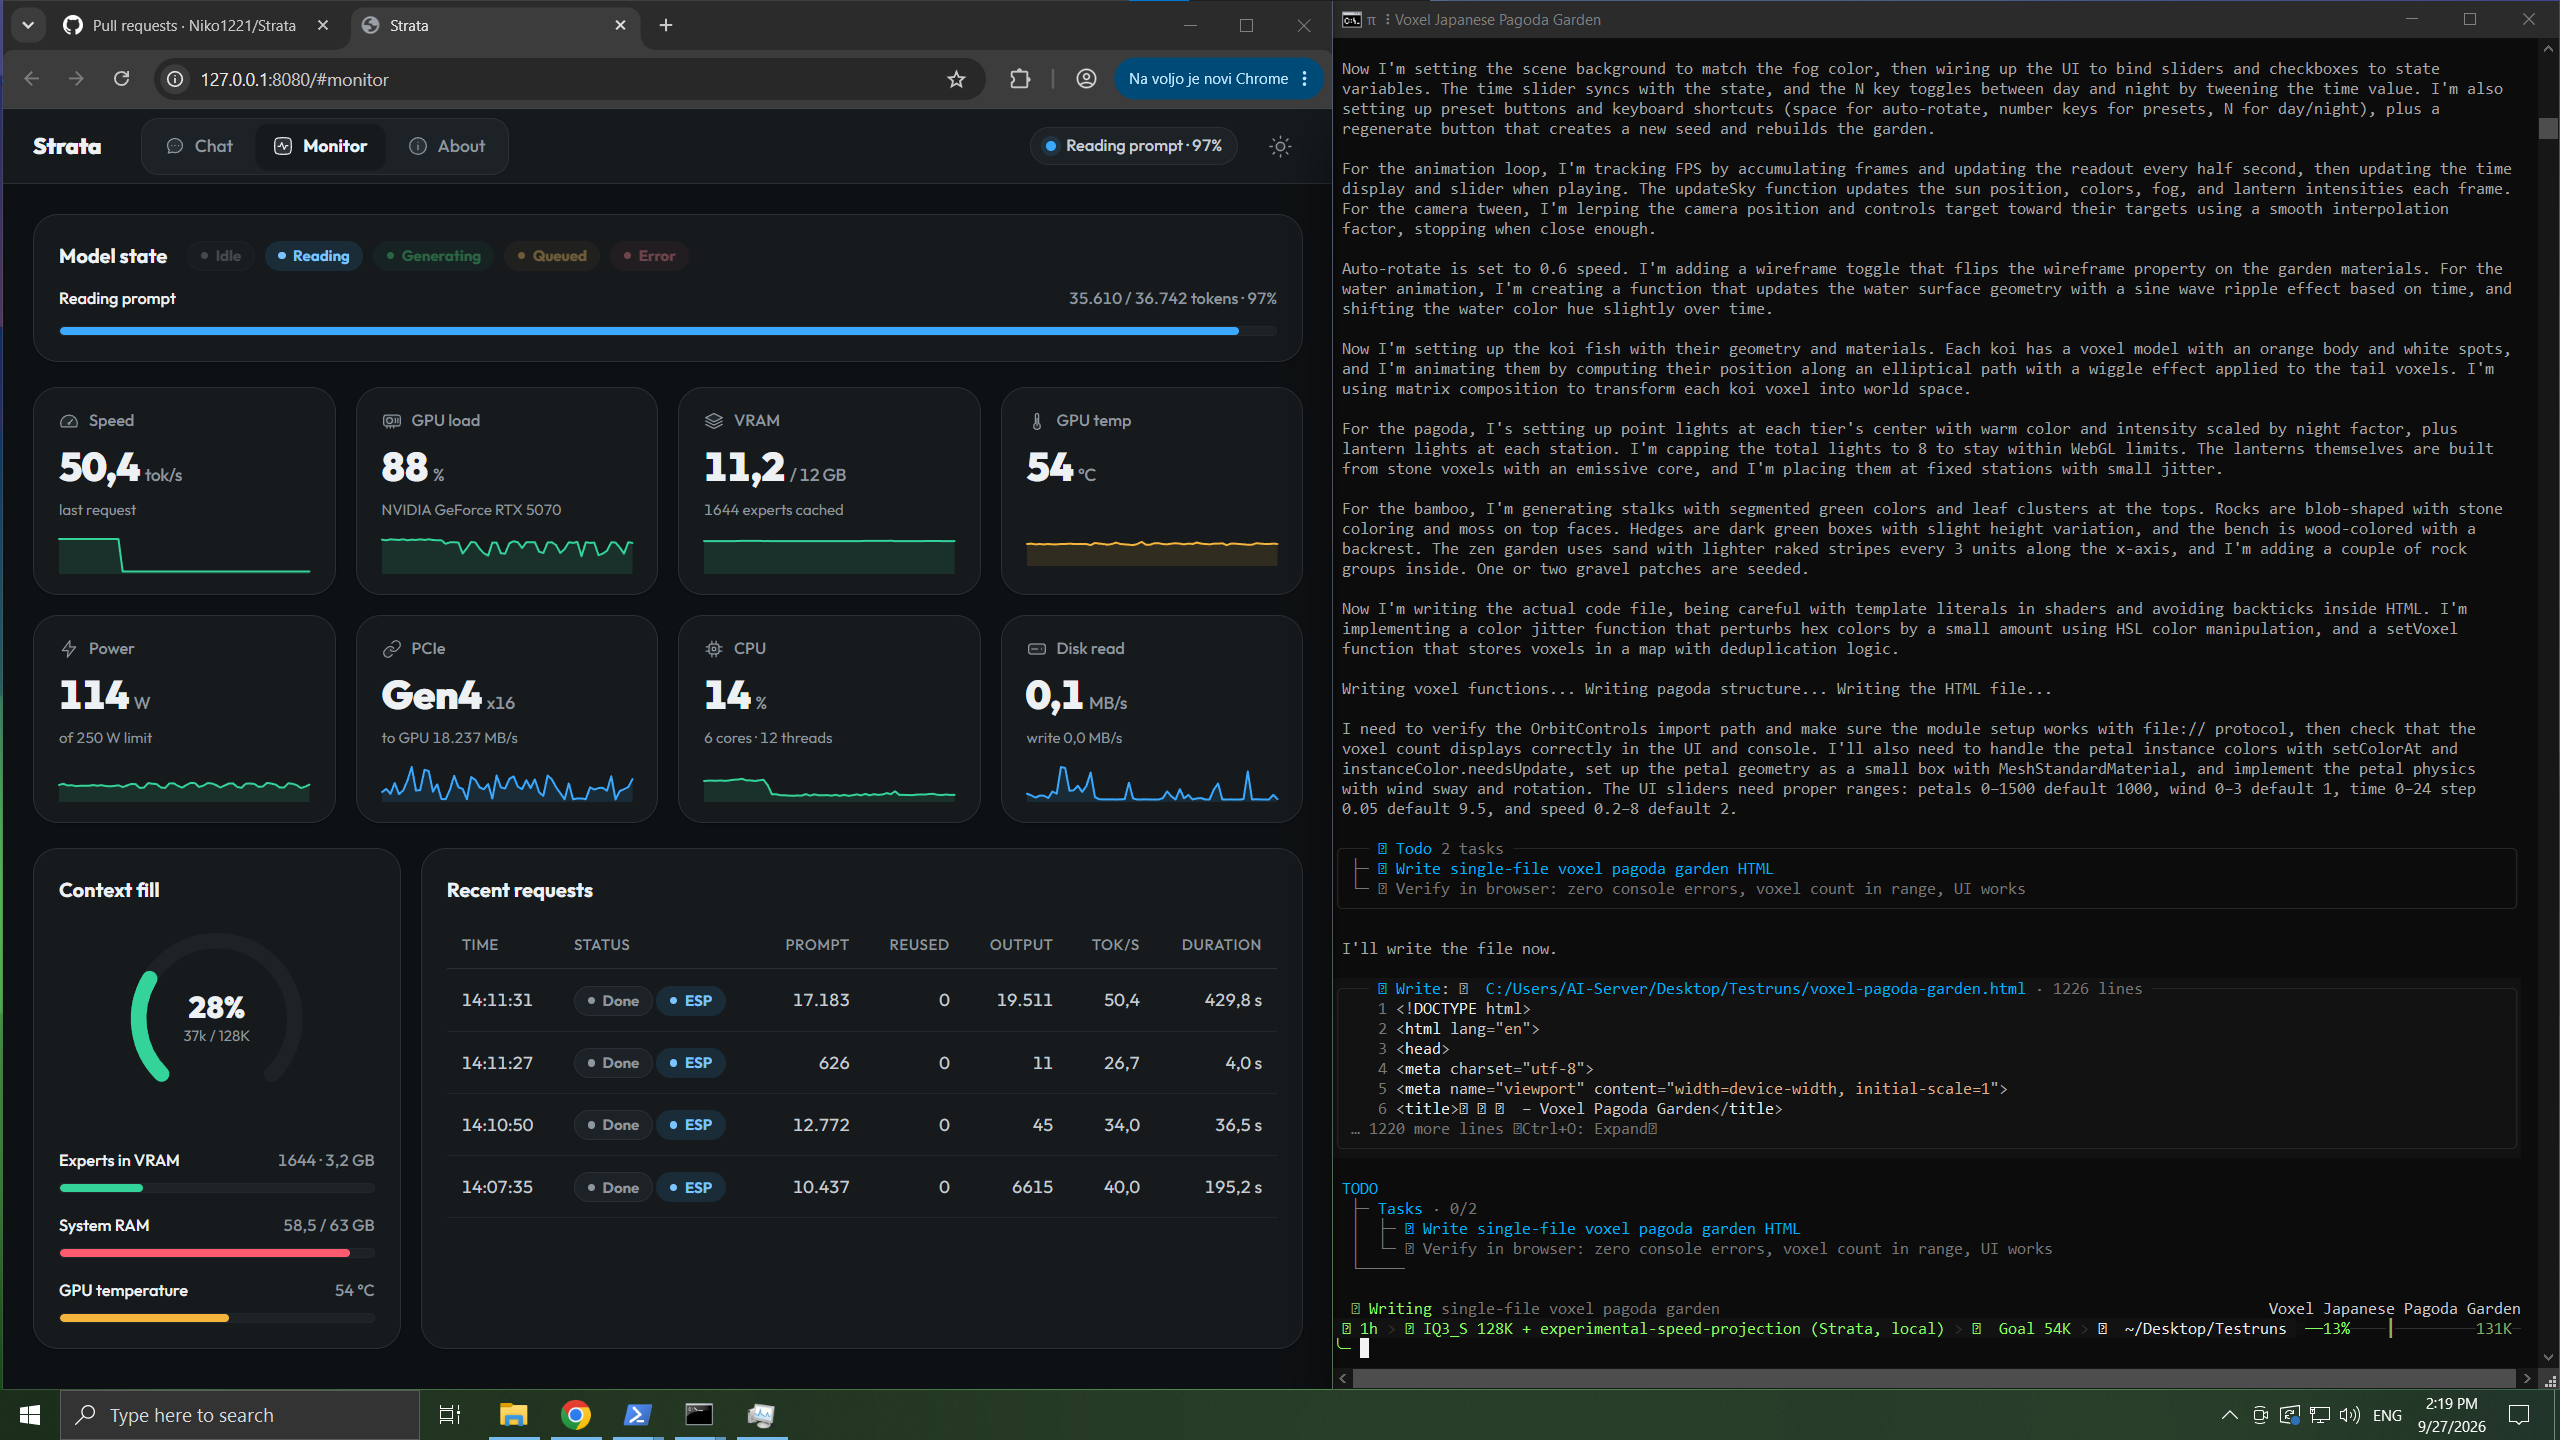
Это приложение или просто движок инференса?И то, и другое: локальный движок инференса на основе llama.cpp/ggml, а также работающее в браузере приложение Strata с чатом, монитором загрузки GPU/CPU/RAM, терминальным клиентом (chat.py) и API-сервером, совместимым с OpenAI и Anthropic.
И то, и другое: локальный движок инференса на основе llama.cpp/ggml, а также работающее в браузере приложение Strata с чатом, монитором загрузки GPU/CPU/RAM, терминальным клиентом (chat.py) и API-сервером, совместимым с OpenAI и Anthropic.Как установить и запустить?В Windows скачайте и распакуйте проект, затем дважды щёлкните START-HERE.bat; в Linux запустите ./setup.sh. Программа задаст несколько вопросов о настройке (модель, размер, длина контекста, поддержка изображений), после чего всё скачает и автоматически откроет приложение Strata в браузере.
В Windows скачайте и распакуйте проект, затем дважды щёлкните START-HERE.bat; в Linux запустите ./setup.sh. Программа задаст несколько вопросов о настройке (модель, размер, длина контекста, поддержка изображений), после чего всё скачает и автоматически откроет приложение Strata в браузере.Какое железо нужно?Видеокарта NVIDIA серии RTX 30, 40 или 50 с 12 ГБ и более видеопамяти, достаточно оперативной памяти для выбранного размера модели (до 64 ГБ для самой большой), около 80 ГБ свободного места на диске и Windows 10/11 или Linux. Самостоятельно нужно установить только драйвер NVIDIA.
Видеокарта NVIDIA серии RTX 30, 40 или 50 с 12 ГБ и более видеопамяти, достаточно оперативной памяти для выбранного размера модели (до 64 ГБ для самой большой), около 80 ГБ свободного места на диске и Windows 10/11 или Linux. Самостоятельно нужно установить только драйвер NVIDIA.Работает ли всё гладко сразу после установки?Первый запуск может на 1–3 минуты замедлить или подвесить ПК, пока в оперативную память загружаются 35–55 ГБ. Первая загрузка модели занимает около 70 ГБ. Если оперативной памяти не хватает, движок может прерваться посреди ответа: просто отправьте сообщение повторно, и он перезапустится.
Первый запуск может на 1–3 минуты замедлить или подвесить ПК, пока в оперативную память загружаются 35–55 ГБ. Первая загрузка модели занимает около 70 ГБ. Если оперативной памяти не хватает, движок может прерваться посреди ответа: просто отправьте сообщение повторно, и он перезапустится.Обязательно нужна карта NVIDIA или будут работать AMD и Intel?Поддерживаются только видеокарты NVIDIA серий RTX 30, 40 и 50 с минимум 12 ГБ видеопамяти. О поддержке GPU от AMD или Intel не упоминается.
Поддерживаются только видеокарты NVIDIA серий RTX 30, 40 и 50 с минимум 12 ГБ видеопамяти. О поддержке GPU от AMD или Intel не упоминается.Чем отличаются базовая модель, Coder и версия Swift 1.5?Базовая Qwen3.8-Flash-Next это полная модель. Coder убирает половину экспертов, чтобы сосредоточиться на программировании, использовании инструментов и изображениях, и занимает меньше оперативной памяти. Swift 1.5 это дообученная версия, которая думает перед ответом меньше времени, при той же скорости и расходе памяти, что и оригинал.
Базовая Qwen3.8-Flash-Next это полная модель. Coder убирает половину экспертов, чтобы сосредоточиться на программировании, использовании инструментов и изображениях, и занимает меньше оперативной памяти. Swift 1.5 это дообученная версия, которая думает перед ответом меньше времени, при той же скорости и расходе памяти, что и оригинал.Она умеет работать с изображениями, а не только с текстом?Да, ввод изображений это необязательная настройка, которую выбирают при установке. Картинки можно прикреплять на странице чата или командой /image в chat.py.
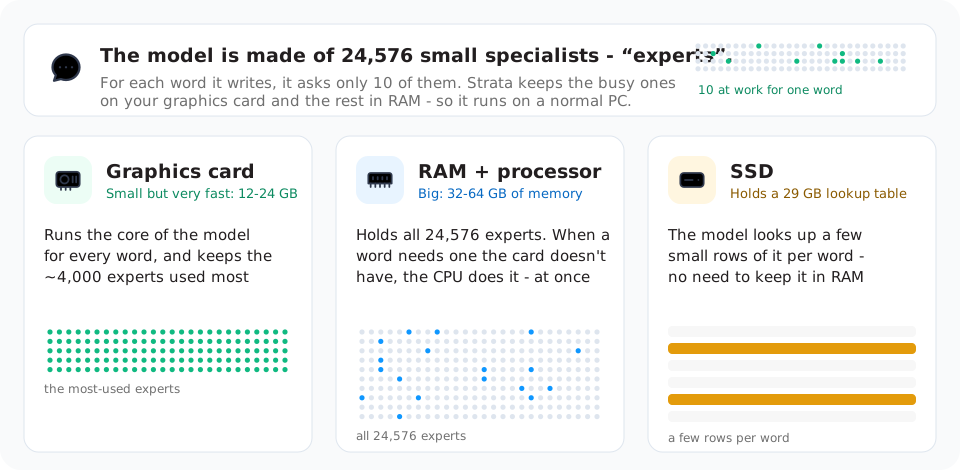
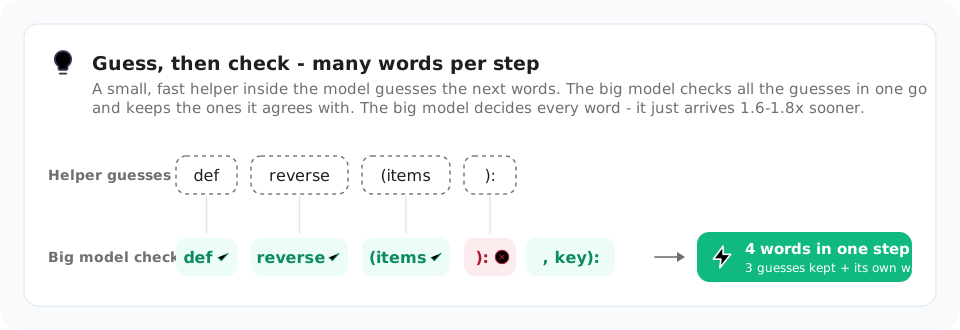
Да, ввод изображений это необязательная настройка, которую выбирают при установке. Картинки можно прикреплять на странице чата или командой /image в chat.py.Почему она так быстро работает для такой огромной модели?Она активирует лишь 10 из 24 576 экспертов на каждое слово, распределяет работу между GPU, оперативной памятью и SSD и использует спекулятивное декодирование: небольшая вспомогательная модель угадывает сразу несколько слов вперёд, а большая модель проверяет их за один раз. Это даёт ускорение в 1,6–1,8 раза.
Она активирует лишь 10 из 24 576 экспертов на каждое слово, распределяет работу между GPU, оперативной памятью и SSD и использует спекулятивное декодирование: небольшая вспомогательная модель угадывает сразу несколько слов вперёд, а большая модель проверяет их за один раз. Это даёт ускорение в 1,6–1,8 раза.Можно ли пользоваться Strata с телефона или с другого ПК?Да. Запуск START-HERE.bat с параметрами --setup --host 0.0.0.0 и API-ключом открывает сервер для вашей локальной сети, чтобы к нему могли подключаться другие устройства.
Да. Запуск START-HERE.bat с параметрами --setup --host 0.0.0.0 и API-ключом открывает сервер для вашей локальной сети, чтобы к нему могли подключаться другие устройства.What are similar projects?project-maya, deltafin, StartLux-Decision, vllm, decider, dgx-spark-qwen38, slotstream, qwen3.8-Flash-DGX
project-maya, deltafin, StartLux-Decision, vllm, decider, dgx-spark-qwen38, slotstream, qwen3.8-Flash-DGXWhich topics is it in?llama-cpp, speculative-decoding, inference-engine, mixture-of-experts, moe, gguf, local-ai, llm-inference, qwen, multimodal, quantization, large-language-models
llama-cpp, speculative-decoding, inference-engine, mixture-of-experts, moe, gguf, local-ai, llm-inference, qwen, multimodal, quantization, large-language-models