Your coding agent remembers everything. No more re-explaining.
Built on iii engine
Persistent memory for Claude Code, GitHub Copilot CLI, Cursor, Gemini CLI, Codex CLI, Hermes, OpenClaw, pi, OpenCode, and any MCP client.
The gist extends Karpathy's LLM Wiki pattern with confidence scoring, lifecycle, knowledge graphs, and hybrid search: agentmemory is the implementation.
Node.js 20 or newer with npm and npx (node -v, npm -v, and npx -v).
macOS/Linux automatic iii-engine installation also needs curl, a POSIX sh, and tar. Minimal images such as node:20-slim may not include them.
Native Windows requires the pinned iii-engine v0.11.2 iii.exe to be installed manually. WSL2 or Docker Desktop are the other supported paths.
Canonical fresh-install command:
npx -y @agentmemory/agentmemory@latest
The first run is an interactive setup: pick the agents to wire (Claude Code, Cursor, Codex, Gemini CLI, OpenCode, ...), pick an LLM provider or stay keyless, and it seeds the config, starts the memory server and its pinned iii engine, and offers to install globally so the bare agentmemory command works everywhere afterward. -y accepts npx's package prompt and @latest avoids a stale cached release. A provider makes LLM features available, but LLM-written observation compression starts only when AGENTMEMORY_AUTO_COMPRESS=true is also set.
Keyless mode disables vector embeddings. memory_recall (the mem::search path) uses BM25, while memory_smart_search can also fuse structural graph matches when graph data already exists. For free on-device semantic recall, set EMBEDDING_PROVIDER=local in ~/.agentmemory/.env and restart. The first embedding request downloads Xenova/all-MiniLM-L6-v2; inference runs locally after that initial model download.
The local runtime uses four ports: 3111 for REST/MCP HTTP, 3112 for iii streams, 3113 for the viewer, and 49134 for the iii worker WebSocket. Persistent iii state lives in ~/Library/Application Support/agentmemory on macOS, $XDG_DATA_HOME/agentmemory or ~/.local/share/agentmemory on Linux, and %APPDATA%\agentmemory on Windows. Use --data-dir <path> or AGENTMEMORY_DATA_DIR to override it, and reuse the same value on every restart. For backward compatibility, an existing ./data/state_store.db or ./data/iii-config.yaml takes precedence over the platform default for instance 0; an explicit flag or environment override still wins.
Then prove recall works and give your agent its skills:
npx -y @agentmemory/agentmemory@latest demo  # seed sample sessions + exercise recall
npx skills add rohitg00/agentmemory -y   # 17 native skills so your agent knows when to reach for memory
The keyword searches should hit in default keyless mode through BM25. The demo's database performance optimization query is intentionally semantic and can return zero until an embedding provider is configured.
Prefer to let a coding agent do the whole thing? Hand it one instruction:
Wire more agents any time with agentmemory connect <agent> — 20 adapters listed at Works with every agent. Full command reference at Quick Start.
Windows
The fast path is WSL2. Native Windows engine setup requires the pinned v0.11.2 ZIP to be downloaded and iii.exe extracted manually; the CLI does not auto-extract it. Docker Desktop is also supported. See the Windows notes for the step-by-step.
Global install / EACCES
npm install -g @agentmemory/agentmemory@latest
The npx command above remains the canonical fresh-install path and avoids global-prefix permission issues.
npx serves an old version
npx caches per version. Force the latest with npx -y @agentmemory/agentmemory@latest, or clear the cache once with rm -rf ~/.npm/_npx (macOS/Linux; on Windows delete %LOCALAPPDATA%\npm-cache\_npx).
Already running your own iii engine
agentmemory pins iii-engine v0.11.2 and won't attach to a different version (the worker can't speak another engine's protocol). Stop the other engine, then run npx -y @agentmemory/agentmemory@latest. It installs and runs the pinned v0.11.2 in ~/.agentmemory/bin, leaving your own iii untouched.
agentmemory works with any agent that supports hooks, MCP, or REST API. All agents share the same memory server.
Claude Code native plugin + 12 hooks + MCP
Codex CLI native plugin + 6 hooks + MCP
GitHub Copilot CLI MCP + plugin hooks/skills
OpenClaw native plugin + MCP
Hermes native plugin + MCP
pi native plugin + MCP
OpenHuman native Memory trait backend
Cursor native plugin + MCP
Gemini CLI MCP server
OpenCode 22 hooks + MCP + plugin
Cline MCP server
Goose MCP server
Kilo Code MCP server
Aider REST API
Claude Desktop MCP server
Devin 6 hooks + MCP
Roo Code MCP server
Warp connect + MCP + skills
Works with any agent that speaks MCP or HTTP. One server, memories shared across all of them.
You explain the same architecture every session. You re-discover the same bugs. You re-teach the same preferences. Built-in memory (CLAUDE.md, .cursorrules) caps out at 200 lines and goes stale. agentmemory fixes this. It silently captures what your agent does, compresses it into searchable memory, and injects the right context when the next session starts. One command. Works across agents.
What changes: Session 1 you set up JWT auth. Session 2 you ask for rate limiting. The agent already knows your auth uses jose middleware in src/middleware/auth.ts, your tests cover token validation, and you chose jose over jsonwebtoken for Edge compatibility, with no re-explaining and no copy-pasting.
npx -y @agentmemory/agentmemory@latest
By default, agentmemory stores iii-engine state outside the repository you start it from: ~/Library/Application Support/agentmemory on macOS, $XDG_DATA_HOME/agentmemory or ~/.local/share/agentmemory on Linux, and %APPDATA%\agentmemory on Windows. An existing legacy ./data/state_store.db or ./data/iii-config.yaml is reused for instance 0 before that platform default. To choose a location explicitly, pass --data-dir <path> or set AGENTMEMORY_DATA_DIR; either explicit setting takes precedence over legacy discovery:
Native and Docker launches use this same resolved host directory; Docker bind-mounts it at /data. --instance 1 appends instance-1 to the resolved directory and selects the separate default port quartet 3211/3212/3213/49234.
100% top-5 hit rate at the P@5 math ceiling for this corpus (0.240, see scorecard). Hybrid retrieves every gold session; grep misses 1 of 2 gold on the multi-session temporal query. Lift is recall + temporal, not aggregate precision. This benchmark is small and gold-sparse; the larger LongMemEval-S below differentiates better. Full per-type breakdown + correction note: docs/benchmarks/2026-05-20-coding-agent-life-v1.md.
Reproduce locally:eval/README.md, an adapter-pluggable harness for LongMemEval _s (public 500-Q) + coding-agent-life-v1 (in-house 15-session corpus). Grep / vector / agentmemory adapters score side-by-side, NDJSON output, published scorecards land in docs/benchmarks/.
Pairs with codegraph, Understand Anything, and Graphify. Code-graph indexing, multi-agent build pipelines, and broader knowledge graphs across docs / PDFs / images / videos. agentmemory remembers the work; those three projects light up the rest of the context layer. Recipes + question-routing table: docs/recipes/pairings.md.
agentmemory
mem0 (63K ⭐)
Letta / MemGPT (24K ⭐)
Khoj (36K ⭐)
supermemory (29K ⭐)
TencentDB Agent Memory (22K ⭐)
MemPalace (54K ⭐)
oracleagentmemory
Hippo
Built-in (CLAUDE.md)
Type
Memory engine + MCP server
Memory layer API
Full agent runtime
Personal AI
Memory API + app
Team memory hub (LLM proxy)
Vector memory (OSS)
Memory engine (Oracle DB)
Memory system
Static file
Retrieval R@5
95.2%
68.5% (LoCoMo)
83.2% (LoCoMo)
N/A
Self-reported
PersonaMem 76% (self-reported)
~96.6% (self-reported)
94.4% (self-reported)
N/A
N/A (grep)
Auto-capture
12 hooks (zero manual effort)
Manual add() calls
Agent self-edits
Manual
API-side extraction
Proxy interception (base-URL swap)
Manual
API extraction
Manual
Manual editing
t
agentmemory (rohitg00/agentmemory)
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
Searching Database…
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.


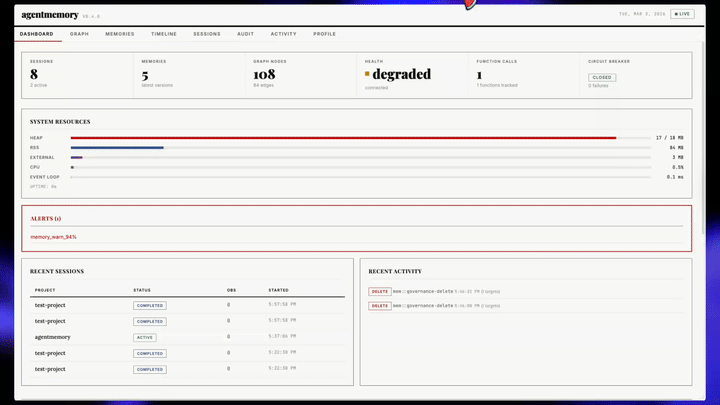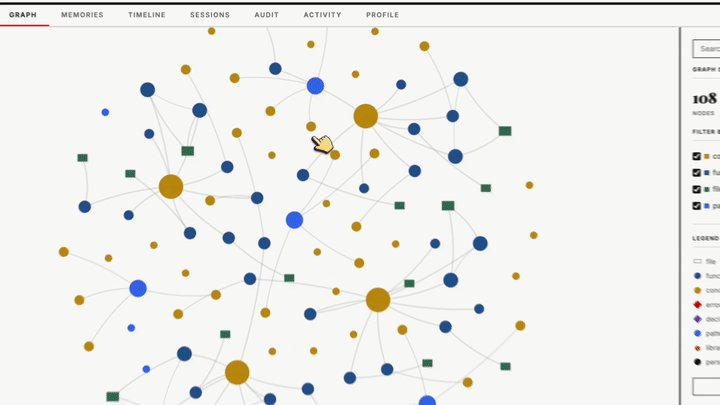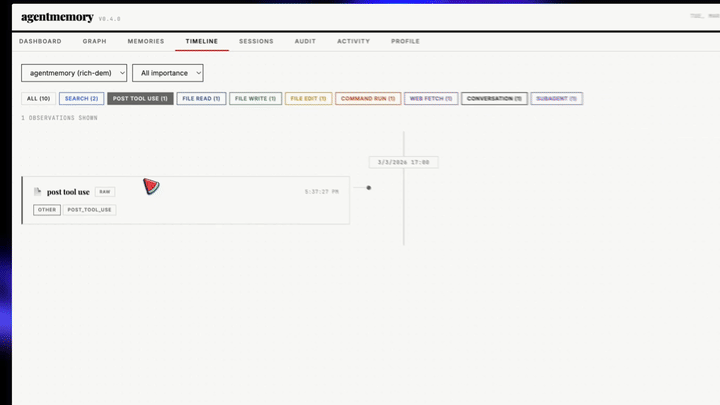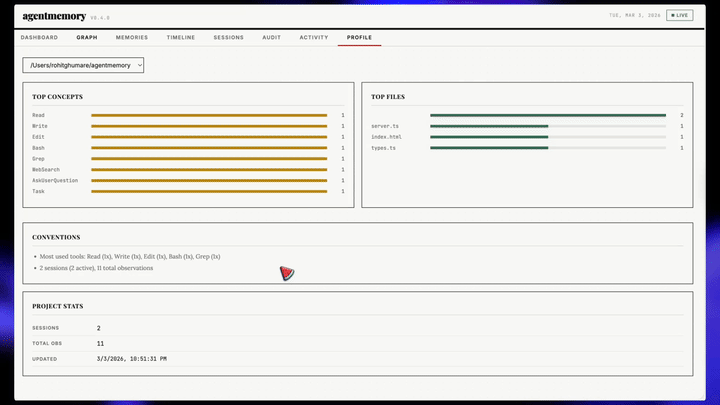










 为 AI 编程智能体提供持久记忆:它会记录你的智能体做过什么,压缩成可搜索的记忆,并在下一次会话开始时注入合适的上下文,这样你就不用再向 Claude Code、Cursor 或 Codex 反复解释你的项目了。