laya-coreml README

The project's README from github.com/mizorewww/laya-coreml. As one markdown file: README.md.

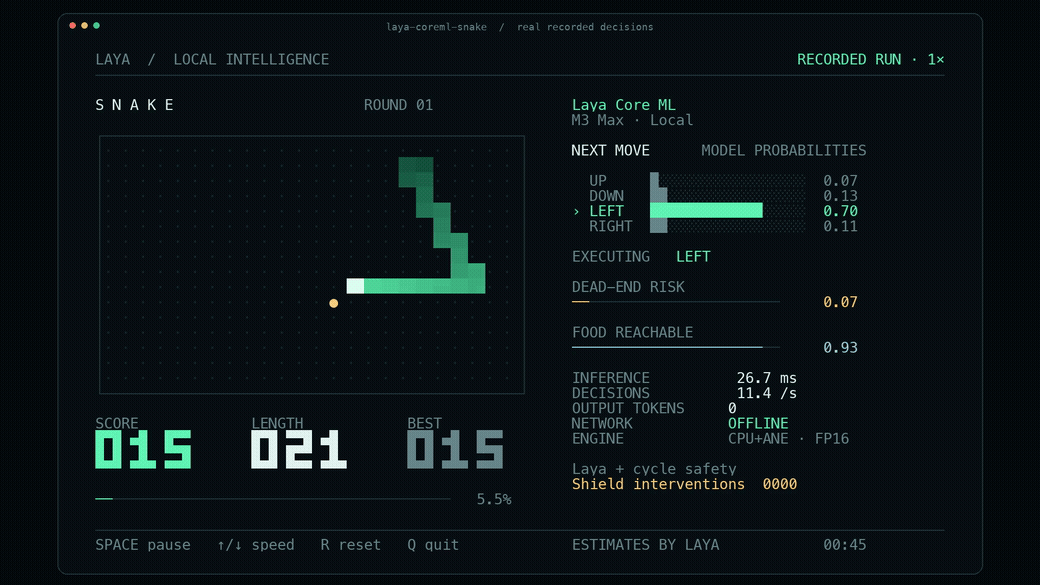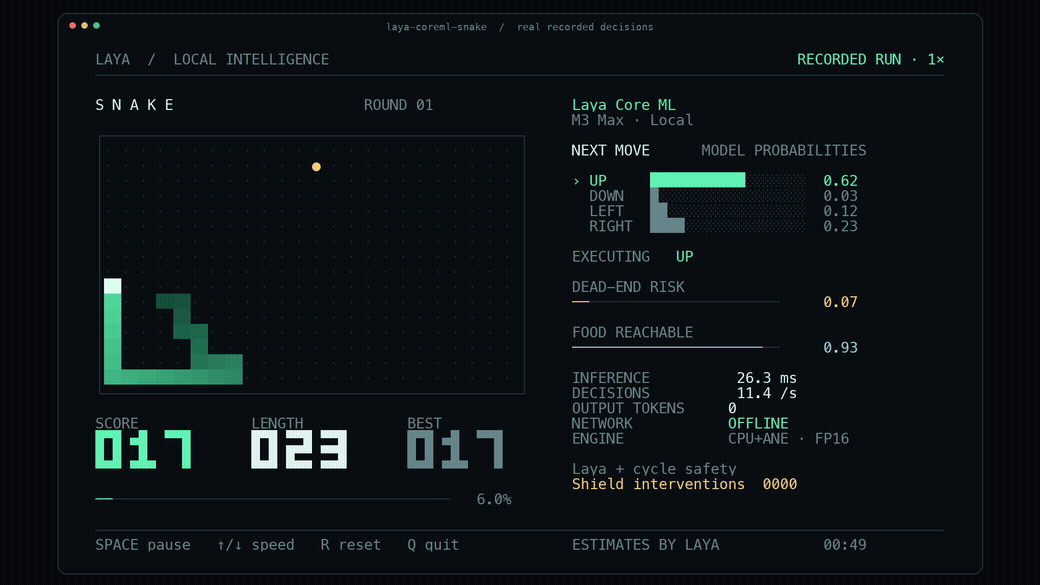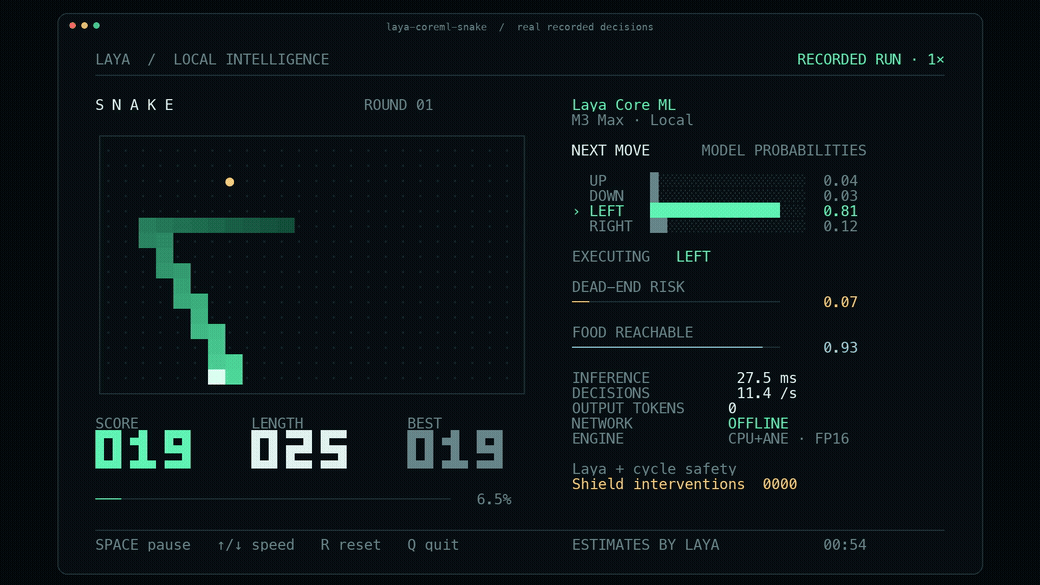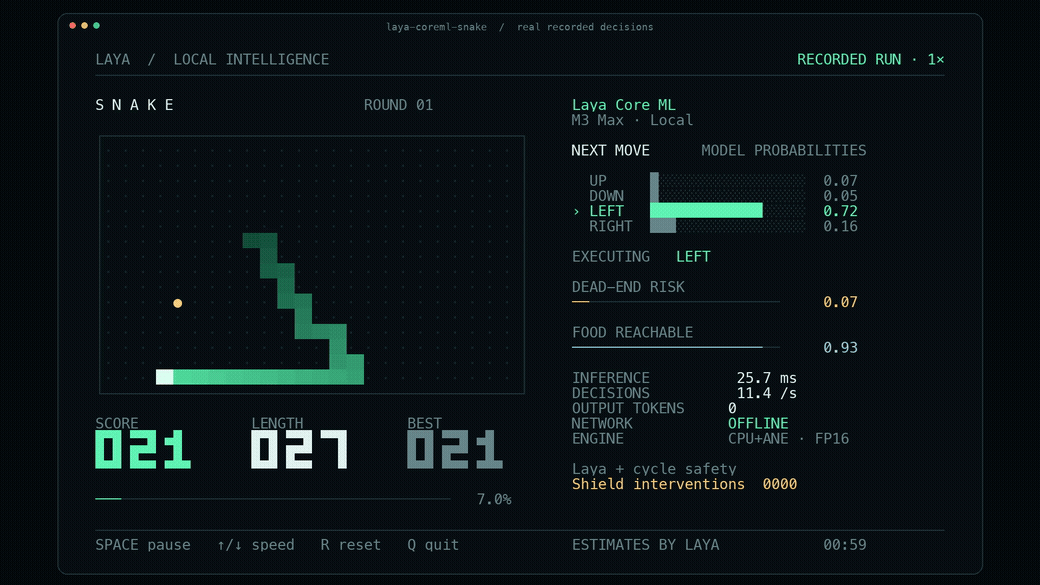
Laya Core ML playing Snake with real local model probabilities

Version 0.4.0 aligns the host inference contract directly with official Laya v0.4.1 (1adc59f), replacing the earlier selective port. Batch/long-text prediction, hooks, structured decisions, calibration, HTTP/MCP, evaluation and Router behavior now share the official host semantics. See the migration guide for changed defaults, validation evidence and the remaining Core ML boundaries.

Laya-CoreML

Open-weight typed decisions on Apple Silicon. Core ML, Neural Engine, zero generated tokens.

PyPI · Hugging Face weights · 中文

A real Laya model plays Snake locally, with visible probabilities, score, length, latency and safety interventions. The GIF replays a recorded Core ML run at 1× speed. The game uses explicit planner features and a visible cycle safety layer.

The complete active Snake loop sustained 49.1–50.0 decisions/s across three uncapped 600-step episodes, with zero deaths and two safety interventions. Game-loop timings and paced-rate limits include rendering serialization; terminal painting is excluded.

One short multilingual decision: 4.98 ms P50 / 5.31 ms P95 on M3 Max with ANE FP16. The same experiment measured 2.78× better whole-system energy per decision than compiled MLX FP16. A separately validated W8 palette variant reached 4.88 ms and 3.19× energy improvement. These are single-question results, not full Snake frame times; the requested 10× improvement was not achieved.

Run the demo

Apple Silicon · macOS 15+ · Python 3.11–3.13.

pip install 'laya-coreml[demo]'
hf download aac6fef/laya-multilingual-coreml-ane --local-dir models/snake
laya-coreml-snake --model ./models/snake

Download once, then play offline. No PyTorch, Transformers or MLX is needed for inference. The terminal needs 104 columns × 35 rows. Space pauses; ↑/↓ changes speed; R resets; Q quits. First-time Core ML initialization can take tens of seconds.

Controls, recording and video export · Measured stable decision rates · Shareable video and recording provenance

Ask for a decision

pip install laya-coreml
import laya_coreml as laya

agent = laya.load("aac6fef/laya-multilingual-coreml-ane")
result = agent.predict(
    "The customer requests a refund of a duplicate payment.",
    {
        "refund": {
            "type": "noul",
            "instructions": "Does the customer request a refund?",
        }
    },
)
print(result["answers"]["refund"])

Laya returns probabilities for choice, ordinal score, and boolean noul questions. There is no autoregressive decoding or generated JSON to parse. Hub models download before initialization; subsequent predictions stay local. Pass local_files_only=True to require an existing cache, or load a local directory.

Following upstream v0.3.5, fitted calibration temperatures are clamped to [0.5, 5.0] before use: the shipped choice:11+ bucket is 0.1006, which would sharpen logits ~10x and report a coin flip as near-certainty. The checkpoint's raw values remain available as agent.temperature_raw and agent.temperature_by_options_raw, and a RuntimeWarning names every clamped bucket at load.

The ANE bundle has a 96-token total limit, including question, options and state. State truncation and long-text scanning use that actual budget; oversized question heads or option sets still fail. Use aac6fef/laya-multilingual-coreml for the general-purpose 1024-token model. Full API, model selection and offline usage.

Measured on M3 Max

Performance figures below come from the linked original benchmark runs. Version 0.4.0 validates fidelity; it makes no new throughput or energy claim.

40-core GPU, 128 GiB, macOS 27.2. One 91-token question padded to 96, including prompt preparation, tokenization, arrays, synchronous inference, calibration and formatting. Loading and warmup are excluded. MLX enables compile, prefix caching and shape buckets. Six alternating 20-second blocks per implementation produced 65,598 stable calls.

Metric Compiled MLX FP16 Core ML ANE FP16 Core ML ANE W8
P50 / P95 6.94 / 7.39 ms 4.98 / 5.31 ms 4.88 / 5.23 ms
Mean system power estimate 61.39 W 30.75 W 27.39 W
System energy / decision 0.4288 J 0.1540 J 0.1344 J
Speed gain 1× 1.39× 1.42×
System energy gain 1× 2.78× 3.19×

Energy uses direct SMC PSTR sensor readings, with raw samples and explicit anomaly rejection. This is an estimate with sensor and background-load uncertainty. Speed gain × average power ratio = energy gain; multiplying energy by speed again would double-count time. The W8 variant compresses weights while retaining FP16 compute. It is approximate, and its package-size reduction is not a speed ratio.

Speed, energy and hardware evidence · Raw measurements.

Available checkpoints

Hugging Face bundle Default engine Capacity Purpose
Laya 421M CPU + GPU 512 tokens Original English model
Multilingual 322M CPU + GPU 1024 tokens General multilingual decisions
Typed Decisions 421M CPU + GPU 1024 tokens Original specialized checkpoint
Snake GPU CPU + GPU B3 / L64 Batches the three compact game questions
Multilingual ANE CPU + ANE B1 / L96 Short decisions, FP16
Multilingual ANE W8 CPU + ANE B1 / L96 Optional approximate palette compression

Every bundle includes tokenizer/configuration, model card, provenance, checksums and packaging-time validation. ANE bundles also include the exact original host embedding/action tensors they need. No original training checkout is required.

Port fidelity and limits

The three general-purpose FP16 checkpoints match upstream selected answers on 189/189 validation questions. Each passes 100 repeated calls. ANE FP16 L96 passes 59/59 fitting questions, with maximum calibrated-probability drift 0.002925; W8 passes the same subset with drift 0.014393 under an unchanged 0.02 gate. Six- and four-bit experiments failed that gate and are not published weights. These are conversion-fidelity fixtures, not proof of general task accuracy.

A separately exported FP16 ANE L1024 graph passes the complete 63/63 fixture, but an actual 1024-token request takes about 91.7 ms in its serial screen. The short ANE result does not establish a long-context advantage. A 600-step paired Snake check matches 600/600 actions, with zero deaths and zero shield interventions; the current ANE adapter's three sequential calls do not establish a consistent full-game speedup over compiled MLX.

The ordinary SDPA Core ML export and the ANE graph are different implementations. The ordinary export defaults to CPU+GPU after unrestricted RangeDim GPU shapes failed local fidelity checks. Changing its device setting alone does not reproduce the ANE result. The ANE rewrite uses BC1L activations, 1×1 projections and per-head attention; its plan and a separate Instruments trace support Neural Engine work. CPU still handles input/output boundaries.

Documentation and reproducibility

To export yourself, install laya-coreml[convert] and run laya-coreml convert laya-multilingual models/custom. ANE research conversion, compression and benchmark scripts live in the Git checkout. The inference wheel contains the portable runtime and optional terminal demo.

Apache-2.0. Independent port of Laya, by Convai Innovations and contributors, building on the MLX sibling project. Not an official Convai Innovations or Apple release. See NOTICE.

Official v0.4.1 host compatibility (v0.4.0)

This release ports host behavior directly from upstream 1adc59f to Core ML. Model weights remain separate downloads. The runtime still needs no PyTorch, Transformers, or MLX. Optional temperature fitting, training helpers and conversion use PyTorch. Migration and complete compatibility scope.

import laya_coreml as laya

router = laya.Router(max_loaded=2)
result = router.predict(state, questions, min_confidence=0.7)
router.register("local", "./models/my-coreml-bundle", description="Custom classifier")
result = router.predict(state, questions, model="local")
router.unload("local")
router.unregister("local")

Router() uses the published English, multilingual and typed-decisions Core ML bundles. It defaults to two resident models and to multilingual when the language is undecided. Use Router(default="english") to choose English as the fallback. route() inspects a request without loading weights; explicit model, task, and lang override inference from the input. Automatic typed-workflow detection is opt-in through auto_task_detection=True. Language detection includes the upstream acronym, capitalization and mixed-script fixes.

Pass models={"custom": "./bundle"} at construction, or use register, registered, attach, preload, and unload. Sources are local Core ML bundles or Hub repository IDs. compute_units, revision, and local_files_only are passed to bundle loading. An attached ANE bundle uses its usual CPU+NE default when compute_units is omitted. Resident-model access and status reads remain available during a cold load; duplicate loads share construction. Replacing/unregistering a source waits for its in-flight build, then removes the old resident entry, following official synchronization. Unload drops router references without invalidating agents held by callers or ongoing predictions. Core ML manages native caches; the router collects unreachable Python objects and never deletes cached model files.

Agent, ANEAgent, and Router accept min_confidence=0.7 or a bucket mapping such as {"choice:2": 0.8, "choice:3-5": 0.7, "default": 0.6}. Answers gain abstention, abstention_threshold, and, when below threshold, low_confidence. The gate preserves the answer and does not automatically call a fallback. Shipped confidence values still require held-out calibration for any correctness-probability interpretation.

result = laya.predict_tournament(router, state, questions, group_size=16)
# Optional external embedder: maps a list of strings to an (N, D) numeric array.
result = laya.predict_shortlist(router, state, questions, embed_fn, k=16)

Tournament elimination handles large choice sets without an embedding model. result["tournament"] records finalists, original counts, and rounds. Probabilities and usage describe the final pass only. Choose group_size / shortlist k within the bundle's exported option capacity. shortlist_choice is also available for caller-managed ranking; the Core ML graph does not expose an encoder embedder.

Email helpers (laya_coreml.email.clean_email_body, email_state, email_questions) include English, Portuguese, Spanish and French cleanup, including the French device footer fix. Cleaning is explicit and never silently applied to ordinary input.

Parallel option layout

The converter supports checkpoints trained with "option_layout": "parallel": shared option positions, option-isolating encoder masks, local attention measured in position IDs, and the position-free decision head. Preparation, fixed/enumerated shapes, conversion and runtime use matching position_ids and option_ids inputs. Missing configuration means sequential; unknown layouts and configuration/export mismatches raise an error. Do not switch an existing bundle to parallel by editing its JSON: the graph and trained weights must match the layout.

FP32 and FP16 exports are tested on CPU and CPU+GPU, with varying input lengths and option order, against upstream v0.4.1. Legacy ANE exports have sequential RoPE baked into the graph and reject parallel configurations; use the general convert path for parallel checkpoints. Existing ANE packages receive the shared prompt, gating, routing and decision-helper features without requiring reconversion. No new parallel pretrained weights or parallel ANE acceleration claim is made by this release.

Validation covers all 24 permutations of four options, a sequential sensitivity control, pinned upstream numerical parity, real Core ML export/load execution, registry races, routing and helper semantics. CI runs portable tests on Linux and actual Core ML tests on macOS. Reproduce with:

uv sync --extra convert --extra dev --extra demo --extra publish --extra reference
# Check out upstream 1adc59f into .upstream for reference parity.
uv run --no-sync pytest -q

The three general-purpose bundles match all 189/189 selected answers from the original FP32 golden fixture. The fixed L96 ANE bundle matches all 59/59 questions that fit its capacity (four long questions are excluded). Each bundle passes 100 identical repeated calls: 248/248 agreements and 400 stability calls in total. This measures port fidelity on the fixture, not general task accuracy. See the release validation report.

laya-coreml (mizorewww/laya-coreml)

Searching Database…

Что это такое?Это Python-порт Laya с открытыми весами, который отвечает на вопросы с заданным форматом ответа — выбор варианта, оценка по шкале или да/нет — локально на Mac с Apple Silicon через Core ML и Neural Engine, не генерируя ни одного текстового токена.
То есть это Python-библиотека, которую я использую в коде, или приложение, которое я запускаю?Python-библиотека: установите laya-coreml из PyPI и вызывайте её классы Agent, ANEAgent и Router из своего кода (CLI тоже входит в комплект). Есть опциональная демка в терминале, где модель играет в Snake.
Как его запустить?Выполните pip install laya-coreml на Mac с Apple Silicon (macOS 15+, Python 3.11–3.13); веса модели один раз скачаются с Hugging Face. Для опциональной демки со Snake нужен терминал 104 колонки × 35 строк.
Нужно ли ещё ставить PyTorch или Transformers?Нет. Для инференса не нужны ни PyTorch, ни Transformers, ни MLX — эти тяжёлые фреймворки нужны только для опциональных возможностей вроде подбора temperature, вспомогательных инструментов обучения и конвертации собственных чекпоинтов.
В чём подвох быстрого режима через Neural Engine?В бандлах для ANE запрос ограничен 96 токенами суммарно — вопрос, варианты и состояние — и слишком большие входы не проходят. Длинный текст — это для бандлов CPU+GPU на 1024 токена; экспорт ANE на 1024 токена занимает около 91,7 мс на запрос, так что ANE подходит для коротких решений.
Получается, работает только на Mac?На практике да: инференс идёт через Core ML и Neural Engine, поэтому нужен Mac на Apple Silicon с macOS 15+. Переносимые тесты из репозитория запускаются на Linux CI, но сам инференс через Core ML возможен только на macOS.
Он работает офлайн или отправляет мои вопросы куда-то?После однократной загрузки модели с хаба Hugging Face всё работает полностью офлайн; каждое последующее предсказание остаётся на вашем компьютере. Передайте localfilesonly=True, чтобы разрешить только уже имеющийся кэш.
Лицензия разрешает всё, и это официальный релиз от Apple или Convai?Apache-2.0, так что коммерческое использование возможно. Это независимый неофициальный порт Laya от сообщества (оригинал создан Convai Innovations и контрибьюторами), а не официальный релиз Convai или Apple.
Насколько он быстрый на самом деле?На M3 Max модель ANE FP16 отвечает на короткий вопрос за 4,98 мс P50 / 5,31 мс P95, вариант W8 — за 4,88 мс, против 6,94 мс у скомпилированной MLX FP16. Энергопотребление всей системы на одно решение в 2,78 раза лучше, чем у MLX (3,19 раза с W8). Это цифры для одного вопроса, а не полное время кадра в Snake.
Какие бандлы модели можно скачать с Hugging Face?Шесть: оригинальная английская 421M (контекст 512 токенов), мультиязычная 322M и модель типизированных решений 421M (по 1024 токена), бандл Snake для GPU и два мультиязычных варианта для Neural Engine — FP16 и приближённый W8 palette. В каждом есть токенизатор, конфиг, модельная карточка, контрольные суммы и нужные тензоры.
Порт на Core ML отвечает точно так же, как оригинальная модель?На валидационных фикстурах — да: три универсальные FP16-модели совпали с оригиналом на 189/189 вопросах, каждая также прошла 100 одинаковых повторных вызовов. Вариант ANE FP16 расходится максимум примерно на 0,003 в откалиброванной вероятности, W8 — примерно на 0,014, при пороге 0,02. Это точность на фикстурах, а не доказанная точность на реальных задачах.
Что даёт класс Router?Он держит в памяти несколько бандлов Core ML и направляет каждый запрос в подходящий, по умолчанию выбирая мультиязычный, если язык не определён; route() проверяет запрос, не загружая веса. Ответы могут пропускаться через порог minconfidence (по умолчанию 0,7), помечающий малоуверенные результаты как отказ от ответа, а большие наборы вариантов обрабатываются последовательным отсеиванием по турнирной схеме.
Creator
mizorewww
Size
6.2 MB
Stars
1.6K
Age
30d
Commits · 90 Days
