2.7K ·GitHub
What is this?
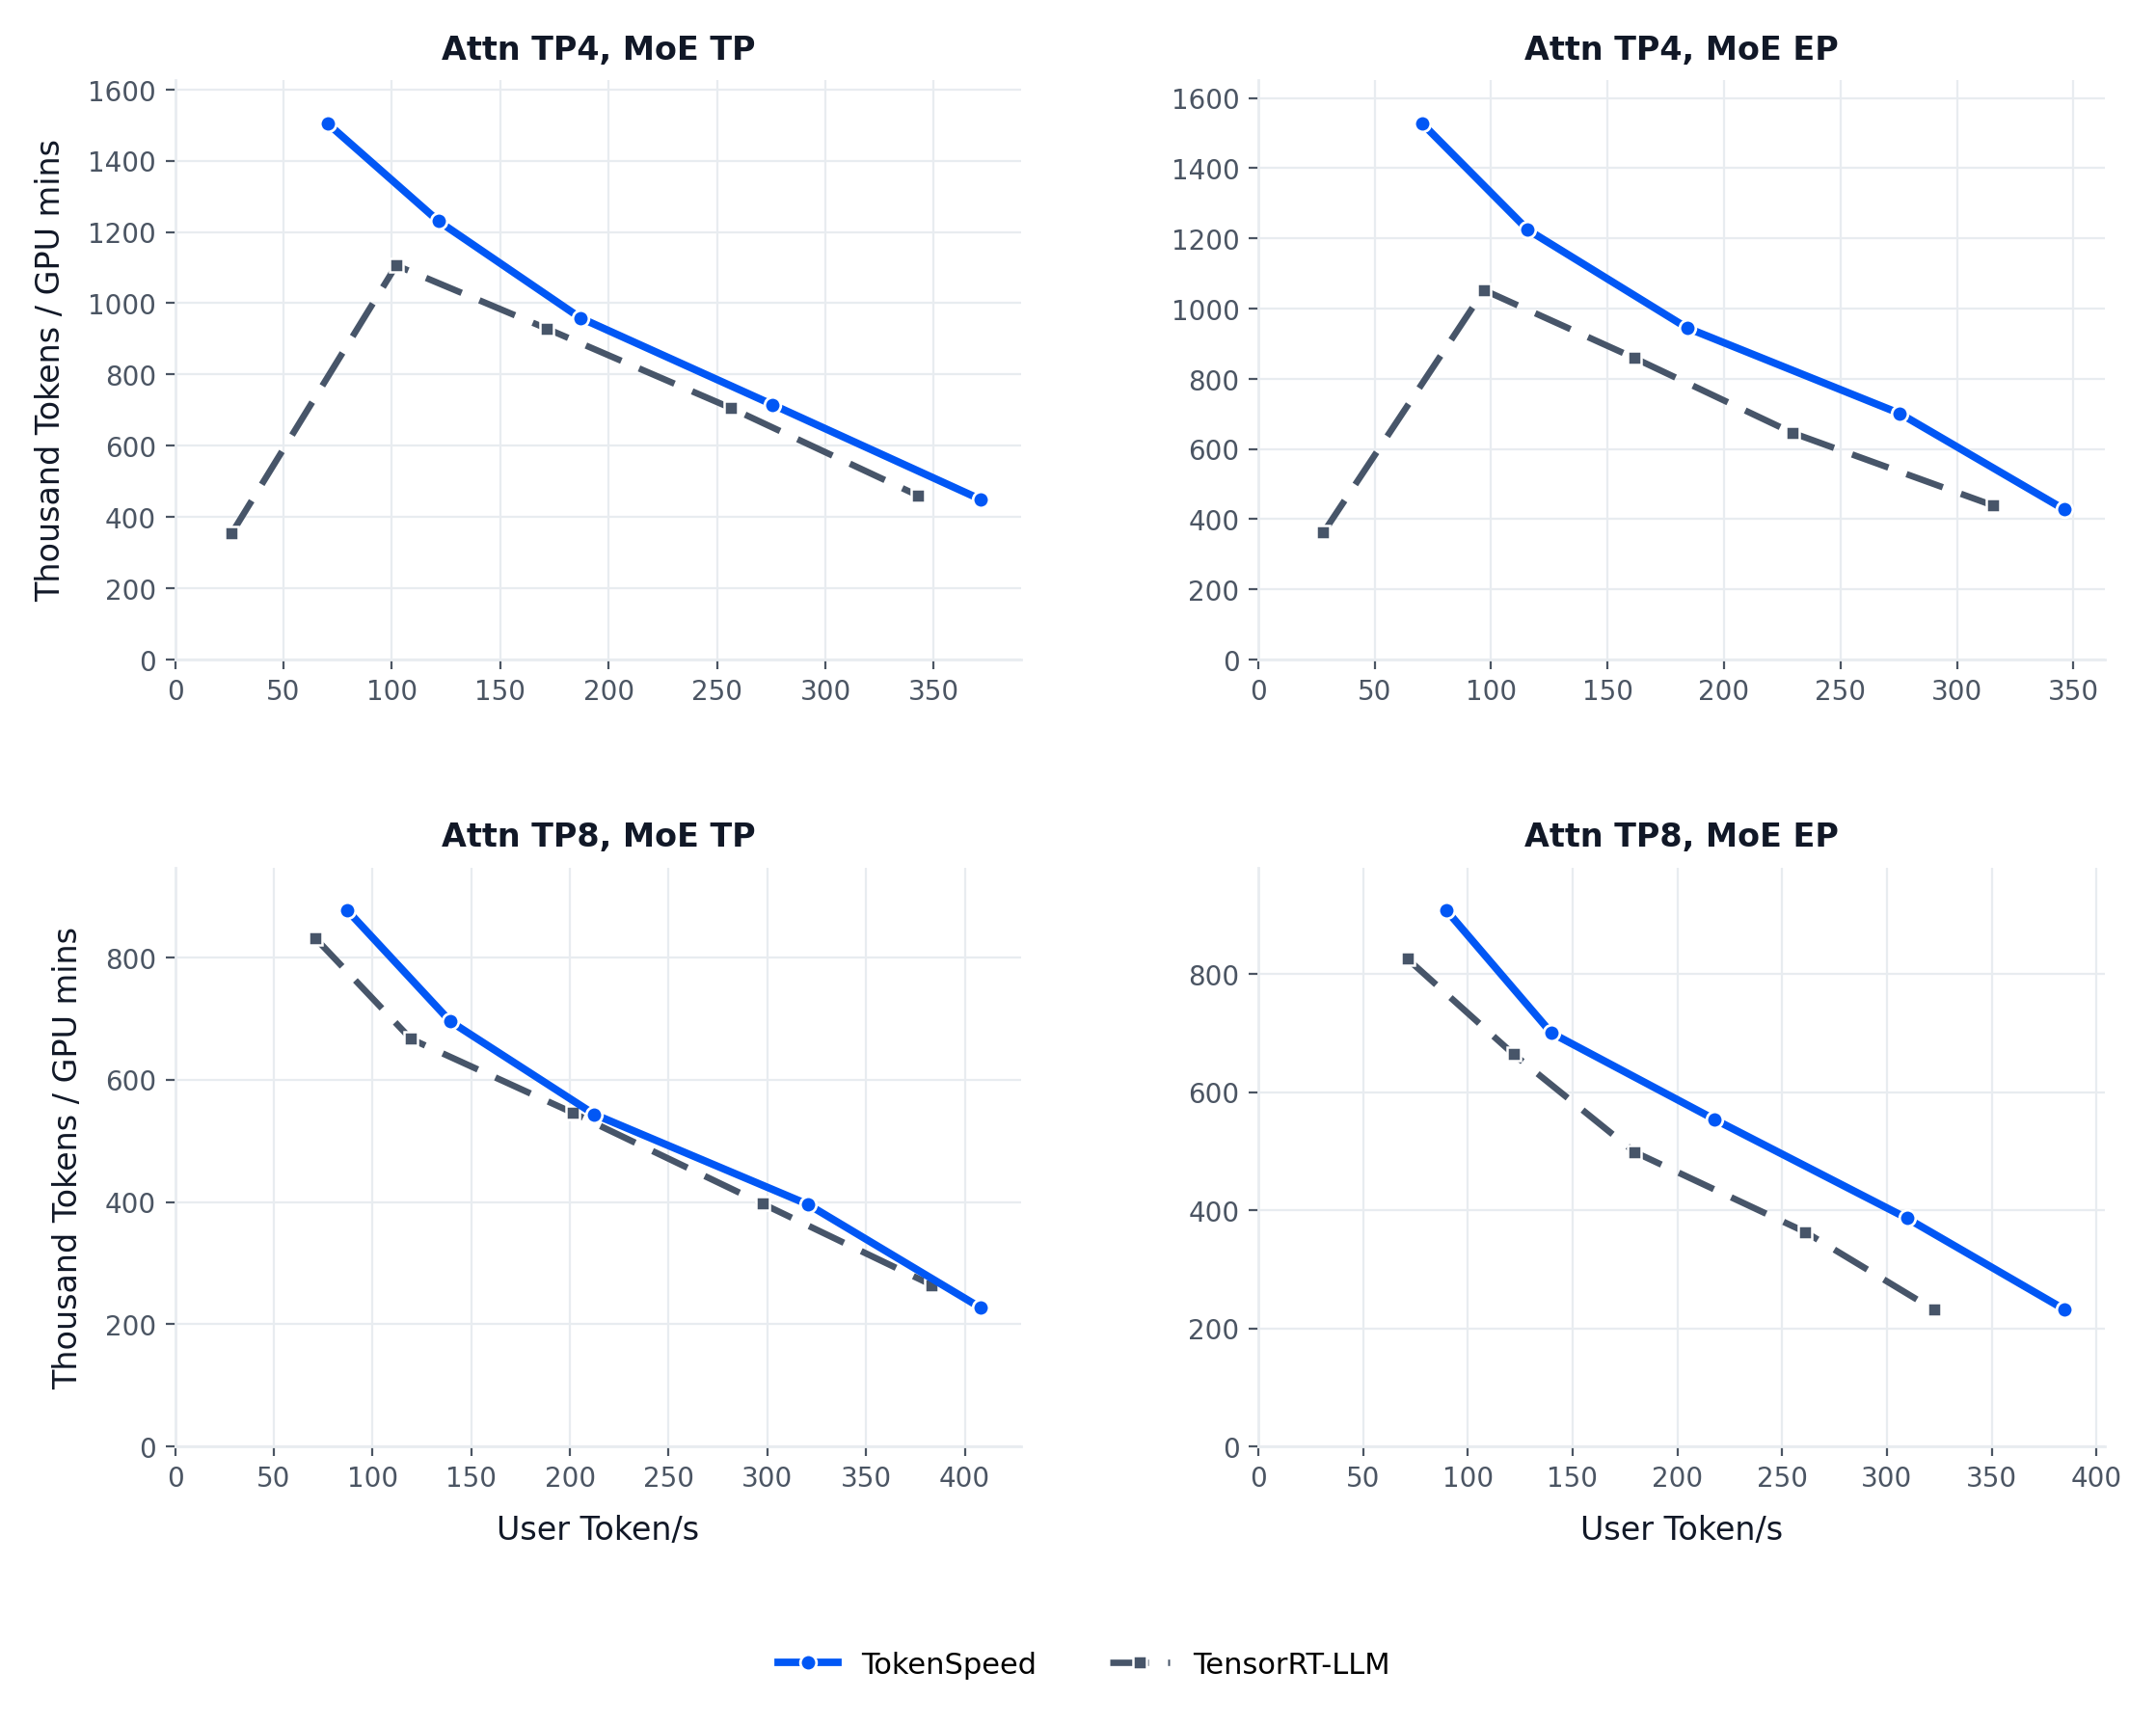
 TokenSpeed is a speed-of-light LLM inference engine built for agentic workloads, aiming to match TensorRT-LLM-level performance with vLLM-level usability.
Is this a library I import, or a server I run?It is run as a server (via an AsyncLLM entrypoint) that you launch to serve models; it is not a simple pip-importable inference library.
It is run as a server (via an AsyncLLM entrypoint) that you launch to serve models; it is not a simple pip-importable inference library.How do I get a model running with TokenSpeed?The docs provide a 'Getting Started' guide and a 'Launching a Server' page that walk through standing up an inference server with specific model recipes.
The docs provide a 'Getting Started' guide and a 'Launching a Server' page that walk through standing up an inference server with specific model recipes.Do I need specific hardware to run it?Yes — it targets high-end accelerators like NVIDIA Blackwell/Rubin (B200/B300/GB200/GB300) and AMD Instinct (MI355X/MI455X) GPUs, not generic consumer hardware.
Yes — it targets high-end accelerators like NVIDIA Blackwell/Rubin (B200/B300/GB200/GB300) and AMD Instinct (MI355X/MI455X) GPUs, not generic consumer hardware.Does it work well on any GPU, or only the latest chips?The headline benchmarks and optimizations (585-685 tokens/s per user, FP4 inference) are shown on the newest NVIDIA and AMD data-center GPUs; performance on older or consumer GPUs isn't discussed in the README.
The headline benchmarks and optimizations (585-685 tokens/s per user, FP4 inference) are shown on the newest NVIDIA and AMD data-center GPUs; performance on older or consumer GPUs isn't discussed in the README.Who is this engine built for?It targets ML systems researchers and engineers running production-scale agentic LLM workloads who need both raw throughput and the flexibility to iterate quickly.
It targets ML systems researchers and engineers running production-scale agentic LLM workloads who need both raw throughput and the flexibility to iterate quickly.What makes TokenSpeed's architecture different from engines like vLLM?It separates the control plane (a C++ finite-state machine that enforces safe KV-cache and request-lifecycle management at compile time) from the execution plane (Python, for fast iteration), plus treats kernels as a pluggable, centrally-registered subsystem.
It separates the control plane (a C++ finite-state machine that enforces safe KV-cache and request-lifecycle management at compile time) from the execution plane (Python, for fast iteration), plus treats kernels as a pluggable, centrally-registered subsystem.What is MLA and why does it matter here?MLA stands for Multi-head Latent Attention; TokenSpeed includes one of the fastest MLA kernel implementations on NVIDIA Blackwell, optimized specifically for agentic workloads.
MLA stands for Multi-head Latent Attention; TokenSpeed includes one of the fastest MLA kernel implementations on NVIDIA Blackwell, optimized specifically for agentic workloads.Which models does TokenSpeed support out of the box?The README highlights Day-0 support and optimization for models like Kimi K3/K2.5, Qwen3.5/3.8, GLM 5.3, DeepSeek, GPT-OSS, and MiniMax.
The README highlights Day-0 support and optimization for models like Kimi K3/K2.5, Qwen3.5/3.8, GLM 5.3, DeepSeek, GPT-OSS, and MiniMax.Why does the project call itself the 'Switzerland' of inference engines?Because it's run by the non-profit LightSeek Foundation rather than a single company, with hardware/engineering support from both NVIDIA and AMD, keeping it vendor-neutral.
Because it's run by the non-profit LightSeek Foundation rather than a single company, with hardware/engineering support from both NVIDIA and AMD, keeping it vendor-neutral.What are similar projects?sglang, vllm, qwen3.8-Flash-DGX, LMCache, v100-skinny, ds4, TensorRT-LLM, DeepSeek-v4-Flash-One-DGX-Spark
sglang, vllm, qwen3.8-Flash-DGX, LMCache, v100-skinny, ds4, TensorRT-LLM, DeepSeek-v4-Flash-One-DGX-SparkWhich topics is it in?blackwell, gpt-oss, minimax, llm-serving, rocm, glm, kimi, vlm, inference-engine, model-serving, amd, agentic
blackwell, gpt-oss, minimax, llm-serving, rocm, glm, kimi, vlm, inference-engine, model-serving, amd, agentic