What is Miller?
Miller is like awk, sed, cut, join, and sort for data formats such as CSV, TSV, JSON, JSON Lines, and positionally-indexed.
What can Miller do for me?
With Miller, you get to use named fields without needing to count positional
indices, using familiar formats such as CSV, TSV, JSON, JSON Lines, and
positionally-indexed. Then, on the fly, you can add new fields which are
functions of existing fields, drop fields, sort, aggregate statistically,
pretty-print, and more.
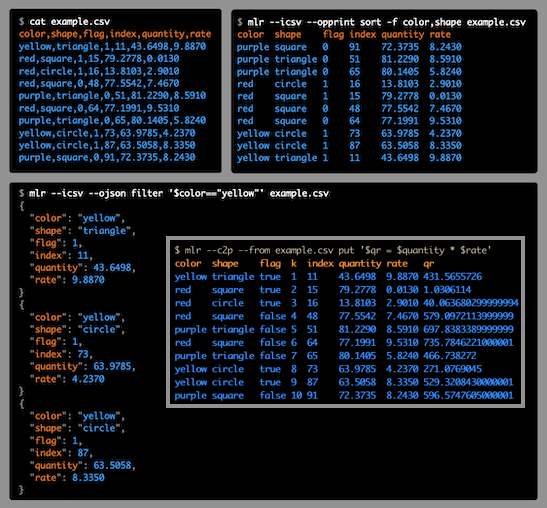
Miller operates on key-value-pair data while the familiar
Unix tools operate on integer-indexed fields: if the natural data structure for
the latter is the array, then Miller's natural data structure is the
insertion-ordered hash map.
Miller handles a variety of data formats,
including but not limited to the familiar CSV, TSV, and JSON/JSON Lines.
(Miller can handle positionally-indexed data too!)
In the above image you can see how Miller embraces the common themes of
key-value-pair data in a variety of data formats.
Installing
There's a good chance you can get Miller pre-built for your system:


| OS |
Installation command |
| Linux |
yum install miller
apt-get install miller
snap install miller |
| Mac |
brew install miller
port install miller |
| Windows |
choco install miller
winget install Miller.Miller
scoop install main/miller |
See also README-versions.md for a full list of package versions. Note that long-term-support (LtS) releases will likely be on older versions.
See also building from source.
Features
Miller is multi-purpose: it's useful for data cleaning,
data reduction, statistical reporting, devops, system
administration, log-file processing, format conversion, and
database-query post-processing.
You can use Miller to snarf and munge log-file data, including selecting
out relevant substreams, then produce CSV format and load that into
all-in-memory/data-frame utilities for further statistical and/or graphical
processing.
Miller complements data-analysis tools such as R, pandas, etc.:
you can use Miller to clean and prepare your data. While you can do
basic statistics entirely in Miller, its streaming-data feature and
single-pass algorithms enable you to reduce very large data sets.
Miller complements SQL databases: you can slice, dice, and reformat data
on the client side on its way into or out of a database. You can also reap some
of the benefits of databases for quick, setup-free one-off tasks when you just
need to query some data in disk files in a hurry.
Miller also goes beyond the classic Unix tools by stepping fully into our
modern, no-SQL world: its essential record-heterogeneity property allows
Miller to operate on data where records with different schema (field names) are
interleaved.
Miller is streaming: most operations need only a single record in
memory at a time, rather than ingesting all input before producing any output.
For those operations which require deeper retention (sort, tac, stats1),
Miller retains only as much data as needed. This means that whenever
functionally possible, you can operate on files which are larger than your
system’s available RAM, and you can use Miller in tail -f contexts.
Miller is pipe-friendly and interoperates with the Unix toolkit.
Miller's I/O formats include tabular pretty-printing, positionally
indexed (Unix-toolkit style), CSV, TSV, JSON, JSON Lines, and others.
Miller does conversion between formats.
Miller's processing is format-aware: e.g. CSV sort and tac keep header lines first.
Miller has high-throughput performance on par with the Unix toolkit.
Miller is written in portable, modern Go, with zero runtime dependencies.
You can download or compile a single binary, scp it to a faraway machine,
and expect it to work.
Getting started

More documentation links


Build status


Building from source
- First:
cd /where/you/want/to/put/the/sourcegit clone https://github.com/johnkerl/millercd miller
- With
make:
- To build:
make. This takes just a few seconds and produces the Miller executable, which is ./mlr (or .\mlr.exe on Windows).
- To run tests:
make check.
- To install:
make install. This installs the executable /usr/local/bin/mlr and manual page /usr/local/share/man/man1/mlr.1 (so you can do man mlr).
- You can do
./configure --prefix=/some/install/path before make install if you want to install somewhere other than /usr/local.
- Without
make:
- To build:
go build github.com/johnkerl/miller/v6/cmd/mlr.
- To run tests:
go test github.com/johnkerl/miller/v6/pkg/... and mlr regtest.
- To install:
go install github.com/johnkerl/miller/v6/cmd/mlr@latest will install to GOPATH/bin/mlr.
- See also the doc page on building from source.
- For more developer information please see README-dev.md.
For developers
License
License: BSD2
What people are saying about Miller
Today I discovered Miller—it's like jq but for CSV: https://t.co/pn5Ni241KM
Also, "Miller complements data-analysis tools such as R, pandas, etc.: you can use Miller to clean and prepare your data." @GreatBlueC @nfmcclure
— Adrien Trouillaud (@adrienjt) September 24, 2020
Underappreciated swiss-army command-line chainsaw.
"Miller is like awk, sed, cut, join, and sort for [...] CSV, TSV, and [...] JSON." https://t.co/TrQqSUK3KK
— Dirk Eddelbuettel (@eddelbuettel) February 28, 2017
Miller looks like a great command line tool for working with CSV data. Sed, awk, cut, join all rolled into one: http://t.co/9BBb6VCZ6Y
— Mike Loukides (@mikeloukides) August 16, 2015
Miller is like sed, awk, cut, join, and sort for name-indexed data such as CSV: http://t.co/1zPbfg6B2W - handy tool!
— Ilya Grigorik (@igrigorik) August 22, 2015
Btw, I think Miller is the best CLI tool to deal with CSV. I used to use this when I need to preprocess too big CSVs to load into R (now we have vroom, so such cases might be rare, though...)https://t.co/kUjrSSGJoT
— Hiroaki Yutani (@yutannihilat_en) April 21, 2020
Miller: a *format-aware* data munging tool By @__jo_ker__ to overcome limitations with *line-aware* workshorses like awk, sed et al https://t.co/LCyPkhYvt9
The project website is a fantastic example of good software documentation!!
— Donny Daniel (@dnnydnl) September 9, 2018
Holy holly data swiss army knife batman! How did no one suggest Miller https://t.co/JGQpmRAZLv for solving database cleaning / ETL issues to me before
Congrats to @__jo_ker__ for amazingly intuitive tool for critical data management tasks!#DataScienceandLaw #ComputationalLaw
— James Miller (@japanlawprof) June 12, 2018
🤯@__jo_ker__'s Miller easily reads, transforms, + writes all sorts of tabular data. It's standalone, fast, and built for streaming data (operating on one line at a time, so you can work on files larger than memory).
And the docs are dream. I've been reading them all morning! https://t.co/Be2pGPZK6t
— Benjamin Wolfe (he/him) (@BenjaminWolfe) September 9, 2021
Contributors ✨
Thanks to all the fine people who help make Miller better (emoji key):


 Miller 是一个命令行工具集,类似于 awk、sed、cut、join 和 sort,但专为 CSV、TSV、JSON 和 JSON Lines 这类带名称索引的数据而设计:你可以按字段名来操作,而不用去数列的位置。