State-of-the-art pretrained models for inference and training
Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer
vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
simple, customizable, and efficient.
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
import torch
from transformers import pipeline

chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]

pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
Expand the examples below to see how Pipeline works for different modalities and tasks.
Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
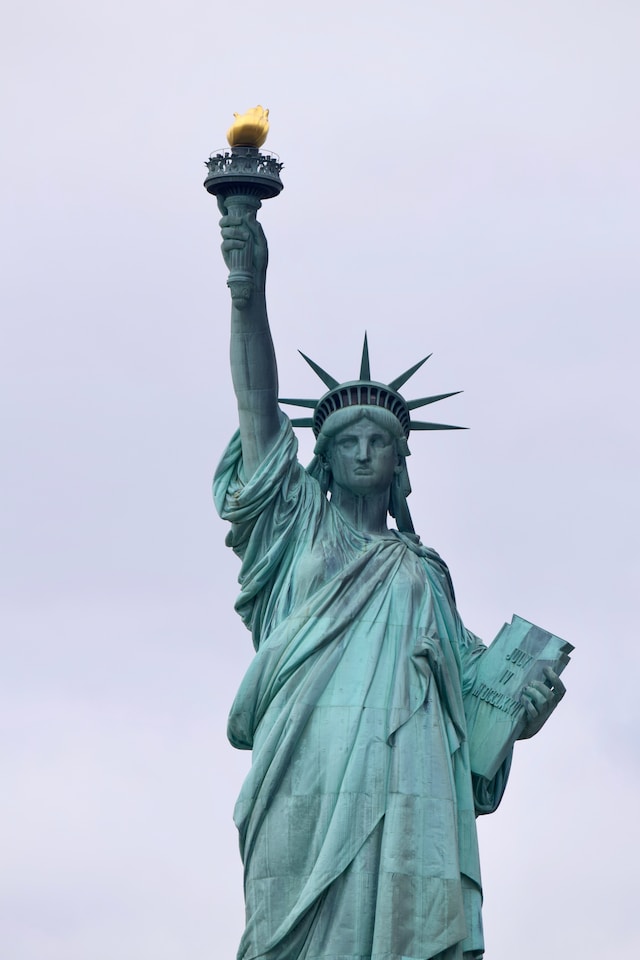
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]
Why should I use Transformers?
Easy-to-use state-of-the-art models:
High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
Low barrier to entry for researchers, engineers, and developers.
Few user-facing abstractions with just three classes to learn.
A unified API for using all our pretrained models.
Lower compute costs, smaller carbon footprint:
Share trained models instead of training from scratch.
Reduce compute time and production costs.
Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
Choose the right framework for every part of a model's lifetime:
Train state-of-the-art models in 3 lines of code.
Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
Pick the right framework for training, evaluation, and production.
Easily customize a model or an example to your needs:
We provide examples for each architecture to reproduce the results published by its original authors.
Model internals are exposed as consistently as possible.
Model files can be used independently of the library for quick experiments.
When shouldn't I use Transformers?
This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.
The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like Accelerate.
The example scripts are only examples. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.
100 projects using Transformers
Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the
Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone
else to build their dream projects.
In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the
community with the awesome-transformers page which lists 100
incredible projects built with Transformers.
If you own or use a project that you believe should be part of the list, please open a PR to add it!
Example models
You can test most of our models directly on their Hub model pages.
Expand each modality below to see a few example models for various use cases.
We now have a paper you can cite for the 🤗 Transformers library:
@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2020.emnlp-demos.6/",
    pages = "38--45"
}
transformers (huggingface/transformers)
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
Searching Database…
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.



 Transformers 是 Hugging Face 推出的模型定义框架,用于构建覆盖文本、视觉、音频、视频和多模态任务的先进机器学习模型,既能做推理,也能做训练。