StreamPI: Streaming Multimodal Temporal Modeling for Vision-Language-Action Models
Zhe Liu1*
Jinghua Hou1*
Yuxiang Lu1
Zhenya Yang1
Xianzhe Fan1
Junwei Luo1
Junyi Li1
Ruihua Han1
Zhi Hou2
Hengshuang Zhao1†
1 The University of Hong Kong
2 ACE Robotics
* Equal contribution † Corresponding author
Official implementation of StreamPI, built on openpi, with additional, fully validated support for JAX multi-node distributed training beyond the standard single-node setup, enabling substantially more efficient training without compromising model performance.
TL;DR
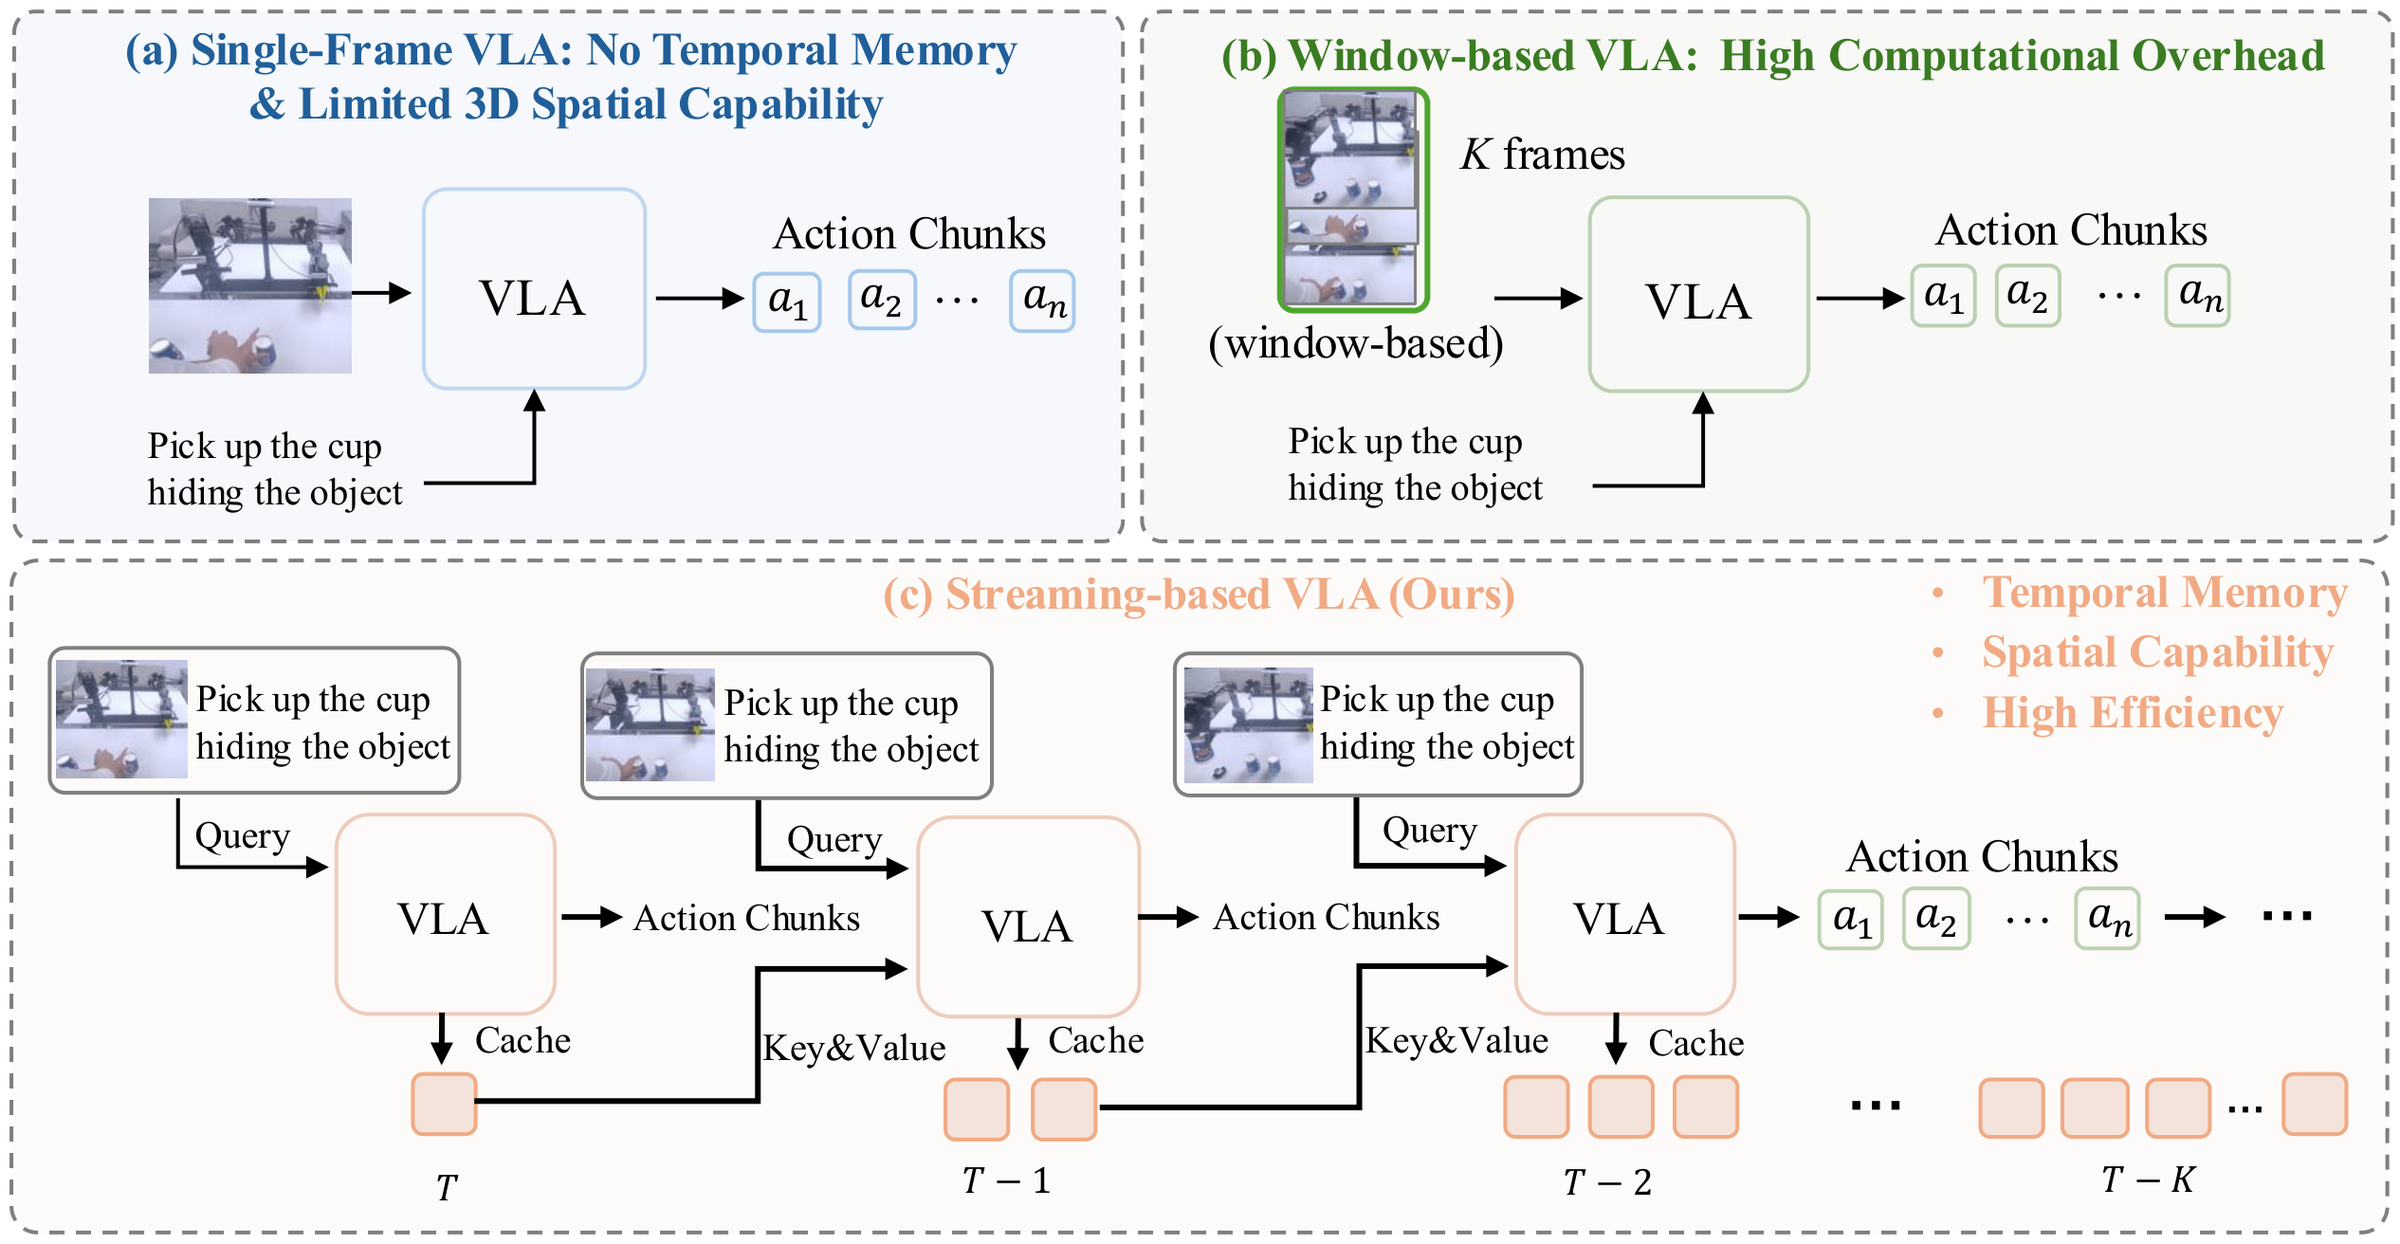
Single-frame Vision-Language-Action (VLA) models such as $\pi_{0.5}$ cannot retain past observations, while window-based multi-frame models repeatedly process the full history at substantial computational cost. StreamPI instead treats every (visual observation, language instruction) pair as an atomic temporal unit. Bidirectional attention within each pair preserves cross-modal grounding, causal attention across pairs captures temporal context, and a KV cache avoids recomputing past observations. This equips a pretrained single-frame VLA with temporal reasoning without adding parameters, while supporting flexible context lengths and efficient streaming inference.
🔥 Highlights
- Persistent temporal reasoning: StreamPI equips $\pi_{0.5}$ with memory and multi-frame geometric cues while preserving its pretrained representation space.
- Instruction-anchored modeling: Repeating the instruction in every temporal unit prevents the task goal from being diluted as visual context grows.
- No additional parameters: Temporal modeling is implemented entirely through an extended token sequence and a block-wise attention mask.
- Asynchrony-aware training: Random-interval sampling and temporal masking expose the policy to variable observation timing and incremental context.
- Efficient deployment: On a single RTX 4090, increasing the context from one to five frames adds only 9.2 ms of mean inference latency (94.4 ms to 103.6 ms).
🎥 Demo
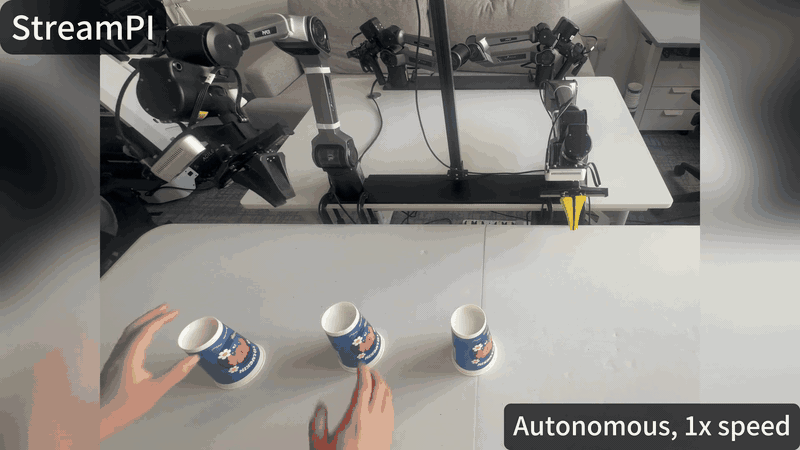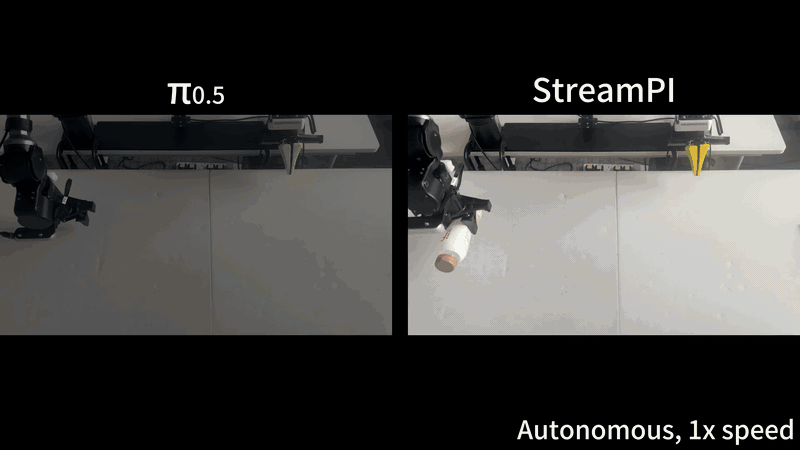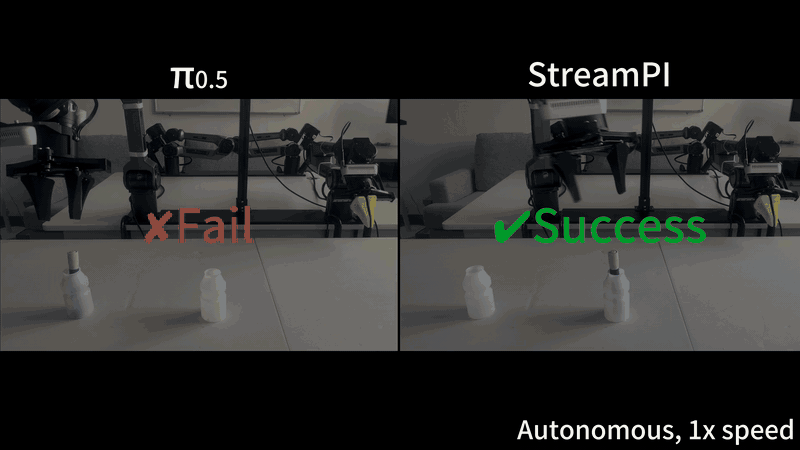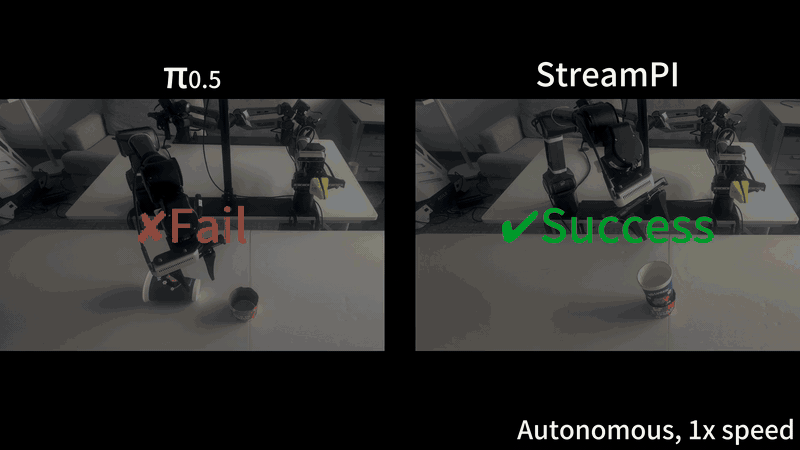
▶ Click to play the 2:07 real-world demonstration (MP4)
The animated preview showcases StreamPI on precise perception and memory-dependent manipulation tasks. Click it to play the full video.
📰 News
- August 30, 2026: Code and model weights will be released.
- August 26, 2026: The paper is released on arXiv.
✨ Abstract
Vision-Language-Action models have demonstrated strong performance in robot manipulation, yet leading models such as $\pi_{0.5}$ still operate one frame at a time. This single-frame paradigm limits both temporal memory and the precise spatial perception that can emerge from aggregating observations over time. StreamPI is a streaming multimodal temporal modeling framework that adds these capabilities without introducing any new model parameters.
The central design is instruction-anchored temporal modeling. StreamPI treats each (visual observation, language instruction) pair as an atomic temporal unit: bidirectional attention within a pair enables full cross-modal fusion, while causal attention across pairs supports autoregressive streaming inference. The instruction therefore remains a persistent semantic anchor throughout execution. A complementary random-interval streaming training strategy improves robustness to variable frame rates and asynchronous observation arrival. By relying on the LLM backbone's length extrapolation, StreamPI inherits all pretrained $\pi_{0.5}$ weights and supports both single-frame and multi-frame inference. Experiments on real robots, LIBERO, and CALVIN show consistent gains from temporal modeling.
🧠 Method
Instruction-Anchored Temporal Modeling
At time $t$, the base VLA receives multi-view visual observations $\mathbf{V}_t$ and a language instruction $l_t$. StreamPI binds them into an indivisible temporal unit and concatenates the latest $T$ units:
$$
\mathbf{u}_t = (\mathbf{V}t, l_t), \qquad
\mathbf{U} = [\mathbf{u}{t-T+1}, \ldots, \mathbf{u}_t].
$$
The attention pattern operates at two levels:
- Intra-pair bidirectional attention allows all visual and language tokens within $\mathbf{u}\tau$ to interact, producing a semantically grounded representation $\mathbf{h}\tau$.
- Inter-pair causal attention allows the current representation to attend to earlier temporal units, but never to future ones.
Re-anchoring the instruction at every time step prevents instruction forgetting as the temporal horizon grows. The entire hierarchy is realized by restructuring the attention mask and extending the input token sequence, so StreamPI inherits all pretrained $\pi_{0.5}$ weights without architectural changes or additional parameters.
Random-Interval Streaming Training
Real robots produce asynchronous observation streams with variable timing. At each historical sampling step $i$, StreamPI perturbs a base interval $\bar{\delta}$ with $\epsilon_i \sim \mathcal{U}(-\Delta, +\Delta)$ and clips $\delta_i = \bar{\delta} + \epsilon_i$ to $[\delta_{\min}, \delta_{\max}]$. Historical frames are selected at cumulative offsets such as $t-\delta_1$ and $t-\delta_1-\delta_2$. In the paper's training protocol, each interval is sampled uniformly from $[3, 7]$.
StreamPI also samples a masking count $k \in {0, \ldots, T-1}$ and hides the earliest $k$ units in a training sequence. This temporal masking simulates the incremental context available at the beginning of streaming inference. Together, randomized intervals and temporal masking reduce the mismatch between synchronous training data and asynchronous deployment.
Streaming Inference
At the first time step, StreamPI encodes the current temporal unit, predicts an action chunk, and stores the resulting Key and Value representations. Each subsequent call encodes only the newly arrived unit, which attends to the cached history. The cache is bounded by the configured context length $T$ and is flushed when the next unit would exceed that limit. This eliminates redundant re-encoding of past observations while retaining the temporal evidence needed for long-horizon manipulation.
📊 Experiments
Real-Robot Manipulation
The real-robot platform uses AgileX PiperX 6-DoF arms in an ALOHA-style leader-follower setup, with one front-view Intel RealSense D455 and two wrist-mounted RealSense D435 cameras. For each task, we collect 100 teleoperated demonstrations at 30 FPS and fully fine-tune the pretrained $\pi_{0.5}$ policy.
Evaluation covers two complementary task categories:
- Precise perception: Cup Insertion into Cup Sleeve and Pen Insertion into Narrow Bottle.
- Memory dependence: Rolling Object Grasping and Shell Game.
StreamPI improves over the single-frame baseline on every task, with gains ranging from 26.7 to 36.6 percentage points.
| Task |
Trials |
$\pi_{0.5}$ |
StreamPI |
Gain |
| Cup Insertion into Cup Sleeve |
25 |
60.0% |
92.0% |
+32.0 pp |
| Pen Insertion into Narrow Bottle |
30 |
40.0% |
66.7% |
+26.7 pp |
| Rolling Object Grasping |
30 |
26.7% |
63.3% |
+36.6 pp |
| Shell Game |
15 |
46.7% |
80.0% |
+33.3 pp |
LIBERO Simulation Benchmark
LIBERO contains four suites - Spatial, Object, Goal, and Long - with 10 tasks per suite and 50 trials per task. Success rates (%) are shown below. StreamPI ($T=5$) reaches 98.3% average success, improving over $\pi_{0.5}$ by 1.4 points overall, 2.8 points on LIBERO-Goal, and 2.6 points on LIBERO-Long. Performance on LIBERO-Spatial remains tied at 98.8%, consistent with that suite's emphasis on static spatial relations already visible in one frame.
| Method |
Spatial |
Object |
Goal |
Long |
Avg. |
| Diffusion Policy |
78.3 |
92.5 |
68.3 |
50.5 |
72.4 |
| Octo |
78.9 |
85.7 |
84.6 |
51.1 |
75.1 |
| SpatialVLA |
88.2 |
89.9 |
78.6 |
55.5 |
71.7 |
| TraceVLA |
84.6 |
85.2 |
75.1 |
54.1 |
74.8 |
| OpenVLA |
84.7 |
88.4 |
79.2 |
53.7 |
75.9 |
| CoT-VLA |
87.5 |
91.6 |
87.6 |
69.0 |
81.1 |
| $\pi_0$-FAST* |
96.4 |
96.8 |
88.6 |
60.2 |
85.0 |
| SmolVLA |
93.0 |
94.0 |
91.0 |
77.0 |
88.8 |
| GR00T-N1 |
94.4 |
97.6 |
93.0 |
90.6 |
93.9 |
| UniVLA |
95.4 |
98.8 |
93.6 |
94.0 |
95.4 |
| FLOWER |
97.1 |
96.7 |
95.6 |
93.5 |
95.7 |
| CronusVLA |
90.1 |
94.7 |
91.3 |
68.7 |
86.2 |
| TriVLA |
91.2 |
93.8 |
89.8 |
73.2 |
87.0 |
| 4D-VLA |
93.8 |
92.8 |
95.6 |
86.5 |
92.2 |
| CogACT |
87.5 |
90.2 |
80.2 |
53.2 |
77.8 |
| ST-$\pi$ |
98.4 |
98.3 |
96.9 |
94.3 |
97.3 |
| MemoryVLA |
98.4 |
98.4 |
96.4 |
93.4 |
96.5 |
| $\pi_0$ |
96.8 |
98.8 |
95.8 |
85.2 |
94.2 |
| $\pi_{0.5}$ |
98.8 |
98.2 |
96.8 |
92.4 |
96.9 |
| StreamPI ($T=3$) |
98.6 |
98.6 |
98.6 |
93.8 |
97.5 |
| StreamPI ($T=5$) |
98.8 |
99.8 |
99.6 |
95.0 |
98.3 |
Key Ablations
Our ablations isolate the contribution of each temporal design choice:
| Component |
Strong setting |
Comparison |
Avg. gain (pp) |
LIBERO-Long gain (pp) |
| Intra-pair fusion |
Bidirectional attention, $T=5$ |
Causal intra-pair attention |
+2.8 |
+4.4 |
| Inter-pair context |
Five frames with causal inter-pair attention |
Single-frame context |
+1.8 |
+3.0 |
| Temporal sampling |
Random $\delta \sim \mathcal{U}[3,7]$, $T=5$ |
Fixed $\delta=1$ |
+1.3 |
+1.6 |
A model trained with $T=5$ also generalizes to shorter inference contexts: it obtains 97.4% average success at test-time $T=3$ and 97.1% at $T=1$, both above the 96.5% single-frame ablation baseline.
Streaming Inference Efficiency
Mean latency over 20 real-robot trials on one NVIDIA GeForce RTX 4090. Extending the temporal context from one to five frames adds only 9.2 ms.
| Streaming frames |
Inference time (ms) |
Overhead vs. $T=1$ |
| 1 |
$94.4 \pm 3.4$ |
N/A |
| 3 |
$97.9 \pm 5.1$ |
3.5 ms |
| 5 |
$103.6 \pm 6.3$ |
9.2 ms |
| 8 |
$110.9 \pm 10.2$ |
16.5 ms |
| 10 |
$117.9 \pm 16.5$ |
23.5 ms |
CALVIN Benchmark
The StreamPI paper also evaluates long-horizon temporal reasoning on CALVIN, where a policy must execute sequences of up to five consecutive tasks. Success rates (%) are reported at each sequence position; Avg. is the average number of consecutively completed tasks.
| Method |
1 |
2 |
3 |
4 |
5 |
Avg. |
| MemoryVLA |
94.8 |
87.4 |
81.4 |
75.9 |
69.4 |
4.090 |
| $\pi_{0.5}$ |
94.2 |
88.7 |
85.7 |
83.2 |
79.5 |
4.313 |
| StreamPI ($T=5$) |
96.9 |
93.6 |
90.7 |
88.5 |
85.0 |
4.547 |
⚙️ Setup
Requirements
StreamPI follows the software requirements of openpi and requires Python 3.11 or later. Because StreamPI stacks $T$ temporal units in the prefix, training memory grows with the temporal horizon. Model parallelism can be configured with --fsdp-devices; multi-node JAX training is provided by scripts/train_multi_node.py.
The reference experiments in the paper use the following compute settings:
| Experiment |
Hardware |
Batch size |
Training steps / trials |
| LIBERO training |
8 x NVIDIA H100 |
256 |
30,000 steps |
| Real-robot training |
8 x NVIDIA H100 |
128 |
50,000 steps |
| Latency evaluation |
1 x NVIDIA RTX 4090 |
N/A |
20 trials |
Installation
Clone the repository with its submodules, then install the dependencies with uv:
git clone --recurse-submodules https://github.com/happinesslz/StreamPI.git
cd StreamPI

GIT_LFS_SKIP_SMUDGE=1 uv sync
GIT_LFS_SKIP_SMUDGE=1 uv pip install -e .
If the repository was cloned without submodules, initialize them separately:
git submodule update --init --recursive
Use uv run <command> for the commands below, or activate the generated environment once with:
source .venv/bin/activate
For a container-based setup, see docs/docker.md.
🚀 Usage
Training Configurations
StreamPI configurations are defined in src/openpi/training/config.py. The temporal context length $T$ is controlled by Pi0Config.hist_horizon; frame spacing and temporal jitter are controlled by DataConfig.hist_interval, jitter_range, and enable_jitter.
| Configuration |
Benchmark |
$T$ |
Base interval |
Jitter enabled by default |
pi05_libero_stream3 |
LIBERO |
3 |
5 |
No |
pi05_libero_stream5 |
LIBERO |
5 |
5 |
No |
pi05_calvin_stream3 |
CALVIN |
3 |
5 |
No |
pi05_calvin_stream5 |
CALVIN |
5 |
5 |
No |
All streaming configurations fine-tune from the pretrained single-frame checkpoint at gs://openpi-assets/checkpoints/pi05_base/params. Because StreamPI introduces no new parameters, it can inherit the pretrained $\pi_{0.5}$ weights directly.
[!IMPORTANT]
The results reported in the paper use independently randomized intervals $\delta \sim \mathcal{U}[3,7]$. The checked-in LIBERO and CALVIN configurations currently set enable_jitter=False, while TemporalJitter applies one shared frame offset around a fixed interval. Exact reproduction of the paper's random-interval experiments therefore requires aligning both the configuration and data-sampling path with the paper protocol.
1. Prepare Normalization Statistics
Precomputed statistics for LIBERO and CALVIN are included under assets/. To recompute them:
# LIBERO
bash compute_norm.sh

# CALVIN (writes to assets/pi05_calvin/.../norm_stats.json)
python compute_norm_calvin.py
2. Launch Training
For the reported results, we fully fine-tune the pretrained $\pi_{0.5}$ weights using the same optimizer and learning-rate schedule as the base model. A single-node LIBERO run can be launched with:
JAX_DEBUG_NOWAIT=1 XLA_PYTHON_CLIENT_MEM_FRACTION=0.9 \
python scripts/train.py pi05_libero_stream5 \
  --exp-name=pi05_stream5_libero \
  --overwrite \
  --batch-size=256 \
  --fsdp-devices=8
For the repository's CALVIN training examples, see train_stream5_calvin.sh and train_stream3_calvin.sh.
JAX Multi-Node Distributed Training
StreamPI extends the upstream openpi training pipeline with a fully validated JAX multi-node distributed training path. scripts/train_multi_node.py uses jax.distributed.initialize to form one global device mesh across all nodes, combines data parallelism with Fully Sharded Data Parallel (FSDP), partitions the global batch across processes, and coordinates checkpoint saving and restoration across hosts. The model architecture, training objective, optimizer, and learning-rate schedule remain unchanged, so multi-node training preserves single-node model performance while substantially reducing wall-clock training time.
Run the same training command on every node after setting the shared coordinator address and a unique zero-based rank for each node:
export MASTER_ADDR=<rank-0-host>
export MASTER_PORT=6060
export NNODES=4
export NODE_RANK=<0-3>
--batch-size denotes the global batch size and must be divisible by the global JAX device count and the number of nodes. --fsdp-devices controls the width of the FSDP axis and must divide the total number of devices. For example, four 8-GPU nodes with --fsdp-devices=8 form a global mesh with four-way data parallelism and eight-way FSDP.
Ready-to-use four-node launchers are provided in train_stream5_calvin_4_nodes.sh and train_stream5_libero_4_nodes.sh. A LIBERO launch command is:
python -u scripts/train_multi_node.py pi05_libero_stream5 \
  --exp-name=pi05_stream5_libero_4nodes \
  --overwrite \
  --batch-size=256 \
  --fsdp-devices=8
Checkpoints are written to:
checkpoints/<config_name>/<exp_name>/<step>
3. Evaluation
LIBERO
See examples/libero/README.md for environment setup and evaluation options. To evaluate a custom checkpoint, run the LIBERO client and policy server in separate processes:
# Client
python examples/libero/main.py

# Policy server
uv run scripts/serve_policy.py --env=LIBERO policy:checkpoint \
  --policy.config=pi05_libero_stream5 \
  --policy.dir=/path/to/checkpoint
CALVIN
See examples/calvin/README.md for the complete setup. Start the policy server in the StreamPI environment:
bash run_eval_calvin_benchmark.sh

# Equivalent command:
python scripts/serve_policy.py --port=8000 policy:checkpoint \
  --policy.config=pi05_calvin_stream5 \
  --policy.dir=checkpoints/pi05_calvin_stream5/pi05_stream5_calvin_4nodes/29999
Then run the client in a separate CALV

 StreamPI 的官方代码(NeurIPS 2026,来自 HKU 和 ACE Robotics):一个流式时序建模框架,让 pi0.5 这类 VLA 机器人策略能记住过去的帧并获得多帧感知能力,且不增加任何新参数。