Datalab
State of the Art models for Document Intelligence


Surya
Surya is a 650M param OCR model with these features:
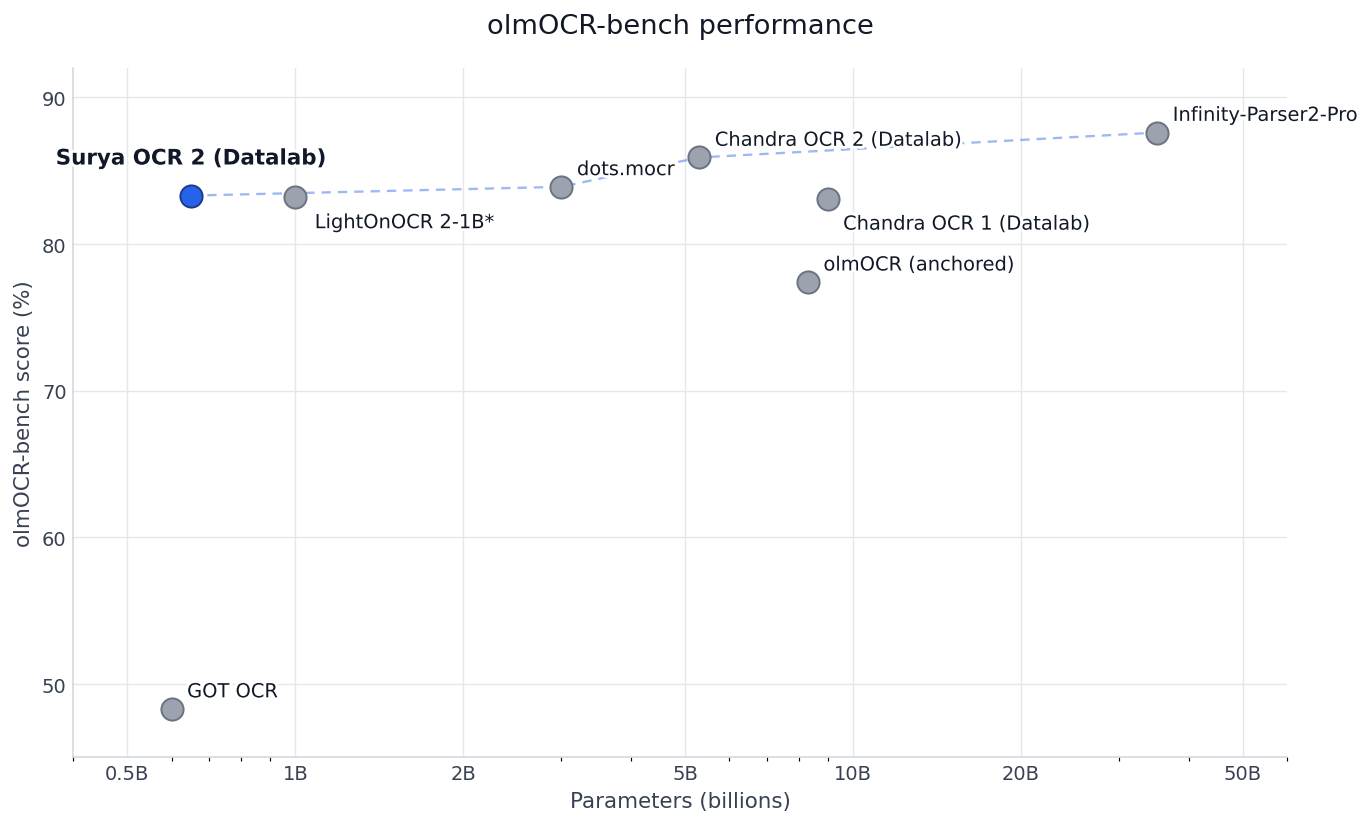
- Accuracy - scores 83.3% on olmOCR-bench (top under 3B params)
- Speed - throughput of 5 pages/s on an RTX 5090
- Multilingual - scores 87.2% on an internal benchmark set of 91 languages (more here)
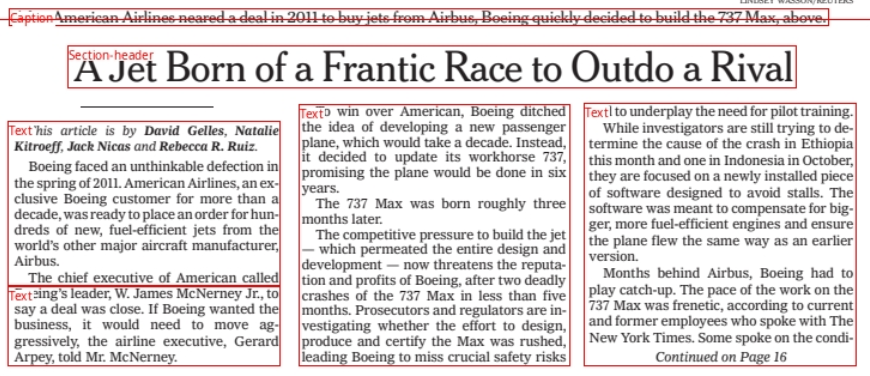
- Layout analysis (table, image, header, etc.) with reading order
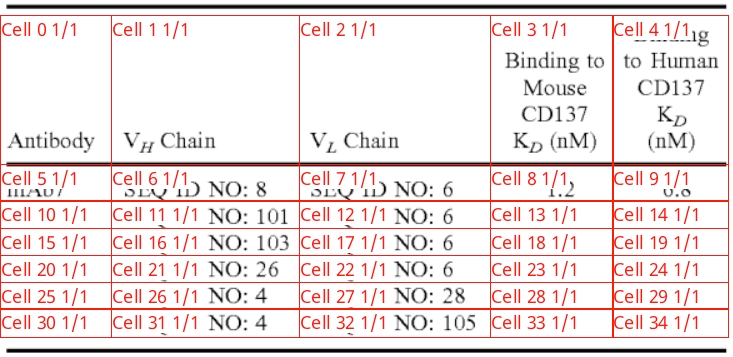
- Table recognition (rows + columns)
We also ship smaller models for line-level text detection and ocr error detection. It works on a range of documents (see usage and benchmarks).
Our managed platform runs both Surya, and variants of our highest accuracy model, Chandra.
Get started with $5 in free credits — sign up (takes under 30 seconds) or try our free public playground.
| Detection |
OCR |
 |
 |
| Layout |
Table Recognition |
 |
 |
Surya is named for the Hindu sun god, who has universal vision.
Examples
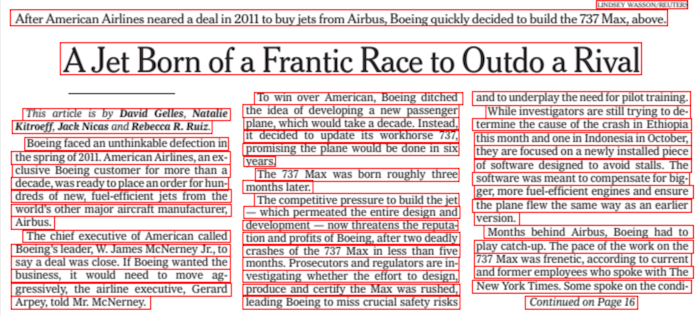
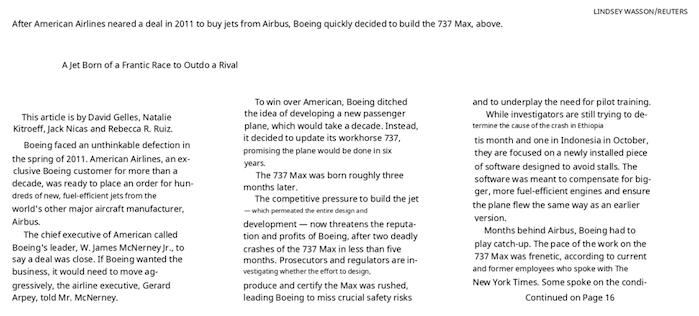
Each row links to five annotated views of the same page: text-line detection, OCR, layout, reading order, and (when present) table recognition.
Commercial usage
The Surya code is licensed under Apache 2.0. The model weights use a modified AI Pubs Open Rail-M license (free for research, personal use, and startups under $5M funding/revenue). For broader commercial licensing of the model weights, visit our pricing page here.
Installation
Install with:
pip install surya-ocr
Inference backend prerequisites
Surya auto-spawns the server on first use, and you need vllm (NVIDIA GPU) or llama.cpp (CPU / Apple Silicon):
Upgrading from Surya v1
If you have v1 code, you can migrate to this:
# v2
from surya.inference import SuryaInferenceManager
from surya.recognition import RecognitionPredictor

manager = SuryaInferenceManager()              # auto-spawns vllm or llama-server
rec = RecognitionPredictor(manager)
predictions = rec([image])
What's different:
SuryaInferenceManager replaces FoundationPredictor. Same manager instance is shared across LayoutPredictor, RecognitionPredictor, TableRecPredictor.- Output schemas changed: see the per-section JSON tables below. Highlights —
text_lines → blocks (with html); layout dropped top_k, added count; table_rec dropped is_header / colspan / rowspan from cells.
Usage
Surya 2 runs layout, OCR, and table recognition through a single VLM. The inference manager will spawn one for you on first use; you can also point it at an existing server via SURYA_INFERENCE_URL=http://host:port/v1.
- Inspect the settings in
surya/settings.py. You can override any setting via env var (e.g. SURYA_INFERENCE_BACKEND=vllm).
- Text detection and OCR errors are separate models.
Server lifecycle (--keep_server)
By default each command spawns the VLM server on startup and shuts it down on
exit — so running several commands in a row pays the startup (and, on GPU, the
model-load) cost every time. Pass --keep_server to leave the server running
so later commands attach to it instead of re-spawning:
surya_ocr    DATA_PATH --keep_server   # spawns the server and leaves it up
surya_layout DATA_PATH                 # attaches to the running server
surya_table  DATA_PATH                 # ...and so on, no re-spawn
--keep_server works on every command. Stop the server when you're done
(docker stop the surya-vllm-* container, or kill the llama-server
process), or set SURYA_INFERENCE_KEEP_ALIVE=1 to make keep-alive the default.
Interactive App
I've included a streamlit app that lets you interactively try Surya on images or PDF files. Run it with:
pip install streamlit pdftext
surya_gui
OCR (text recognition)
This command will write out a json file with the detected text and bboxes:
surya_ocr DATA_PATH
DATA_PATH can be an image, pdf, or folder of images/pdfs--images will save images of the pages and detected blocks (optional)--output_dir specifies the directory to save results to instead of the default--page_range specifies the page range to process in the PDF, specified as a single number, a comma separated list, a range, or comma separated ranges - example: 0,5-10,20.--keep_server leaves the inference server running after the command exits so later commands reuse it (see Server lifecycle). Available on every command.
The results.json file contains a dict keyed by input filename (no extension). Each value is a list of page dicts. Each page dict contains:
blocks - per-block OCR results in reading order
label - canonicalized layout label (e.g. Text, SectionHeader, Table, Equation, Picture, Form, PageHeader, ...). See surya/layout/label.py:LAYOUT_PRED_RELABEL for the full canonical-name set.raw_label - original label emitted by the model, before canonicalizationreading_order - 0-indexed position in layout outputhtml - block content as HTML (math wrapped in <math>...</math>, tables as <table>...</table>, etc.). "" if the block was skippedpolygon - 4-corner polygon in [[x0,y0],[x1,y0],[x1,y1],[x0,y1]] orderbbox - axis-aligned [x0, y0, x1, y1] derived from the polygonconfidence - mean per-token probability across the block's decode (0-1)skipped - true if the block was a visual label (e.g. Picture) and not OCR'derror - true if the block OCR call failed
image_bbox - [0, 0, width, height] for the page image
Performance tips
- Throughput is governed by the inference backend. With
vllm, raise --max-num-seqs / --max-num-batched-tokens (or SURYA_INFERENCE_PARALLEL on the client side) to keep more pages in flight. With llama.cpp, set SURYA_INFERENCE_PARALLEL to match --parallel on llama-server.
- DPI can also impact throughput significantly - you can adjust the DPI settings to make the right throughput/accuracy tradeoff for your usecase. Try going from 192 to 96 for improved throughput.
- MTP can also impact latency/throughput - you can adjust the vllm mtp config in settings.
From python
from PIL import Image
from surya.inference import SuryaInferenceManager
from surya.recognition import RecognitionPredictor

manager = SuryaInferenceManager()
recognition_predictor = RecognitionPredictor(manager)

# Default: full-page OCR. One VLM call per page. Returns one PageOCRResult per
# image: `.blocks` (each with label, html, polygon, bbox, confidence, ...) and
# `.image_bbox` — the same schema as block mode.
predictions = recognition_predictor([Image.open(IMAGE_PATH)])

# Block mode: pre-run layout, then per-block OCR. Same return schema as above.
# Auto-selected when `layout_results` is passed.
from surya.layout import LayoutPredictor
layout = LayoutPredictor(manager)
layouts = layout([Image.open(IMAGE_PATH)])
predictions = recognition_predictor([Image.open(IMAGE_PATH)], layouts)
Text line detection
This command will write out a json file with the detected bboxes.
surya_detect DATA_PATH
DATA_PATH can be an image, pdf, or folder of images/pdfs--images will save images of the pages and detected text lines (optional)--output_dir specifies the directory to save results to instead of the default--page_range specifies the page range to process in the PDF, specified as a single number, a comma separated list, a range, or comma separated ranges - example: 0,5-10,20.
The results.json file will contain a json dictionary where the keys are the input filenames without extensions. Each value will be a list of dictionaries, one per page of the input document. Each page dictionary contains:
bboxes - detected bounding boxes for text
bbox - the axis-aligned rectangle for the text line in (x1, y1, x2, y2) format. (x1, y1) is the top left corner, and (x2, y2) is the bottom right corner.polygon - the polygon for the text line in (x1, y1), (x2, y2), (x3, y3), (x4, y4) format. The points are in clockwise order from the top left.confidence - the confidence of the model in the detected text (0-1)
vertical_lines - vertical lines detected in the document
bbox - the axis-aligned line coordinates.
page - the page number in the fileimage_bbox - the bbox for the image in (x1, y1, x2, y2) format. (x1, y1) is the top left corner, and (x2, y2) is the bottom right corner. All line bboxes will be contained within this bbox.
Performance tips
Detection is a torch model. DETECTOR_BATCH_SIZE defaults to an auto-picked value at runtime; override the env var to control VRAM usage on GPU and raise it on larger cards.
From python
from PIL import Image
from surya.detection import DetectionPredictor

det_predictor = DetectionPredictor()
predictions = det_predictor([Image.open(IMAGE_PATH)])
Layout and reading order
This command will write out a json file with the detected layout and reading order.
surya_layout DATA_PATH
DATA_PATH can be an image, pdf, or folder of images/pdfs--images will save images of the pages and detected text lines (optional)--output_dir specifies the directory to save results to instead of the default--page_range specifies the page range to process in the PDF, specified as a single number, a comma separated list, a range, or comma separated ranges - example: 0,5-10,20.
The results.json file contains a dict keyed by input filename (no extension). Each value is a list of page dicts. Each page dict contains:
bboxes - layout boxes in reading order
polygon - 4-corner polygon [[x0,y0],[x1,y0],[x1,y1],[x0,y1]]bbox - axis-aligned [x0, y0, x1, y1] derived from the polygonlabel - canonicalized label. One of Caption, Footnote, Equation, ListGroup, PageHeader, PageFooter, Picture, SectionHeader, Table, Text, Figure, Code, Form, TableOfContents, ChemicalBlock, Diagram, Bibliography, BlankPageraw_label - original label emitted by the modelposition - 0-indexed reading ordercount - model's token estimate for OCR'ing this block (rounded to multiples of 50; used to size the per-block decode budget)confidence - mean per-token probability across the layout decode (0-1)
image_bbox - [0, 0, width, height]raw - raw JSON the layout model emitted, for debuggingerror - true if the layout call failed
Performance tips
Layout runs through the shared inference backend. Throughput tuning is the same as OCR — see Performance tips above.
From python
from PIL import Image
from surya.inference import SuryaInferenceManager
from surya.layout import LayoutPredictor

layout_predictor = LayoutPredictor(SuryaInferenceManager())
layout_predictions = layout_predictor([Image.open(IMAGE_PATH)])
Table Recognition
This command will write out a json file with the detected table cells and row/column ids, along with row/column bounding boxes. If you want to get cell positions and text, along with nice formatting, check out the marker repo. You can use the TableConverter to detect and extract tables in images and PDFs. It supports output in json (with bboxes), markdown, and html.
surya_table DATA_PATH
DATA_PATH can be an image, pdf, or folder of images/pdfs--images will save annotated row + column overlays alongside the json (optional)--output_dir specifies the directory to save results to instead of the default--page_range specifies the page range to process in the PDF, specified as a single number, a comma separated list, a range, or comma separated ranges - example: 0,5-10,20.--skip_table_detection tells table recognition not to detect tables first. Use this if your image is already cropped to a table.
The results.json file contains a dict keyed by input filename (no extension). Each value is a list of per-table dicts. Each table dict contains:
rows - detected table rows in reading order
polygon / bbox - row geometry (same convention as everywhere else)row_id - 0-indexed row id
cols - detected table columns
polygon / bbox - column geometrycol_id - 0-indexed column id
cells - geometric row × column intersections (simple mode)
polygon / bbox - cell geometryrow_id, col_id, cell_id
html - full <table>...</table> HTML (only populated when predict_full is used; handles spanning cells / header rows). null in simple mode.mode - "simple" or "full"image_bbox - the table crop bboxerror - true if the table_rec call failedraw - raw model output, for debugging
Performance tips
Table recognition routes through the shared VLM. Throughput tuning is the same as OCR.
From python
from PIL import Image
from surya.inference import SuryaInferenceManager
from surya.table_rec import TableRecPredictor

table_rec_predictor = TableRecPredictor(SuryaInferenceManager())

# Default: rows + columns only, cells derived from intersections.
table_predictions = table_rec_predictor([Image.open(IMAGE_PATH)])

# Or full HTML output (better for spanning cells / headers):
# table_predictions = table_rec_predictor.predict_full([image])
Math / equations
Surya 2 handles math inline as part of full-page OCR — recognized equations
come back inside <math>...</math> tags in the same HTML output as
surrounding prose, in KaTeX-compatible LaTeX. No separate LaTeX OCR pass.
Inference Backends
Layout / OCR / table_rec all share one VLM, served either by vllm (GPU) or llama.cpp (CPU / Apple Silicon). The SuryaInferenceManager will spawn one automatically; you can also point at a pre-running server:
# Attach to an existing vllm
export SURYA_INFERENCE_BACKEND=vllm
export SURYA_INFERENCE_URL=http://localhost:8000/v1
| Setting |
Default |
Notes |
SURYA_INFERENCE_BACKEND |
auto (vllm if NVIDIA, else llamacpp) |
vllm | llamacpp | unset (auto) |
SURYA_INFERENCE_URL |
(auto-spawn) |
Attach to a running OpenAI-compatible server |
SURYA_INFERENCE_PARALLEL |
8 |
Client-side concurrency to the backend |
SURYA_INFERENCE_KEEP_ALIVE |
false |
Leave the spawned server up after exit (cf. --keep_server) |
SURYA_GUIDED_LAYOUT |
true |
JSON-schema-constrained layout decode |
Limitations
- This is specialized for document OCR. Performance on photos or natural scenes is not the goal.
- Layout / OCR / table_rec all need a running inference backend (vllm or llama.cpp). Detection runs purely on torch and works without it.
Troubleshooting
If OCR isn't working properly:
- Try increasing resolution of the image so the text is bigger. If the resolution is already very high, try decreasing it to no more than a
2048px width.
- Preprocessing the image (binarizing, deskewing, etc) can help with very old/blurry images.
- You can adjust
DETECTOR_BLANK_THRESHOLD and DETECTOR_TEXT_THRESHOLD if you don't get good results. DETECTOR_BLANK_THRESHOLD controls the space between lines - any prediction below this number will be considered blank space. DETECTOR_TEXT_THRESHOLD controls how text is joined - any number above this is considered text. DETECTOR_TEXT_THRESHOLD should always be higher than DETECTOR_BLANK_THRESHOLD, and both should be in the 0-1 range. Looking at the heatmap from the debug output of the detector can tell you how to adjust these (if you see faint things that look like boxes, lower the thresholds, and if you see bboxes being joined together, raise the thresholds).
Manual install
If you want to develop surya, you can install it manually with uv:
git clone https://github.com/datalab-to/surya.git
cd surya
uv sync --group dev      # installs runtime + dev deps
uv run surya_ocr ...     # or `source .venv/bin/activate` to enter the venv
Benchmarks
Surya 2 is a single VLM that handles layout analysis, OCR (full-page or
per-block), and table recognition in one model. We evaluate end-to-end on
olmOCR-bench — the
standard quality benchmark for document parsers.
olmOCR-bench
Pareto-optimal on the size-vs-score frontier, and best in class under 3B params.
| Model |
Params |
Score |
| Infinity-Parser2-Pro |
35.1B |
87.6 |
| Chandra OCR 2 (Datalab) |
4.0B |
85.9 |
| dots.mocr |
3.0B |
83.9 |
| Surya OCR 2 (Datalab) |
0.65B |
83.3 |
| LightOnOCR 2-1B * |
1.0B |
83.2 |
| Chandra OCR 1 (Datalab) |
9.0B |
83.1 |
| olmOCR (anchored) |
8.3B |
77.4 |
| GOT OCR |
0.6B |
48.3 |
* LightOnOCR 2-1B uses a different benchmark methodology than the other entries (see their release notes); the score is included for context but is not directly comparable.
Comparison scores from the olmOCR-bench dataset card.
Surya 2, per-source pass rate on the default preset (8,413 tests total):
| ArXiv |
Base |
Hdr/Ftr |
TinyTxt |
MultCol |
OldScan |
OldMath |
Tables |
| 88.3 |
99.7 |
92.5 |
93.7 |
82.4 |
41.8 |
81.4 |
86.6 |
Multilingual
We also evaluate Surya 2 against a 91-language internal benchmark covering
text accuracy, layout, tables, math, and reading order in documents drawn
from each language.
Overall pass rate: 87.2% across 91 languages. 38 of the
91 languages score ≥ 90%; 76 score ≥ 80%.
Top 15 widely-spoken languages:
| Code |
Language |
Score |
ar |
Arabic |
72.7% |
bn |
Bengali |
82.7% |
zh |
Chinese |
82.5% |
en |
English |
92.3% |
fr |
French |
89.3% |
de |
German |
89.7% |
hi |
Hindi |
82.2% |
it |
Italian |
93.0% |
ja |
Japanese |
86.2% |
ko |
Korean |
86.7% |
fa |
Persian |
82.3% |
pt |
Portuguese |
86.1% |
ru |
Russian |
88.8% |
es |
Spanish |
90.7% |
vi |
Vietnamese |
73.2% |
See static/docs/multilingual.md for the full 91-language table.
Throughput
Full-page OCR, 96 DPI input (~2,400 output tokens/page average), measured
client-side against a running inference server.
RTX 5090 (vllm)
vllm/vllm-openai:v0.20.1, single RTX 5090 (32 GB).
| Concurrency |
Pages/s |
Tokens/s |
p50 (ms) |
p95 (ms) |
avg tok/page |
| 128 |
5.35 |
12,884 |
18,915 |
42,538 |
2,410 |
llama-server with Metal backend.
--parallel |
Pages/s |
Tokens/s |
p50 (ms) |
p95 (ms) |
avg tok/page |
Power |
| 8 |
0.108 |
254 |
59,313 |
129,173 |
2,360 |
~30 W |
Reproducing
We score Surya 2 on olmOCR-bench by serving the model with vllm (or
llama.cpp) and running the olmOCR-bench harness from
allenai/olmocr, with some adjustments applied to account for our output HTML format.
Training
Layout, OCR, and table recognition all share a single vision-language model
(Qwen3.5-style architecture, ~650M params). It's trained on diverse document
images to emit either a layout JSON or a full-page HTML output, depending on
prompt. Text-line detection is a separate small torch model — a modified
EfficientViT segformer trained from scratch on document line annotations.
If you want help finetuning Surya on your own data, or to use our managed
training stack, reach us at [email protected].
Thanks
This work would not have been possible without amazing open source AI work:
Thank you to everyone who makes open source AI possible.
Citation
If you use surya (or the associated models) in your work or research, please consider citing us using the following BibTeX entry:
@misc{paruchuri2025surya,
  author       = {Vikas Paruchuri and Datalab Team},
  title        = {Surya: A lightweight document OCR and analysis toolkit},
  year         = {2025},
  howpublished = {\url{https://github.com/datalab-to/surya}},
  note         = {GitHub repository},
}

 Surya 是 Datalab 开源的一款文档 OCR 系统,核心是一个 65 亿……不对,是 650M 参数的模型。它能从图片和 PDF 中识别文字,还能做版面分析、阅读顺序判断和表格识别。