Qwen3-TTS
🤗 Hugging Face | 🤖 ModelScope | 📑 Blog | 📑 Paper
🖥️ Hugging Face Demo | 🖥️ ModelScope Demo | 💬 WeChat (微信) | 🫨 Discord | 📑 API
We release Qwen3-TTS, a series of powerful speech generation capabilities developed by Qwen, offering comprehensive support for voice clone, voice design, ultra-high-quality human-like speech generation, and natural language-based voice control. It provides developers and users with the most extensive set of speech generation features available.
News
- 2026.1.22: 🎉🎉🎉 We have released Qwen3-TTS series (0.6B/1.7B) based on Qwen3-TTS-Tokenizer-12Hz. Please check our blog!
Contents
Overview
Introduction
Qwen3-TTS covers 10 major languages (Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian) as well as multiple dialectal voice profiles to meet global application needs. In addition, the models feature strong contextual understanding, enabling adaptive control of tone, speaking rate, and emotional expression based on instructions and text semantics, and they show markedly improved robustness to noisy input text. Key features:
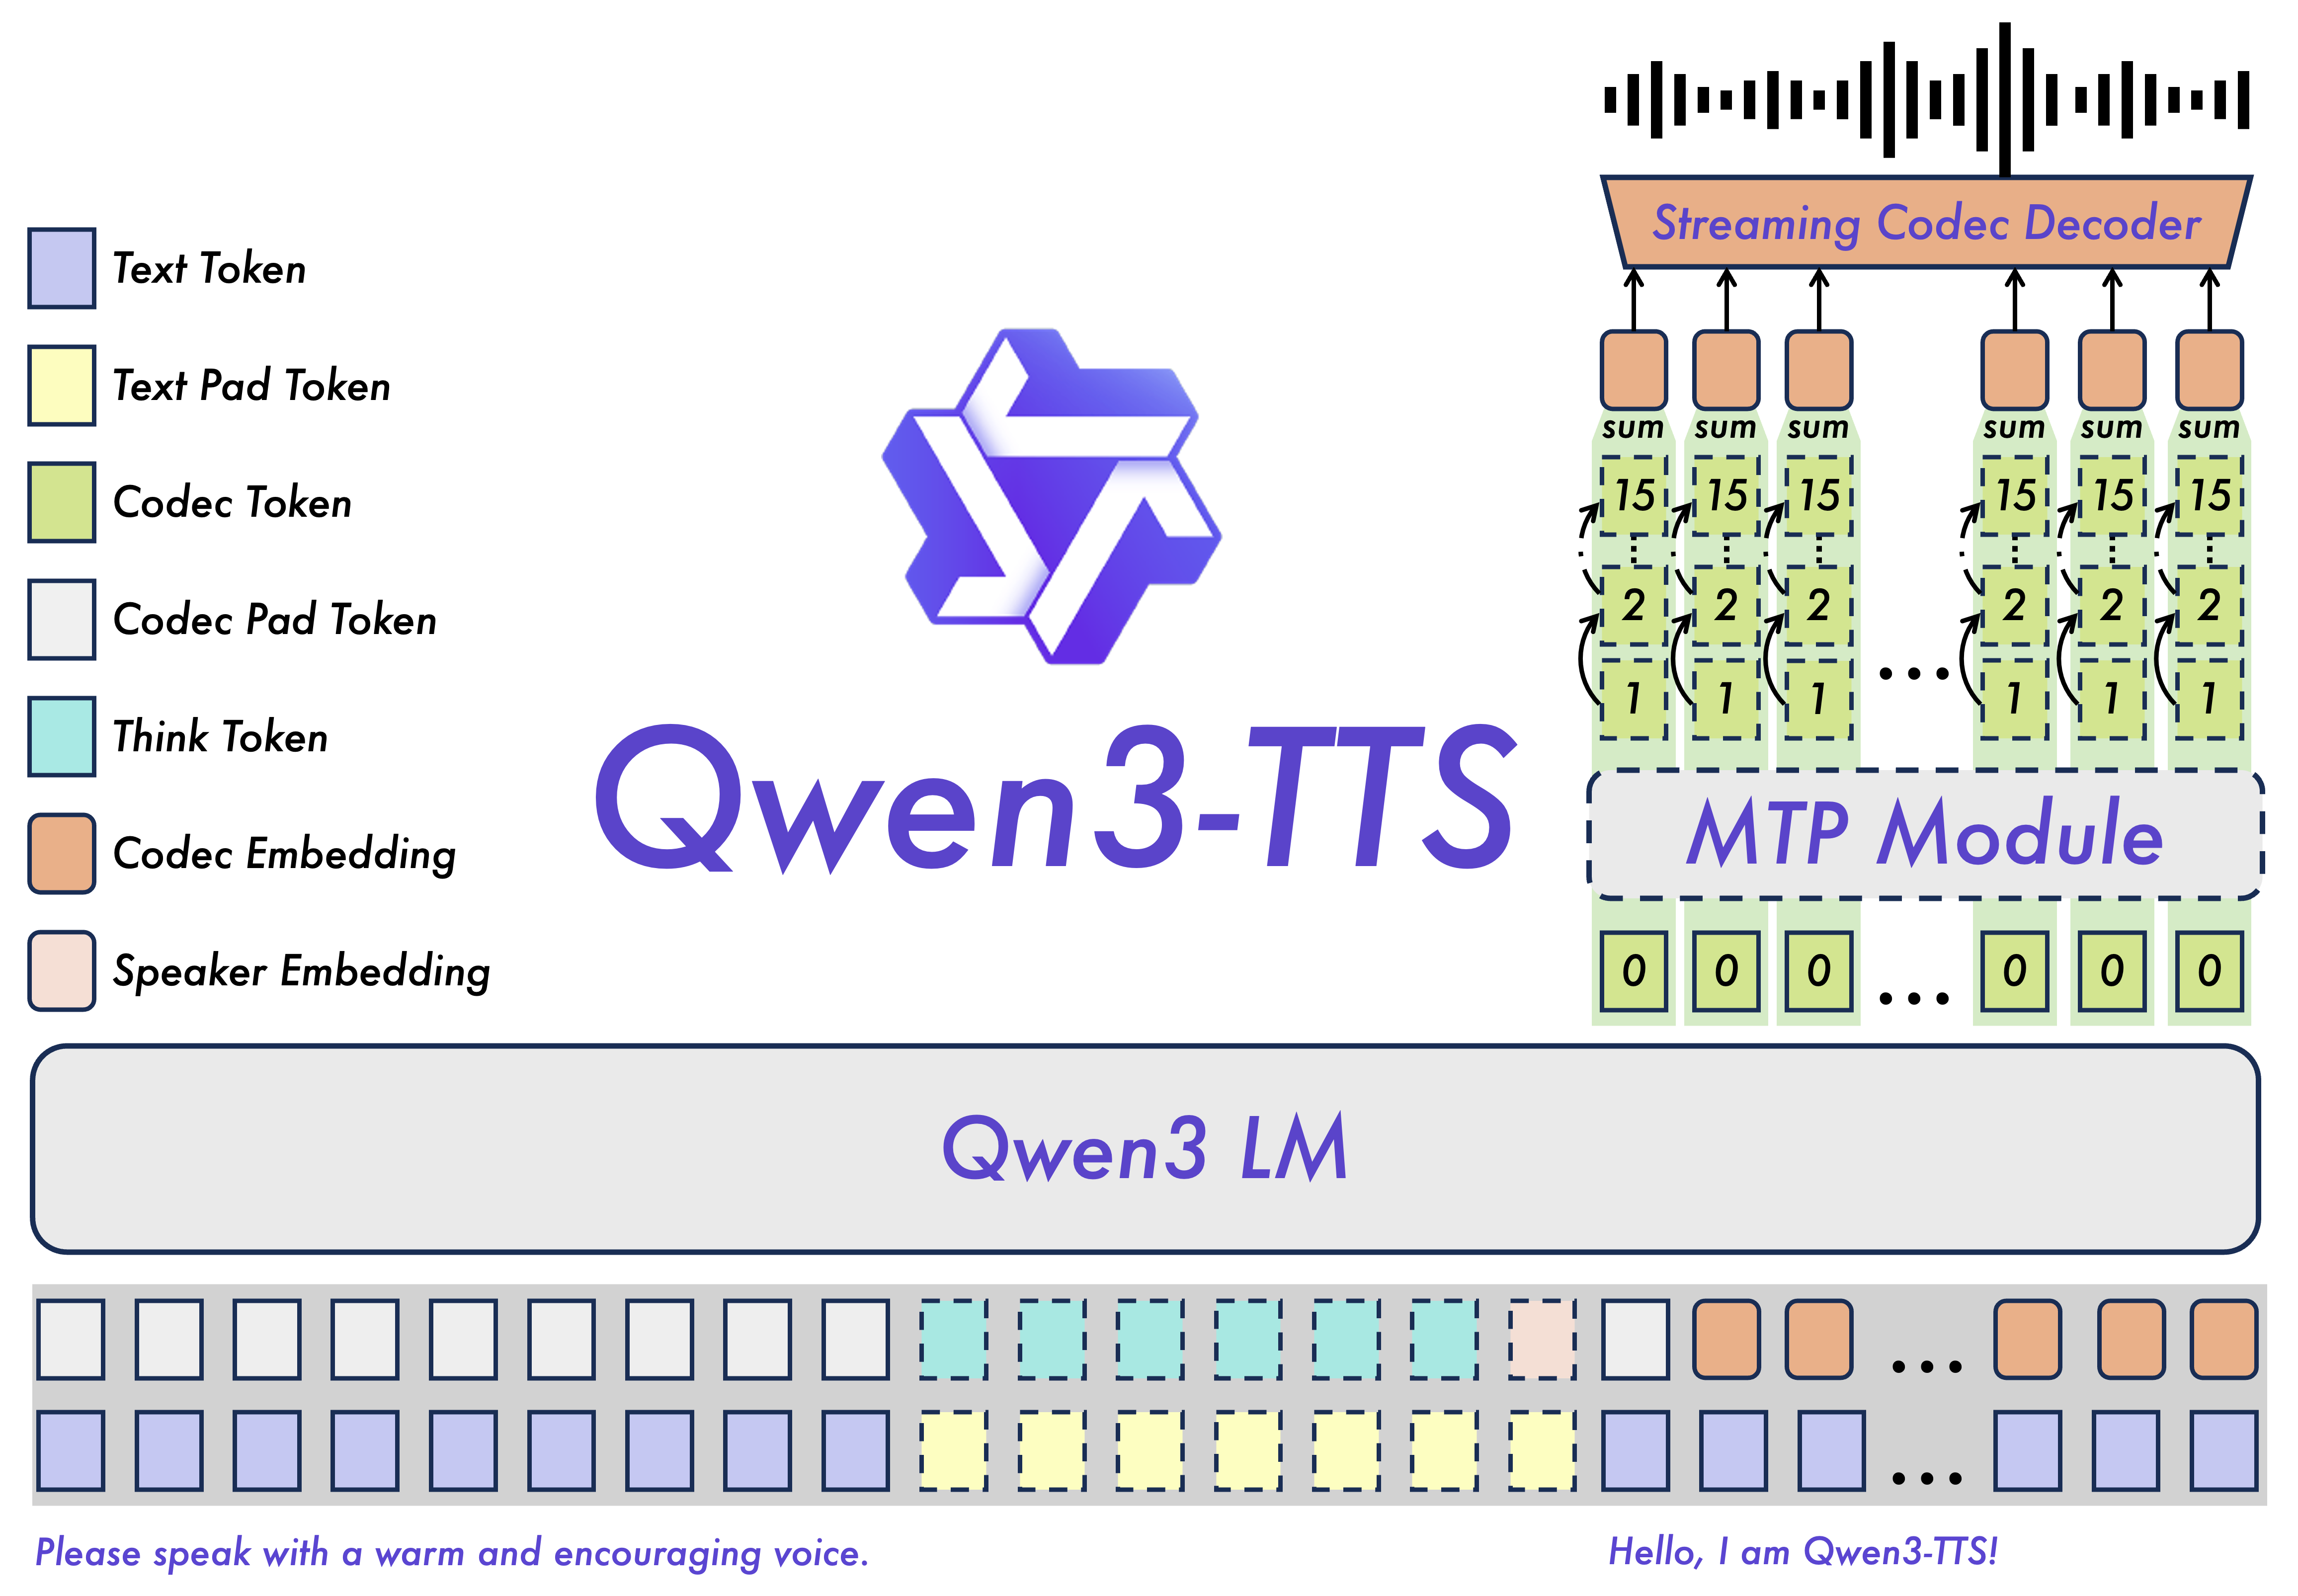
- Powerful Speech Representation: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, it achieves efficient acoustic compression and high-dimensional semantic modeling of speech signals. It fully preserves paralinguistic information and acoustic environmental features, enabling high-speed, high-fidelity speech reconstruction through a lightweight non-DiT architecture.
- Universal End-to-End Architecture: Utilizing a discrete multi-codebook LM architecture, it realizes full-information end-to-end speech modeling. This completely bypasses the information bottlenecks and cascading errors inherent in traditional LM+DiT schemes, significantly enhancing the model’s versatility, generation efficiency, and performance ceiling.
- Extreme Low-Latency Streaming Generation: Based on the innovative Dual-Track hybrid streaming generation architecture, a single model supports both streaming and non-streaming generation. It can output the first audio packet immediately after a single character is input, with end-to-end synthesis latency as low as 97ms, meeting the rigorous demands of real-time interactive scenarios.
- Intelligent Text Understanding and Voice Control: Supports speech generation driven by natural language instructions, allowing for flexible control over multi-dimensional acoustic attributes such as timbre, emotion, and prosody. By deeply integrating text semantic understanding, the model adaptively adjusts tone, rhythm, and emotional expression, achieving lifelike “what you imagine is what you hear” output.
Model Architecture
Released Models Description and Download
Below is an introduction and download information for the Qwen3-TTS models that have already been released. Other models mentioned in the technical report will be released in the near future. Please select and download the model that fits your needs.
| Tokenizer Name |
Description |
| Qwen3-TTS-Tokenizer-12Hz |
The Qwen3-TTS-Tokenizer-12Hz model which can encode the input speech into codes and decode them back into speech. |
| Model |
Features |
Language Support |
Streaming |
Instruction Control |
| Qwen3-TTS-12Hz-1.7B-VoiceDesign |
Performs voice design based on user-provided descriptions. |
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian |
✅ |
✅ |
| Qwen3-TTS-12Hz-1.7B-CustomVoice |
Provides style control over target timbres via user instructions; supports 9 premium timbres covering various combinations of gender, age, language, and dialect. |
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian |
✅ |
✅ |
| Qwen3-TTS-12Hz-1.7B-Base |
Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. |
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian |
✅ |
|
| Qwen3-TTS-12Hz-0.6B-CustomVoice |
Supports 9 premium timbres covering various combinations of gender, age, language, and dialect. |
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian |
✅ |
|
| Qwen3-TTS-12Hz-0.6B-Base |
Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. |
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian |
✅ |
|
During model loading in the qwen-tts package or vLLM, model weights will be automatically downloaded based on the model name. However, if your runtime environment is not conducive to downloading weights during execution, you can refer to the following commands to manually download the model weights to a local directory:
# Download through ModelScope (recommended for users in Mainland China)
pip install -U modelscope
modelscope download --model Qwen/Qwen3-TTS-Tokenizer-12Hz  --local_dir ./Qwen3-TTS-Tokenizer-12Hz
modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --local_dir ./Qwen3-TTS-12Hz-1.7B-CustomVoice
modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign --local_dir ./Qwen3-TTS-12Hz-1.7B-VoiceDesign
modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-Base --local_dir ./Qwen3-TTS-12Hz-1.7B-Base
modelscope download --model Qwen/Qwen3-TTS-12Hz-0.6B-CustomVoice --local_dir ./Qwen3-TTS-12Hz-0.6B-CustomVoice
modelscope download --model Qwen/Qwen3-TTS-12Hz-0.6B-Base --local_dir ./Qwen3-TTS-12Hz-0.6B-Base

# Download through Hugging Face
pip install -U "huggingface_hub[cli]"
huggingface-cli download Qwen/Qwen3-TTS-Tokenizer-12Hz --local-dir ./Qwen3-TTS-Tokenizer-12Hz
huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --local-dir ./Qwen3-TTS-12Hz-1.7B-CustomVoice
huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign --local-dir ./Qwen3-TTS-12Hz-1.7B-VoiceDesign
huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-Base --local-dir ./Qwen3-TTS-12Hz-1.7B-Base
huggingface-cli download Qwen/Qwen3-TTS-12Hz-0.6B-CustomVoice --local-dir ./Qwen3-TTS-12Hz-0.6B-CustomVoice
huggingface-cli download Qwen/Qwen3-TTS-12Hz-0.6B-Base --local-dir ./Qwen3-TTS-12Hz-0.6B-Base
Quickstart
Environment Setup
The easiest way to quickly use Qwen3-TTS is to install the qwen-tts Python package from PyPI. This will pull in the required runtime dependencies and allow you to load any released Qwen3-TTS model. We recommend using a fresh, isolated environment to avoid dependency conflicts with existing packages. You can create a clean Python 3.12 environment like this:
conda create -n qwen3-tts python=3.12 -y
conda activate qwen3-tts
then run:
pip install -U qwen-tts
If you want to develop or modify the code locally, install from source in editable mode.
git clone https://github.com/QwenLM/Qwen3-TTS.git
cd Qwen3-TTS
pip install -e .
Additionally, we recommend using FlashAttention 2 to reduce GPU memory usage.
pip install -U flash-attn --no-build-isolation
If your machine has less than 96GB of RAM and lots of CPU cores, run:
MAX_JOBS=4 pip install -U flash-attn --no-build-isolation
Also, you should have hardware that is compatible with FlashAttention 2. Read more about it in the official documentation of the FlashAttention repository. FlashAttention 2 can only be used when a model is loaded in torch.float16 or torch.bfloat16.
Python Package Usage
After installation, you can import Qwen3TTSModel to run custom voice TTS, voice design, and voice clone. The model weights can be specified either as a Hugging Face model id (recommended) or as a local directory path you downloaded. For all the generate_* functions below, besides the parameters shown and explicitly documented, you can also pass generation kwargs supported by Hugging Face Transformers model.generate, e.g., max_new_tokens, top_p, etc.
Custom Voice Generate
For custom voice models (Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice), you just need to call generate_custom_voice, passing a single string or a batch list, along with language, speaker, and optional instruct. You can also call model.get_supported_speakers() and model.get_supported_languages() to see which speakers and languages the current model supports.
import torch
import soundfile as sf
from qwen_tts import Qwen3TTSModel

model = Qwen3TTSModel.from_pretrained(
    "Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice",
    device_map="cuda:0",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
)

# single inference
wavs, sr = model.generate_custom_voice(
    text="其实我真的有发现,我是一个特别善于观察别人情绪的人。",
    language="Chinese", # Pass `Auto` (or omit) for auto language adaptive; if the target language is known, set it explicitly.
    speaker="Vivian",
    instruct="用特别愤怒的语气说", # Omit if not needed.
)
sf.write("output_custom_voice.wav", wavs[0], sr)

# batch inference
wavs, sr = model.generate_custom_voice(
    text=[
        "其实我真的有发现,我是一个特别善于观察别人情绪的人。",
        "She said she would be here by noon."
    ],
    language=["Chinese", "English"],
    speaker=["Vivian", "Ryan"],
    instruct=["", "Very happy."]
)
sf.write("output_custom_voice_1.wav", wavs[0], sr)
sf.write("output_custom_voice_2.wav", wavs[1], sr)
For Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice models, the supported speaker list and speaker descriptions are provided below. We recommend using each speaker’s native language for the best quality. Of course, each speaker can speak any language supported by the model.
| Speaker |
Voice Description |
Native language |
| Vivian |
Bright, slightly edgy young female voice. |
Chinese |
| Serena |
Warm, gentle young female voice. |
Chinese |
| Uncle_Fu |
Seasoned male voice with a low, mellow timbre. |
Chinese |
| Dylan |
Youthful Beijing male voice with a clear, natural timbre. |
Chinese (Beijing Dialect) |
| Eric |
Lively Chengdu male voice with a slightly husky brightness. |
Chinese (Sichuan Dialect) |
| Ryan |
Dynamic male voice with strong rhythmic drive. |
English |
| Aiden |
Sunny American male voice with a clear midrange. |
English |
| Ono_Anna |
Playful Japanese female voice with a light, nimble timbre. |
Japanese |
| Sohee |
Warm Korean female voice with rich emotion. |
Korean |
Voice Design
For the voice design model (Qwen3-TTS-12Hz-1.7B-VoiceDesign), you can use generate_voice_design to provide the target text and a natural-language instruct description.
import torch
import soundfile as sf
from qwen_tts import Qwen3TTSModel

model = Qwen3TTSModel.from_pretrained(
    "Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign",
    device_map="cuda:0",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
)

# single inference
wavs, sr = model.generate_voice_design(
    text="哥哥,你回来啦,人家等了你好久好久了,要抱抱!",
    language="Chinese",
    instruct="体现撒娇稚嫩的萝莉女声,音调偏高且起伏明显,营造出黏人、做作又刻意卖萌的听觉效果。",
)
sf.write("output_voice_design.wav", wavs[0], sr)

# batch inference
wavs, sr = model.generate_voice_design(
    text=[
      "哥哥,你回来啦,人家等了你好久好久了,要抱抱!",
      "It's in the top drawer... wait, it's empty? No way, that's impossible! I'm sure I put it there!"
    ],
    language=["Chinese", "English"],
    instruct=[
      "体现撒娇稚嫩的萝莉女声,音调偏高且起伏明显,营造出黏人、做作又刻意卖萌的听觉效果。",
      "Speak in an incredulous tone, but with a hint of panic beginning to creep into your voice."
    ]
)
sf.write("output_voice_design_1.wav", wavs[0], sr)
sf.write("output_voice_design_2.wav", wavs[1], sr)
Voice Clone
For the voice clone model (Qwen3-TTS-12Hz-1.7B/0.6B-Base), to clone a voice and synthesize new content, you just need to provide a reference audio clip (ref_audio) along with its transcript (ref_text). ref_audio can be a local file path, a URL, a base64 string, or a (numpy_array, sample_rate) tuple. If you set x_vector_only_mode=True, only the speaker embedding is used so ref_text is not required, but cloning quality may be reduced.
import torch
import soundfile as sf
from qwen_tts import Qwen3TTSModel

model = Qwen3TTSModel.from_pretrained(
    "Qwen/Qwen3-TTS-12Hz-1.7B-Base",
    device_map="cuda:0",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
)

ref_audio = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-TTS-Repo/clone.wav"
ref_text  = "Okay. Yeah. I resent you. I love you. I respect you. But you know what? You blew it! And thanks to you."

wavs, sr = model.generate_voice_clone(
    text="I am solving the equation: x = [-b ± √(b²-4ac)] / 2a? Nobody can — it's a disaster (◍•͈⌔•͈◍), very sad!",
    language="English",
    ref_audio=ref_audio,
    ref_text=ref_text,
)
sf.write("output_voice_clone.wav", wavs[0], sr)
If you need to reuse the same reference prompt across multiple generations (to avoid recomputing prompt features), build it once with create_voice_clone_prompt and pass it via voice_clone_prompt.
prompt_items = model.create_voice_clone_prompt(
    ref_audio=ref_audio,
    ref_text=ref_text,
    x_vector_only_mode=False,
)
wavs, sr = model.generate_voice_clone(
    text=["Sentence A.", "Sentence B."],
    language=["English", "English"],
    voice_clone_prompt=prompt_items,
)
sf.write("output_voice_clone_1.wav", wavs[0], sr)
sf.write("output_voice_clone_2.wav", wavs[1], sr)
For more examples of reusable voice clone prompts, batch cloning, and batch inference, please refer to the example codes. With those examples and the generate_voice_clone function description, you can explore more advanced usage patterns.
Voice Design then Clone
If you want a designed voice that you can reuse like a cloned speaker, a practical workflow is: (1) use the VoiceDesign model to synthesize a short reference clip that matches your target persona, (2) feed that clip into create_voice_clone_prompt to build a reusable prompt, and then (3) call generate_voice_clone with voice_clone_prompt to generate new content without re-extracting features every time. This is especially useful when you want a consistent character voice across many lines.
import torch
import soundfile as sf
from qwen_tts import Qwen3TTSModel

# create a reference audio in the target style using the VoiceDesign model
design_model = Qwen3TTSModel.from_pretrained(
    "Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign",
    device_map="cuda:0",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
)

ref_text = "H-hey! You dropped your... uh... calculus notebook? I mean, I think it's yours? Maybe?"
ref_instruct = "Male, 17 years old, tenor range, gaining confidence - deeper breath support now, though vowels still tighten when nervous"
ref_wavs, sr = design_model.generate_voice_design(
    text=ref_text,
    language="English",
    instruct=ref_instruct
)
sf.write("voice_design_reference.wav", ref_wavs[0], sr)

# build a reusable clone prompt from the voice design reference
clone_model = Qwen3TTSModel.from_pretrained(
    "Qwen/Qwen3-TTS-12Hz-1.7B-Base",
    device_map="cuda:0",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
)

voice_clone_prompt = clone_model.create_voice_clone_prompt(
    ref_audio=(ref_wavs[0], sr),   # or "voice_design_reference.wav"
    ref_text=ref_text,
)

sentences = [
    "No problem! I actually... kinda finished those already? If you want to compare answers or something...",
    "What? No! I mean yes but not like... I just think you're... your titration technique is really precise!",
]

# reuse it for multiple single calls
wavs, sr = clone_model.generate_voice_clone(
    text=sentences[0],
    language="English",
    voice_clone_prompt=voice_clone_prompt,
)
sf.write("clone_single_1.wav", wavs[0], sr)

wavs, sr = clone_model.generate_voice_clone(
    text=sentences[1],
    language="English",
    voice_clone_prompt=voice_clone_prompt,
)
sf.write("clone_single_2.wav", wavs[0], sr)

# or batch generate in one call
wavs, sr = clone_model.generate_voice_clone(
    text=sentences,
    language=["English", "English"],
    voice_clone_prompt=voice_clone_prompt,
)
for i, w in enumerate(wavs):
    sf.write(f"clone_batch_{i}.wav", w, sr)
Tokenizer Encode and Decode
If you only want to encode and decode audio for transport or training and so on, Qwen3TTSTokenizer supports encode/decode with paths, URLs, numpy waveforms, and dict/list payloads, for example:
import soundfile as sf
from qwen_tts import Qwen3TTSTokenizer

tokenizer = Qwen3TTSTokenizer.from_pretrained(
    "Qwen/Qwen3-TTS-Tokenizer-12Hz",
    device_map="cuda:0",
)

enc = tokenizer.encode("https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-TTS-Repo/tokenizer_demo_1.wav")
wavs, sr = tokenizer.decode(enc)
sf.write("decode_output.wav", wavs[0], sr)
For more tokenizer examples (including different input formats and batch usage), please refer to the example codes. With those examples and the description for Qwen3TTSTokenizer, you can explore more advanced usage patterns.
Launch Local Web UI Demo
To launch the Qwen3-TTS web ui demo, simply install the qwen-tts package and run

 Qwen3-TTS — это серия моделей синтеза речи с открытым исходным кодом от команды Qwen компании Alibaba. Она генерирует стабильную и выразительную речь, поддерживает создание голоса по текстовому описанию и умеет клонировать голос по короткому аудиофрагменту.